
Nvidia Gpu Quantization Support For Llms Youtube

NVIDIA GPU Quantization Support for LLMs - YouTube

How To Choose a GPU For AI Models/LLMs - NVIDIA GPUs - YouTube

Benchmarking LLMs on Ollama with an NVIDIA V100 GPU Server - YouTube

LLMs Quantization Crash Course for Beginners - YouTube
How to Achieve Extreme Low-bit Quantization for LLMs - YouTube

A great GPU for training LLMs: Nvidia RTX 3060 12 GB - YouTube
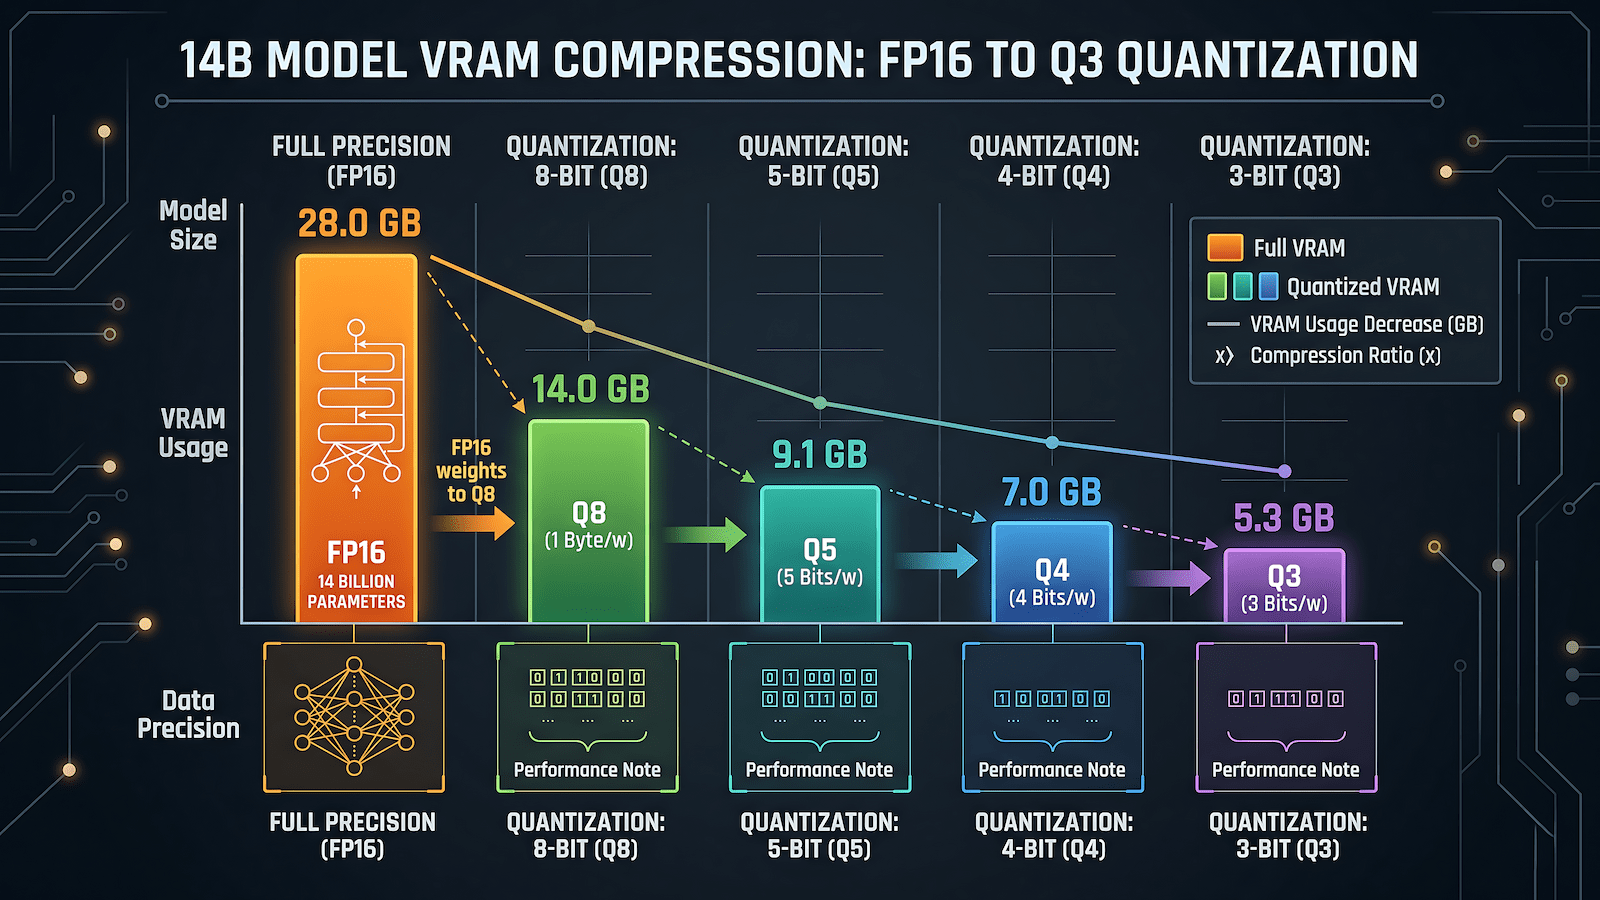
LLM Quantization Explained: What Q4, Q5, and Q8 Actually Mean for Your GPU
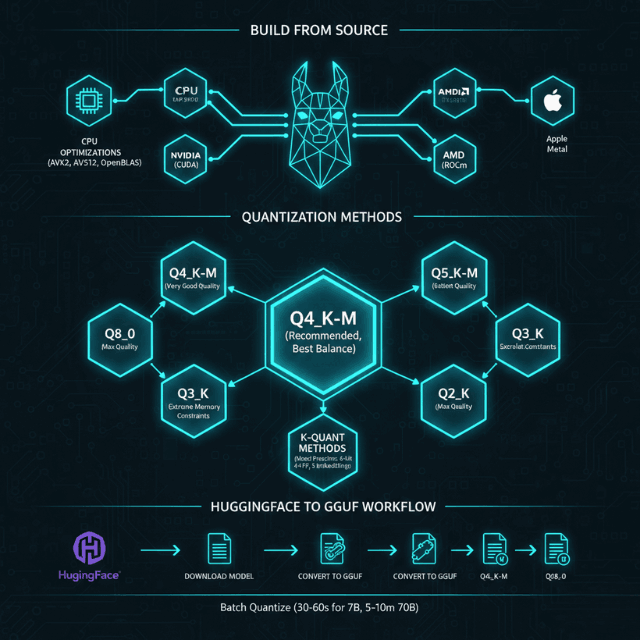
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...

How NVIDIA improves GPU Cluster Utilization with LLM Agents - YouTube
Advertisement Space (300x250)
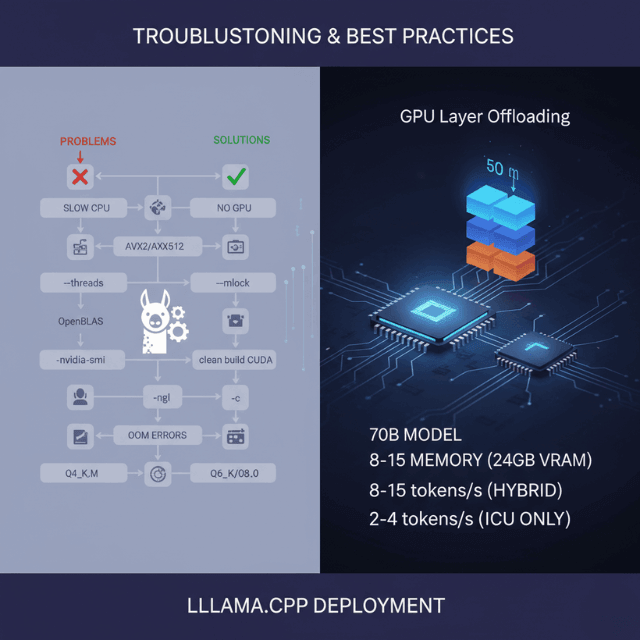
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)
MXFP4 Quantization on GPU Cloud: Deploy LLMs at 4-Bit Precision (2026 ...
Free Video: Curating Text Data for Pre-training LLMs using GPU ...
Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...
Post-Training Quantization for LLMs | NVIDIA/TensorRT-Model-Optimizer ...

Run GGUF Quantized 7B LLMs with no GPU on your laptop - YouTube
Best NVIDIA GPUs for LLMs in 2026: Ranked by Use Case | Spheron Blog

GGUF quantization of LLMs with llama cpp - YouTube
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...

How LLMs survive in low precision | Quantization Fundamentals - YouTube
Advertisement Space (336x280)

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...

GPU Meetup Getting Started With LLMs - By Innoplexus - YouTube
AWQ Quantization Guide: Deploy LLMs at Half the GPU Cost (2026 ...

EfficientQAT - New LLMs Quantization Algorithm - YouTube

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...

Does Quantization Make LLMs Dumb? - YouTube

LLM Marathon series : Quantization in LLMs: Future in LLMs - YouTube

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...

Understanding Model Quantization and Distillation in LLMs - YouTube

Run LLMs on Apple Silicon GPU | #llm #vscode - YouTube
Advertisement Space (336x280)

[IDSL Seminar'25] M-ANT: Efficient Low-bit Group Quantization for LLMs ...

NVIDIA Generative AI LLMs (NCA-GENL) - YouTube

openai/gpt-oss-20b · NVIDIA L40S GPU's for MXFP4 quantization
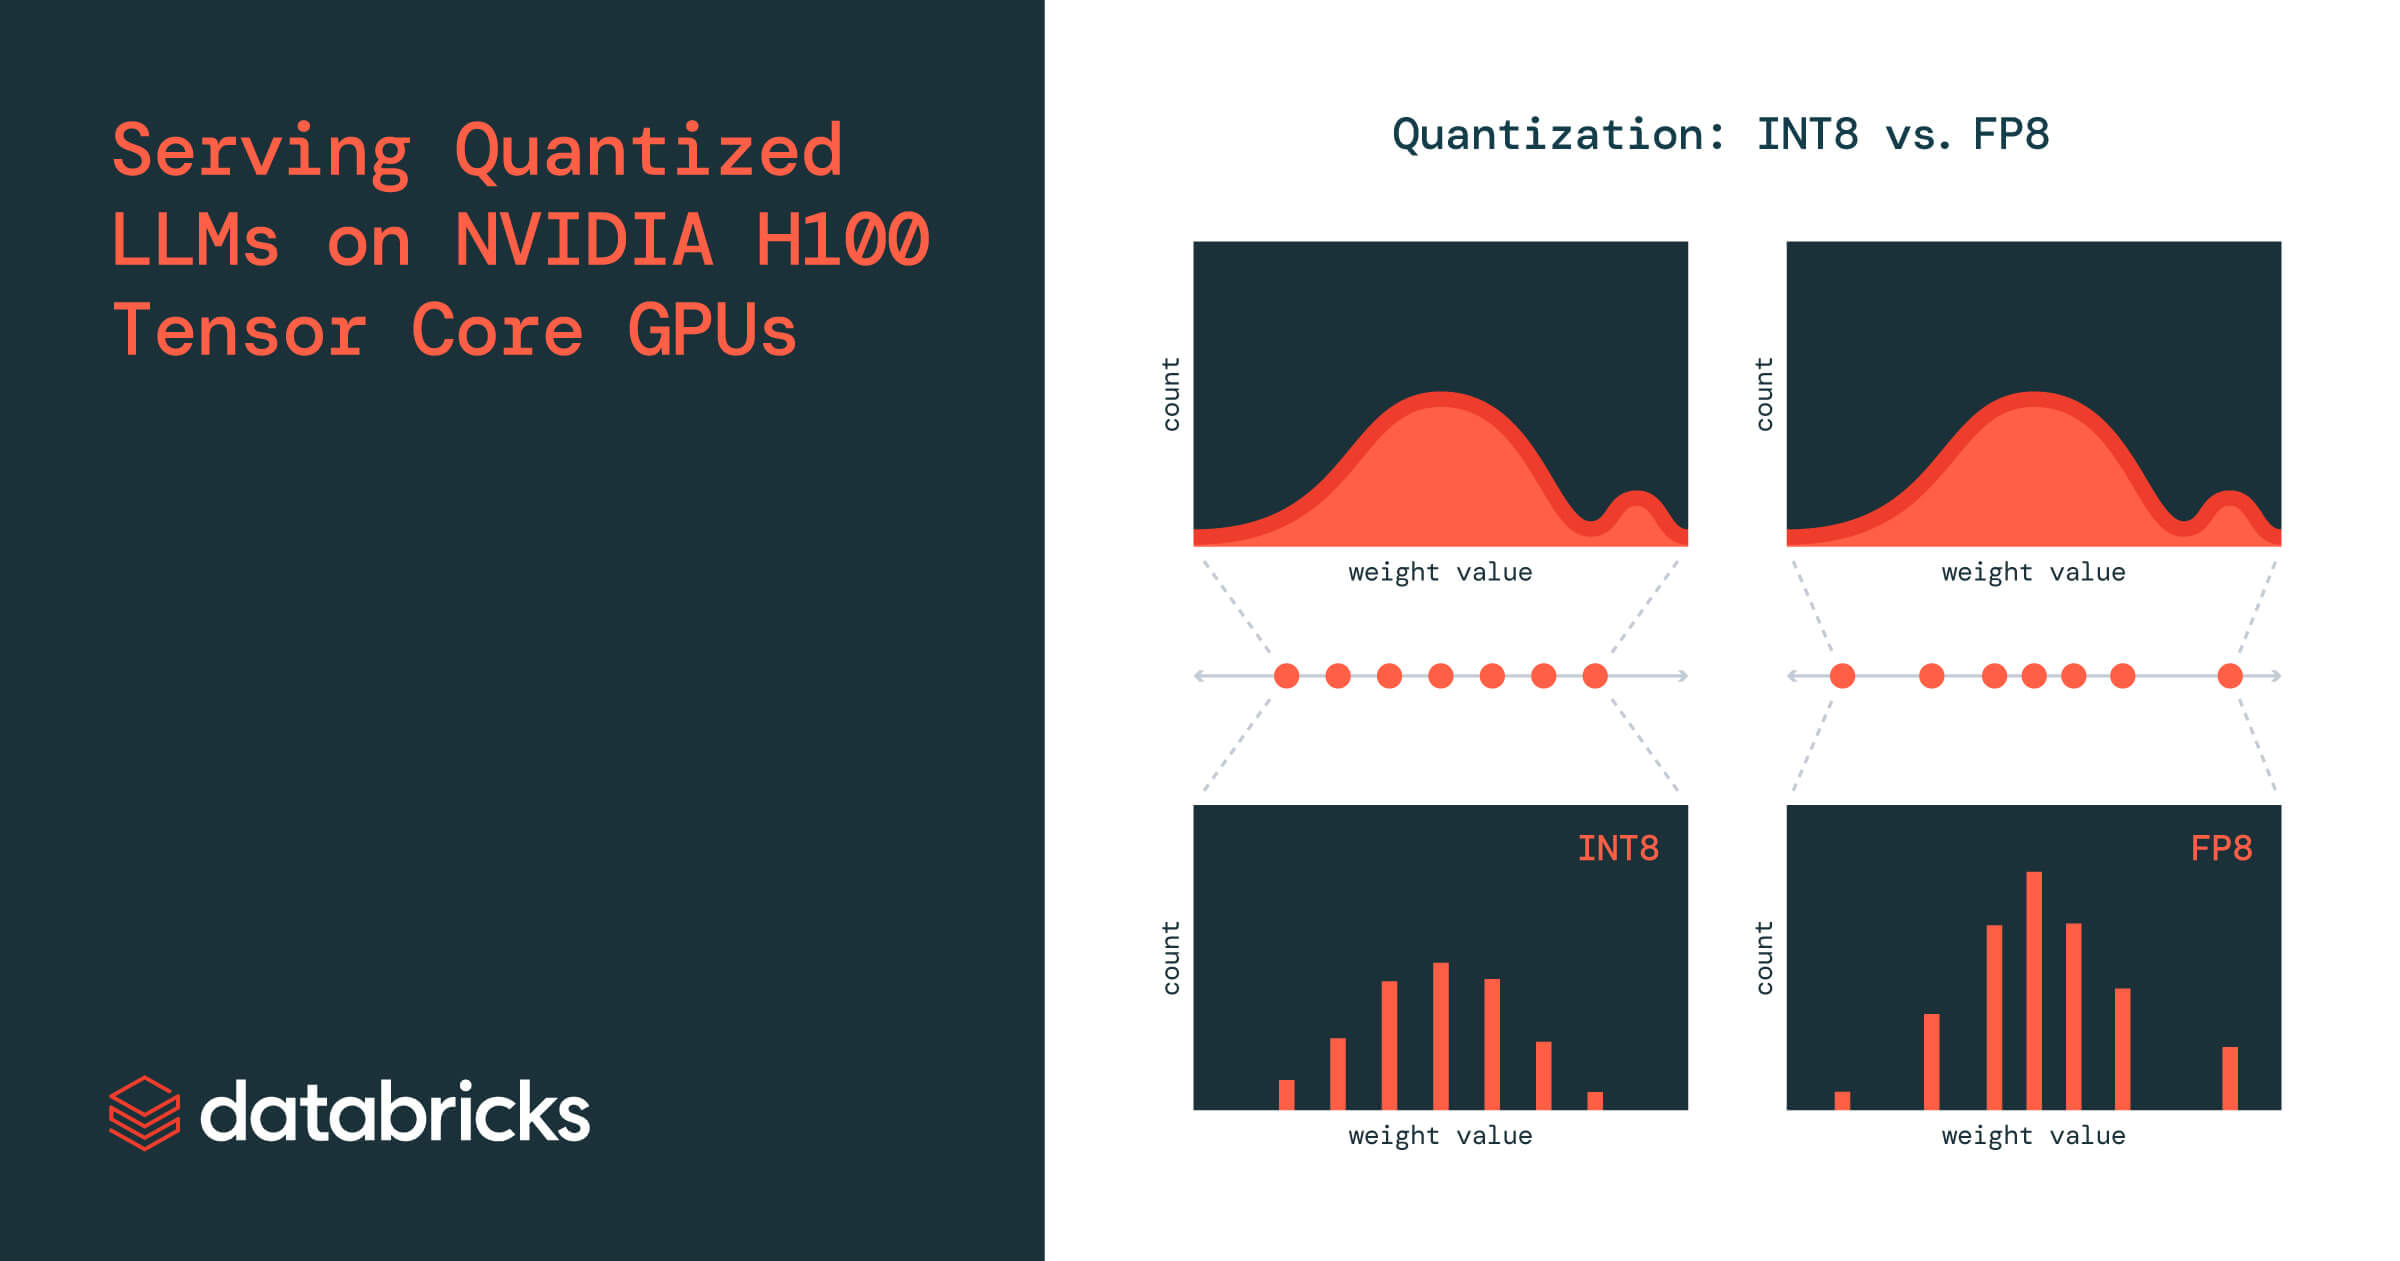
Serving Quantized LLMs on NVIDIA H100 Tensor Core GPUs | Databricks Blog
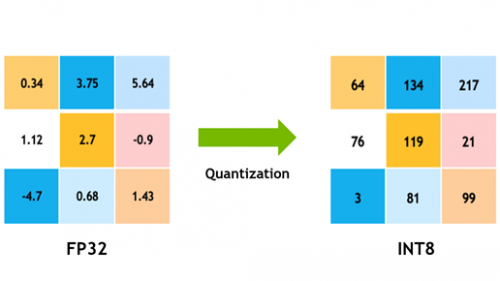
Optimizing LLMs for Performance and Accuracy with Post-Training ...

Optimizing LLMs for Performance and Accuracy with Post-Training ...