
Nvidia Tensorrt Inference With Onnx Ohye
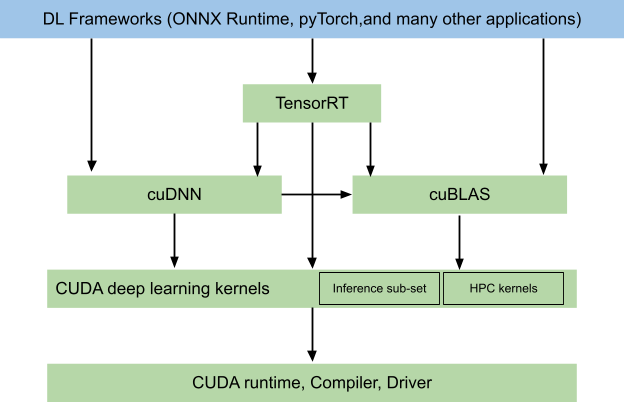
Nvidia Tensorrt Inference With Onnx – OHYE
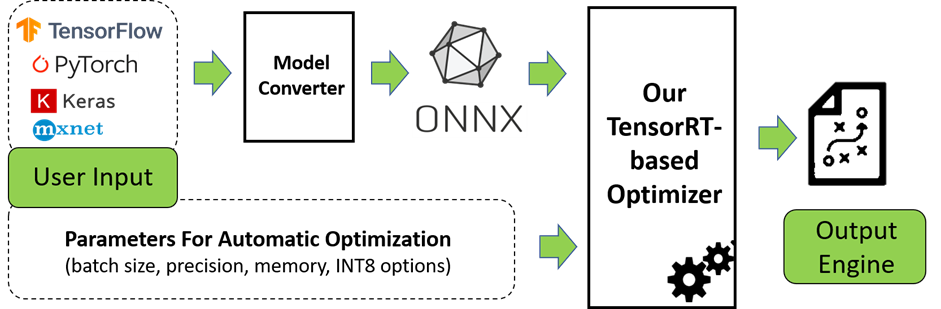
Nvidia Tensorrt Inference With Onnx – OHYE
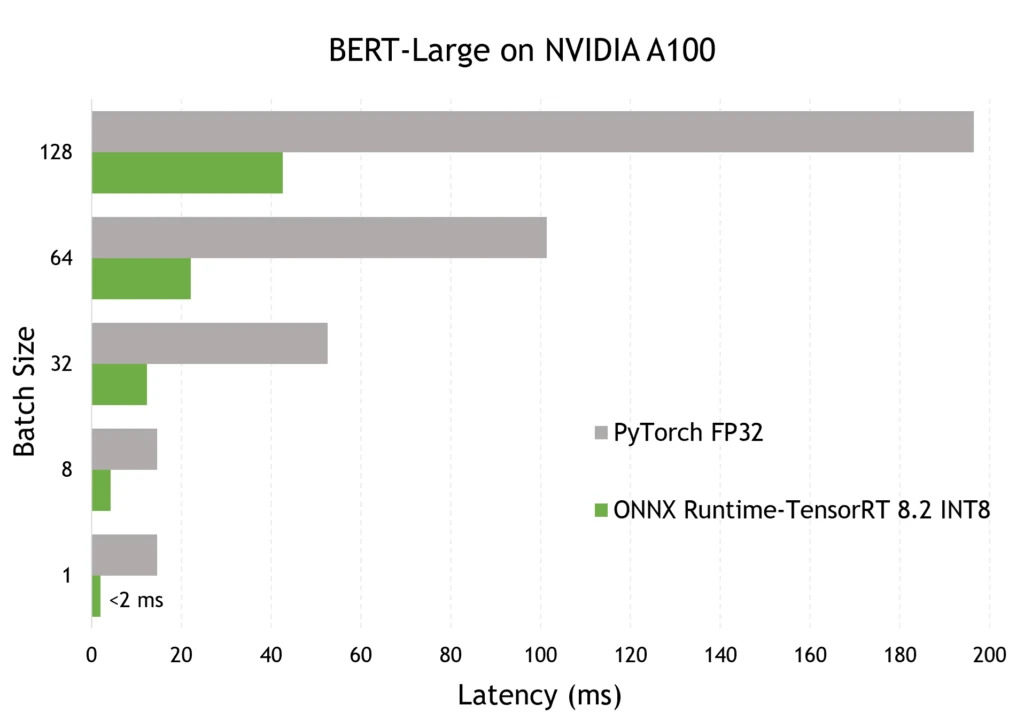
Nvidia Tensorrt Inference With Onnx – OHYE

Nvidia Tensorrt Inference With Onnx – OHYE

Nvidia Tensorrt Inference With Onnx – OHYE
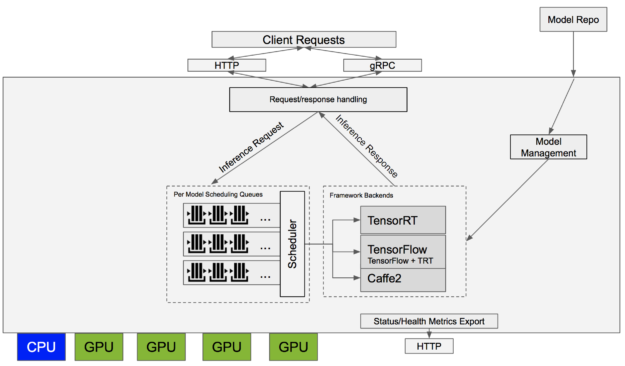
Deploy ONNX models with TensorRT Inference Serving | by zong fan | Medium

Using TensorRT with ONNX Models in Jetson Inference - Help Docs for ...
Boost inference speeds with NVIDIA TensorRT on UbiOps - UbiOps - AI ...
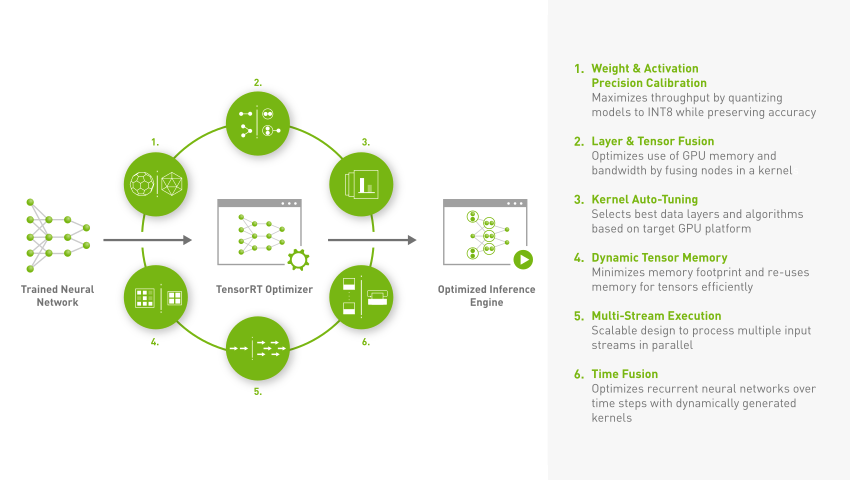
Boost inference speeds with NVIDIA TensorRT on UbiOps - UbiOps
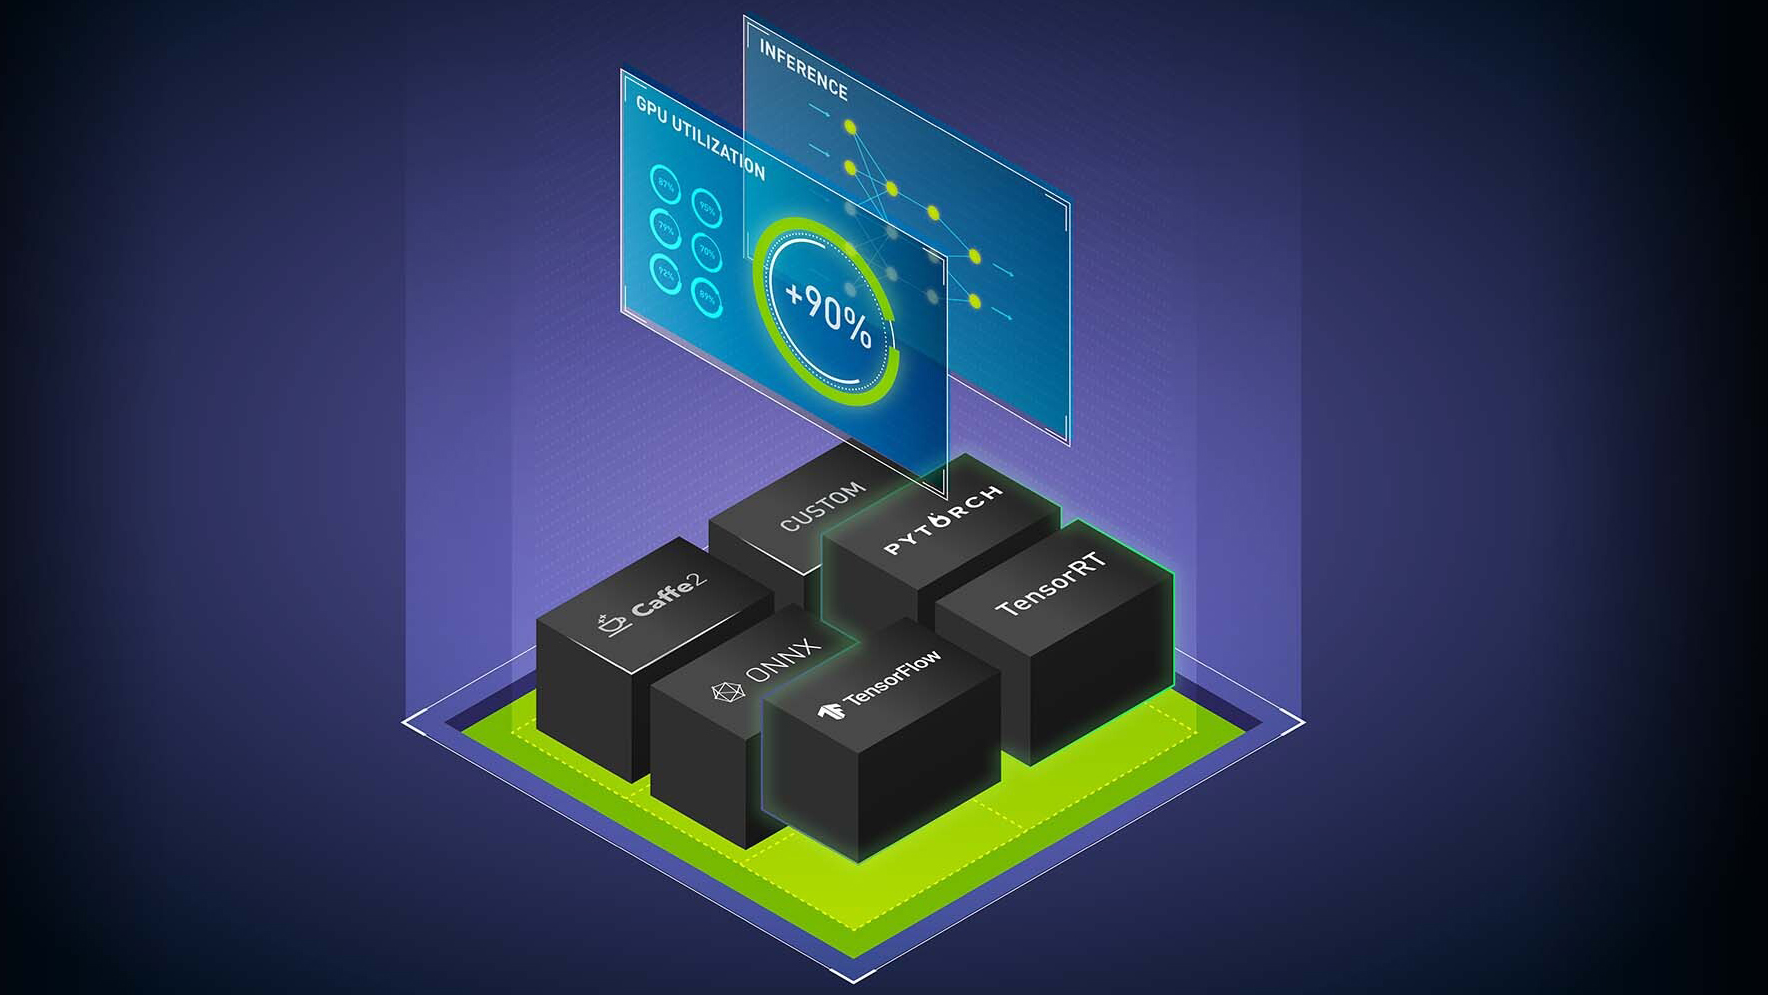
Power Your AI Inference with New NVIDIA Triton and NVIDIA TensorRT ...
Advertisement Space (300x250)

ONNX TensorRT Inference Gives wrong result - TensorRT - NVIDIA ...
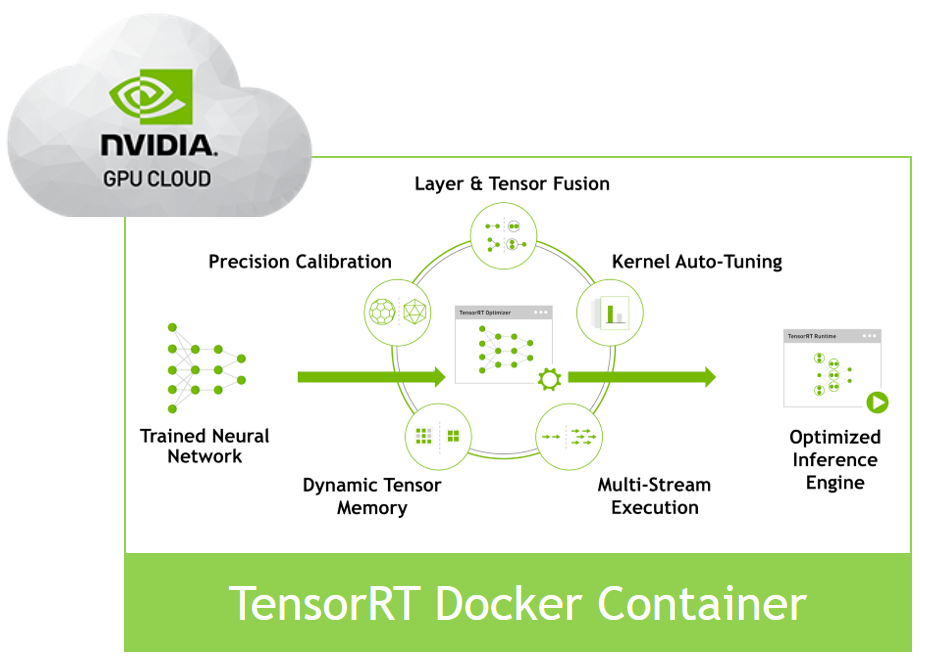
RESTful Inference with the TensorRT Container and NVIDIA GPU Cloud ...

ONNX TensorRT Inference Gives wrong result - TensorRT - NVIDIA ...
GTC 2020: TensorRT inference with TensorFlow 2.0 | NVIDIA Developer
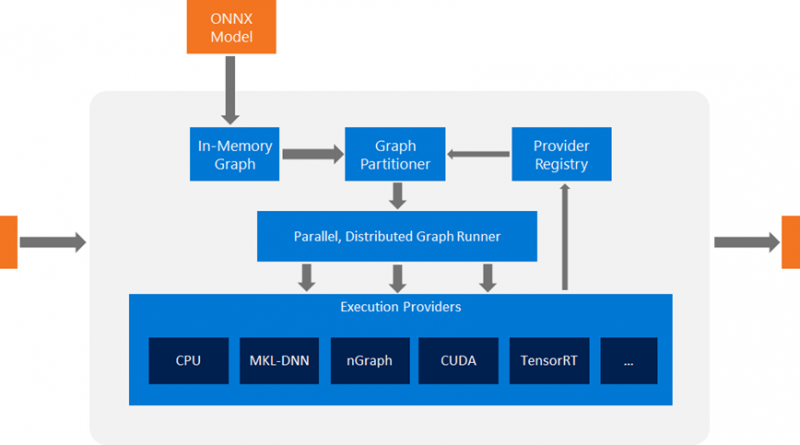
ONNX Runtime integration with NVIDIA TensorRT in preview | Mashford's ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

ONNX TensorRT Inference Gives wrong result - TensorRT - NVIDIA ...
Power Your AI Inference with New NVIDIA Triton and NVIDIA TensorRT ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...
TensorRT vs. ONNX Runtime | Inference Engine Comparison | Inference Systems
Advertisement Space (336x280)
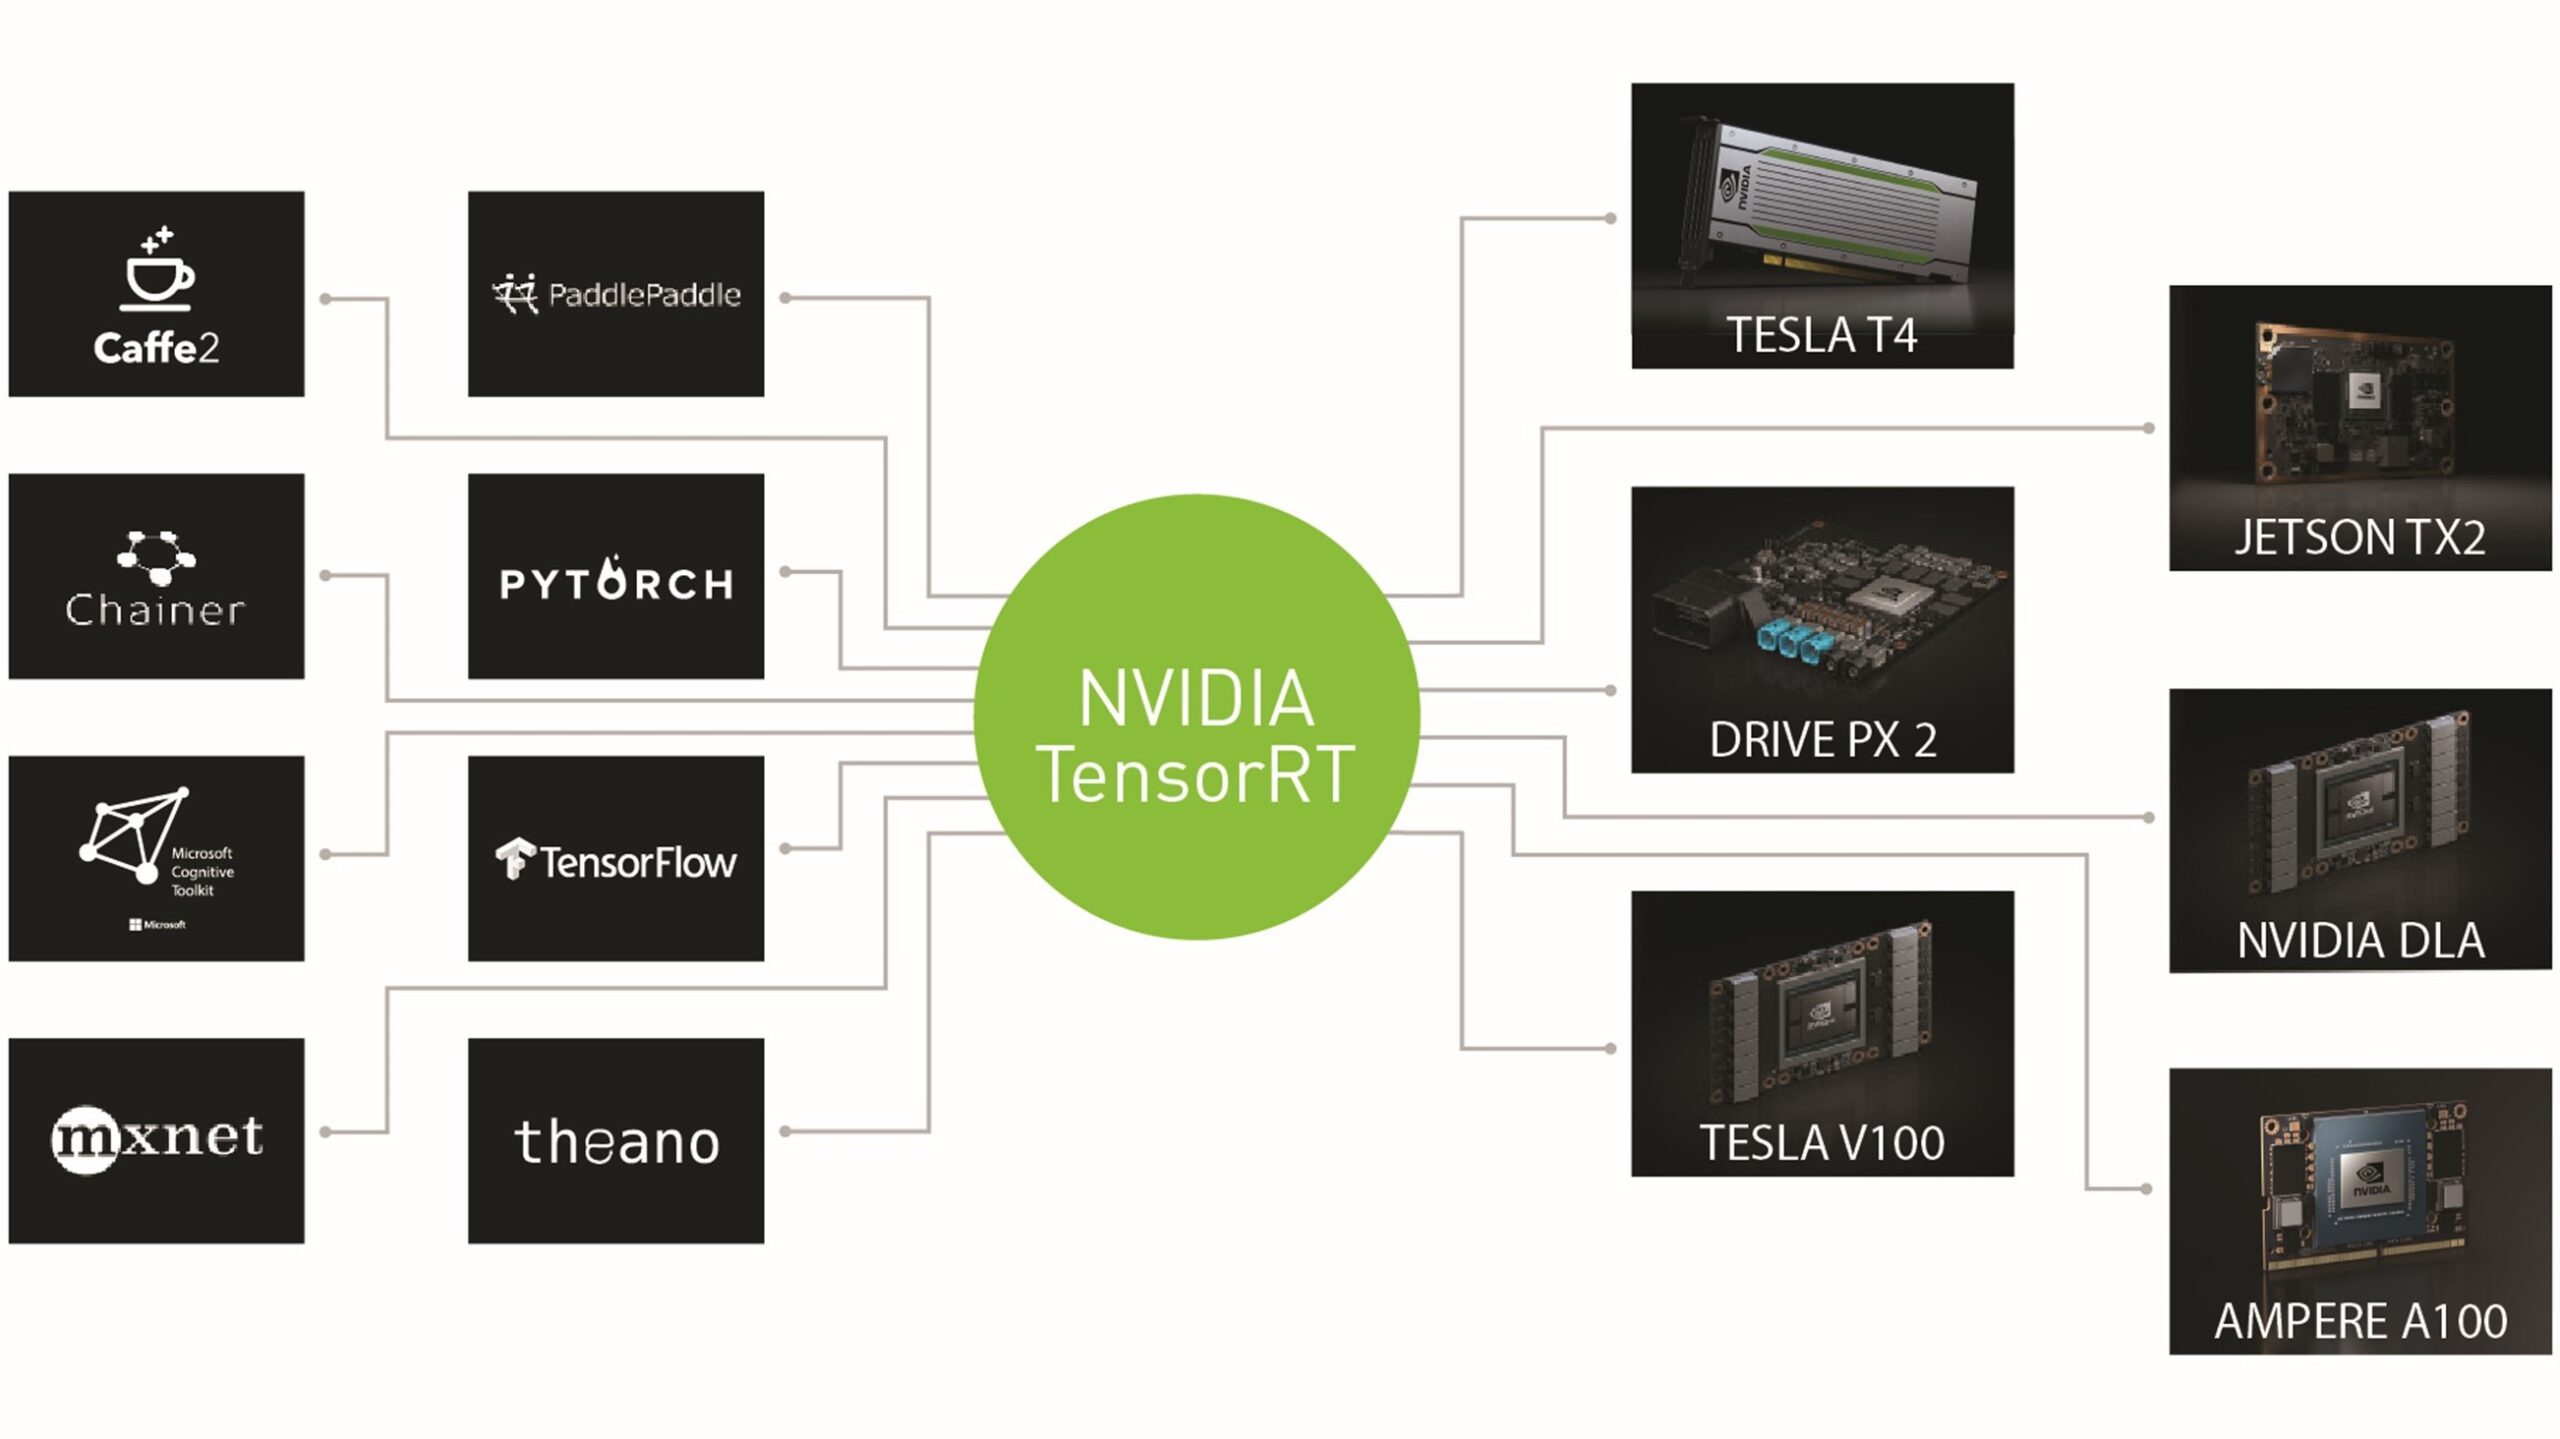
Incorrect inference results after converting from ONNX to TRT with ...
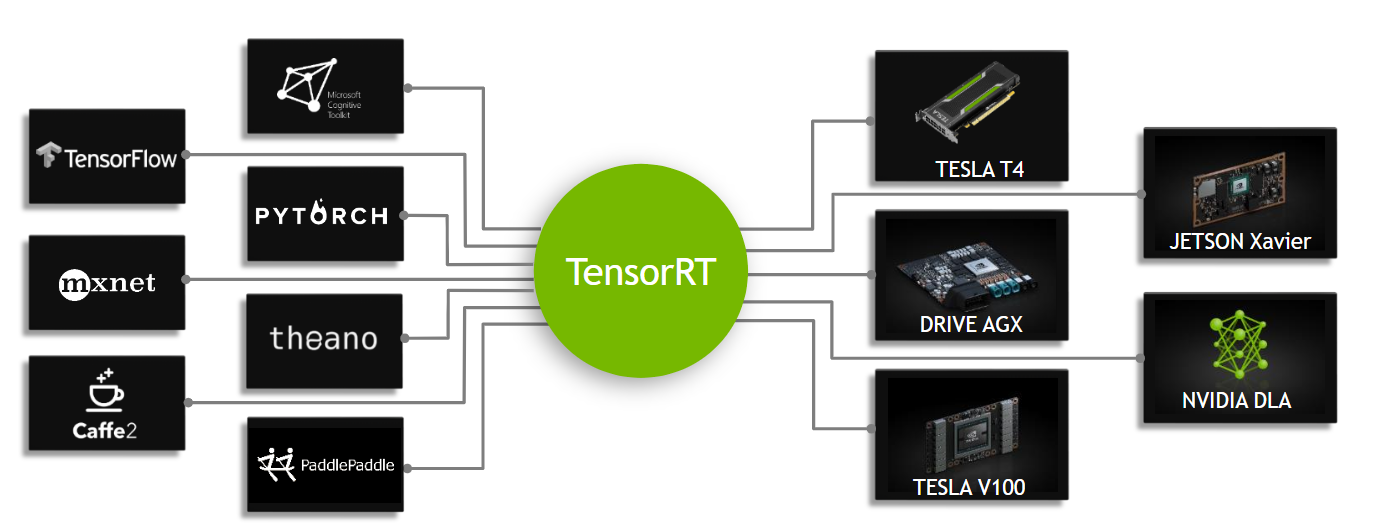
Tensorrt Onnx Inference – Onnx Inference Examples – ZNTBGH

Estimating Depth with ONNX Models and Custom Layers Using NVIDIA ...

NVIDIA TensorRT for RTX Introduces an Optimized Inference AI Library on ...

Estimating Depth with ONNX Models and Custom Layers Using NVIDIA ...
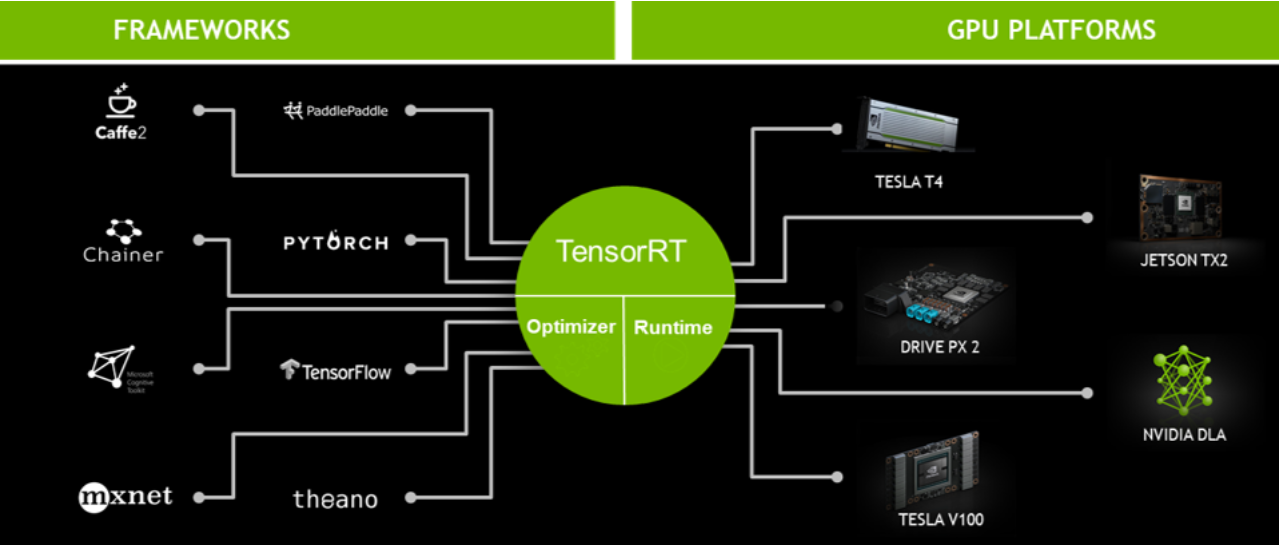
NVIDIA TensorRT – Inference 최적화 및 가속화를 위한 NVIDIA의 Toolkit - NVIDIA ...

NVIDIA TensorRT for RTX Introduces an Optimized Inference AI Library on ...
Failed converting ONNX model to TensorRT model · Issue #2039 · NVIDIA ...
Tensorflow V2 object detection onnx to tensorrt · Issue #1412 · NVIDIA ...
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime
Advertisement Space (336x280)
How TensorRT Works: Deep Dive into NVIDIA Inference Optimization Engine ...
Inconsistent results between TensorRT and ONNX · Issue #3850 · NVIDIA ...
Int8 Inference in C++ TensorRT API without Onnx Model · Issue #659 ...

Boost Llama 3.3 70B Inference Throughput 3x with NVIDIA TensorRT-LLM ...

TensorRT ONNX error - TensorRT - NVIDIA Developer Forums

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...