
Onnx Vs Tensorrt Vs Tflite Choosing Your Ml Inference
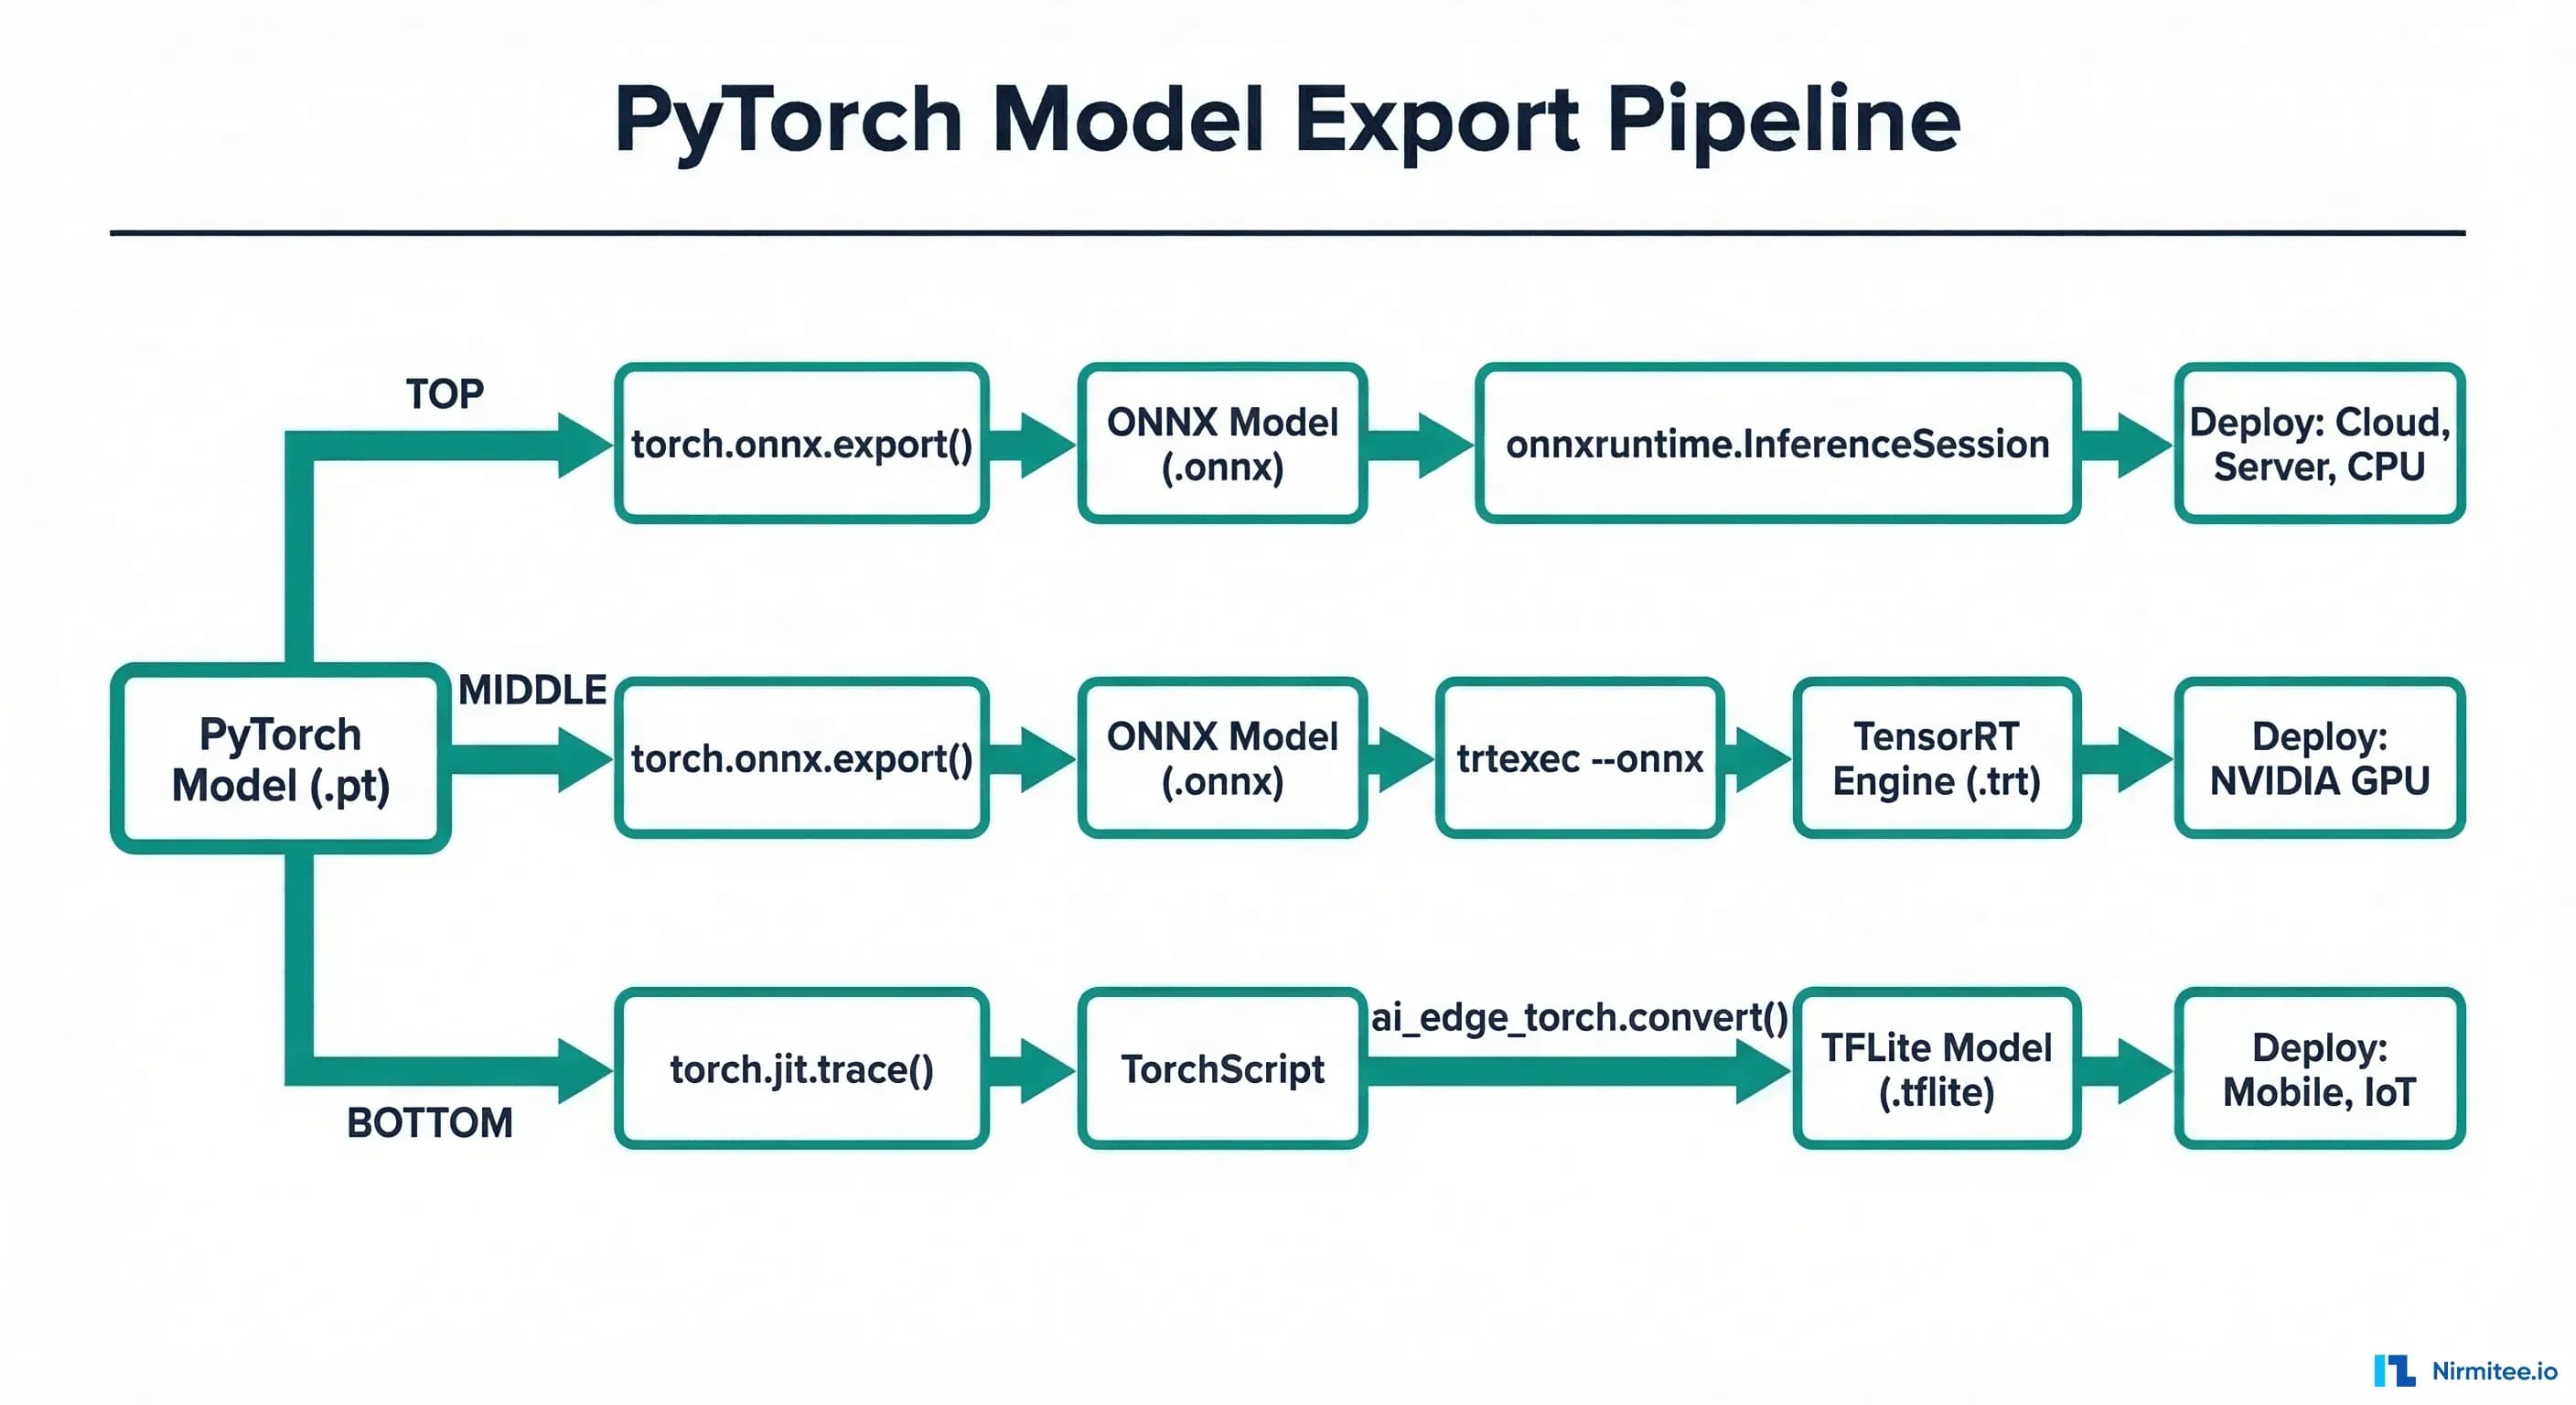
ONNX vs TensorRT vs TFLite: Choosing Your ML Inference
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime

AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime
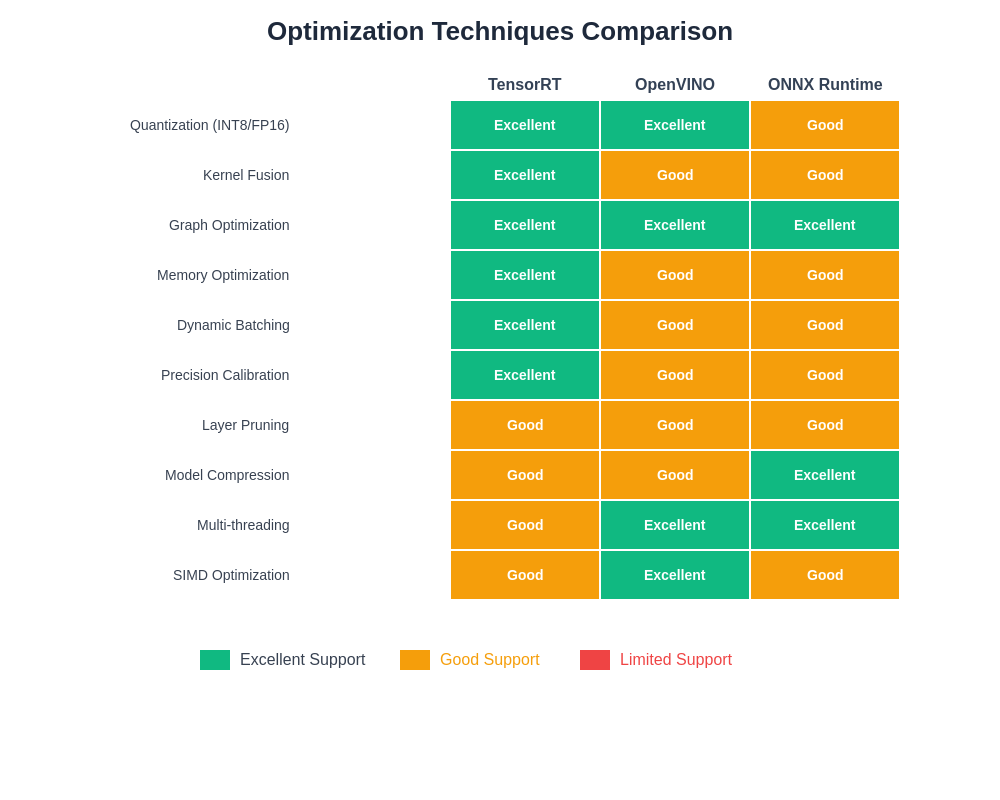
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime
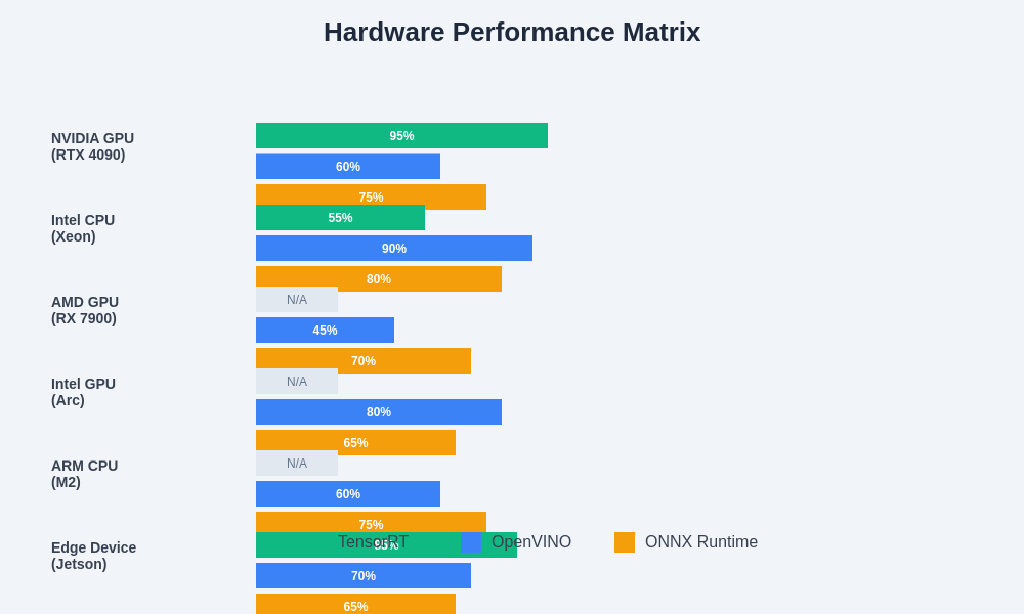
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime

PyTorch 2.0 vs ONNX vs TensorRT 비교

TensorRT vs vLLM: The Complete Guide to LLM Inference Engines
Best LLM Inference Engine? TensorRT vs vLLM vs LMDeploy vs MLC-LLM ...

vLLM vs SGLang vs TensorRT-LLM vs Ollama: Choosing an Inference Engine ...
TensorRT vs. ONNX Runtime | Inference Engine Comparison | Inference Systems
Advertisement Space (300x250)

vLLM vs TensorRT-LLM: Which Inference Engine Should You Use in 2026 ...

TGI vs. TensorRT LLM: Choosing the Best Inference Library for Large ...
Using TensorRT with ONNX Models in Jetson Inference - Help Docs for ...

Hardware List: OpenVINO vs ONNX Runtime vs WinML Analysis

Onnx Vs Pytorch Speed: In-Depth Performance Comparison – EEKJRM

Battle of the Lightweight AI Engines: TensorFlow Lite vs ONNX Runtime ...
High performance ML inference with NVIDIA TensorRT
Choosing Your Engine for LLM Inference: The Ultimate vLLM vs. TensorRT ...
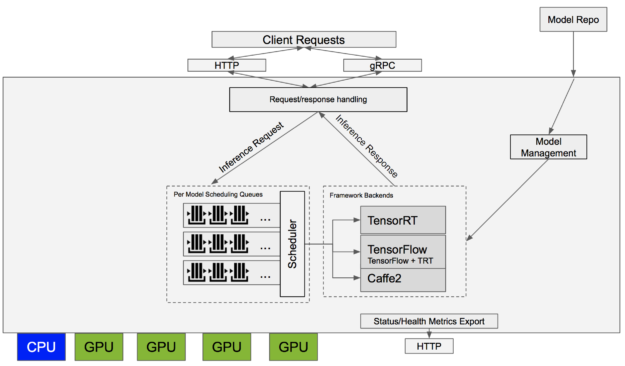
Deploy ONNX models with TensorRT Inference Serving | by zong fan | Medium

The Great LLM Inference Showdown: TensorRT-LLM vs vLLM Technical Comparison
Advertisement Space (336x280)

10 TensorRT & ONNX Runtime Tricks for Snappy Inference | by Syntal | Medium
ONNX vs TensorRT: Which Format Is Best for Model Inference?
LLM Inference Battle: vLLM vs. TensorRT-LLM vs. Hugging Face TGI vs ...
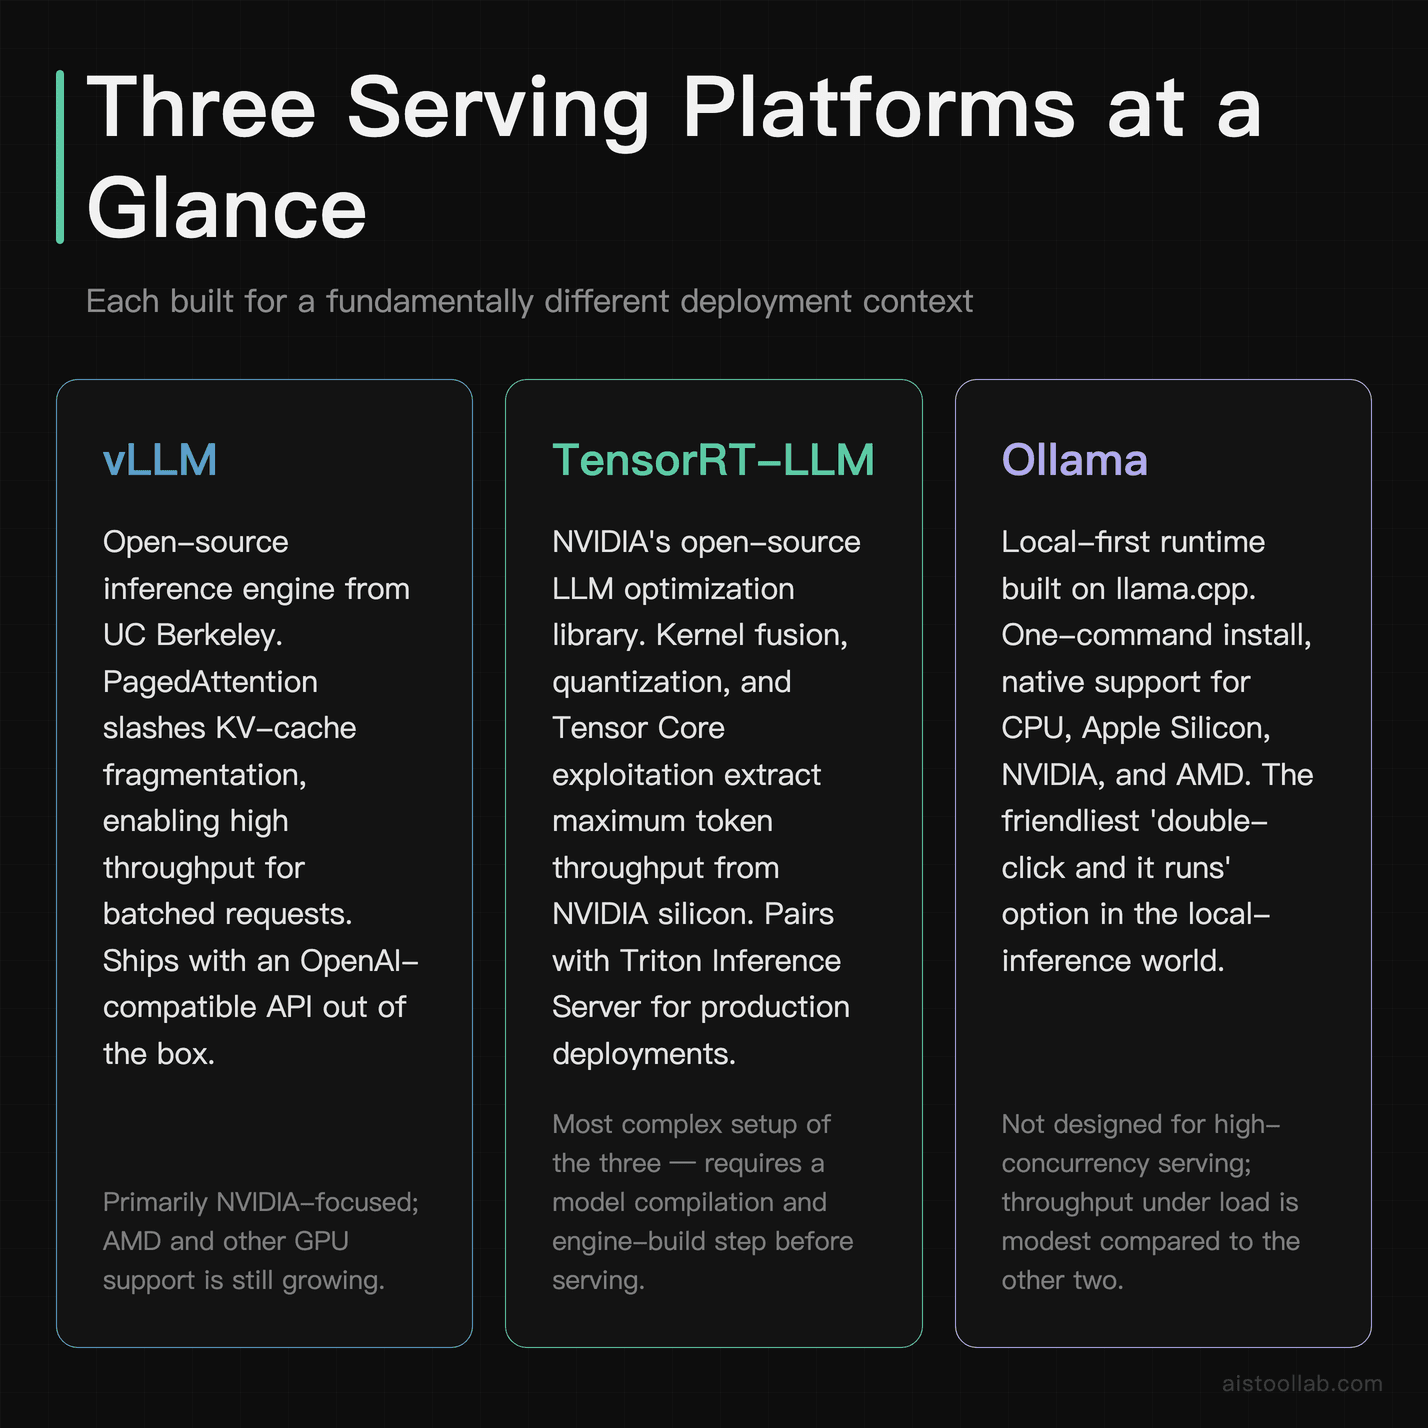
LLM Serving Cost 2026: vLLM vs TensorRT vs Ollama?
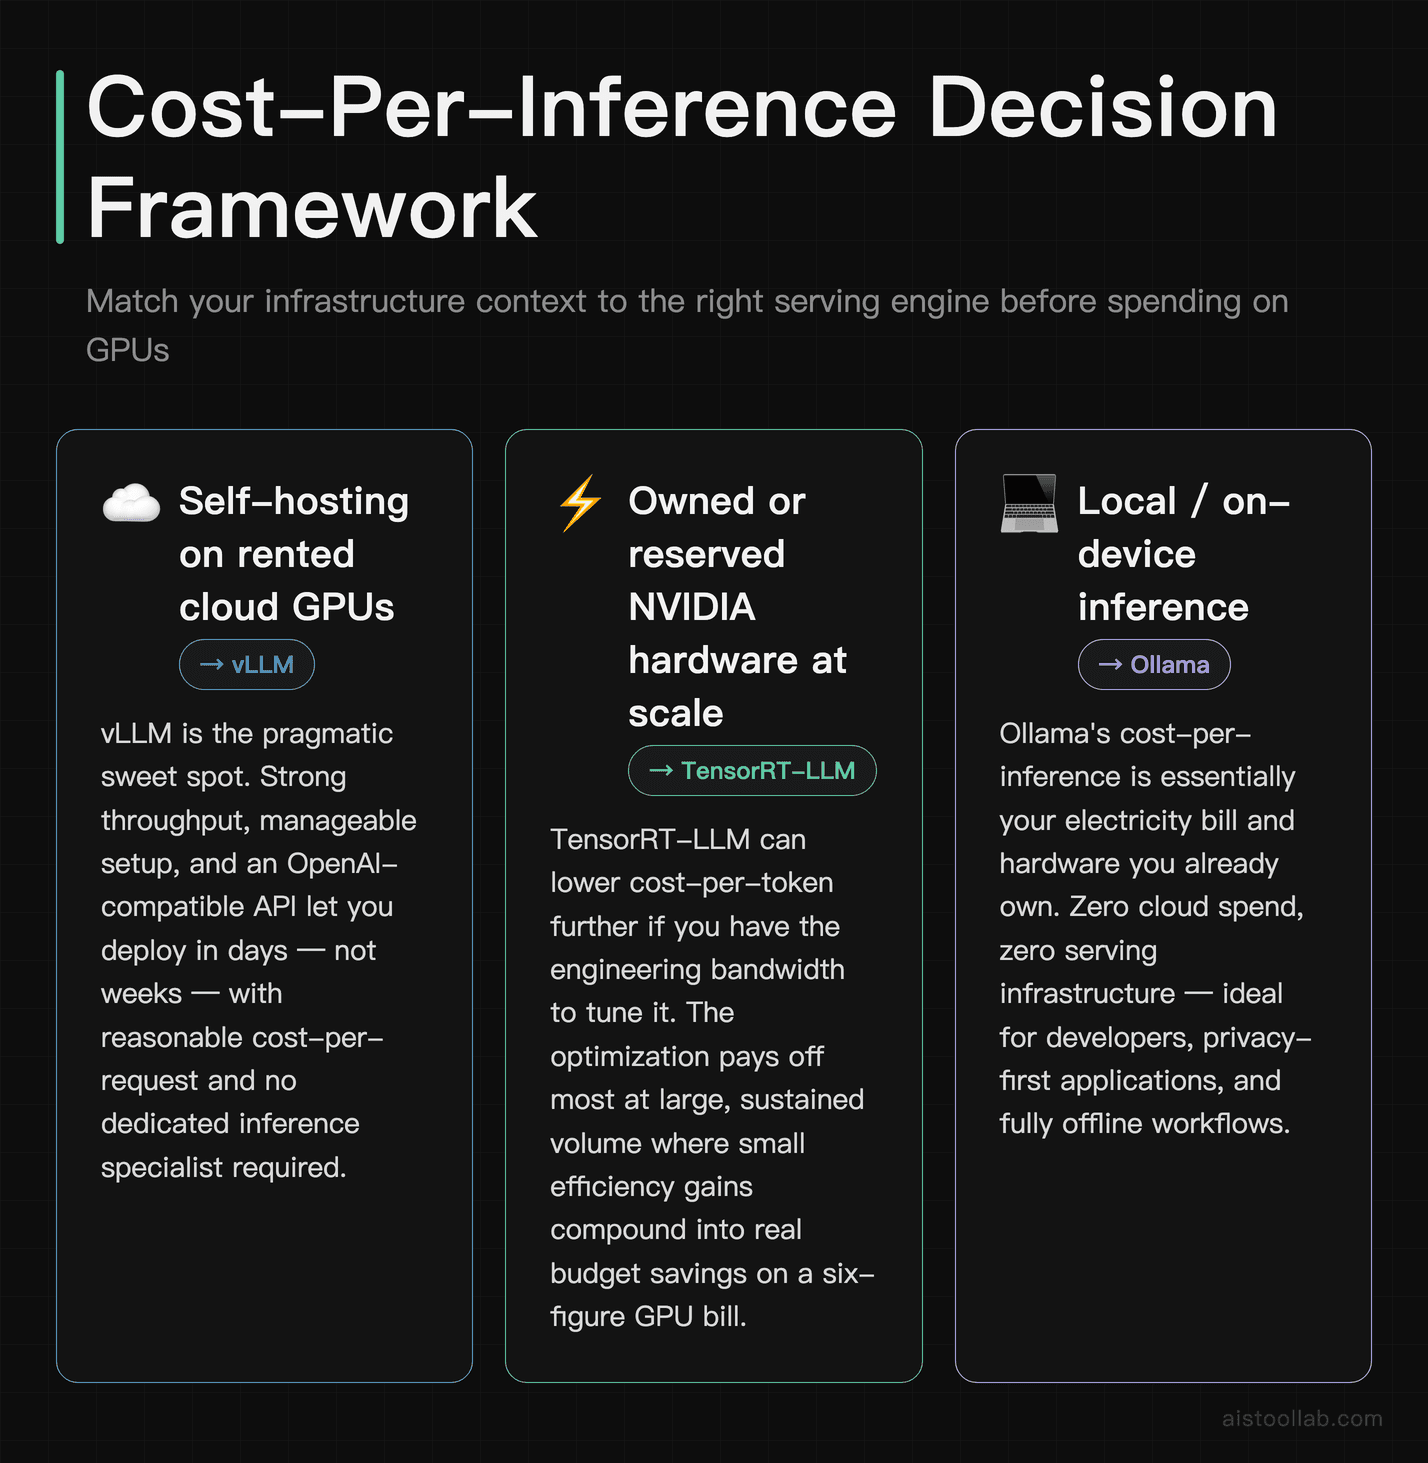
LLM Serving Cost 2026: vLLM vs TensorRT vs Ollama?
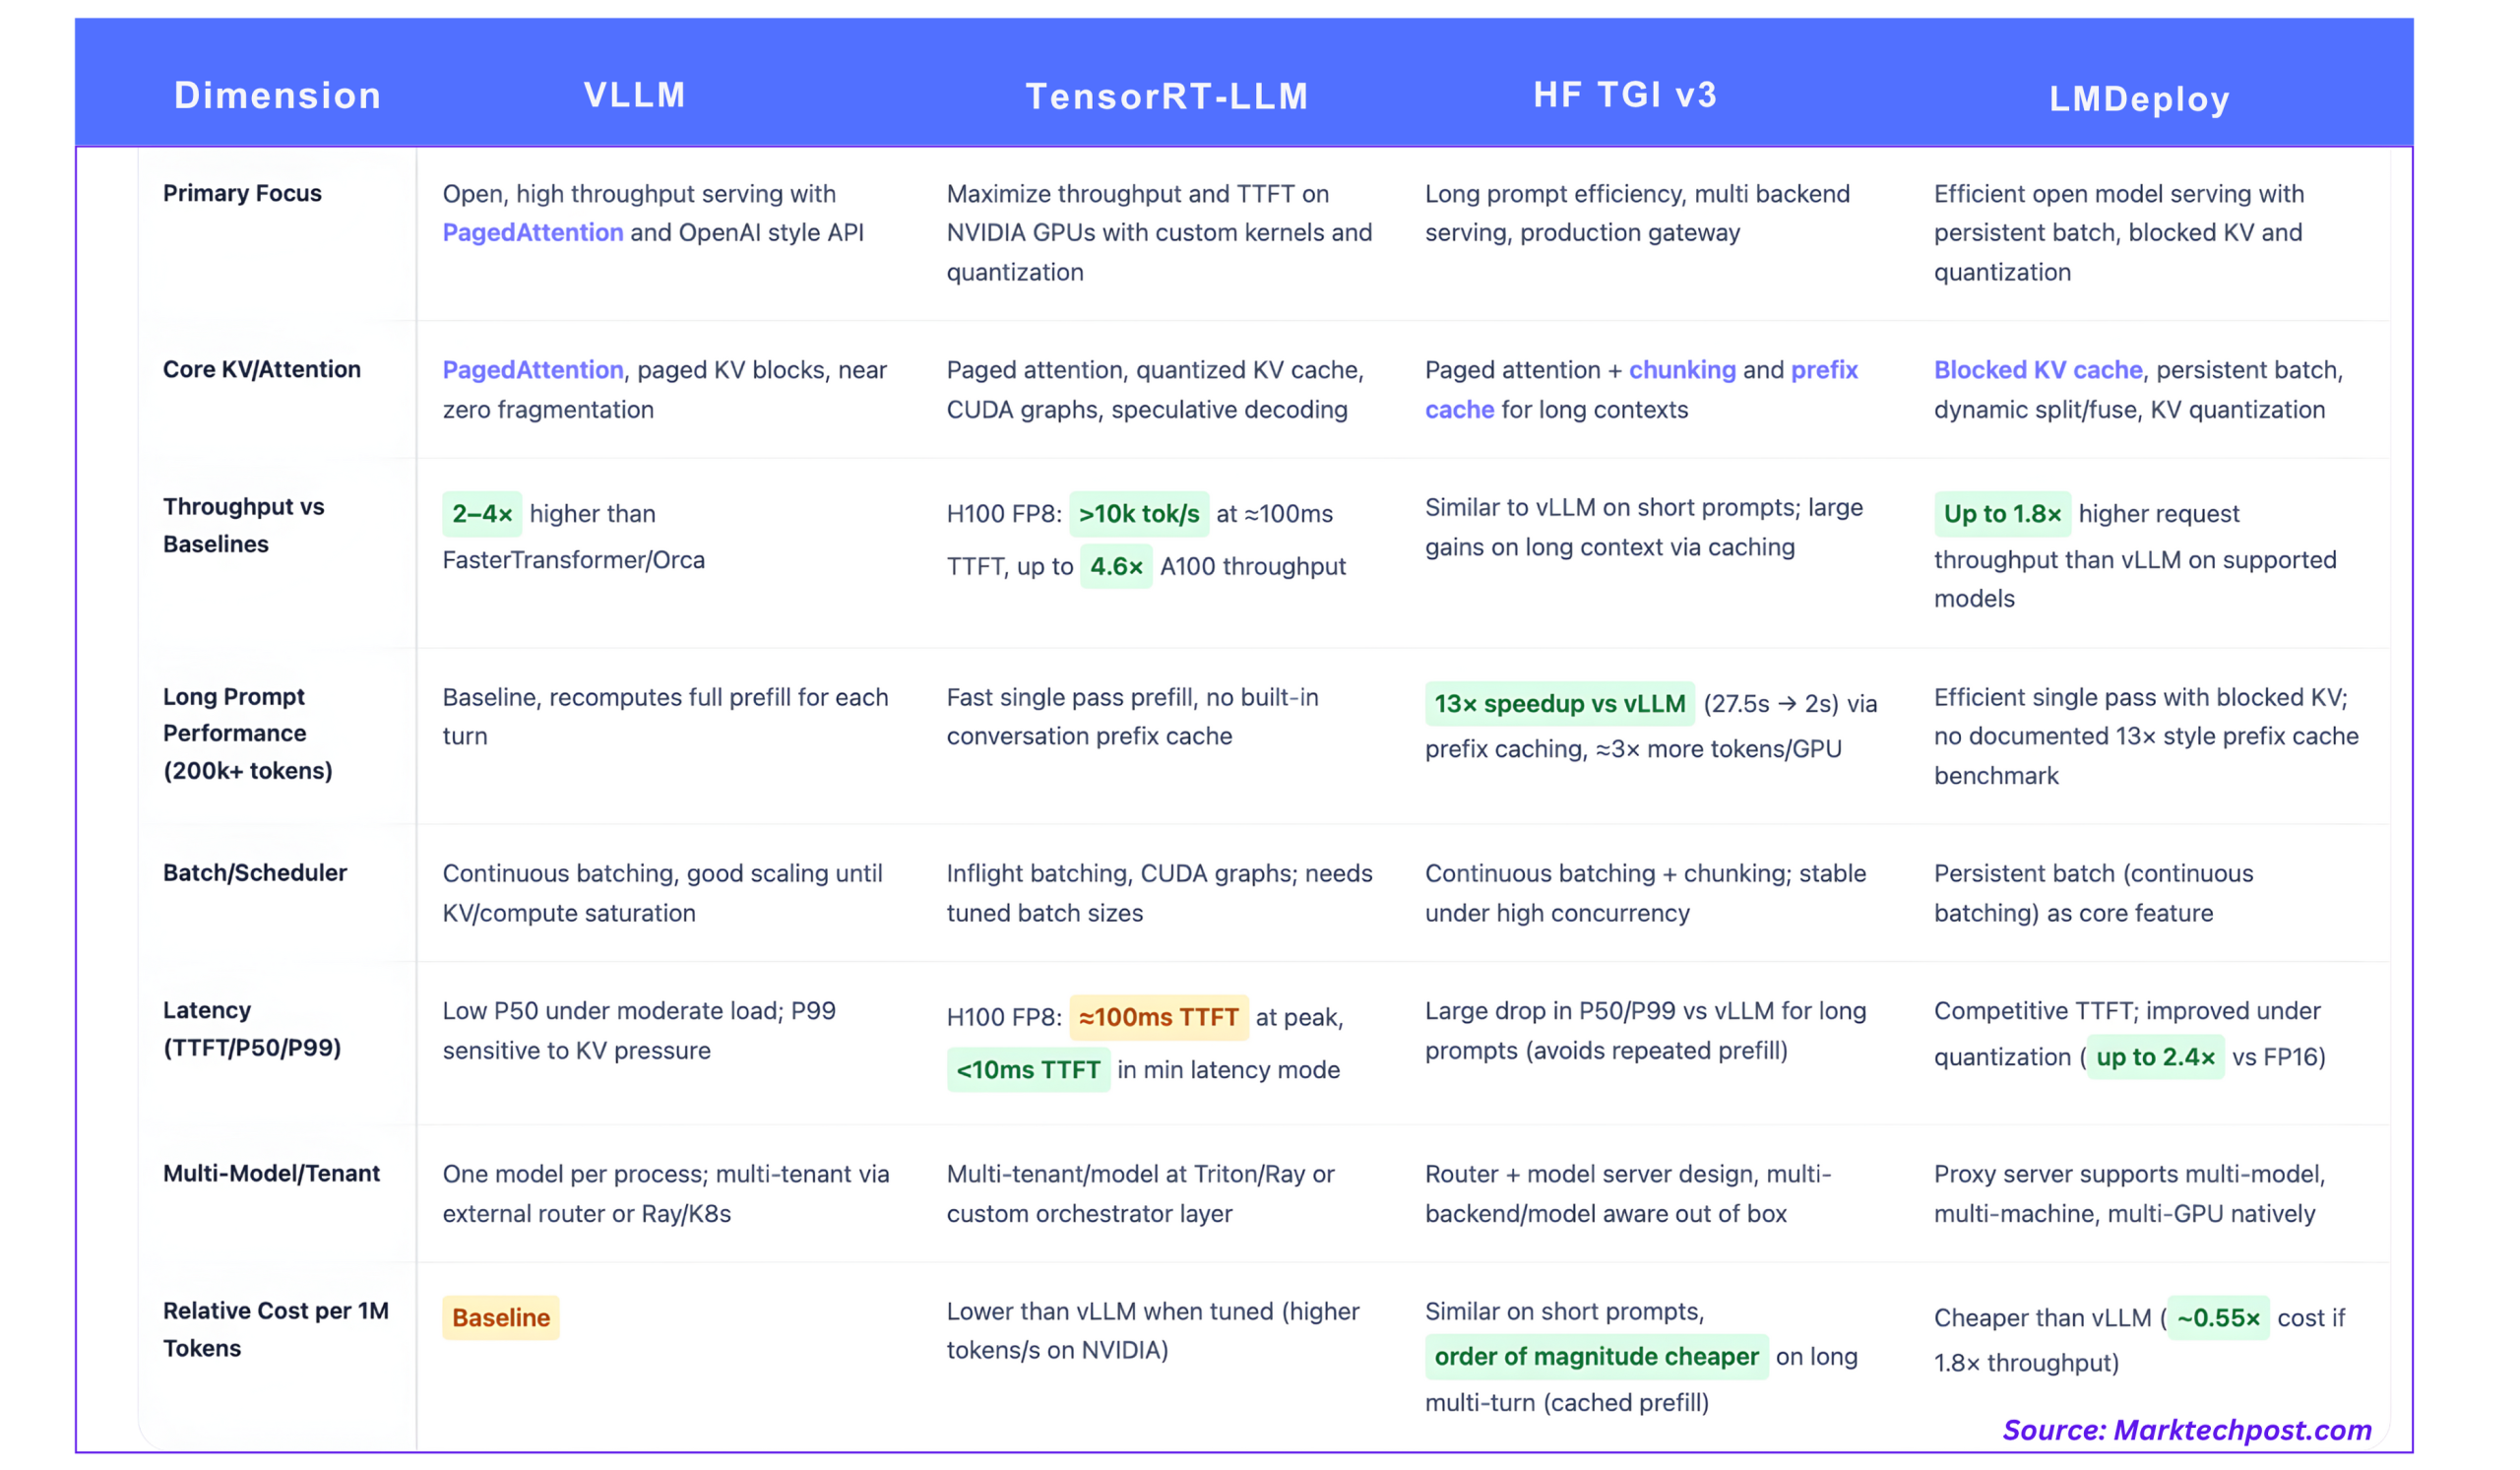
vLLM vs TensorRT-LLM vs HF TGI vs LMDeploy, A Deep Technical ...

Improving on-device ML inference performance with compilers - Fluendo
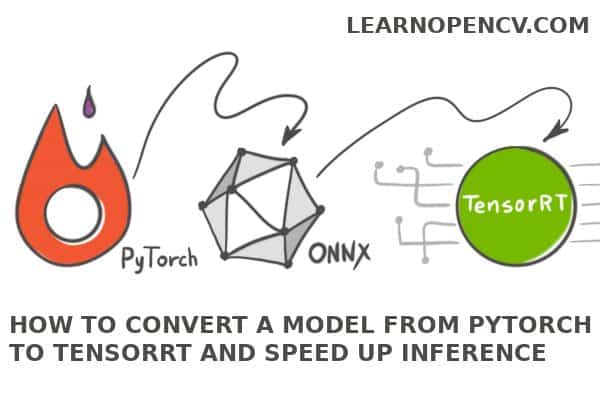
How to Convert a Model from PyTorch to TensorRT and Speed Up Inference ...
GitHub - parlaynu/inference-tensorrt: Convert ONNX models to TensorRT ...
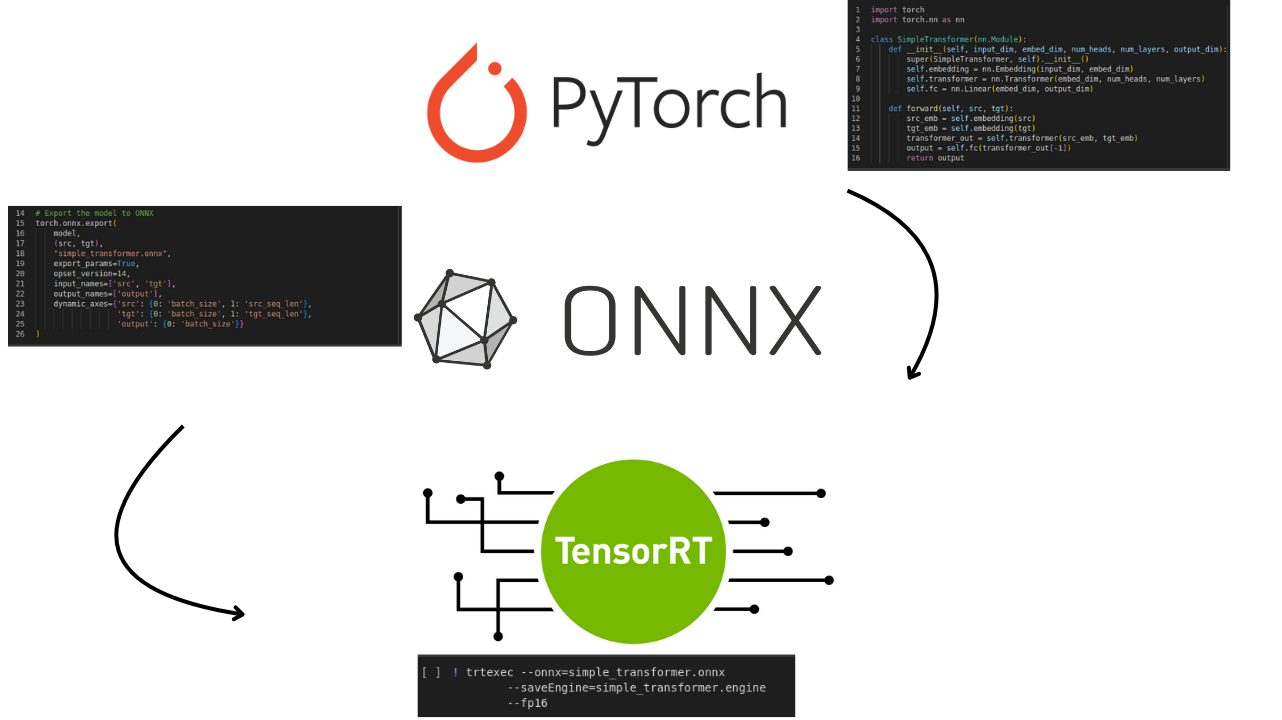
The Beginner’s Guide: CPU Inference Optimization with ONNX (99.8% TF ...
Advertisement Space (336x280)

vLLM vs TensorRT-LLM vs HF TGI vs LMDeploy, A Deep Technical ...
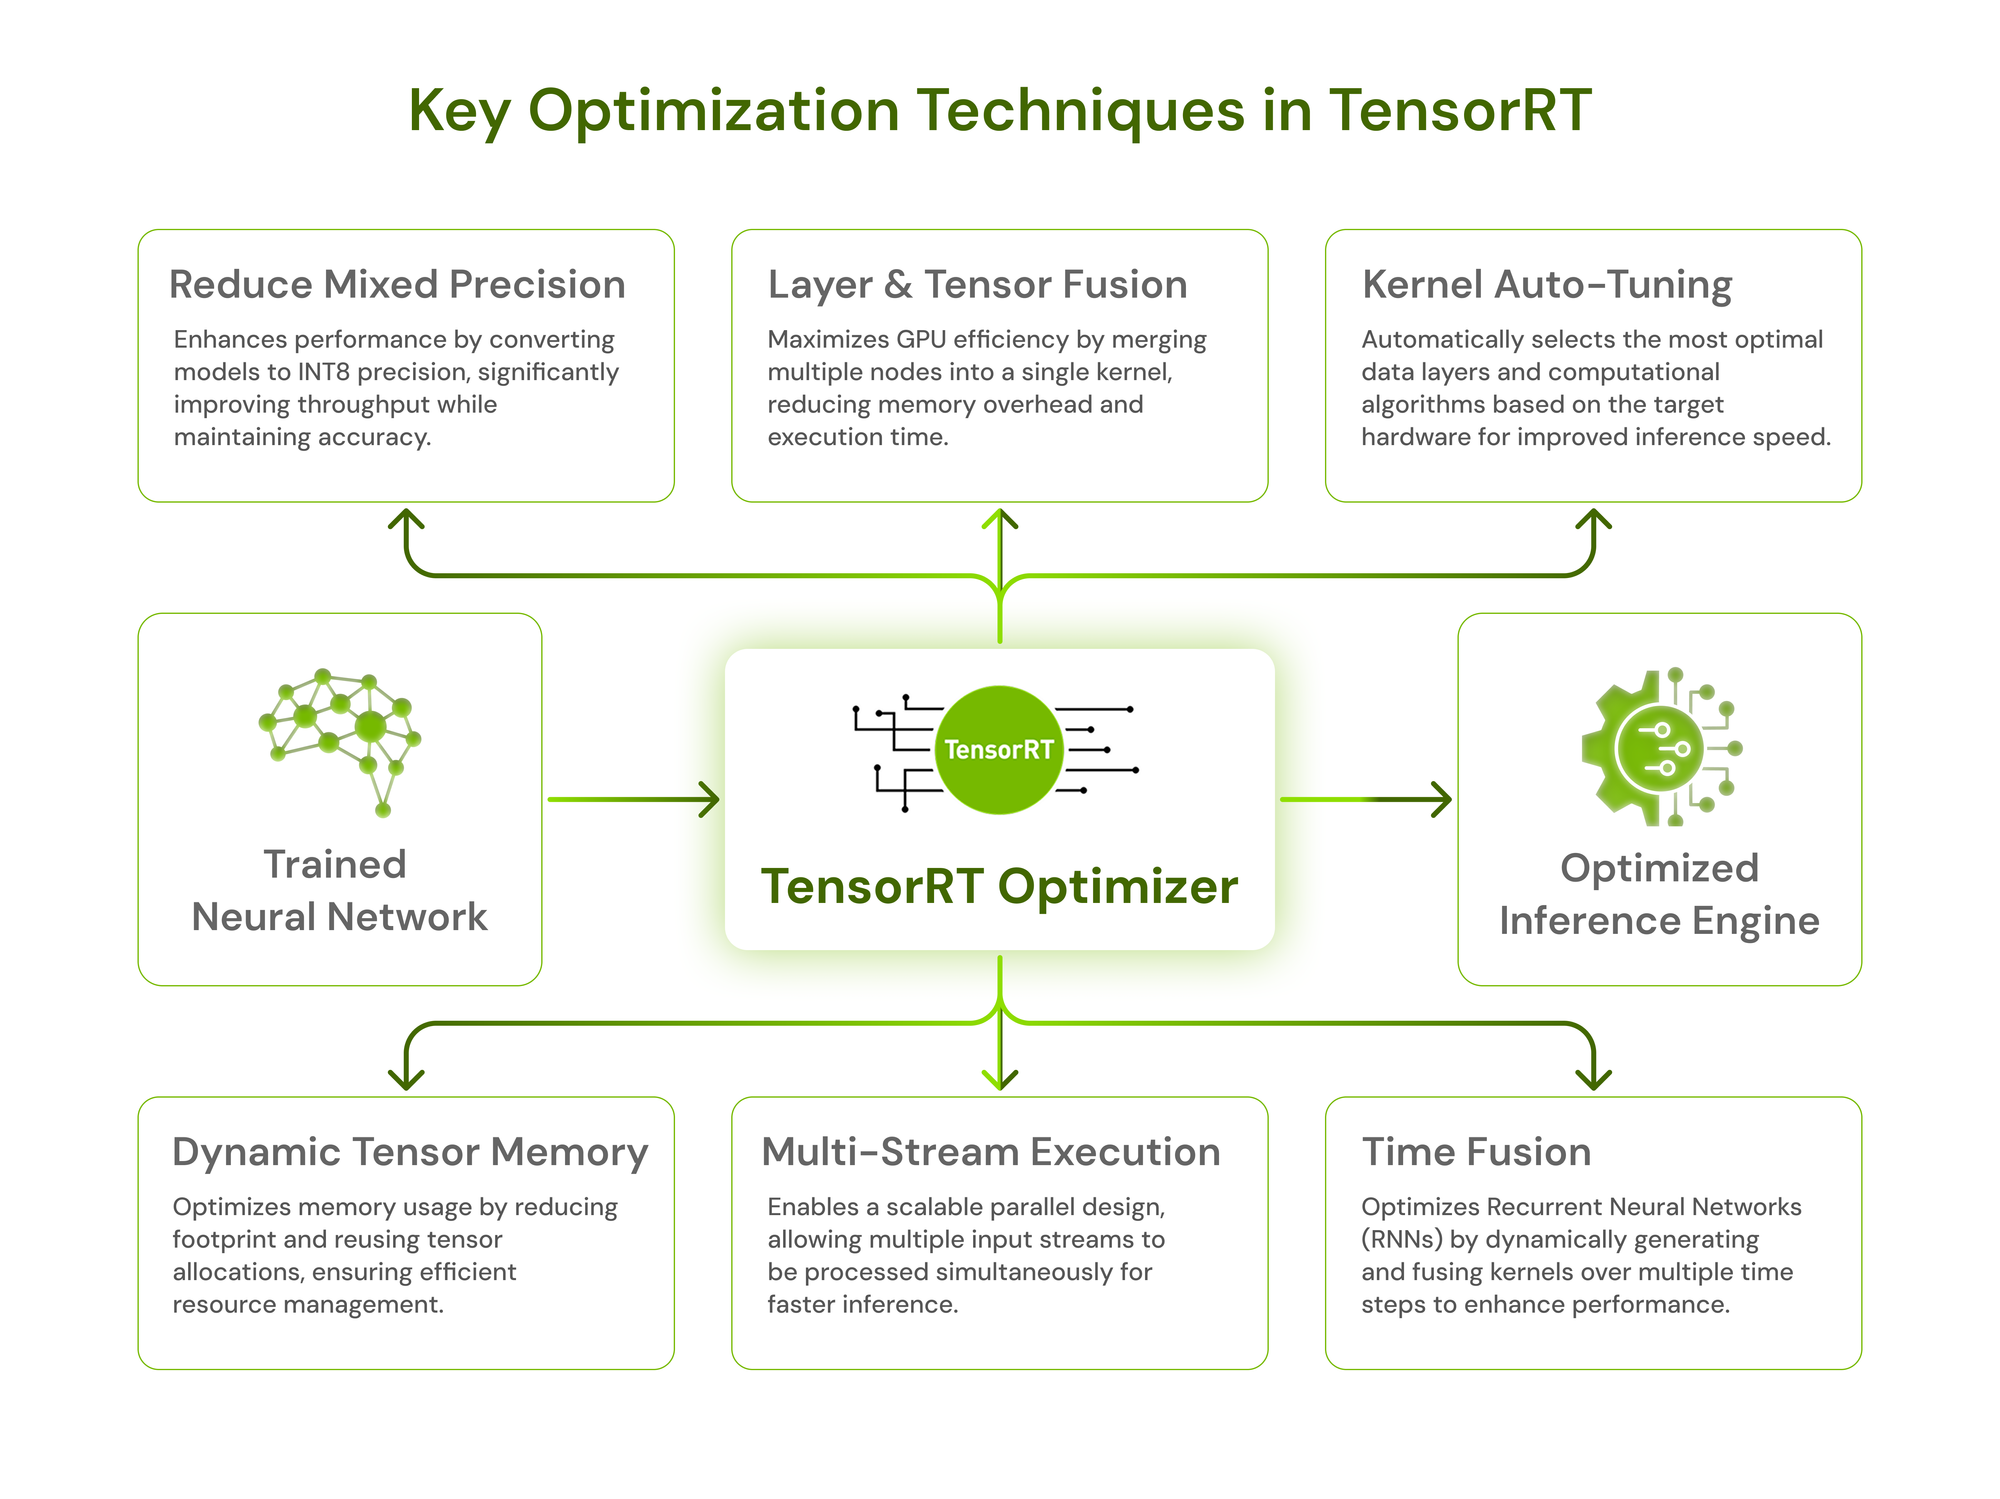
How to optimize inference using TensorRT on Jetson AGX Orin
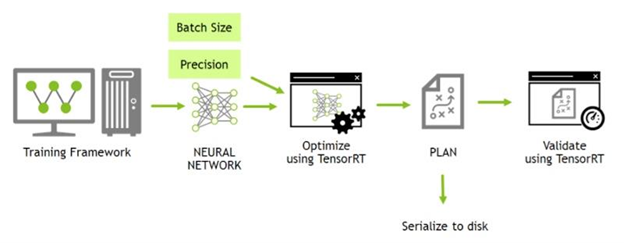
一文吃透 TensorRT 实战:从 ONNX 到 Engine,再到高性能推理落地_onnx和engine模型-CSDN博客

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
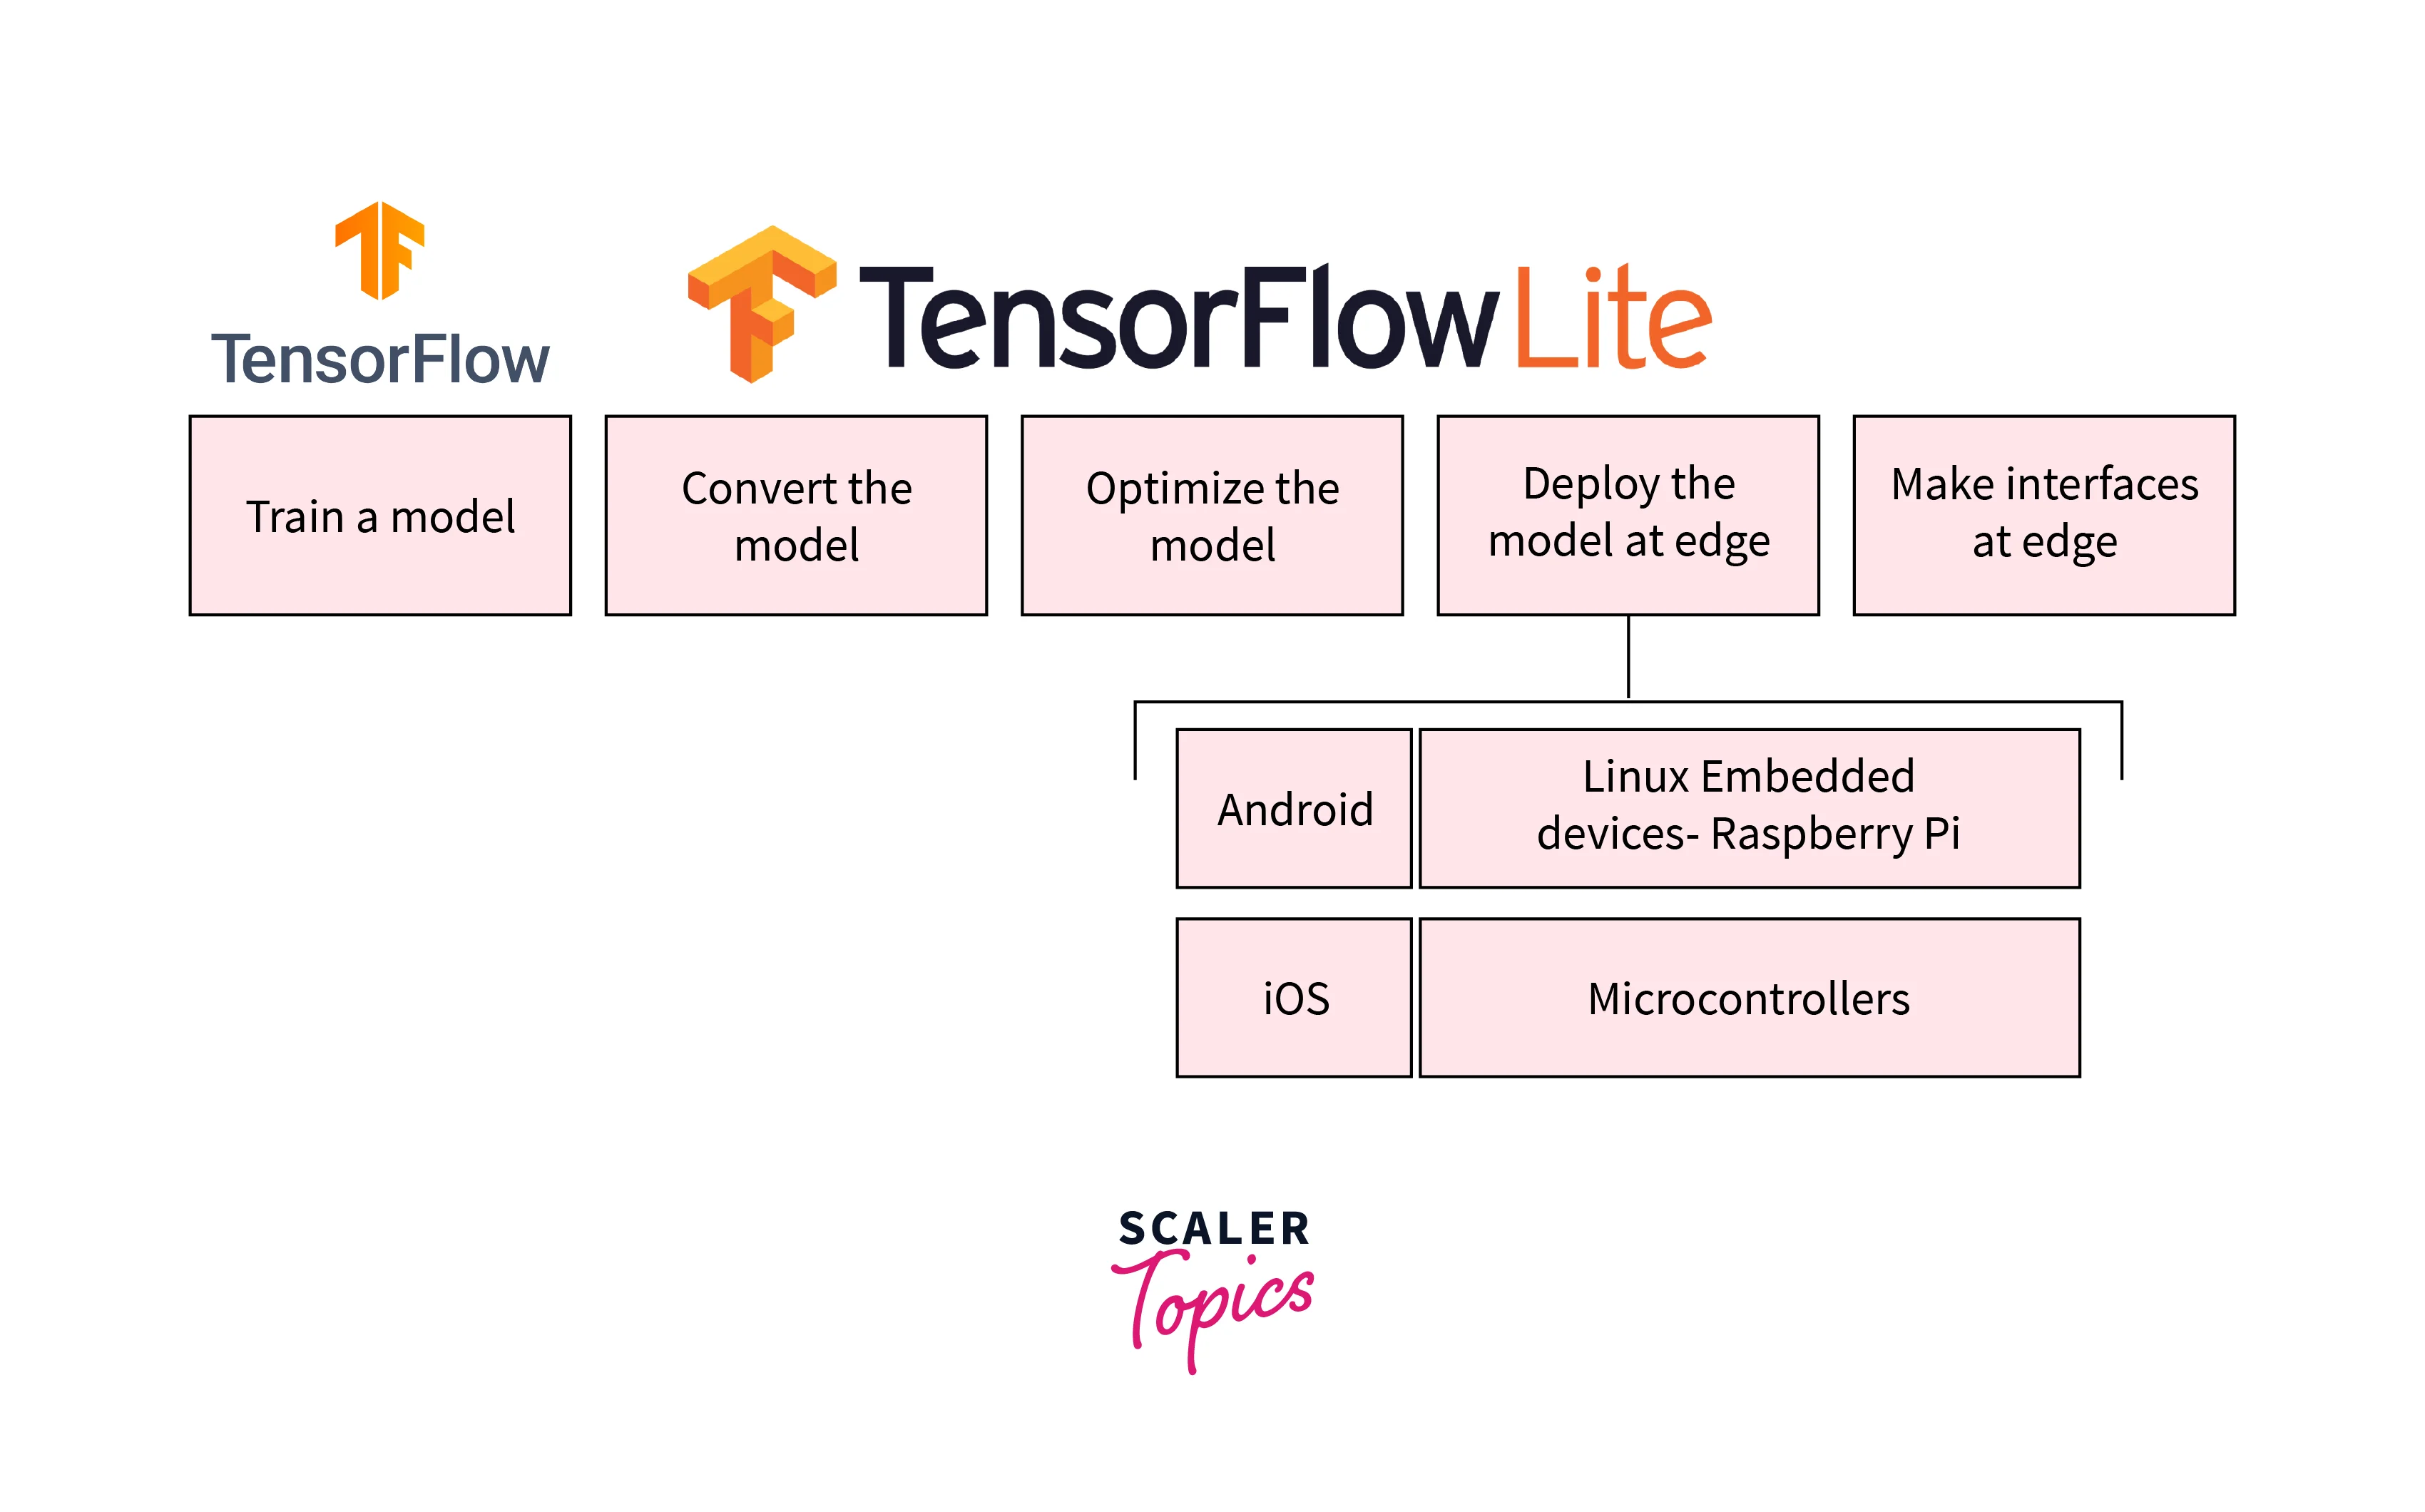
Tensorflow Inference Example | Tensorrt Cpp Inference – YRCKY

Using an ONNX model for inference in an image classification problem ...