
Optimized Llm Inference Api For Mistral 7b Using Vllm A Lightning
Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...

Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...

Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...

Learn to serve LLMs (Mistral 7B) with optimized LLM Inference API using ...

A Brief Introduction to Optimized Batched Inference with vLLM | by ...
How to Deploy Mistral 7B with vLLM on a $12/Month DigitalOcean Droplet ...

A Step-by-Step Guide to Fine-Tuning the Mistral 7B LLM

(PDF) Probabilistic Inference Layer Integration in Mistral LLM for ...

Can a 2B LLM outperform Mistral AI 7B or Meta Llama 13B? Creators of ...

I Built a vLLM So I’d Finally Understand LLM Inference | by Tattva ...
Advertisement Space (300x250)

Mistral 7B LLM AI Leaderboard: Baseline Testing Q3 CPU Inference i9 ...
LLM Evaluation with Mistral 7B for Evaluating your Finetuned models ...
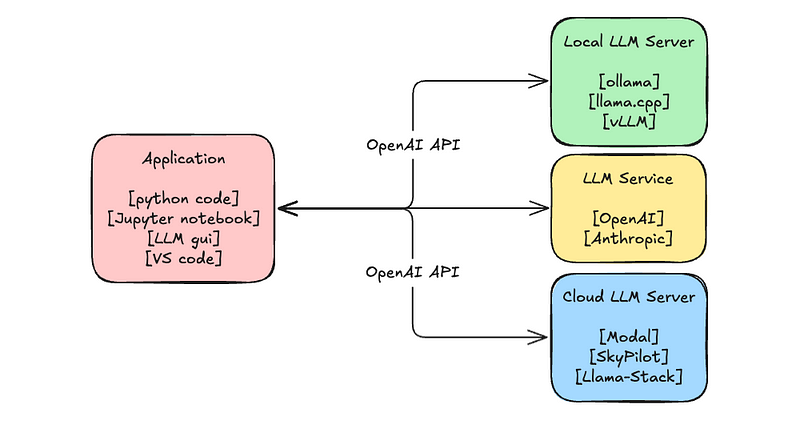
A Brief Introduction to Optimized Batched Inference with vLLM | by ...

Tutorial: Fine-Tune a Mistral 7B Instruct LLM on Custom Datasets

Deploy Mistral 7B with vLLM on Mystic

Mistral.rs: A Lightning-Fast LLM Inference Platform with Device Support ...
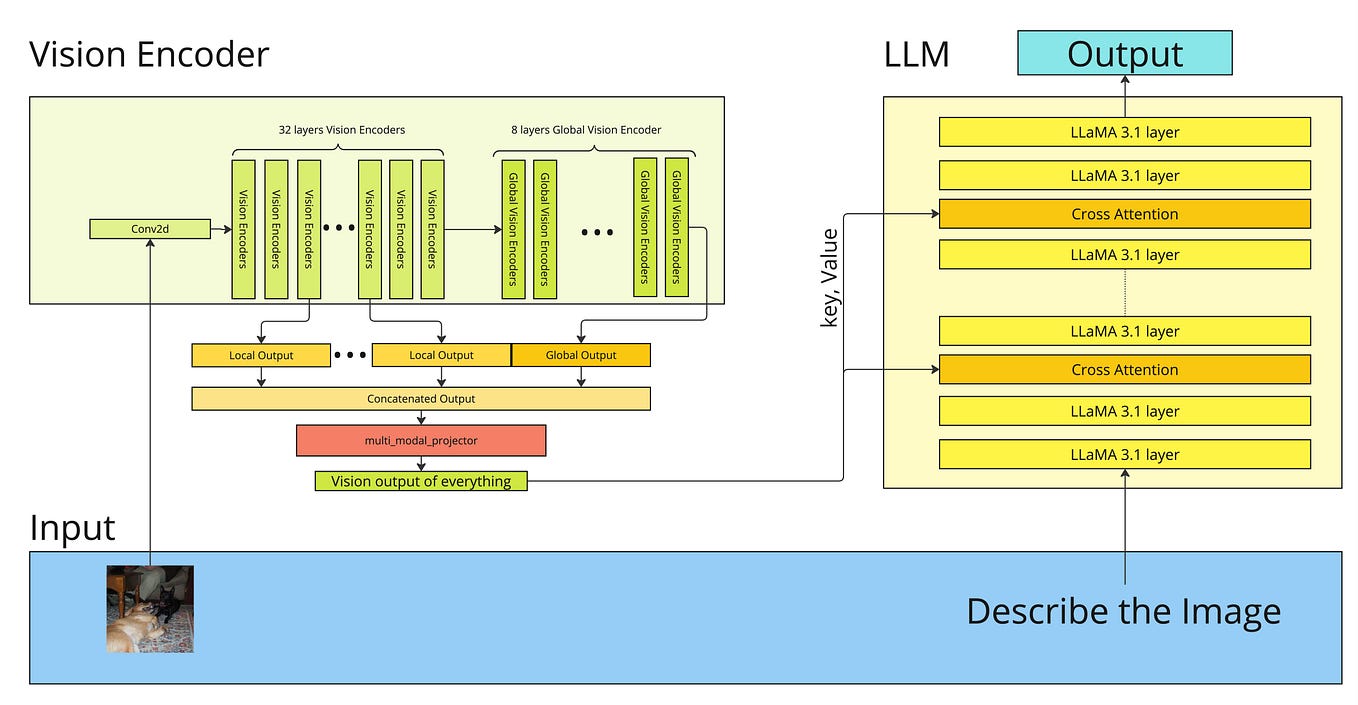
Mistral 7B vs. Llama 3 70B vs. Gemma 2 9B: A Comprehensive Benchmark ...

Meet vLLM: For faster, more efficient LLM inference and serving

How to run Mistral 7B with an API – Replicate
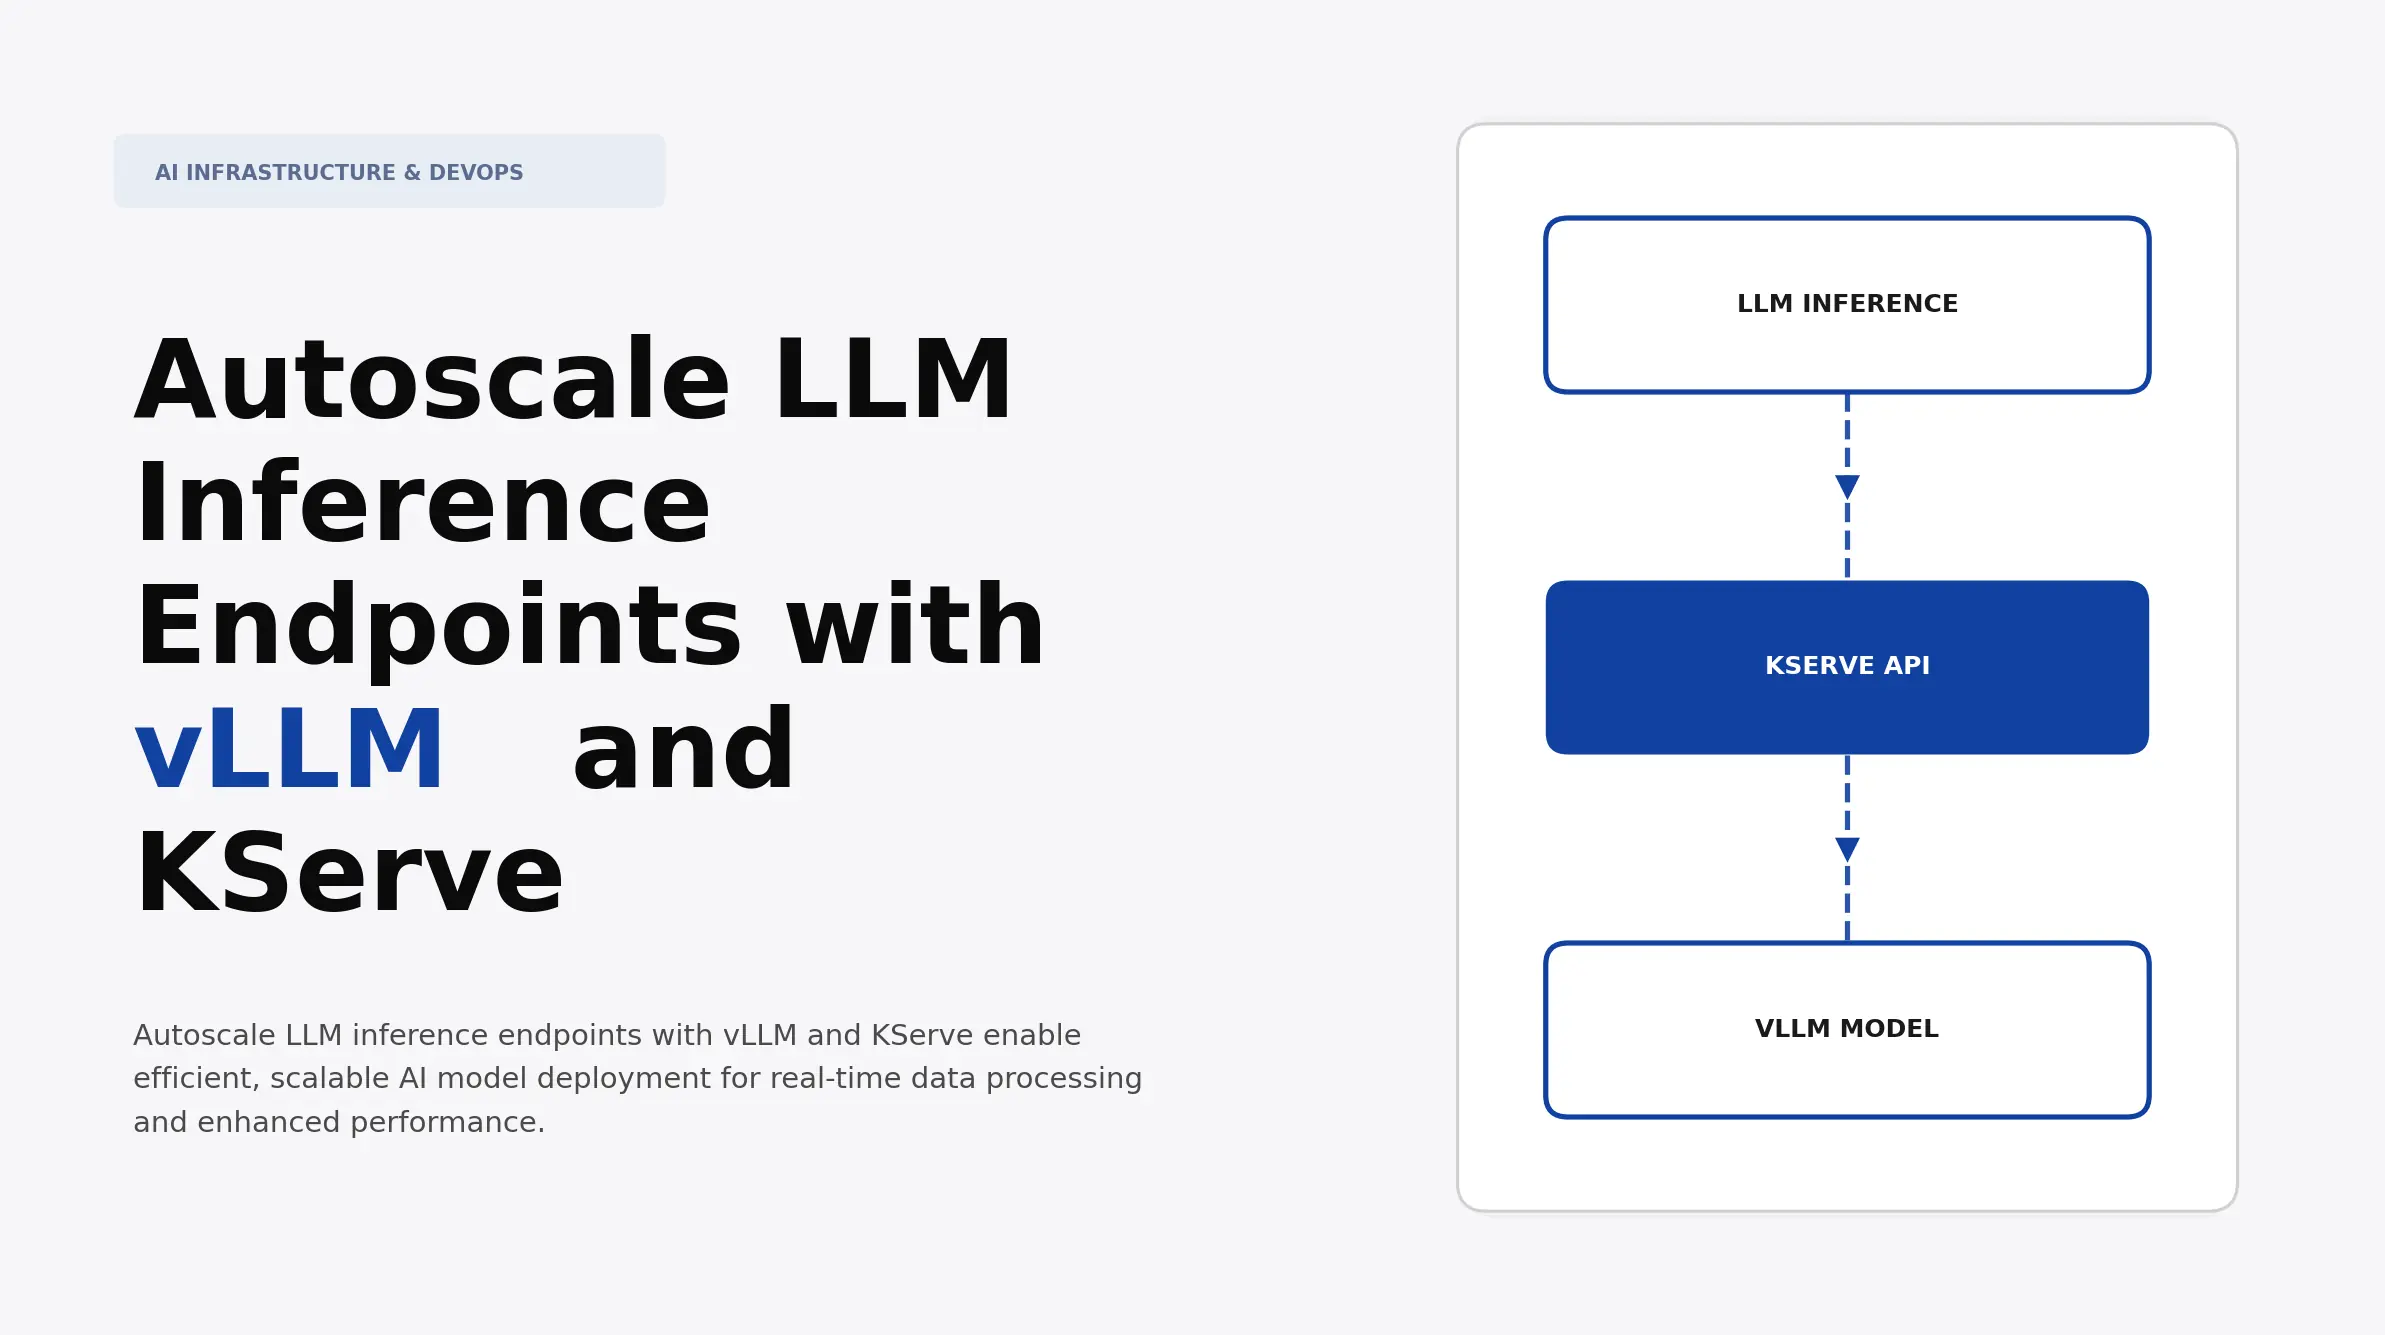
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
Advertisement Space (336x280)

How to run Mistral 7B with an API – Replicate
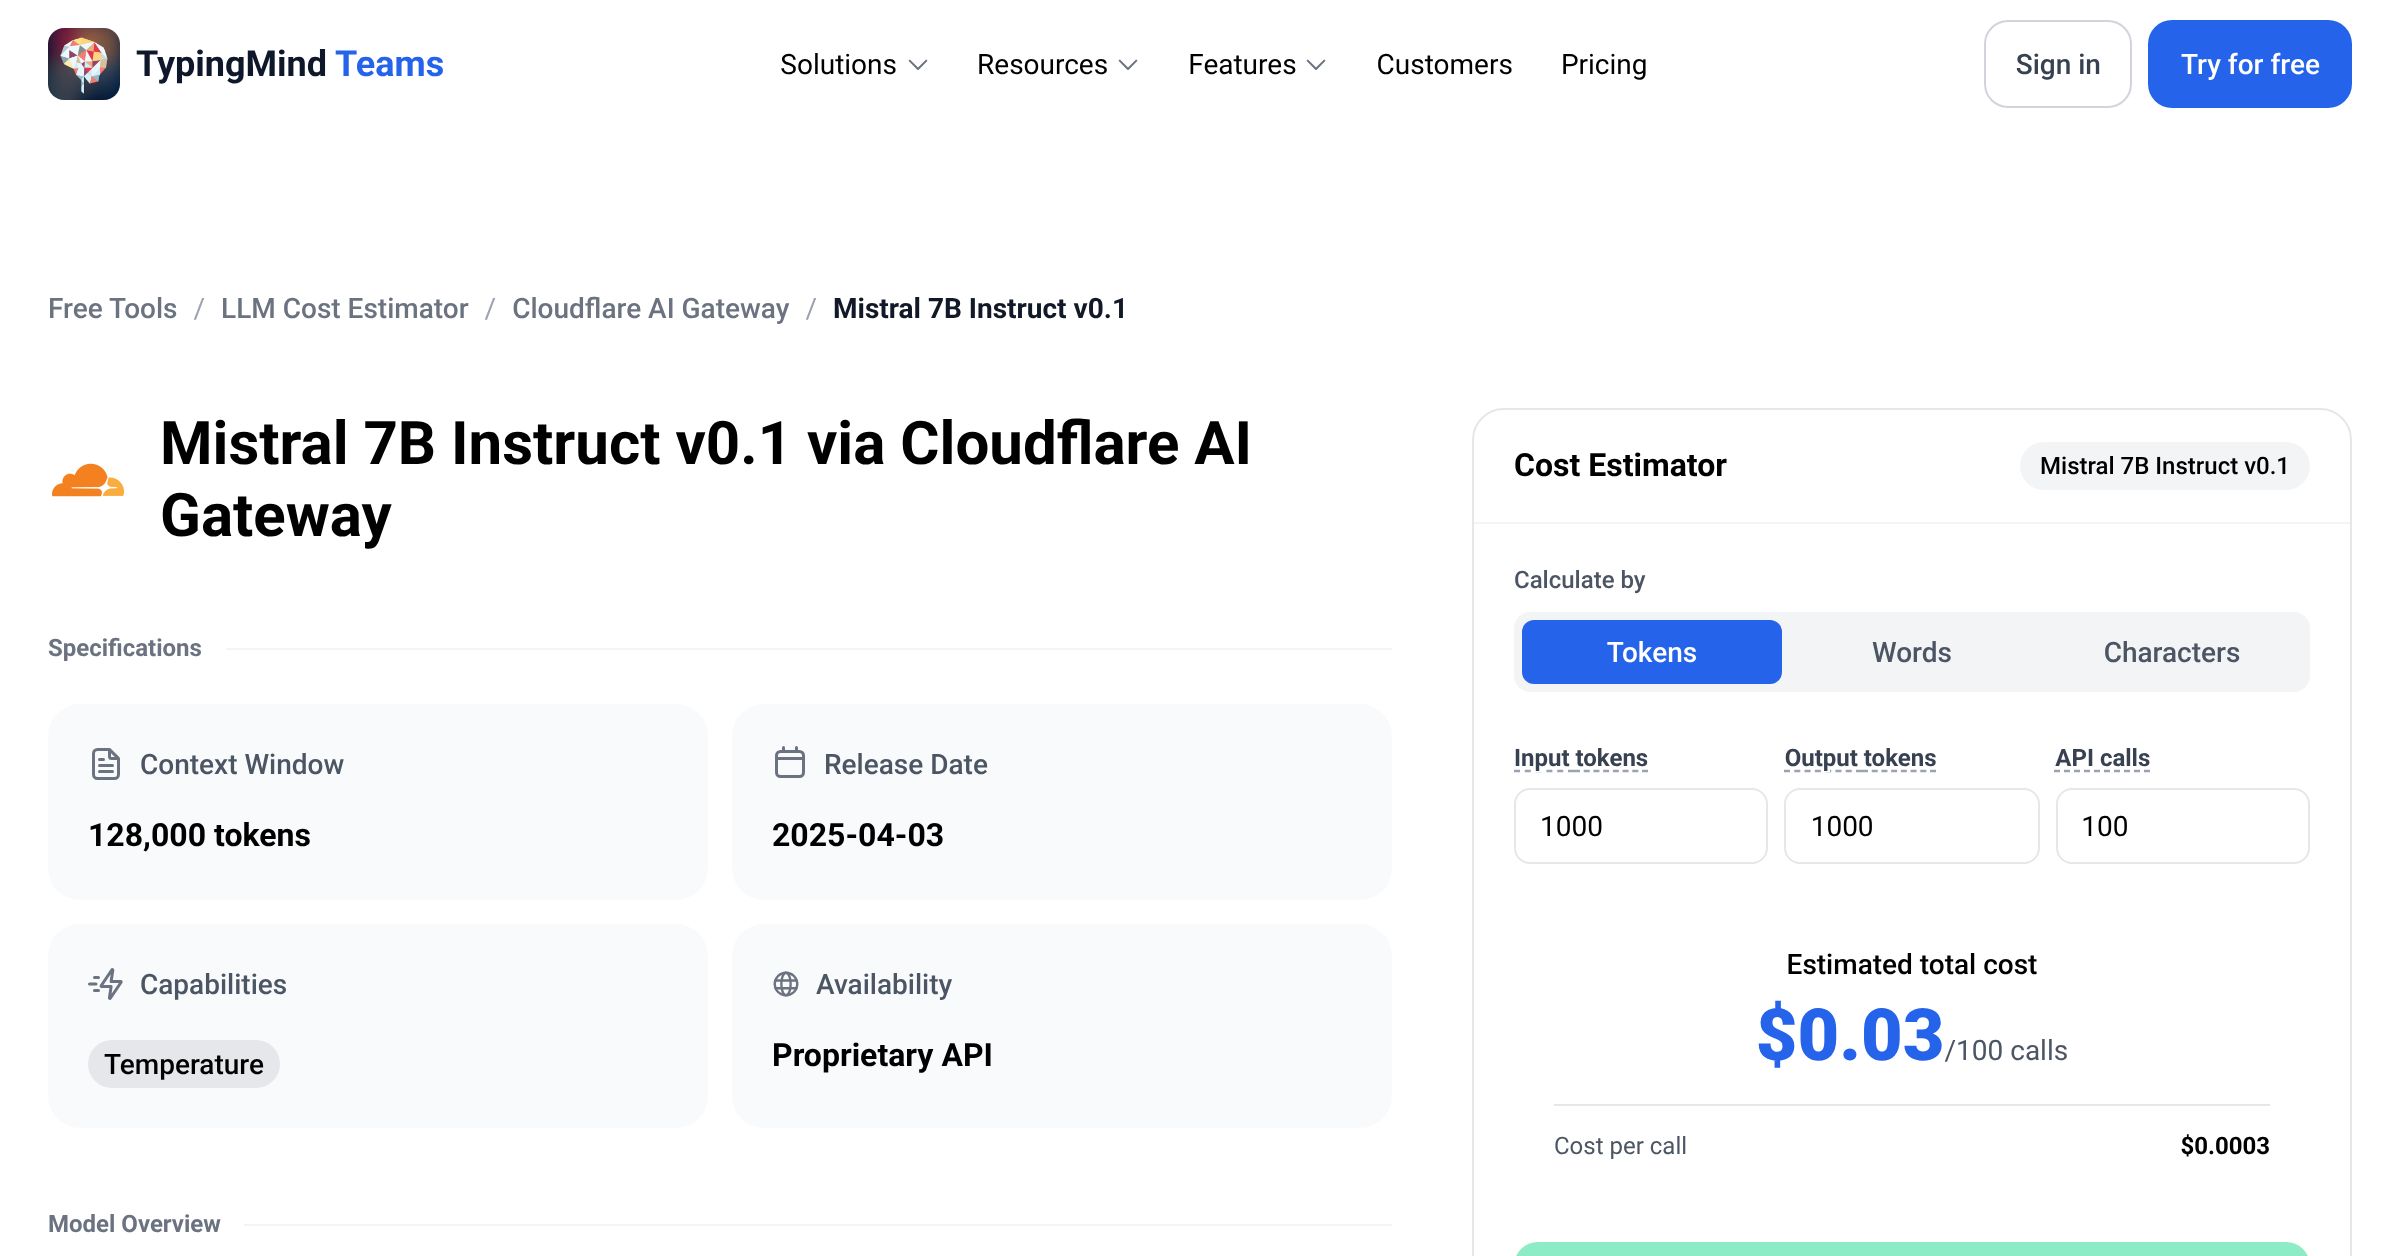
Cloudflare AI Gateway Mistral 7B Instruct v0.1 API Pricing Calculator
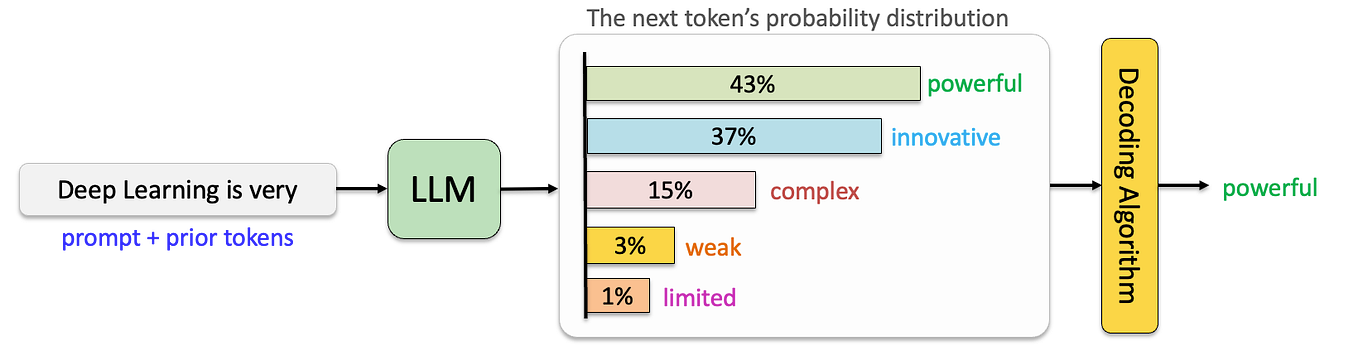
Papers Explained 64: Mistral. Mistral 7B is an LLM engineered for… | by ...

(PDF) Optimizing LLM API Performance: A Comparative Analysis of Qwen ...

Mistral Ai Unveils Mistral 7B An Open Source Llm With 7 3B Parameters ...

LLM inference engines performance testing: SGLang VS. vLLM | by ...
Mistral 7B Instruct V0.2 ONNX by microsoft | LLM Explorer

Tailoring LLM Inference with NVIDIA NIM using Key Features of TensorRT ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Mistral 7B from Mistral AI is now available on Hugging Face Inference ...
Advertisement Space (336x280)

mistralai/Mistral-7B-Instruct-v0.3 · Documentation for inference API ...

Benchmarking Mistral 7B Inference performance on GPUs – BudEcosystem

Mistral.rs: A Fast LLM Inference Platform Supporting Inference on a ...
[Bug]: Performance of VLLM - GPU utilization - Mistral 7B · Issue #4238 ...
Fast & Efficient LLM Inference with vLLM: A New Course with ...
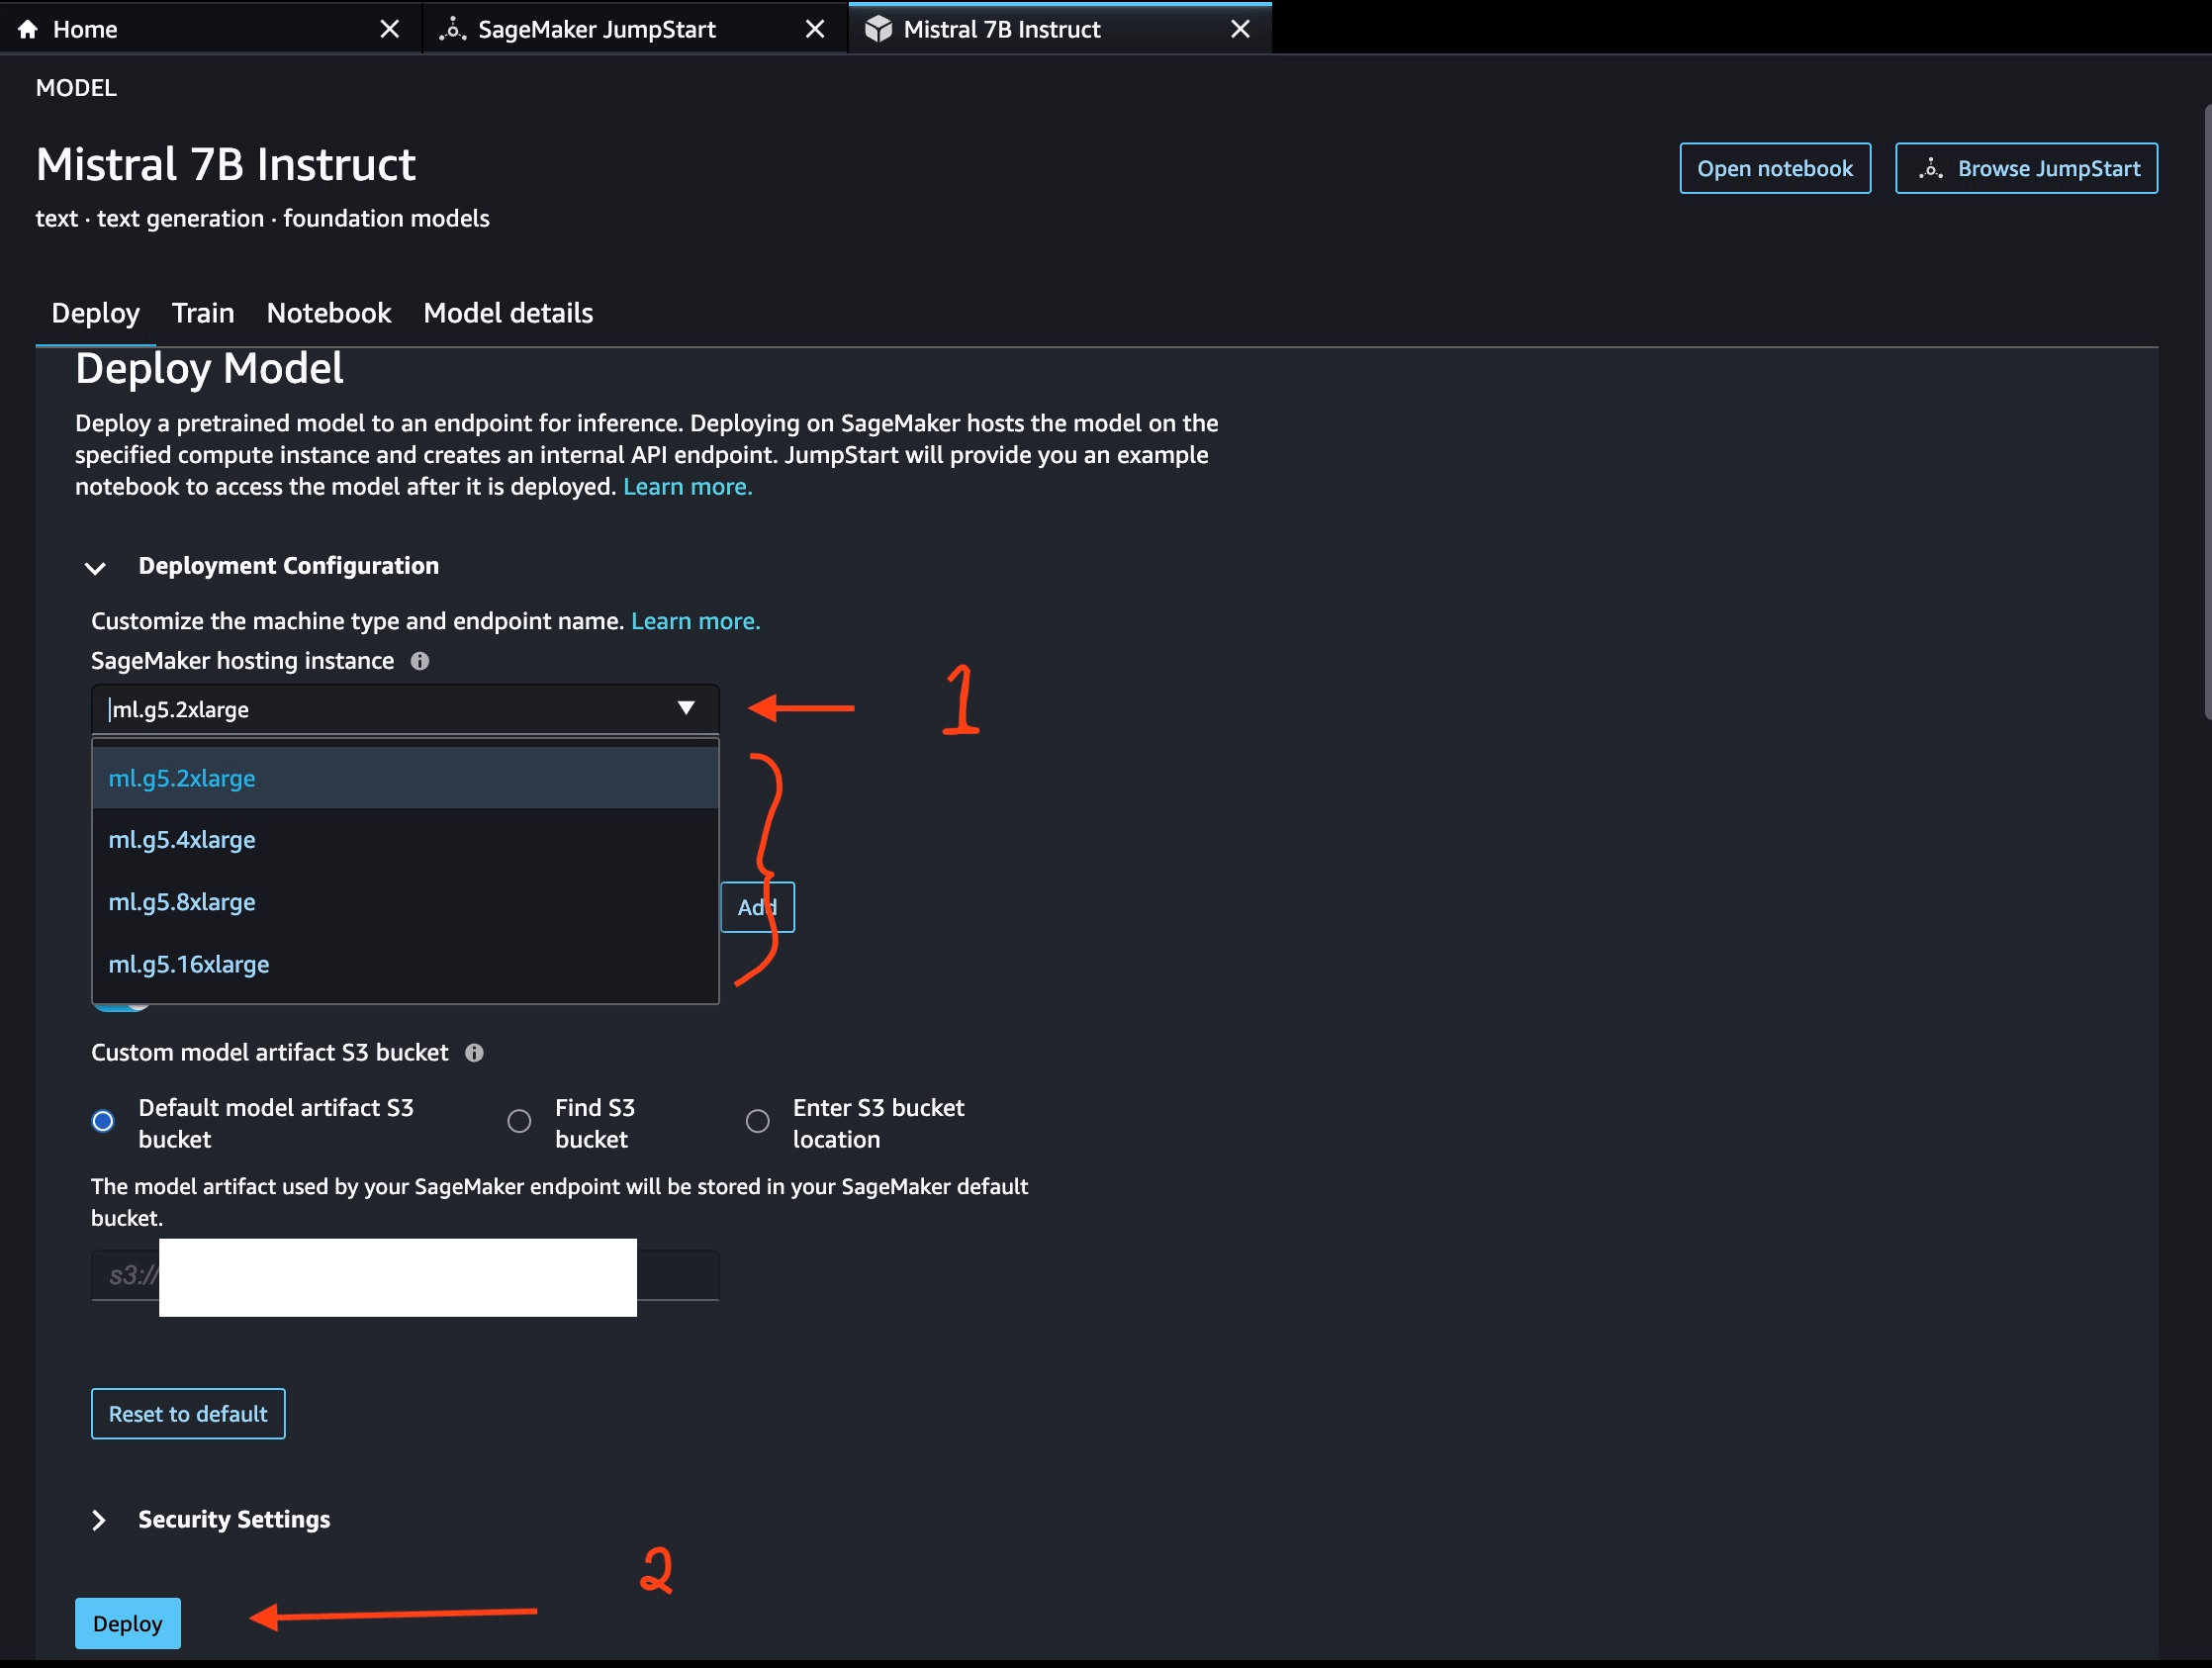
Deploy & Inference Mistral 7B Instruct on SageMaker JumpStart