
Optimizing Llms With Nvfp4 Speed And Memory Magic By Tamanna Medium
Optimizing LLMs with NVFP4 Speed and Memory Magic | by Tamanna | Medium

Optimizing LLMs for Performance and Accuracy with Post-Training ...

NVFP4 Trains with Precision of 16-Bit and Speed and Efficiency of 4-Bit ...

NVFP4 Trains with Precision of 16-Bit and Speed and Efficiency of 4-Bit ...
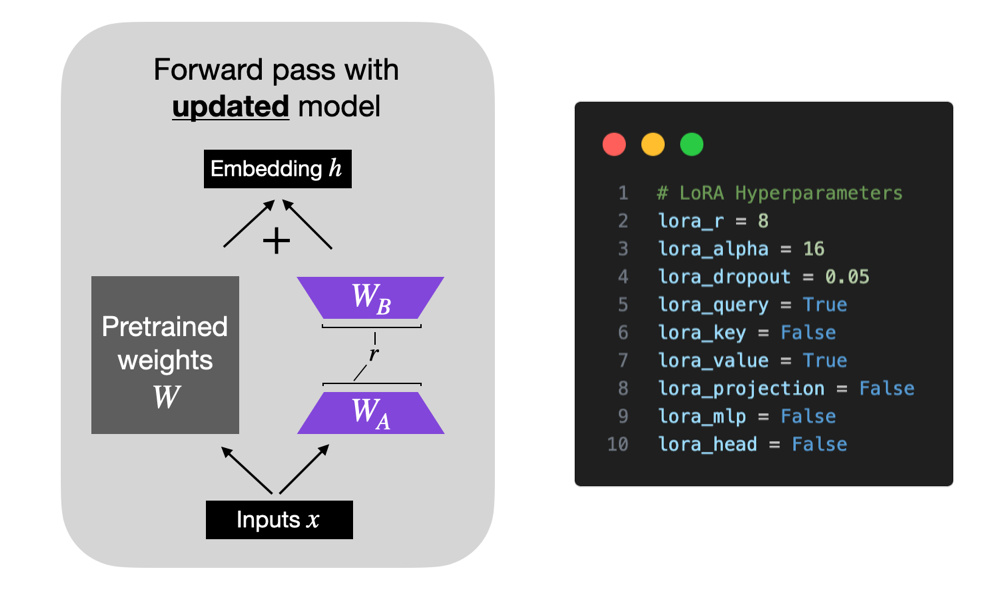
Optimizing Memory Usage for Training LLMs and Vision Transformers in ...

Optimizing Inference for Long Context and Large Batch Sizes with NVFP4 ...

Free Video: Deploy LLMs More Efficiently with vLLM and Neural Magic ...
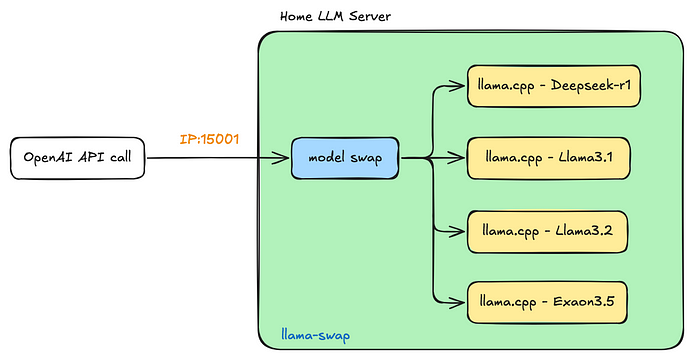
How to run LLMs with less GPU and CPU memory? | by Mehul Gupta | Data ...

Optimizing Memory Usage for Training LLMs and Vision Transformers in ...

The Art of Fine-tuning LLMs with Almost No Memory | by Om Choudhary ...
Advertisement Space (300x250)

Optimizing Inference for Long Context and Large Batch Sizes with NVFP4 ...

Transforming AI with Multi-Agent Systems and Decentralized Agents | by ...

How to optimize inference speed using batching, vLLM, and UbiOps | by ...
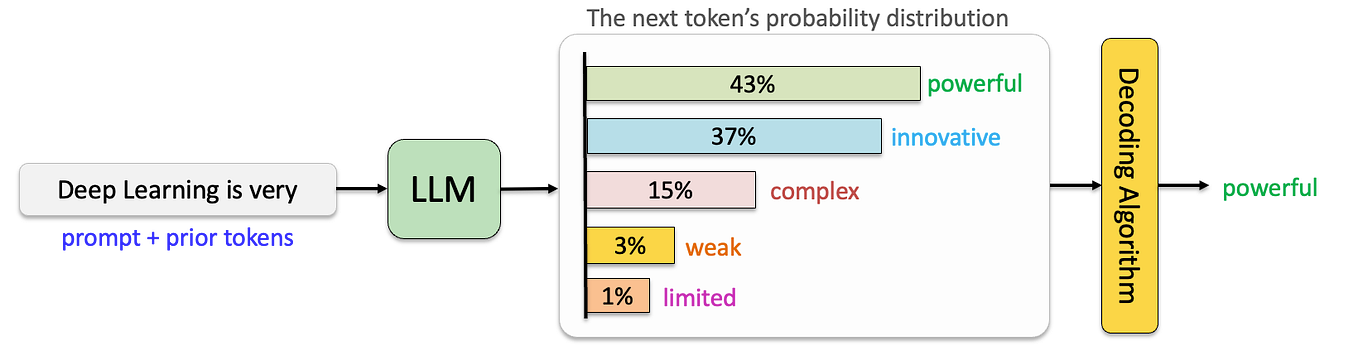
Deep Dive: Estimating Memory Consumption of LLMs for Inference and Fine ...
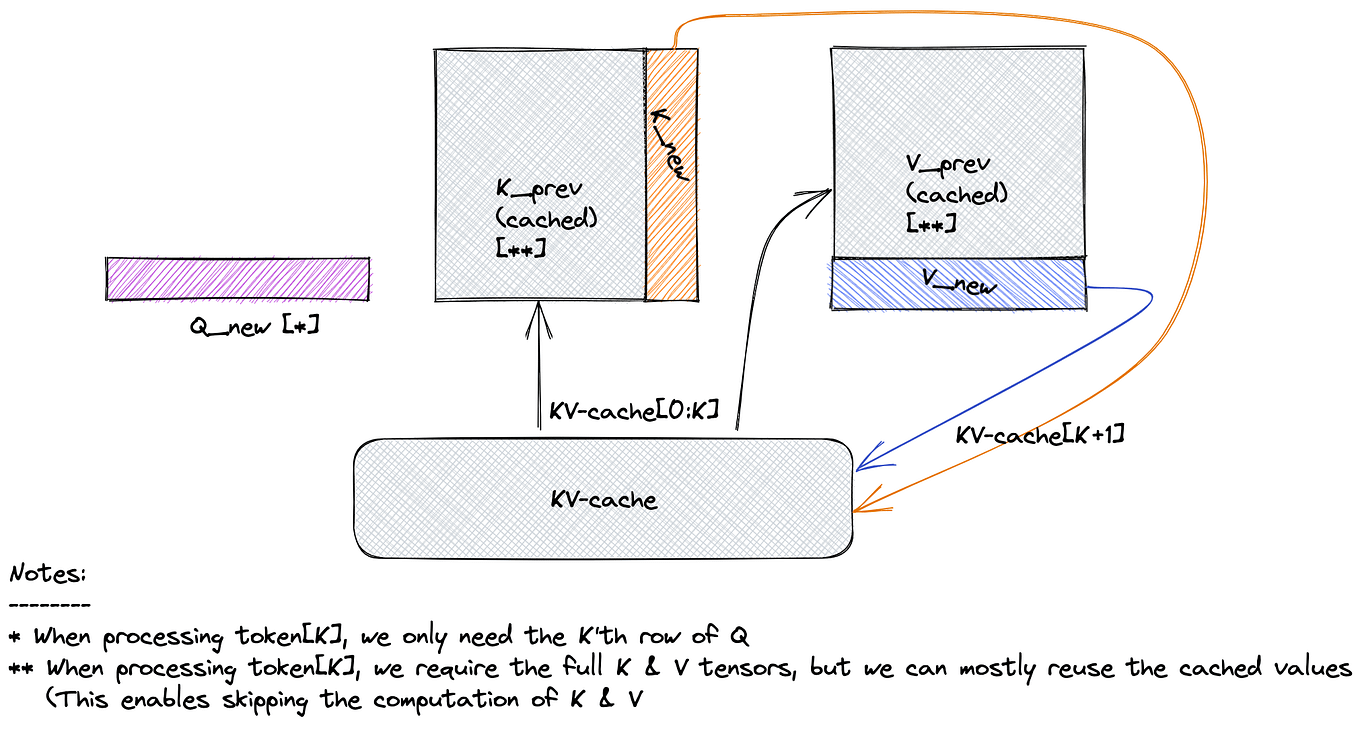
A Guide to Estimating VRAM for LLMs | by LM Po | Medium
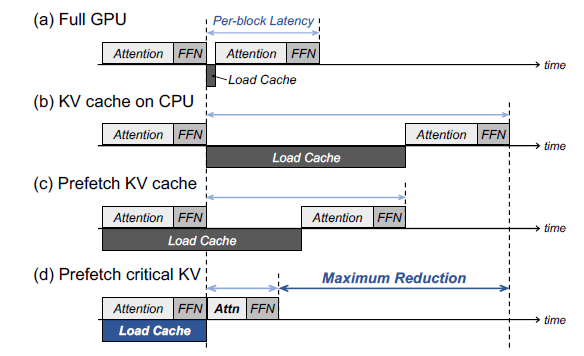
How to optimize inference speed using batching, vLLM, and UbiOps | by ...
Optimizing Large Language Models with vLLM and Related Tools.pdf
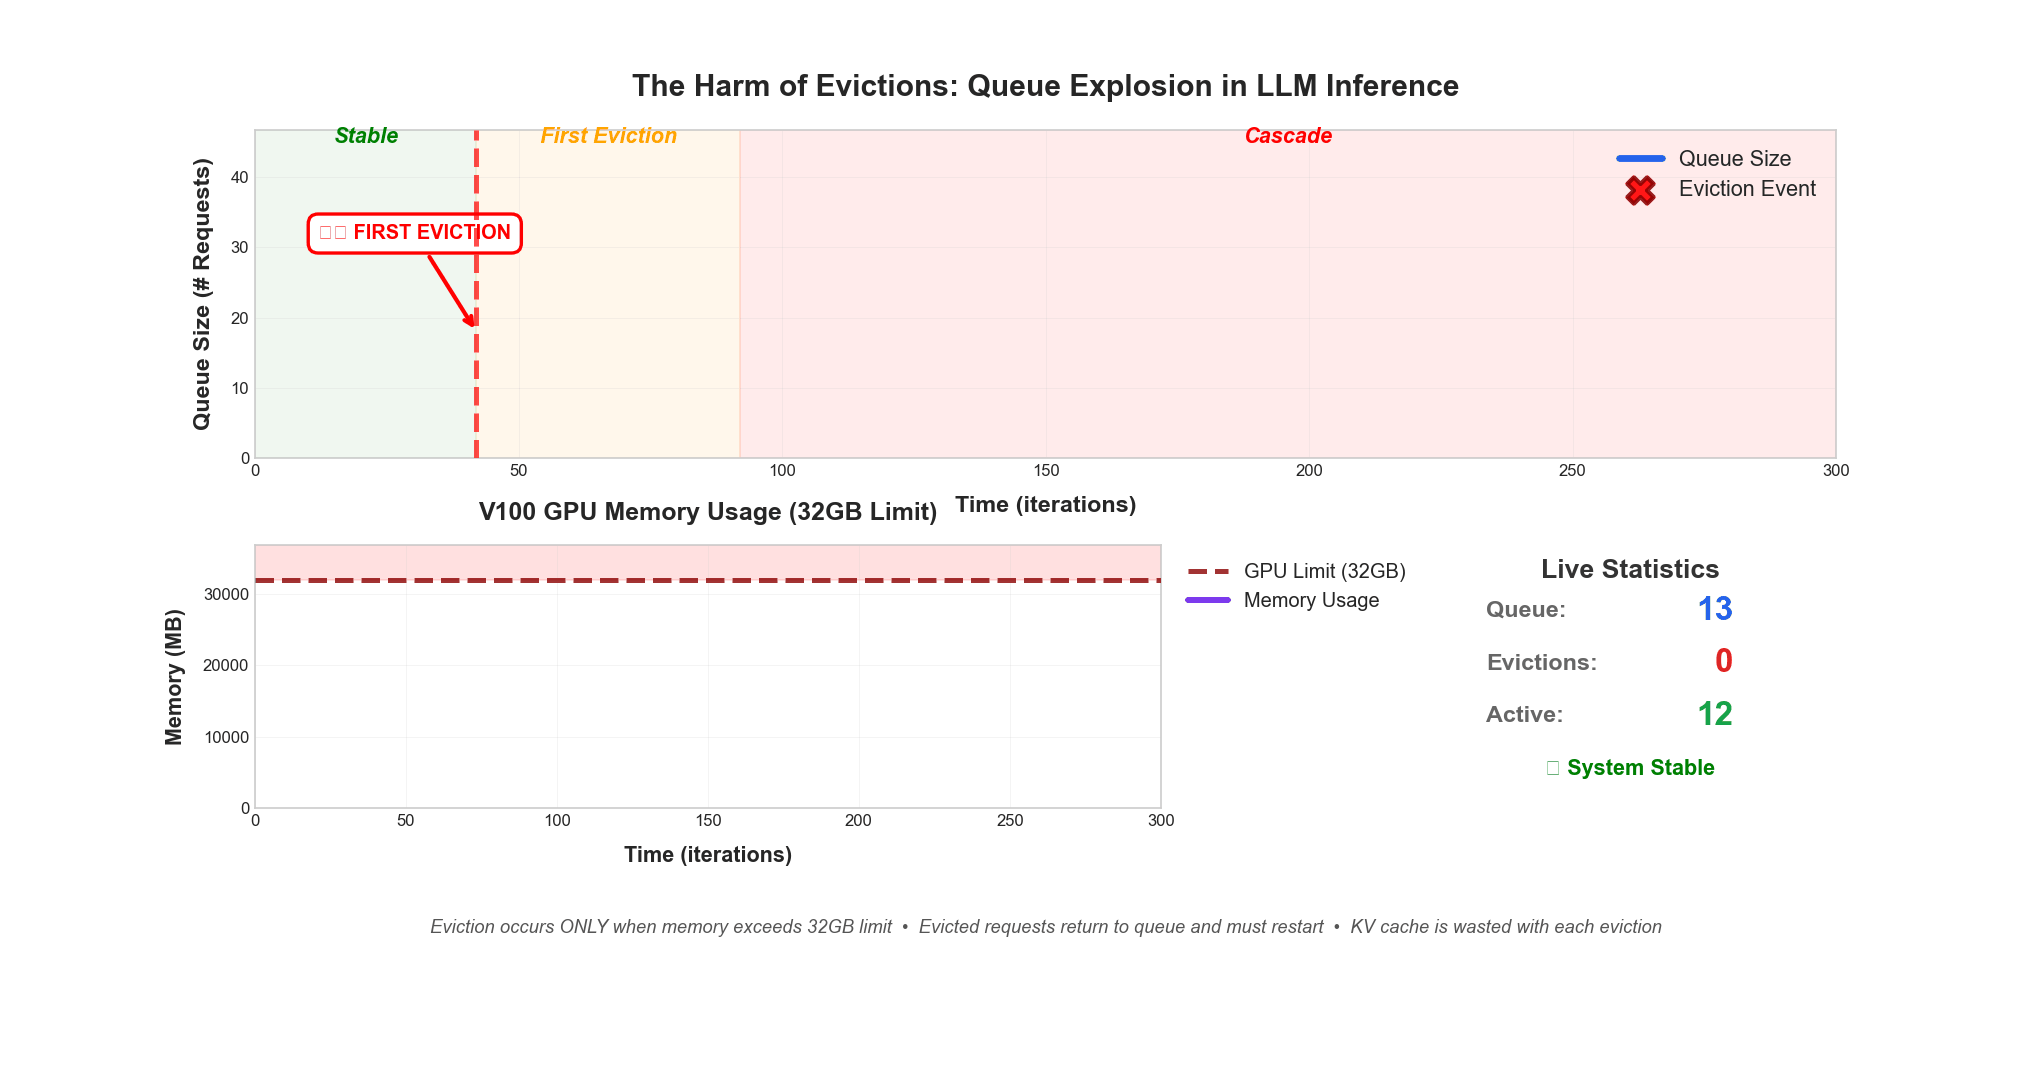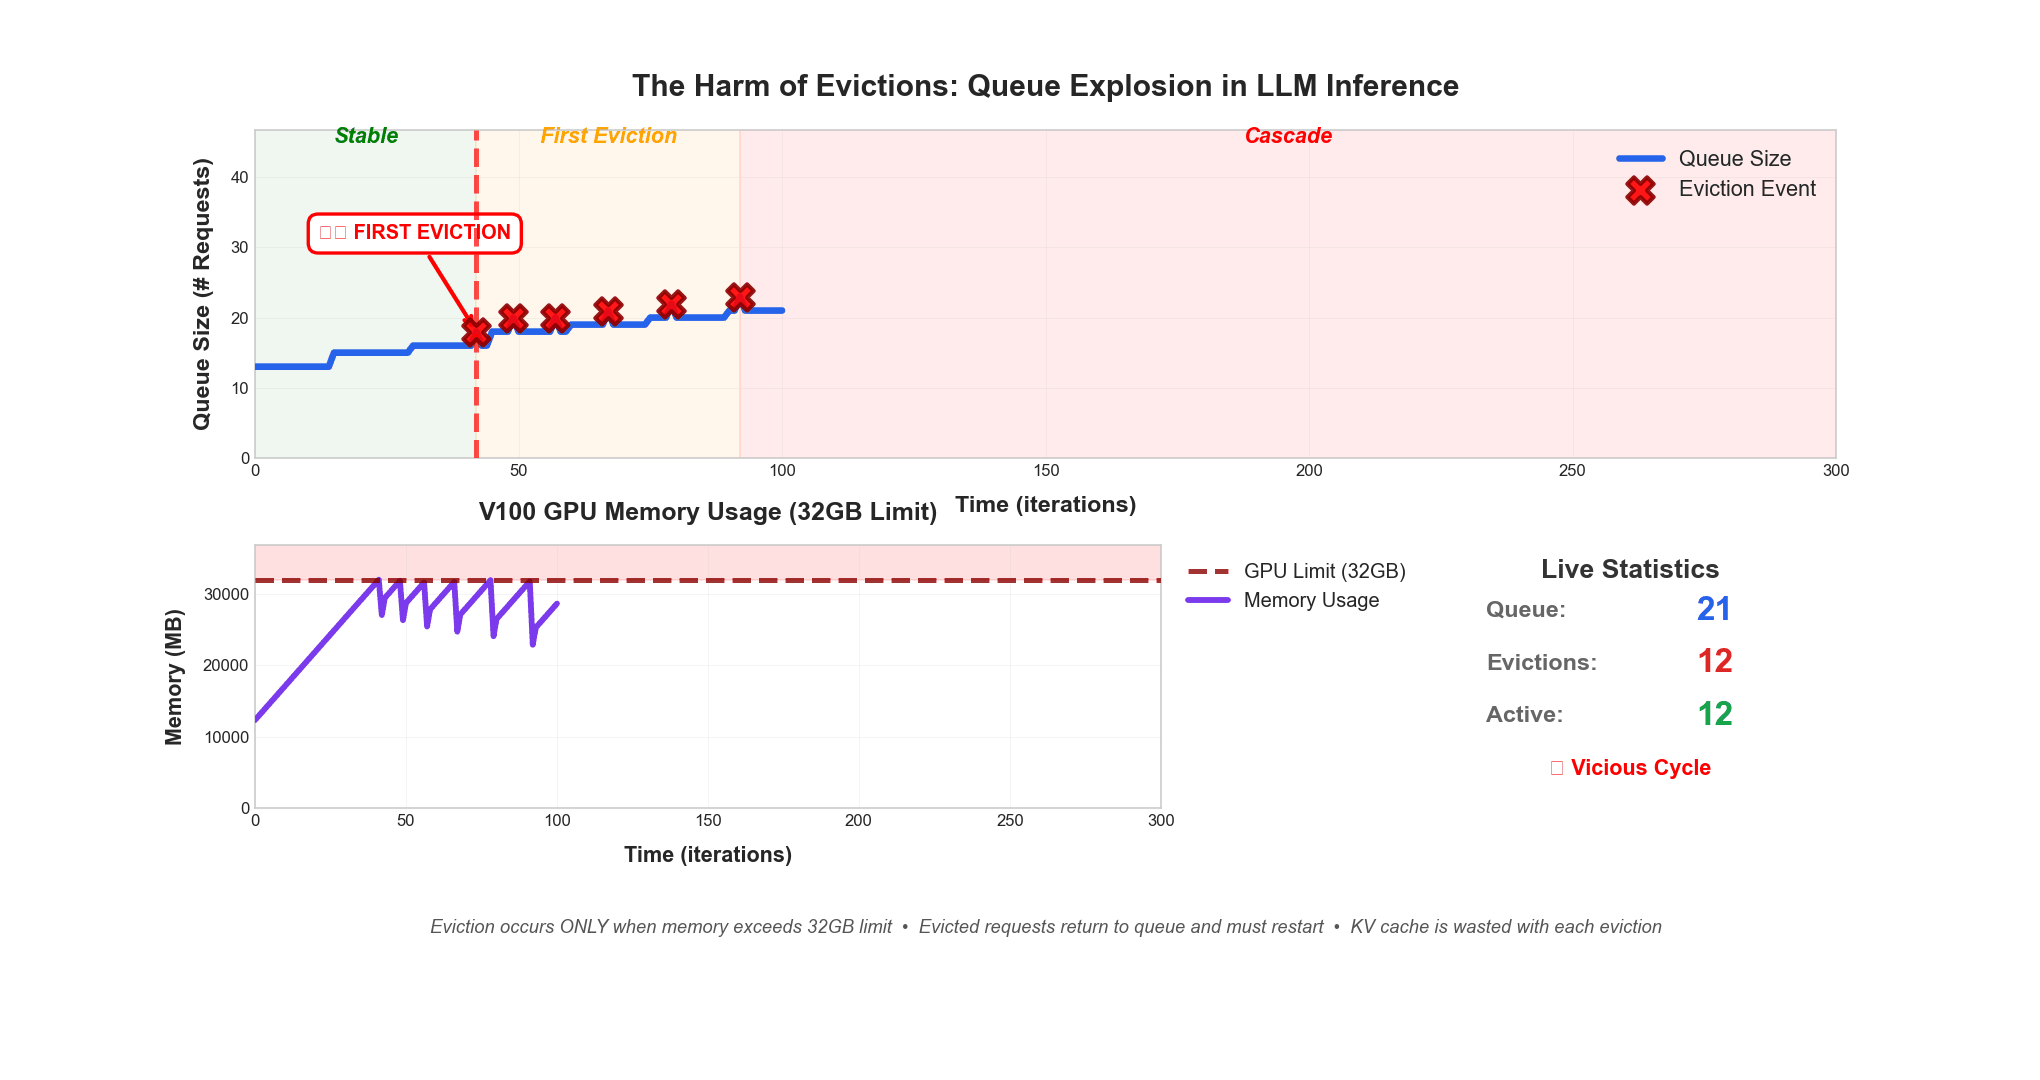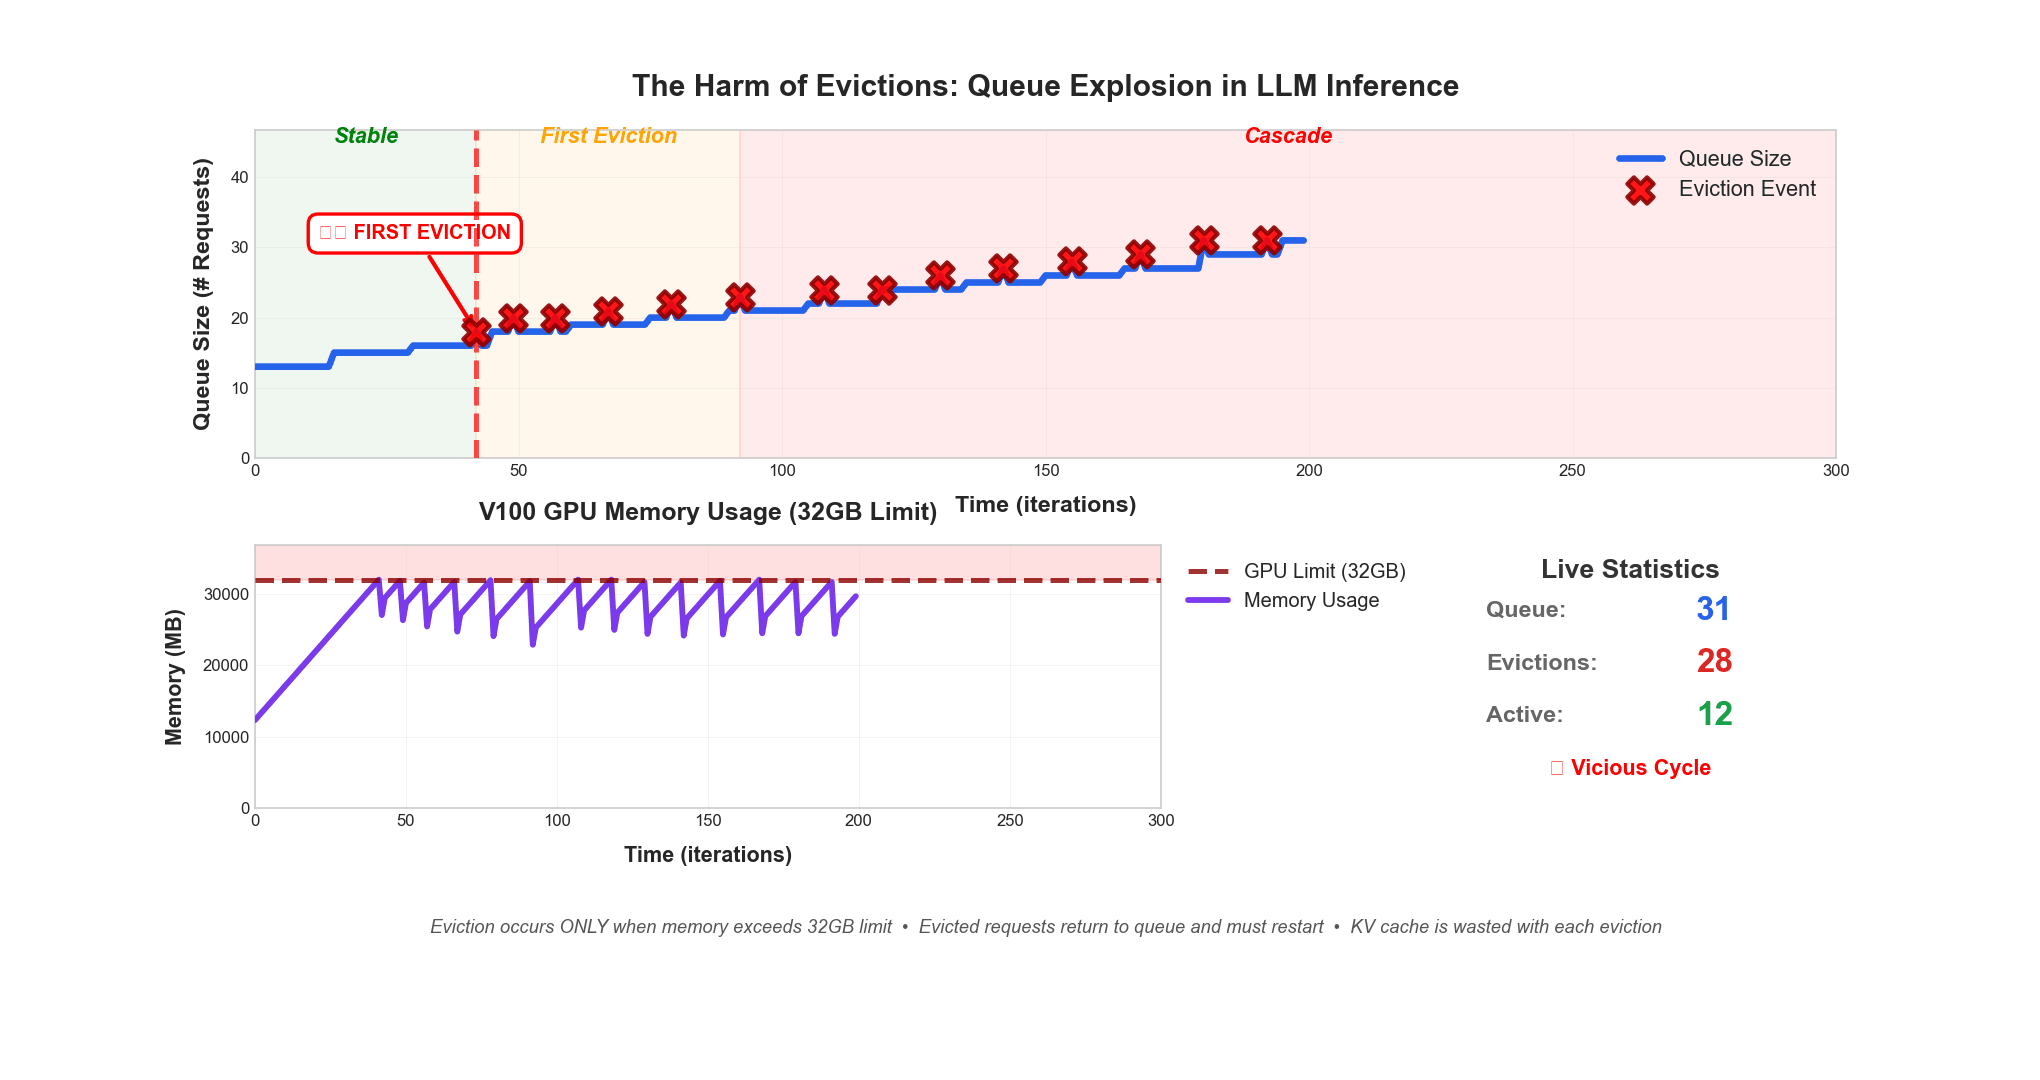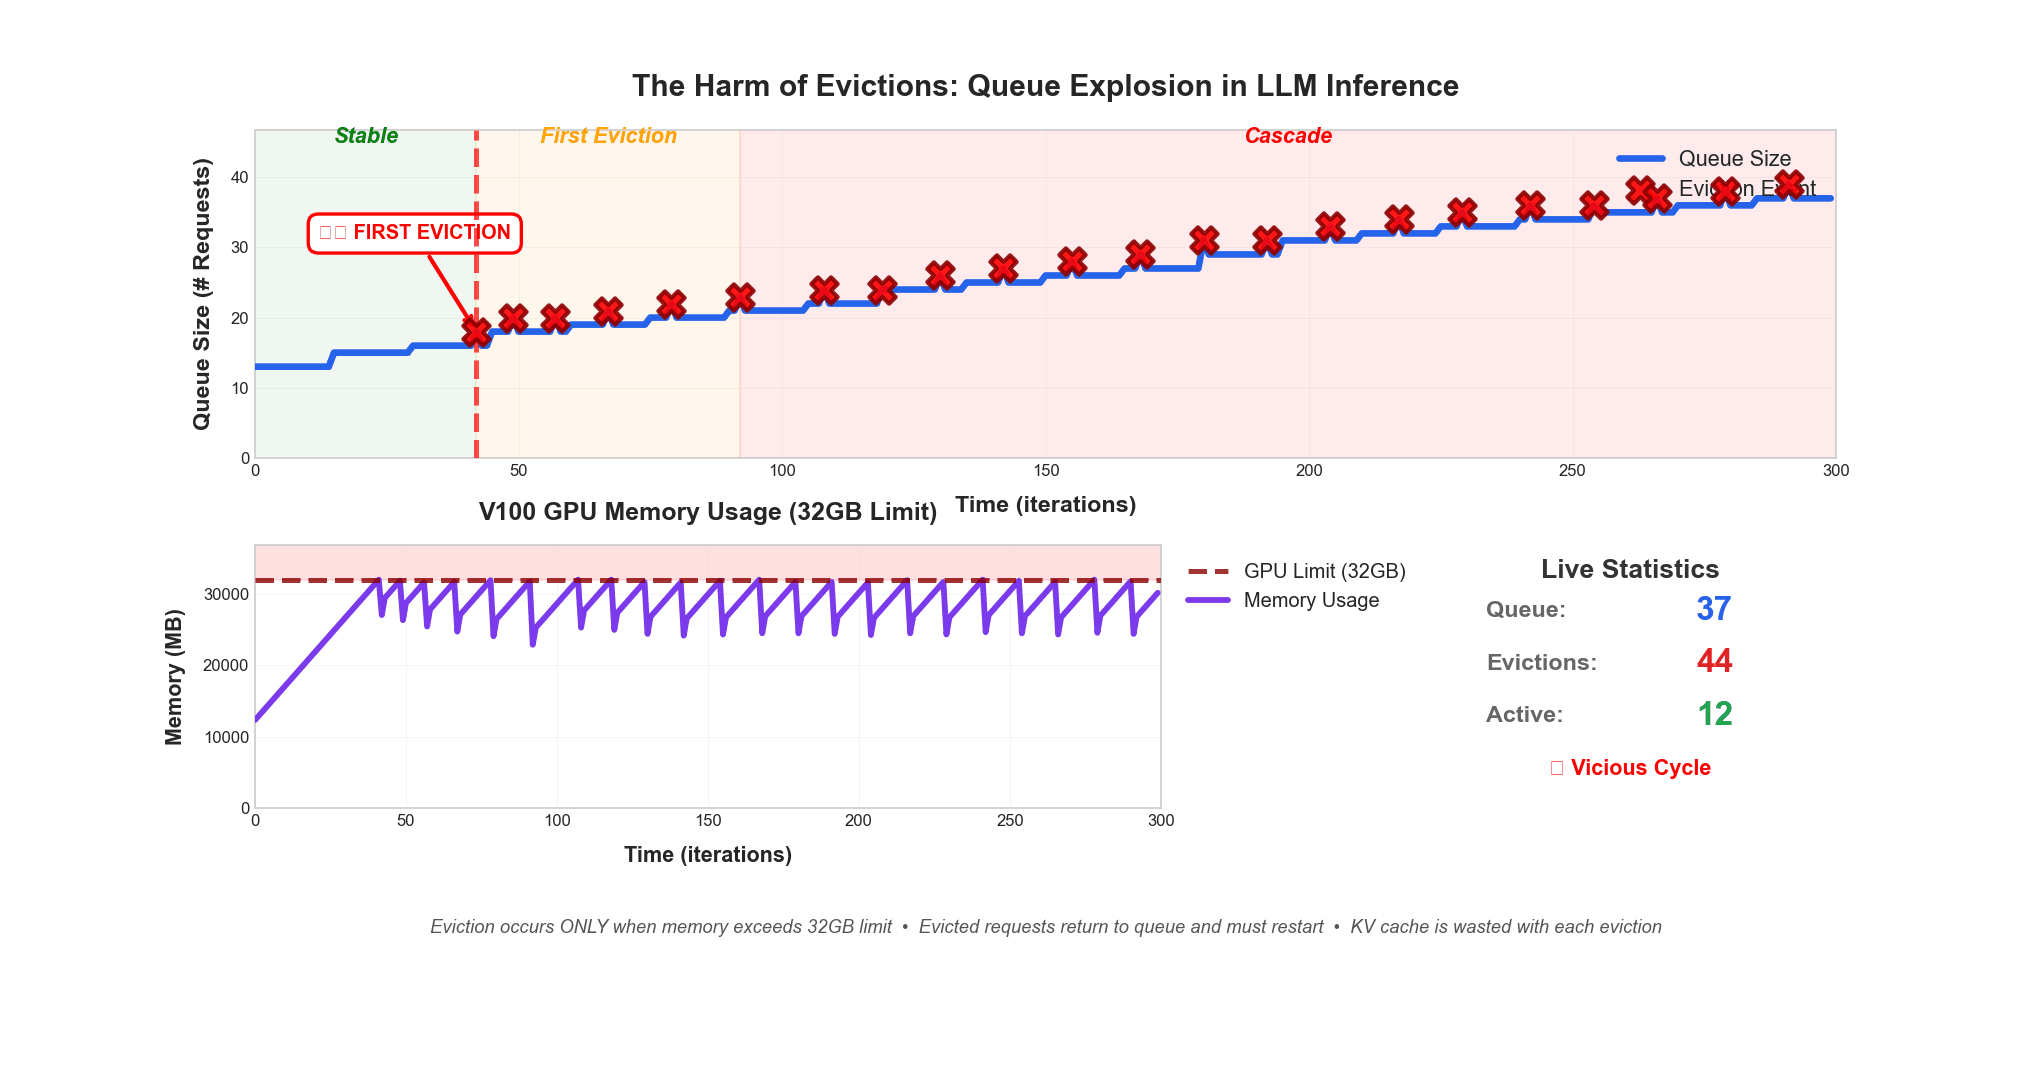
Optimizing LLM Inference: Fluid-Guided Online Scheduling with Memory ...

Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

Optimizing LLM Training: Memory Management and Multi-GPU Techniques ...
Advertisement Space (336x280)
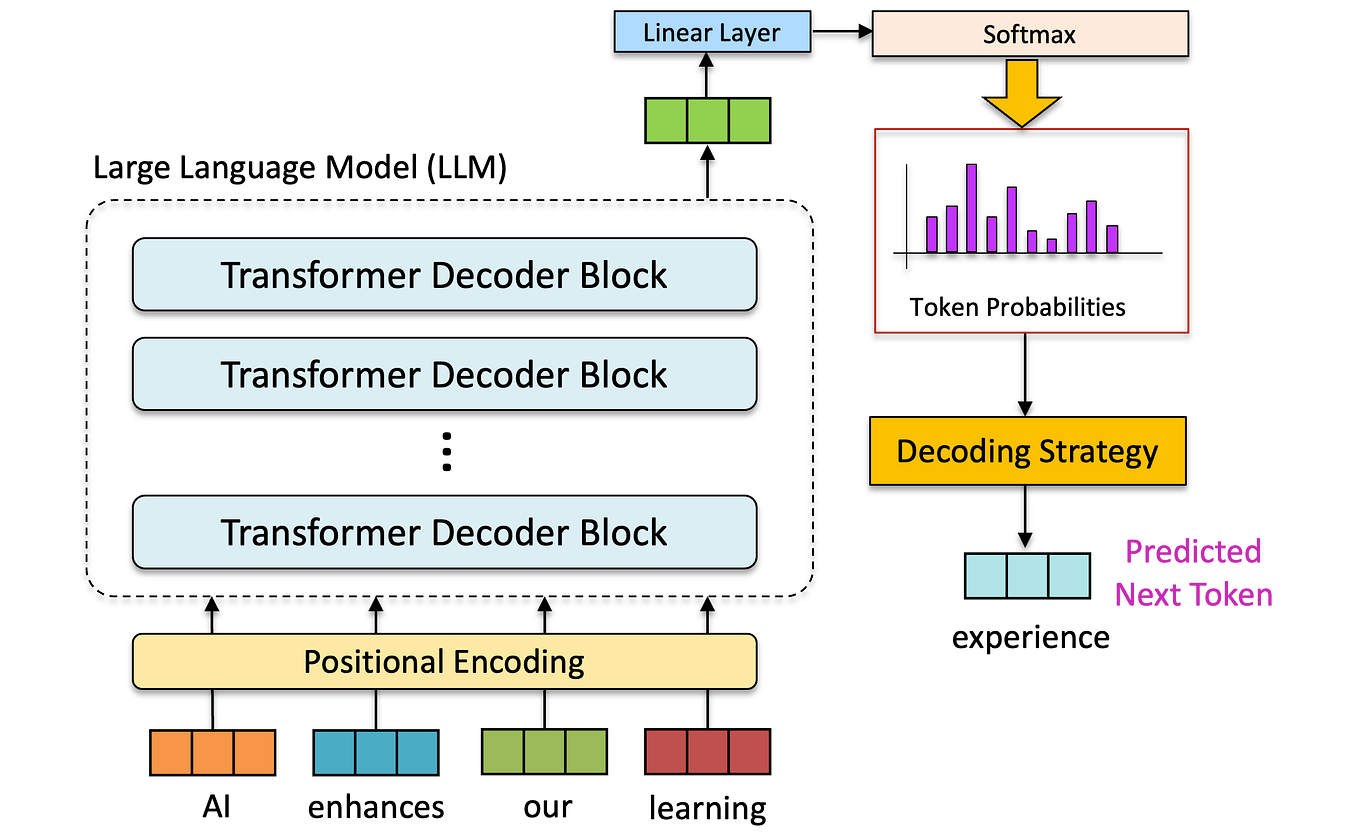
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

Optimizing Large Language Models with vLLM and Related Tools.pdf

Optimizing LLM for Long Text Inputs and Chat Applications | by ...
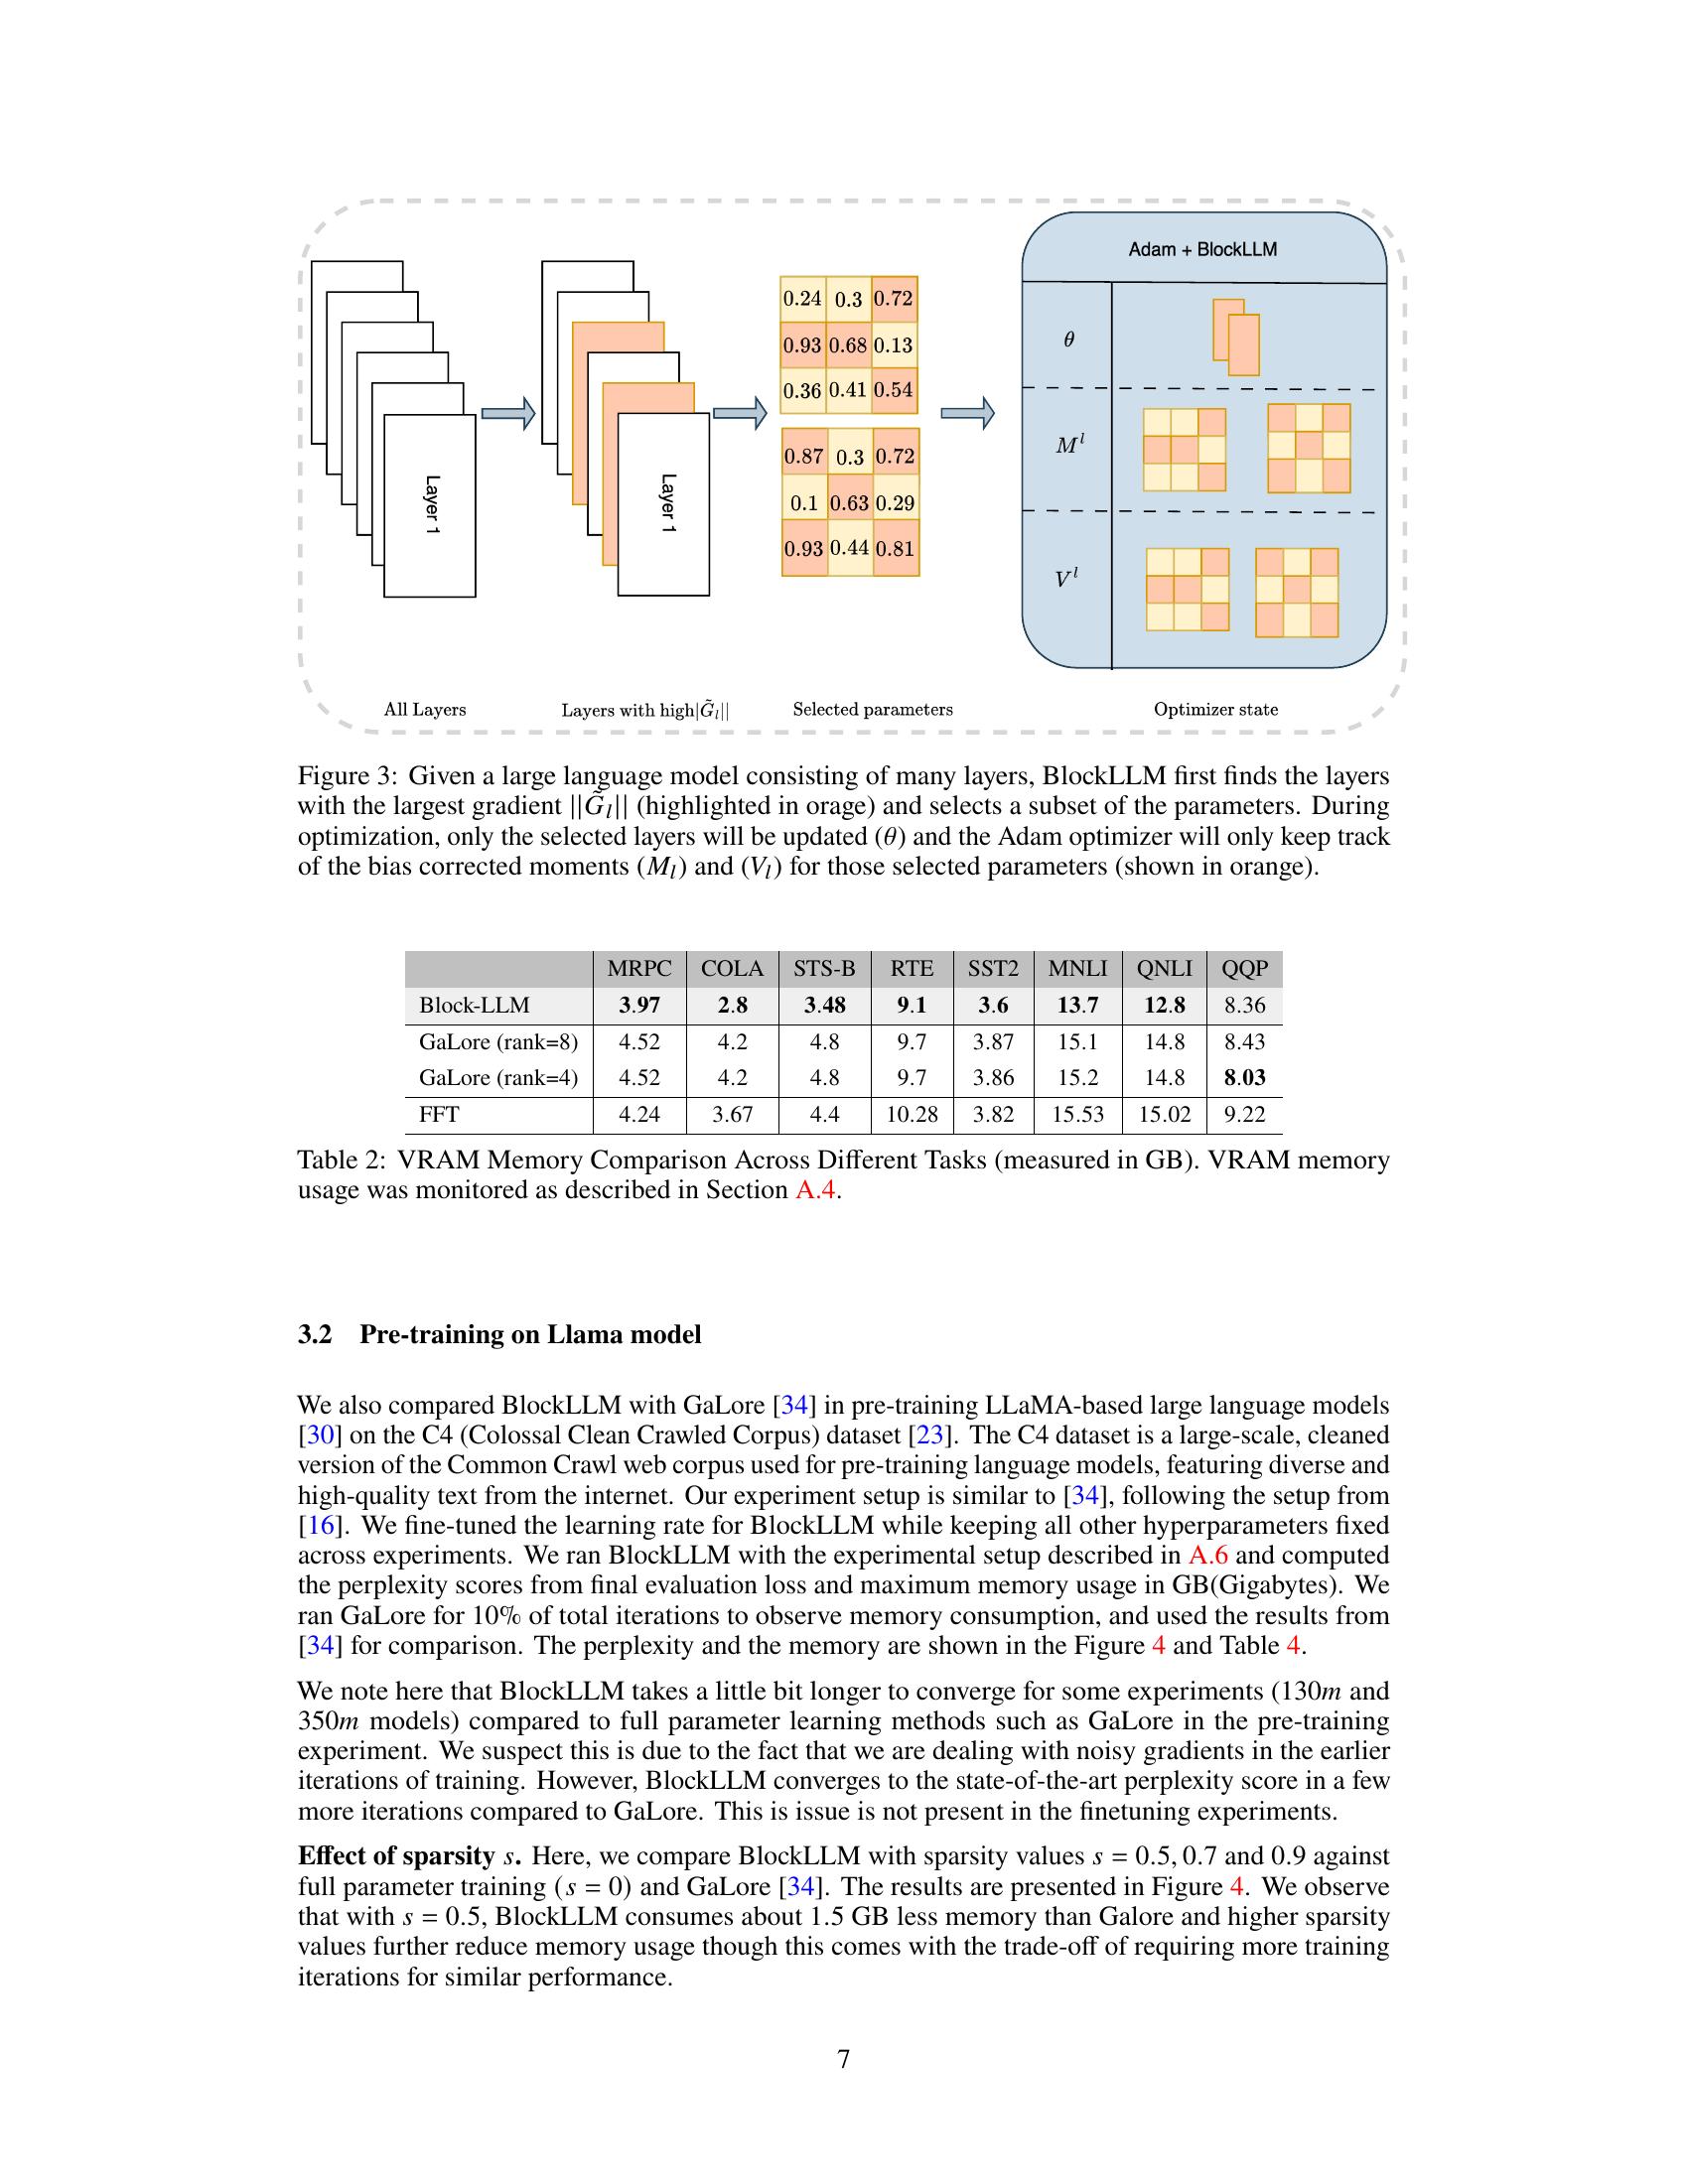
BlockLLM: Memory-Efficient Adaptation of LLMs by Selecting and ...
AI Memory Management for LLMs and Agents

Optimizing Inference Efficiency for LLMs at Scale with NVIDIA NIM ...

NVIDIA Blackwell: The Impact of NVFP4 For LLM Inference - Edge AI and ...
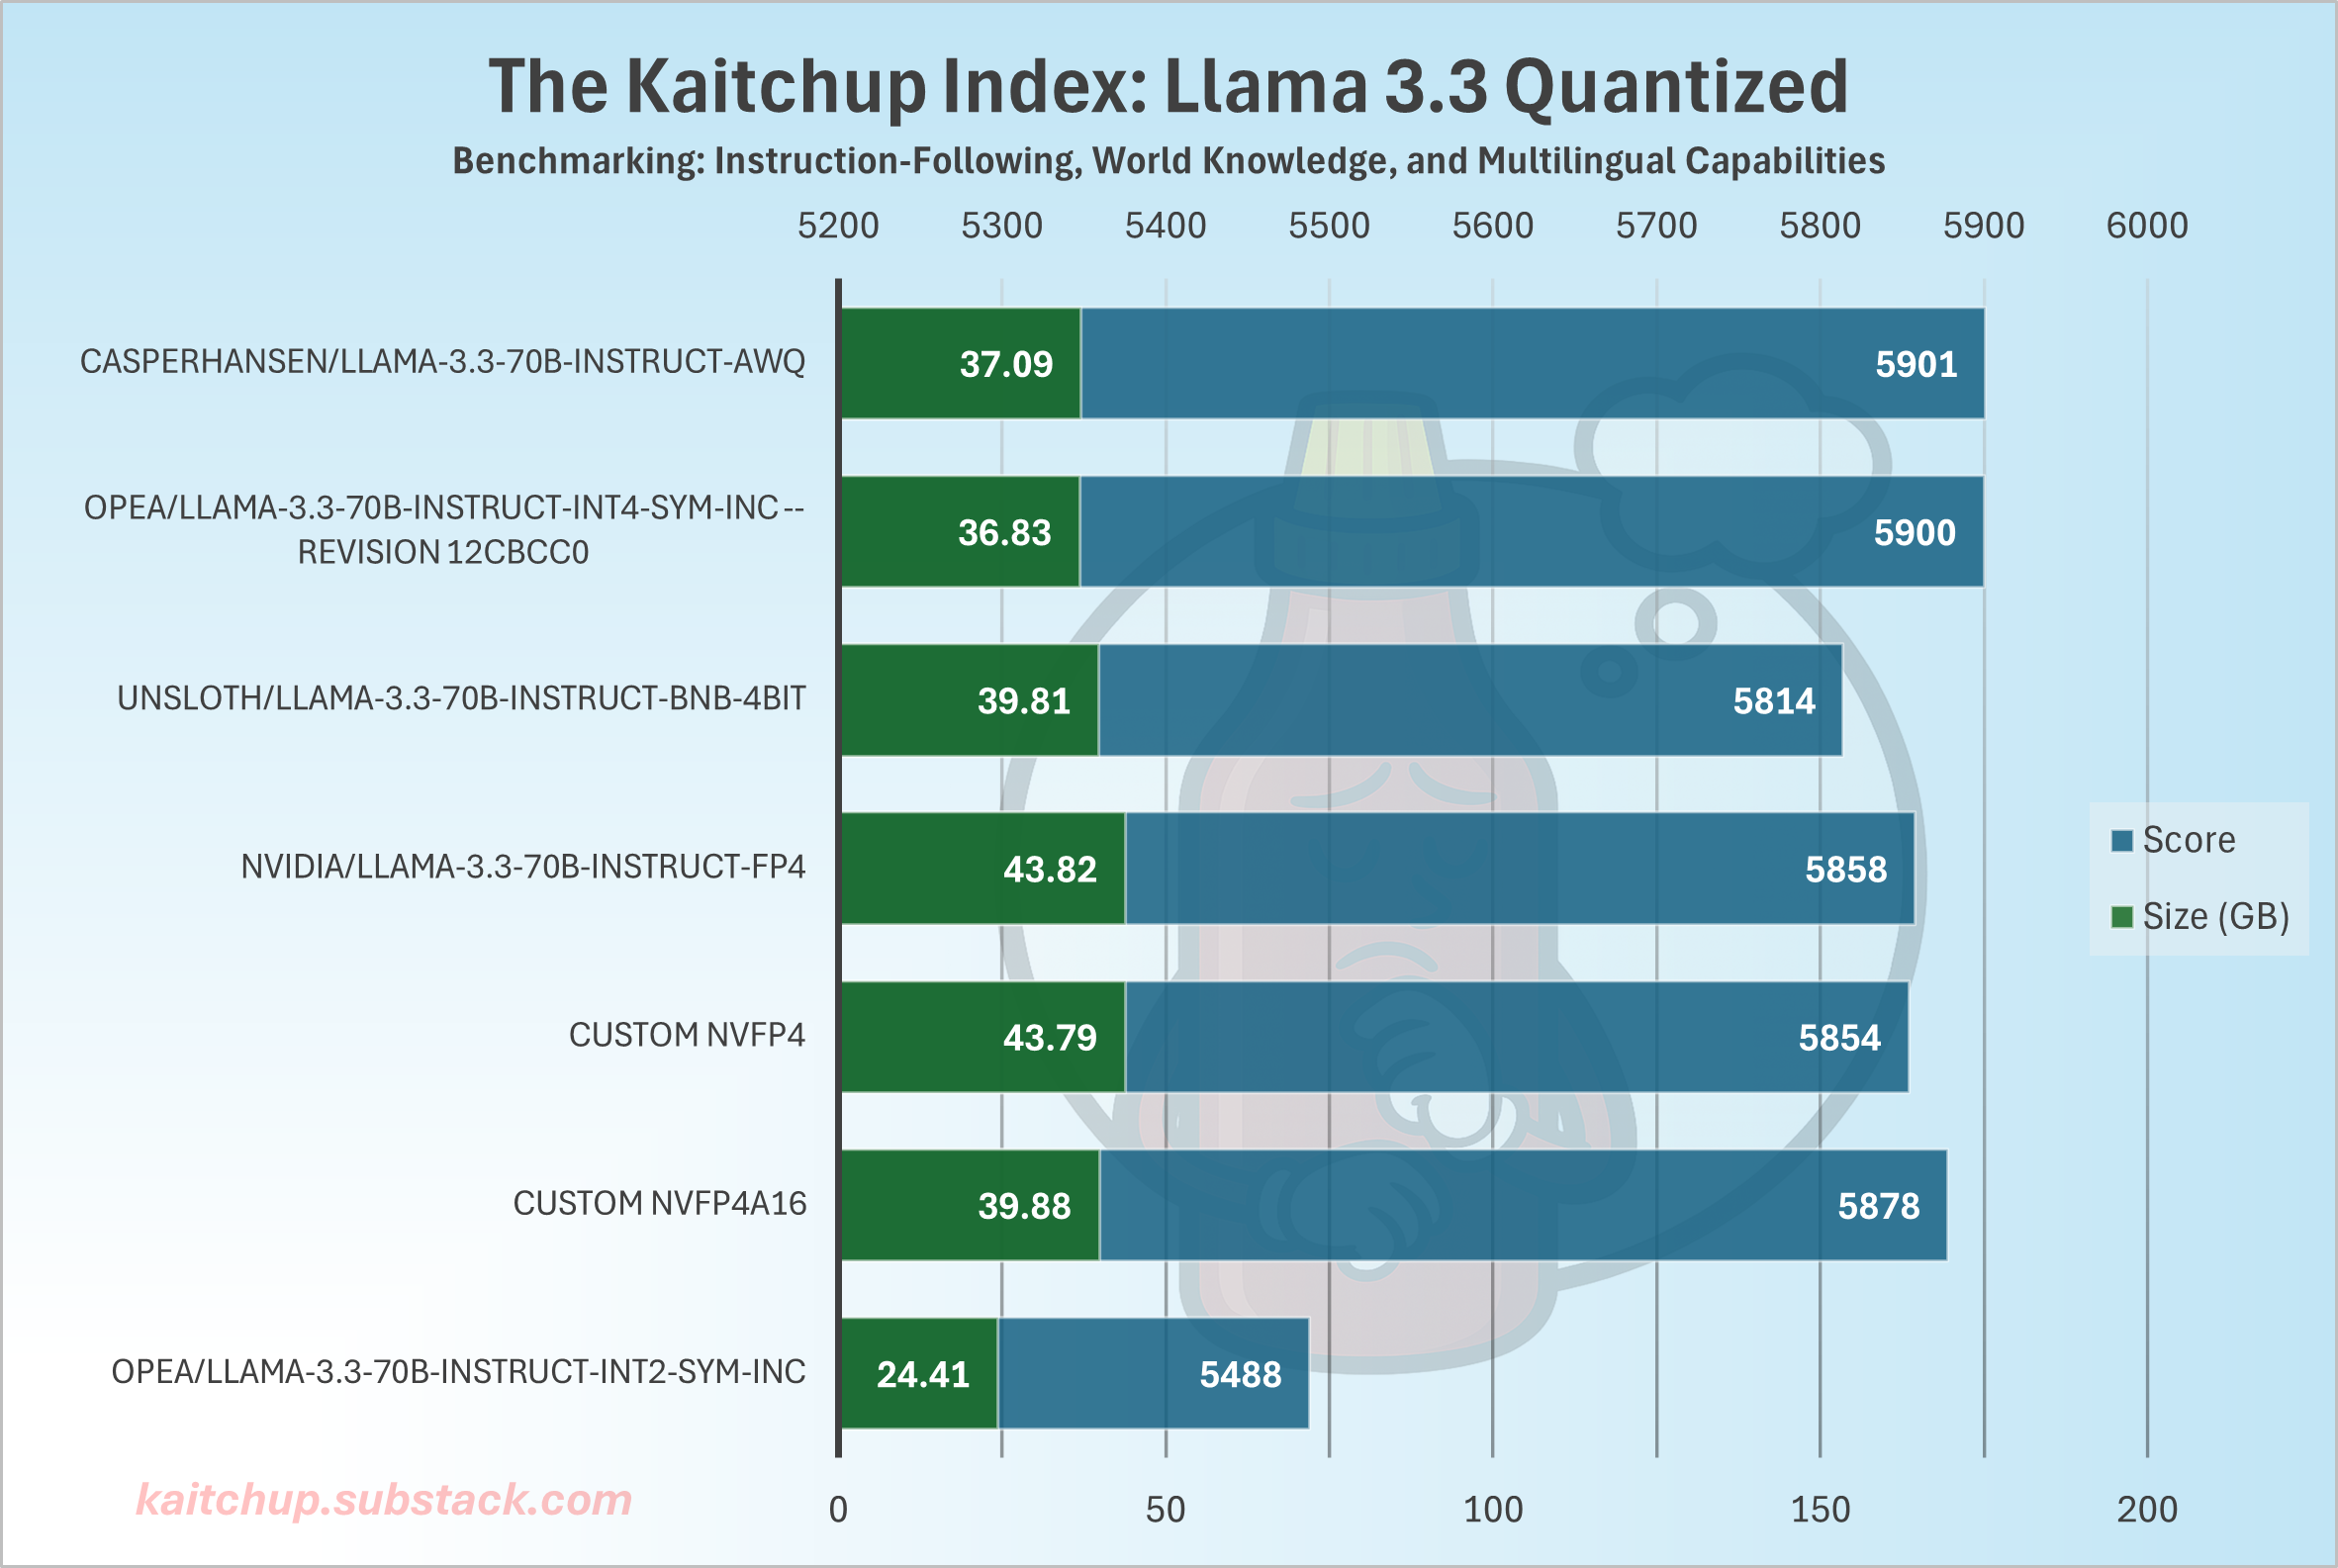
NVFP4: Same Accuracy with 2.3x Higher Throughput for 4-Bit LLMs
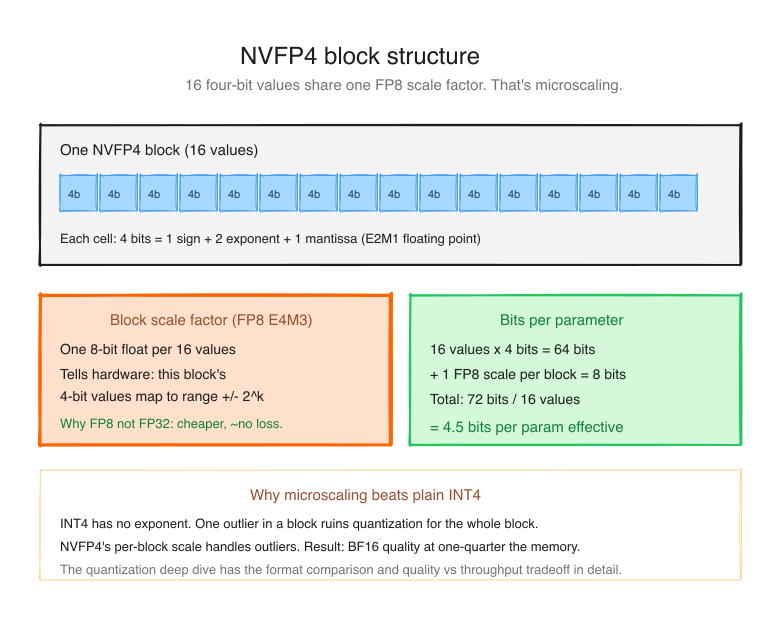
Day 3: DGX Spark Unpacked. GB10, Unified Memory, sm_121, and NVFP4 ...
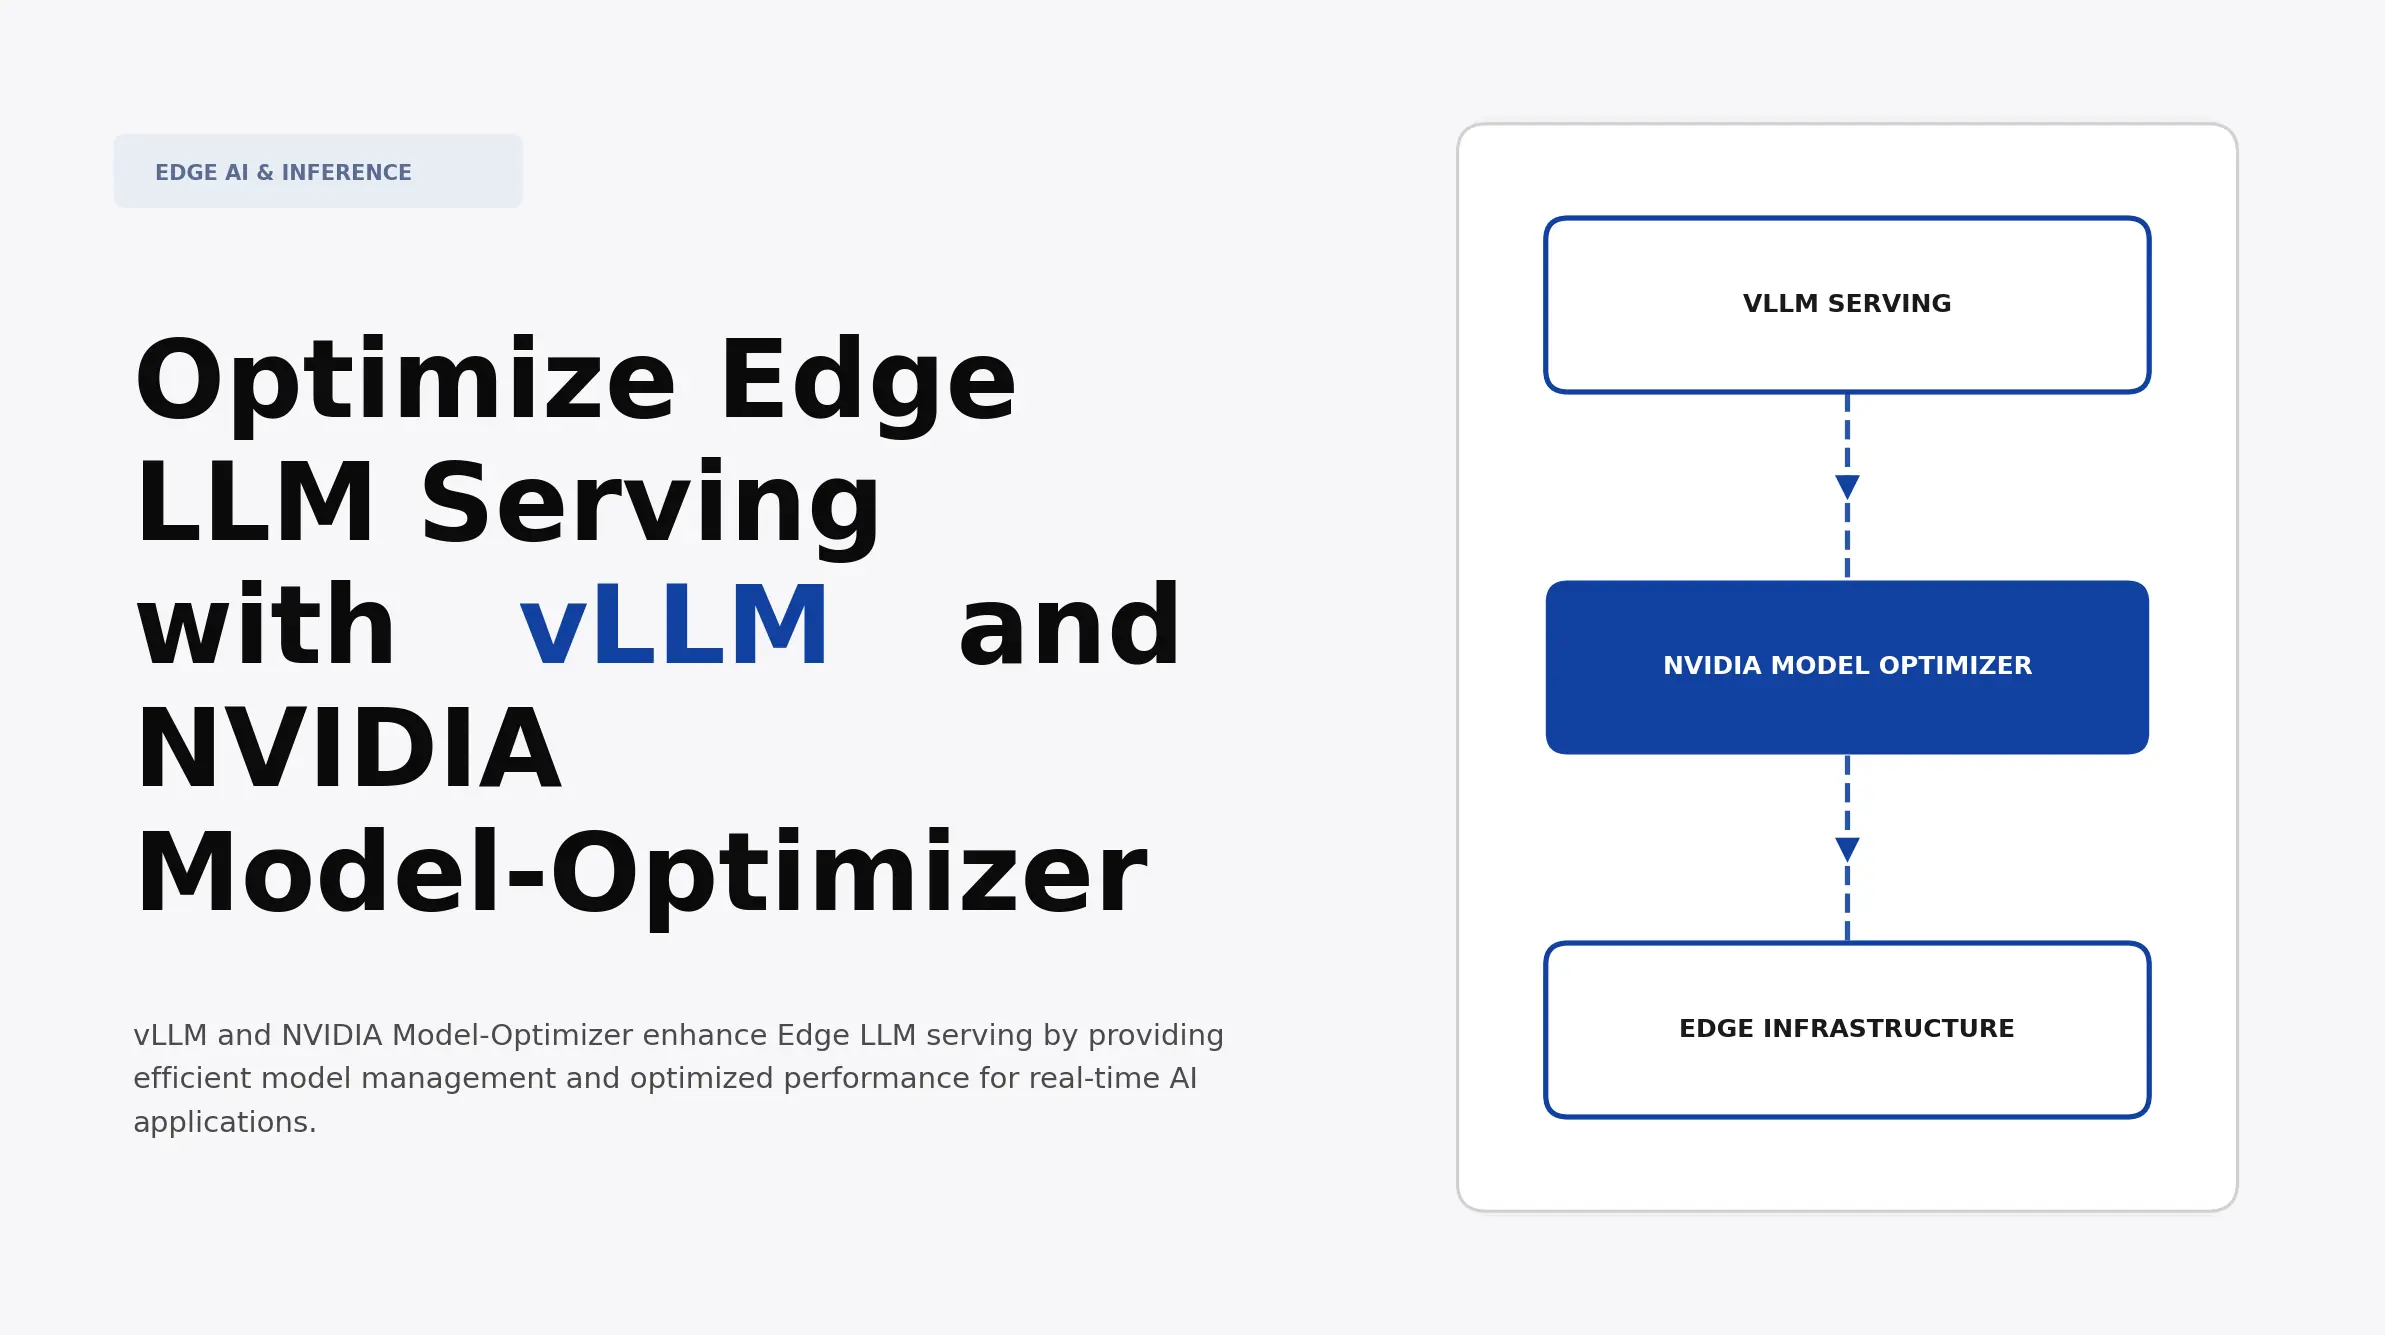
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
Advertisement Space (336x280)

List: AI vLLM | Curated by Oliver Kowalke | Medium

LLMs Get a Speed Boost: New Tech Makes Them BLAZING FAST!
Quartet II: Accurate LLM Pre-Training in NVFP4 by Improved Unbiased ...

Quartet II: Accurate LLM Pre-Training in NVFP4 by Improved Unbiased ...

Introducing NVFP4 for Efficient and Accurate Low-Precision Inference ...

Optimizing LLM Training. TL;DR This blog describes when FSDP is… | by ...