
Optimizing Local Llm Inference On Apple M4 Memory Bottlenecks Vs

Optimizing Local LLM Inference On Apple M4: Memory Bottlenecks Vs ...

Local LLM inference on M4 Max vs M5 Max

LLM Inference on Apple Silicon — M4 Performance Guide (2026)
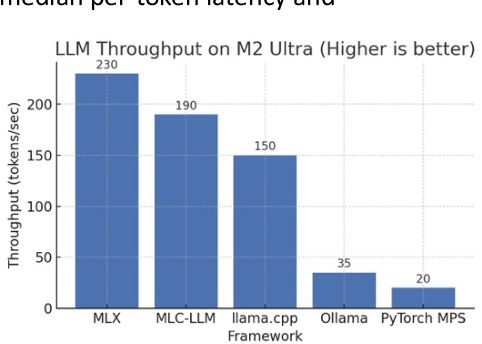
Figure 1 from Production-Grade Local LLM Inference on Apple Silicon: A ...
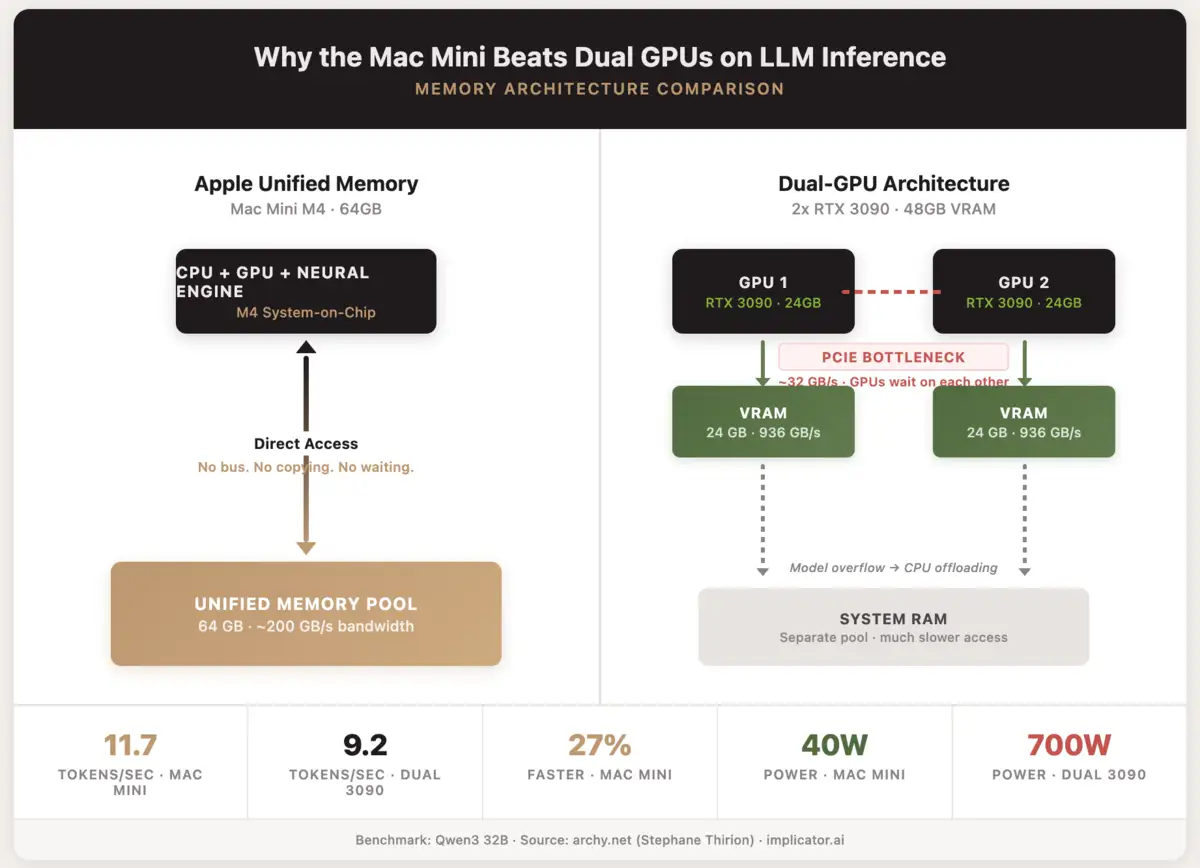
Mac Mini M4 Outpaces Dual RTX 3090s on LLM Inference

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...

Native LLM and MLLM Inference at Scale on Apple Silicon | AI Research ...
Local LLM Benchmarks on Apple Silicon: Token Speed Across M1 to M5 ...

Mac Mini M4 vs Mini PC for Local LLM in 2026 — Which Should You ...

Efficient LLM and MLLM Inference on Apple Silicon
Advertisement Space (300x250)

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
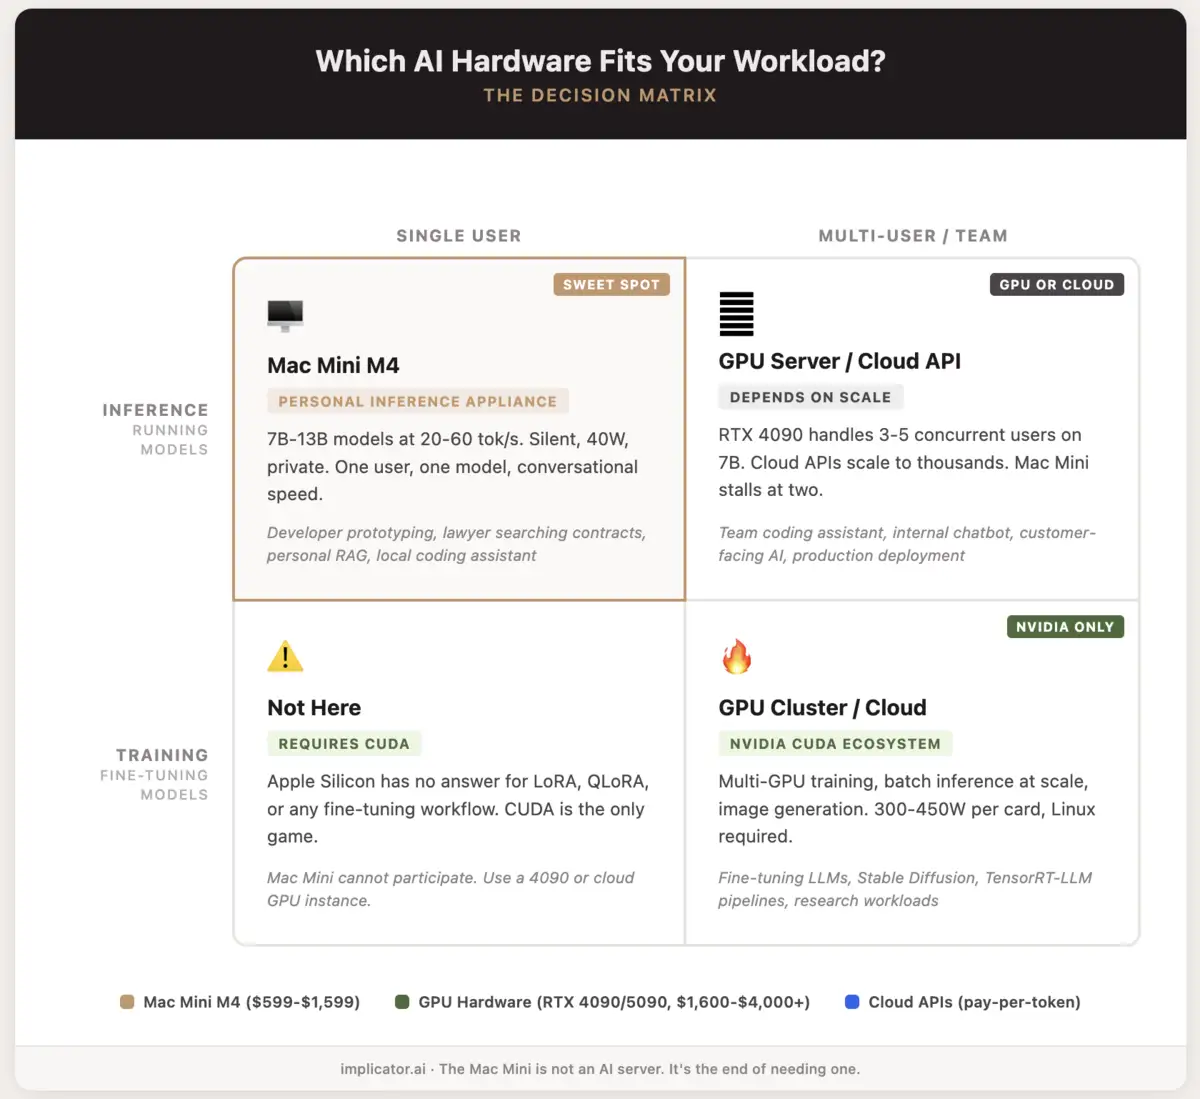
Mac Mini M4 Outpaces Dual RTX 3090s on LLM Inference
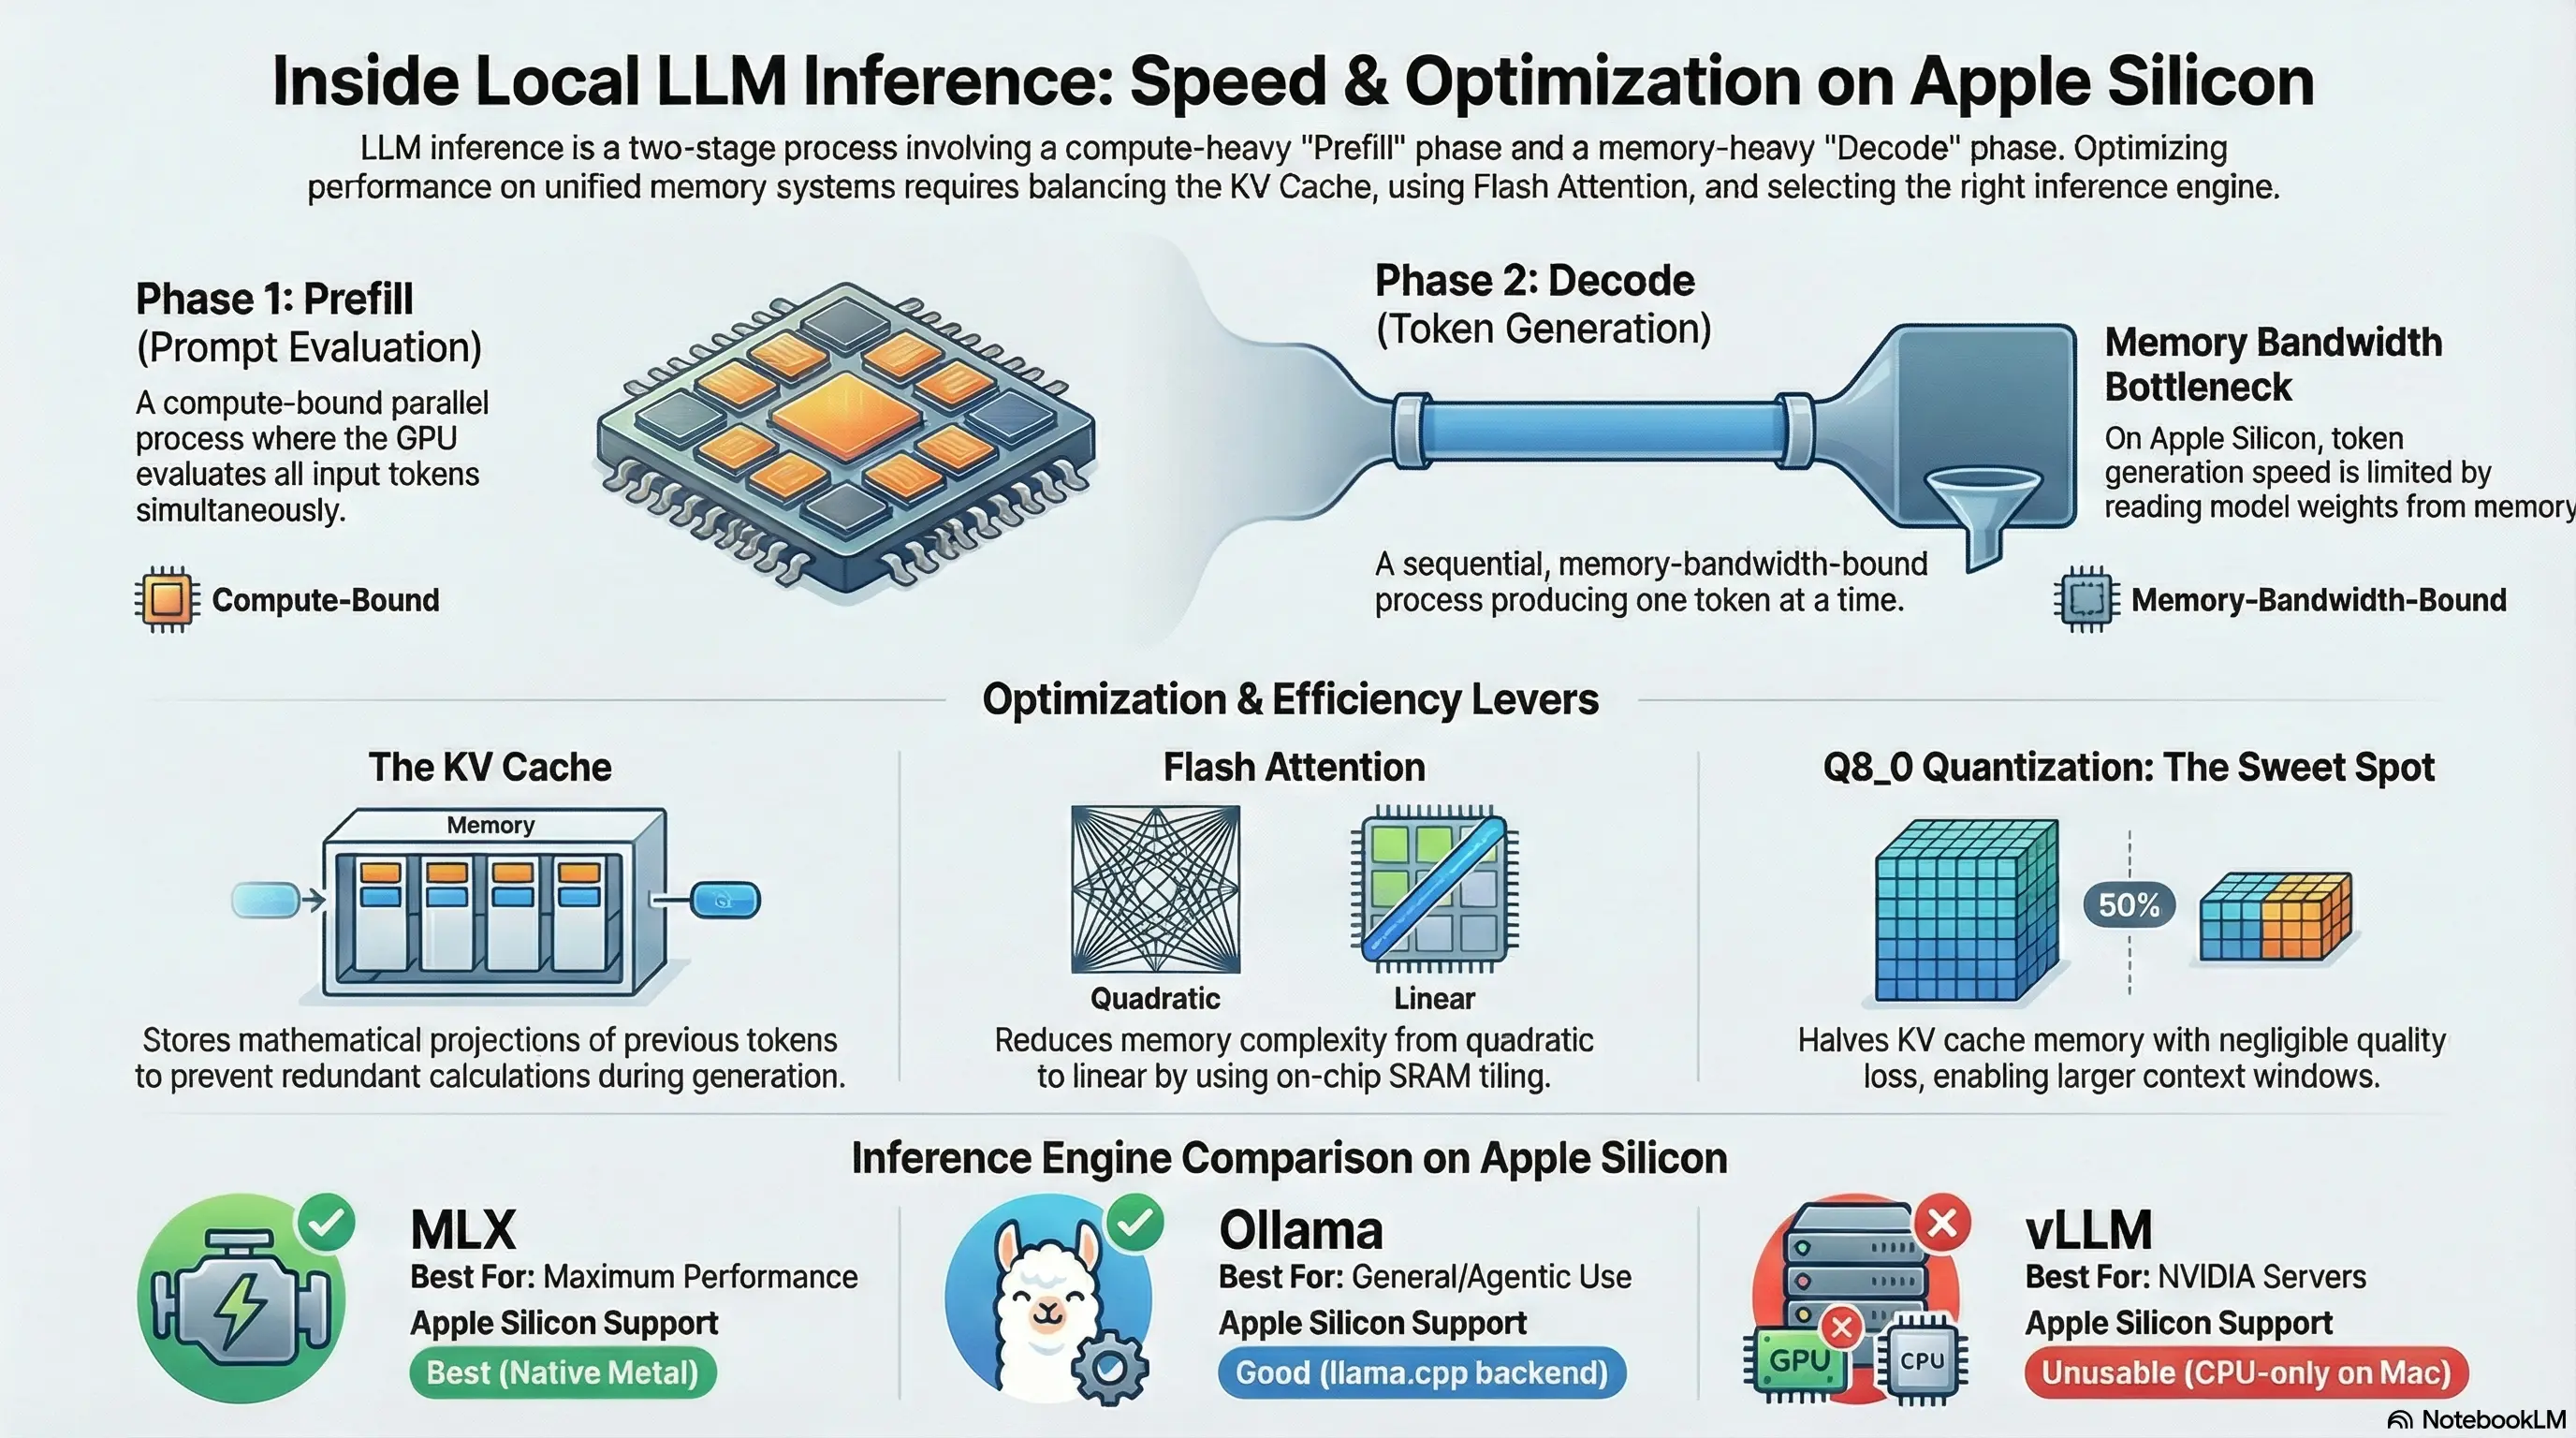
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...

LLM in a flash: Efficient LLM Inference with Limited Memory

Local LLM on M1 Max: 64GB RAM Optimization Guide (2026)

Apple Silicon LLM Inference Optimization: The Complete Guide to Maximum ...
Apple Silicon MLX LLM Inference Optimization Tutorial | Branch8
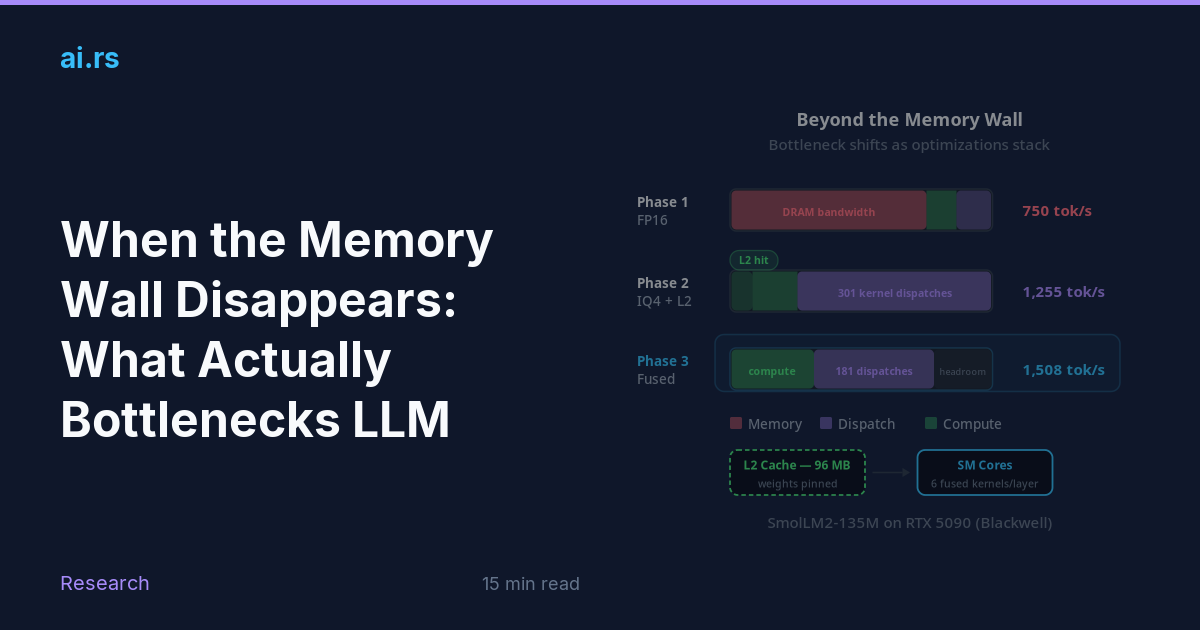
When the Memory Wall Disappears: What Actually Bottlenecks LLM ...

Diagnosing Retrieval vs. Utilization Bottlenecks in LLM Agent Memory ...
LLM Inference Bottlenecks
Advertisement Space (336x280)
Estimating LLM Inference Memory Requirements
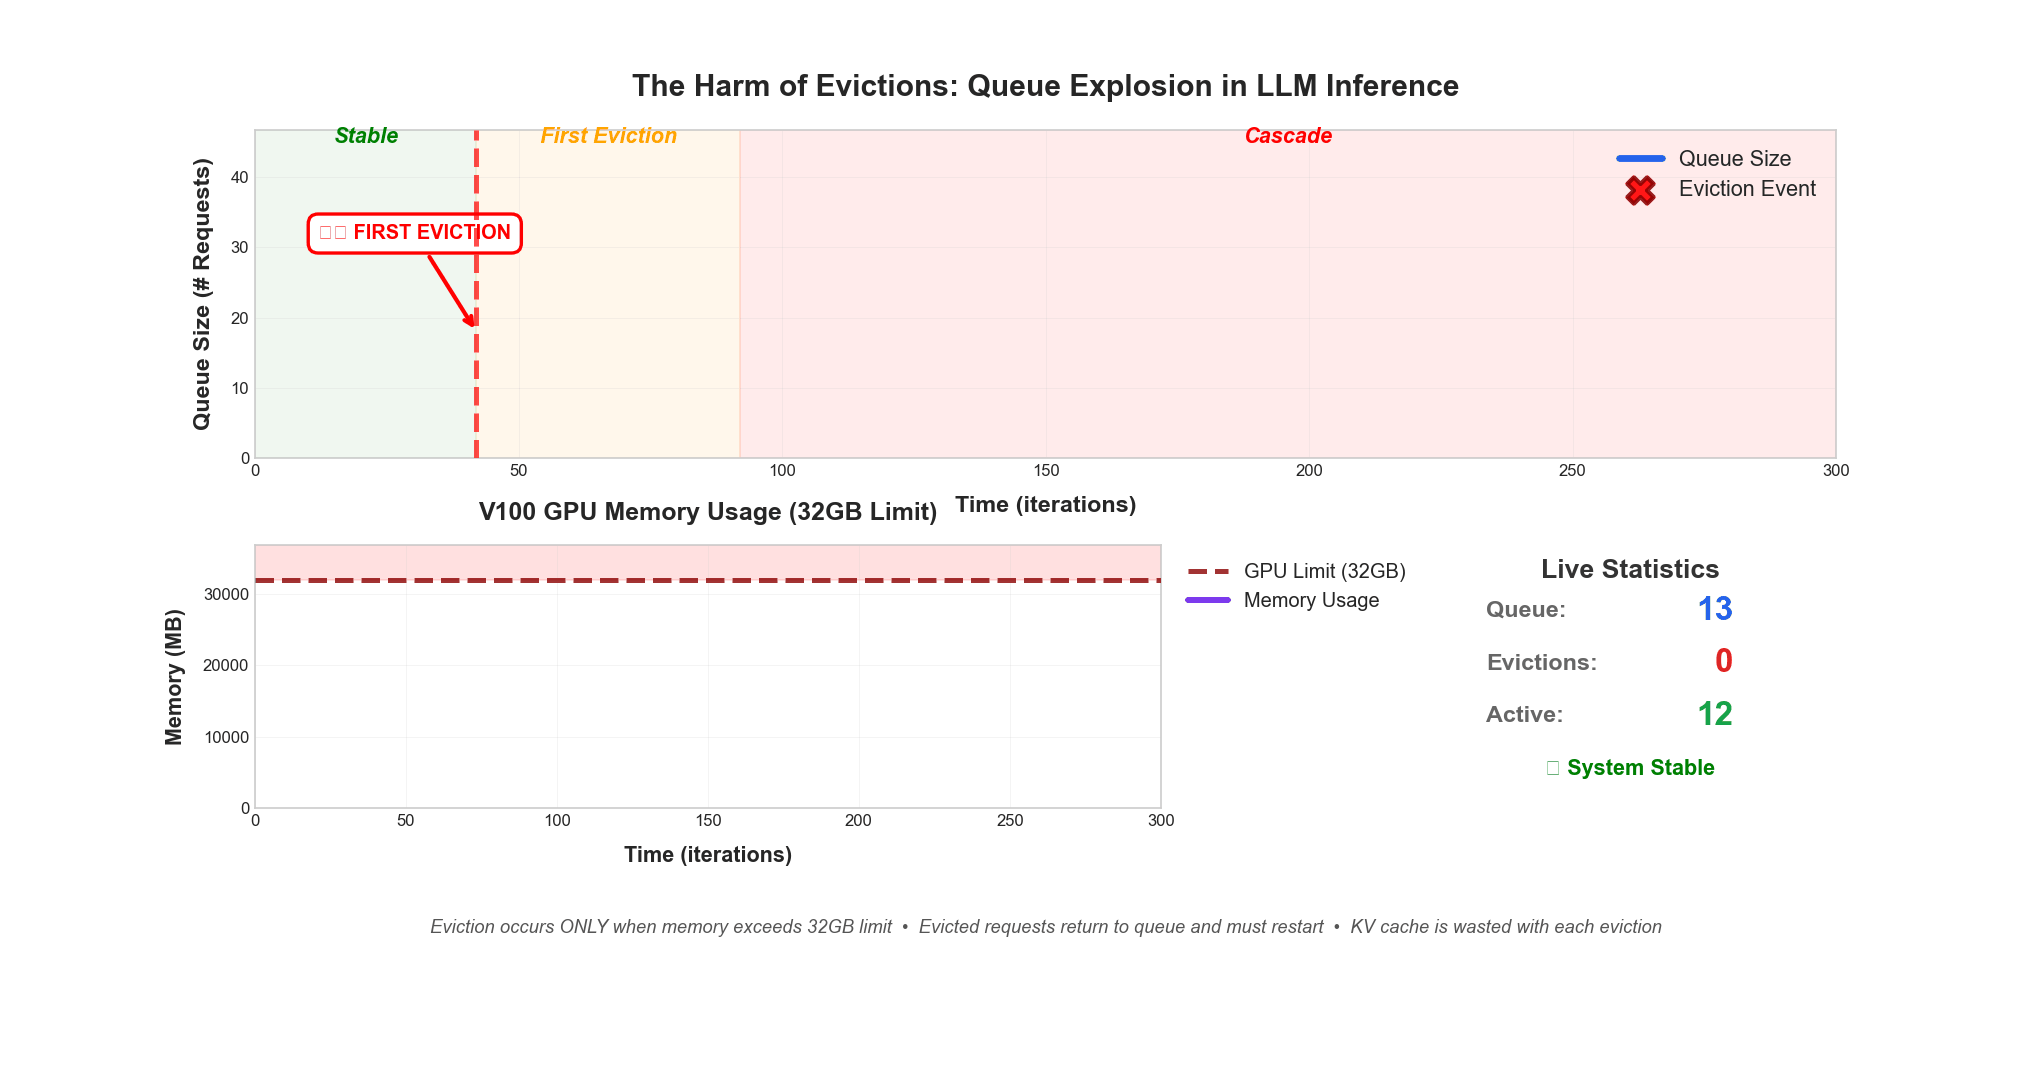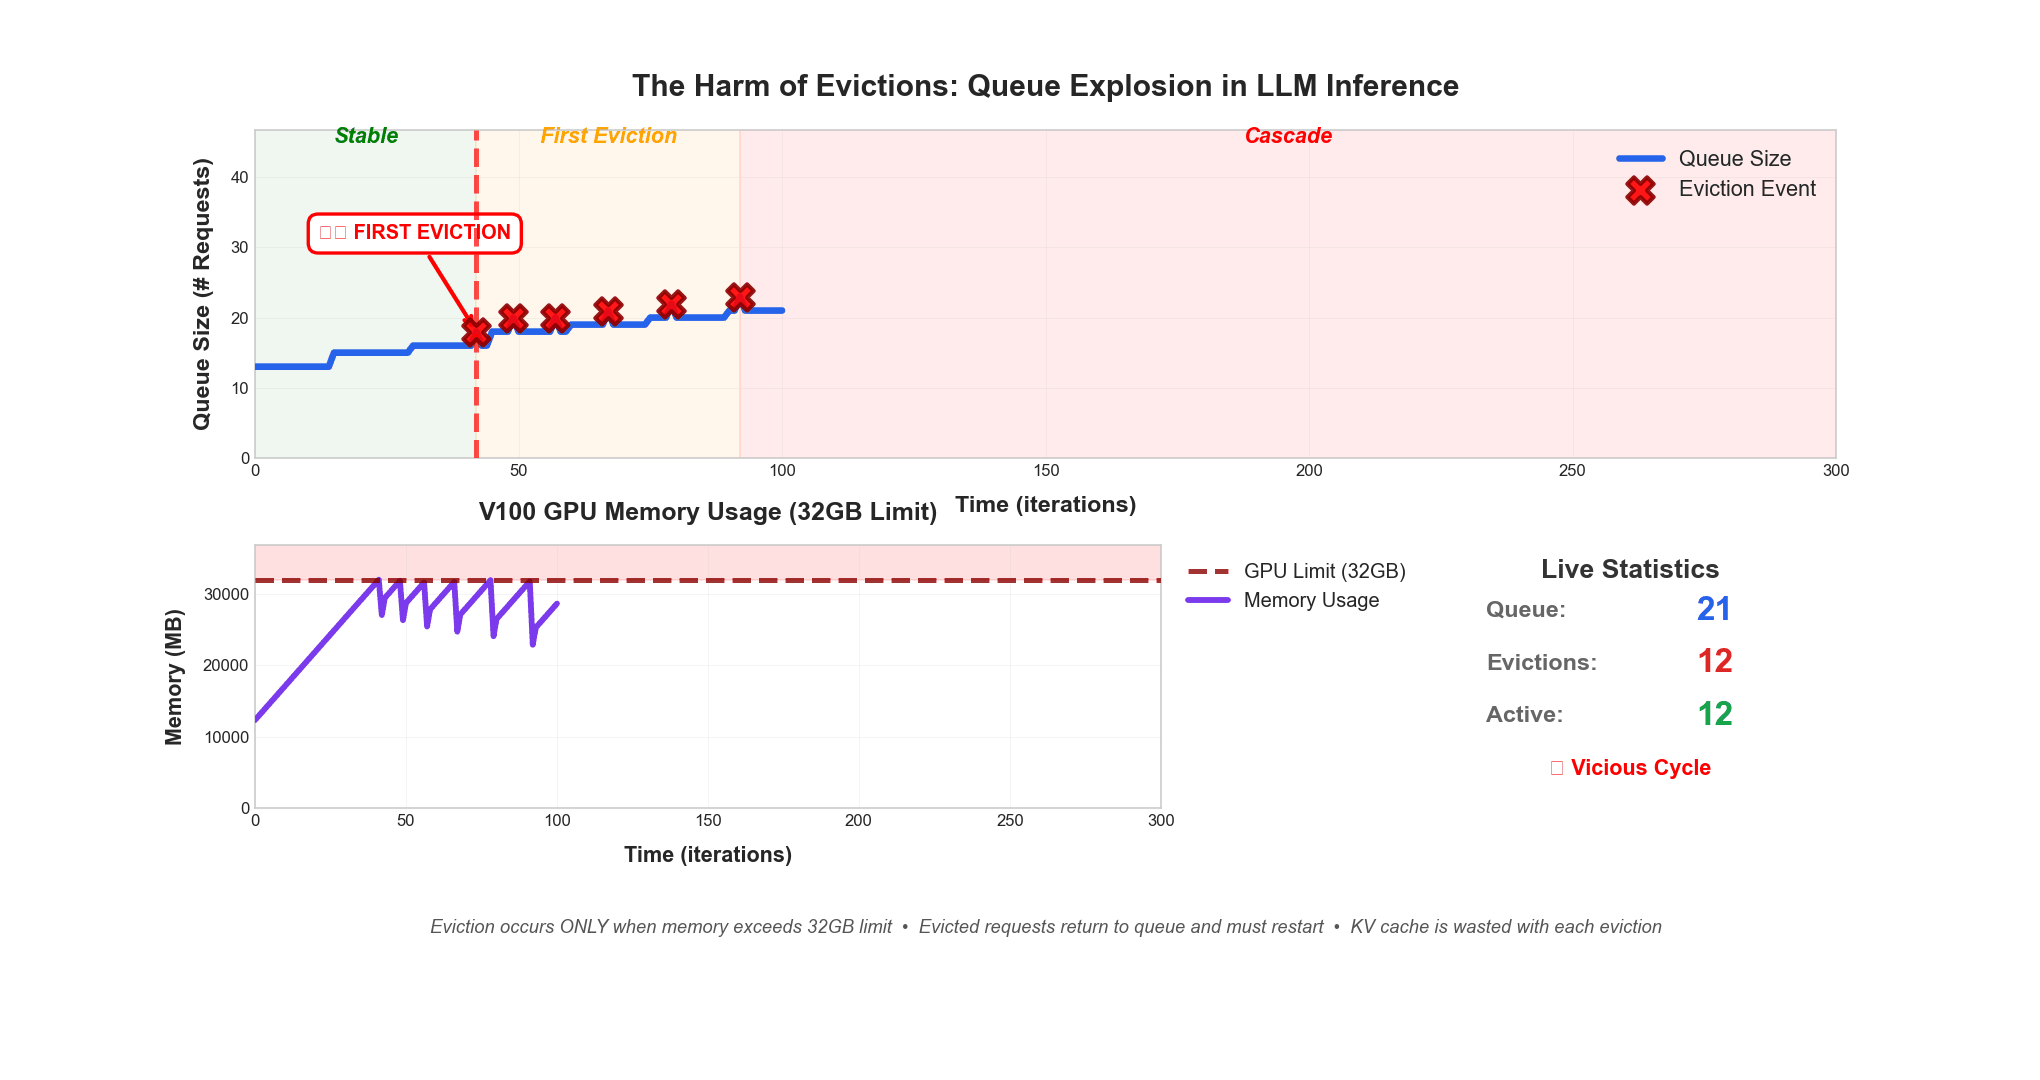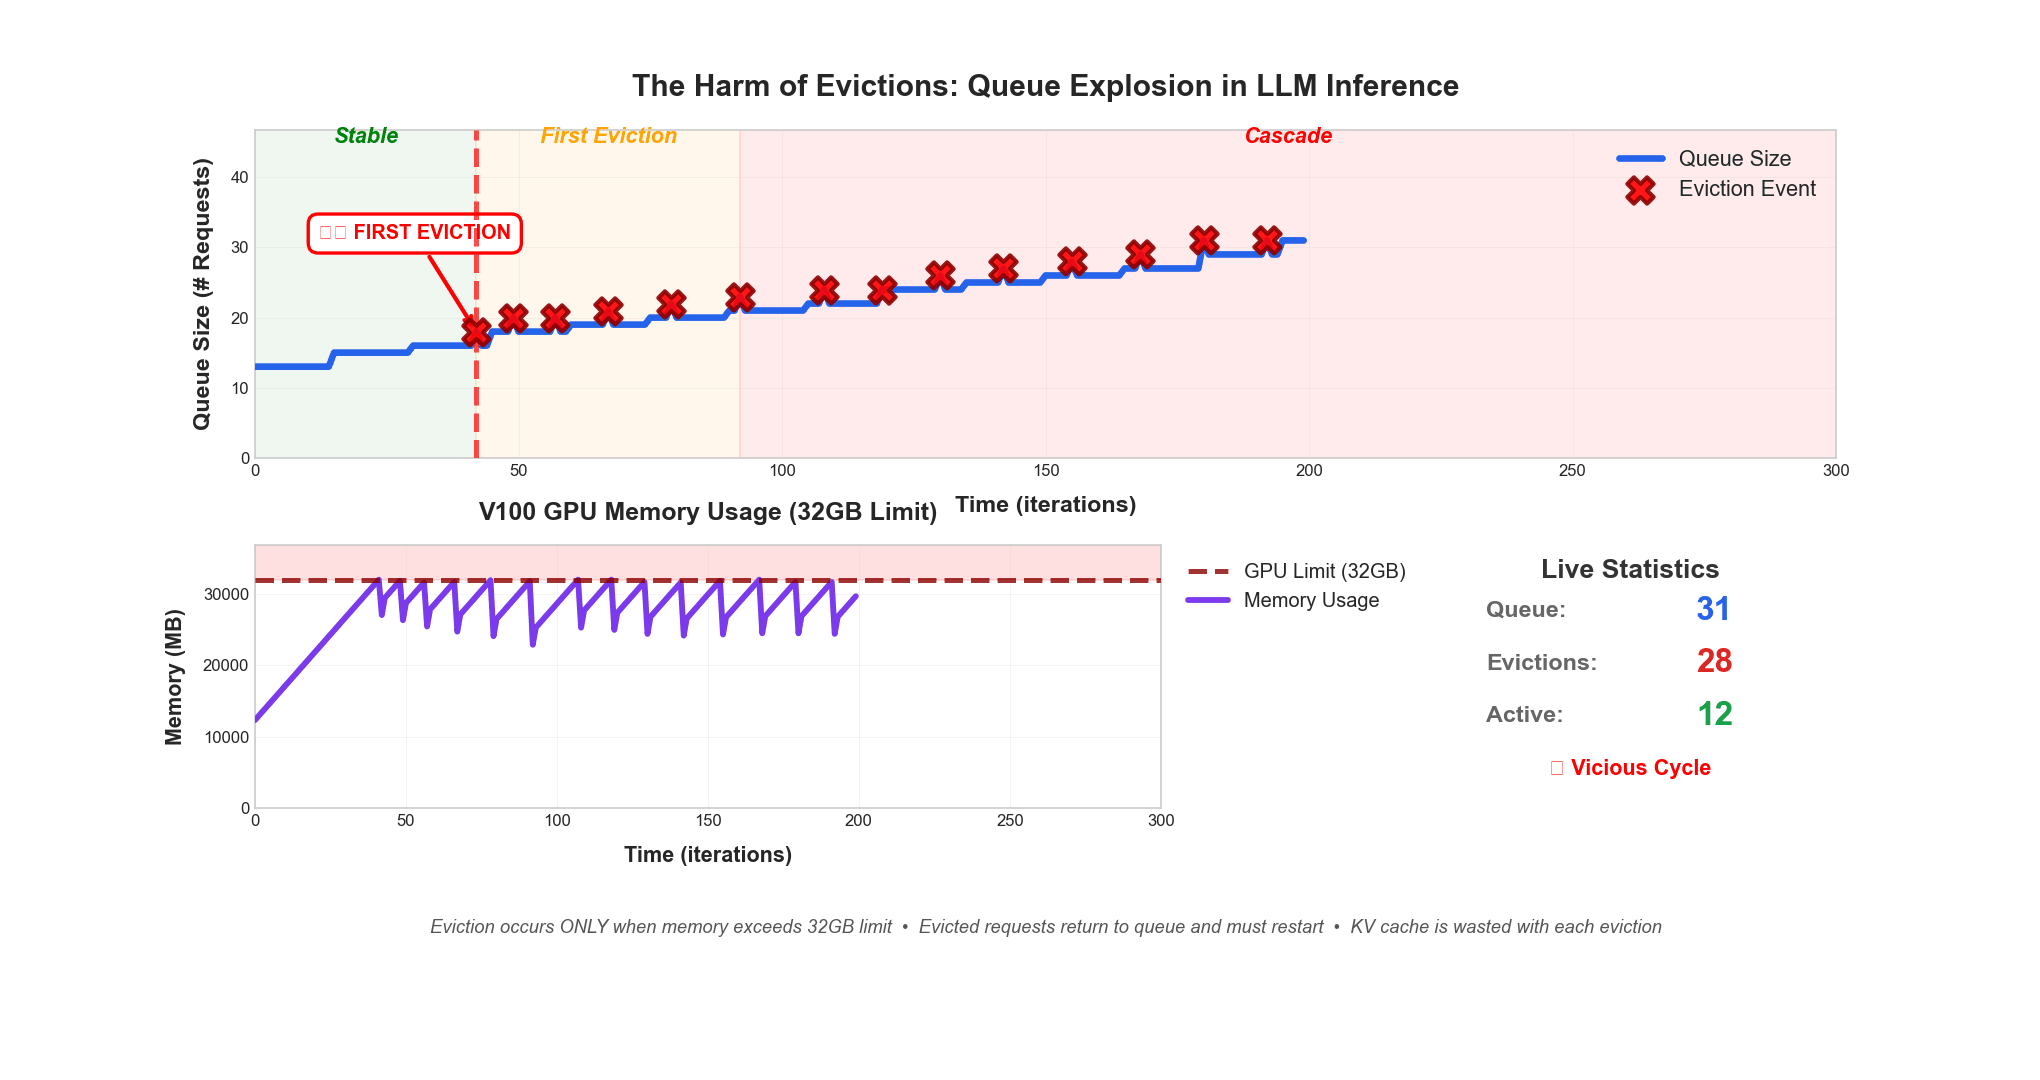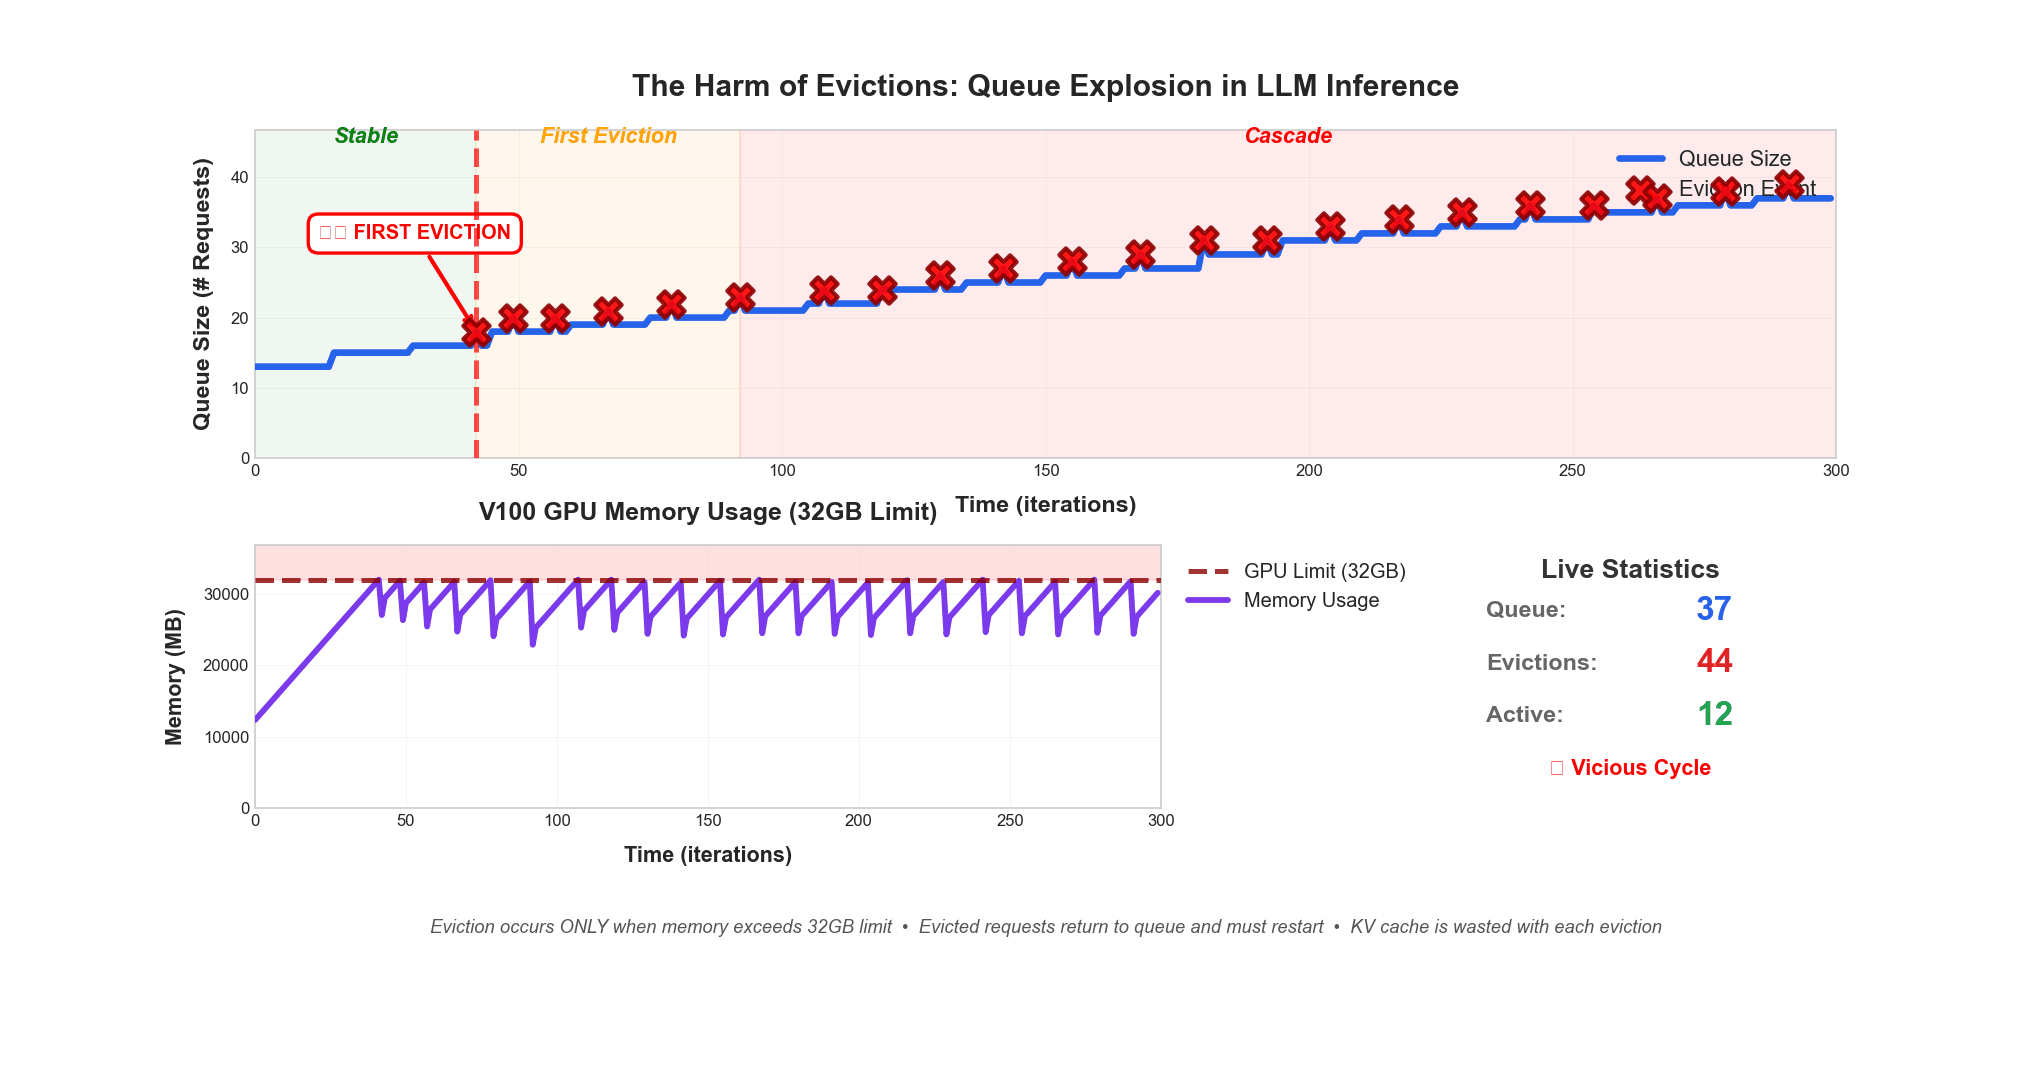
Optimizing LLM Inference: Fluid-Guided Online Scheduling with Memory ...

[论文评述] Diagnosing Retrieval vs. Utilization Bottlenecks in LLM Agent Memory

How to Run Local LLM Apple Silicon Mac (M1/M2/M3/M4 Guide) - Carthage ...
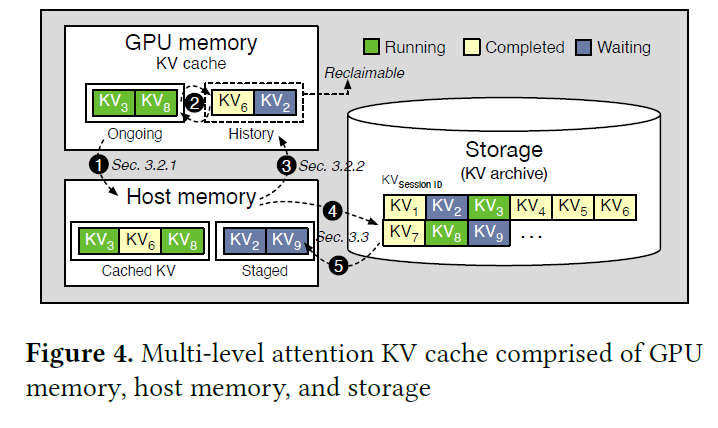
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Deep Dive: Optimizing LLM inference - YouTube
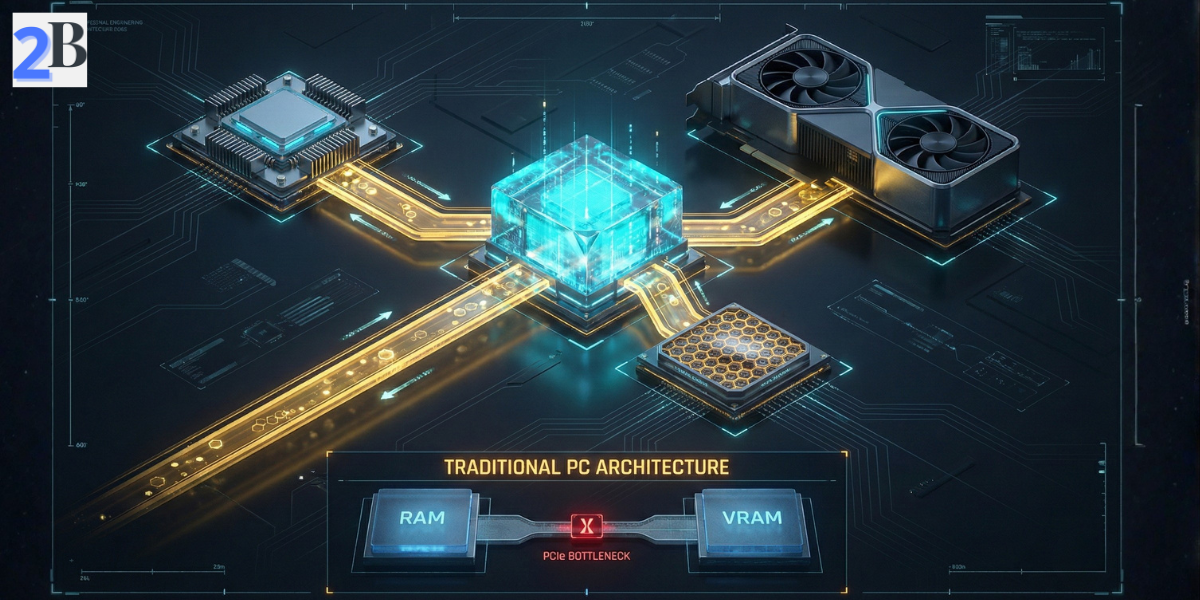
Mac Mini M4 Local LLM Server: The Ultimate AI Powerhouse for Small ...
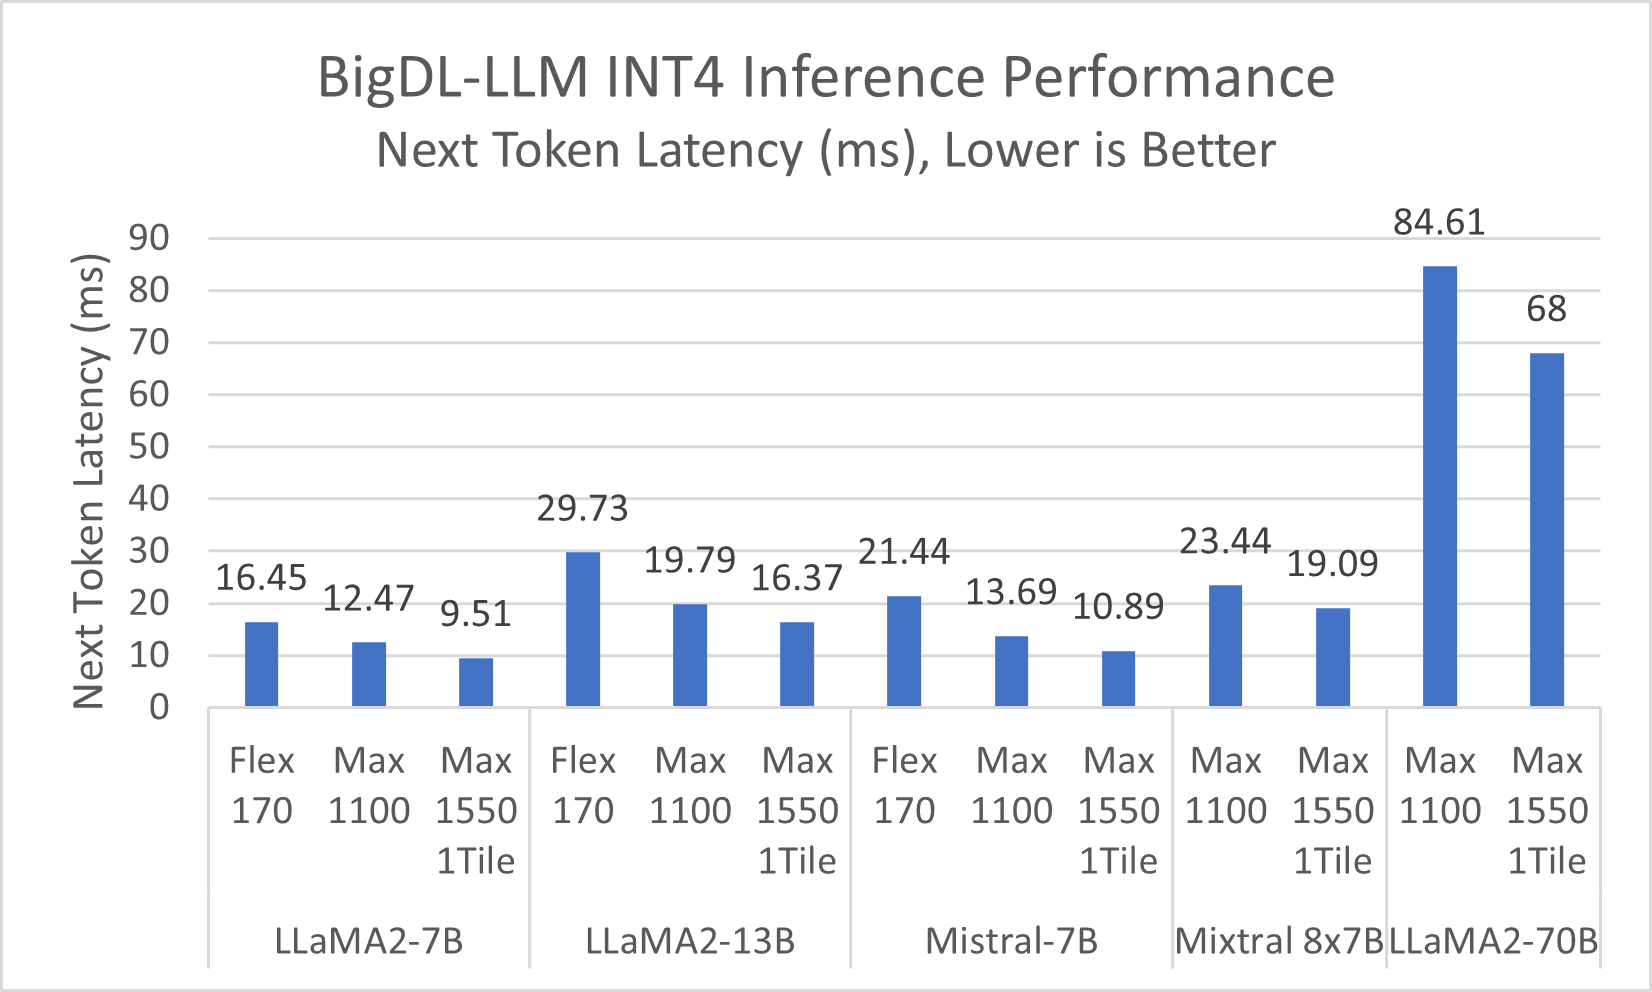
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM

M5 Chip Shows Major Speed Gains in Local LLM Performance Over the M4 ...
Apple Silicon LLM Inference Guide | Starmorph Config | Starmorph
Advertisement Space (336x280)

Apple shows how much faster the M5 runs local LLMs on MLX - 9to5Mac
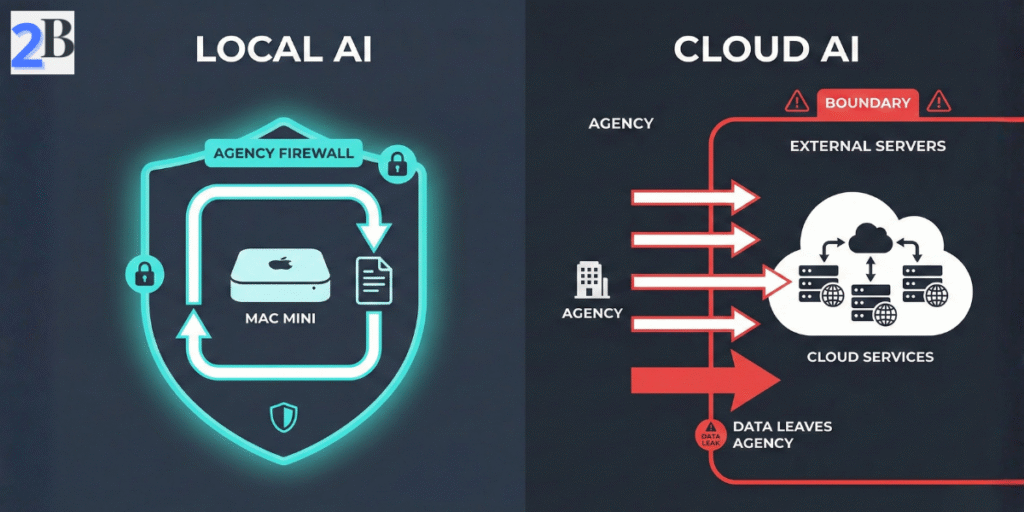
Mac Mini M4 Local LLM Server: The Ultimate AI Powerhouse for Small ...
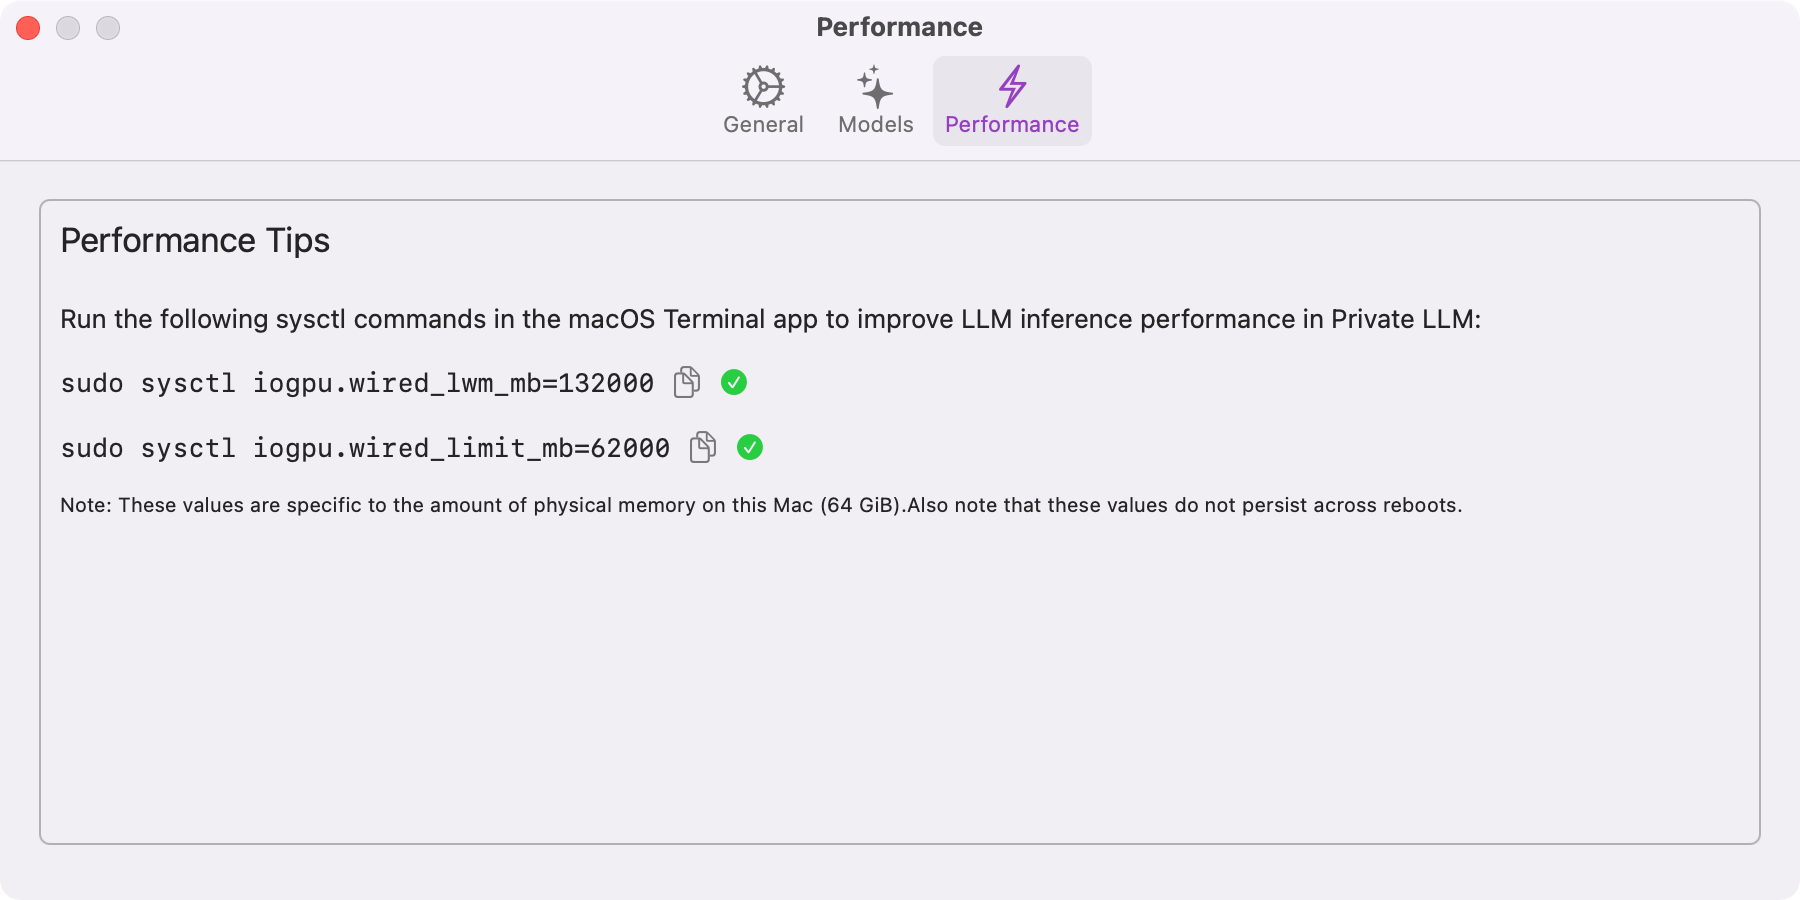
Local LLM on iPhone, iPad, and Mac: Run Local AI Offline

Why LLM Inference Gets Fast and Then Runs Out of Memory
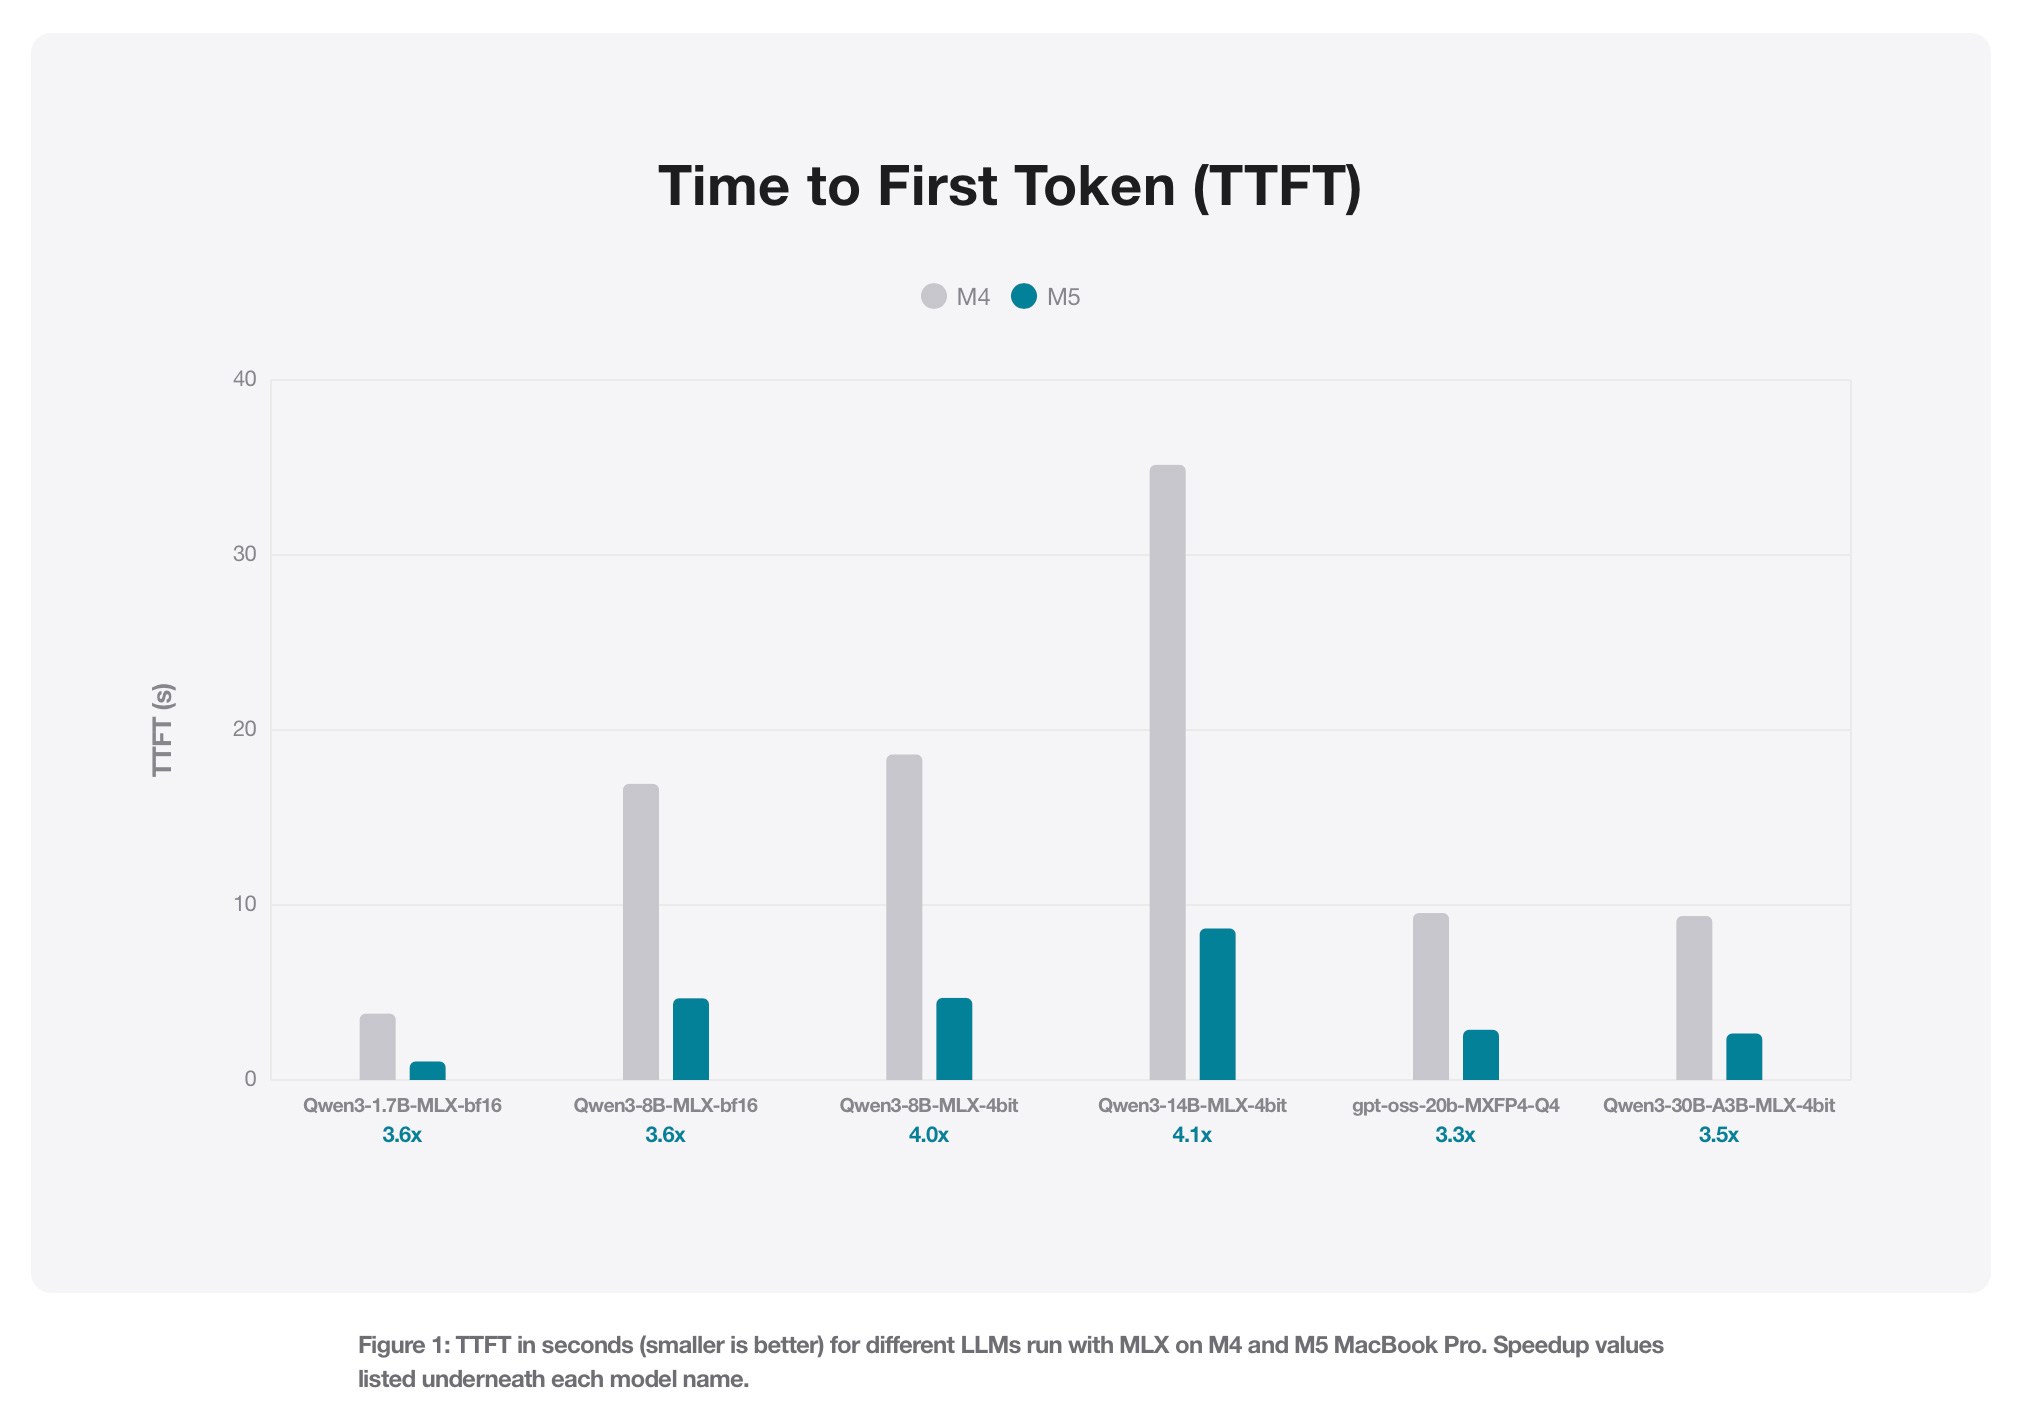
Apple shows how much faster the M5 runs local LLMs on MLX - 9to5Mac
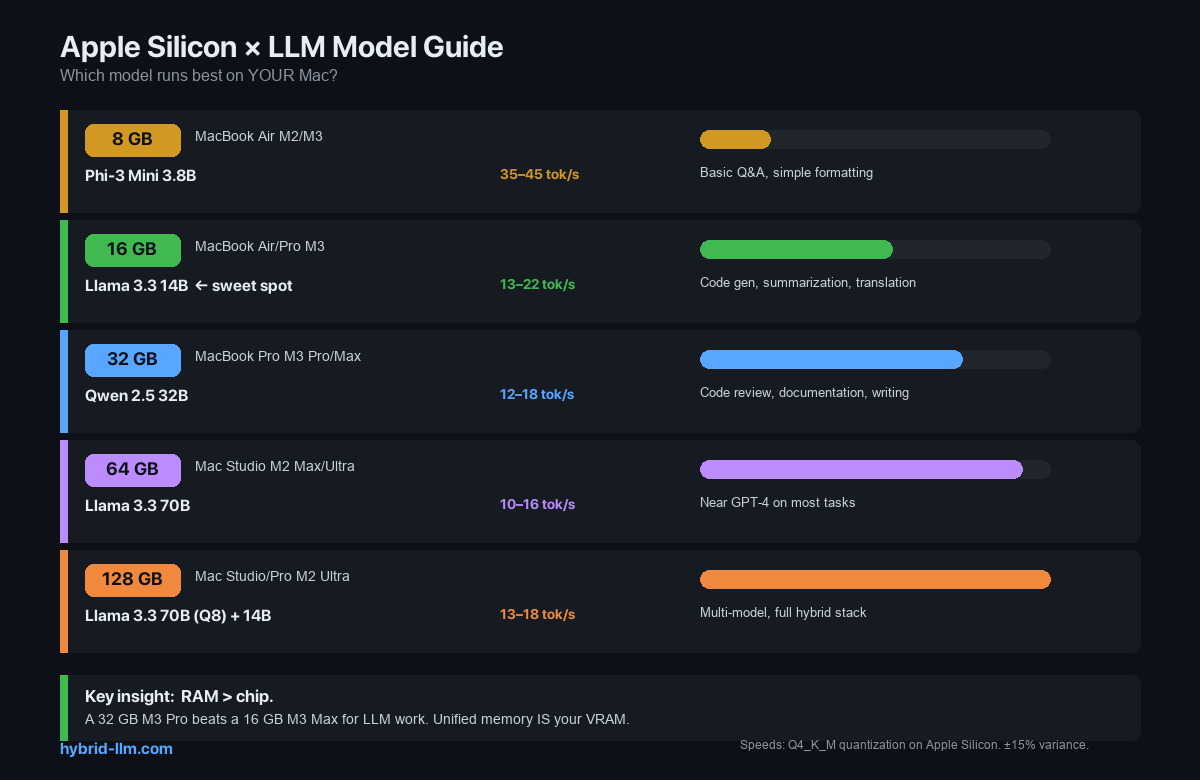
Best Local LLM Models for M2/M3/M4 Mac: Performance Benchmark 2026 ...