
Paper Page Baq Efficient Bit Allocation Quantization For Large

Paper page - BAQ: Efficient Bit Allocation Quantization for Large ...

Paper page - RoPE-Aware Bit Allocation for KV-Cache Quantization

Paper page - RoPE-Aware Bit Allocation for KV-Cache Quantization

(PDF) Optimal Quantization and Bit Allocation for Compressing Large ...

Paper page - Mixed-Precision Graph Neural Quantization for Low Bit ...

Paper page - Efficient Quantization Strategies for Latent Diffusion Models

Paper page - QQQ: Quality Quattuor-Bit Quantization for Large Language ...

Paper page - Atom: Low-bit Quantization for Efficient and Accurate LLM ...

Paper page - ELUTQ: Efficient LUT-Aware Quantization for Deploying ...

Paper page - MixPE: Quantization and Hardware Co-design for Efficient ...
Advertisement Space (300x250)

Paper page - KV Cache is 1 Bit Per Channel: Efficient Large Language ...

Paper page - ParoQuant: Pairwise Rotation Quantization for Efficient ...

Paper page - GPTQv2: Efficient Finetuning-Free Quantization for ...

Paper page - A Survey of Quantization Methods for Efficient Neural ...
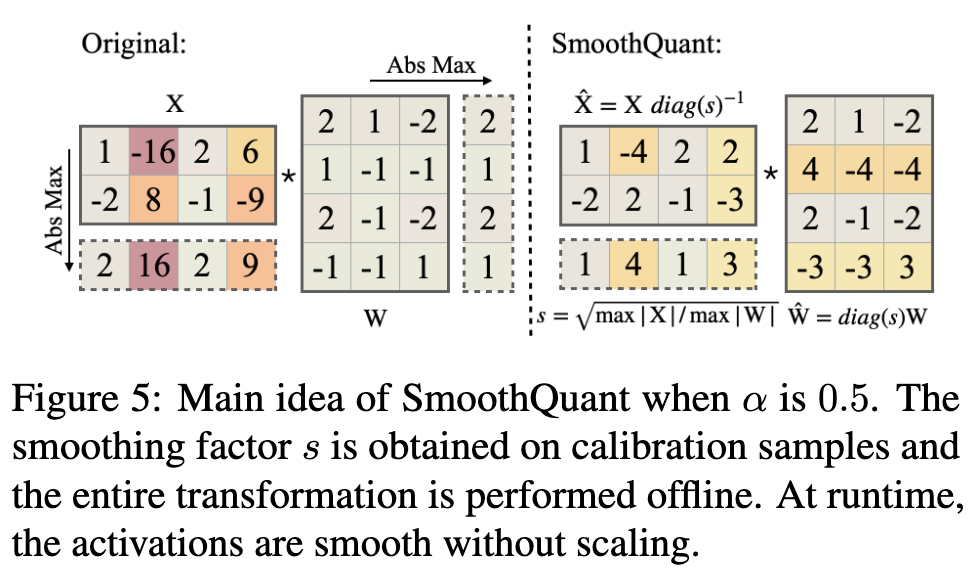
SmoothQuant Accurate and Efficient Post-Training Quantization for Large ...

Paper page - EfficientQAT: Efficient Quantization-Aware Training for ...
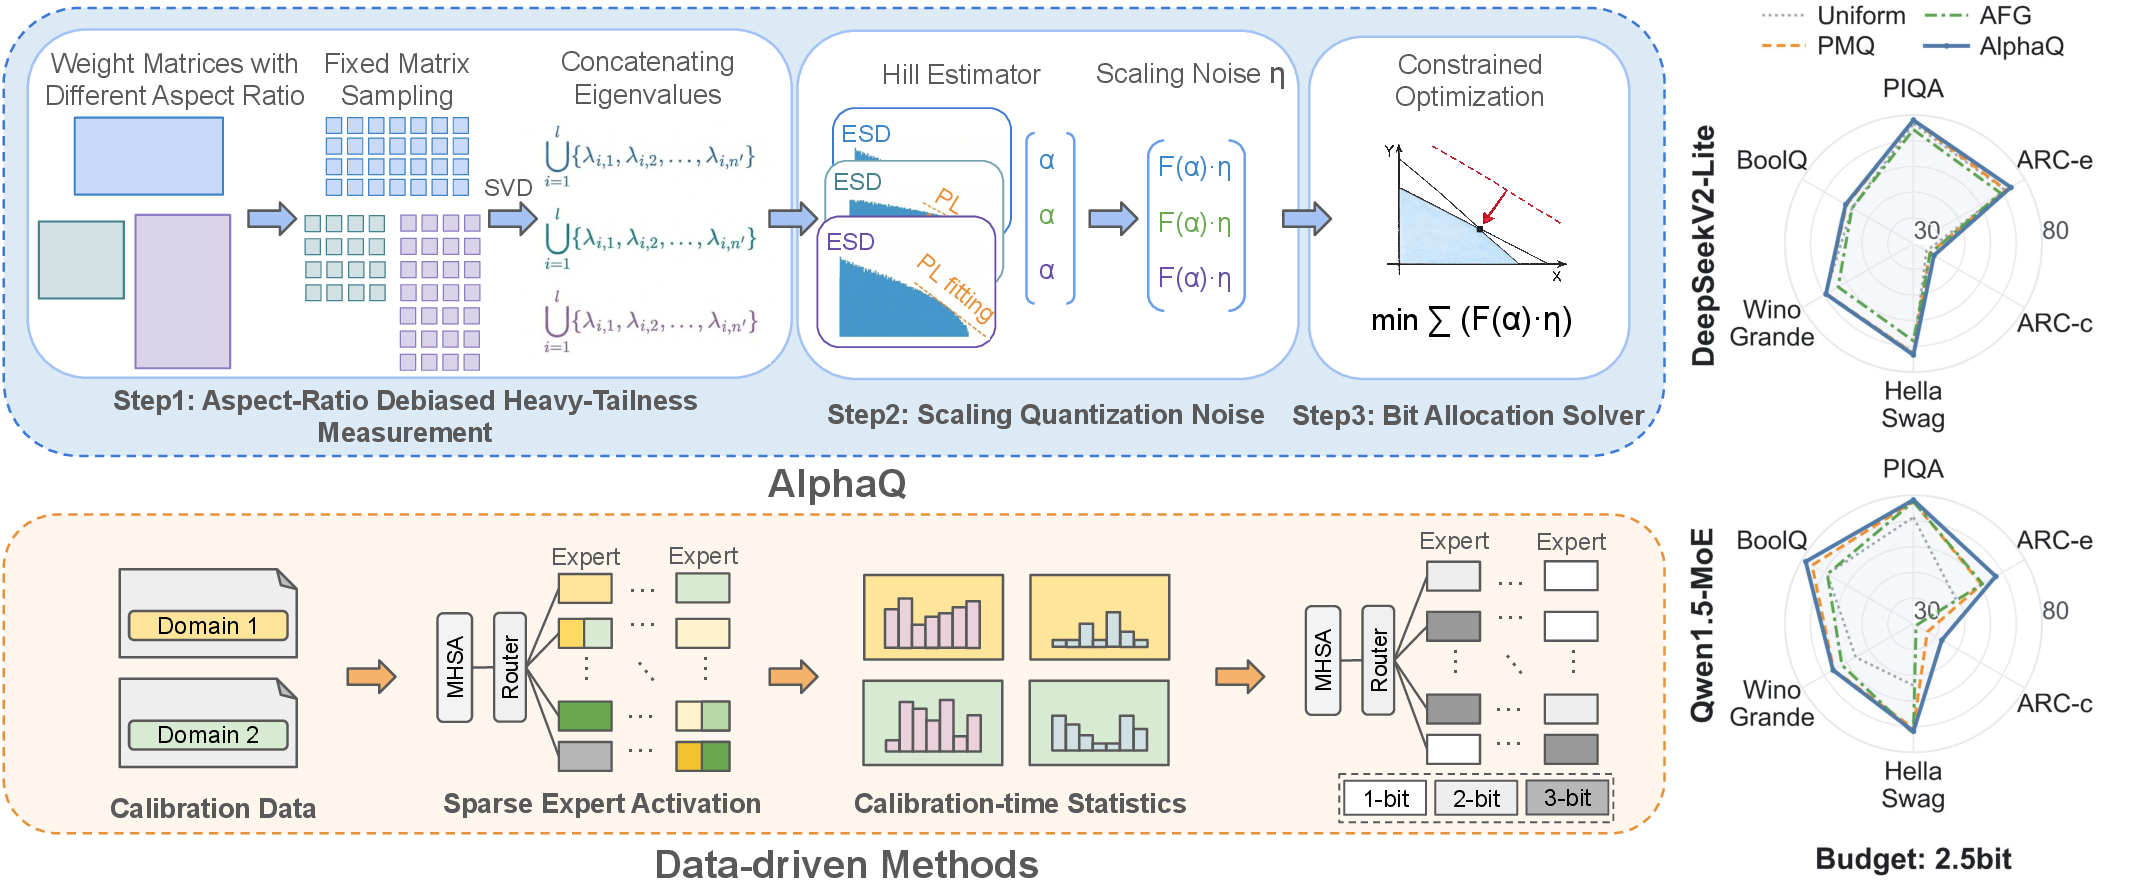
AlphaQ: Calibration-Free Bit Allocation for Mixture-of-Experts Quantization

Latitude-Adaptive Integer Bit Allocation for Quantization of ...

Paper page - QuIP: 2-Bit Quantization of Large Language Models With ...

Paper page - Outlier-Safe Pre-Training for Robust 4-Bit Quantization of ...
Advertisement Space (336x280)

(PDF) An efficient key point quantization algorithm for large scale ...

(PDF) Efficient bit allocation and CTU level rate control for High ...

Paper page - MergeQuant: Accurate 4-bit Static Quantization of Large ...

Mixed-Precision Graph Neural Quantization for Low Bit Large Language Models

Paper page - From 16-Bit to 1-Bit: Visual KV Cache Quantization for ...
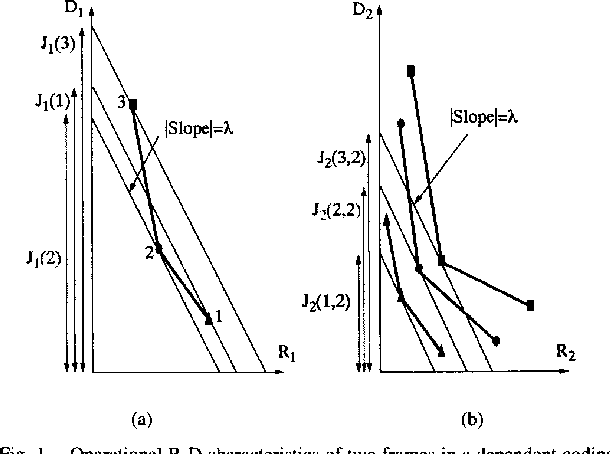
Figure 1 from Bit allocation for dependent quantization with ...

Paper page - Task Vector Quantization for Memory-Efficient Model Merging

Paper page - AMAQ: Adaptive Mixed-bit Activation Quantization for ...

[논문 리뷰] Mixed-Precision Graph Neural Quantization for Low Bit Large ...
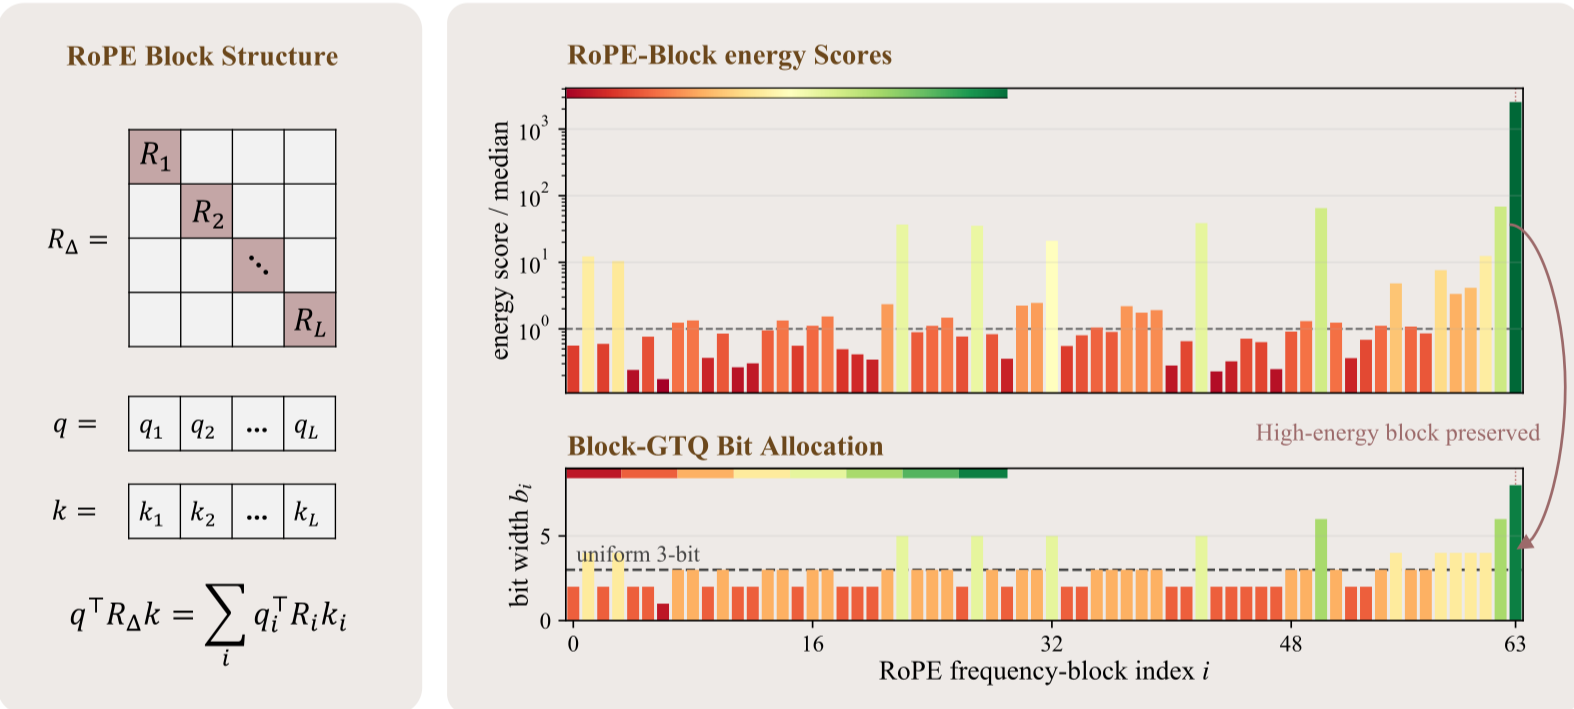
[논문 리뷰] RoPE-Aware Bit Allocation for KV-Cache Quantization
Advertisement Space (336x280)
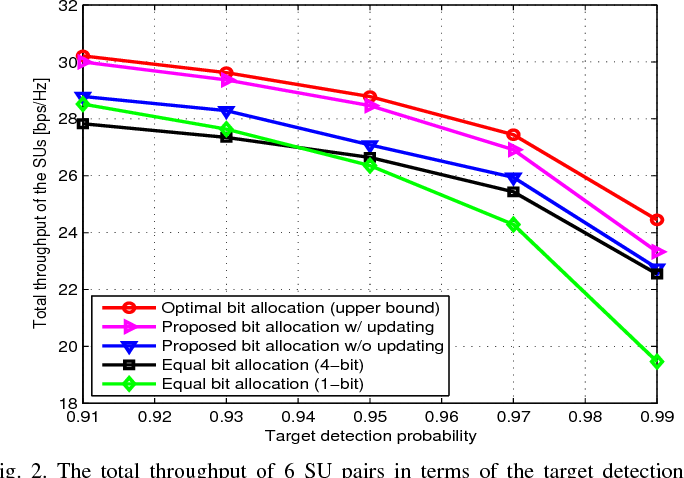
Figure 2 from Quantization bit allocation for reporting-throughput ...
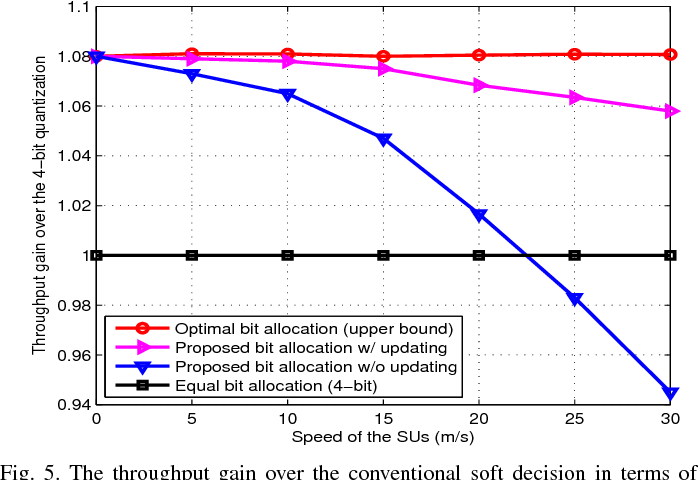
Figure 5 from Quantization bit allocation for reporting-throughput ...

Zeroquant Efficient and Affordable Post Training Quantization For Large ...

Figure 1 from Efficient bit allocation using new intra and inter-frame ...

Atom: Low-bit Quantization for Efficient and Accurate LLM Serving

NanoQuant: Efficient Sub-1-Bit Quantization of Large Language Models ...