
Paper Page Infinite Llm Efficient Llm Service For Long Context With

Paper page — Infinite-LLM: Efficient LLM Service for Long Context with ...

Paper page - Infinite-LLM: Efficient LLM Service for Long Context with ...

Infinite-Llm: Efficient LLM Service For Long Context With Distattention ...

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...

[short] Infinite-LLM: Efficient LLM Service for Long Context with ...

Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
[2401.02669] Infinite-LLM: Efficient LLM Service for Long Context with ...
Advertisement Space (300x250)
[2401.02669] Infinite-LLM: Efficient LLM Service for Long Context with ...
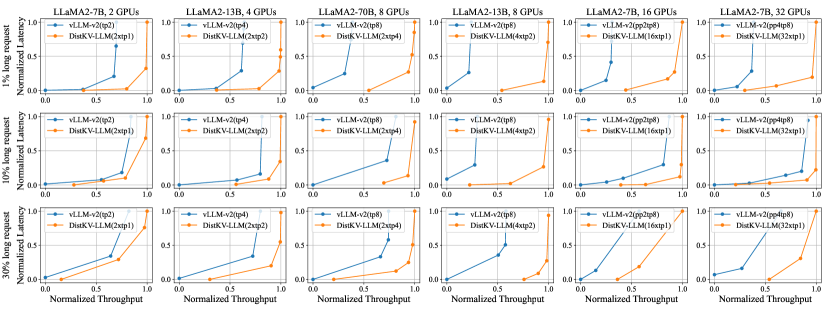
[2401.02669] Infinite-LLM: Efficient LLM Service for Long Context with ...
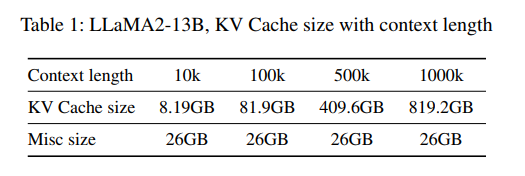
Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
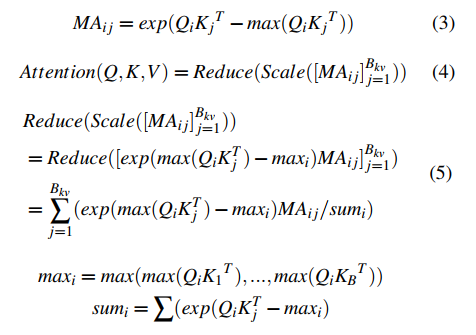
Infinite-LLM: Efficient LLM Service for Long Context with DistAttention ...
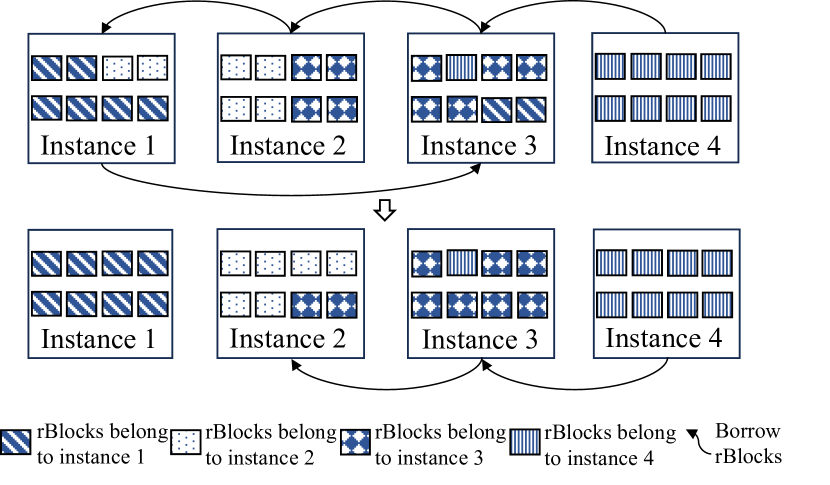
[2401.02669] Infinite-LLM: Efficient LLM Service for Long Context with ...
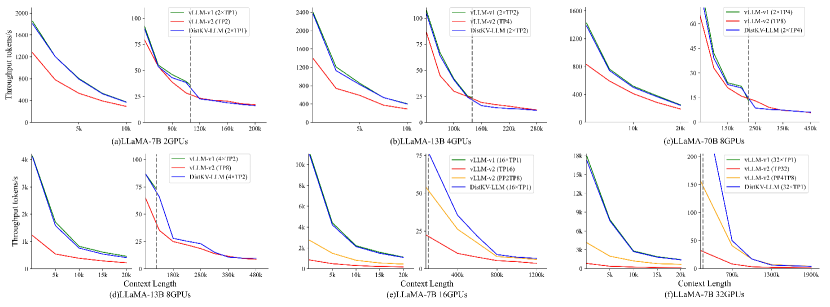
[2401.02669] Infinite-LLM: Efficient LLM Service for Long Context with ...
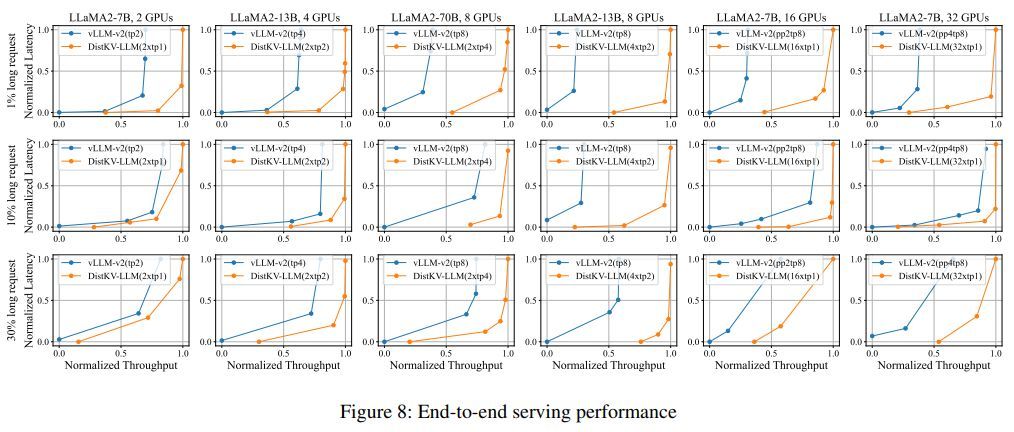
Santosh Sawant - Infinite-LLM: Efficient LLM Service for Long Context ...

Paper page - Quest: Query-Aware Sparsity for Efficient Long-Context LLM ...

Paper page - Squeezed Attention: Accelerating Long Context Length LLM ...

Paper page - LazyLLM: Dynamic Token Pruning for Efficient Long Context ...
Advertisement Space (336x280)

Paper page - Megalodon: Efficient LLM Pretraining and Inference with ...

Paper page - LazyLLM: Dynamic Token Pruning for Efficient Long Context ...

Megalodon: Efficient LLM pretraining with infinite context | Clio AI ...

Paper page - User-LLM: Efficient LLM Contextualization with User Embeddings

Paper page - Efficient LLM Inference with Kcache

Paper page - A Little Help Goes a Long Way: Efficient LLM Training by ...

Paper page - Unlocking Efficient Long-to-Short LLM Reasoning with Model ...

Paper page - DuoAttention: Efficient Long-Context LLM Inference with ...

Paper page - Structured Packing in LLM Training Improves Long Context ...

Paper page - Star Attention: Efficient LLM Inference over Long Sequences
Advertisement Space (336x280)

Paper page - Paper Copilot: A Self-Evolving and Efficient LLM System ...

Paper page - Human-like Episodic Memory for Infinite Context LLMs
Paper page - LongRoPE: Extending LLM Context Window Beyond 2 Million Tokens
Paper page - Efficient LLM inference solution on Intel GPU

Paper page - MemAgent: Reshaping Long-Context LLM with Multi-Conv RL ...
Paper page - Efficient LLM Inference on CPUs