
Paper Page Post Training Sparse Attention With Double Sparsity

Paper page - Post-Training Sparse Attention with Double Sparsity

Paper page - Dynamic Sparse Training with Structured Sparsity

(PDF) Post-Training Sparse Attention with Double Sparsity

Post-Training Sparse Attention with Double Sparsity | alphaXiv

Table 3 from Post-Training Sparse Attention with Double Sparsity ...

Post-Training Sparse Attention with Double Sparsity | alphaXiv

Paper page - Sparse Attention with Linear Units

Post-Training Sparse Attention with Double Sparsity | alphaXiv

Paper page - Lag-Relative Sparse Attention In Long Context Training

Paper page - Less Is More: Training-Free Sparse Attention with Global ...
Advertisement Space (300x250)

Paper page - Training Bayesian Neural Networks with Sparse Subspace ...

Post-Training Sparse Attention with Double Sparsity | alphaXiv

Paper page - SpargeAttention2: Trainable Sparse Attention via Hybrid ...

Figure 3 from Dynamic Sparse Training with Structured Sparsity ...

Paper page - SpargeAttention2: Trainable Sparse Attention via Hybrid ...

Paper page - SeerAttention: Learning Intrinsic Sparse Attention in Your ...

(PDF) Dynamic Sparse Training with Structured Sparsity

Paper page - SSA: Sparse Sparse Attention by Aligning Full and Sparse ...

[논문 리뷰] STS: Efficient Sparse Attention with Speculative Token Sparsity

Paper page - ProxyAttn: Guided Sparse Attention via Representative Heads
Advertisement Space (336x280)
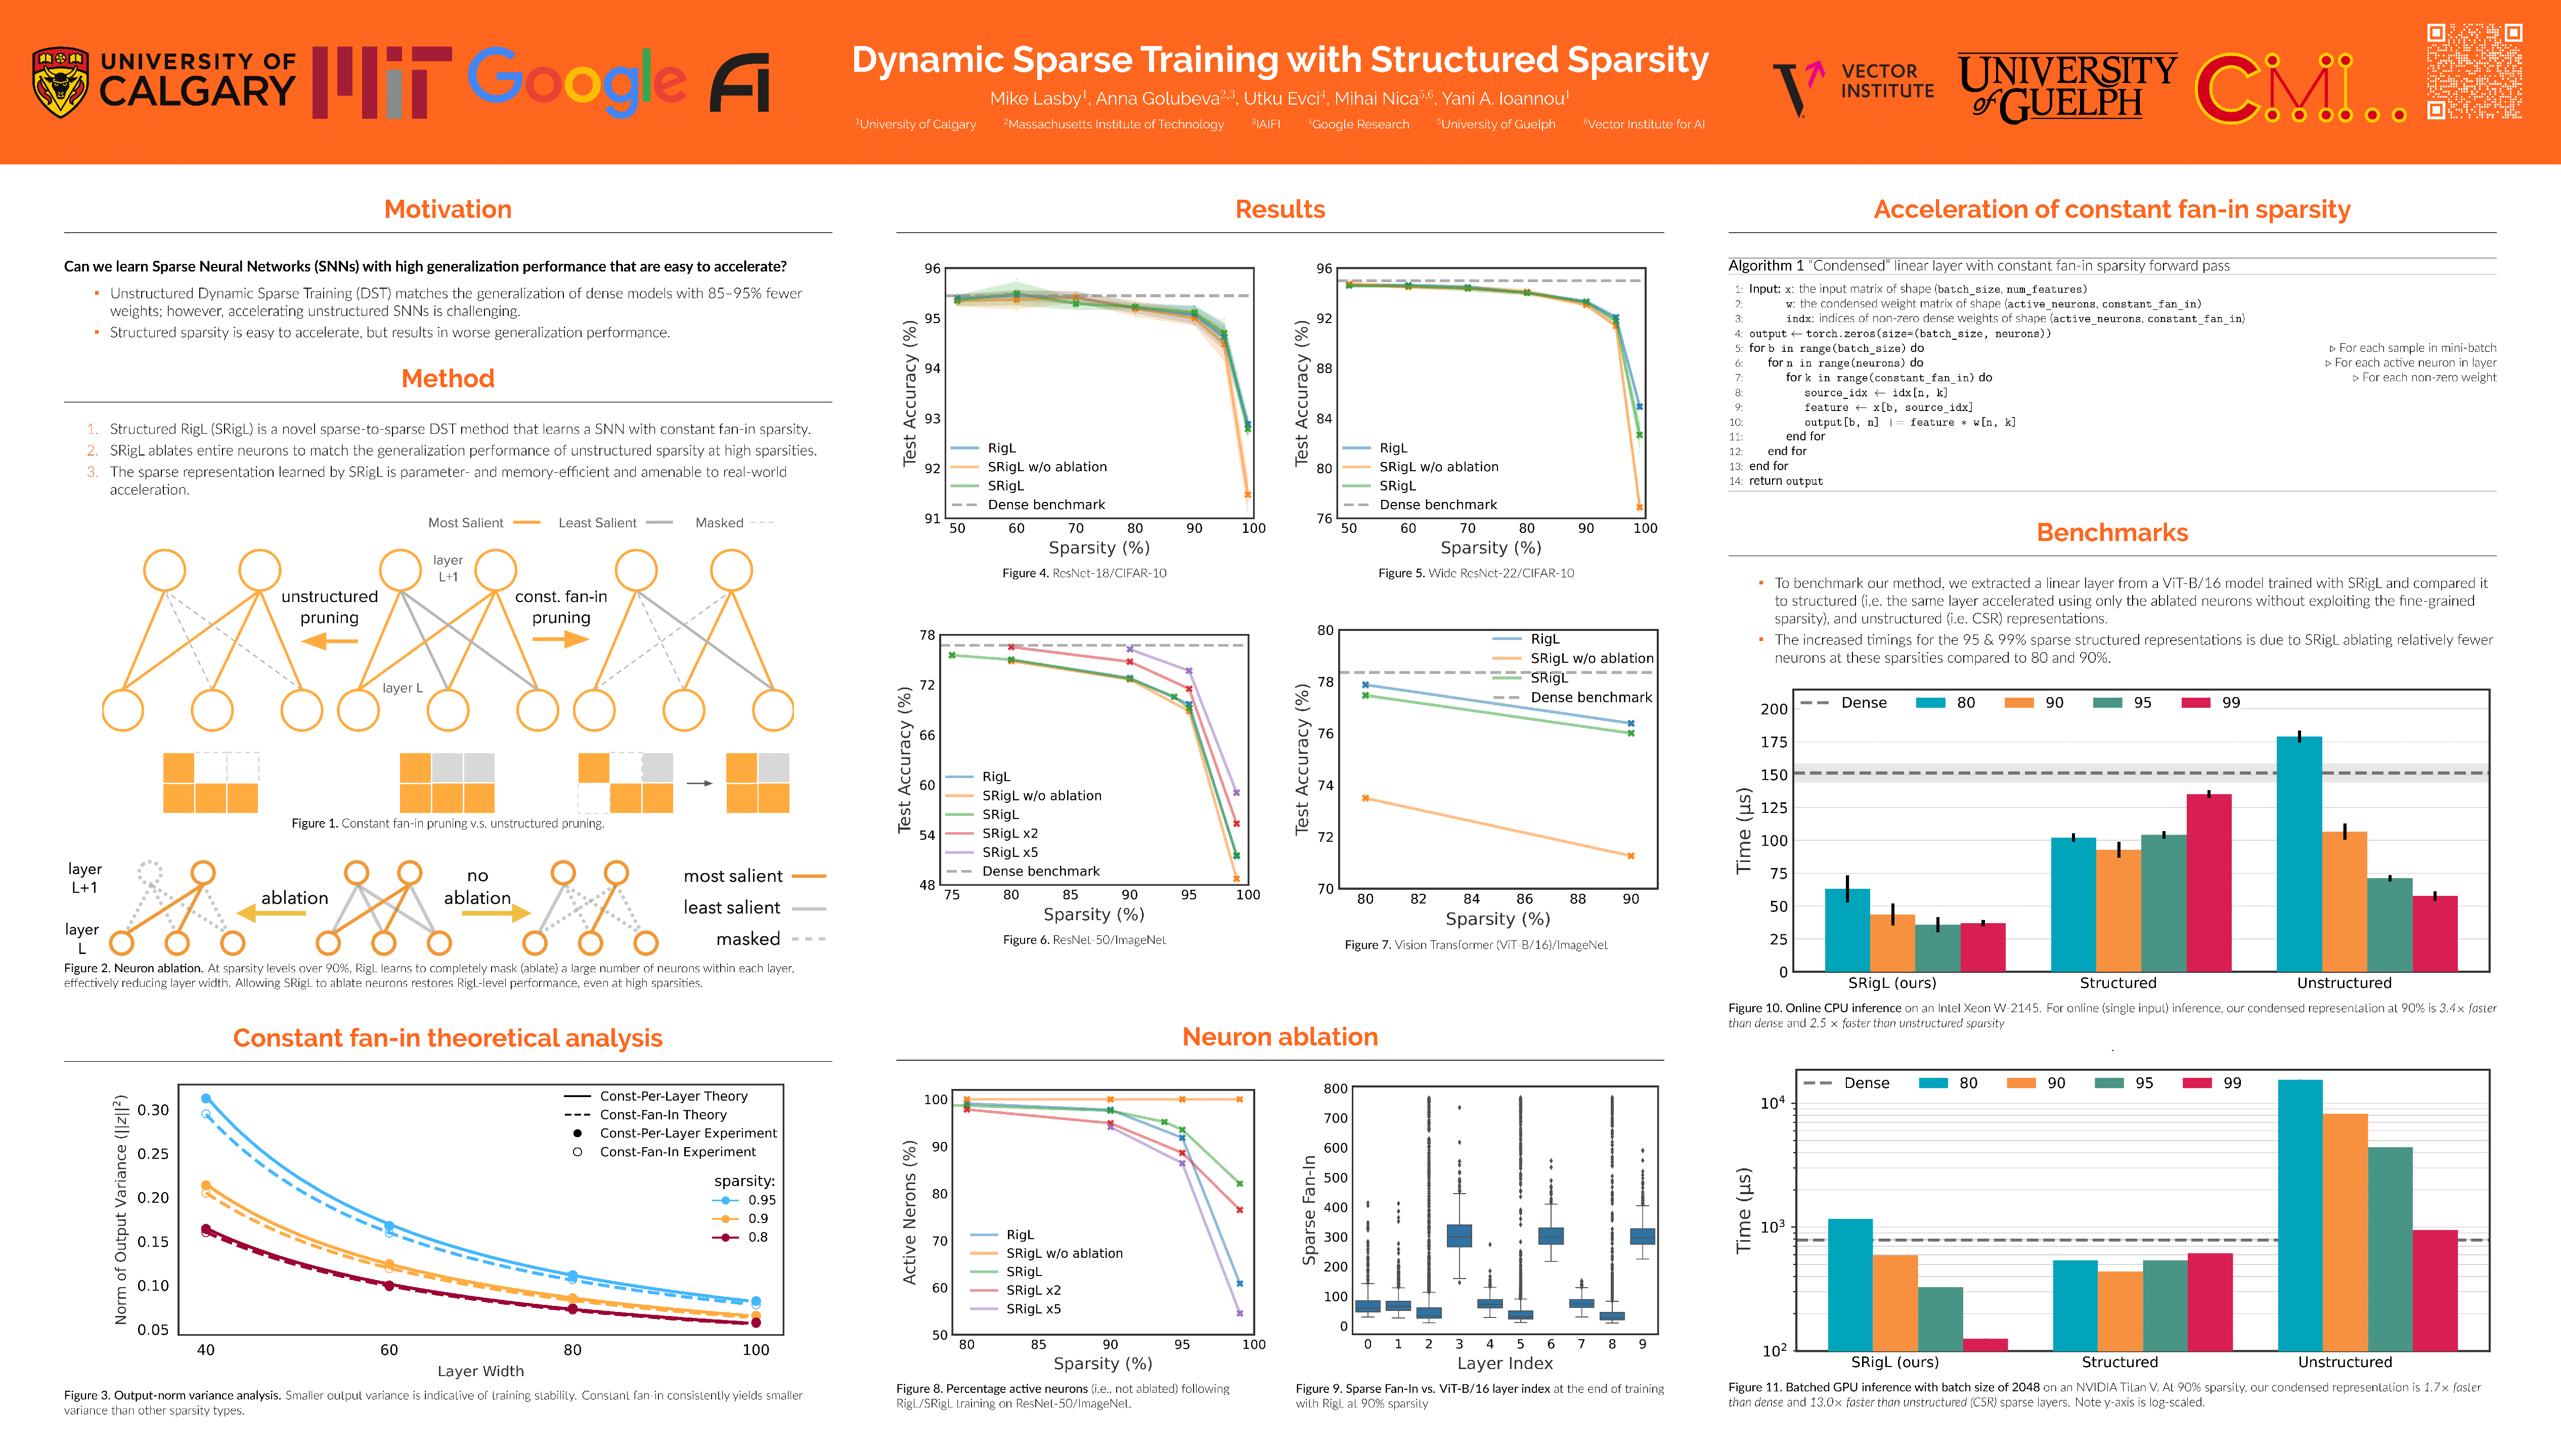
ICLR Poster Dynamic Sparse Training with Structured Sparsity

Paper page - SparseD: Sparse Attention for Diffusion Language Models

Paper page - Efficient N:M Sparse DNN Training Using Algorithm ...

Paper page - MTraining: Distributed Dynamic Sparse Attention for ...

Paper page - AdaSplash: Adaptive Sparse Flash Attention

Paper page - SeerAttention: Learning Intrinsic Sparse Attention in Your ...

Paper page - IndexCache: Accelerating Sparse Attention via Cross-Layer ...

Paper page - SLA2: Sparse-Linear Attention with Learnable Routing and QAT

Paper page - Sparse Networks from Scratch: Faster Training without ...

Figure 2 from Dynamic Sparse Training with Structured Sparsity ...
Advertisement Space (336x280)

Paper page - Training-free and Adaptive Sparse Attention for Efficient ...

Paper page - Trainable Dynamic Mask Sparse Attention

Paper page - MiniCPM-SALA: Hybridizing Sparse and Linear Attention for ...

Paper page - Native Sparse Attention: Hardware-Aligned and Natively ...

Bidirectional Sparse Attention for Faster Video Diffusion Training | AI ...

Dual sparse training framework: inducing activation map sparsity via ...