
Paper Page Scaling Pre Training To One Hundred Billion Data For

Paper page - Scaling Pre-training to One Hundred Billion Data for ...

Scaling Pre-training to One Hundred Billion Data for Vision Language ...

[2502.07617] Scaling Pre-training to One Hundred Billion Data for ...

[논문 리뷰] Scaling Pre-training to One Hundred Billion Data for Vision ...

Scaling Pre-training to One Hundred Billion Data for Vision Language ...

Scaling Pre-training to One Hundred Billion Data for Vision Language ...

Paper page - Prescriptive Scaling Laws for Data Constrained Training

Paper page - FineInstructions: Scaling Synthetic Instructions to Pre ...

Paper page - Webscale-RL: Automated Data Pipeline for Scaling RL Data ...

Paper page - Scaling Laws for Floating Point Quantization Training
Advertisement Space (300x250)

Paper page - GeoPT: Scaling Physics Simulation via Lifted Geometric Pre ...

Scaling Quality Training Data | White Paper

Scaling Quality Training Data | White Paper

Paper page - Revisiting ResNets: Improved Training and Scaling Strategies
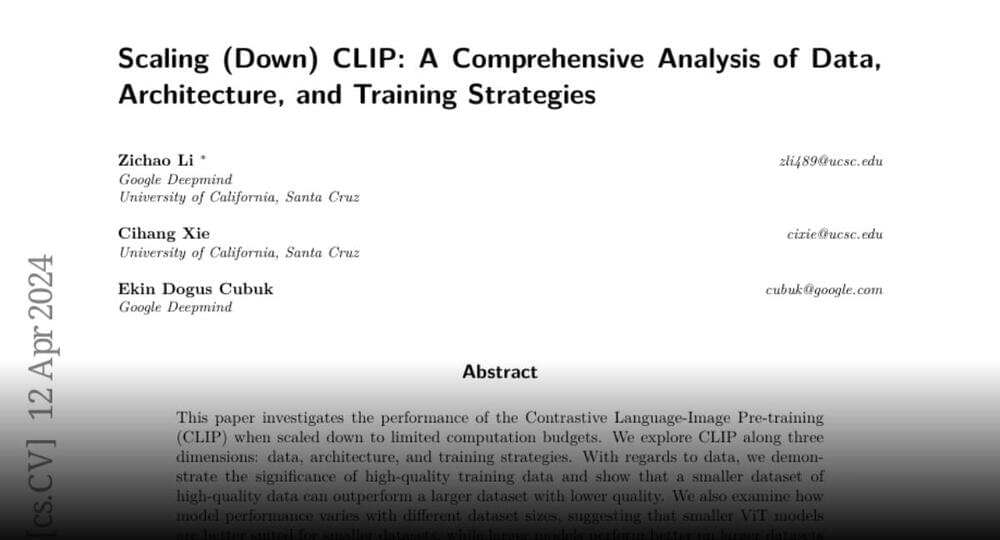
Paper page — Scaling (Down) CLIP: A Comprehensive Analysis of Data ...

Scaling Law for Quantization-Aware Training | AI Research Paper Details

Scaling Laws for Floating Point Quantization Training · HF Daily Paper ...

Paper page - RefineX: Learning to Refine Pre-training Data at Scale ...

Paper page - Scaling Smart: Accelerating Large Language Model Pre ...
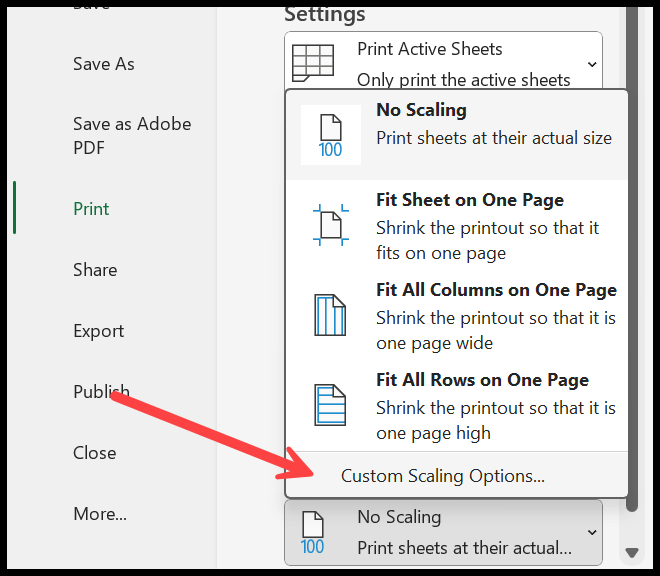
How to Print Data on One Page in Excel (Fit to One Page)
Advertisement Space (336x280)

Paper page - ResFormer: Scaling ViTs with Multi-Resolution Training

Paper page - Scaling Synthetic Data Creation with 1,000,000,000 Personas

Scaling Laws for Floating Point Quantization Training · HF Daily Paper ...

Paper page - The Art of Scaling Reinforcement Learning Compute for LLMs

Data Scaling Laws for End-to-End Autonomous Driving | AI Research Paper ...

Scaling Pedagogical Pre-training: From Optimal Mixing to 10 Billion Tokens
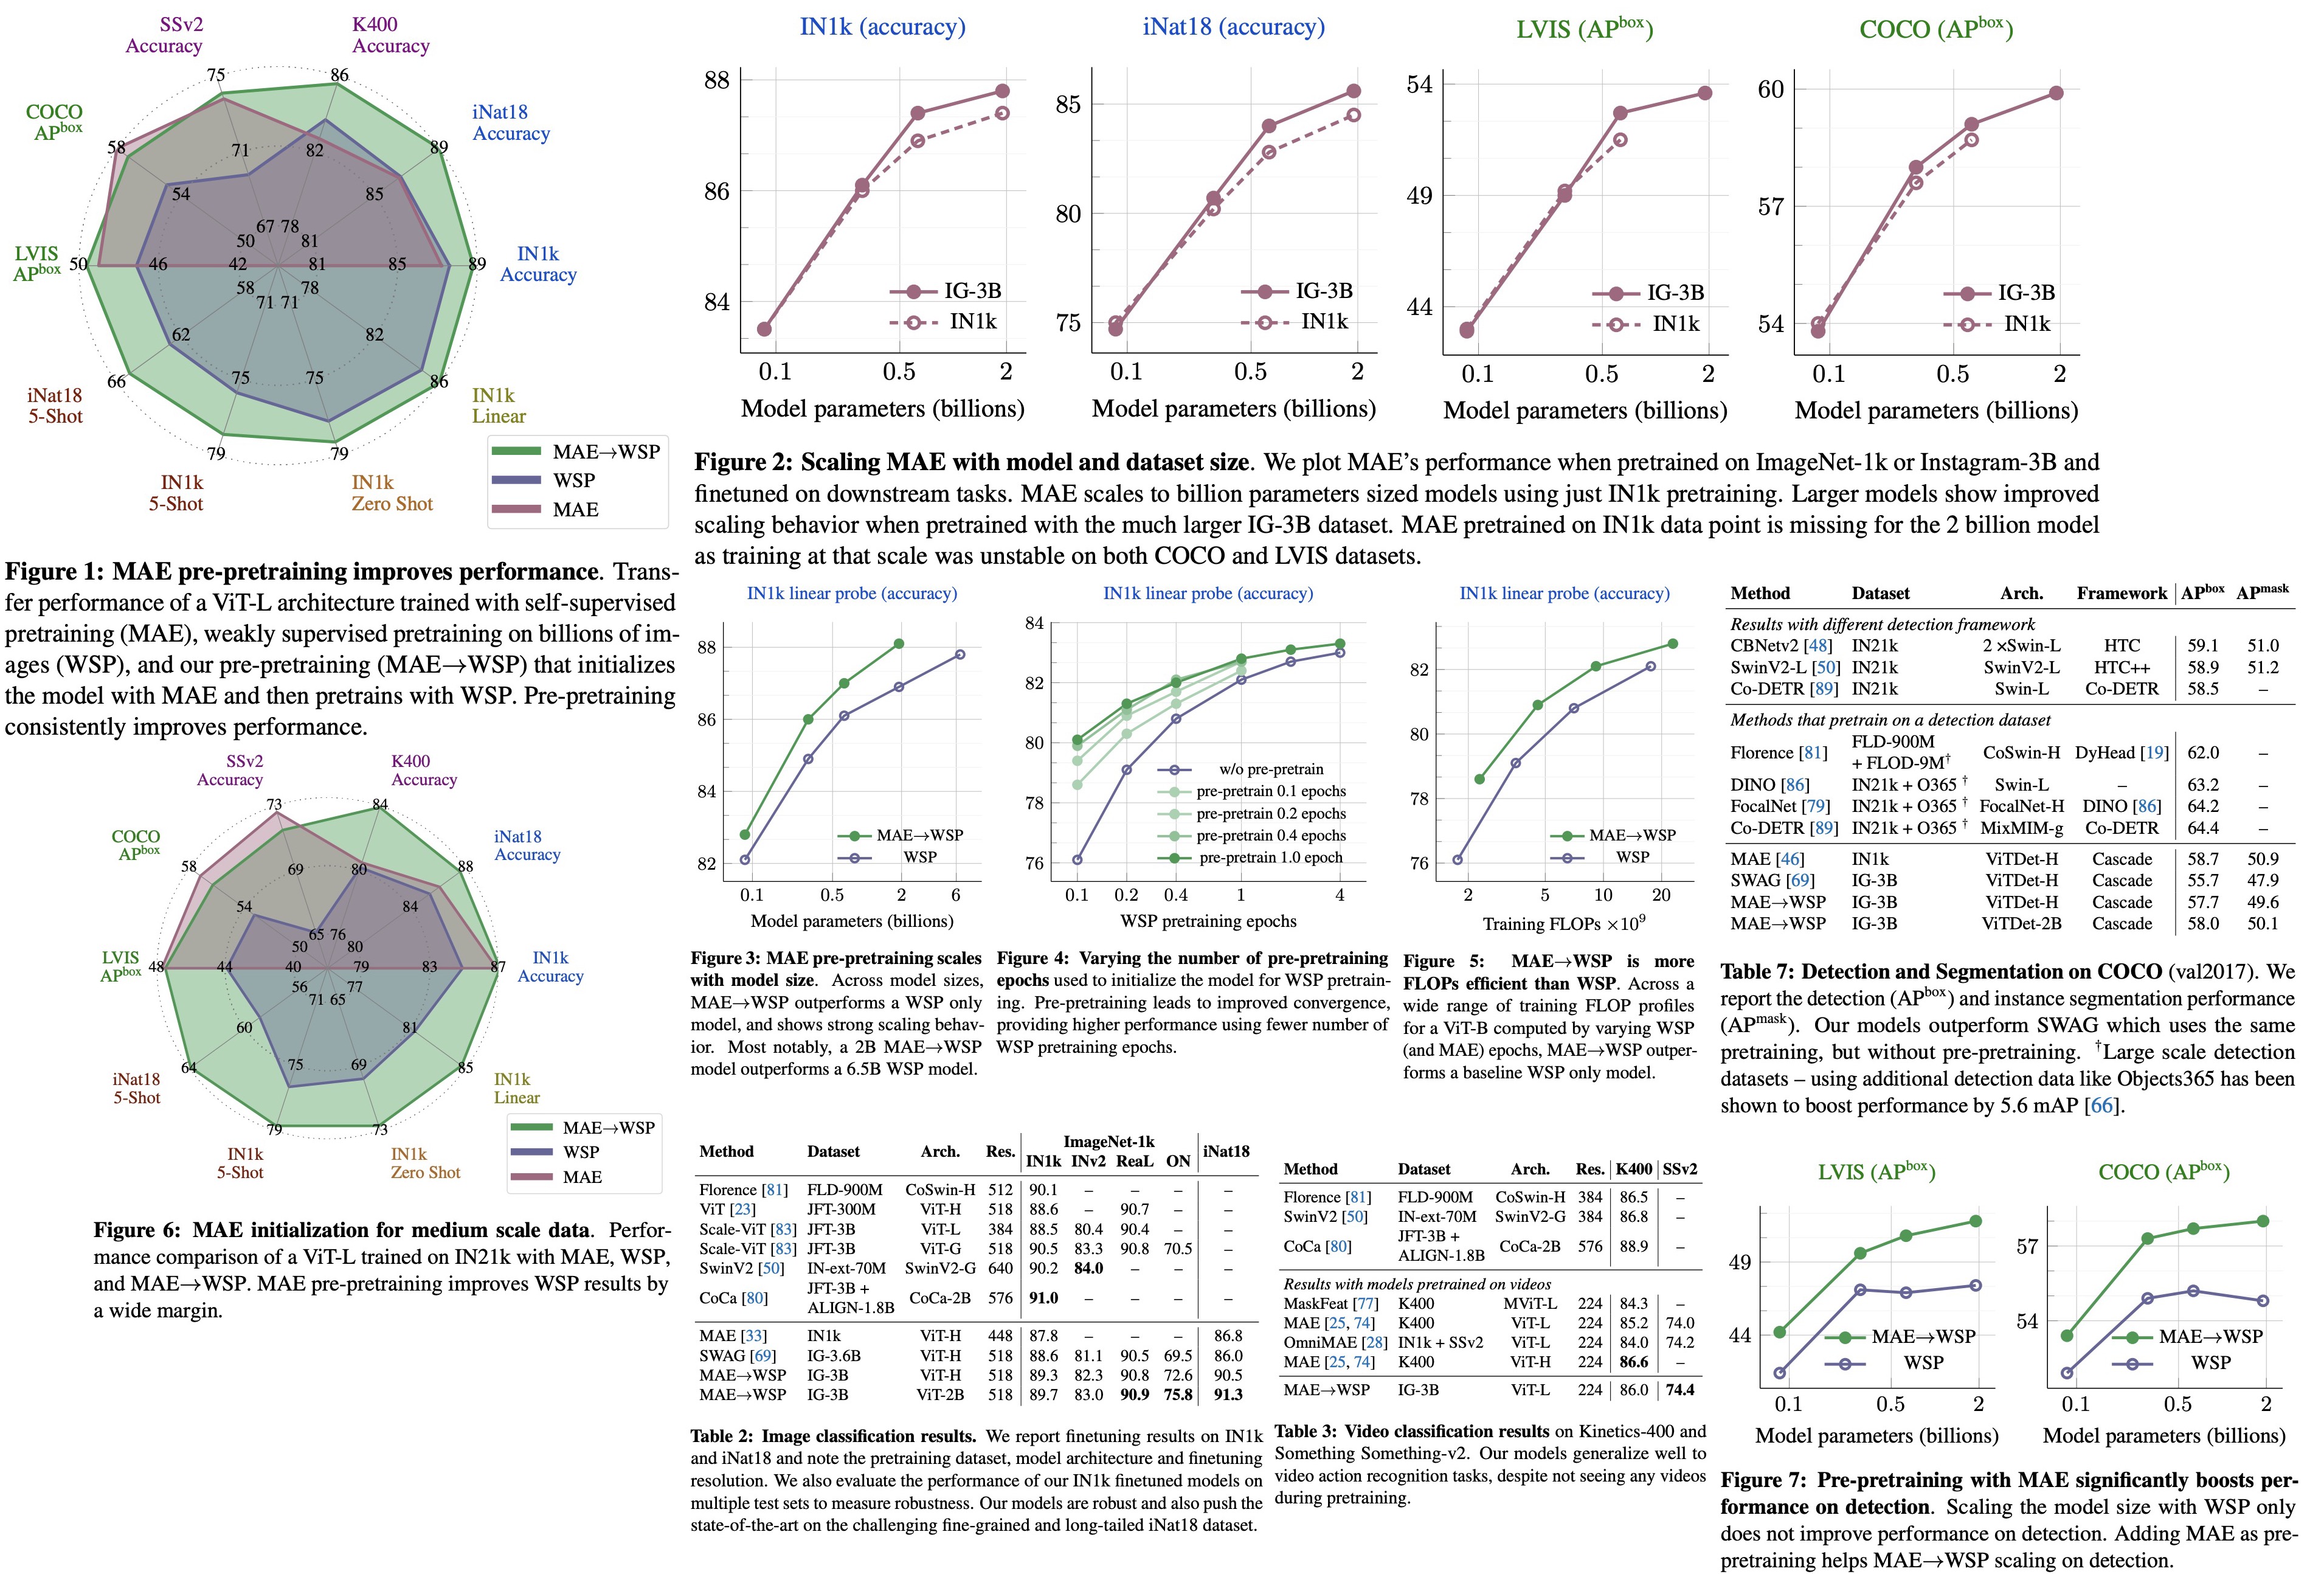
Paper Review: The effectiveness of MAE pre-pretraining for billion ...

AI Text Data Training and Other Scaling Problems and Limits ...

Paper page - Efficient Pretraining Length Scaling
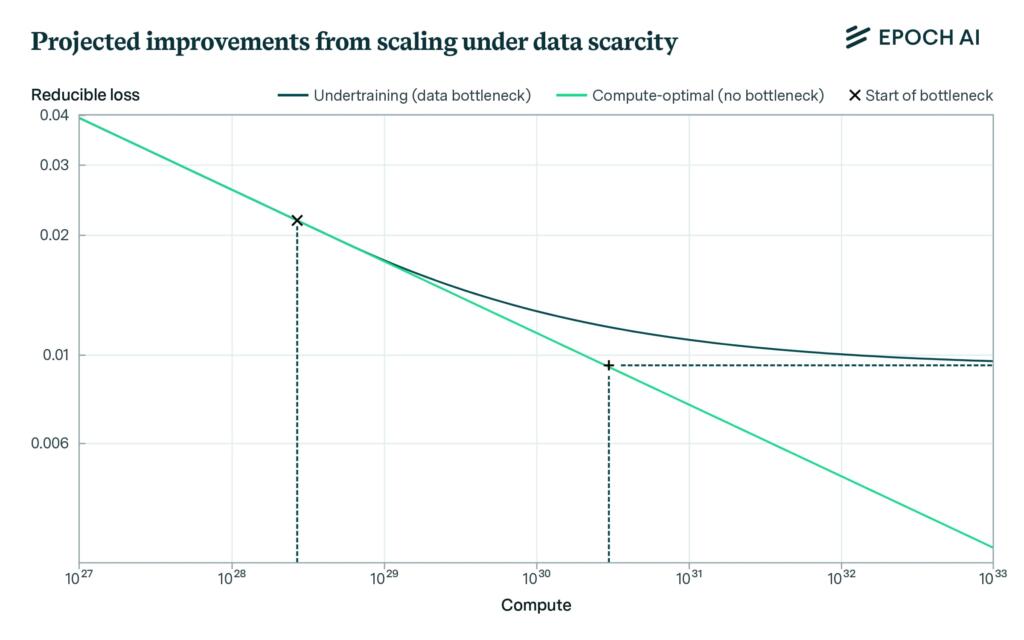
AI Text Data Training and Other Scaling Problems and Limits ...
Advertisement Space (336x280)

Scaling Pedagogical Pre-training: From Optimal Mixing to 10 Billion Tokens
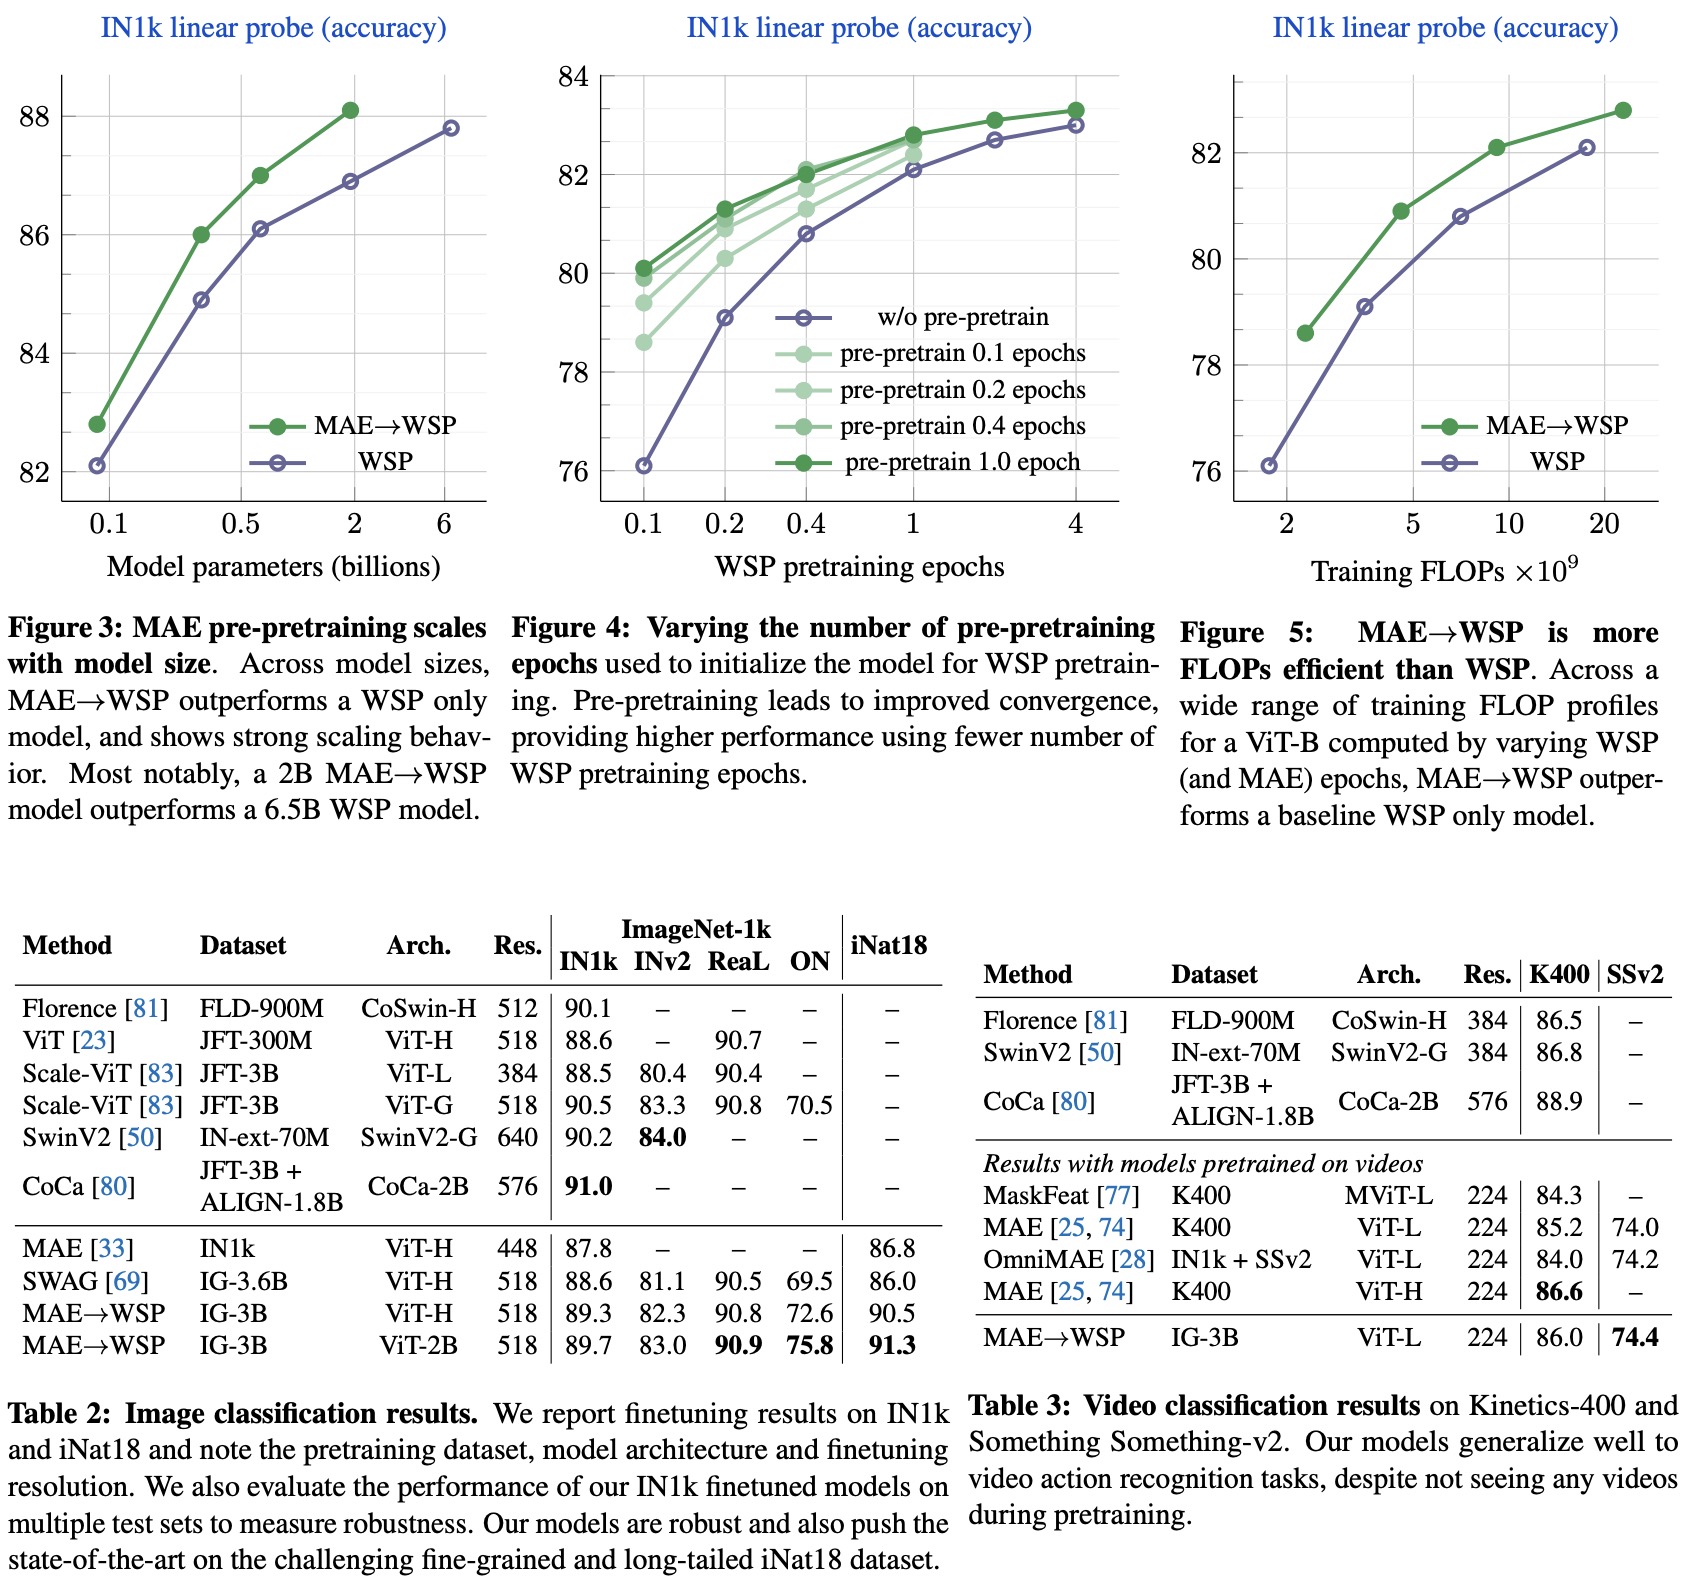
Paper Review: The effectiveness of MAE pre-pretraining for billion ...

Paper page - Low-Bit Quantization Favors Undertrained LLMs: Scaling ...

Paper page - The Journey Matters: Average Parameter Count over Pre ...

Paper page - Scaling Test-Time Compute Without Verification or RL is ...

Understanding the Role of Training Data in Test-Time Scaling | AI ...