
Papers With Code Benchmarks And Implementation Links
Papers with Code Benchmarks and Implementation Links

Speculative decoding — papers and benchmarks | Papers with Code

(PDF) Benchmarks and Metrics for Evaluations of Code Generation: A ...
Benchmarks and Metrics for Evaluations of Code Generation: A Critical ...

When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...
Code Generation From Flowcharts with Texts: A Benchmark Dataset and An ...
A Survey of Code Review Benchmarks and Evaluation Practices in Pre-LLM ...

Paper page - Benchmarking LLMs for Fine-Grained Code Review with ...
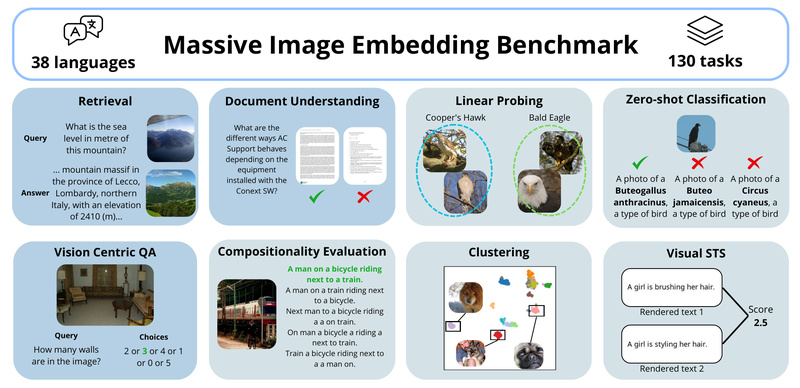
Awesome Visual Representation Learning Papers and Source Codes | PaperCodex

Paper page - Web-Bench: A LLM Code Benchmark Based on Web Standards and ...
Advertisement Space (300x250)

Existing Benchmarks for Code Generation | Download Scientific Diagram

Benchmark of Benchmarks: Unpacking Influence and Code Repository ...

Do Papers Tell the Whole Story? A Benchmark and Framework for ...

Web-Bench: A LLM Code Benchmark Based on Web Standards and Frameworks ...
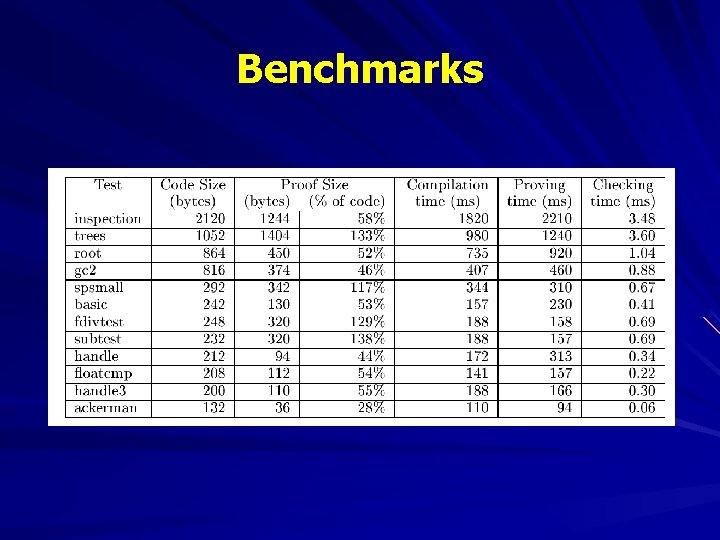
The Design and Implementation of a Certifying Compiler

Benchmarking LLMs for Fine-Grained Code Review with Enriched Context in ...
(PDF) Implementation Benchmarks for Assessing an Alternative ...

Discussion on "LLM for Coding Benchmarks and Datasets" | Hashnode
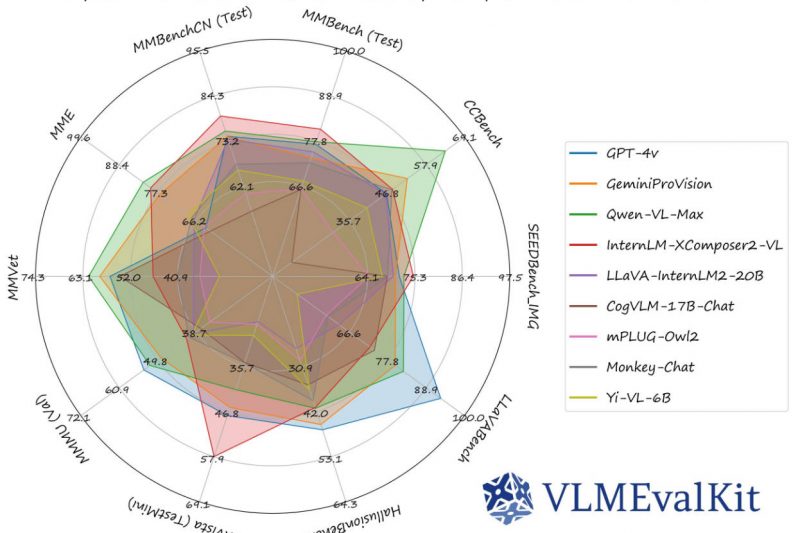
Awesome Benchmarking Papers and Source Codes | PaperCodex
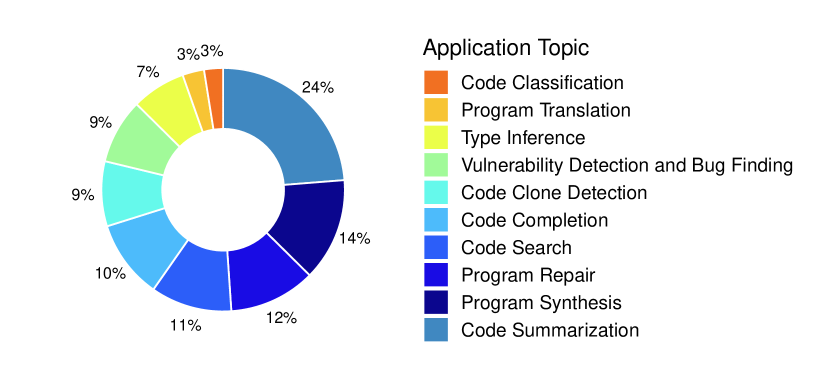
[2401.00288] Deep Learning for Code Intelligence: Survey, Benchmark and ...
Advertisement Space (336x280)
AI Code Review Benchmarks 2025 | Greptile

(PDF) Re-Evaluating Code LLM Benchmarks Under Semantic Mutation

[论文评述] Automatic Generation of Benchmarks and Reliable LLM Judgment for ...
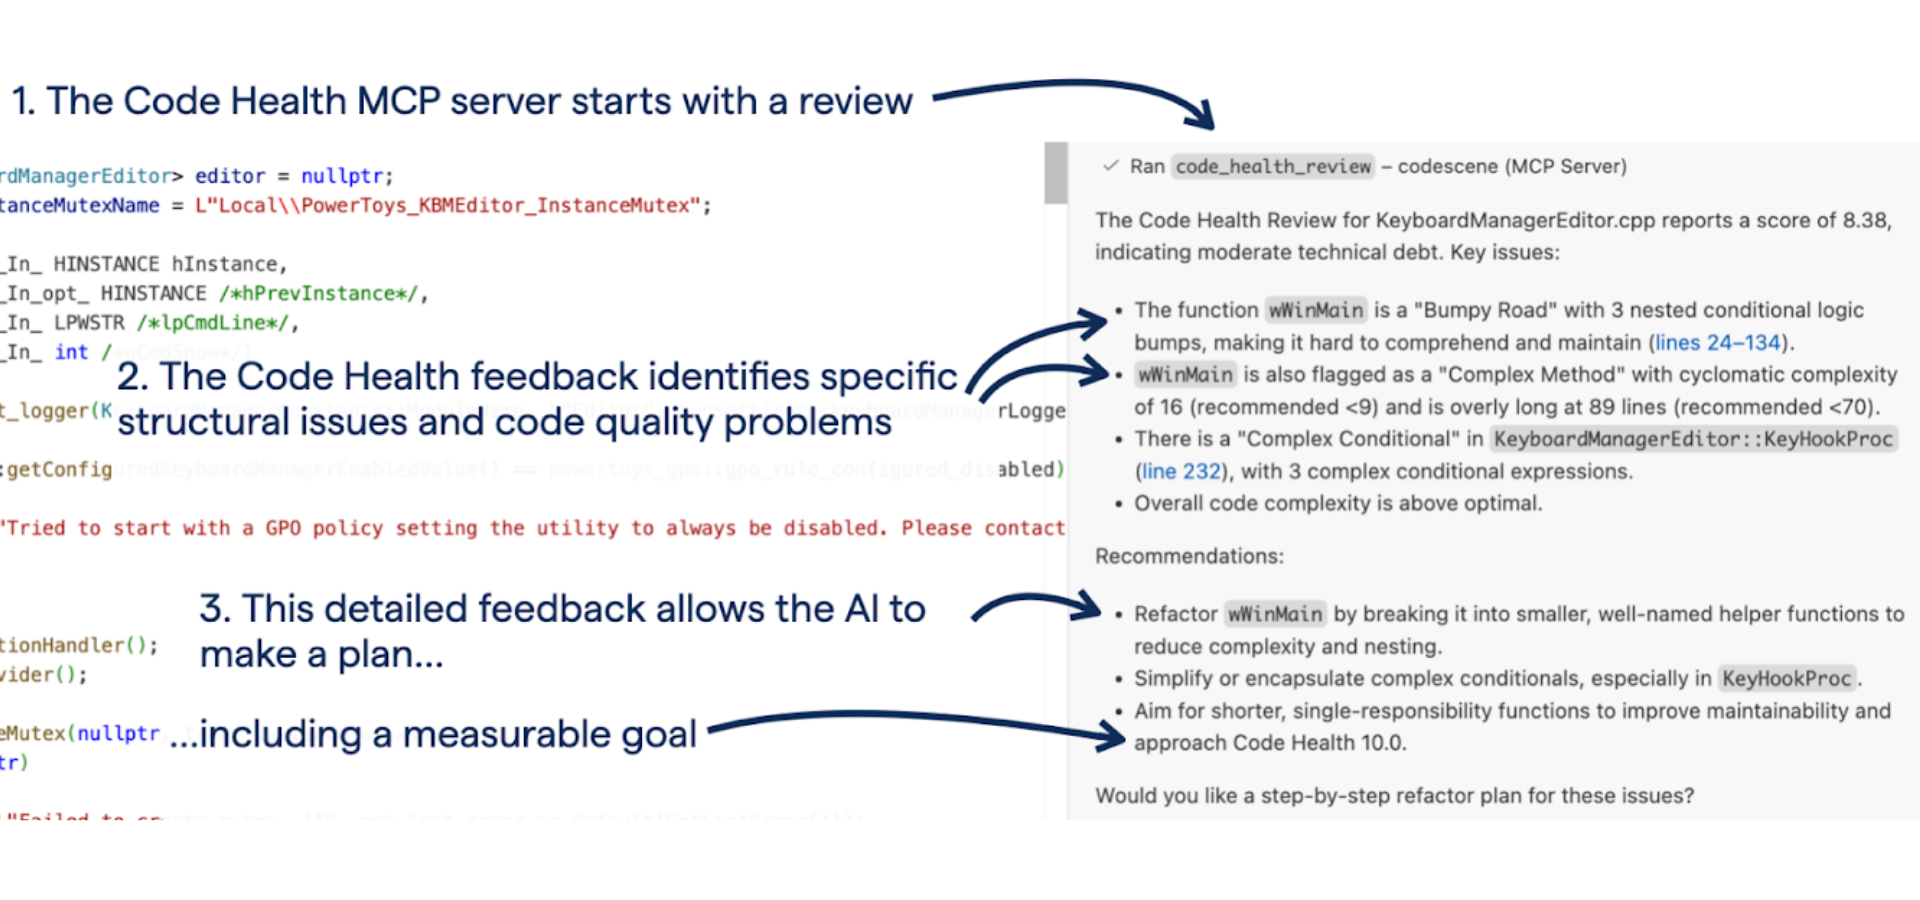
Making Legacy Code AI-Ready: Benchmarks on Agentic Refactoring
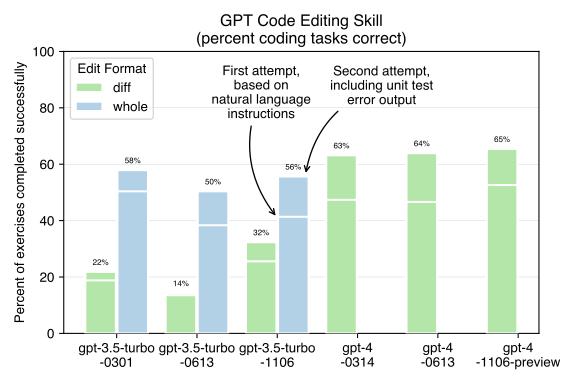
Code editing benchmarks for OpenAI’s “1106” models | aider

Paper page - Benchmarking and Studying the LLM-based Code Review

Implementation Benchmarks 2023 | KLAS Report
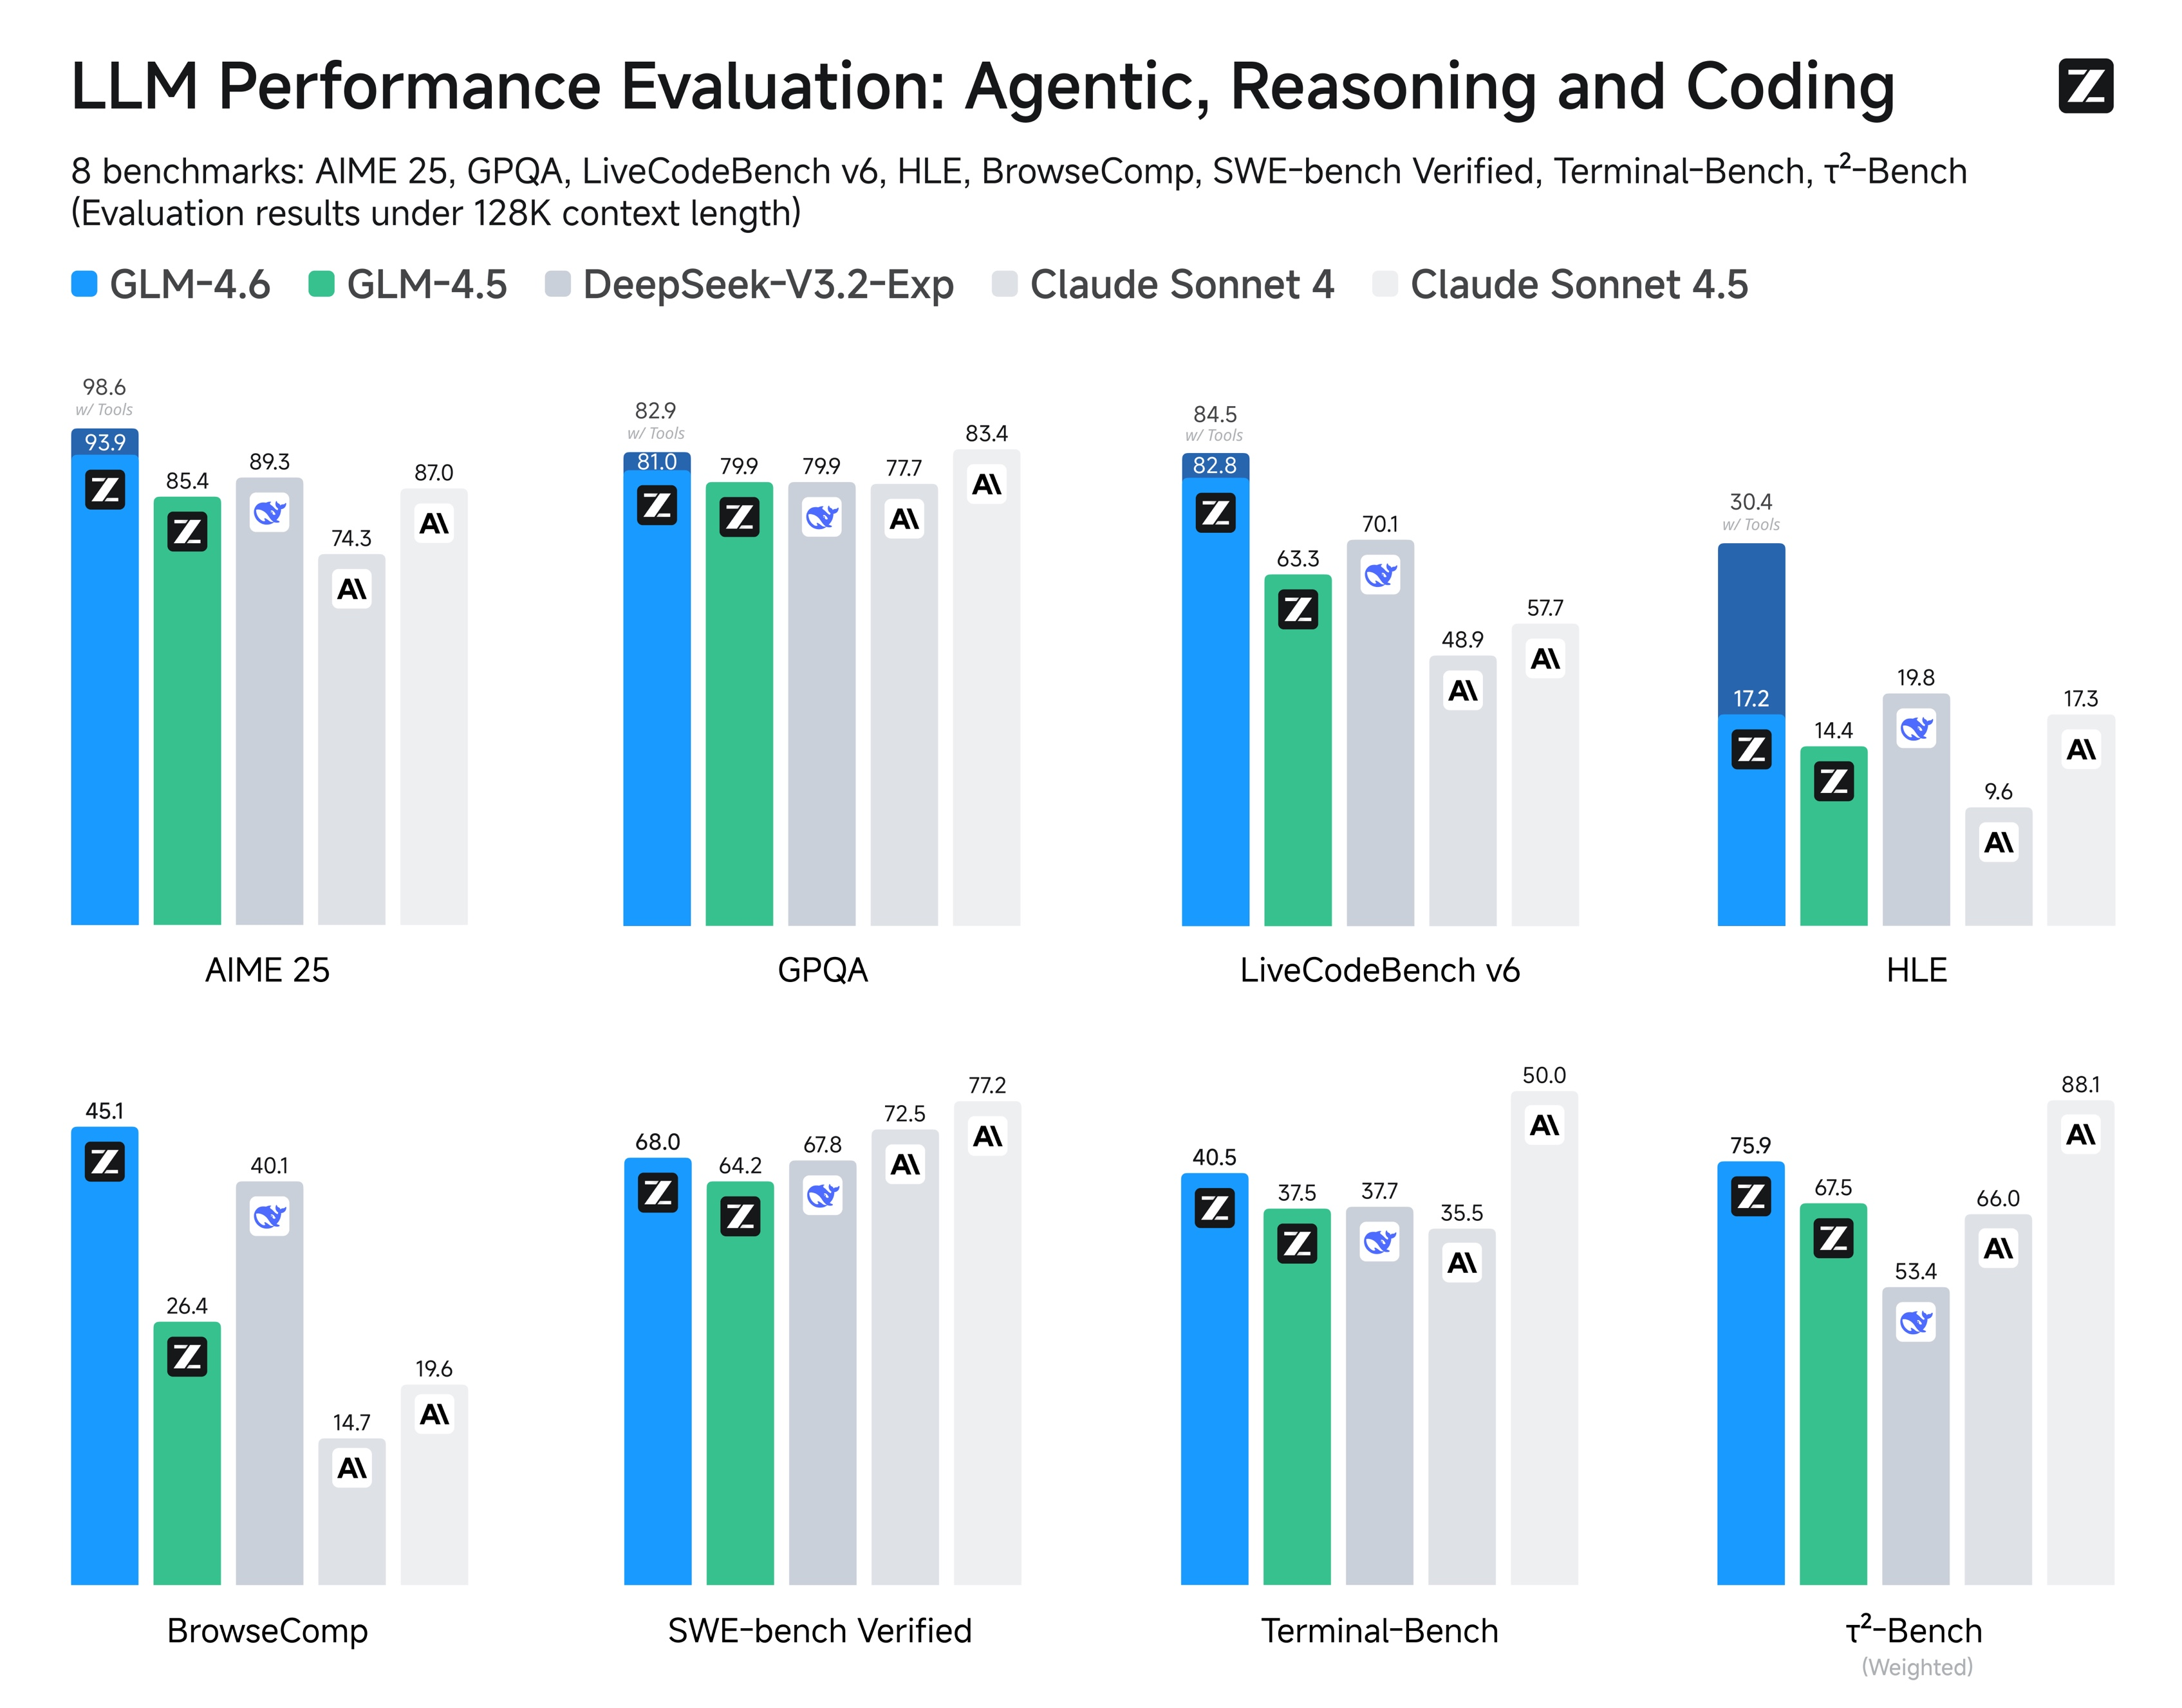
GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities
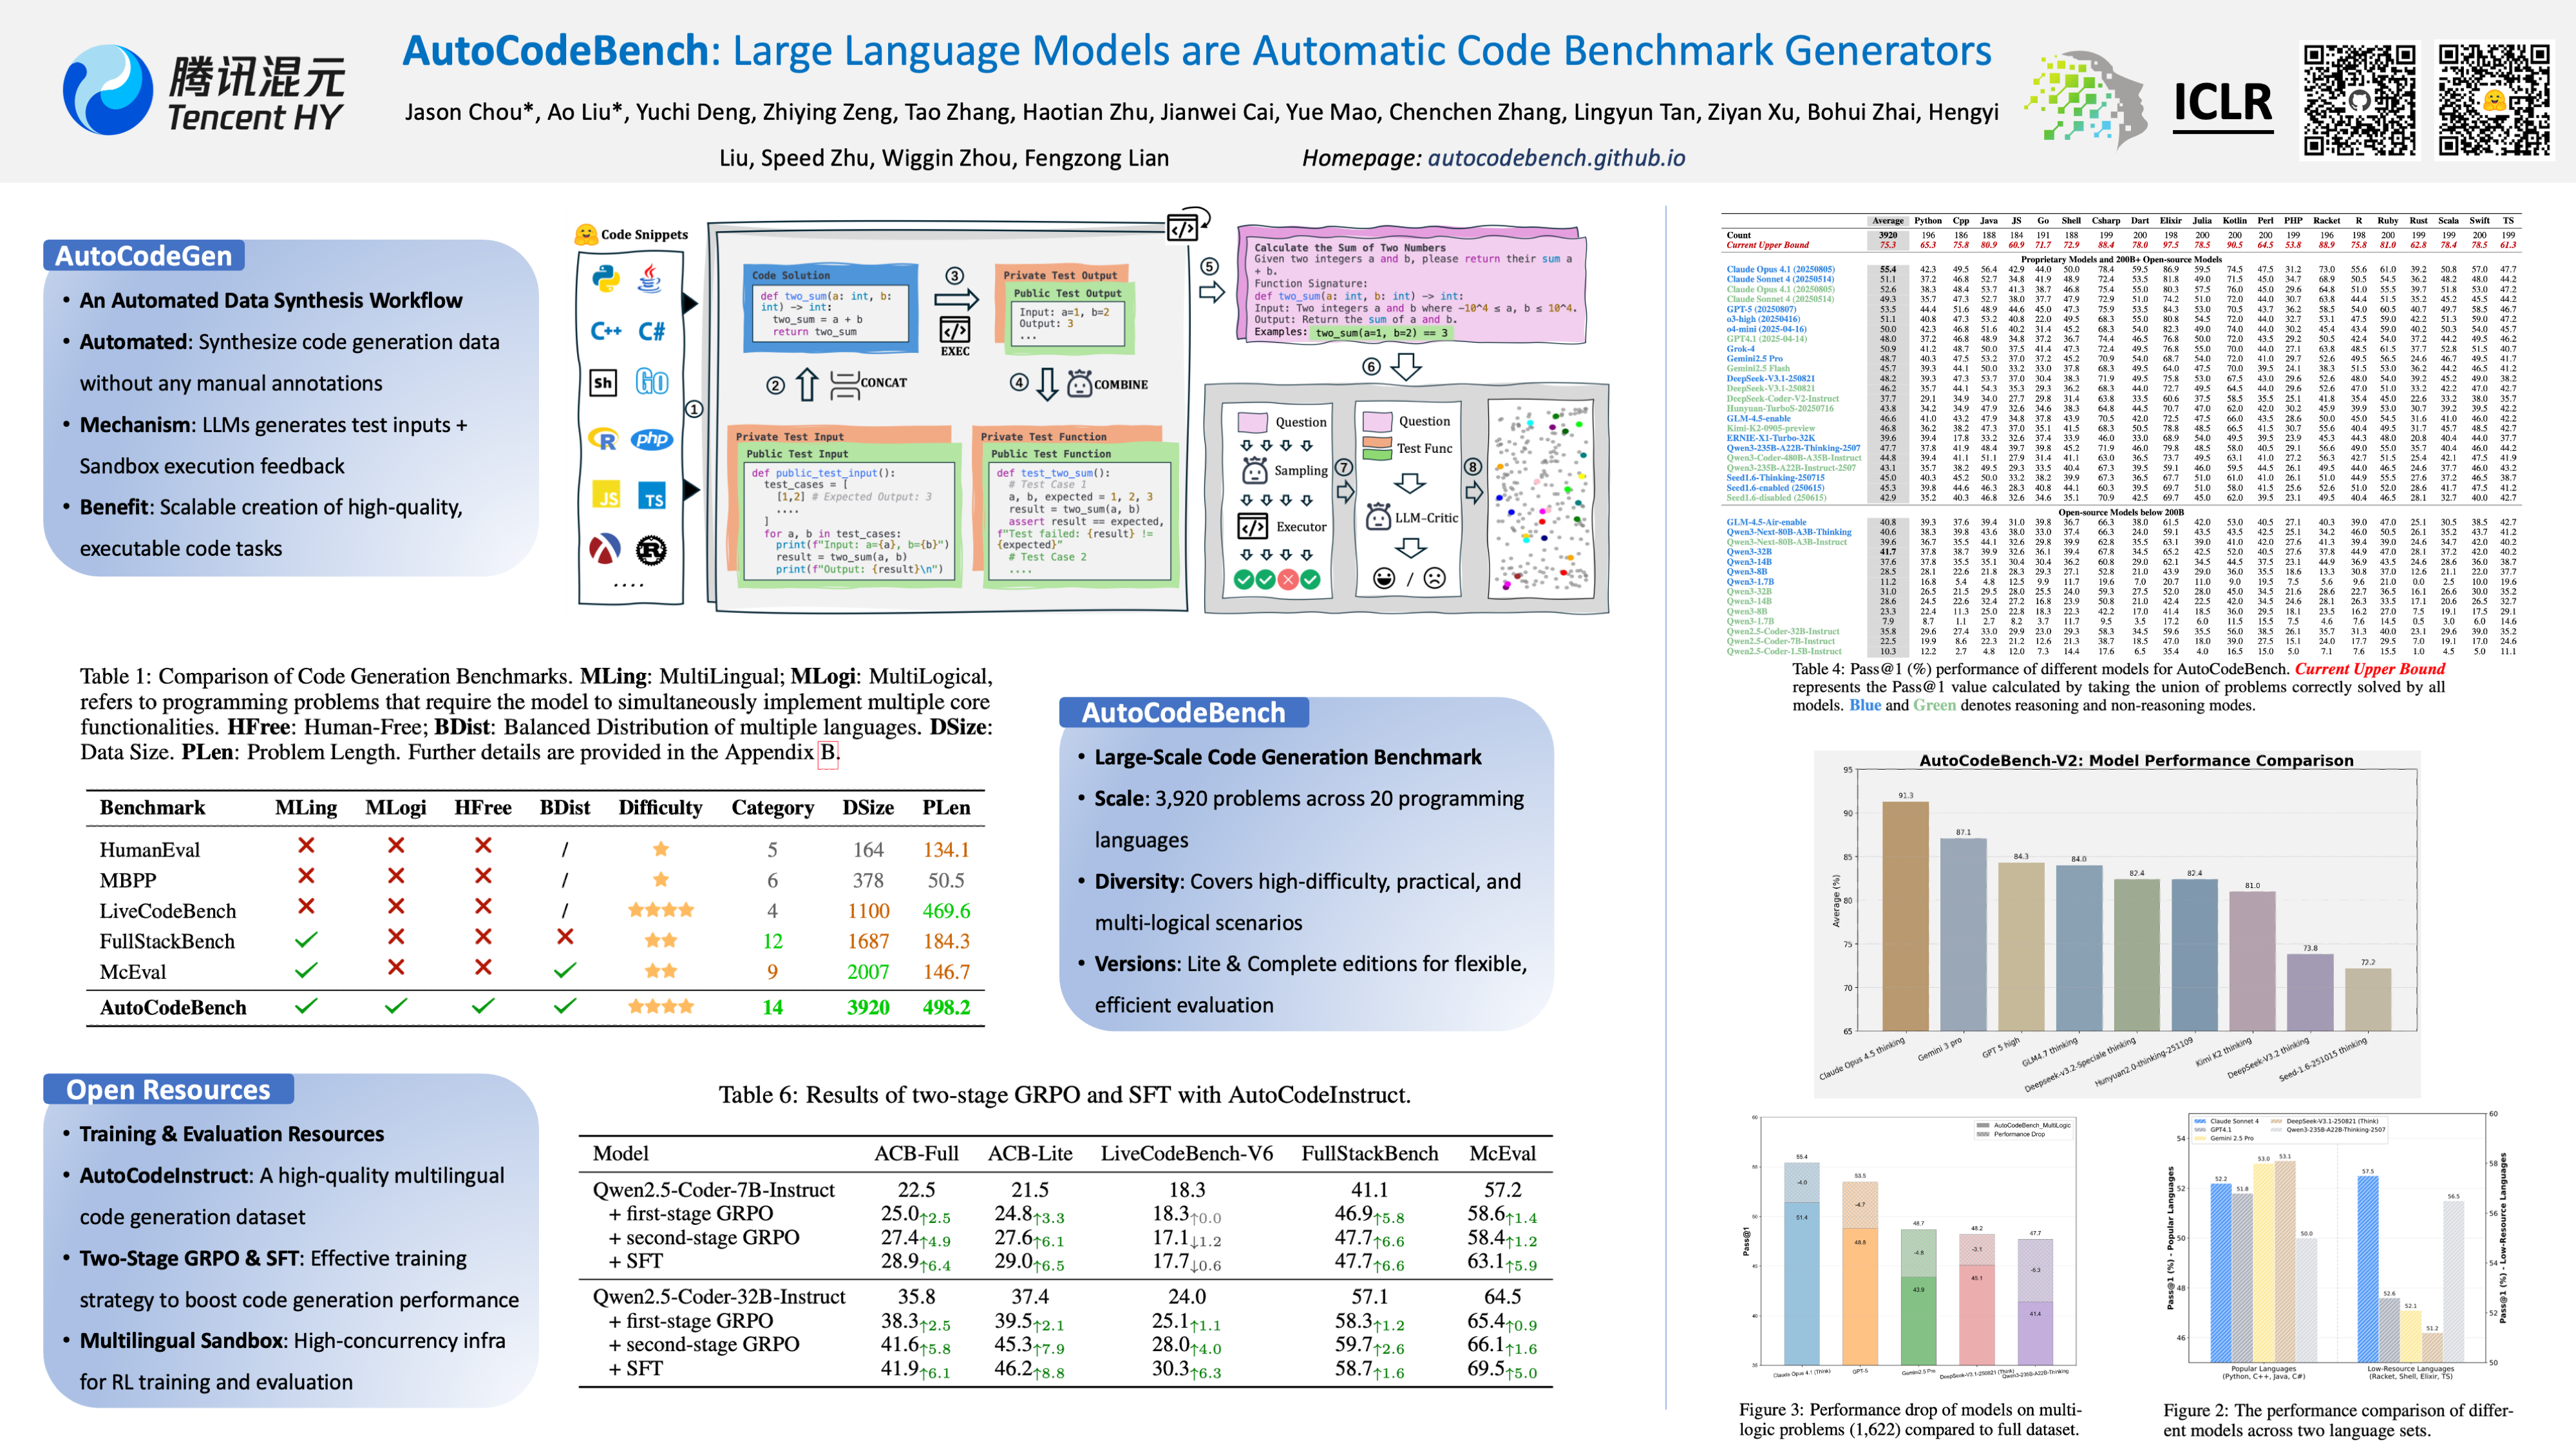
ICLR Poster AutoCodeBench: Large Language Models are Automatic Code ...

Paper page - AutoCodeBench: Large Language Models are Automatic Code ...
Advertisement Space (336x280)
FEA-Bench: A Benchmark for Evaluating Repository-Level Code Generation ...

GenAI for Systems: Recurring Challenges and Design Principles from ...

[논문 리뷰] CoCo-Bench: A Comprehensive Code Benchmark For Multi-task Large ...

(PDF) CodeMMLU: A Multi-Task Benchmark for Assessing Code Understanding ...

(PDF) CoIR: A Comprehensive Benchmark for Code Information Retrieval Models