
When Benchmarks Talk Re Evaluating Code Llms With Interactive Feedback

When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...
When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...

[논문 리뷰] When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive ...
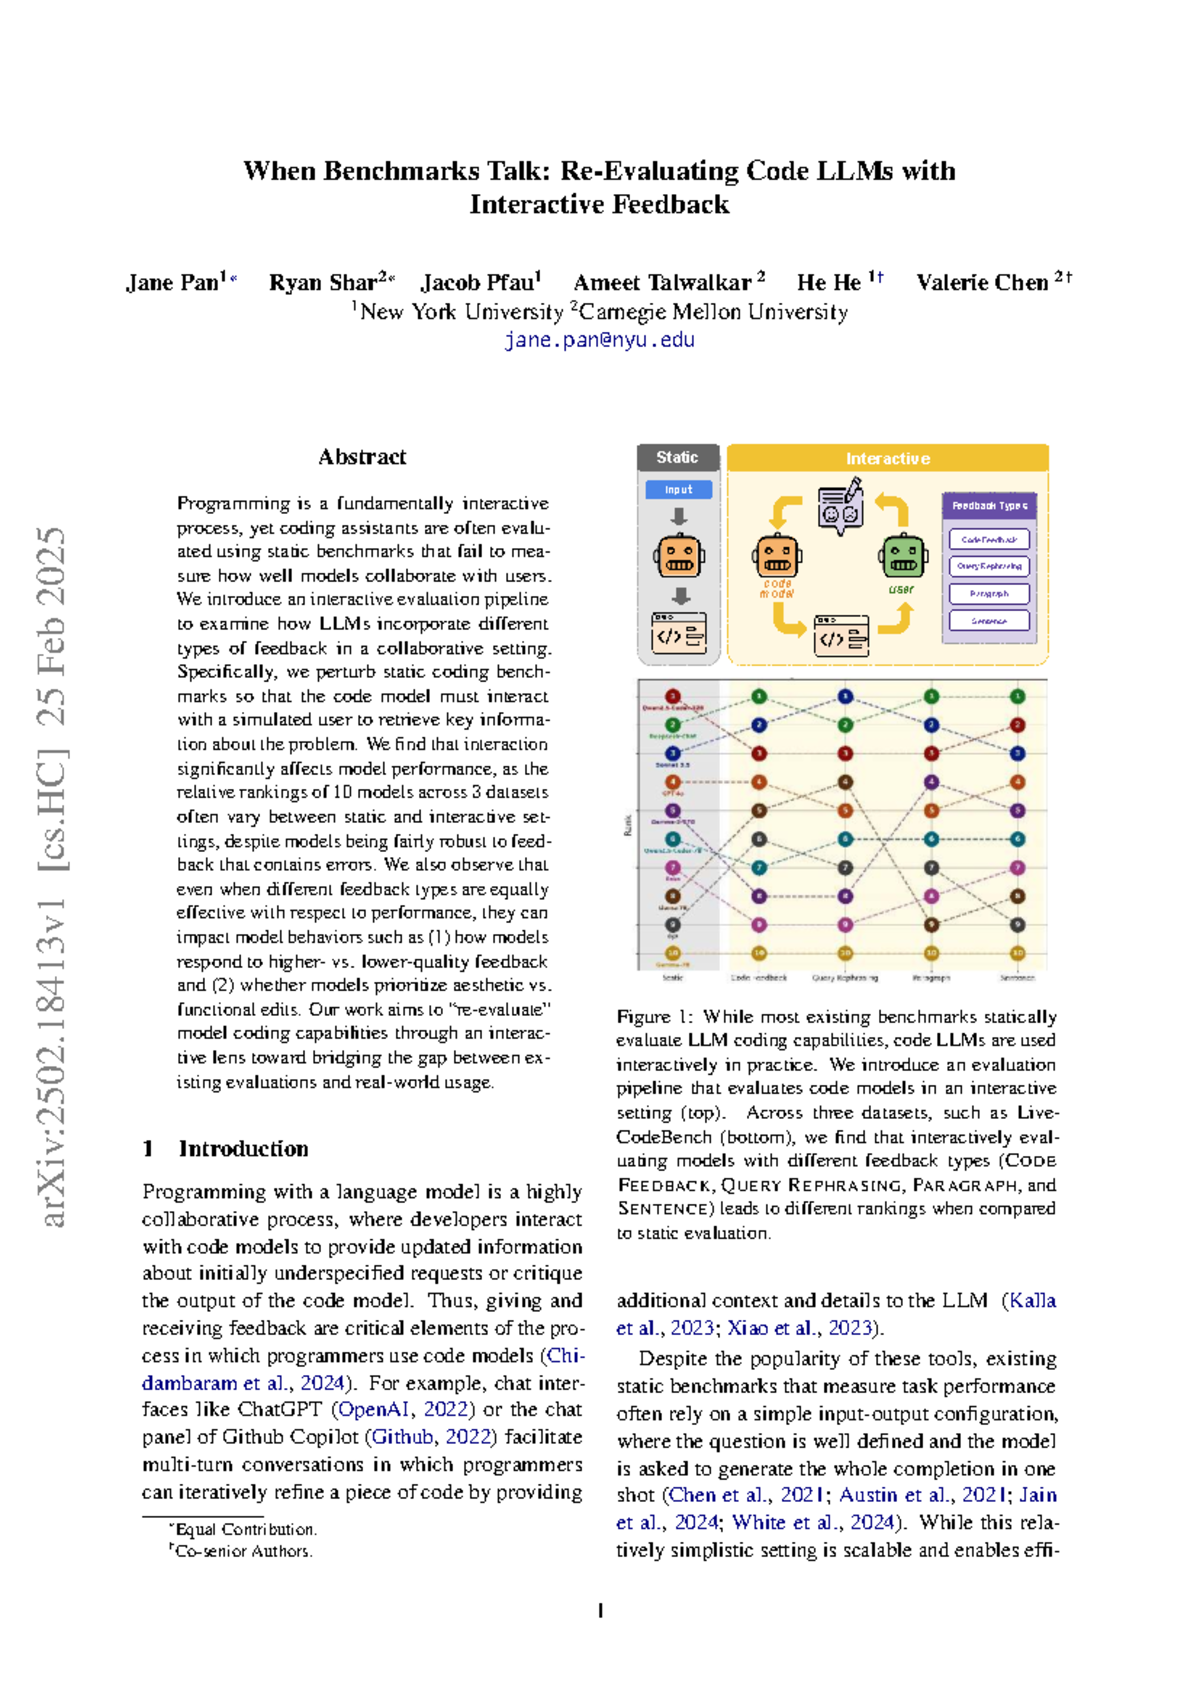
Interactive Evaluation of Code LLMs: Feedback Types and Performance (CS ...
Evaluating LLMs for Production Beyond Benchmarks

CodeElo: Benchmarking Competition-level Code Generation of LLMs with ...
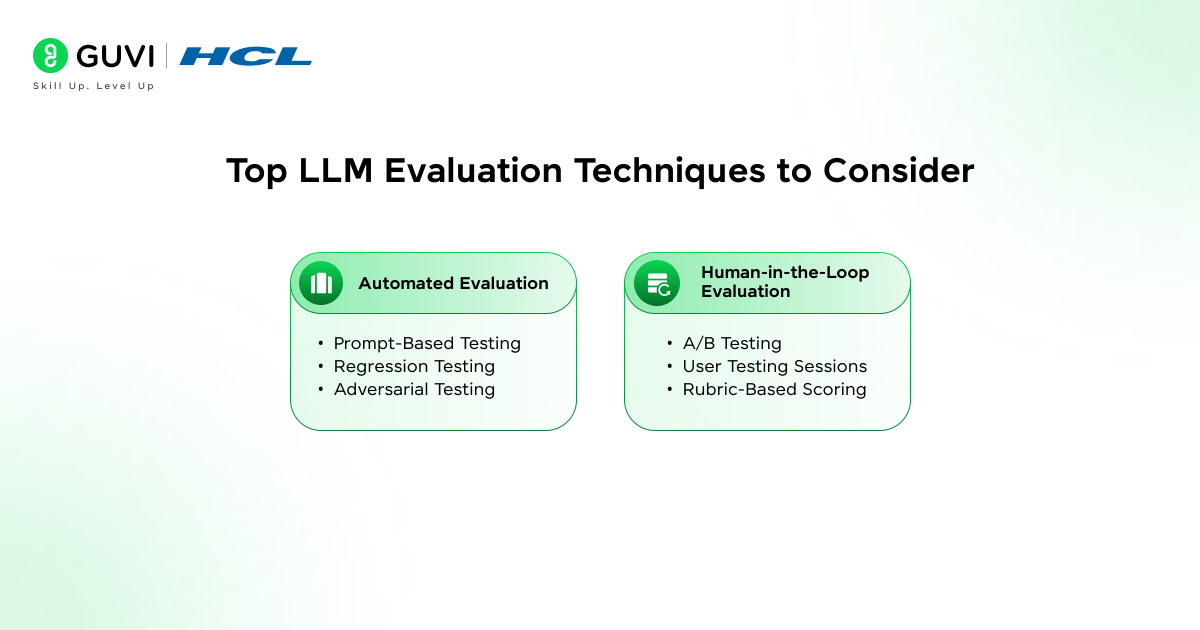
Evaluating LLMs for Production Beyond Benchmarks

Pitfalls of Evaluating Language Models with Open Benchmarks | AI ...
Evaluating LLMs for Production Beyond Benchmarks
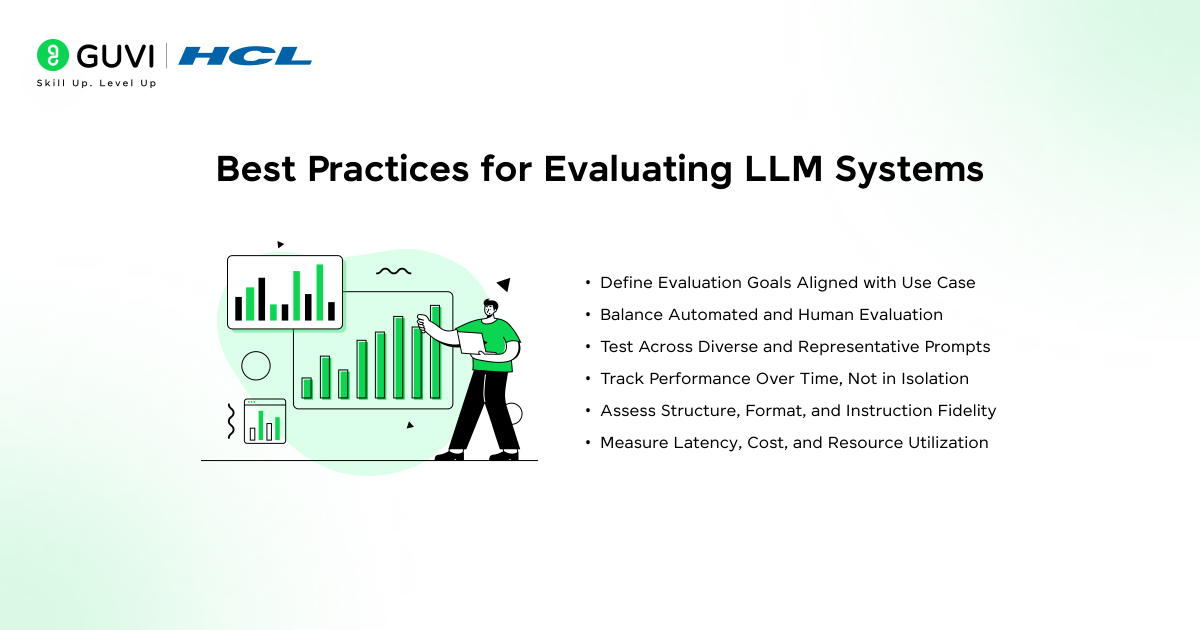
Evaluating LLMs for Production Beyond Benchmarks
Advertisement Space (300x250)

AI Code Generation: New DevQualityEval Benchmark Reveals Which LLMs ...

Meeseeks: An Iterative Benchmark Evaluating LLMs Multi-Turn Instruction ...

CodeARC: A New Benchmark for LLMs in Code Synthesis | Muhammed Aslam A ...

A new benchmark is pushing LLMs to their coding limits with real-world ...

[论文评述] HLS-Eval: A Benchmark and Framework for Evaluating LLMs on High ...

ToolSandbox: Realistic Interactive Benchmark for Evaluating LLM Tool ...
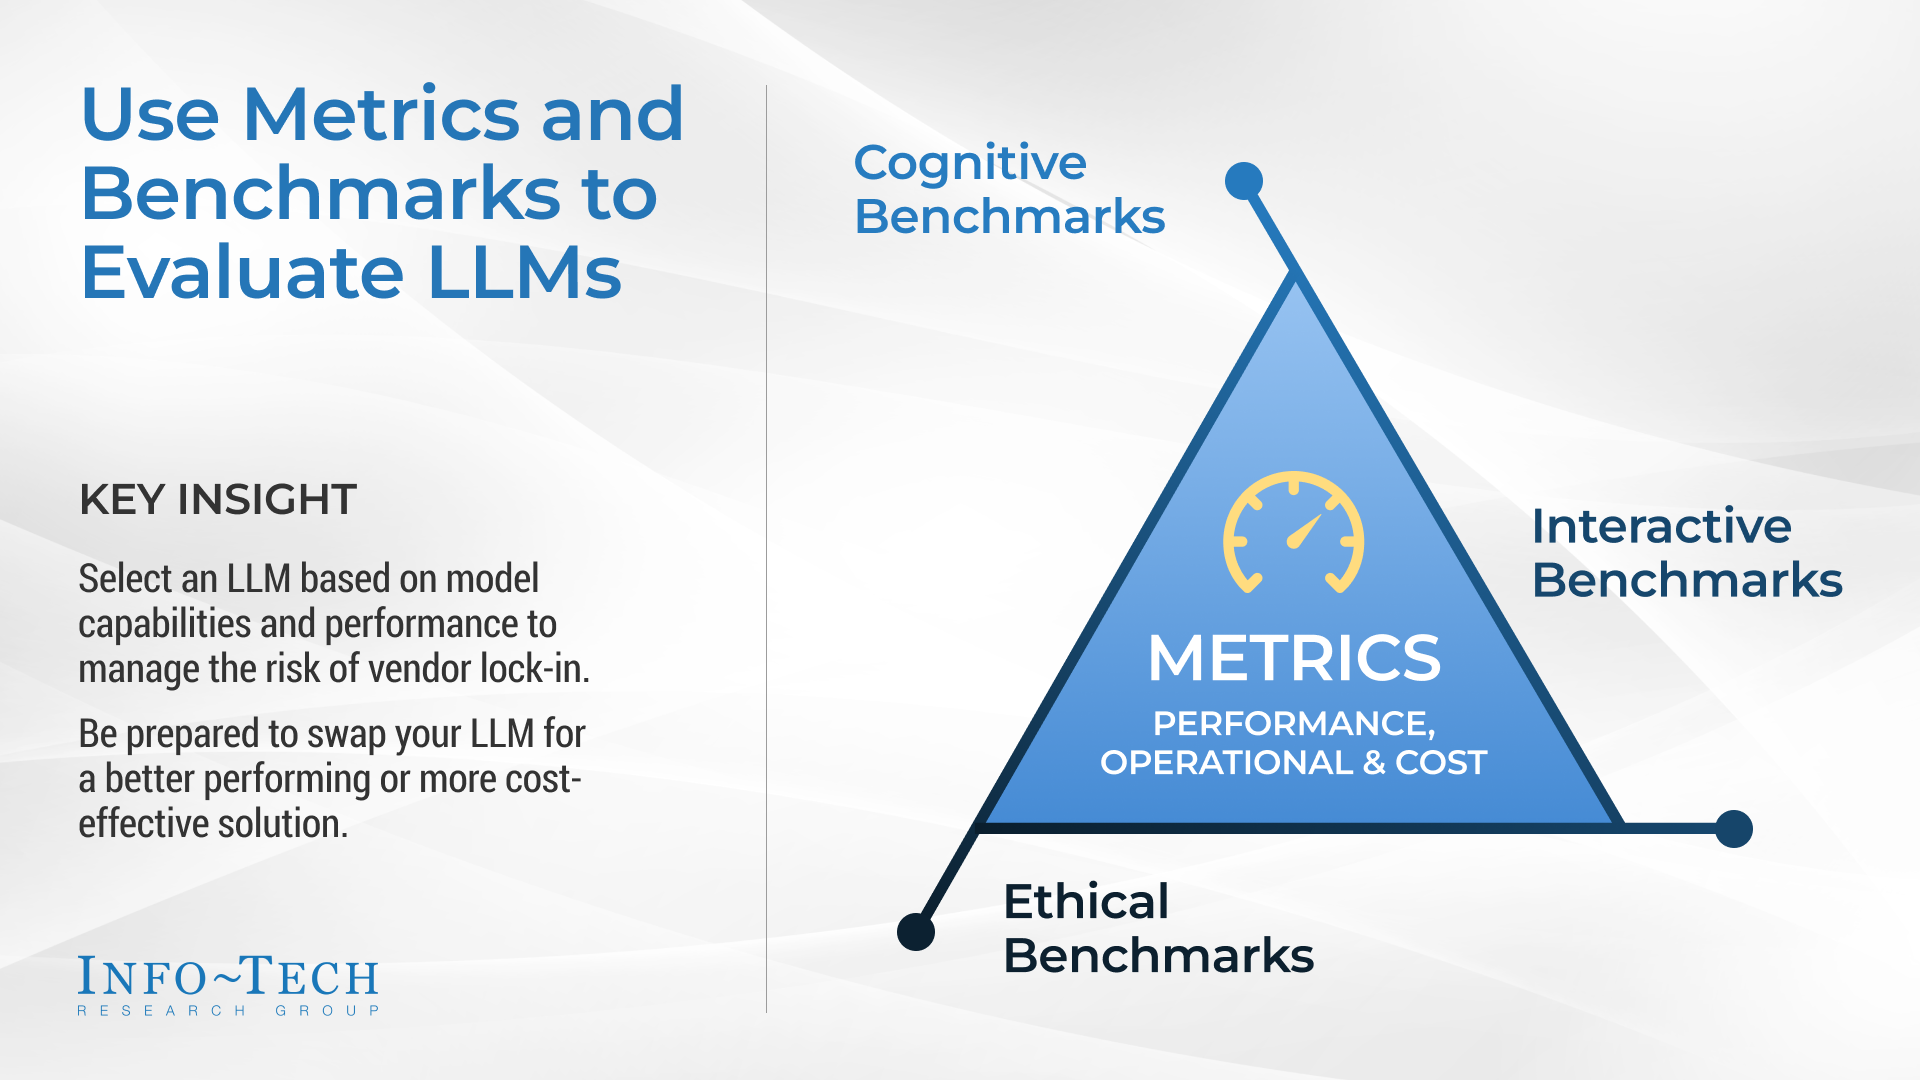
Leverage Metrics and Benchmarks to Evaluate LLMs | Info-Tech Research Group

GBQA: A Game Benchmark for Evaluating LLMs as Quality Assurance ...
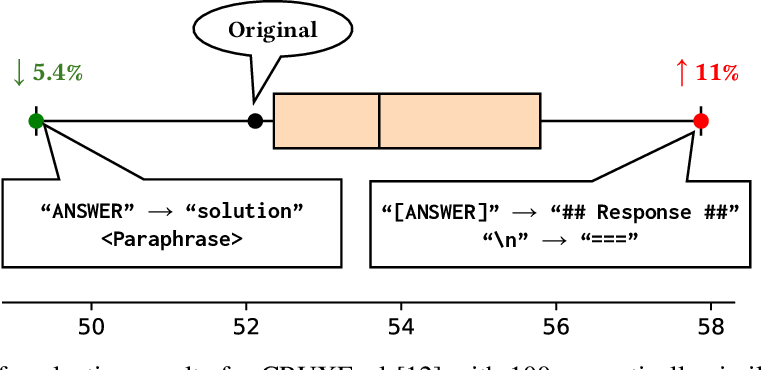
Figure 1 from Re-Evaluating Code LLM Benchmarks Under Semantic Mutation ...
GitHub - Khanhtkp/LLMs-Benchmark: A list of benchmarks dataset with ...
Advertisement Space (336x280)
Bench4HLS: End-to-End Evaluation of LLMs in High-Level Synthesis Code ...

(PDF) Re-Evaluating Code LLM Benchmarks Under Semantic Mutation
HumanEval Benchmark: Evaluating LLM Code Generation Capability
How to Test and Benchmark Multiple LLMs Without Rewriting Your Code ...

Where Do LLMs Still Struggle? An In-Depth Analysis of Code Generation ...
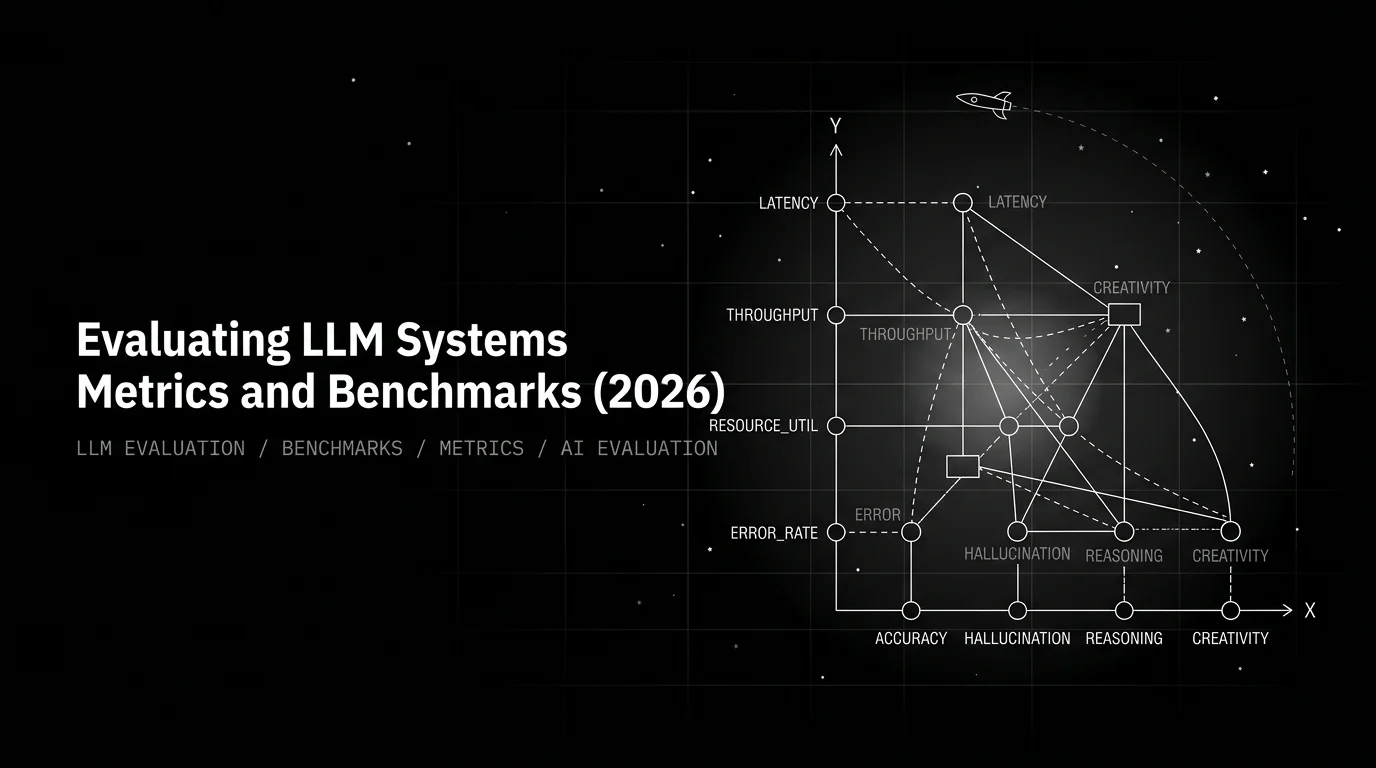
Evaluating LLM Systems: Metrics & Benchmarks 2026

Evaluating and Achieving Controllable Code Completion in Code LLM | AI ...

New benchmark for LLMs on secure code generation | Clint Gibler posted ...

FB-Bench: A Fine-Grained Multi-Task Benchmark for Evaluating LLMs ...

CTIBench - A Benchmark For Evaluating LLMs in Cyber Threat ...
Advertisement Space (336x280)
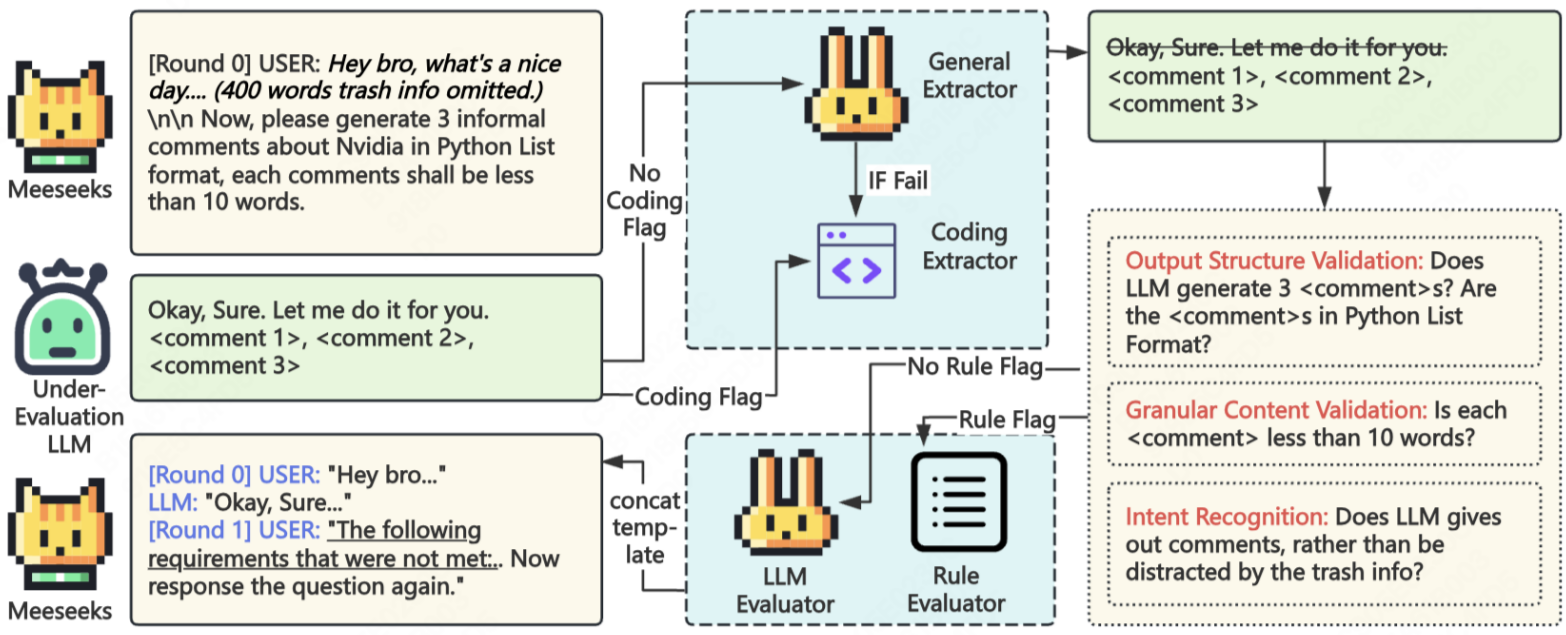
[论文评述] Meeseeks: An Iterative Benchmark Evaluating LLMs Multi-Turn ...
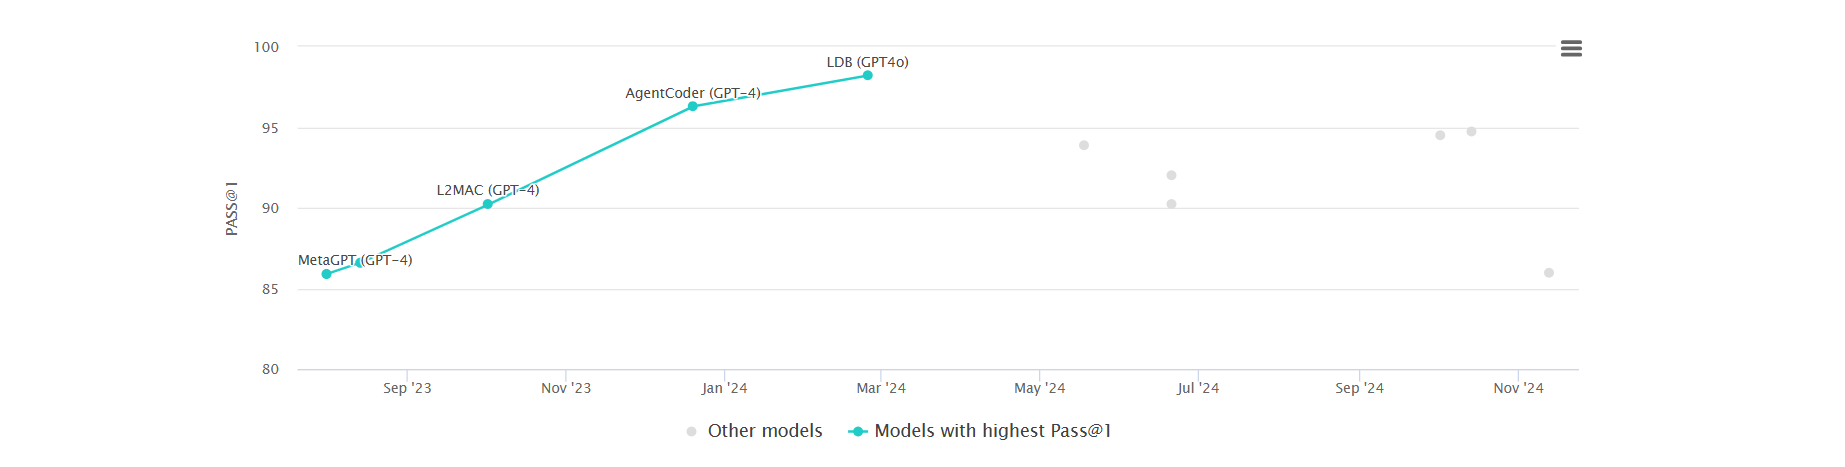
HumanEval Benchmark: Evaluating LLM Code Generation Capability

(PDF) ClassEval: A Manually-Crafted Benchmark for Evaluating LLMs on ...
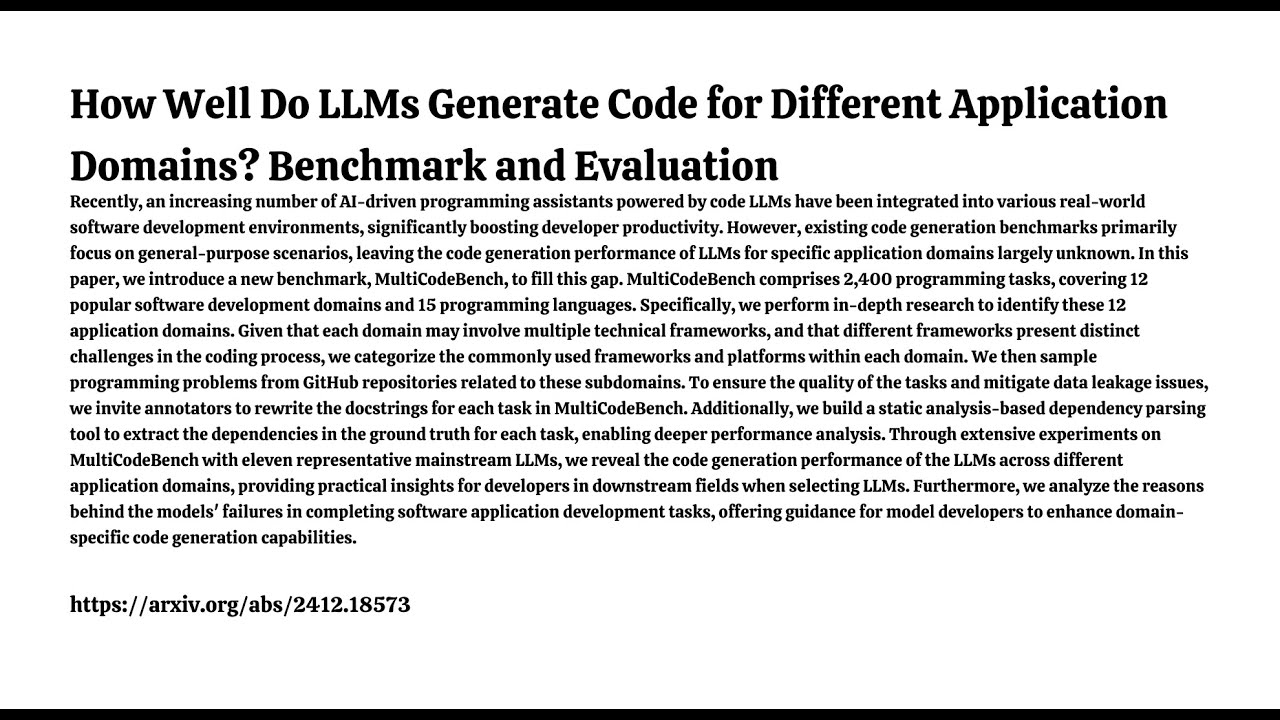
How Well Do LLMs Generate Code for Different Application Domains ...
GBQA: A Game Benchmark for Evaluating LLMs as Quality Assurance ...

(PDF) FrontendBench: A Benchmark for Evaluating LLMs on Front-End ...