
Pdf Scalify Scale Propagation For Efficient Low Precision Llm Training
Scalify: scale propagation for efficient low-precision LLM training ...

(PDF) Scalify: scale propagation for efficient low-precision LLM training
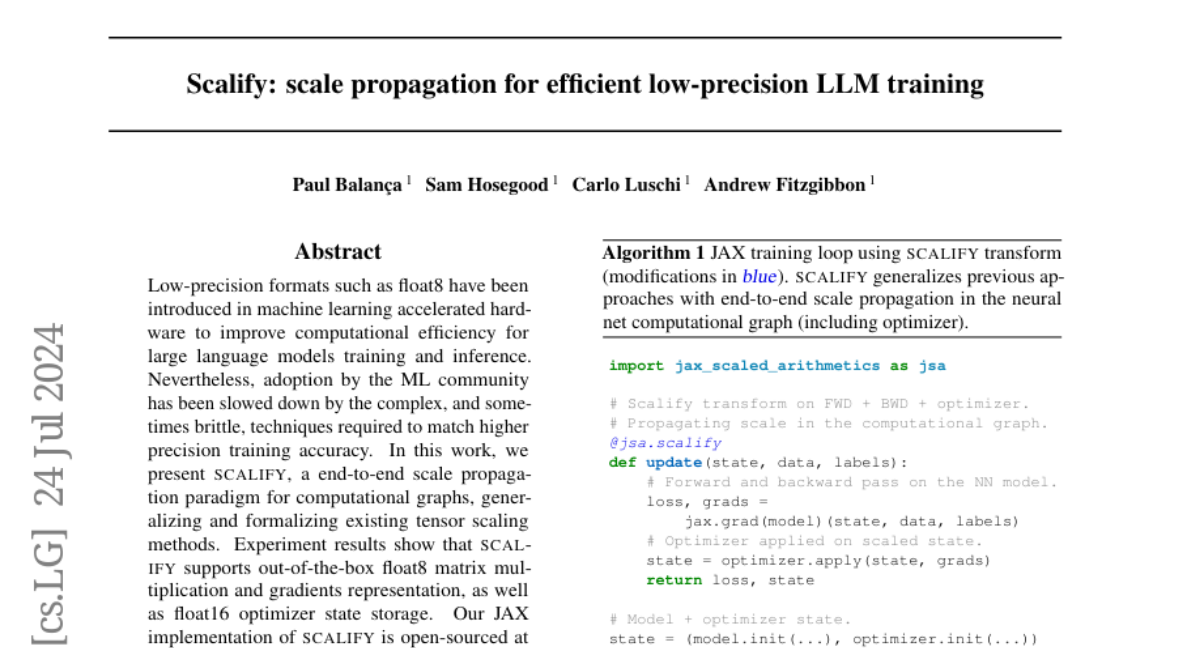
Scalify: scale propagation for efficient low-precision LLM training ...

Scalify: scale propagation for efficient low-precision LLM training ...

Scaling with Collapse: Efficient and Predictable Training of LLM Families

Rethinking LLM scaling laws for both training and inference efficiency

Evaluating LLM Models for Production Systems Methods and Practices - | PDF

Scaling with Collapse: Efficient and Predictable Training of LLM Families

Collage: Light-Weight Low-Precision Strategy for LLM Training - 智源社区论文

Training loss of SCALIFY GPT2 experiments. Table 3 details the ...
Advertisement Space (300x250)
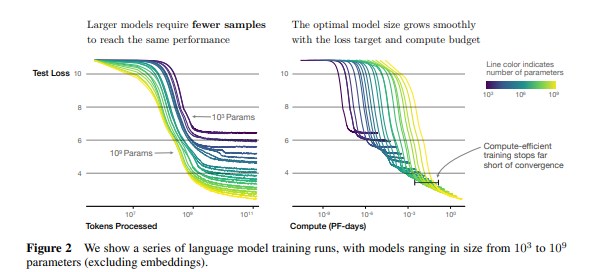
[2024 LLM 스터디] Scaling Laws for Neural Language Models (2020)

[논문 리뷰] Scaling with Collapse: Efficient and Predictable Training of ...
New Scalability Tips for LLM Platforms: Step-by-Step Guide
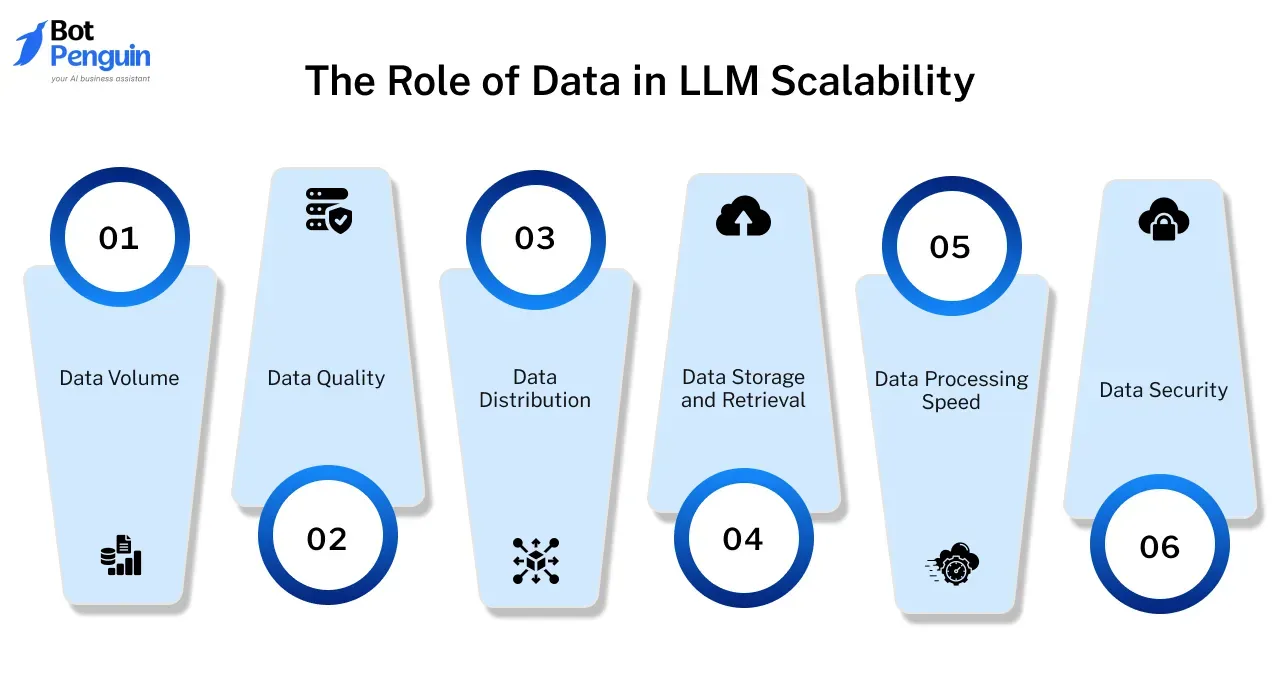
New Scalability Tips for LLM Platforms: Step-by-Step Guide

(PDF) Lumos: Efficient Performance Modeling and Estimation for Large ...

GitHub - horseee/Awesome-Efficient-LLM: A curated list for Efficient ...

GitHub - horseee/Awesome-Efficient-LLM: A curated list for Efficient ...
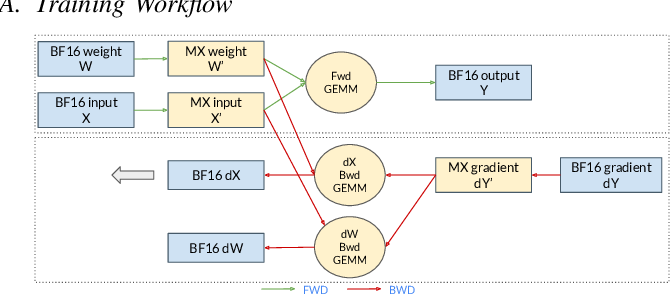
Figure 1 from An Empirical Study of Microscaling Formats for Low ...
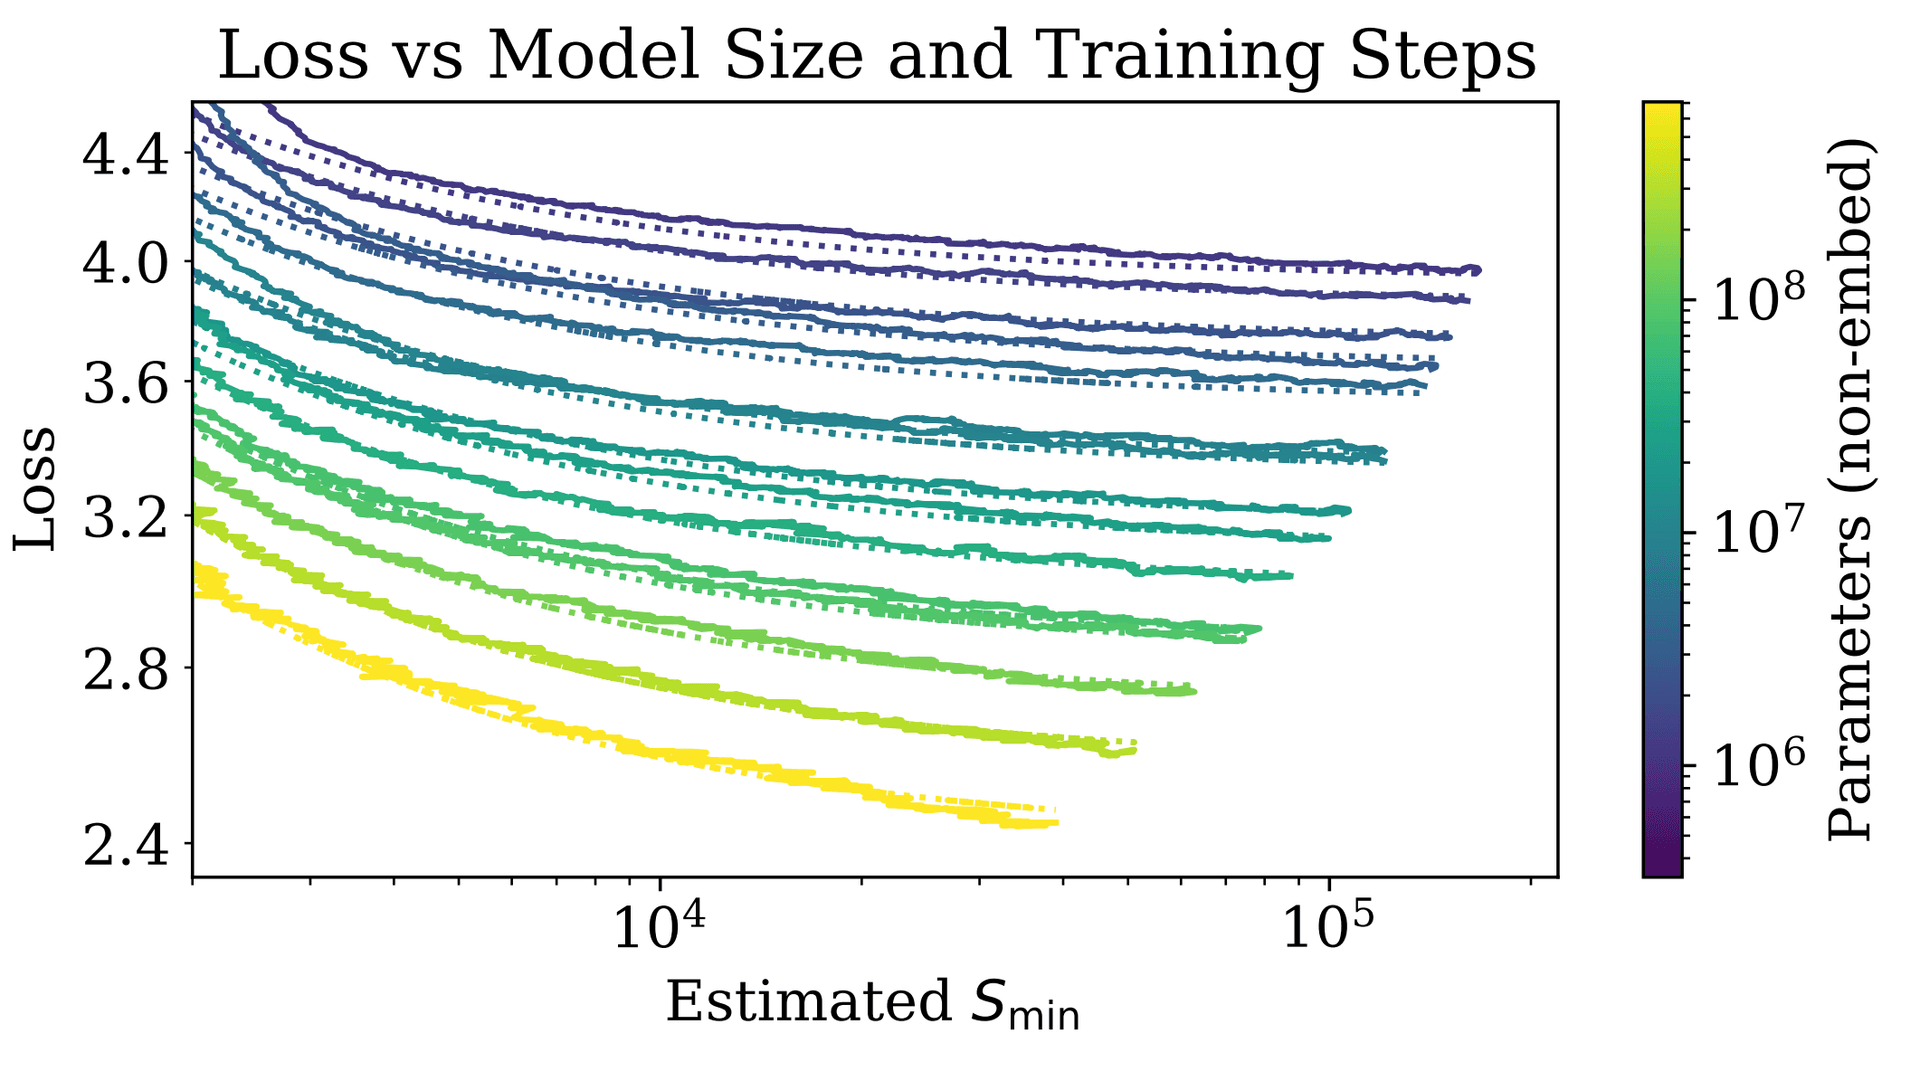
Scaling Laws for LLM Pretraining

Figure 1 from Memory-Efficient LLM Training by Various-Grained Low-Rank ...
Advertisement Space (336x280)
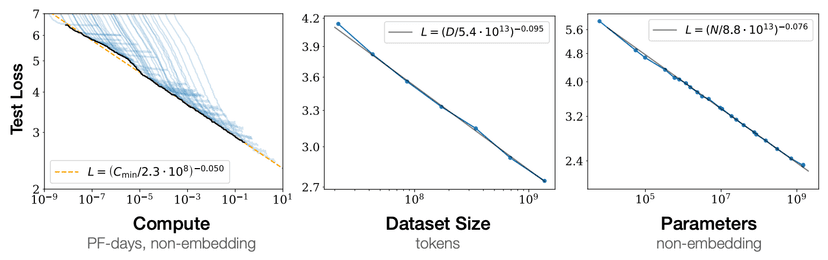
Scaling Laws for LLM Pretraining

Scaling Laws for LLM Pretraining

Essential Practices for Building Robust LLM Pipelines

Galore: Memory-Efficient LLM Training by Gradient Low-Rank Projection ...
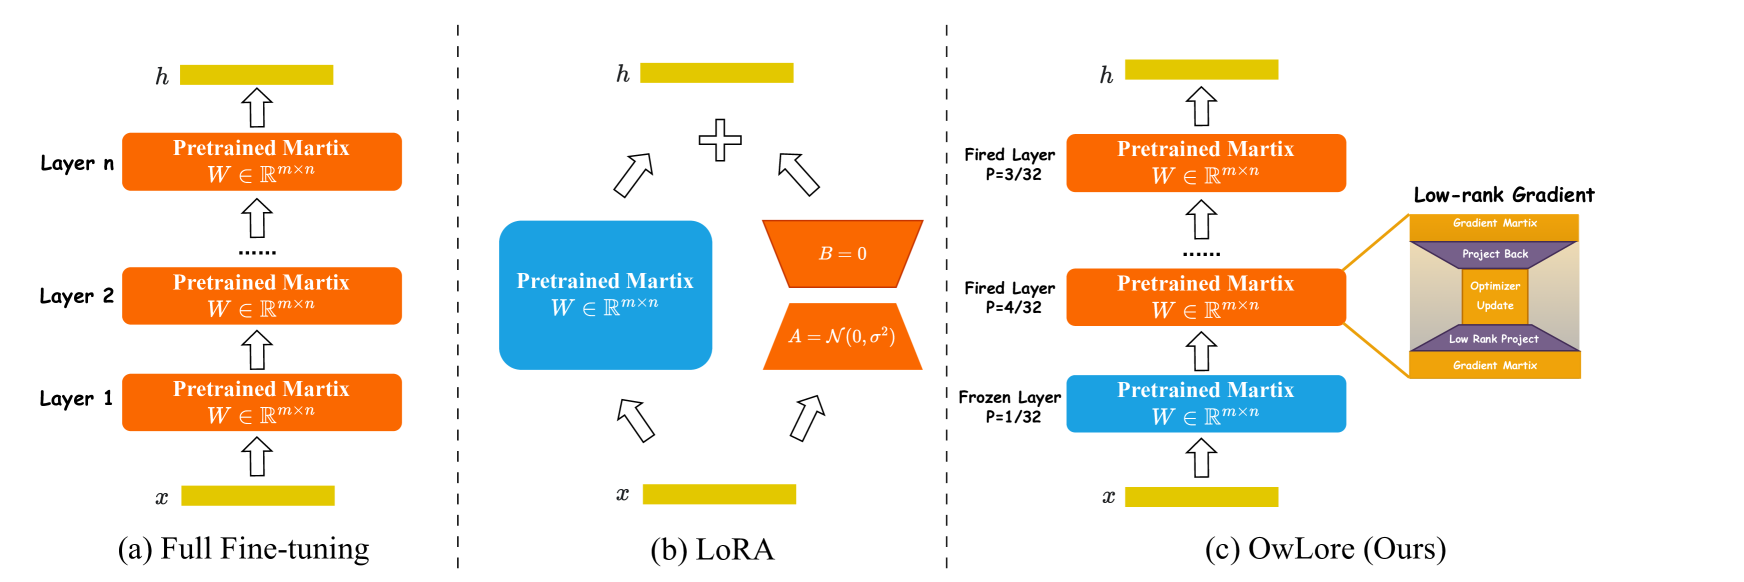
GaLore: Memory-Efficient LLM Training by Gradient Low-Rank Projection ...
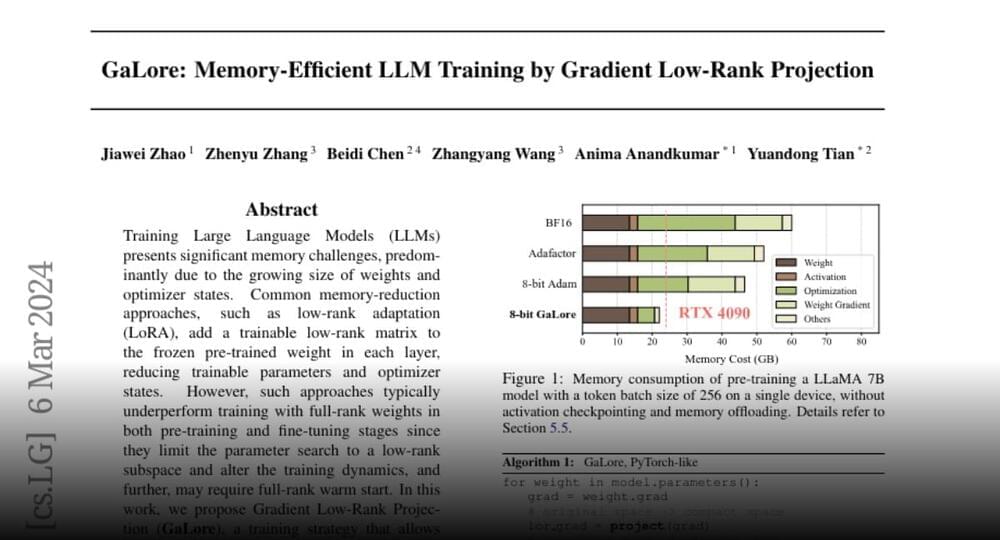
GaLore: Memory-Efficient LLM Training by Gradient Low-Rank Projection ...

How To Train Your LLM Efficiently? Best Practices for Small-Scale ...

New Scalability Tips for LLM Platforms: Step-by-Step Guide

Paper page - Sloth: scaling laws for LLM skills to predict multi ...

New Scalability Tips for LLM Platforms: Step-by-Step Guide
Advertisement Space (336x280)

SimpleScale: Simplifying the Training of an LLM Model Using 1024 GPUs

[论文评述] Scaling Environments for LLM Agents in the Era of Learning from ...

Scaling LLMs for Single-Cell Analysis | PDF | Information Science

Cool new paper preprint Scaling Laws for Precision Two important ...
Vidur: A Large-Scale Simulation Framework for LLM Inference Performance ...

SimpleScale: Simplifying the Training of an LLM Model Using 1024 GPUs