
Performance Of Llama 31 8b Ai Inference Using Vllm On Nd H100 V5

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...
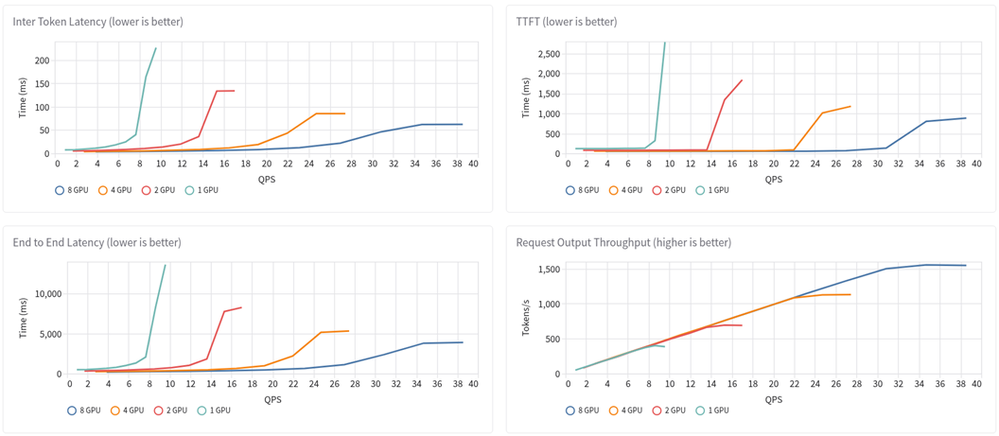
Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...
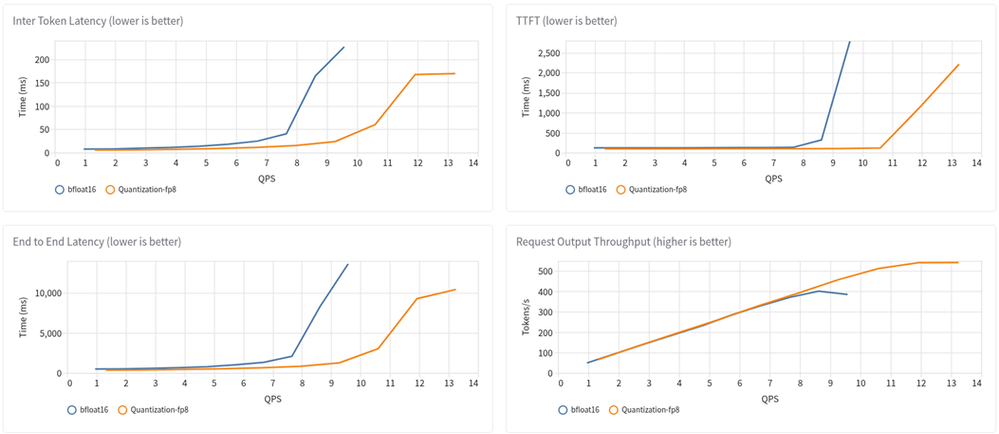
Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...
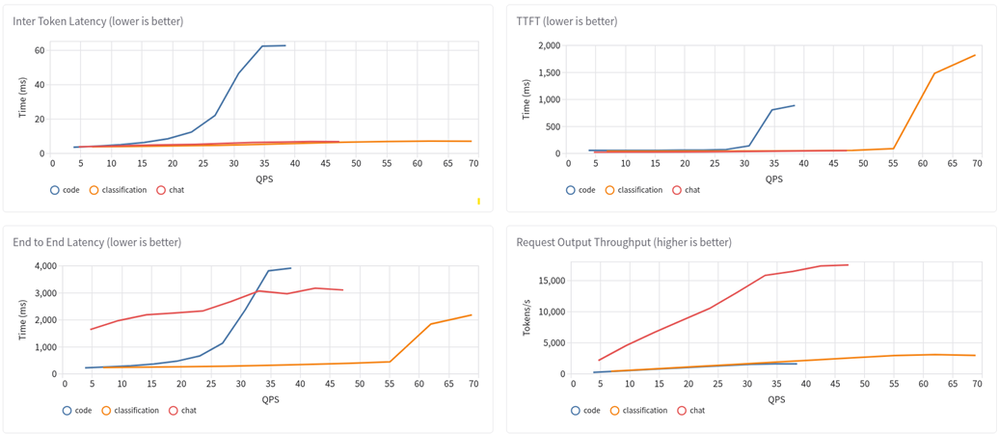
Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...

Inference performance of Llama 3.1 8B using vLLM across various GPUs ...
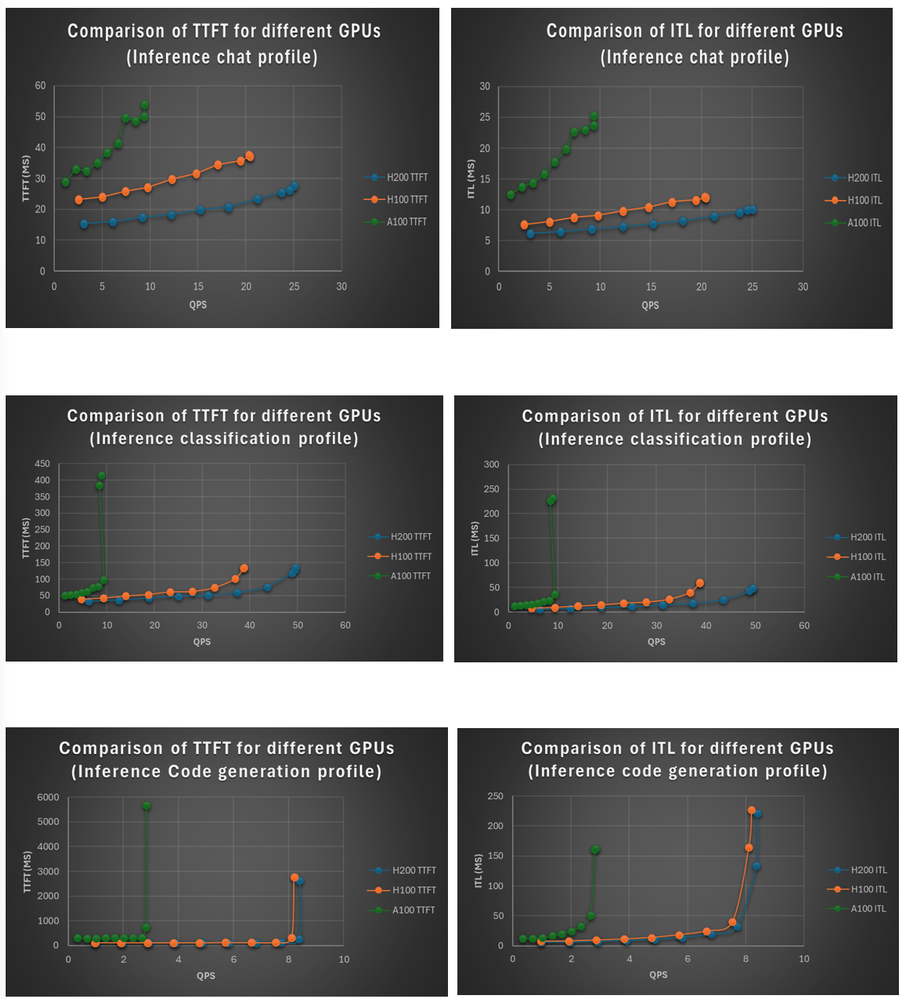
Inference performance of Llama 3.1 8B using vLLM across various GPUs ...

Inference performance of Llama 3.1 8B using vLLM across various GPUs ...
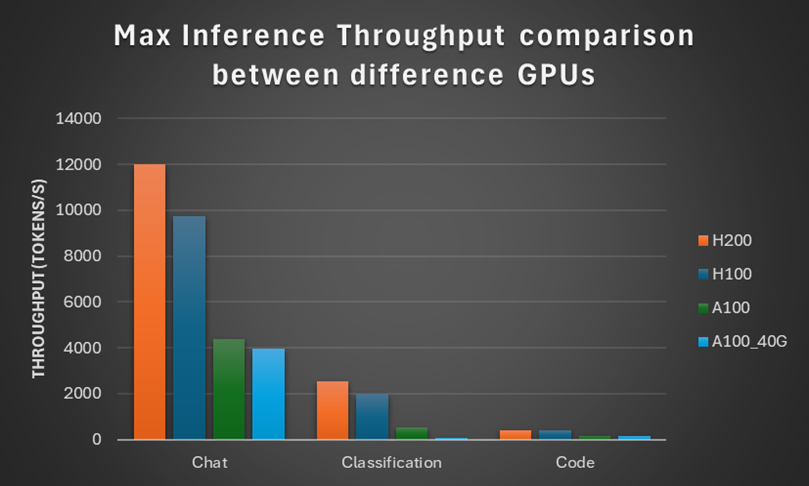
Inference performance of Llama 3.1 8B using vLLM across various GPUs ...
Advertisement Space (300x250)

Performance analysis of DeepSeek R1 AI Inference using vLLM on ND-H100 ...

Performance analysis of DeepSeek R1 AI Inference using vLLM on ND-H100 ...

Performance analysis of DeepSeek R1 AI Inference using vLLM on ND-H100 ...

Performance analysis of DeepSeek R1 AI Inference using vLLM on ND-H100 ...

Inference Benchmarking on Llama 3.1 8B instruct

Boost LLM Inference performance on H100 with quantization This report ...
Phi-4 vs. Llama 3.1 8B for Edge AI and Power Efficiency | Inference Systems

Run OpenAI-compatible LLM inference with LLaMA 3.1-8B and vLLM | Modal Docs

Deploy Llama 3 8B with vLLM | Red Hat Developer

Run Llama 3.1 with vLLM on RunPod Serverless | Runpod Blog
Advertisement Space (336x280)

Supercharging Your Inference of Large Language Models with vLLM (part-1 ...

Deploy Llama 3 8B with vLLM | Red Hat Developer
Introducing vLLM Inference Provider in Llama Stack | vLLM Blog

10 Key Features of Llama 3.1: Meta's Latest AI Model
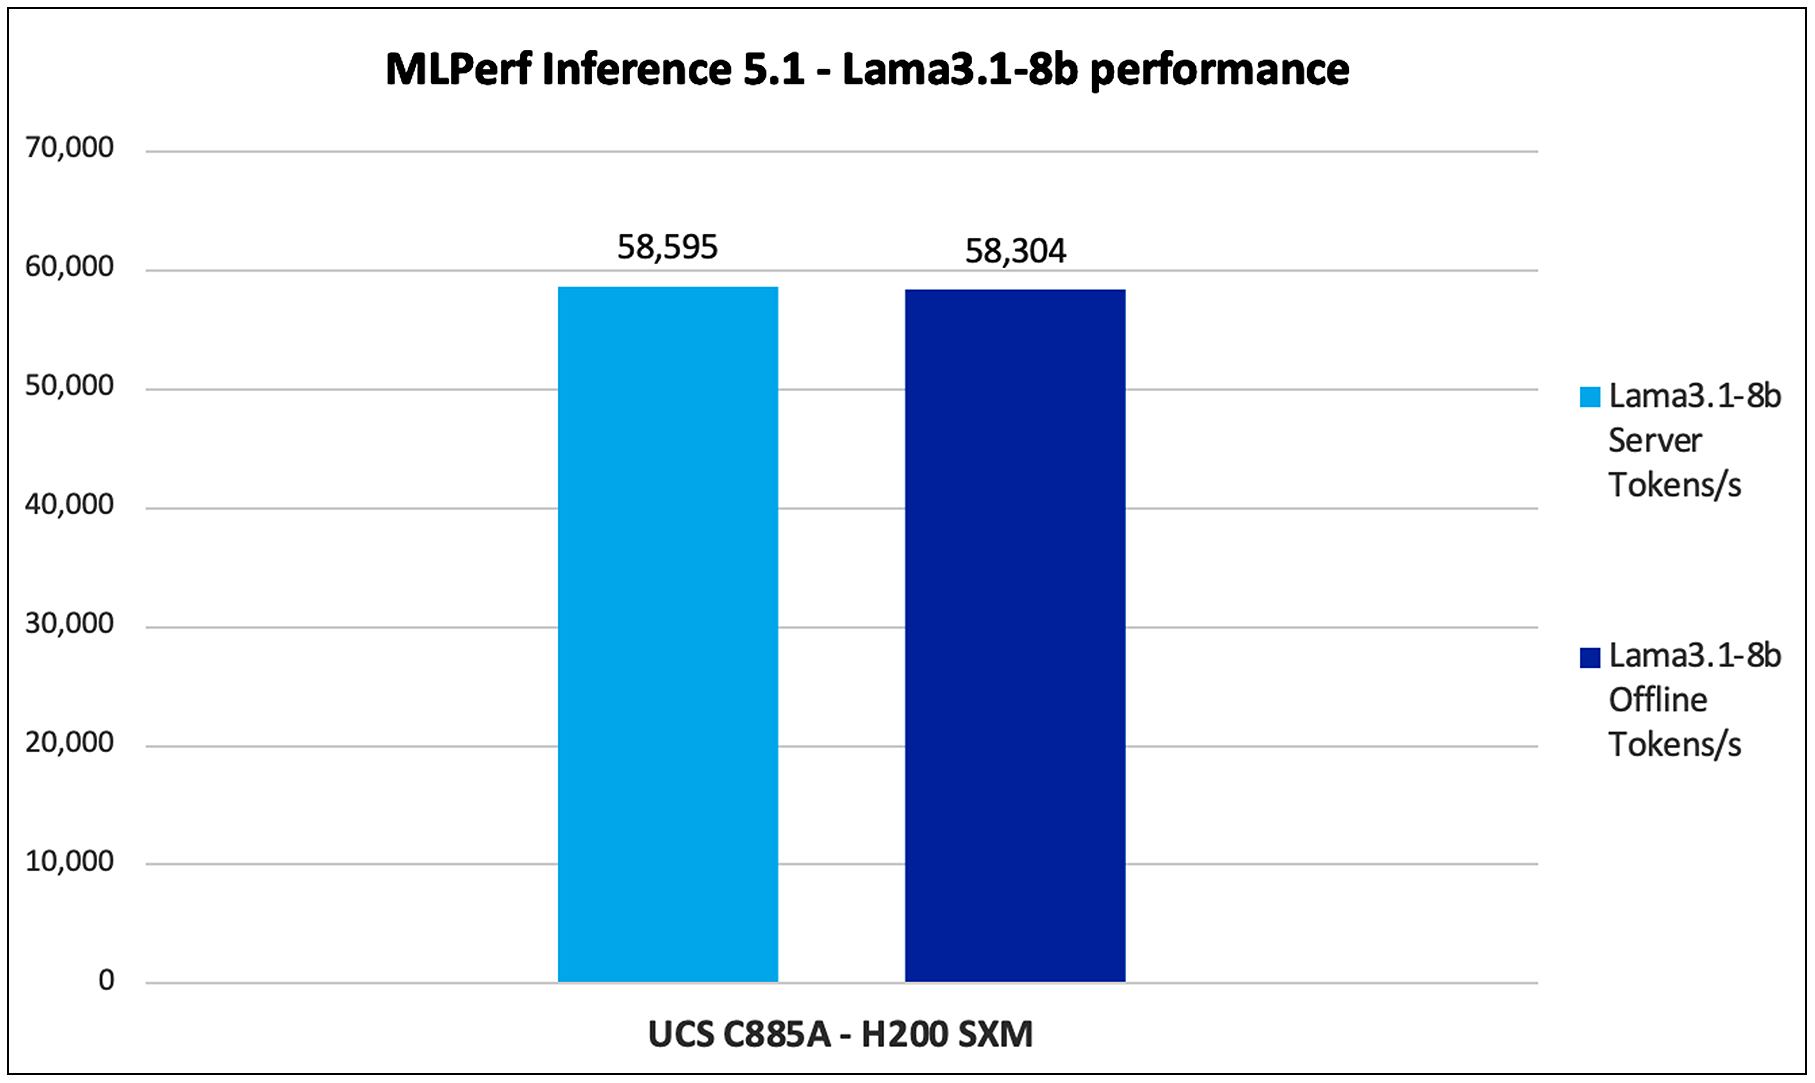
AI Performance: MLPerf Inference on Cisco UCS C885A M8 HGX platform ...
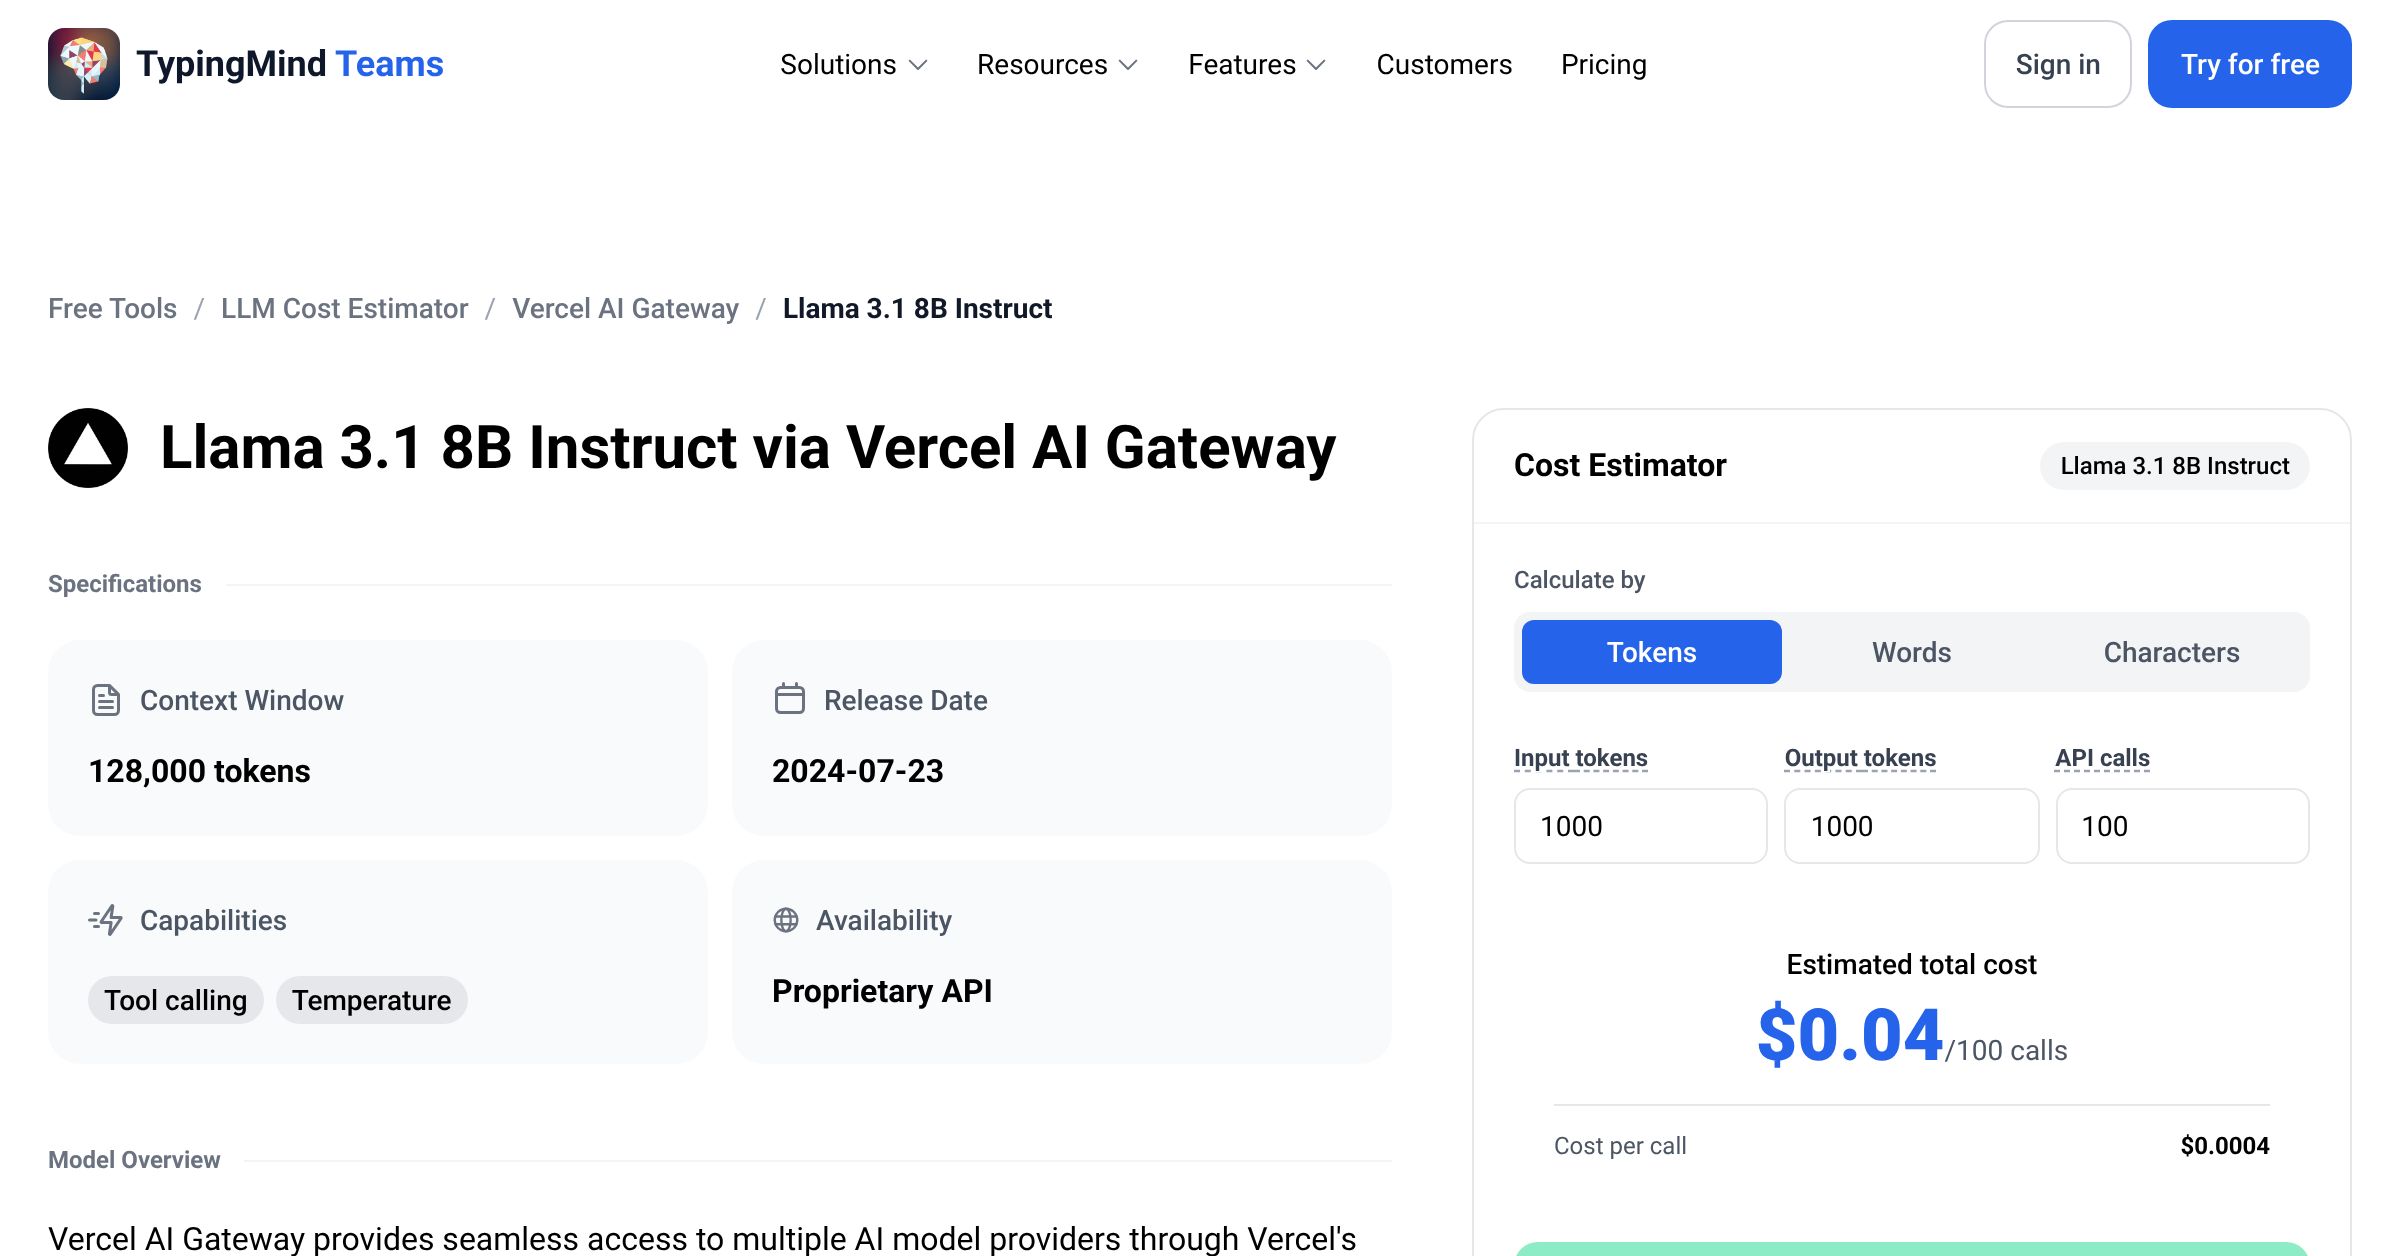
Vercel AI Gateway Llama 3.1 8B Instruct API Pricing Calculator
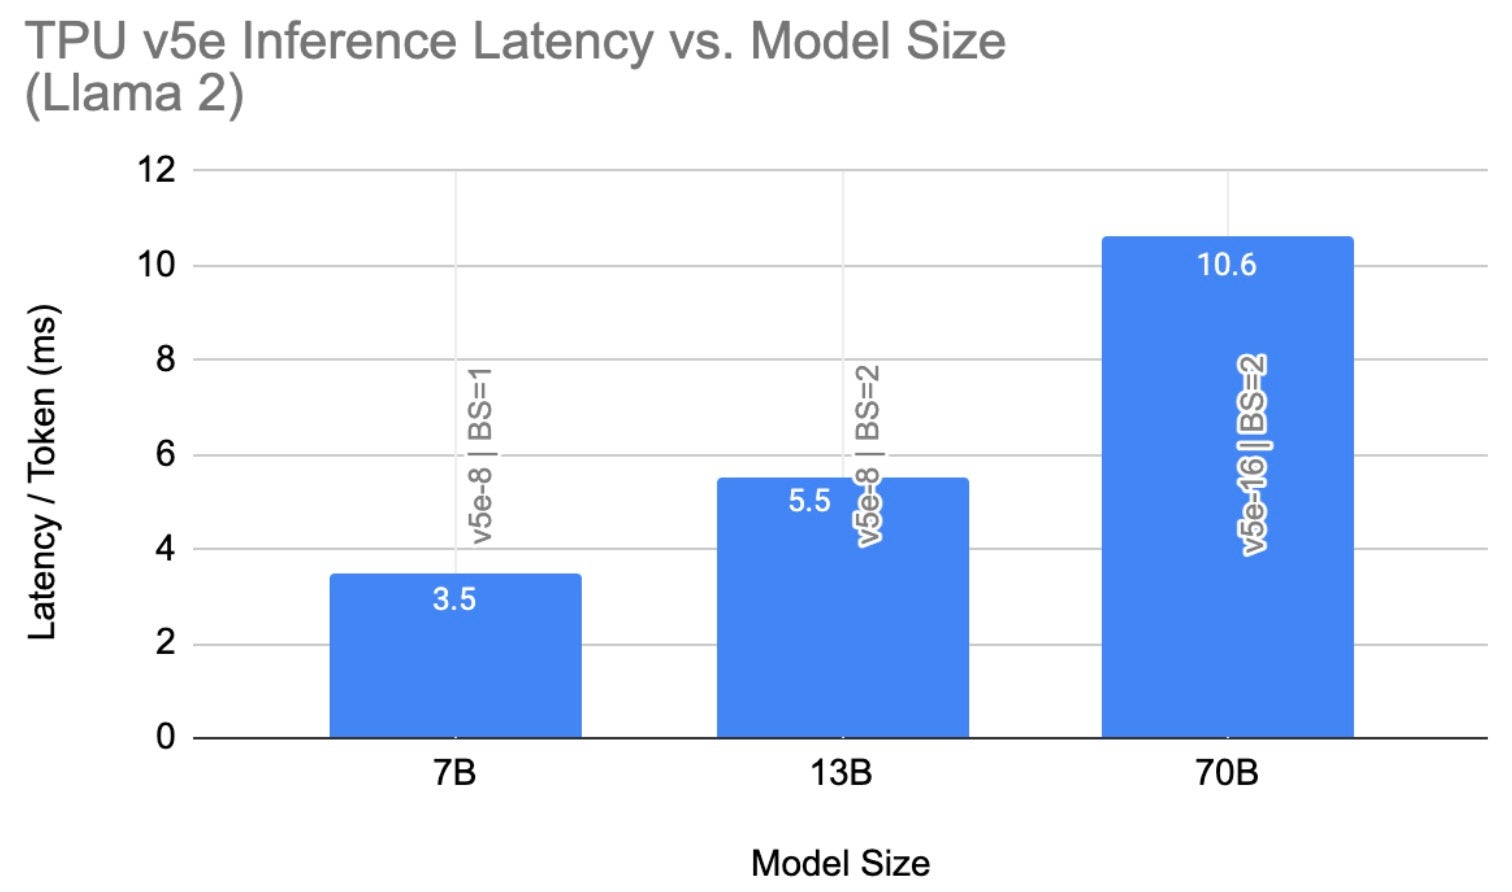
High-Performance Llama 2 Training and Inference with PyTorch/XLA on ...
Compare R1 Distill Llama 8B vs Llama 3.2 Instruct 90B (Vision) | AI ...
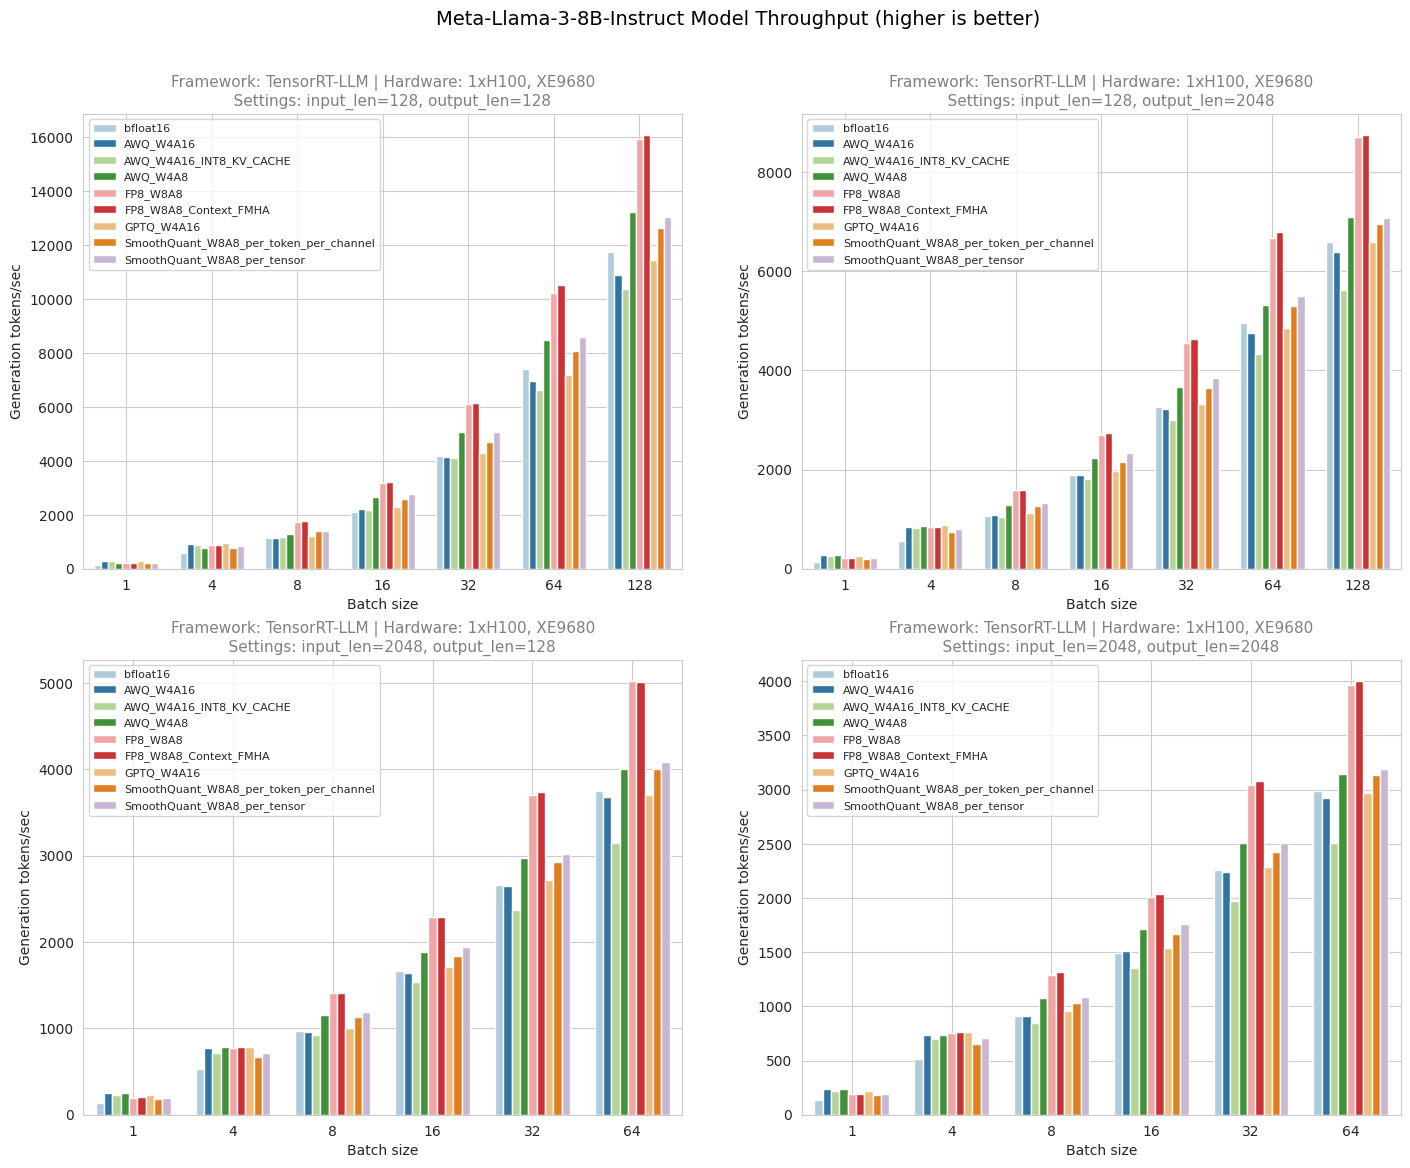
Deploying Llama 8B Model with Advanced Quantization Techniques on Dell ...
llama 3 8b model with A10 GPU, OOM with VLLM, but holds good on HF ...
Advertisement Space (336x280)
Llama 3.1 8B Instruct compared to other AI models | OpenRouter
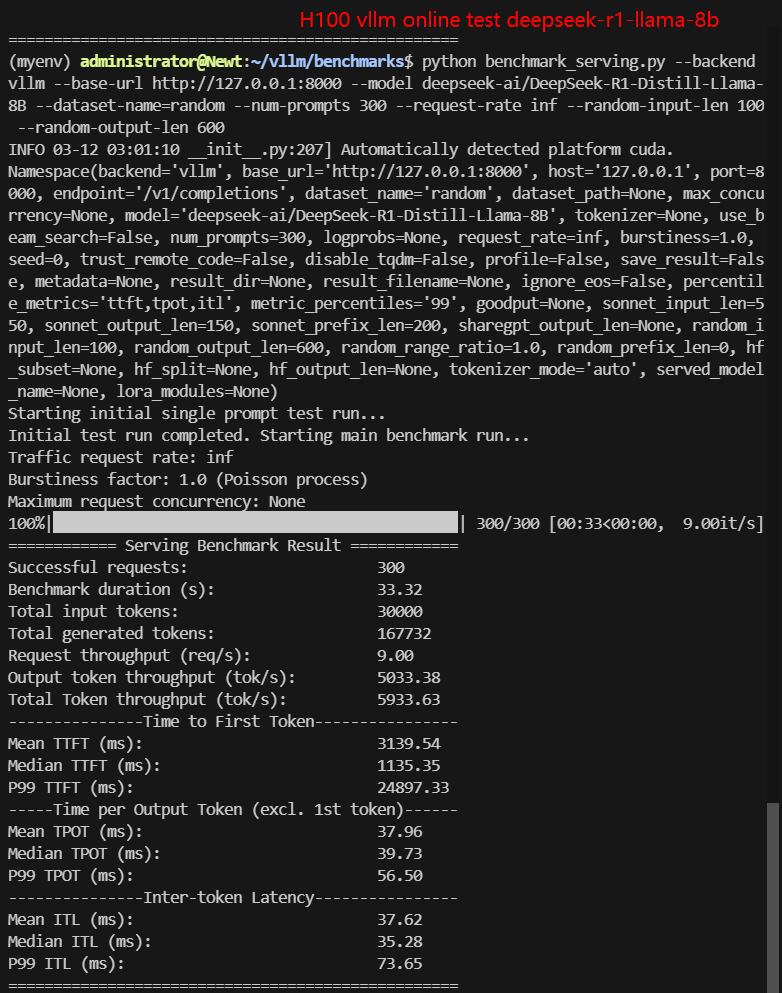
Nvidia H100 vLLM Benchmark Results: Reasoning LLMs on Hugging Face

Llama-3-8B with vLLM on Inferentia2 | AI on EKS
2:4 Sparse Llama FP8: SOTA performance for NVIDIA Hopper GPUs | Red Hat ...
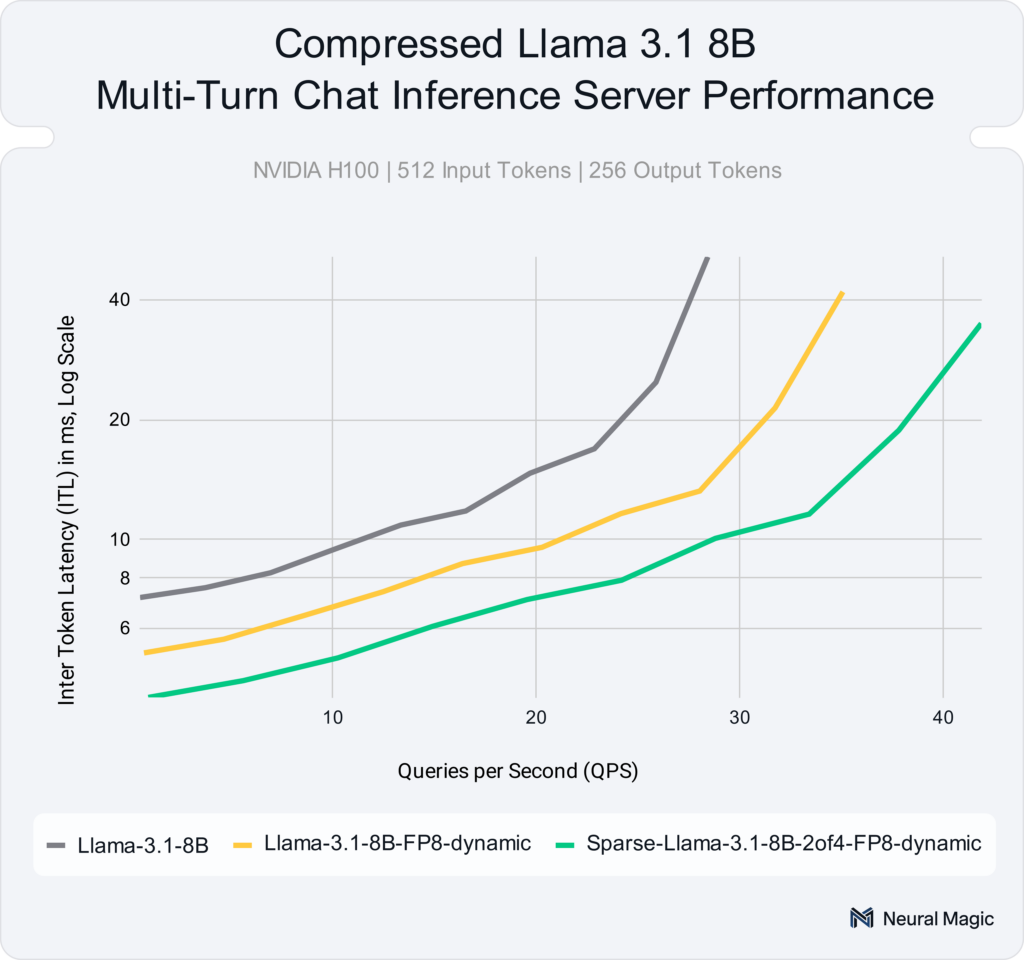
2:4 Sparse Llama FP8: SOTA performance for NVIDIA Hopper GPUs | Red Hat ...
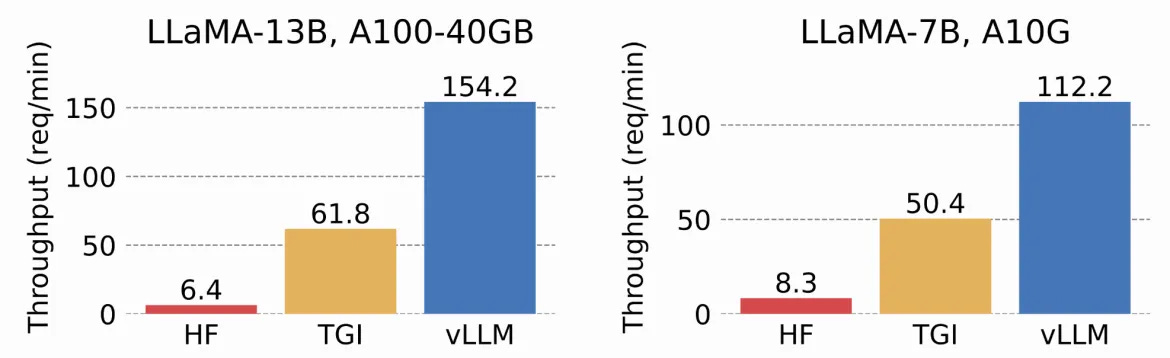
The AI Engineer's Guide to Inference Engines and Frameworks