
Pseudovc Improving One Shot Voice Conversion With Pseudo Paired Data

PseudoVC: Improving One-shot Voice Conversion with Pseudo Paired Data ...

PseudoVC: Improving One-shot Voice Conversion with Pseudo Paired Data ...

PseudoVC: Improving One-shot Voice Conversion with Pseudo Paired Data ...

(PDF) Improving robustness of one-shot voice conversion with deep ...

Figure 1 from Improving robustness of one-shot voice conversion with ...
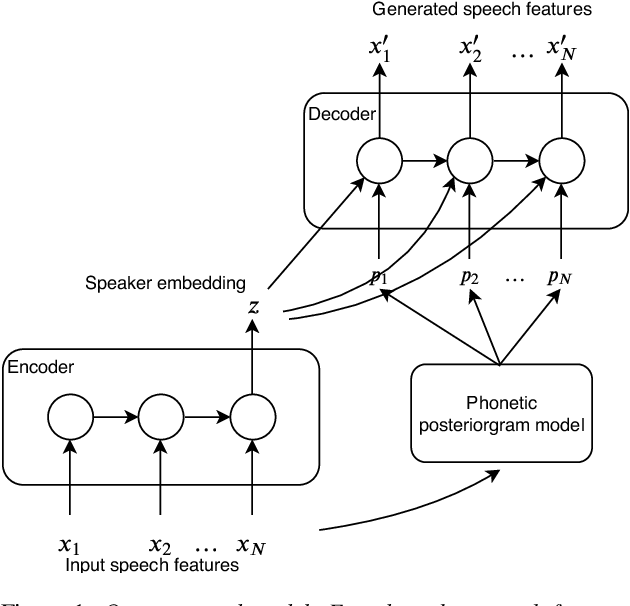
Figure 1 from One-Shot Voice Conversion with Disentangled ...

One-Shot Voice Conversion Using IN | PDF | Data Compression | Speech ...

(PDF) W2VC: WavLM representation based one-shot voice conversion with ...

(PDF) One-Shot Voice Conversion with Global Speaker Embeddings
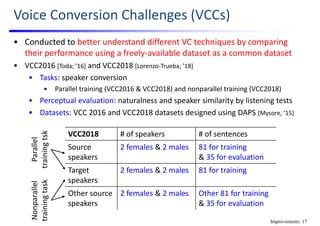
Statistical voice conversion with direct waveform modeling | PDF
Advertisement Space (300x250)

[논문 리뷰] Improving 3D Few-Shot Segmentation with Inference-Time Pseudo ...
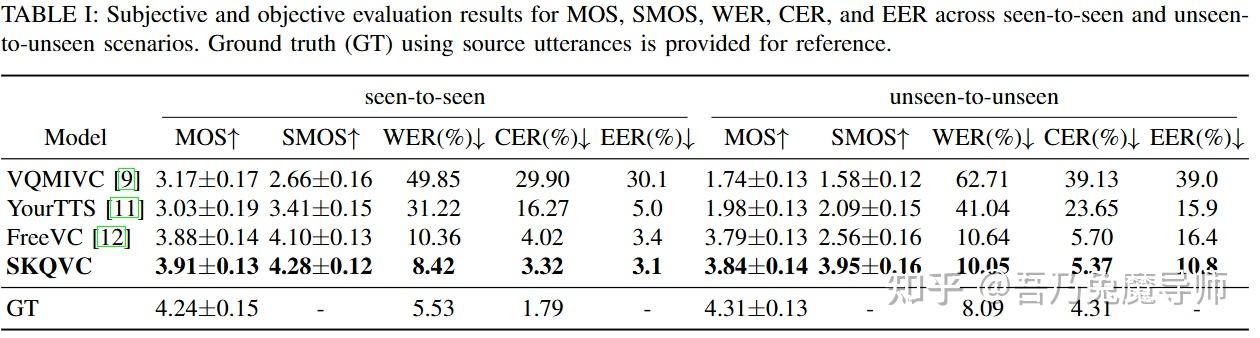
SKQVC: One-Shot Voice Conversion by K-Means Quantization with Self ...

Diffusion-Based Voice Conversion with Fast Maximum Likelihood Sampling ...
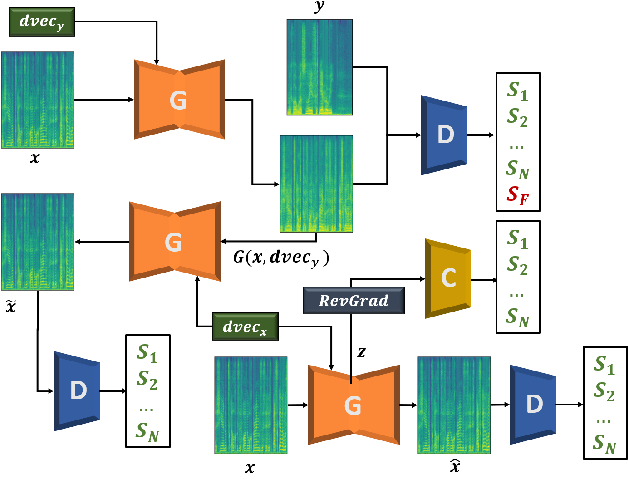
Figure 1 from One-Shot Voice Conversion with Speaker-Agnostic StarGAN ...
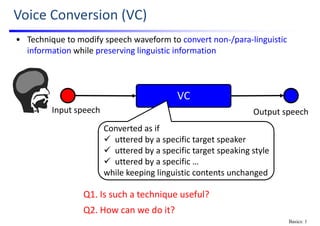
Statistical voice conversion with direct waveform modeling | PDF
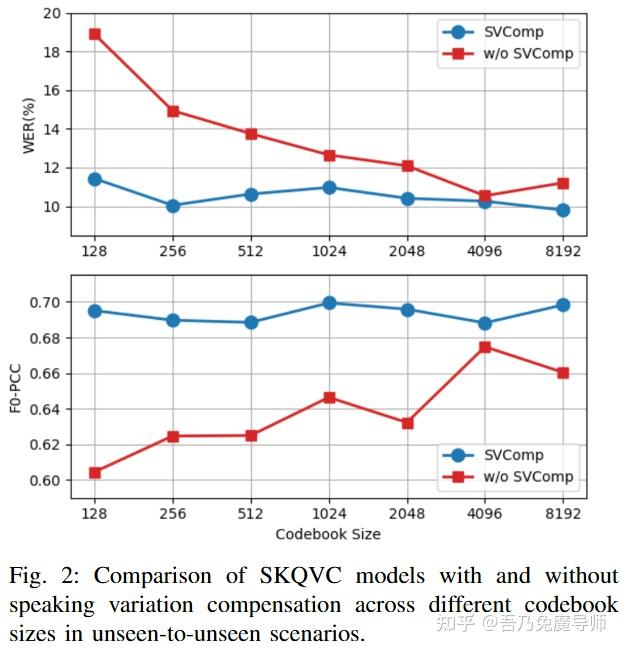
SKQVC: One-Shot Voice Conversion by K-Means Quantization with Self ...

[논문 리뷰] Enhancing Expressive Voice Conversion with Discrete Pitch ...

Iteratively Improving Speech Recognition and Voice Conversion | by ...

AVQVC: One-shot Voice Conversion by Vector Quantization with Applying ...
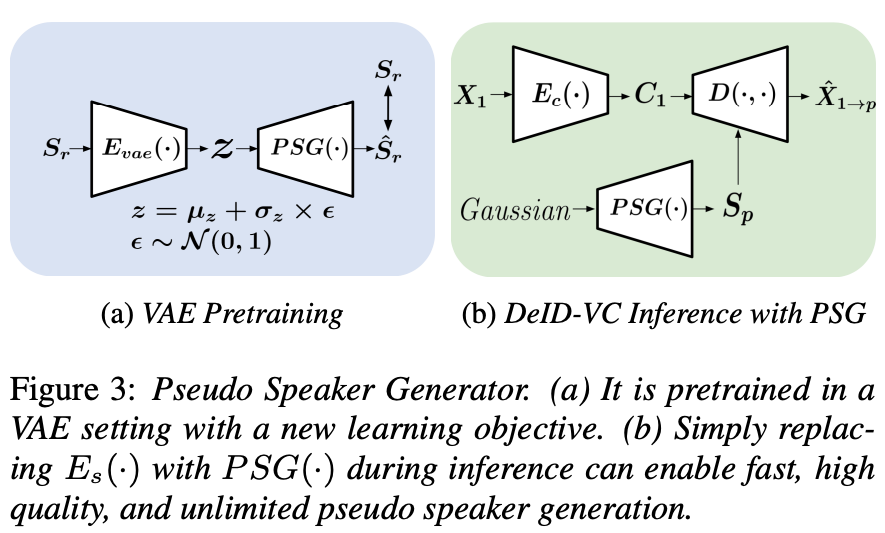
[論文メモ] DeID-VC: Speaker De-identification via Zero-shot Pseudo Voice ...
Advertisement Space (336x280)
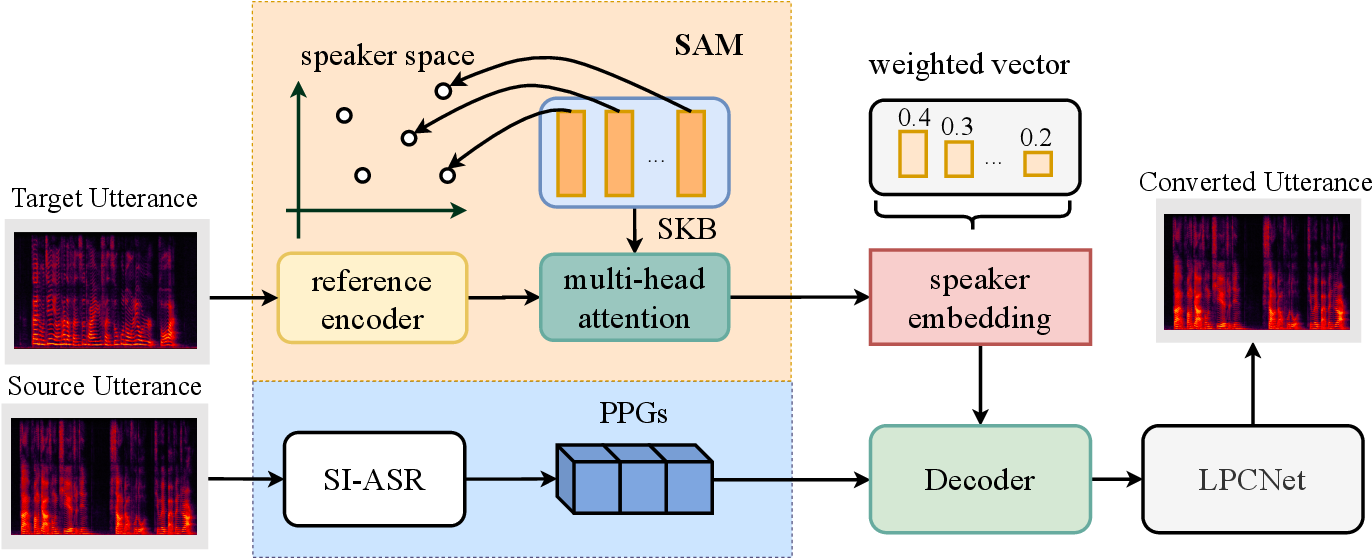
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

STYLETTS-VC: ONE-SHOT VOICE CONVERSION BY KNOWLEDGE TRANSFER FROM STYLE ...

[2308.06382] Phoneme Hallucinator: One-shot Voice Conversion via Set ...

[Paper review] Robust One-Shot Singing Voice Conversion (ROSVC)

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Demo page for SSL-VC: One-Shot Voice Conversion Through Self-Supervised ...
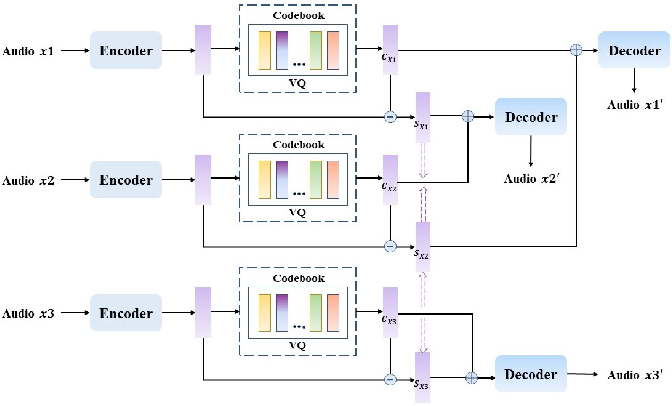
Figure 2 from Avqvc: One-Shot Voice Conversion By Vector Quantization ...
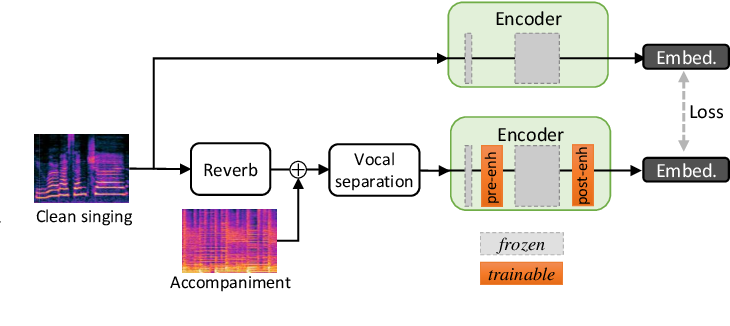
Figure 2 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

【VC】VQVC+: One-Shot Voice Conversion by Vector Quantization and U-Net ...
Advertisement Space (336x280)
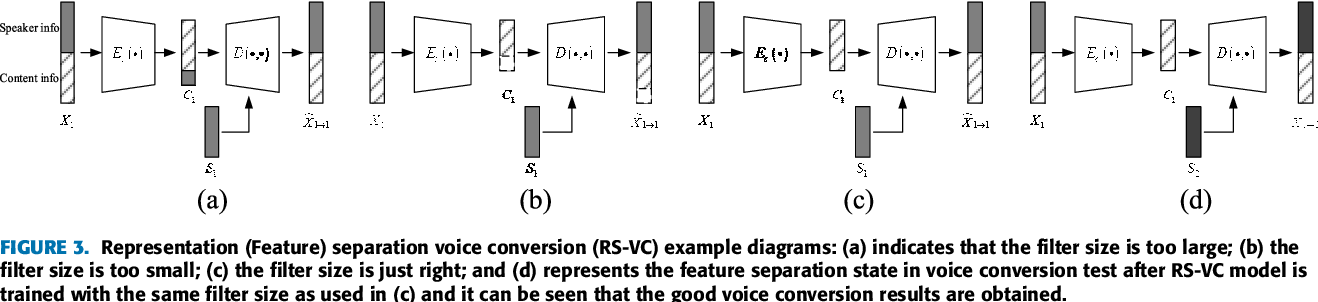
Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

[2011.00316] AGAIN-VC: A One-shot Voice Conversion using Activation ...
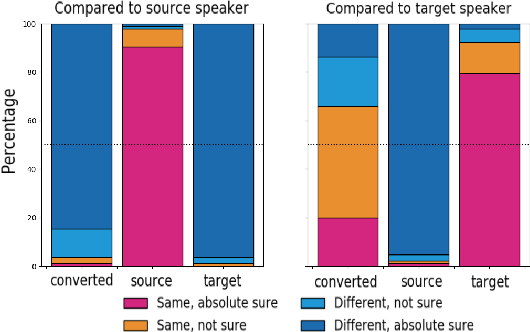
Figure 6 from One-shot Voice Conversion by Separating Speaker and ...
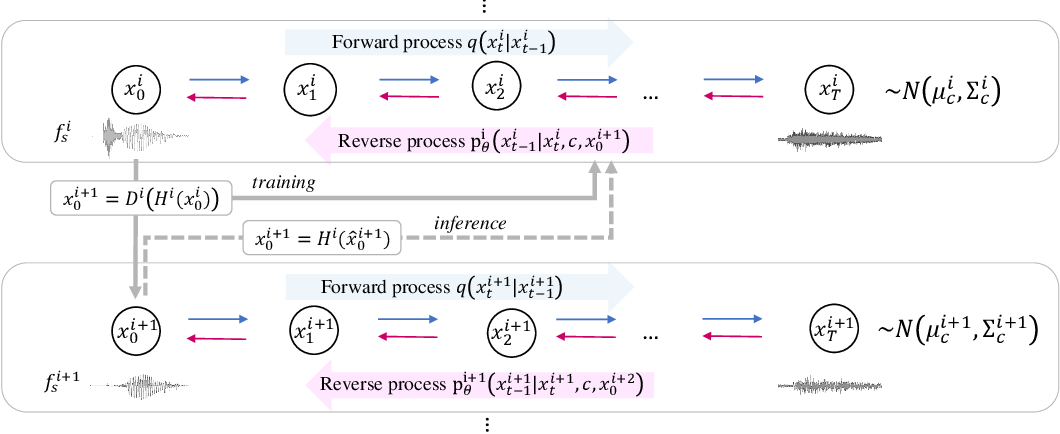
Figure 3 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

(PDF) Phoneme Hallucinator: One-shot Voice Conversion via Set Expansion