
Python Tpu Pallas Kernel Flashattention Deephub

python - TPU 架构与 Pallas Kernel 编程入门:从内存层次结构到 FlashAttention - deephub ...

python - TPU 架构与 Pallas Kernel 编程入门:从内存层次结构到 FlashAttention - deephub ...

python - TPU 架构与 Pallas Kernel 编程入门:从内存层次结构到 FlashAttention - deephub ...
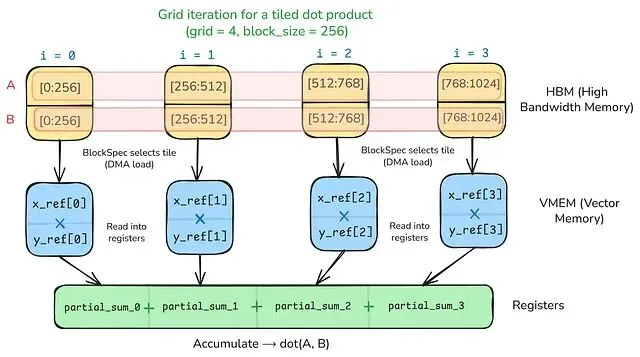
TPU 架构与 Pallas Kernel 编程入门:从内存层次结构到 FlashAttention-阿里云开发者社区

python - JAX 训练加速指南:8 个让 TPU 满跑的工程实战习惯 - deephub - SegmentFault 思否
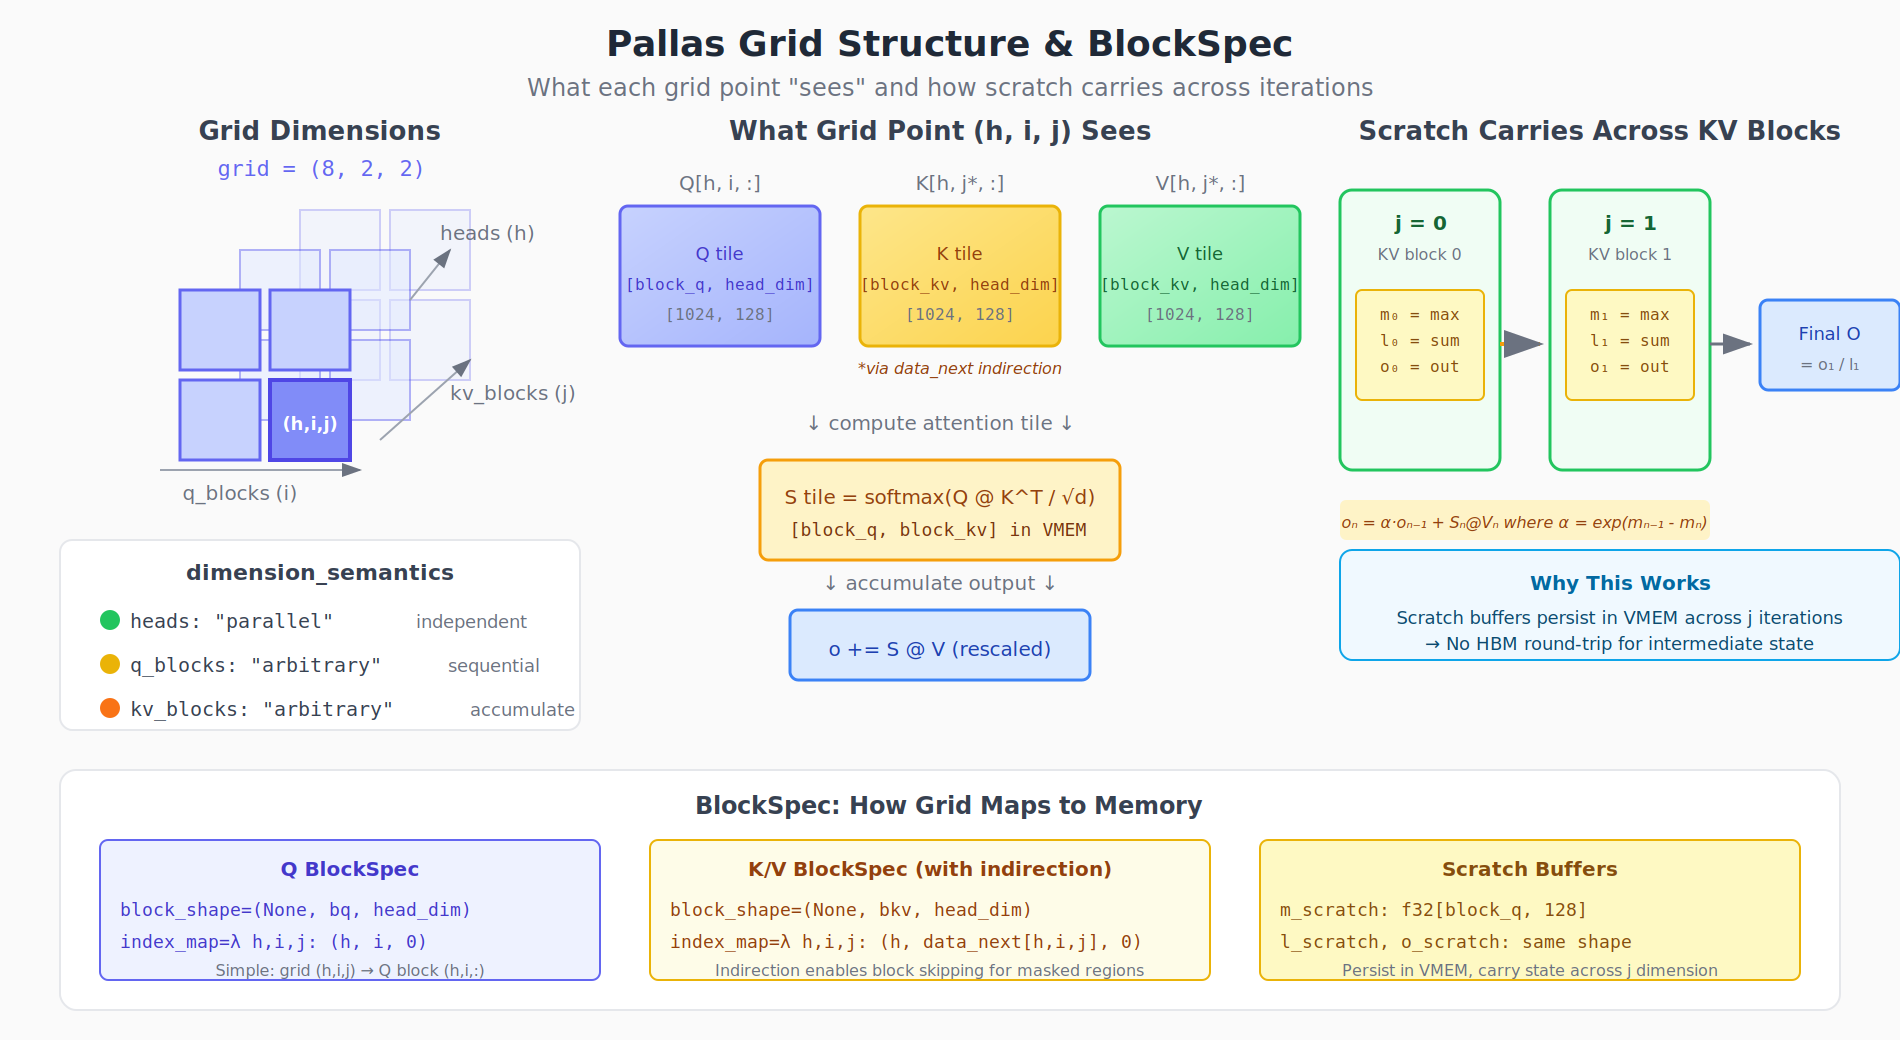
When XLA Isn't Enough: From Pallas to VLIW with Splash Attention on TPU
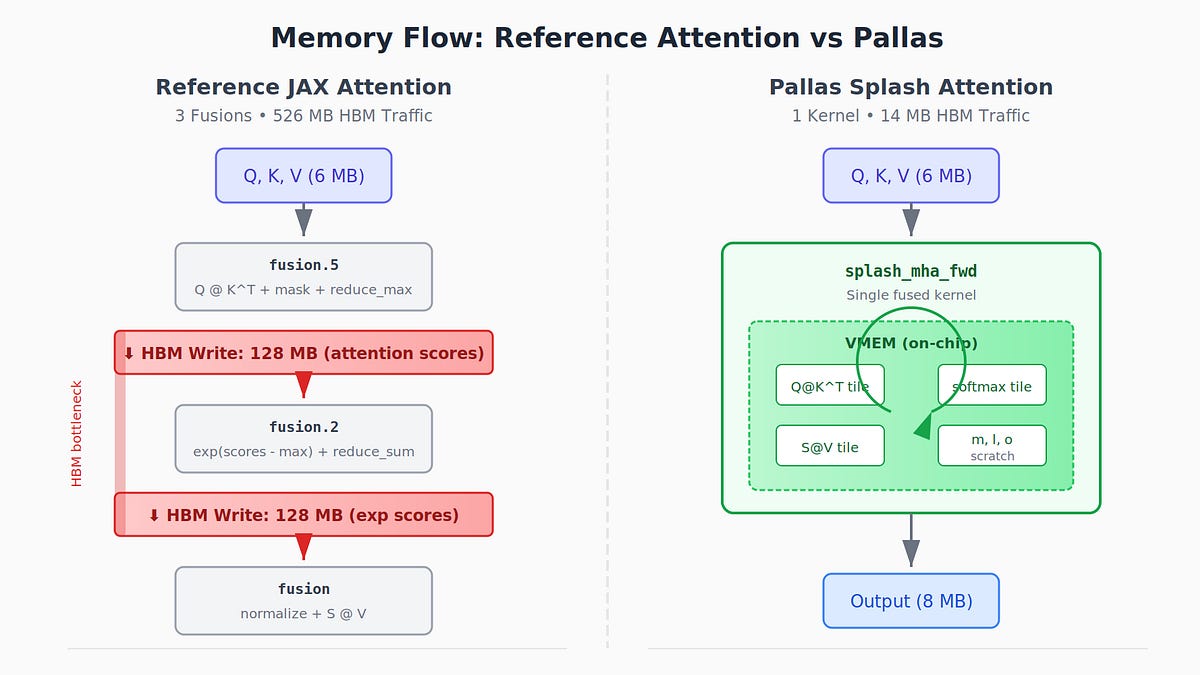
When XLA Isn't Enough: From Pallas to VLIW with Splash Attention on TPU
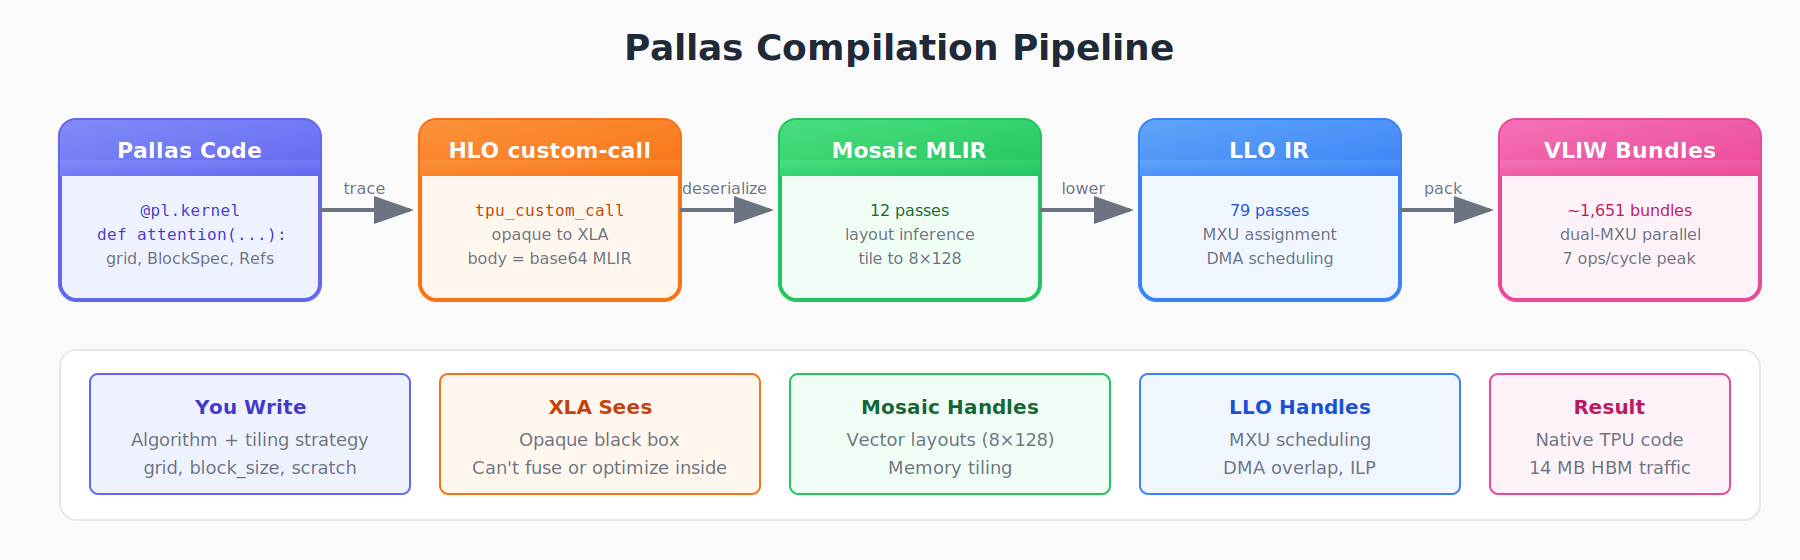
When XLA Isn't Enough: From Pallas to VLIW with Splash Attention on TPU

How to Write a Flash Attention Kernel in Pallas — Vikram's Data Science ...

Writing TPU kernels with Pallas — JAX documentation
Advertisement Space (300x250)

How to Write a Flash Attention Kernel in Pallas — Vikram's Data Science ...

Unlocking TPU Performance with Custom MatMul Kernels using JAX Pallas ...
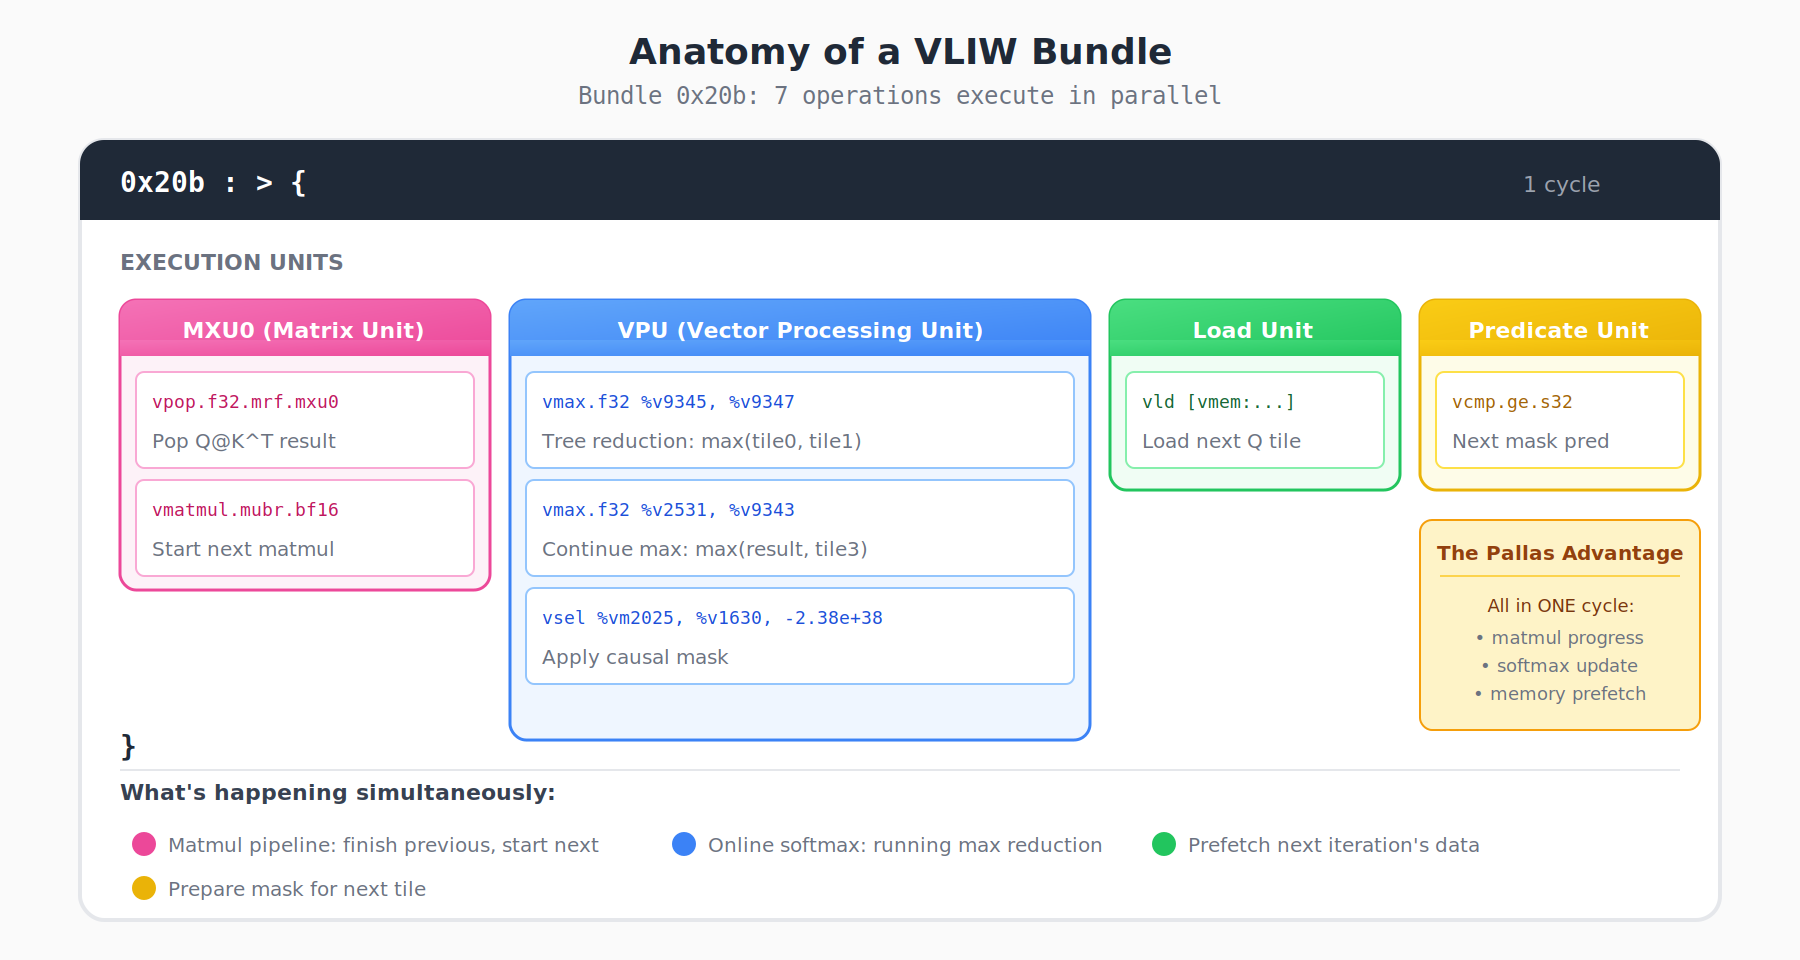
When XLA Isn't Enough: From Pallas to VLIW with Splash Attention on TPU
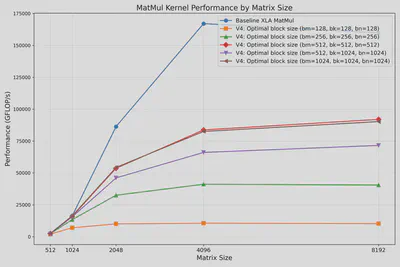
Unlocking TPU Performance with Custom MatMul Kernels using JAX Pallas ...

How to Write a Flash Attention Kernel in Pallas — Vikram's Data Science ...
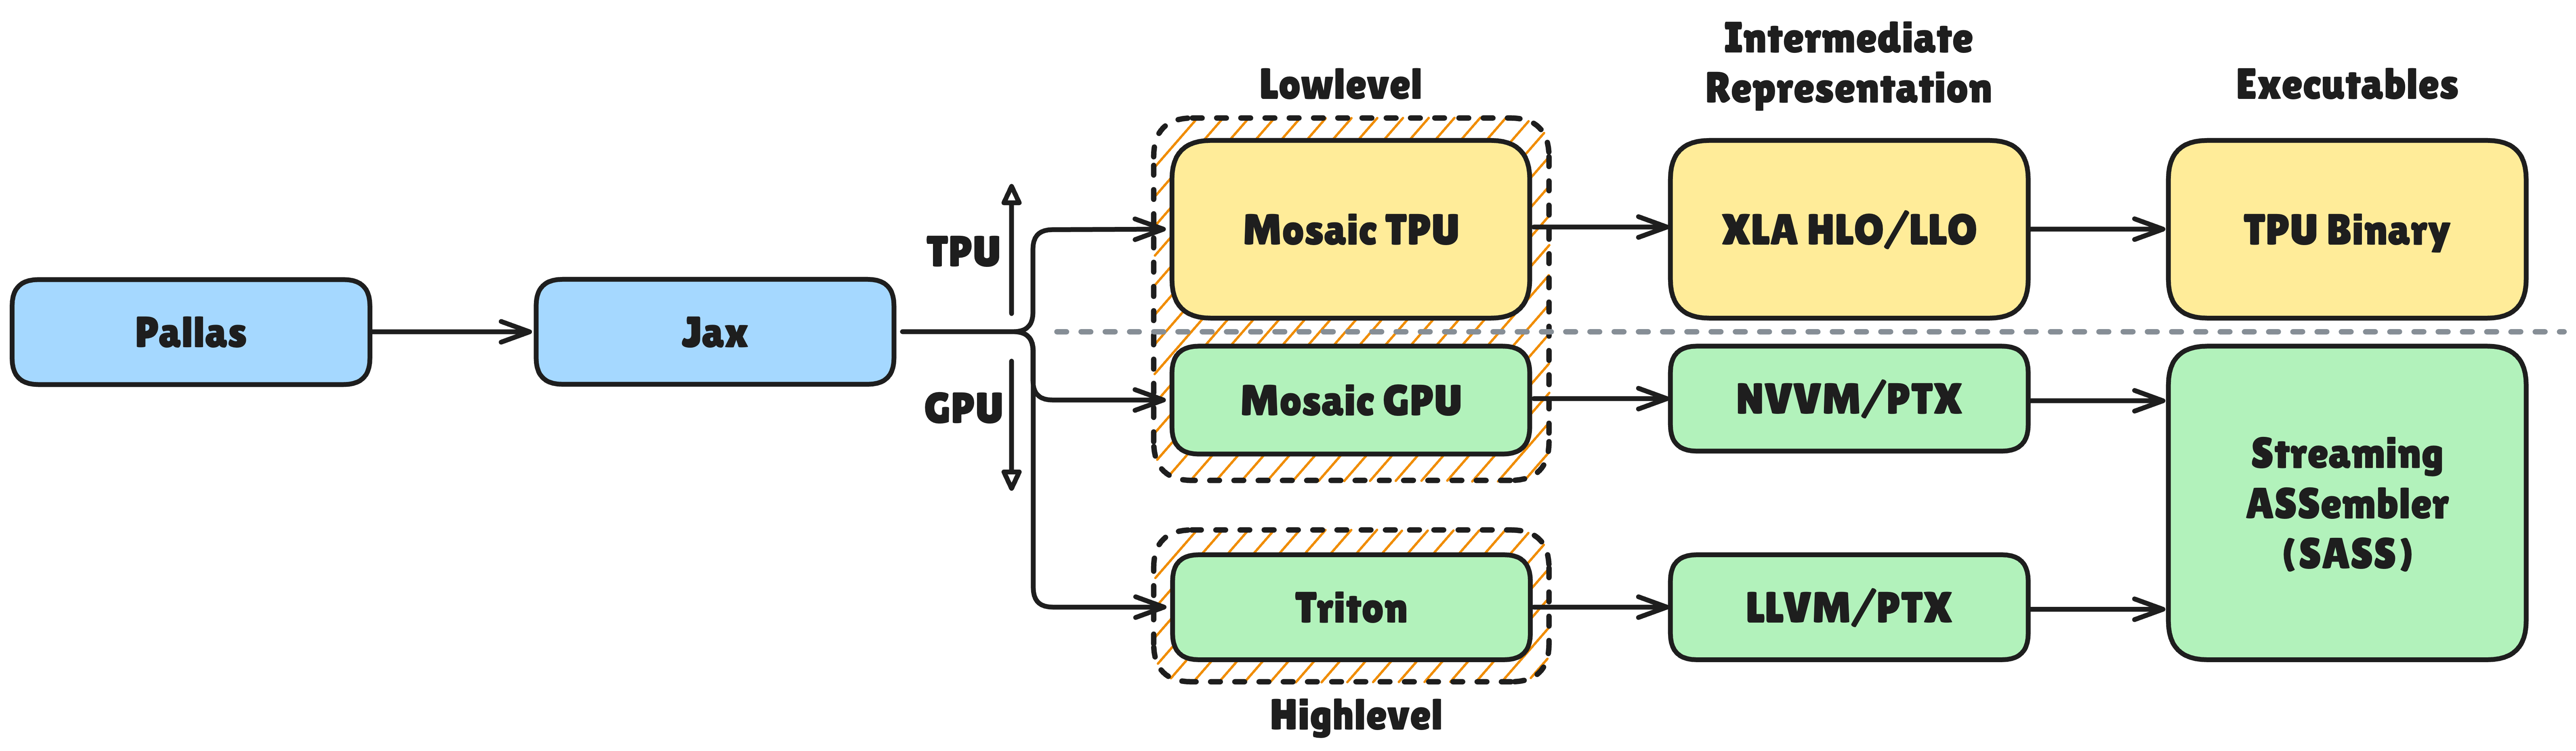
Know Your Enemy, Know Yourself, Supplement: Pallas Programming Model ...
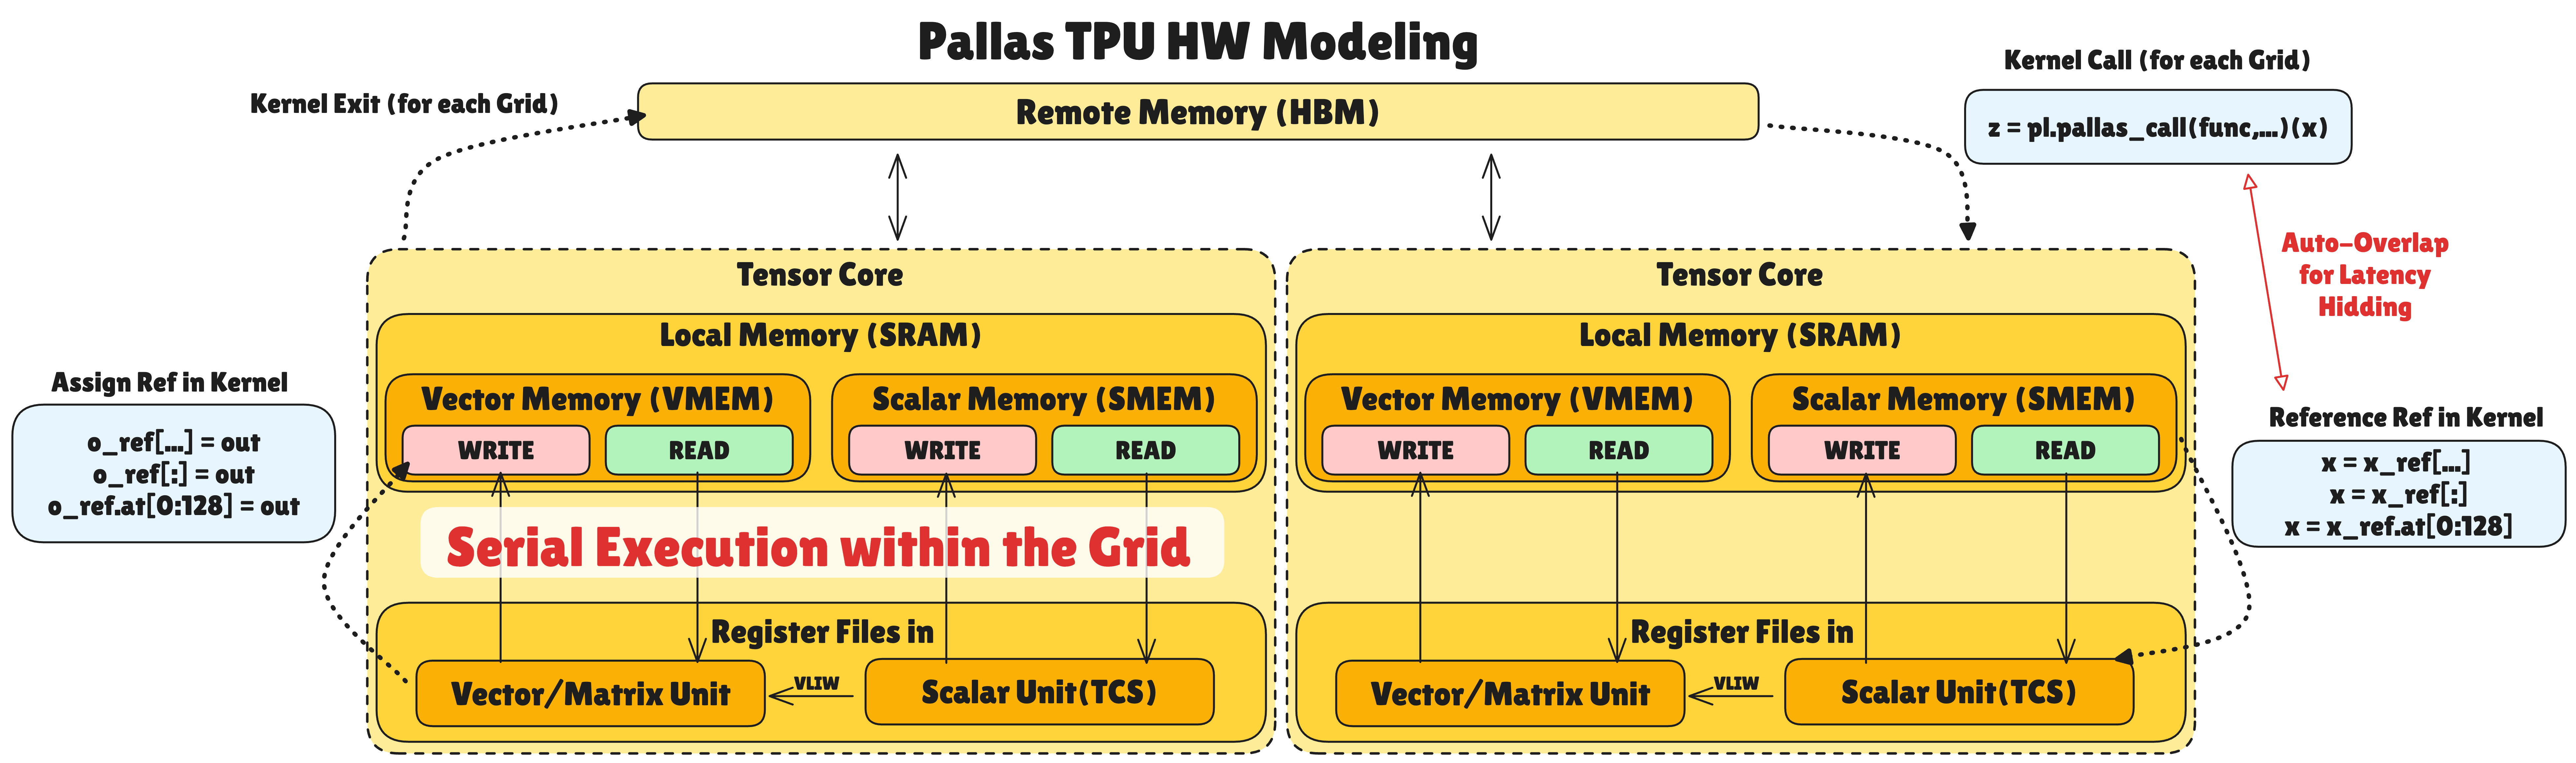
Know Your Enemy, Know Yourself, Supplement: Pallas Programming Model ...

An Introduction to Pallas: Writing Fused TPU Kernels in JAX | by Dr ...
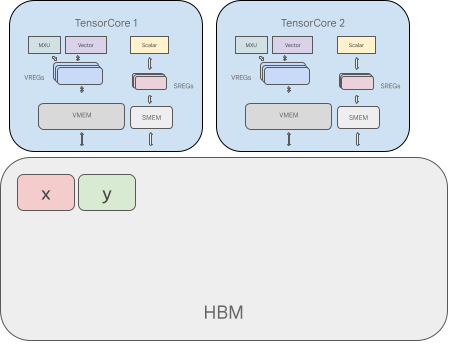
TPU 流水线 · Pengcheng's Blog
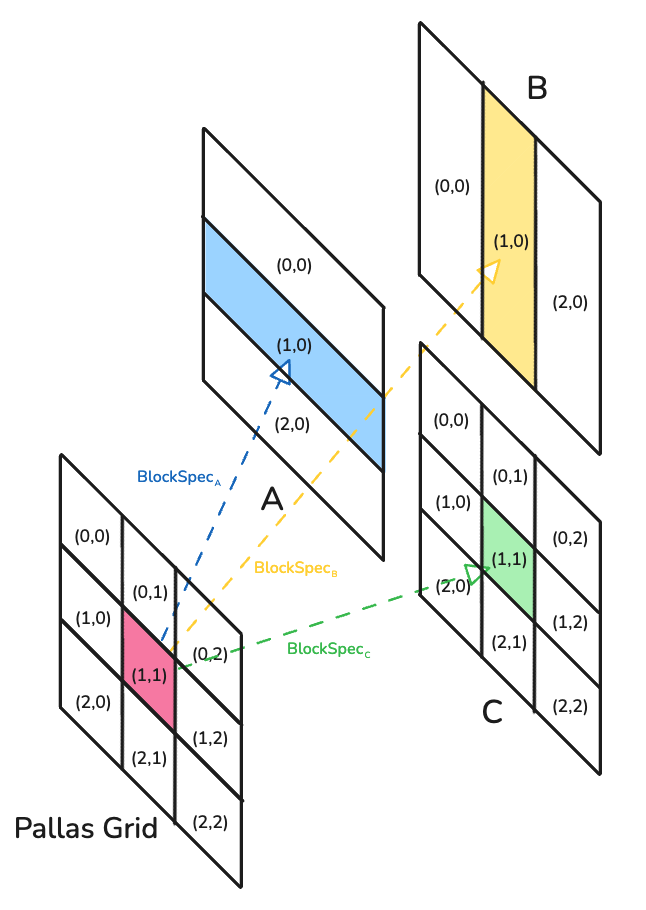
Optimizing NSA for TPUs - Kernel Worklog
Advertisement Space (336x280)
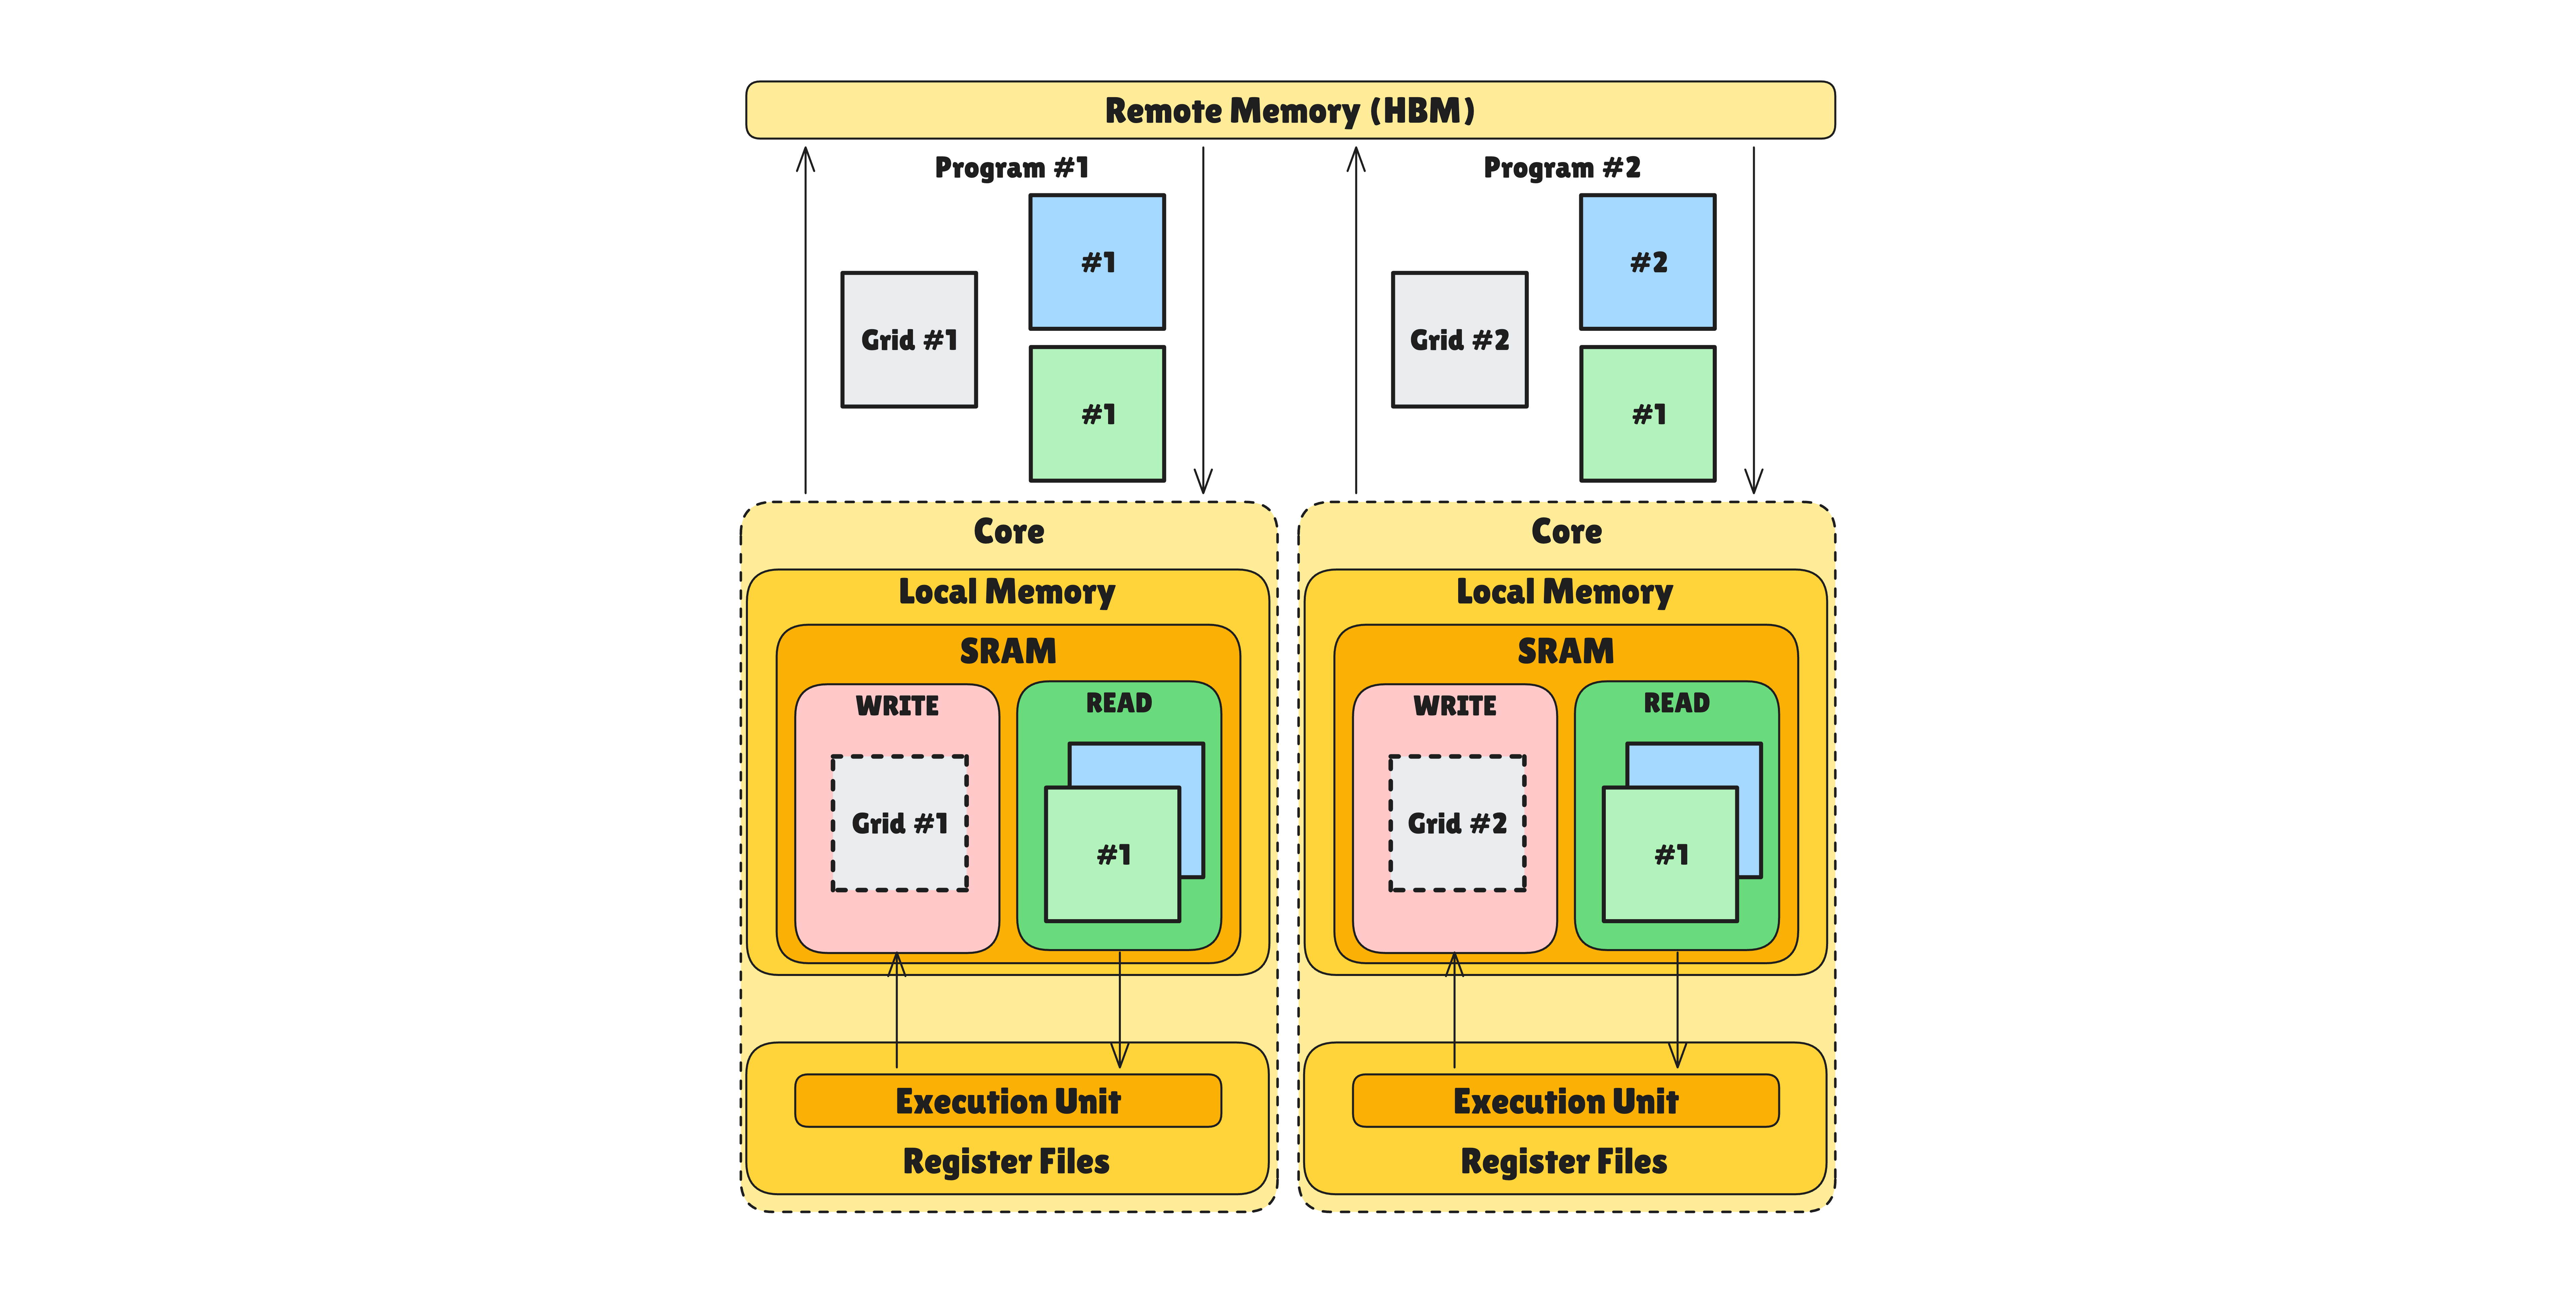
Know Your Enemy, Know Yourself, Supplement: Pallas Programming Model ...
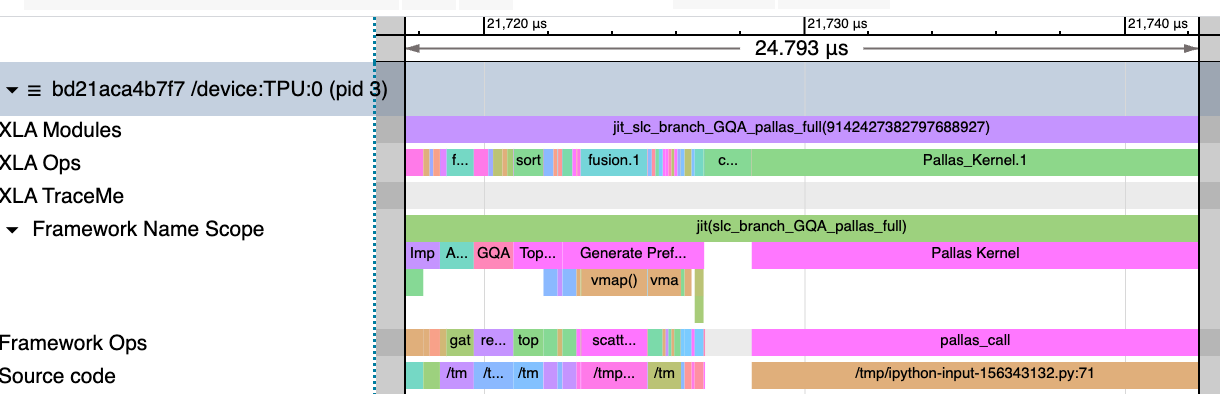
Optimizing NSA for TPUs - Kernel Worklog
Custom Kernels and Pallas Integration | pytorch/xla | DeepWiki
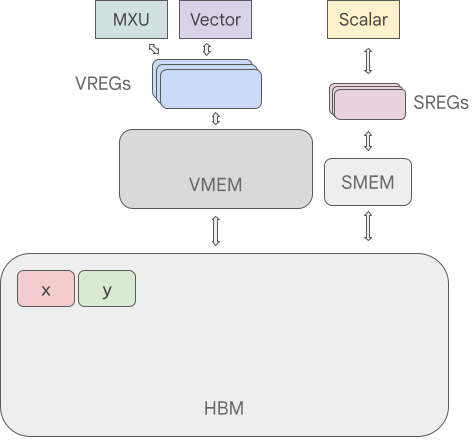
TPU 流水线 · Pengcheng's Blog
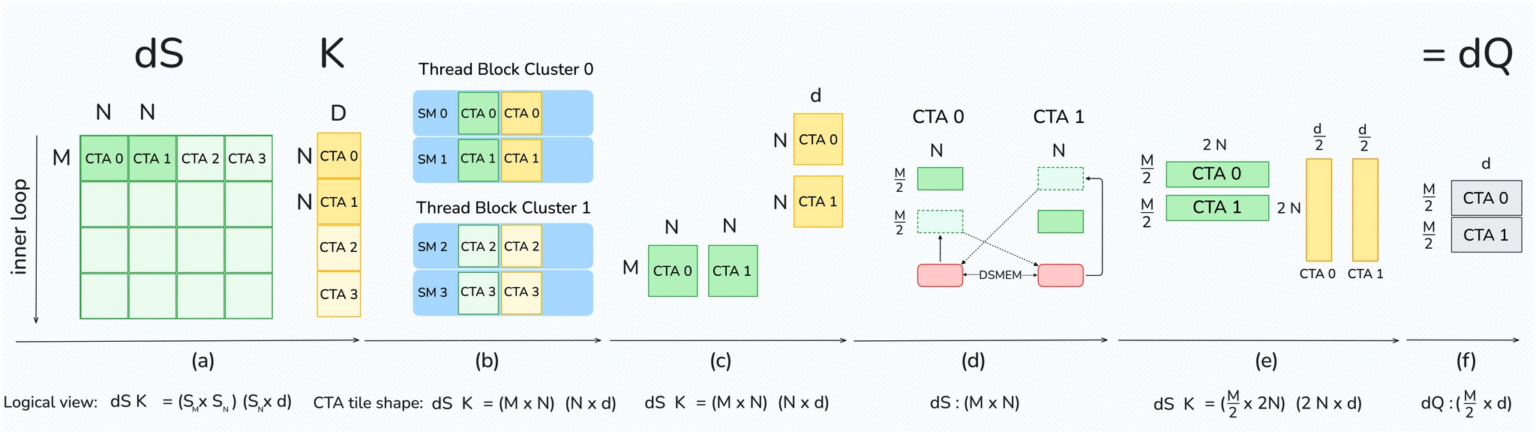
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for ...
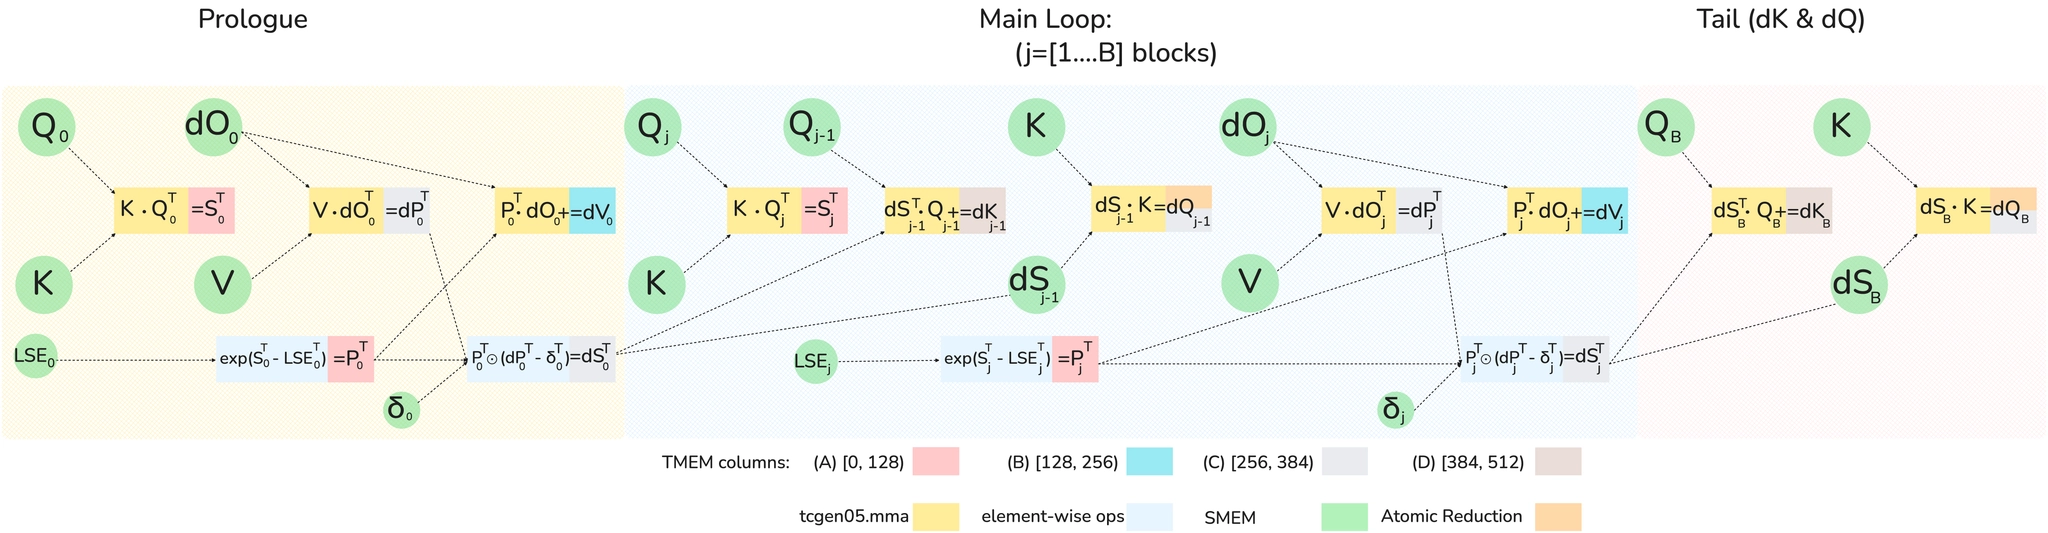
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for ...
Pallas Design — Jax Documentation – GIMX
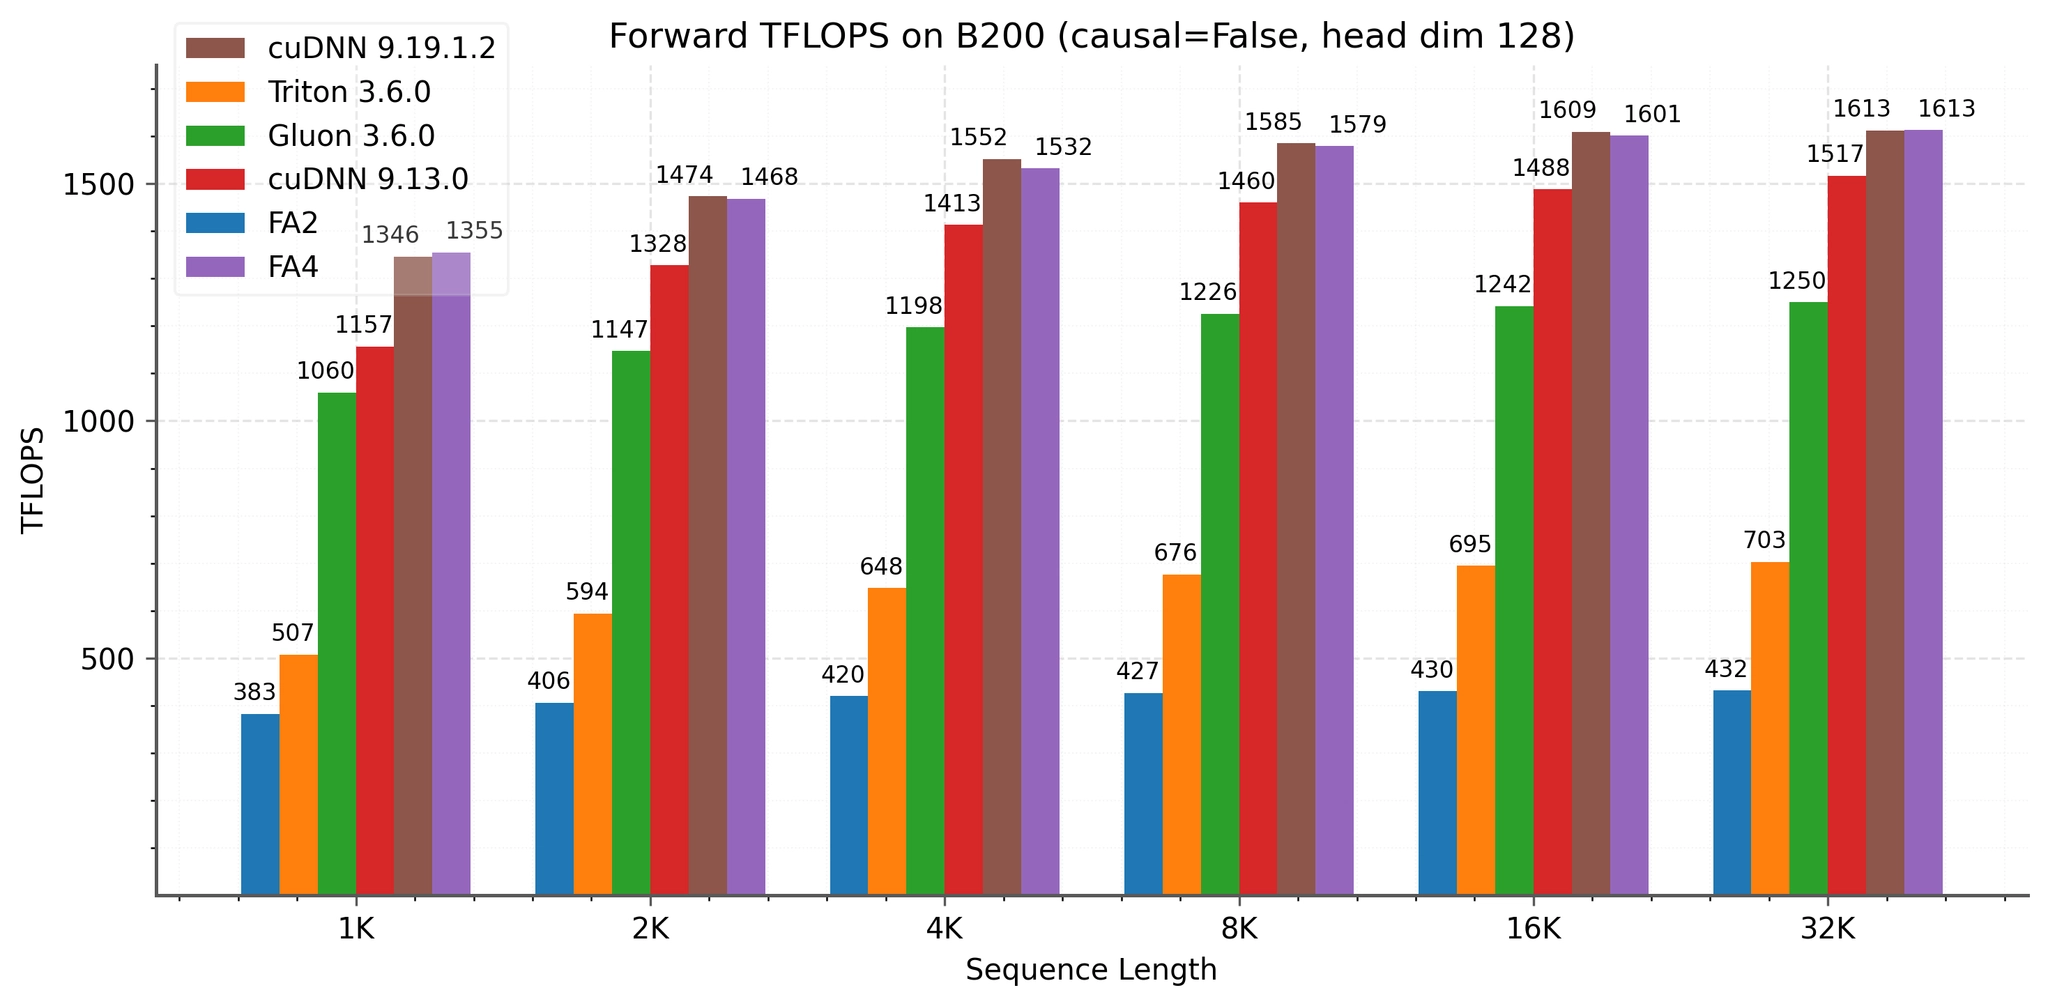
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for ...
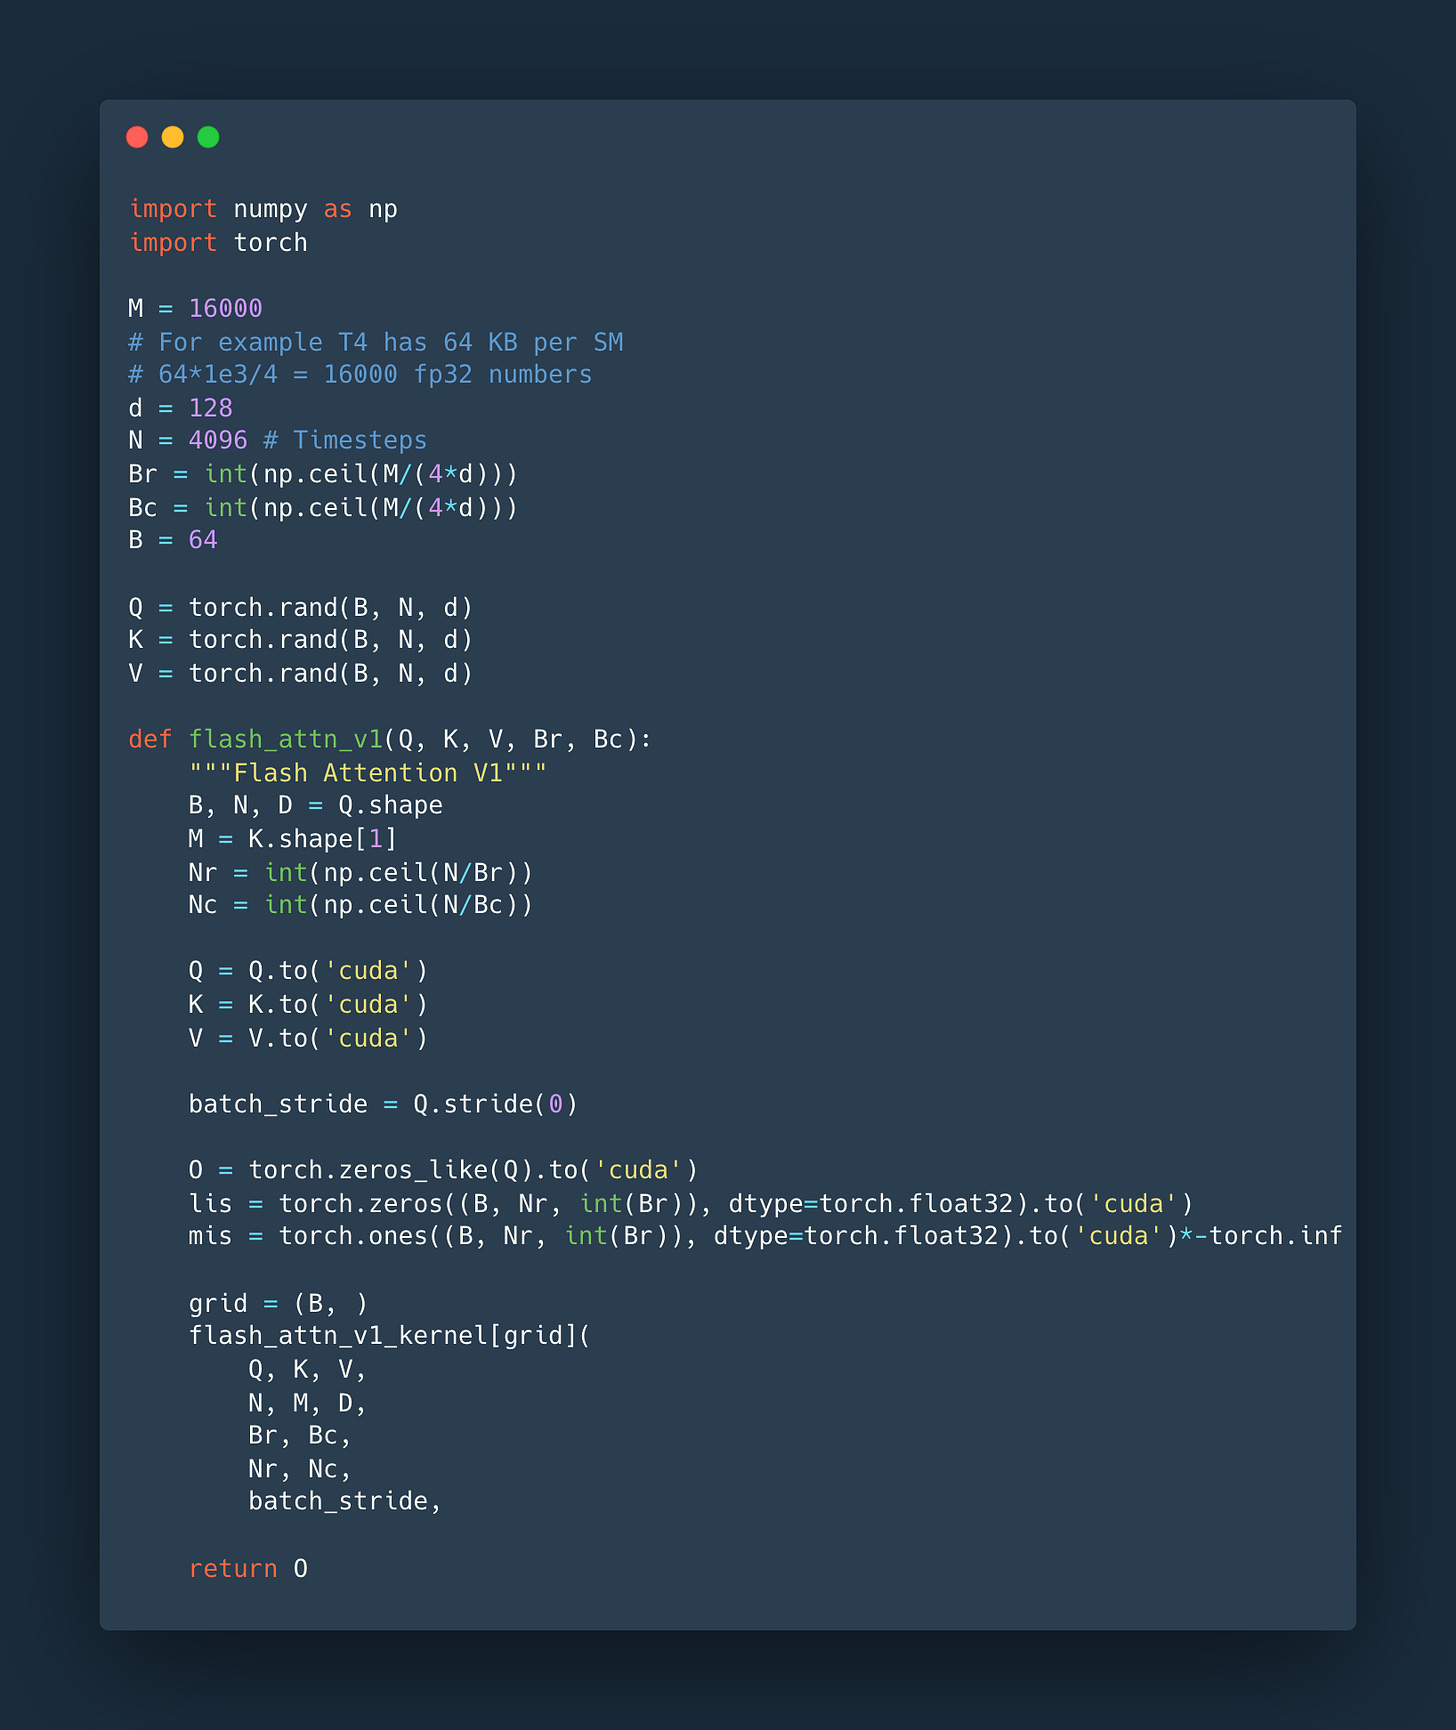
Kernel Case Study: Flash Attention - by Arunjith
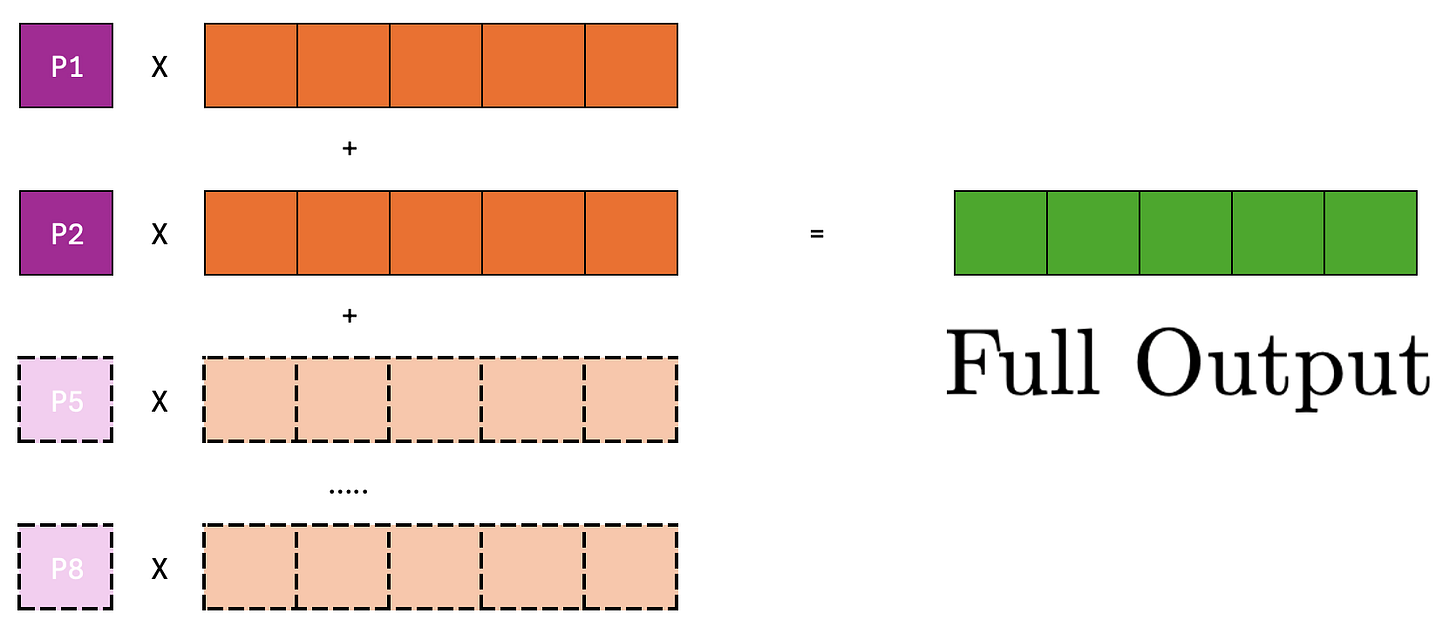
Kernel Case Study: Flash Attention - by Arunjith
Advertisement Space (336x280)
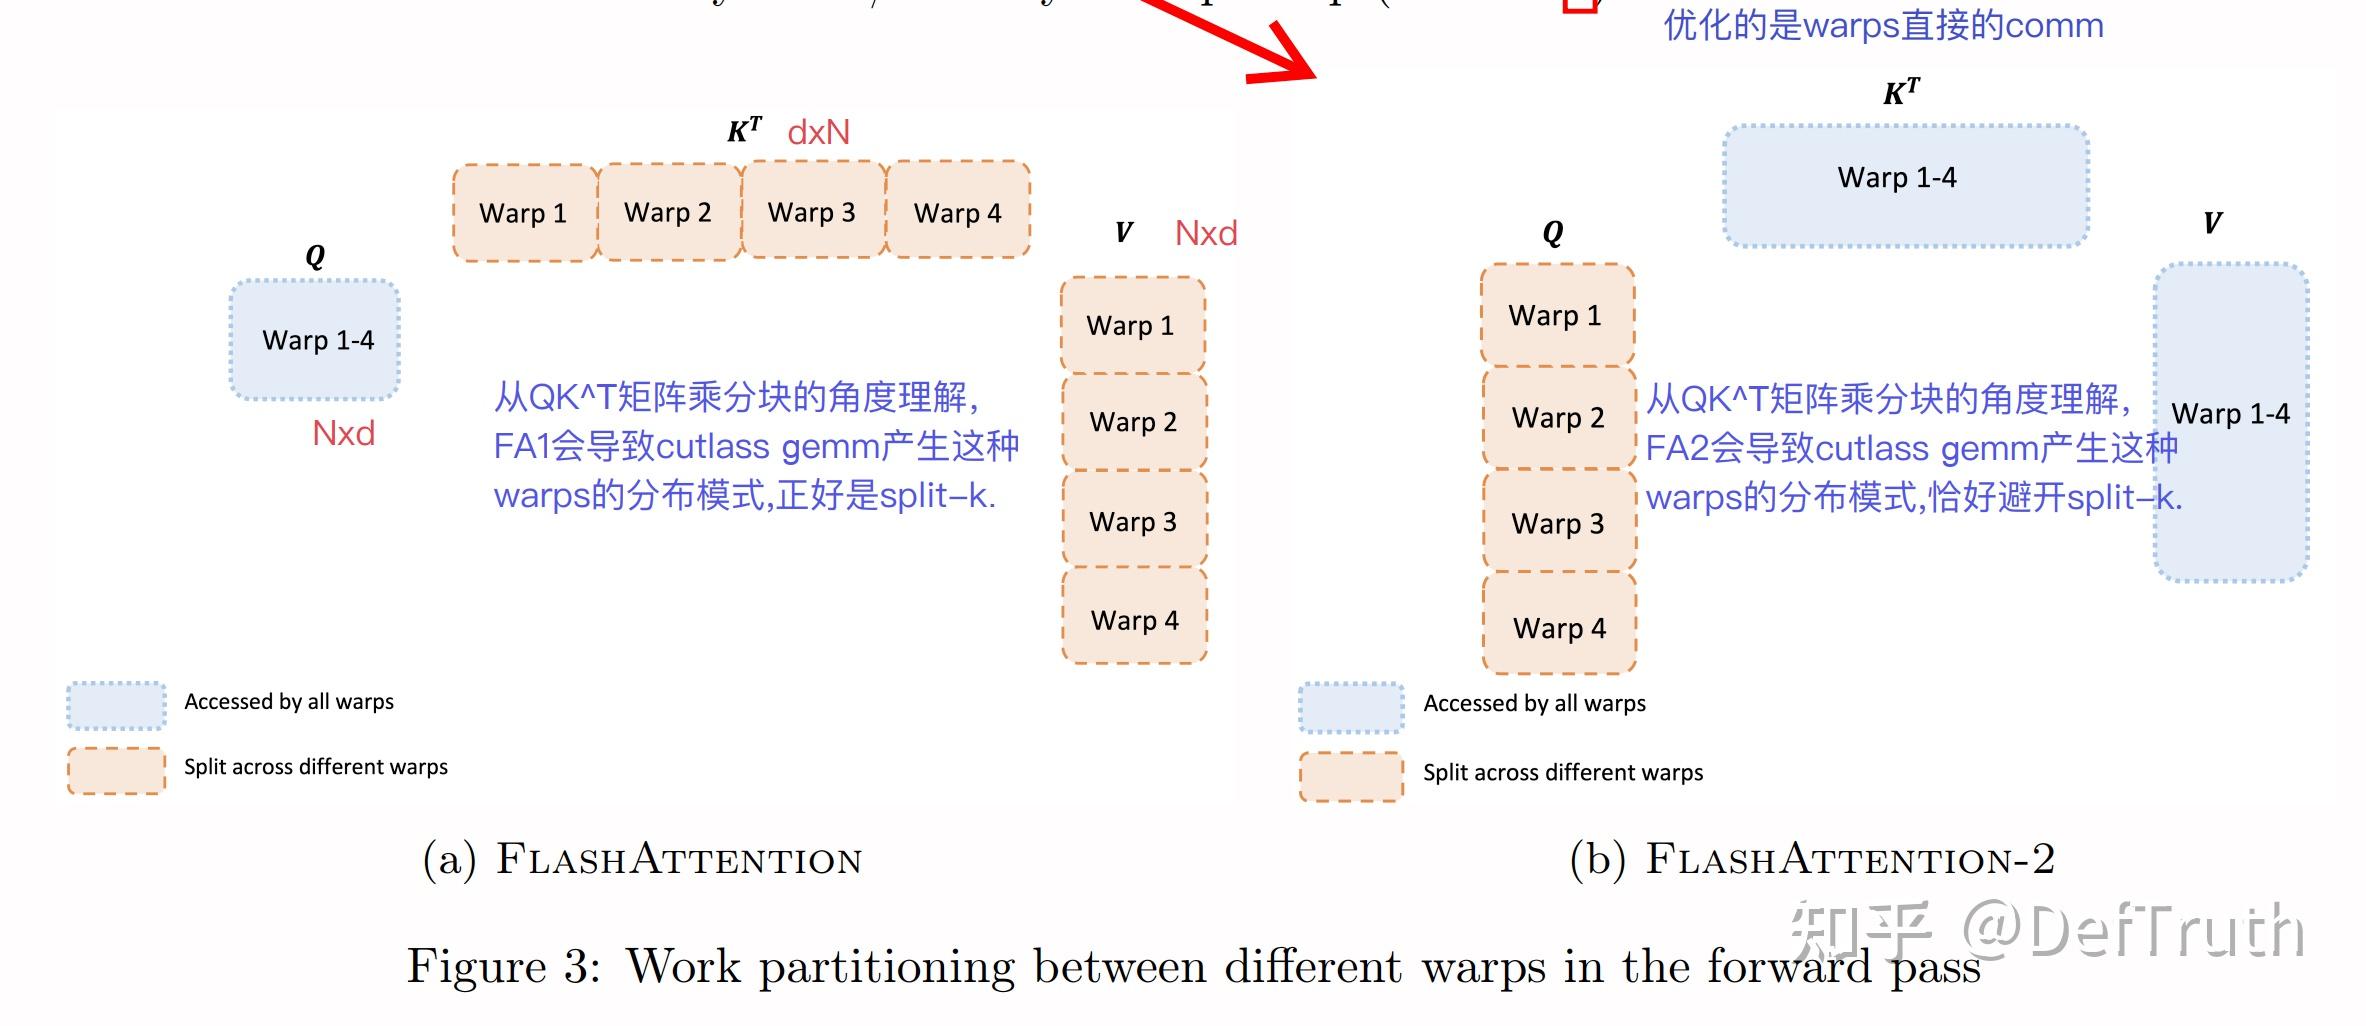
FlashAttention 的速度优化原理是怎样的? - 知乎
Optimized Kernel Library | vllm-project/tpu-inference | DeepWiki
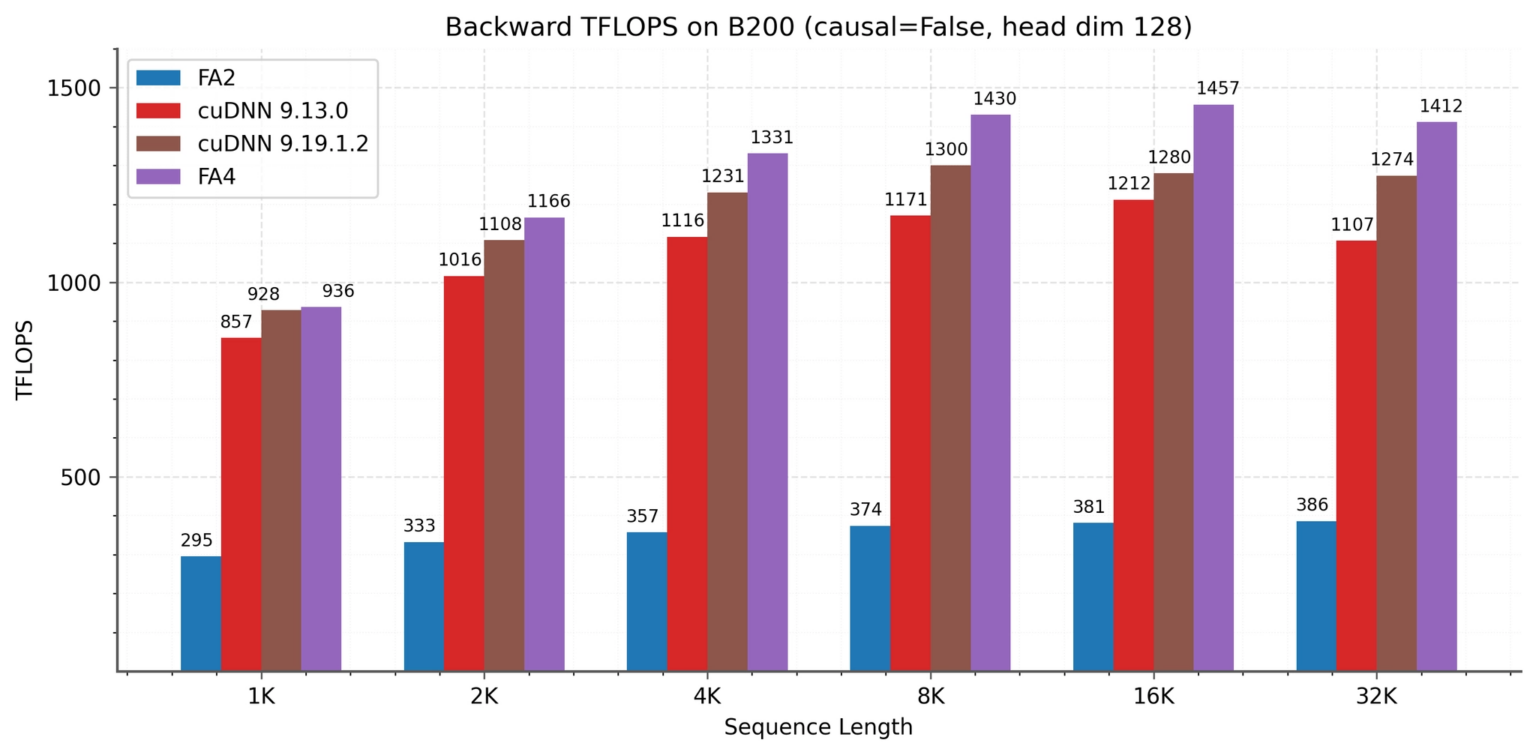
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for ...
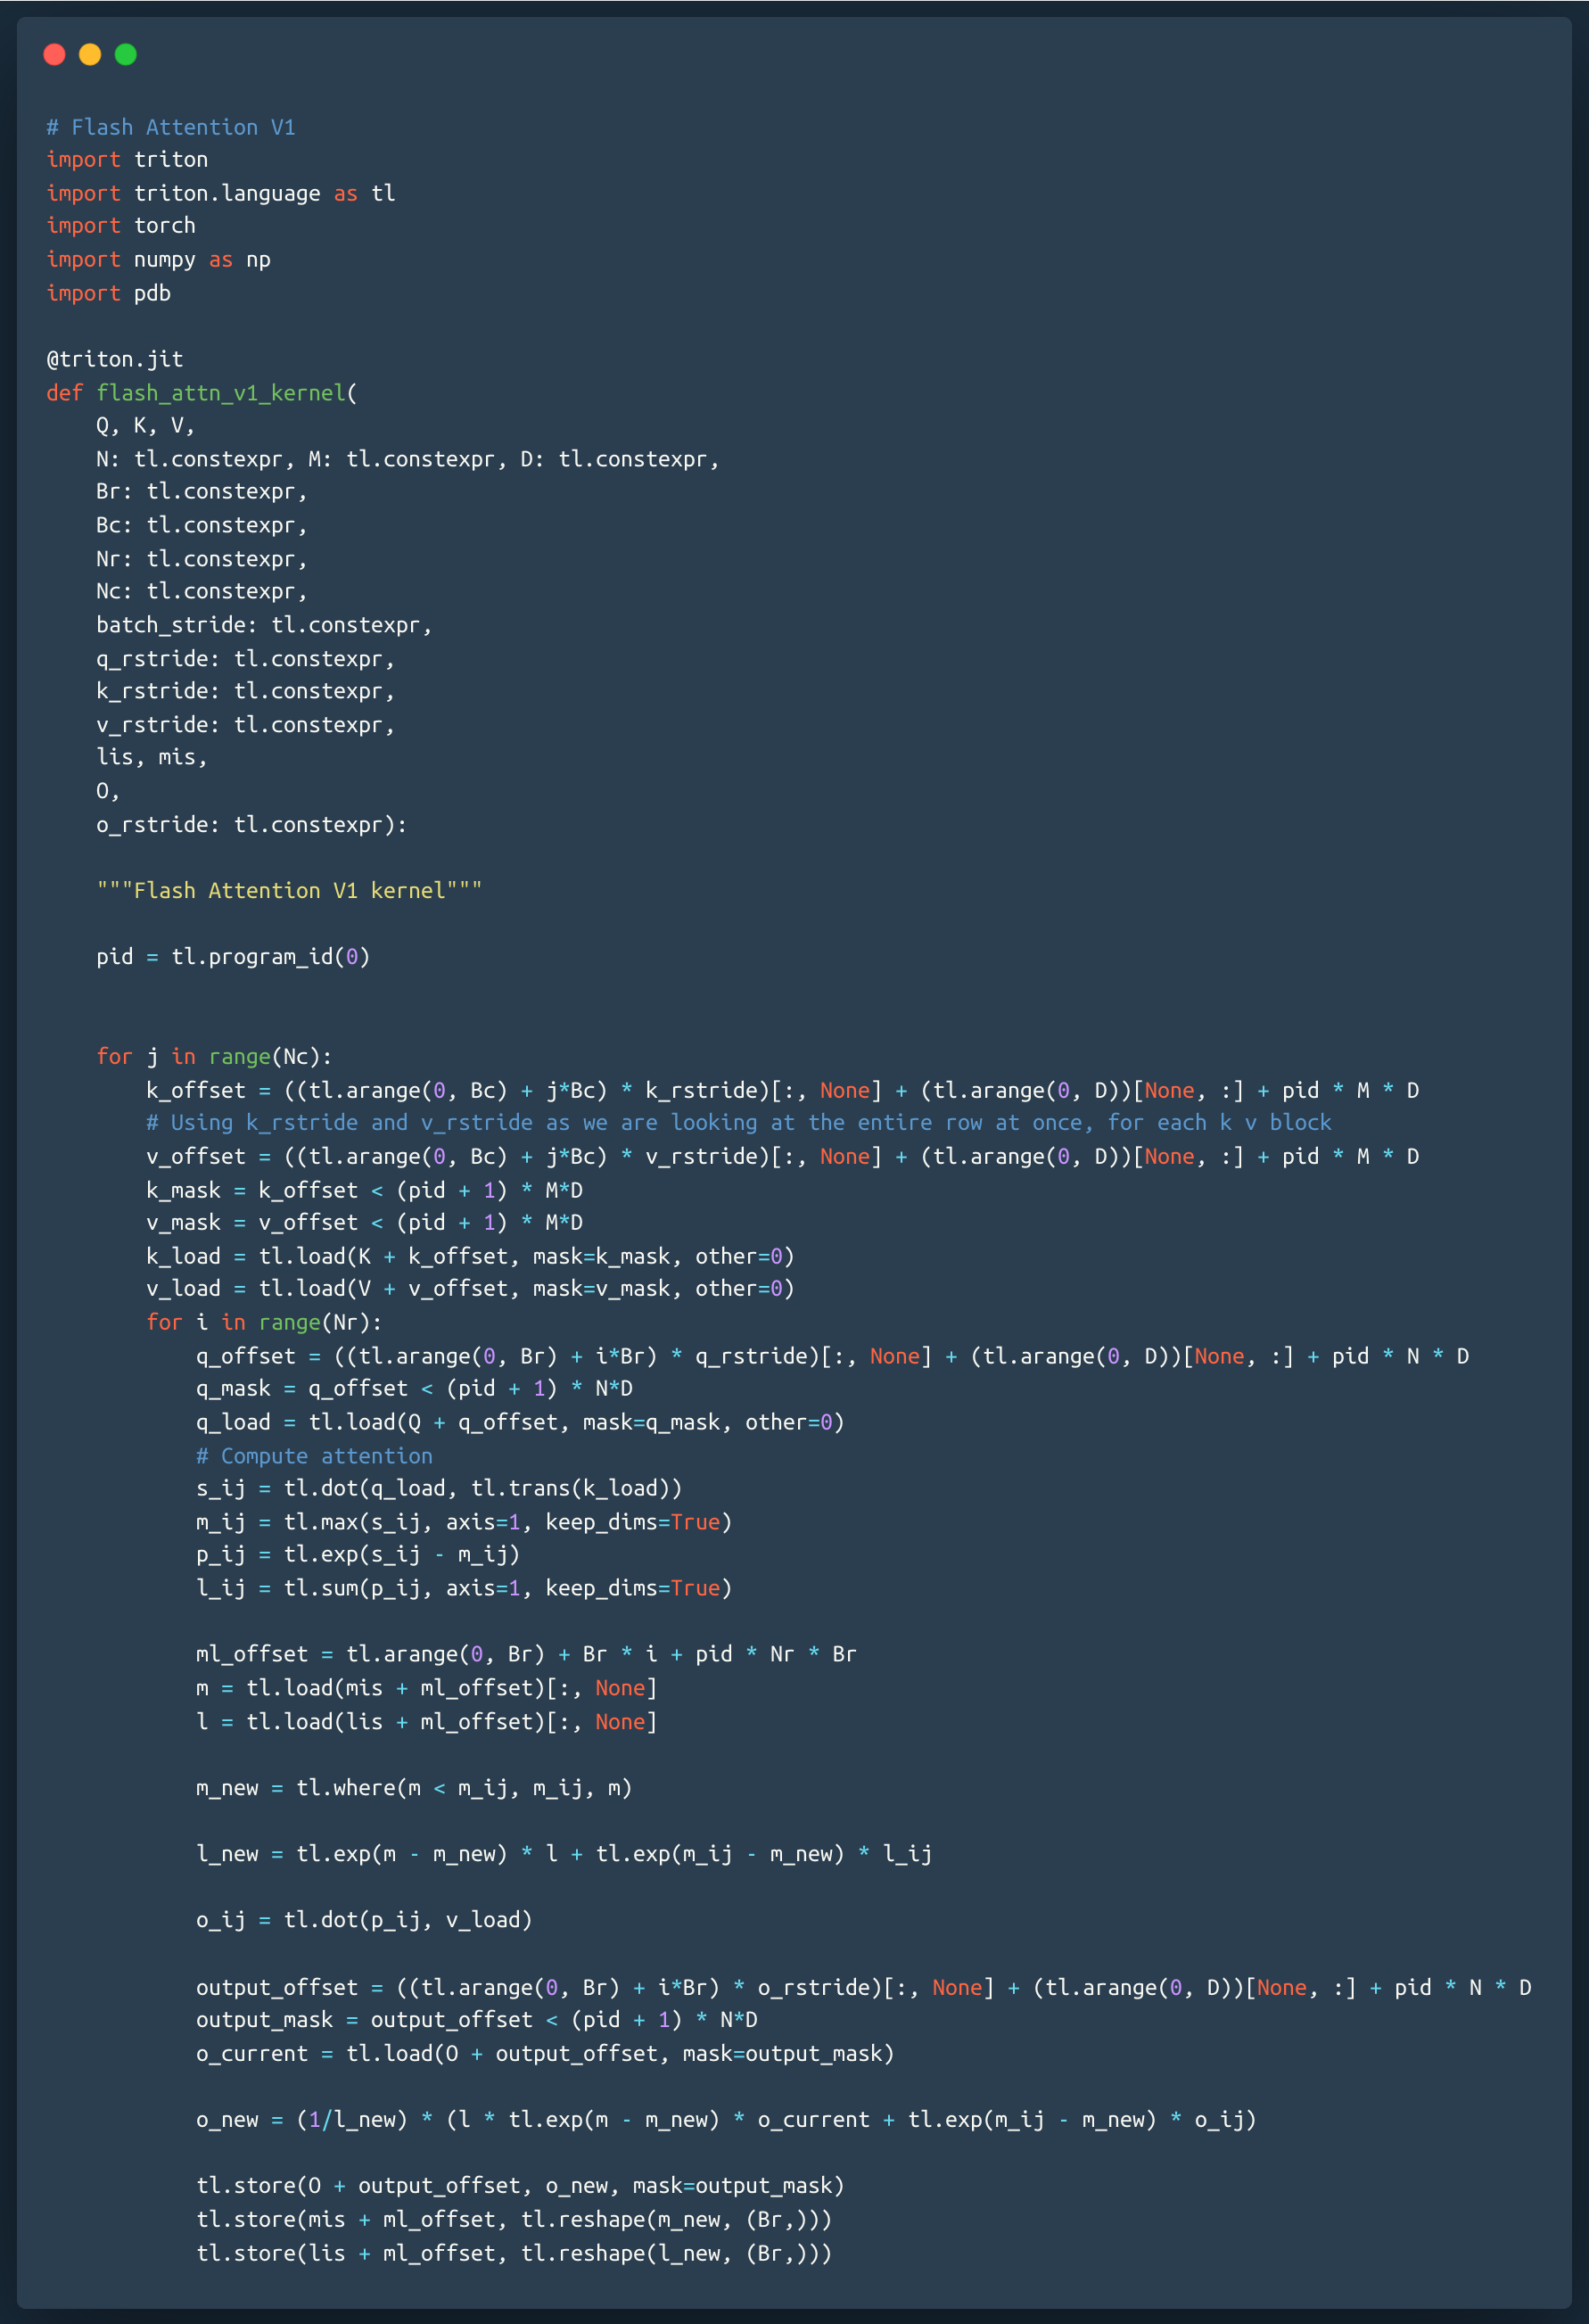
Kernel Case Study: Flash Attention - by Arunjith
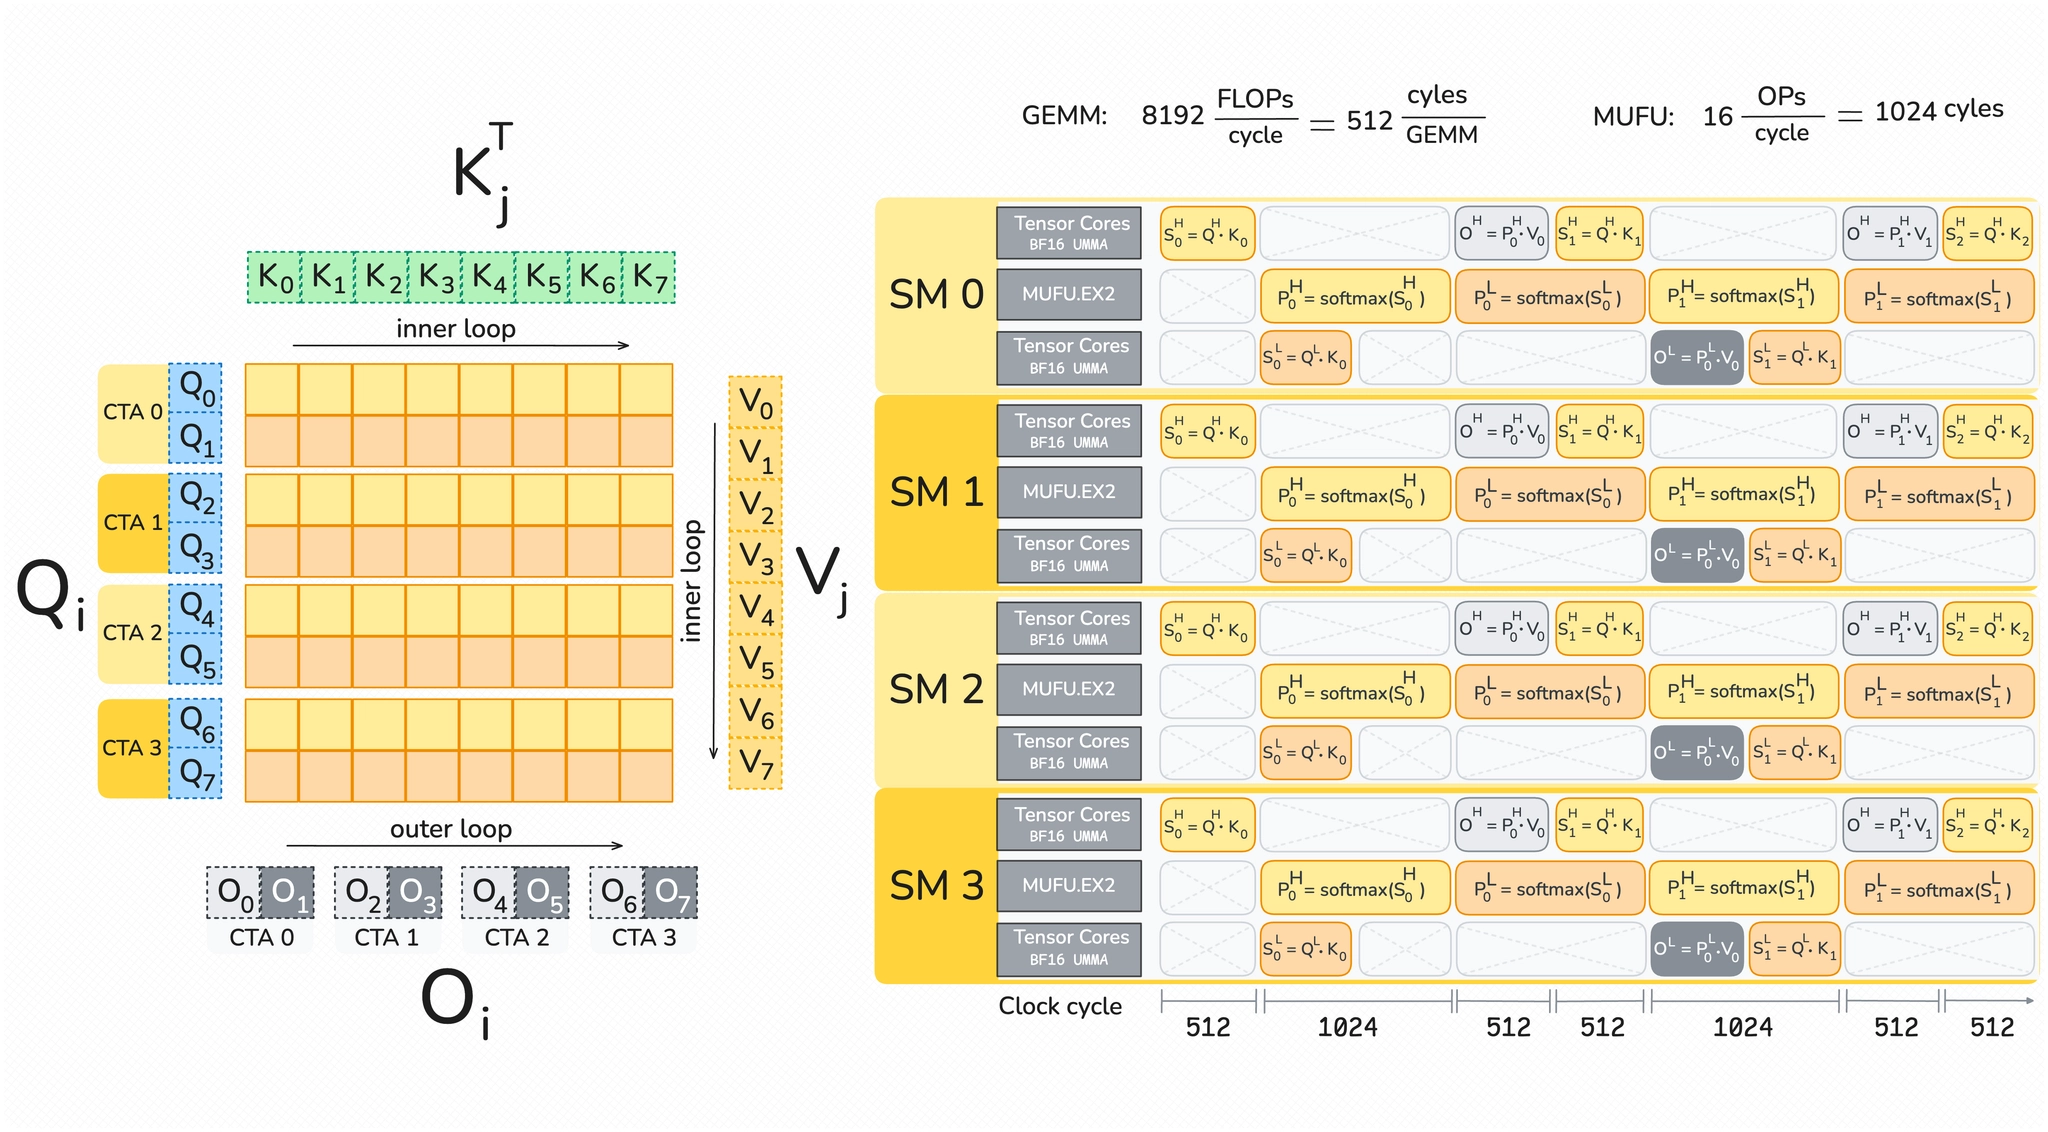
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for ...
Kernel Case Study: Flash Attention - by Arunjith