
Quantization Fp16 Model Using Pytorchquantization And Tensorrt Issue

Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...
Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...
TensorRT Explicit Quantization and Fallback to FP16 · Issue #4021 ...
INT8 Quantization of dinov2 TensorRT Model is Not Faster than FP16 ...
PyTorch to Torchscript with FP16 Quantization · Issue #9430 ...

TensorRT NOT match result from pytorch quantization · Issue #988 ...
Cannot export models to TensorRT with int8 quantization · Issue #82463 ...
PTQ quantization int8 is slower than fp16 · Issue #1532 · NVIDIA ...
fp16 conversion breaks model · Issue #4175 · NVIDIA/TensorRT · GitHub
Cannot use fp16 model · Issue #2087 · NVIDIA/TensorRT · GitHub
Advertisement Space (300x250)
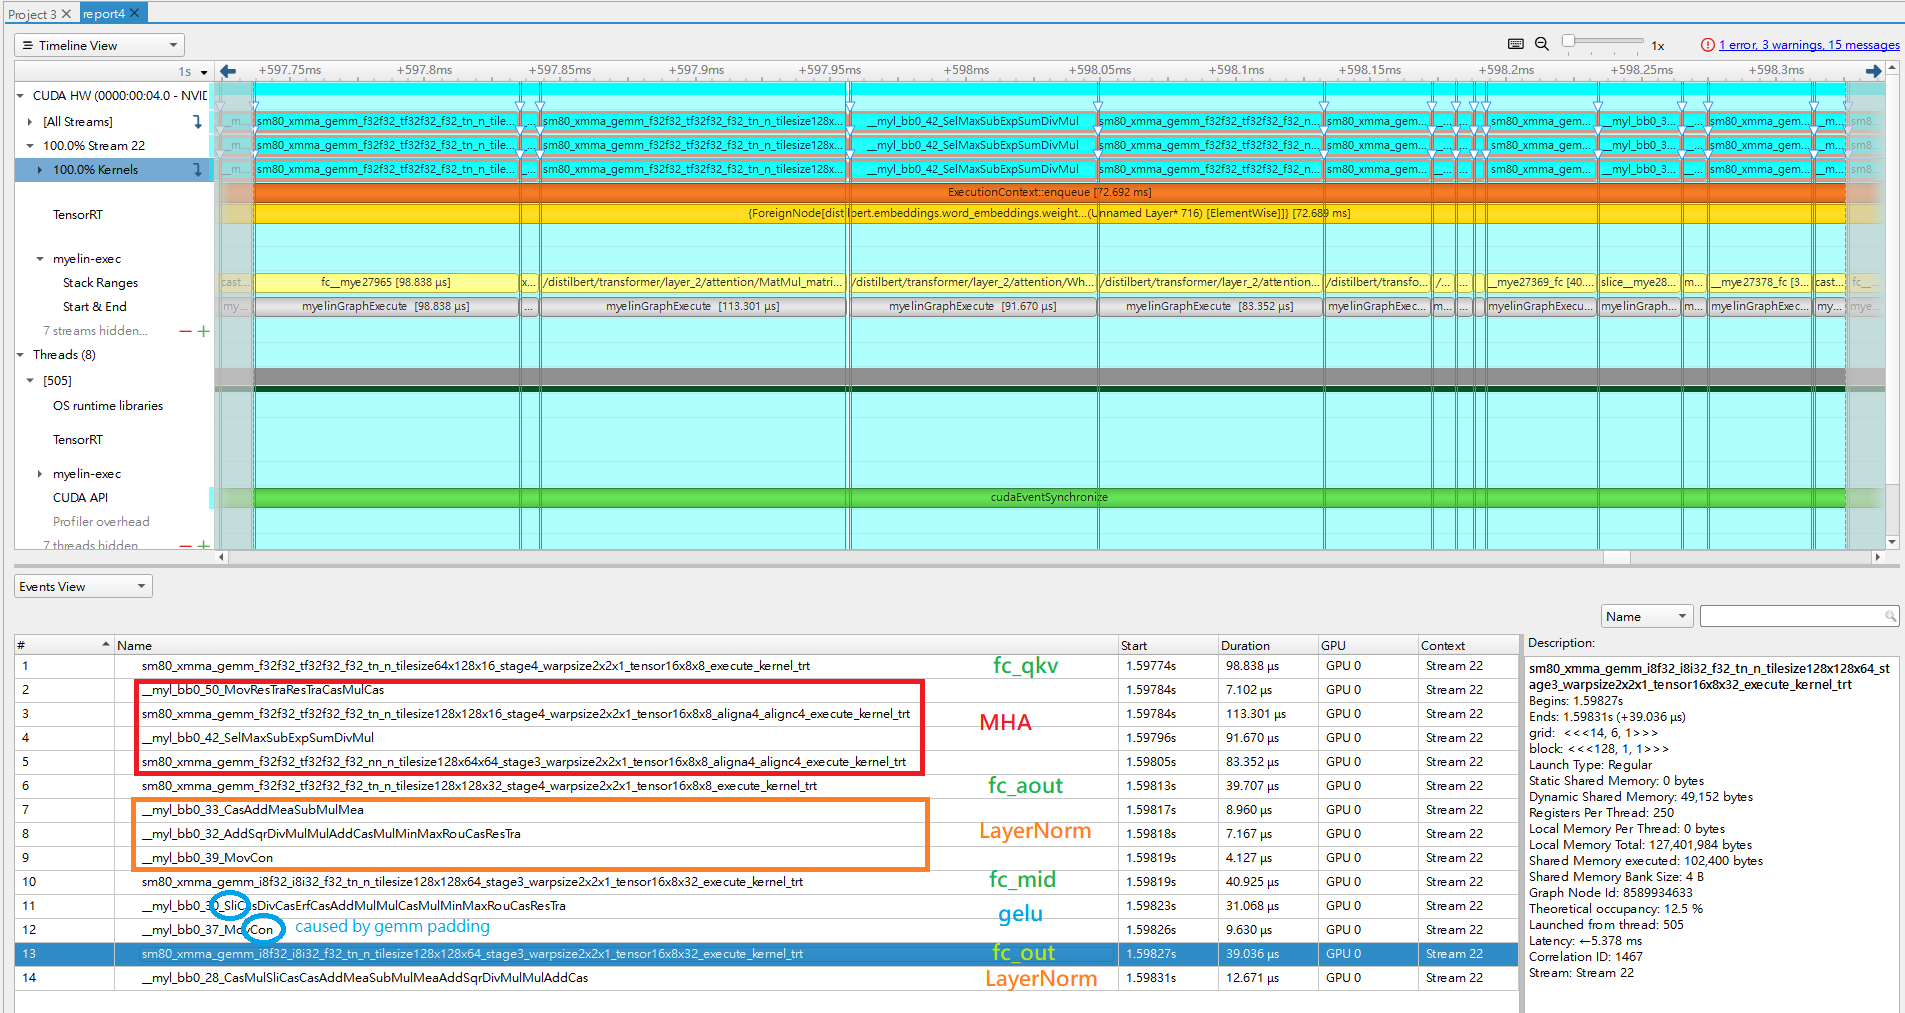
Performance Discrepancy between Quantized ONNX Model and FP16 Model ...
Inference TensorRT model with FP16 in yolov5 with torch.hub.load ...
pytorch fake quantization model parse failed with TensorRT 7.1.3.0 ...

using pytorch_quantization to quantize mmdetection3d model · Issue ...

How am I able to make TensorRT work and quantize the AI model to FP4 ...
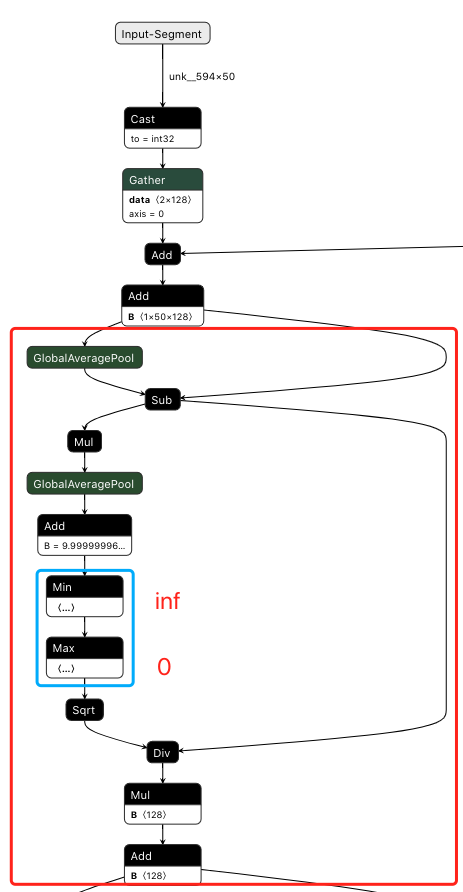
Roberta fp16 got wrong inference results · Issue #2466 · NVIDIA ...

TensorRT quantization Optimization - TensorRT - NVIDIA Developer Forums
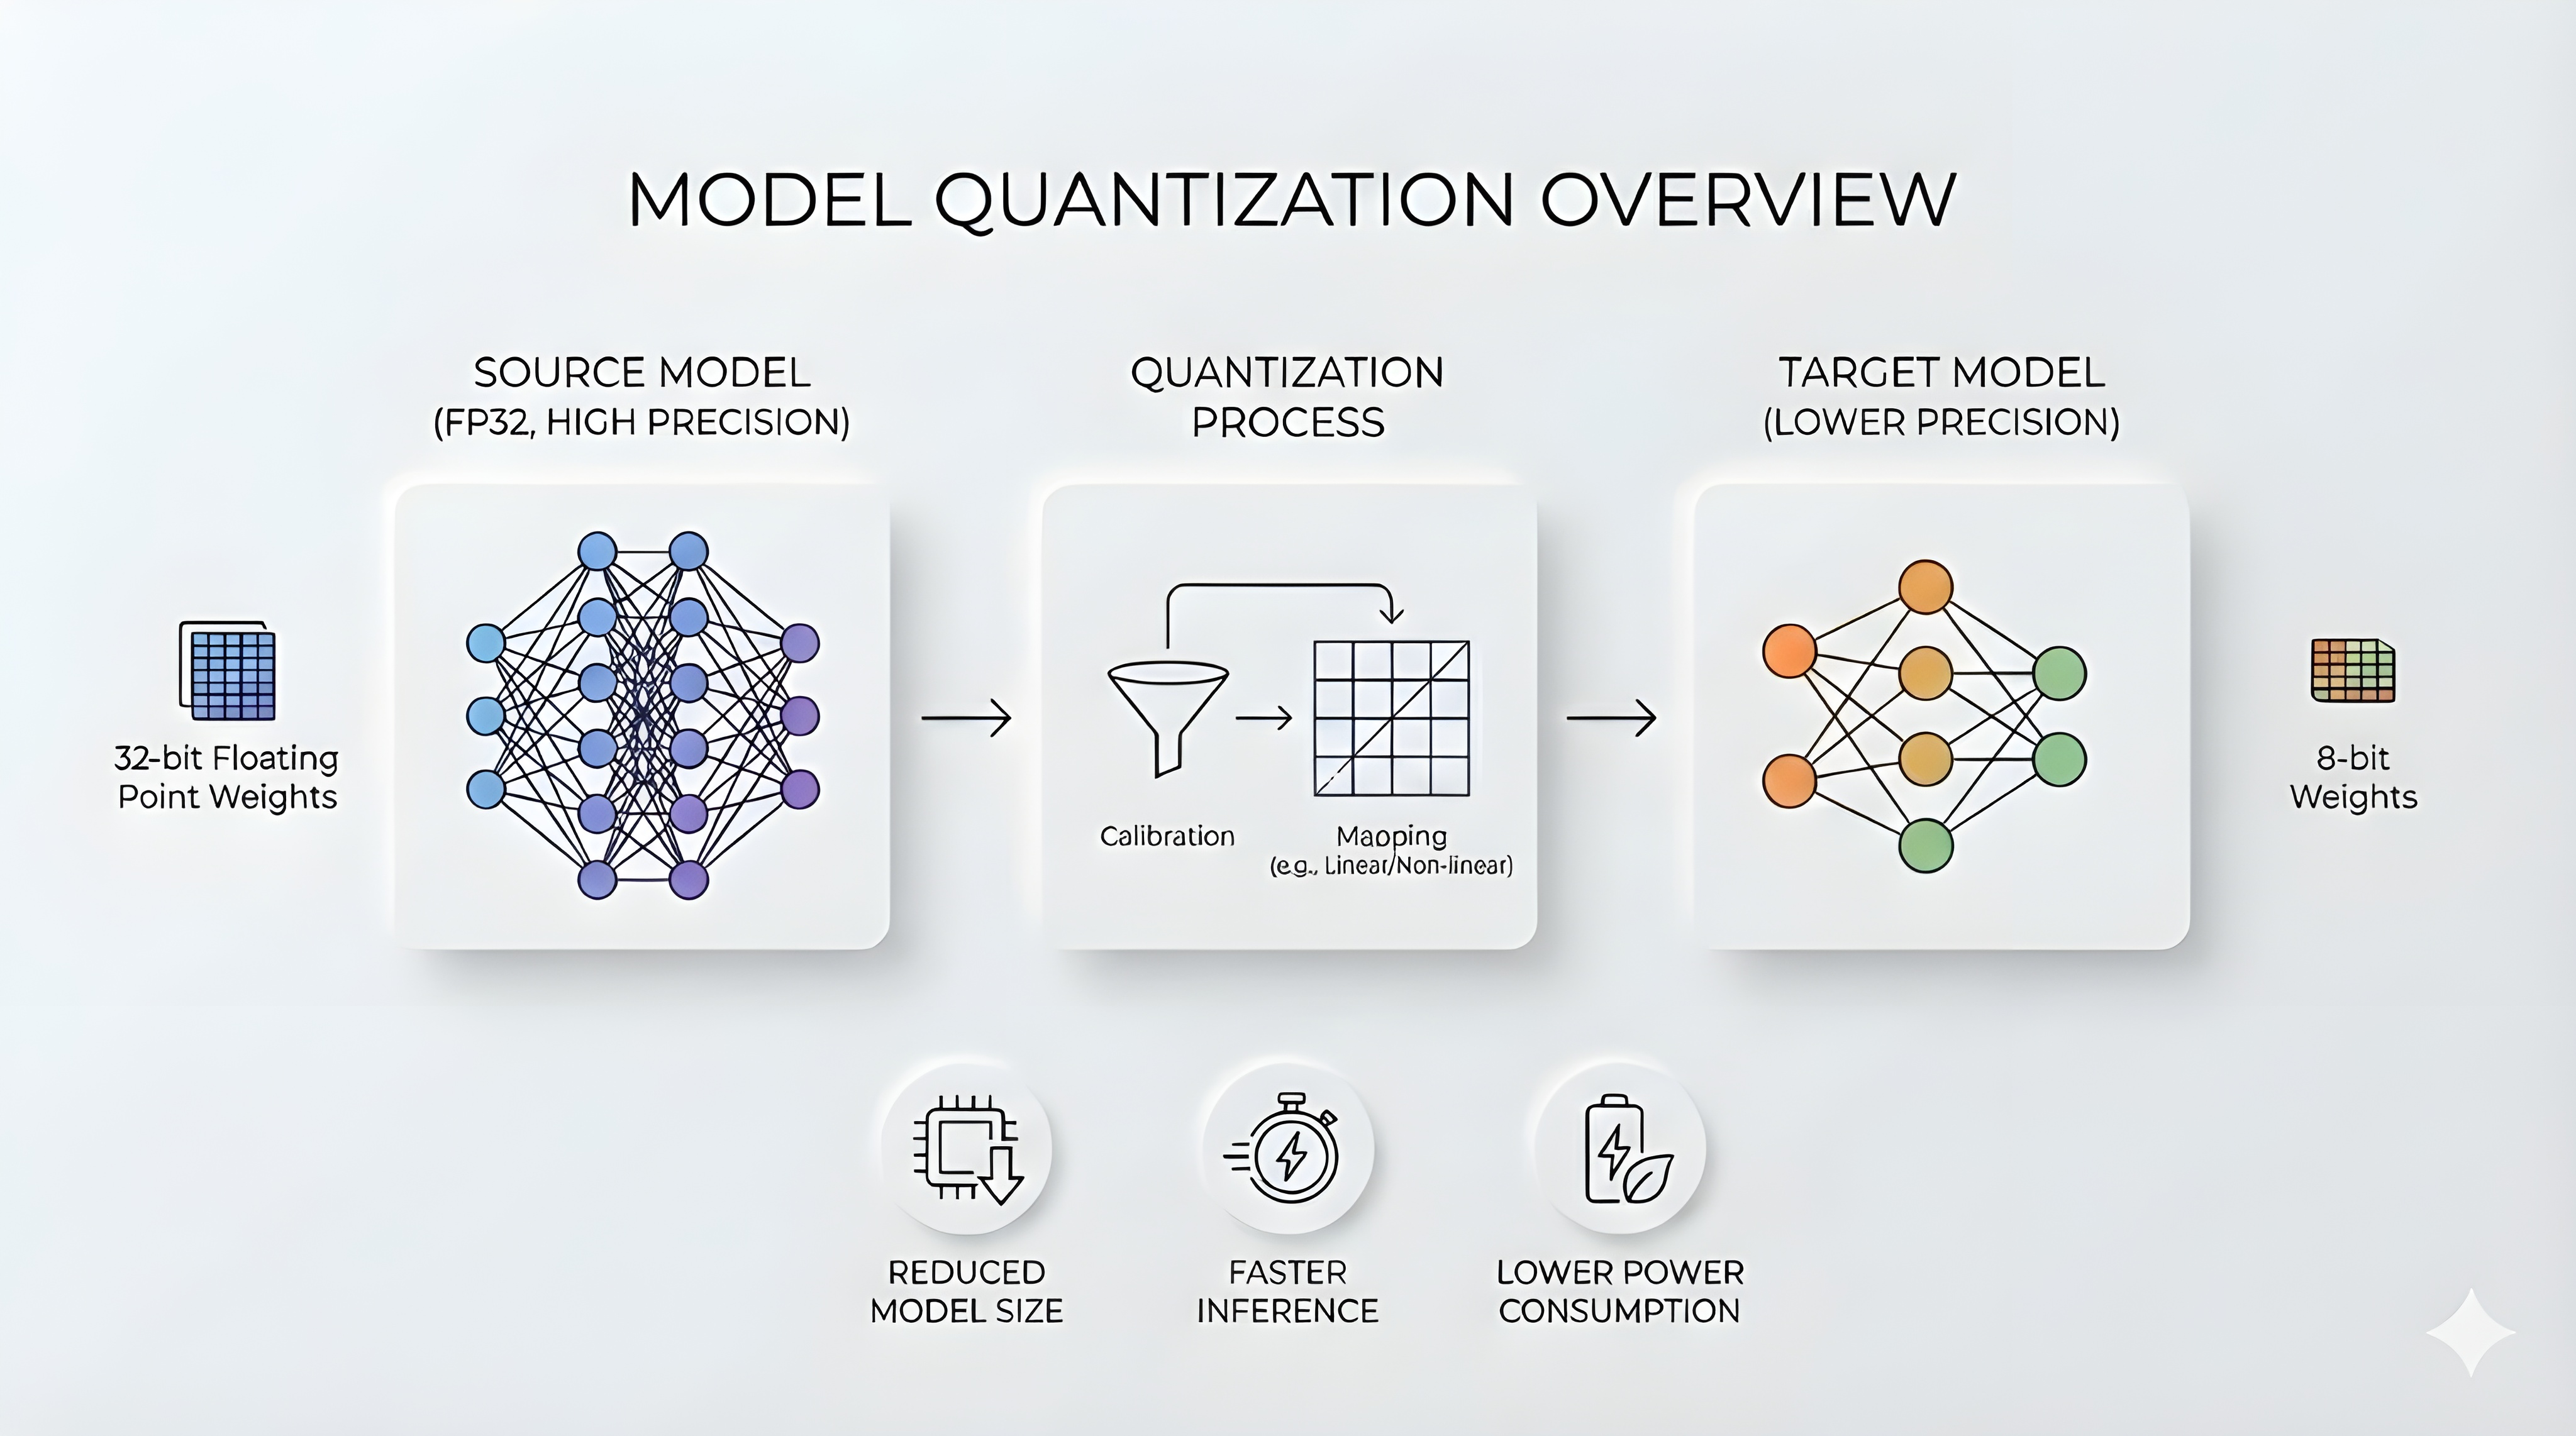
Float8 (FP8) Quantized LightGlue in TensorRT with NVIDIA Model ...
GitHub - satya15july/quantization: Model Quantization with Pytorch ...
TensorRT is encountering issues with models quantized using pytorch ...
Advertisement Space (336x280)
LSQ using pytorch_quantization · Issue #3076 · NVIDIA/TensorRT · GitHub
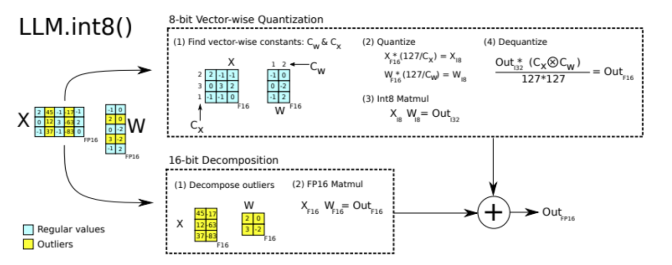
Fast and Accurate GPU Quantization for Transformers
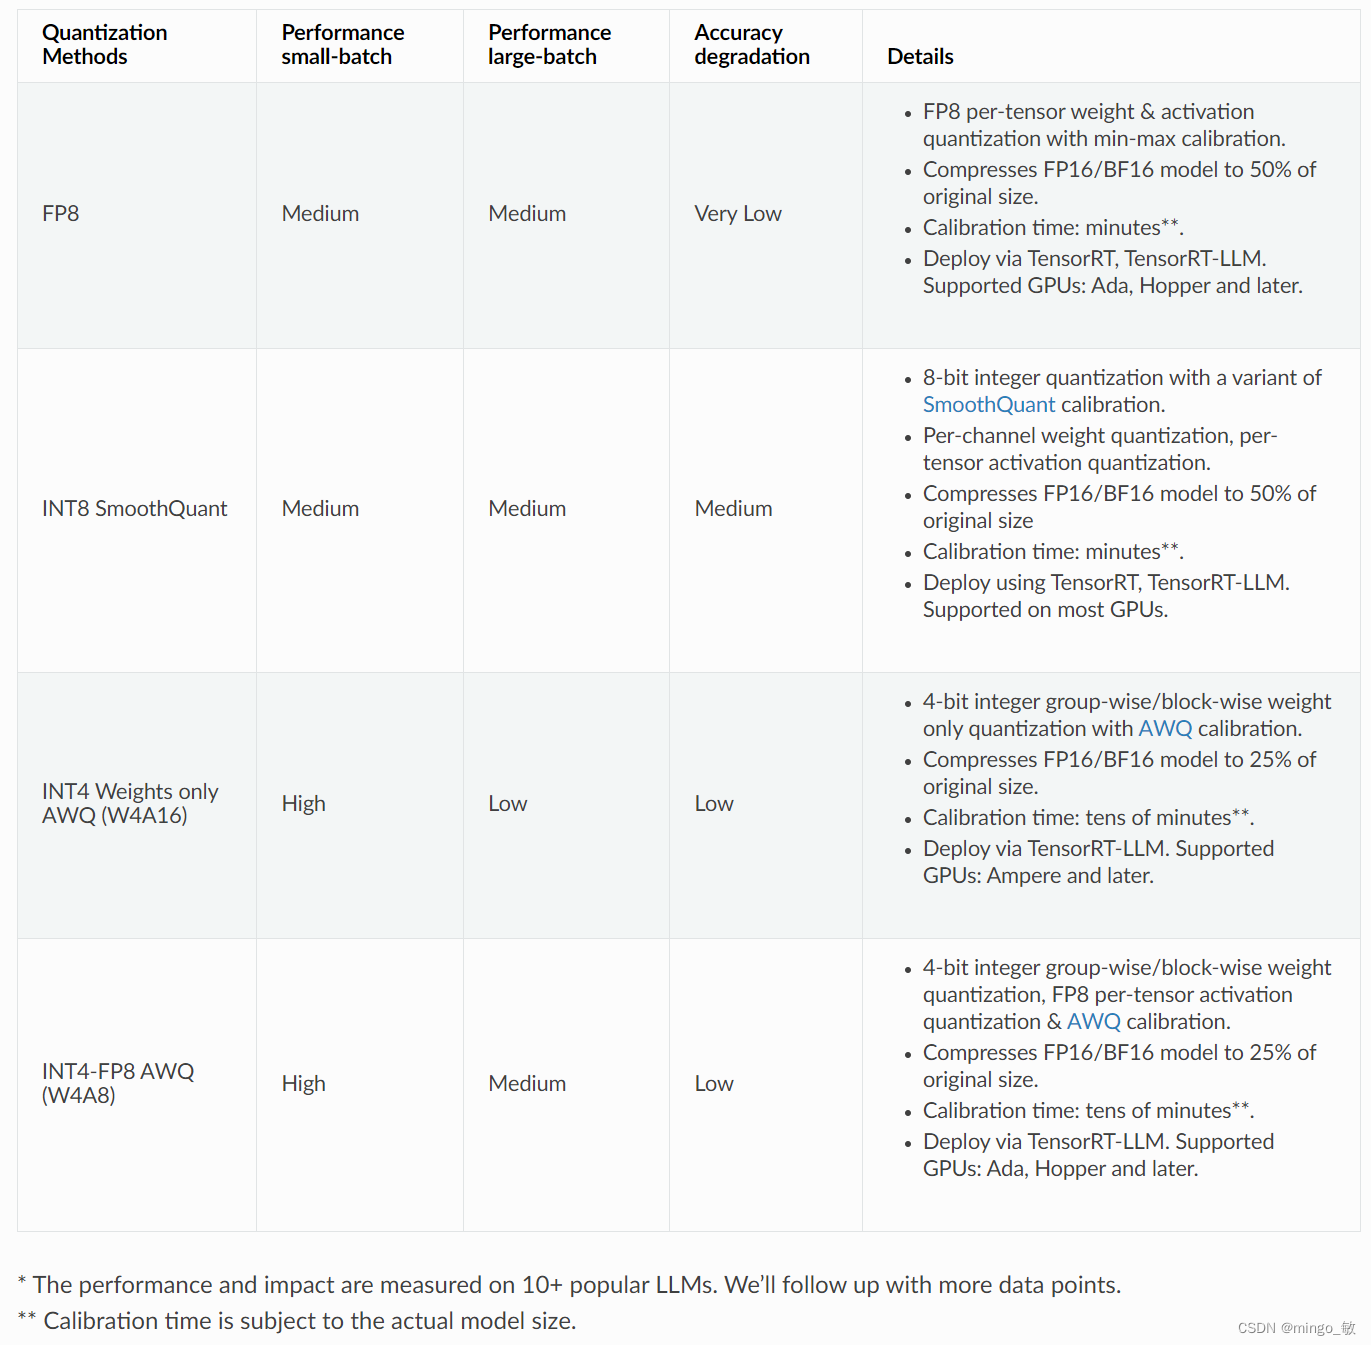
NVIDIA TensorRT Model Optimizer_modelopt-CSDN博客
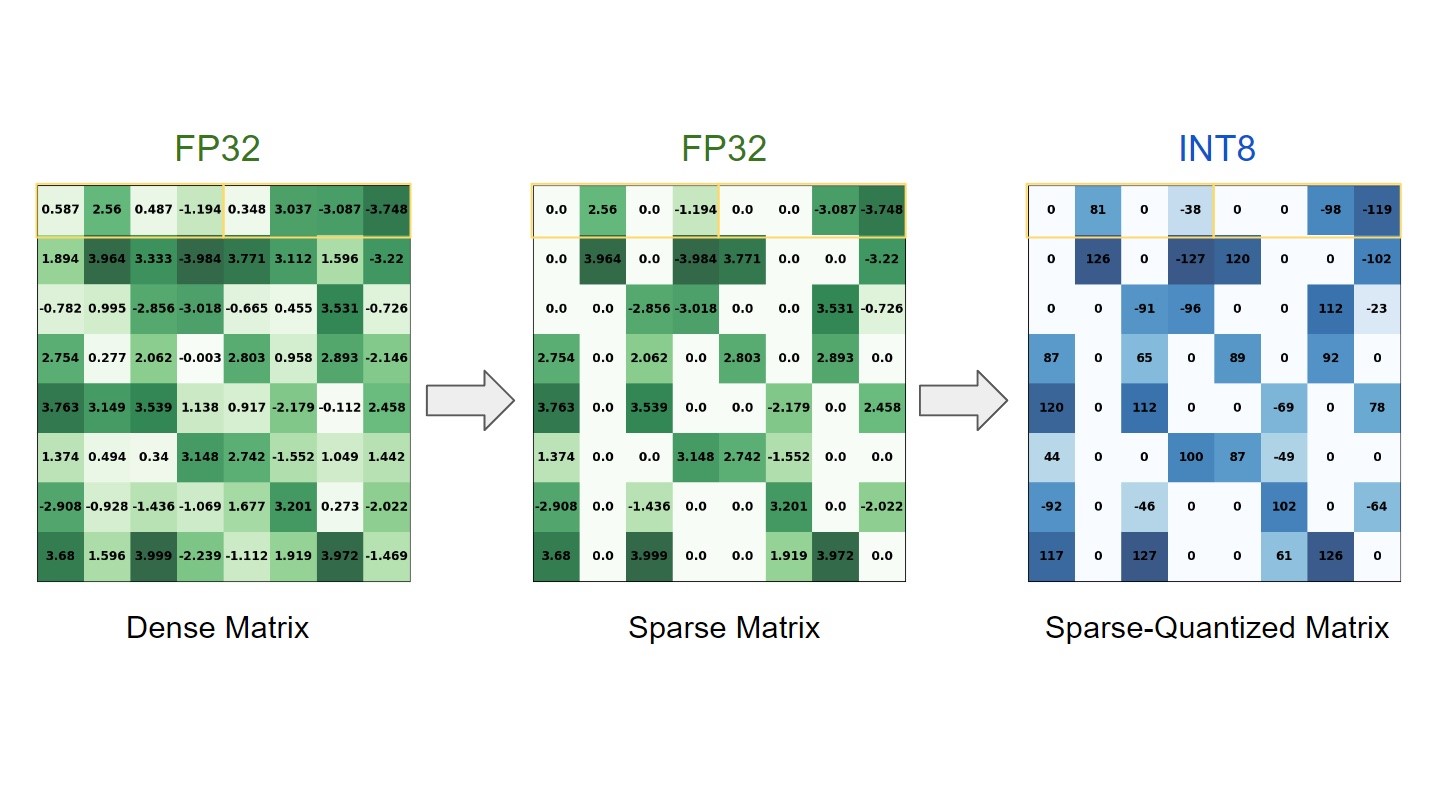
Achieving FP32 Accuracy for INT8 Inference Using Quantization Aware ...
GitHub - abhilash1910/TFModelQuantizer: A model weights quantization ...
Precision-recall curves for the Darknet FP32 model, TensorRT FP16 ...

some stange error when using pytorch_quantization for googlenet · Issue ...

Accelerating AI/Deep learning models using tensorRT & triton inference

Wrong Results for FP16 Models in CUDAExecutionProvider and ...
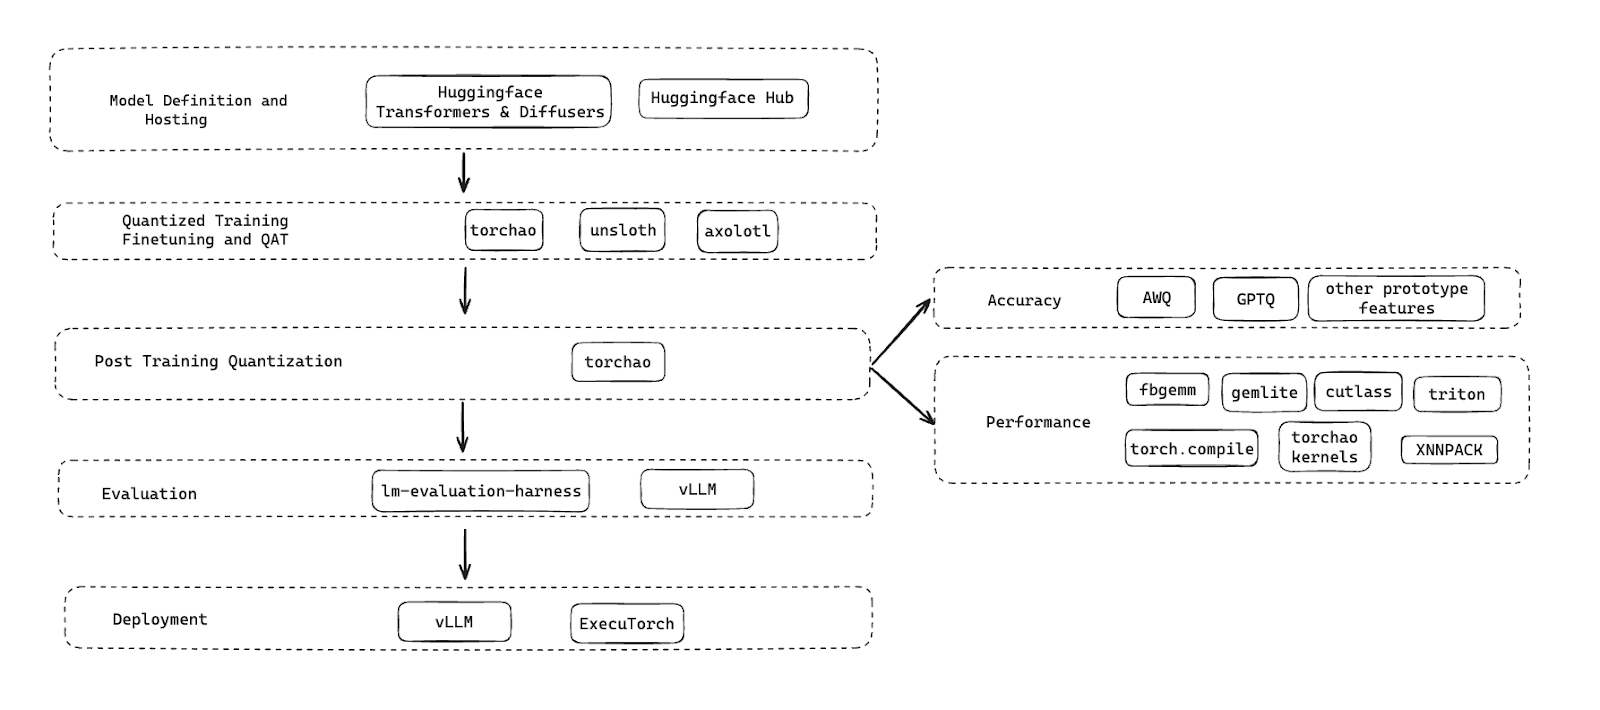
TorchAO Quantized Models and Quantization Recipes Now Available on ...
Advertisement Space (336x280)

A Hands-On Walkthrough on Model Quantization - Medoid AI

Pytorch dynamic quantization issue - PyTorch Forums

QAT int8 TRT engine slower than fp16 - TensorRT - NVIDIA Developer Forums

TensorRT: Quantization issues with convtranspose3D - TensorRT - NVIDIA ...
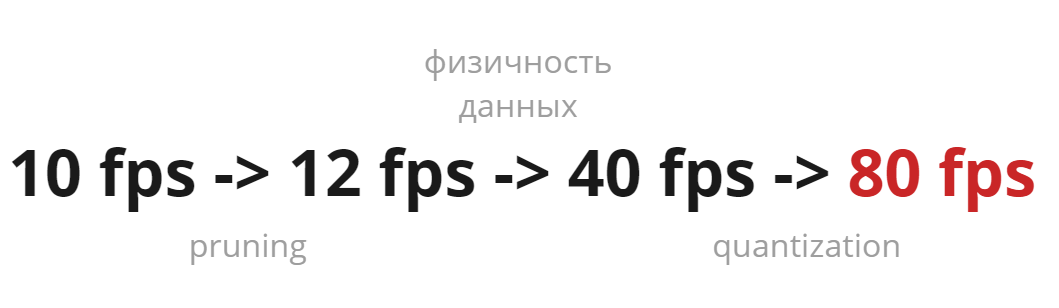
Quantization Aware Training. Или как правильно использовать fp16 ...
Quantization Explained: Q4 vs Q8 vs FP16 — What You Actually Lose ...