
Quantizing Model Appears To Slow Inference Speed Issue 975 Deci Ai
Quantizing model appears to slow inference speed · Issue #975 · Deci-AI ...
Model inference speed is slow · Issue #3 · shikiw/OPERA · GitHub
Ollama Slow Inference Fix: Speed Up Local AI Model Response Times (2026)

zai-org/glm-10b-chinese · How to solve Model inference speed is too slow?
INT8 Inference: 8-bit Quantization for AI Model Speed | Inference Systems
Abnormally slow inference speed of quantized model? · Issue #24762 ...
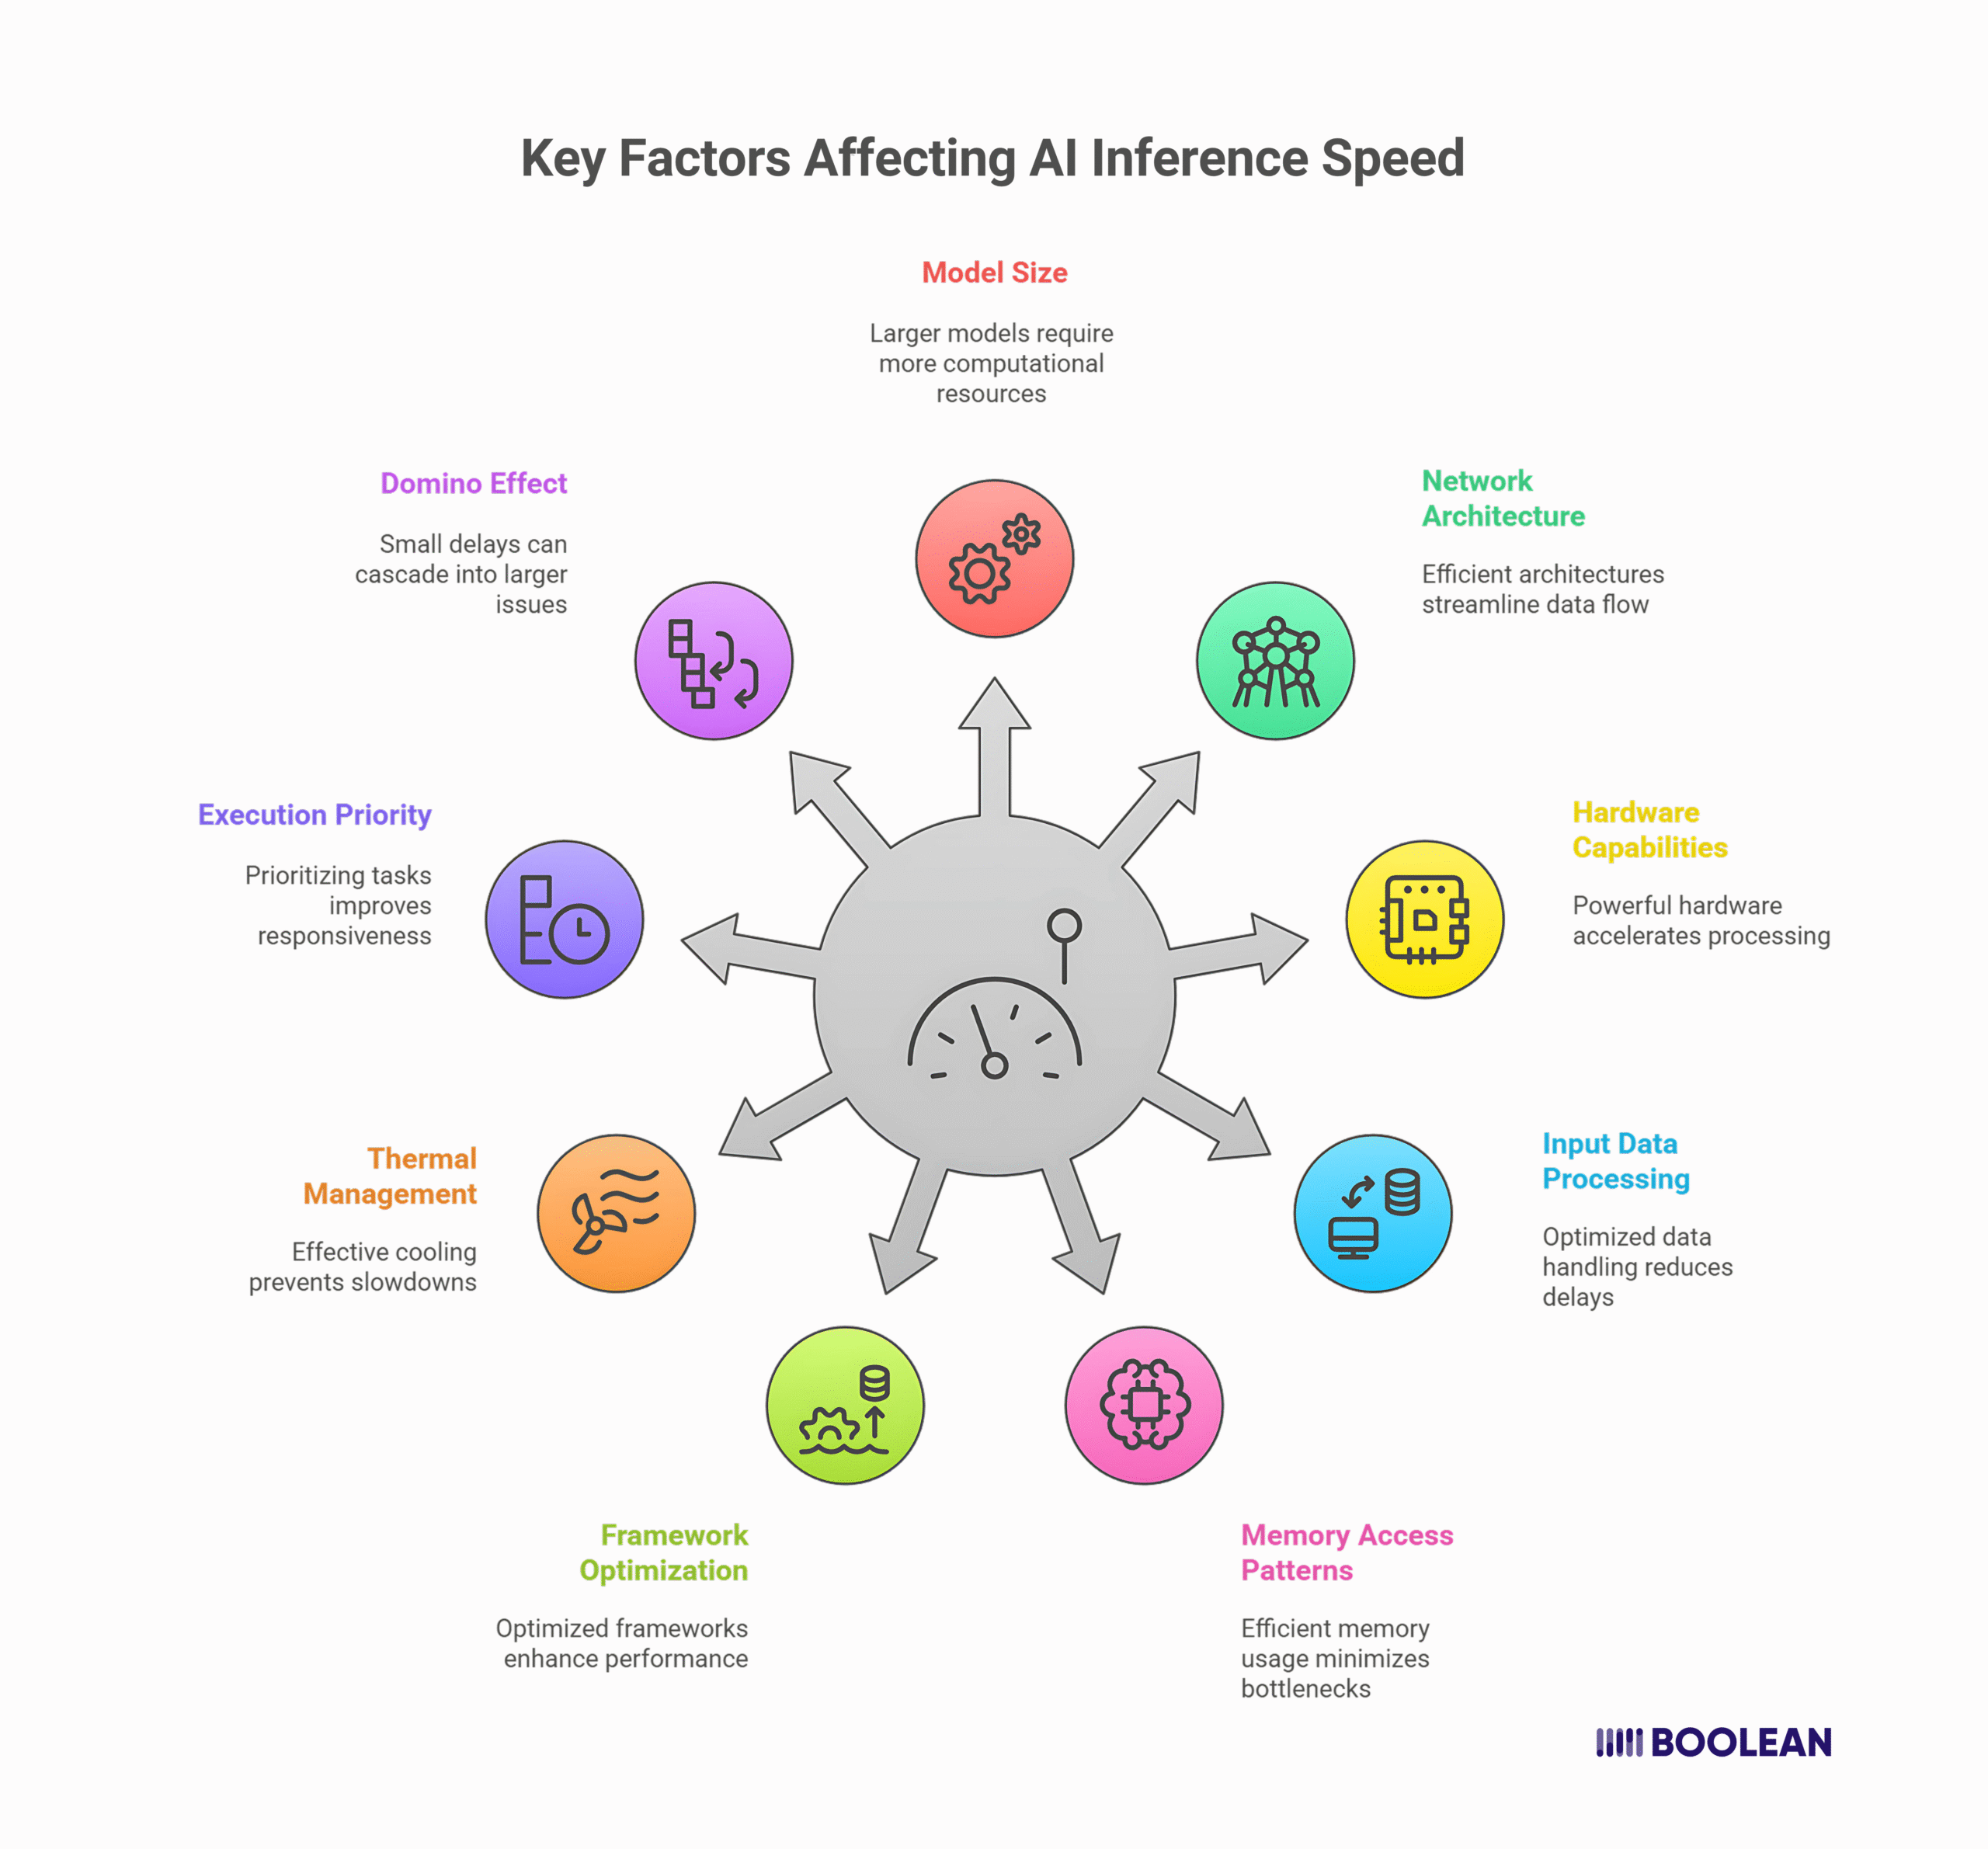
How to Optimize Inference Speed for AI Driven Mobile Apps

Benchmarking Inference Speed in LLMs | AI Tutorial | Next Electronics
Dynamic Range Calibration for AI Model Quantization | Inference Systems
Graph Quantization Folding: AI Model Optimization Explained | Inference ...
Advertisement Space (300x250)
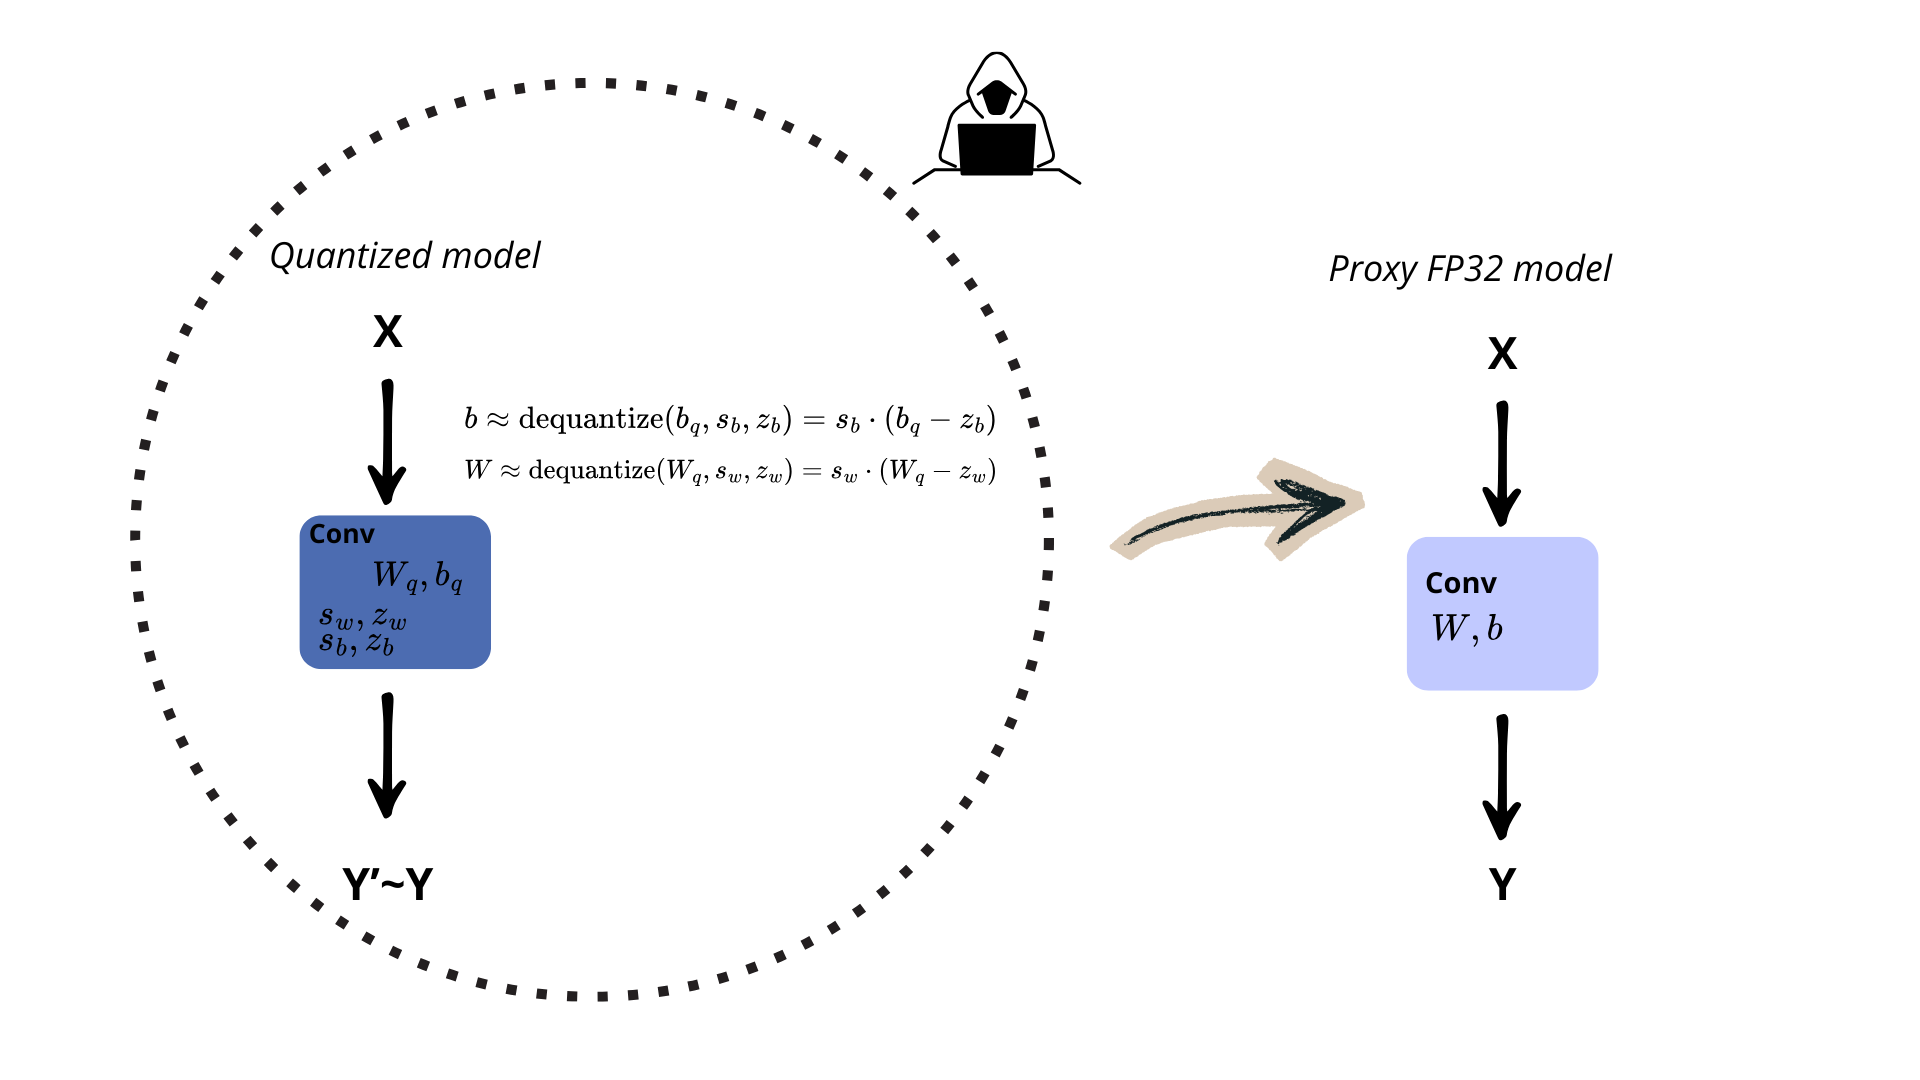
How to Quantize an AI Model for Deployment?
Optimize AI Inference Speed & Accuracy | Coursera

Model Accuracy vs Inference Speed | Download Scientific Diagram
Speed slows down after model quantization · Issue #29024 · pytorch ...
Why does the model's inference speed slow down when ‘half==True ...

DeepSpeed ZeRO++: A leap in speed for LLM and chat model training with ...
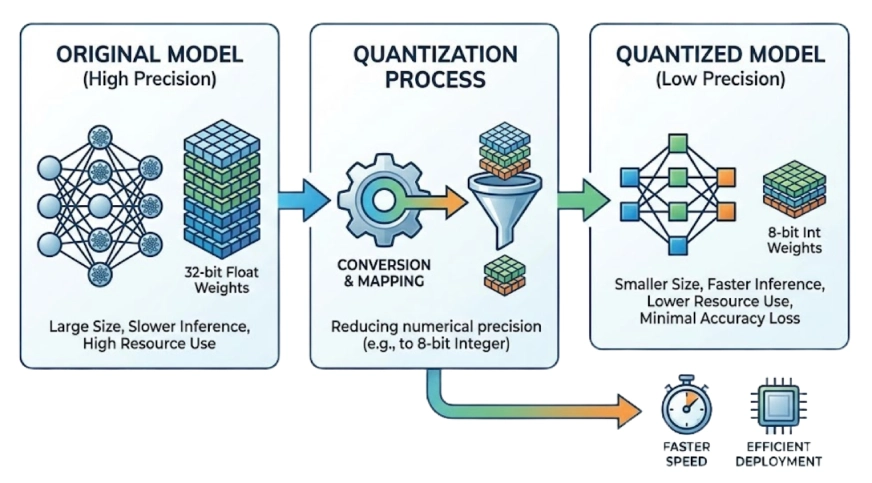
Model Quantization: Run Large AI Models on Limited Hardware
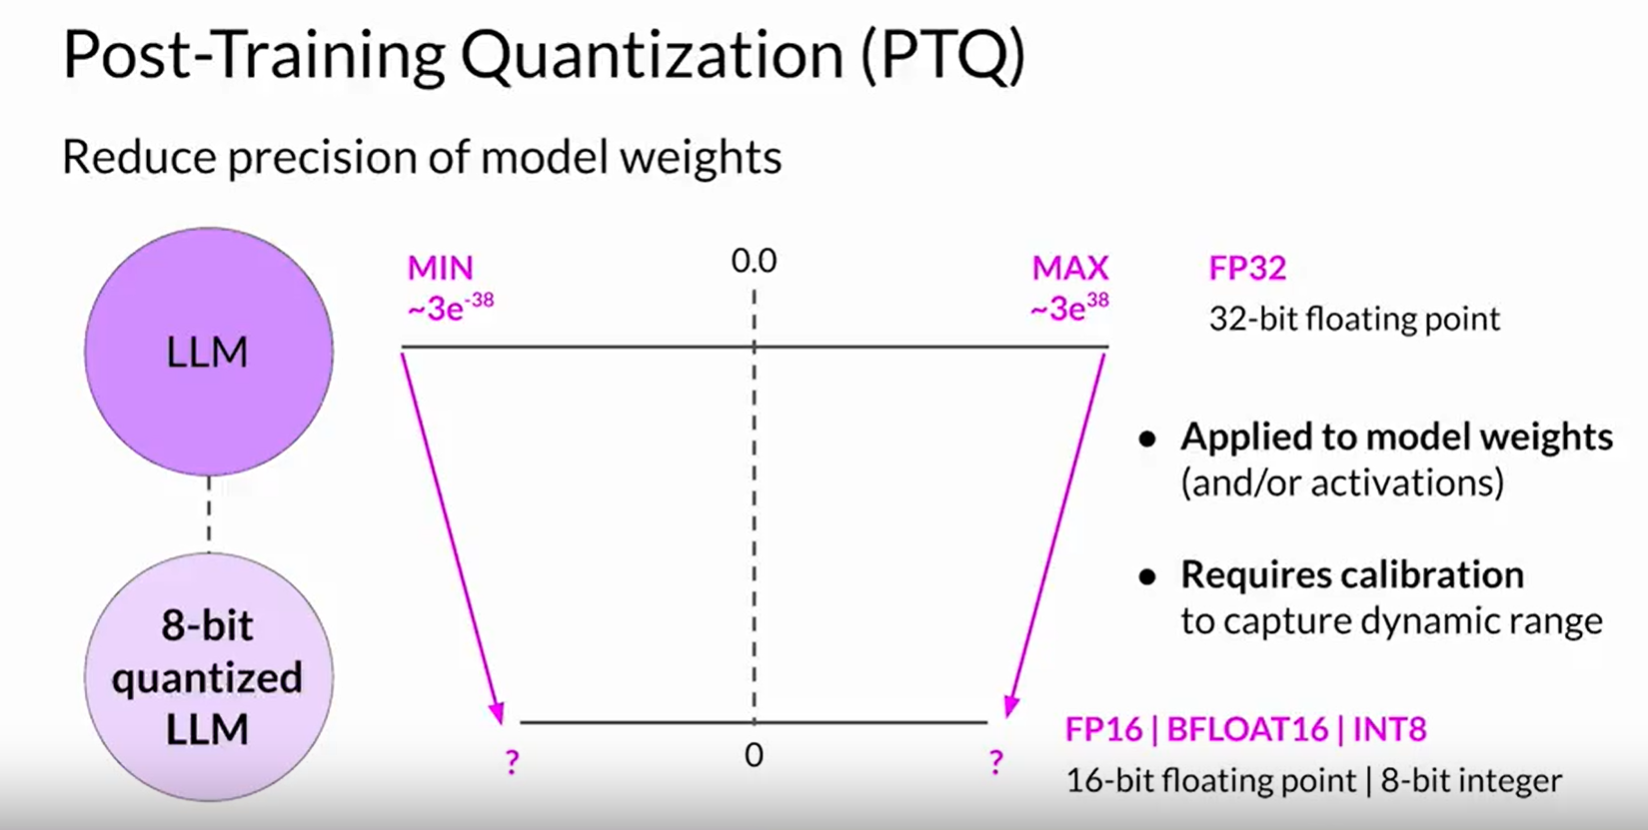
Machine Learning Model Inference – Monir Moniruzzaman – Data Scientist ...

7 Model Quantization Techniques That Shrink AI Models by 75% | by ...
Quantization Error: Definition & Impact on AI Models | Inference Systems
Advertisement Space (336x280)

Model Quantization: Unlock ⚡Faster⚡ Inference Speeds - YouTube
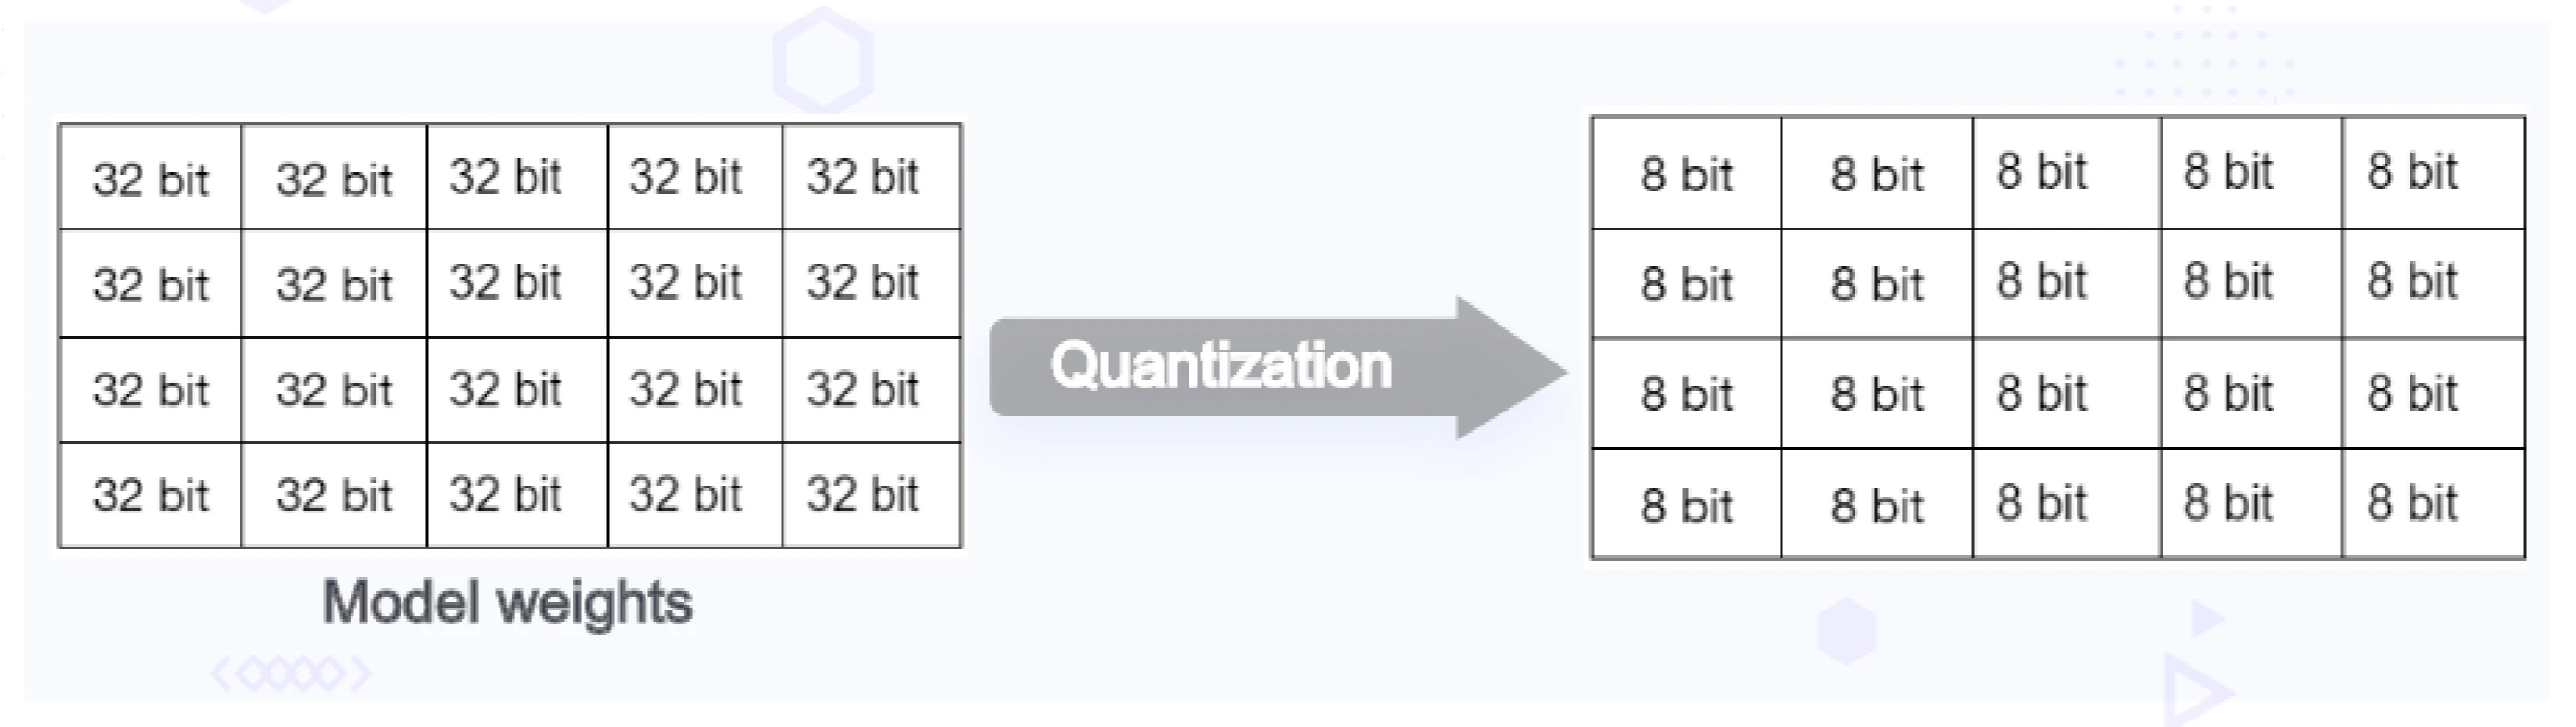
Exploring AI Model Inference: Servers, Frameworks, and Optimization ...
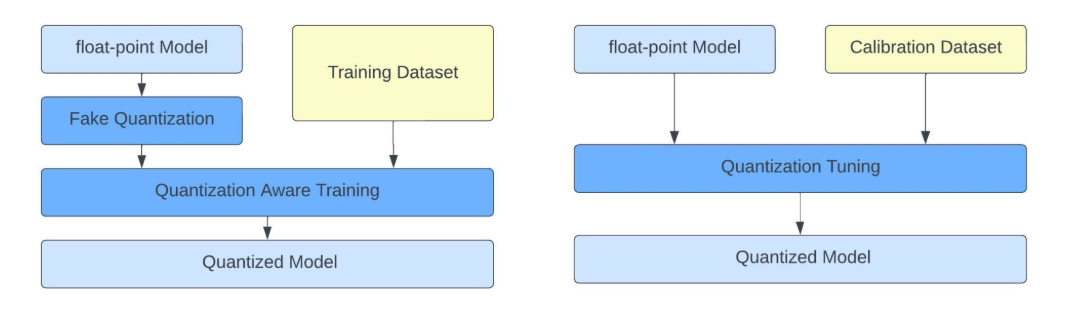
Dwith Chenna | AI Inference Technical Leader

LLM inference optimization: Model Quantization and Distillation - YouTube
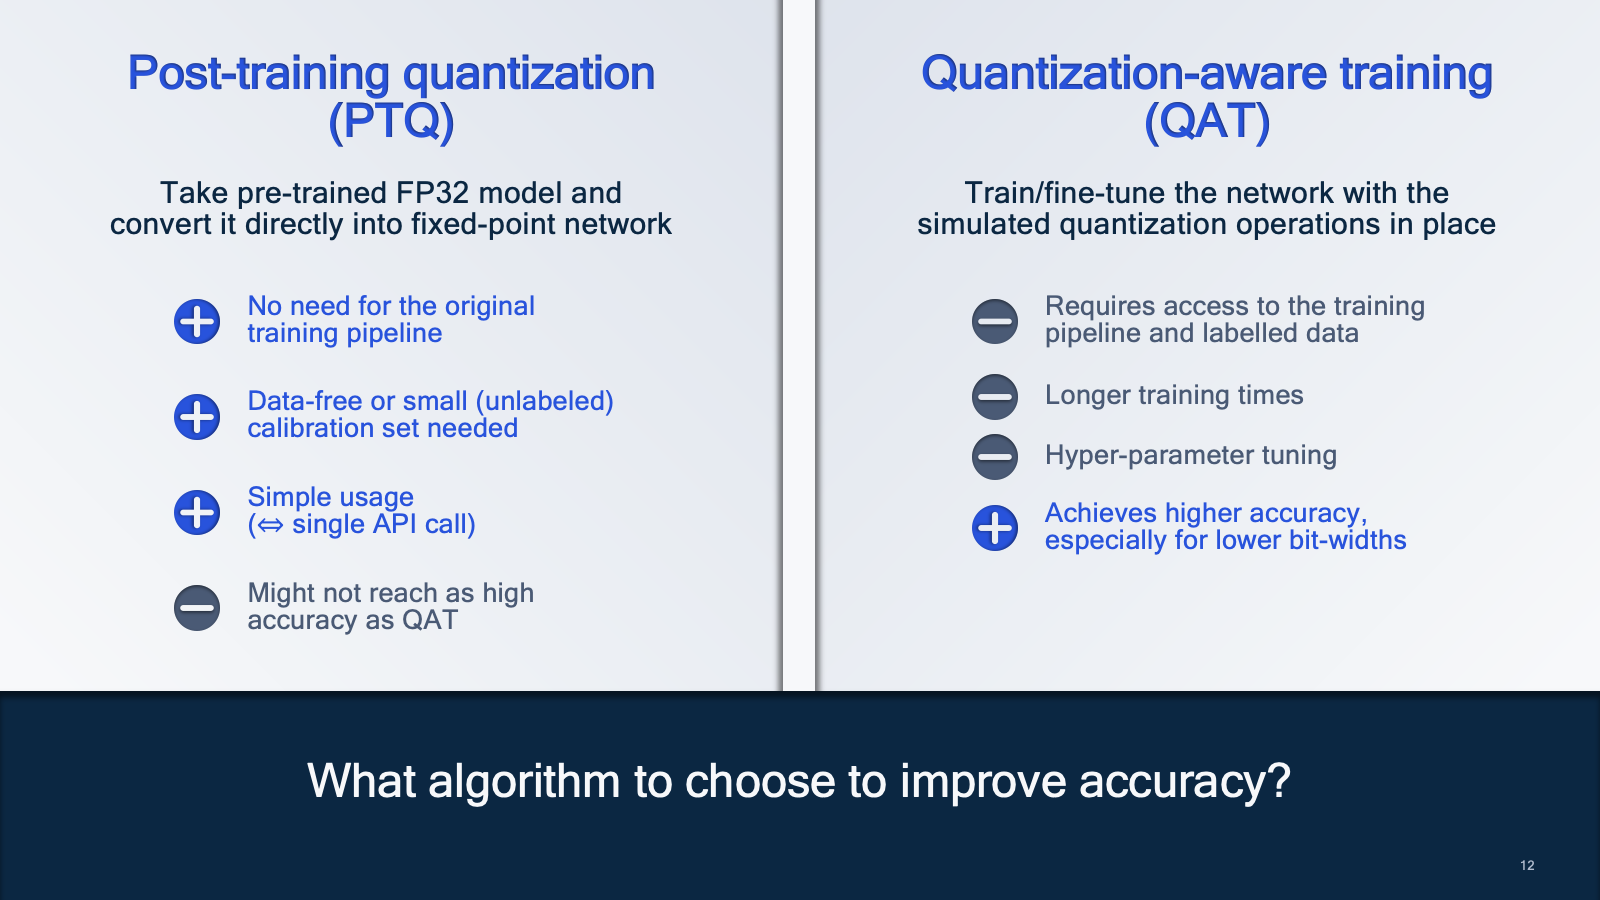
The Future of Model Efficiency for Edge AI - Edge AI and Vision Alliance
Model Quantization for Inference

AI Model Quantization: Reducing Size Without Losing Performance ...

LLM Inference Optimization | Speed, Cost & Scalability for AI Models

KLLM: Fast LLM Inference with K-Means Quantization | AI Research Paper ...
Model Parameter Count vs. Inference Speed. While being slower than LSTM ...
Advertisement Space (336x280)

AI Inference Optimization: How Quantization, KV-Cache, and Speculative ...

A Hands-On Walkthrough on Model Quantization - Medoid AI
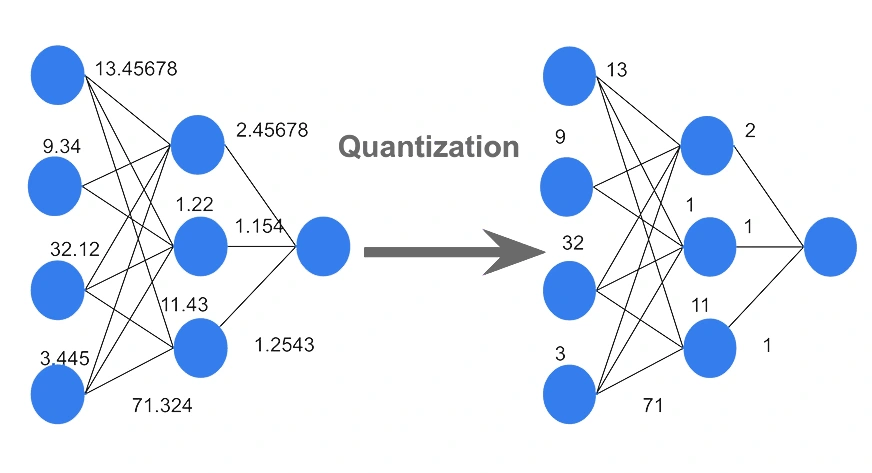
Model Quantization: Run Large AI Models on Limited Hardware
Faster LLMs with Quantization - How to get faster inference times with ...
What is Calibration in Quantization? | AI Glossary | Inference Systems
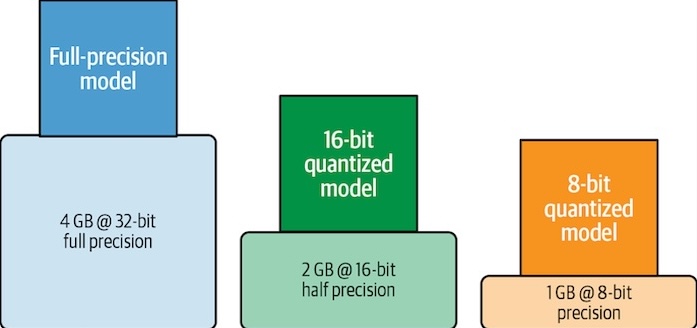
Lean AI - How to Reduce LLM Cost? | Benny's Mind Hack