
Ray Issue While Running Api Server Issue 544 Vllm Projectvllm
Ray issue while running API server · Issue #544 · vllm-project/vllm ...
Error while starting API server when using Ray · Issue #741 · vllm ...
New Ray Release Breaks VLLM API Server · Issue #563 · vllm-project/vllm ...
vLLM running on a Ray Cluster Hanging on Initializing · Issue #2826 ...
How to use vllm openai api server for video reasoning ? · Issue #540 ...
[Bug]: OpenAI API Server always reports 0 tokens/s · Issue #4209 · vllm ...
[Bug]: vllm server hang when running DeepSeek R1 · Issue #13778 · vllm ...
API Server batch request issue · Issue #2441 · vllm-project/vllm · GitHub
Multi-node serving with vLLM - Problems with Ray · Issue #2406 · vllm ...
[Bug]: vllm cannot connect to an external ray cluster · Issue #14349 ...
Advertisement Space (300x250)
[Bug]: vLLM still runs after Ray workers crash · Issue #16259 · vllm ...
[Bug]: The vllm is disconnected after running for some time · Issue ...
[Bug]: start api server stuck · Issue #4027 · vllm-project/vllm · GitHub
[Bug]: Cannot run vLLM server with OpenVINO backend · Issue #12687 ...
Default api server stuck on some cases · Issue #667 · vllm-project/vllm ...
API Server Performance · Issue #1677 · vllm-project/vllm · GitHub
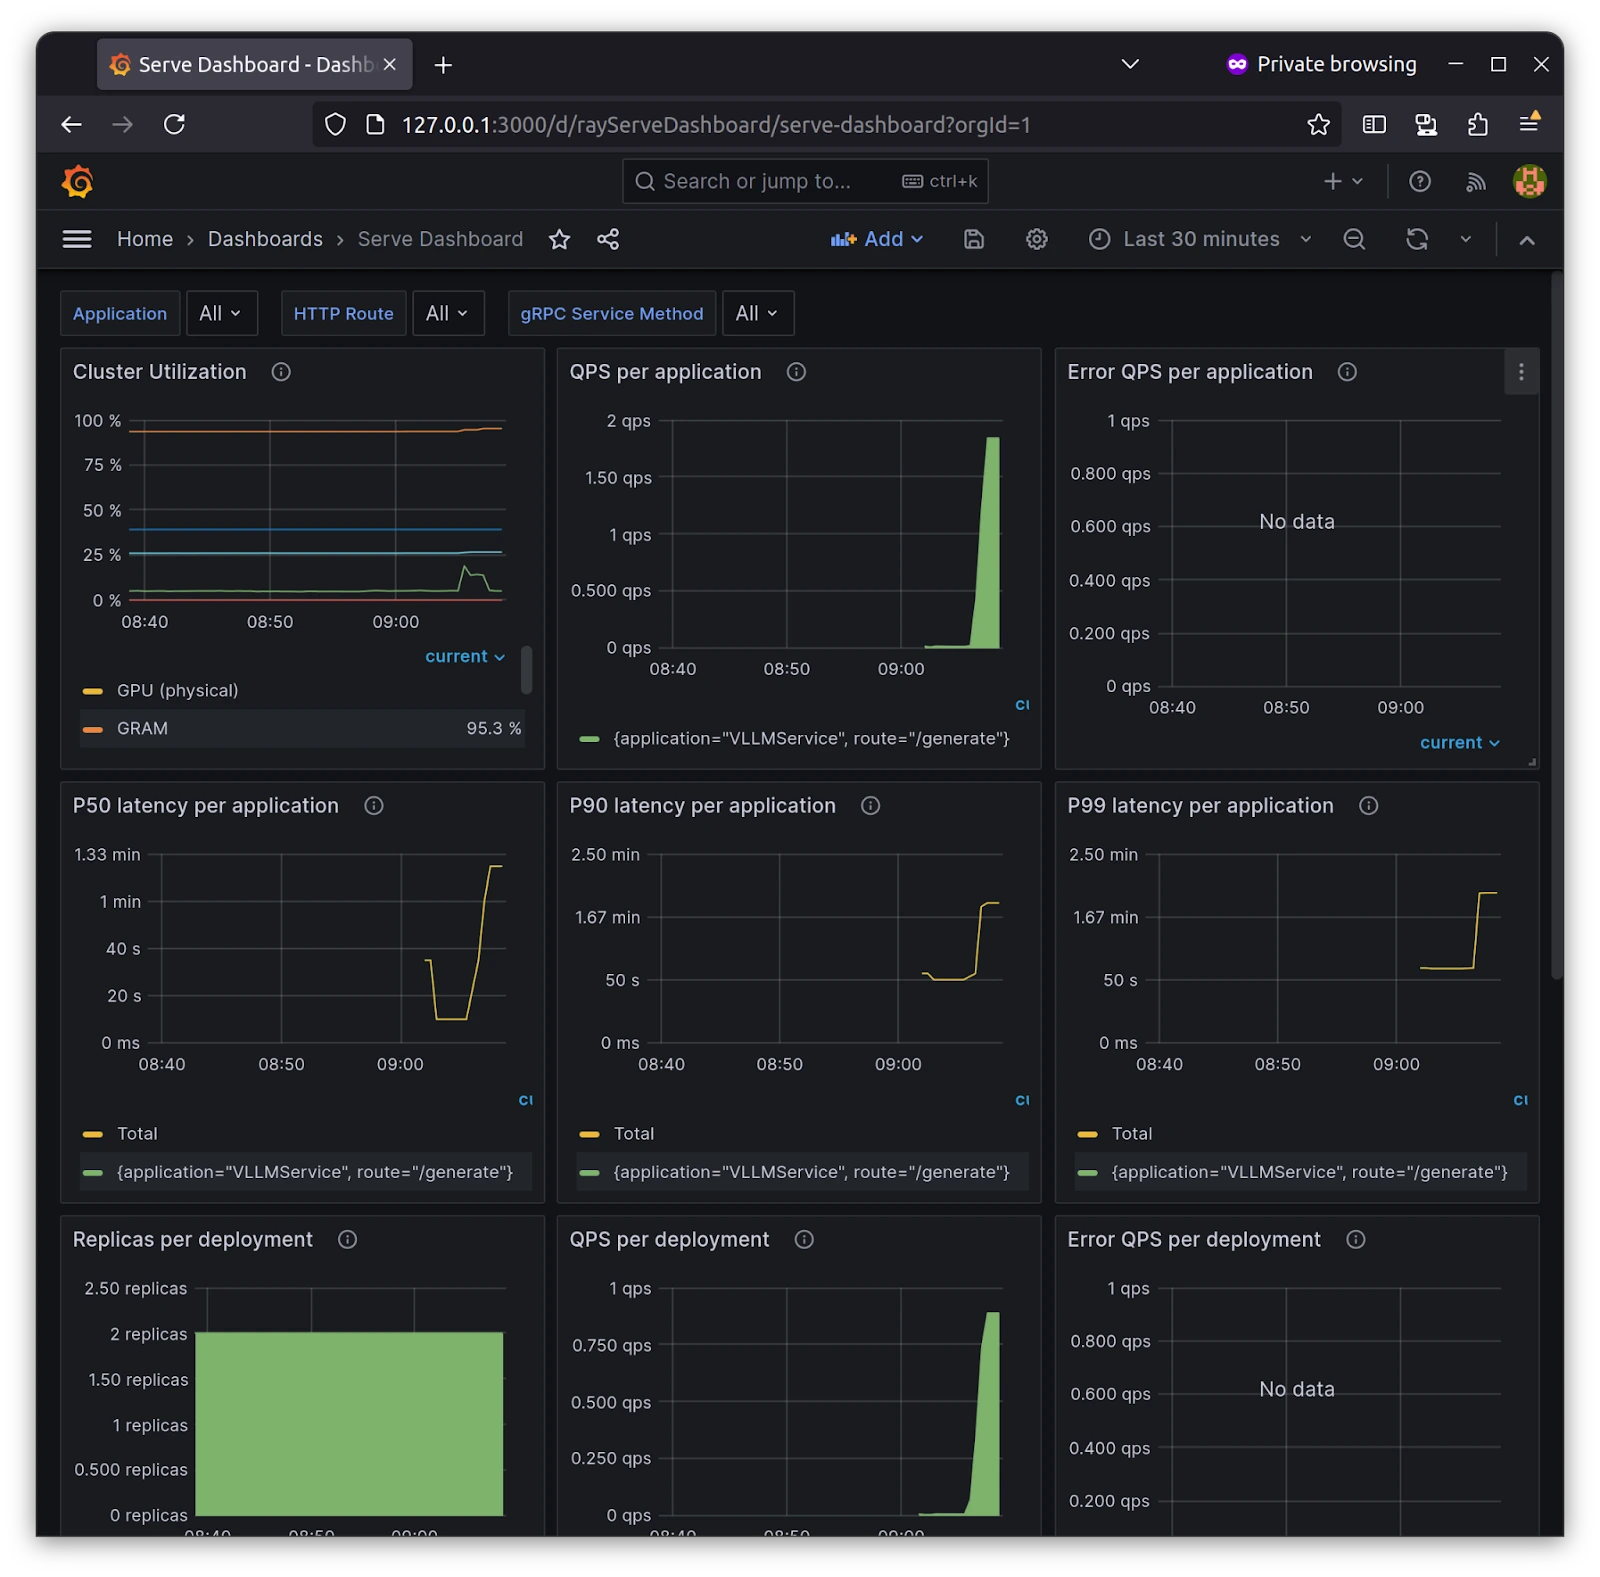
Running Phi 3 with vLLM and Ray Serve
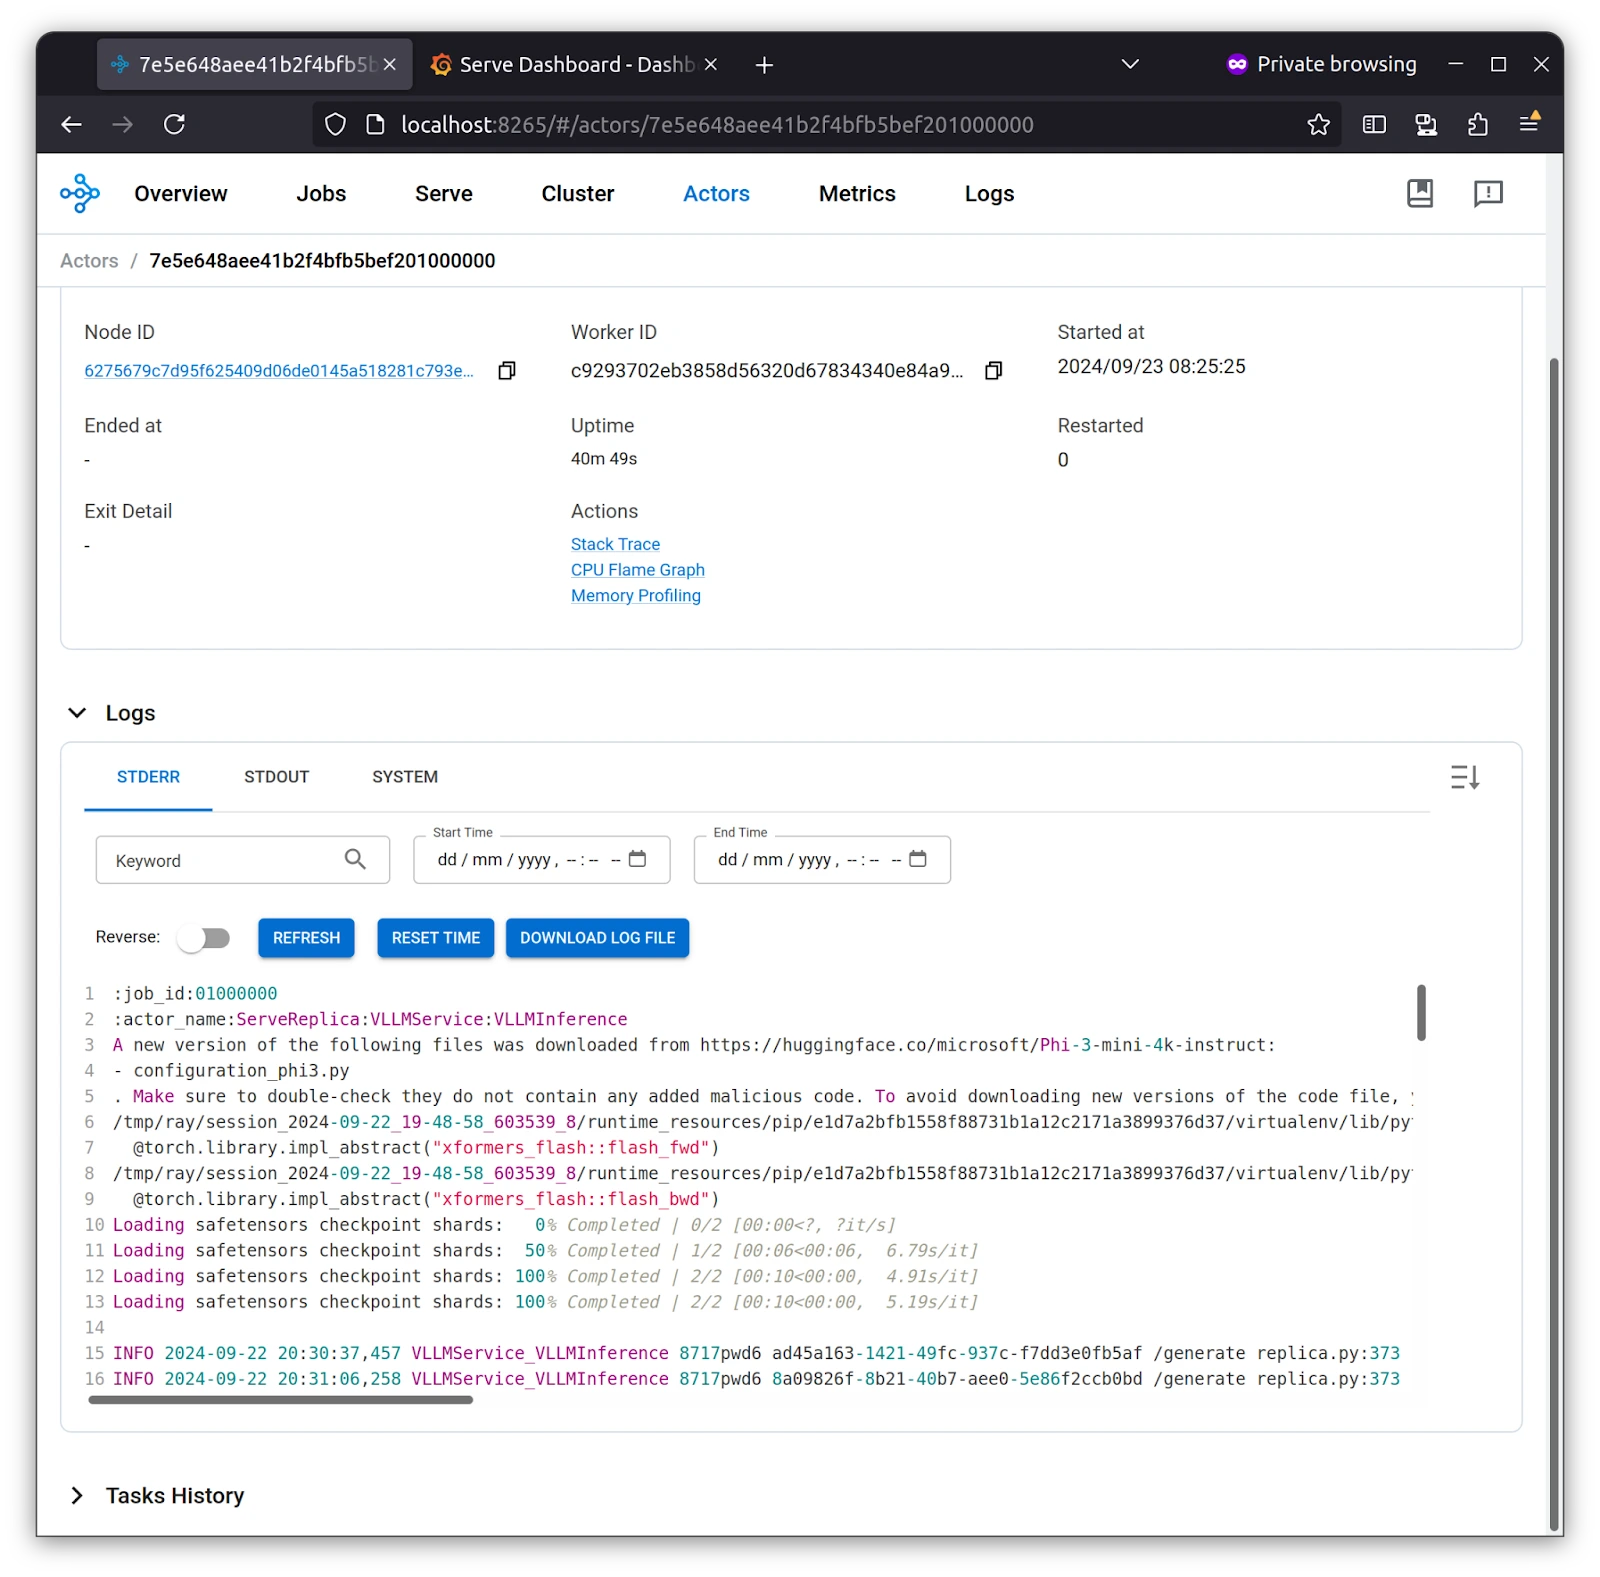
Running Phi 3 with vLLM and Ray Serve
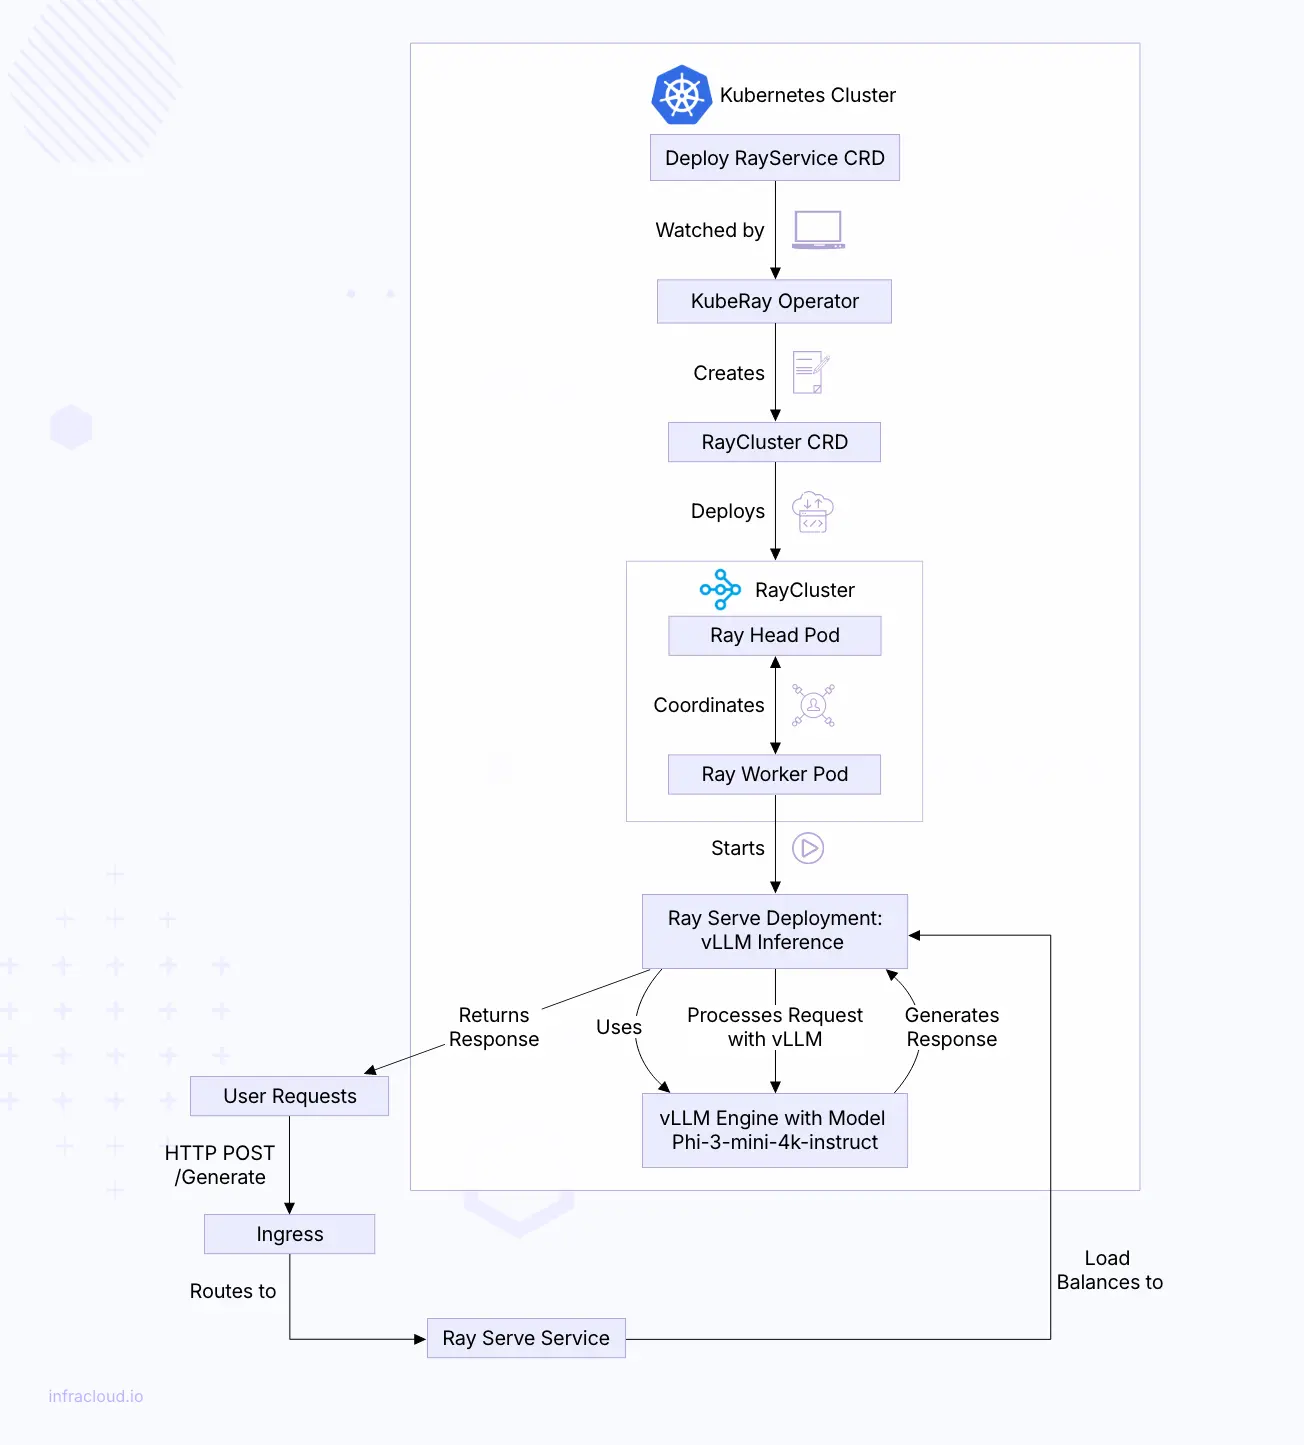
Running Phi 3 with vLLM and Ray Serve
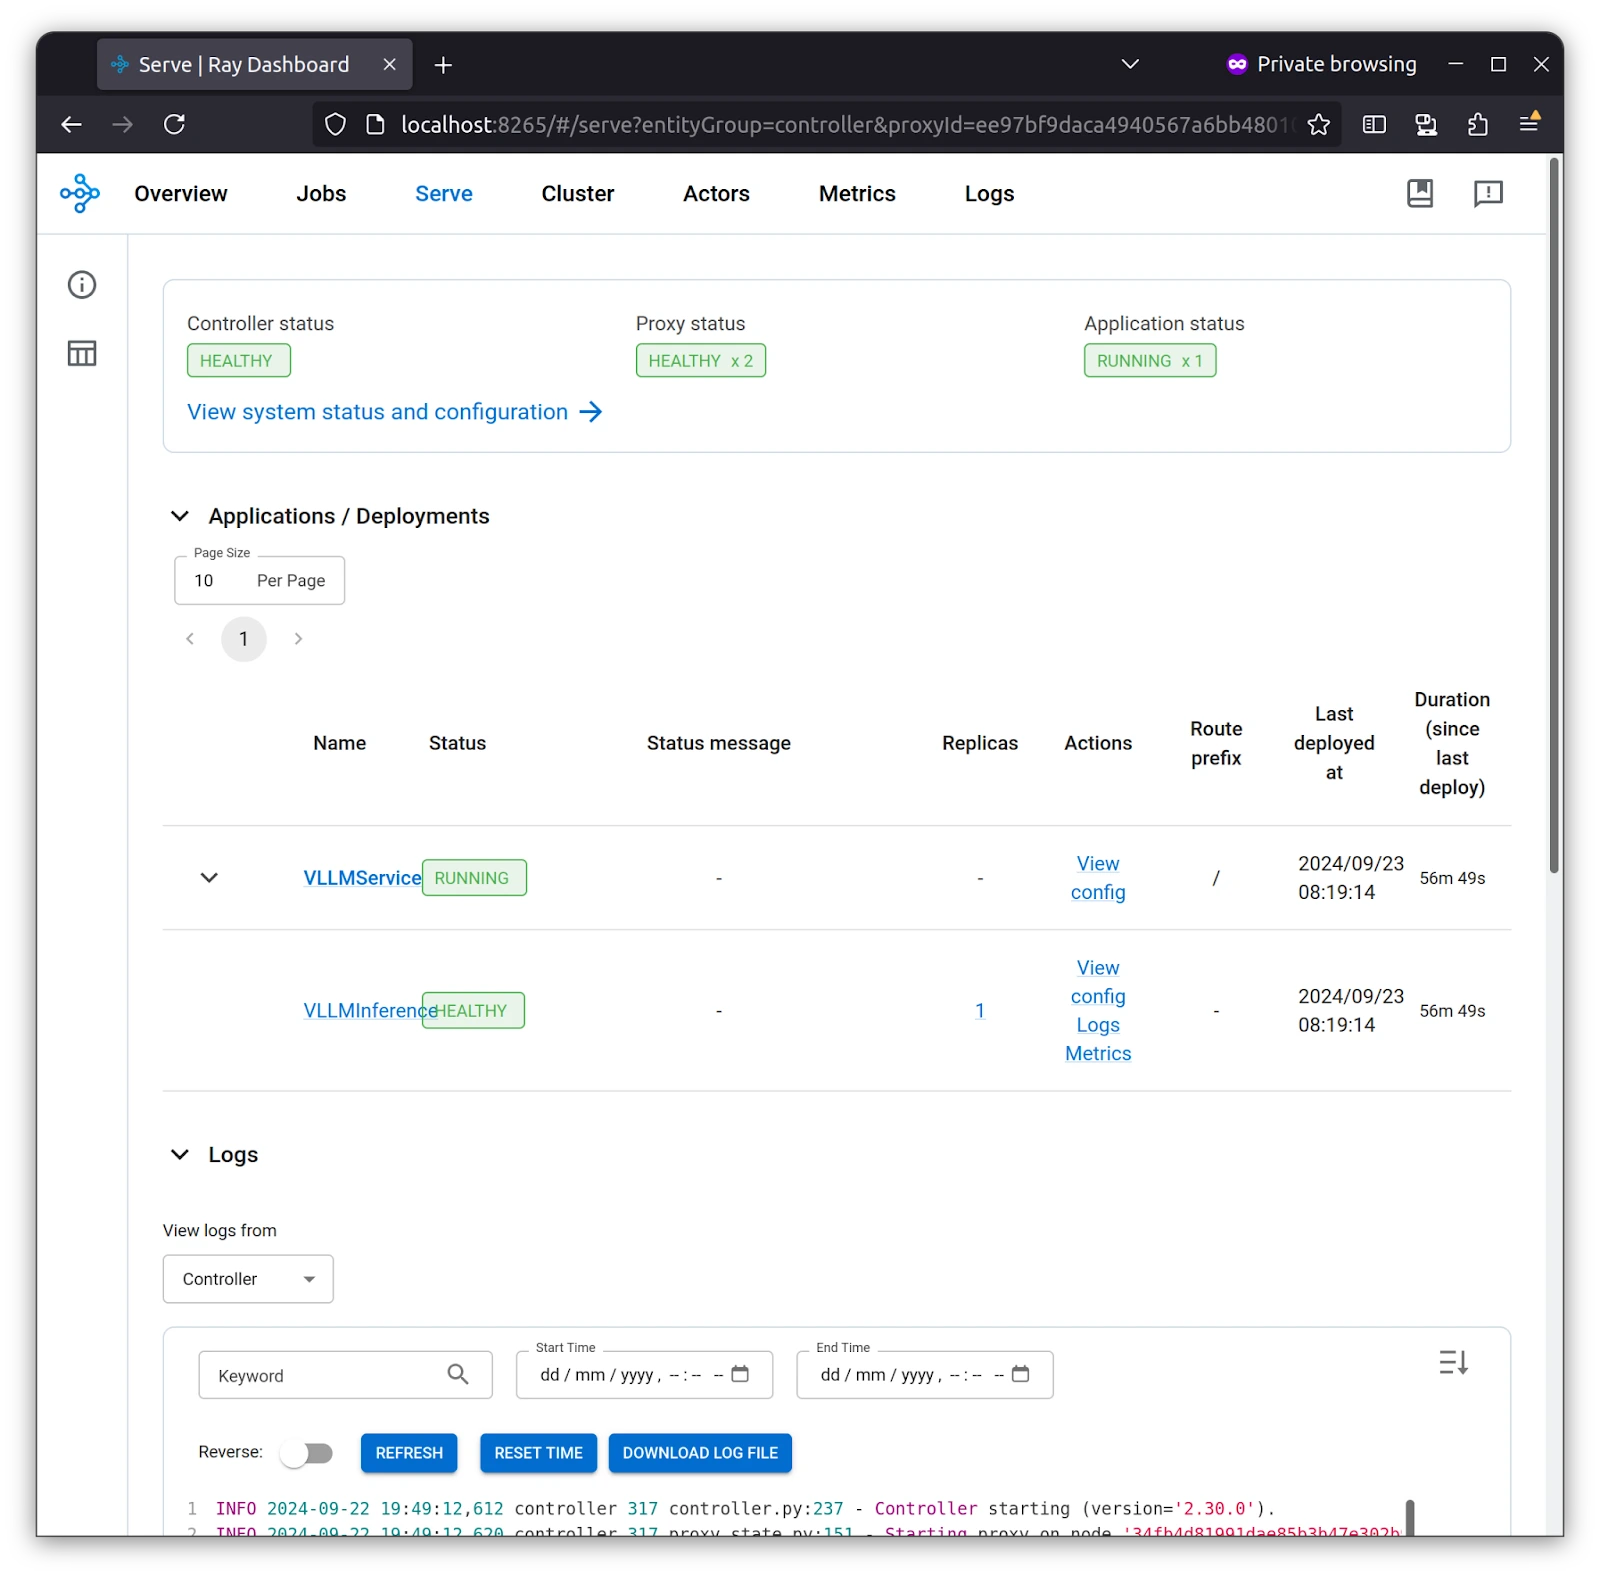
Running Phi 3 with vLLM and Ray Serve
Advertisement Space (336x280)
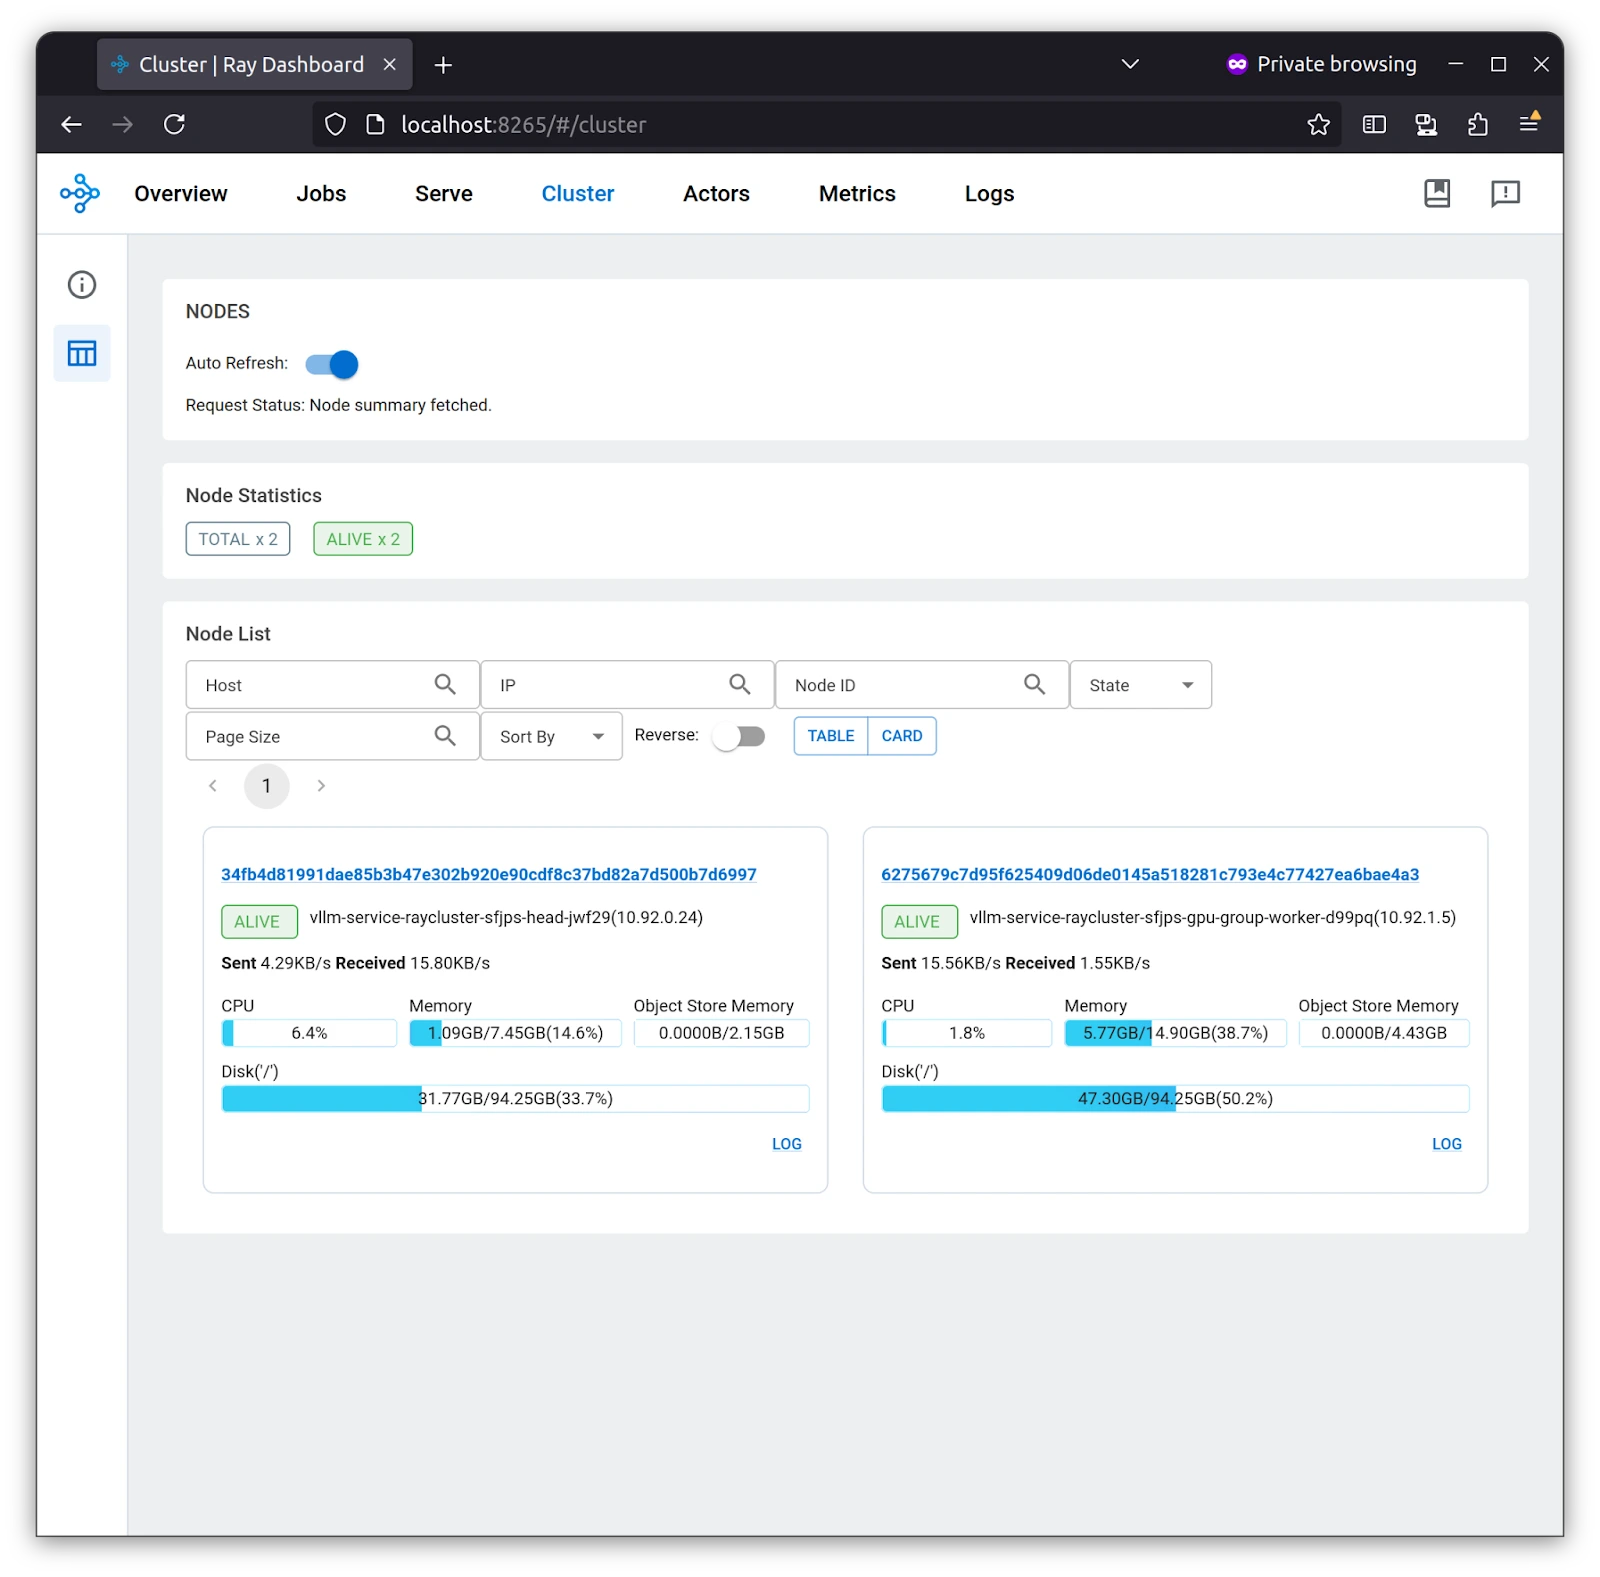
Running Phi 3 with vLLM and Ray Serve
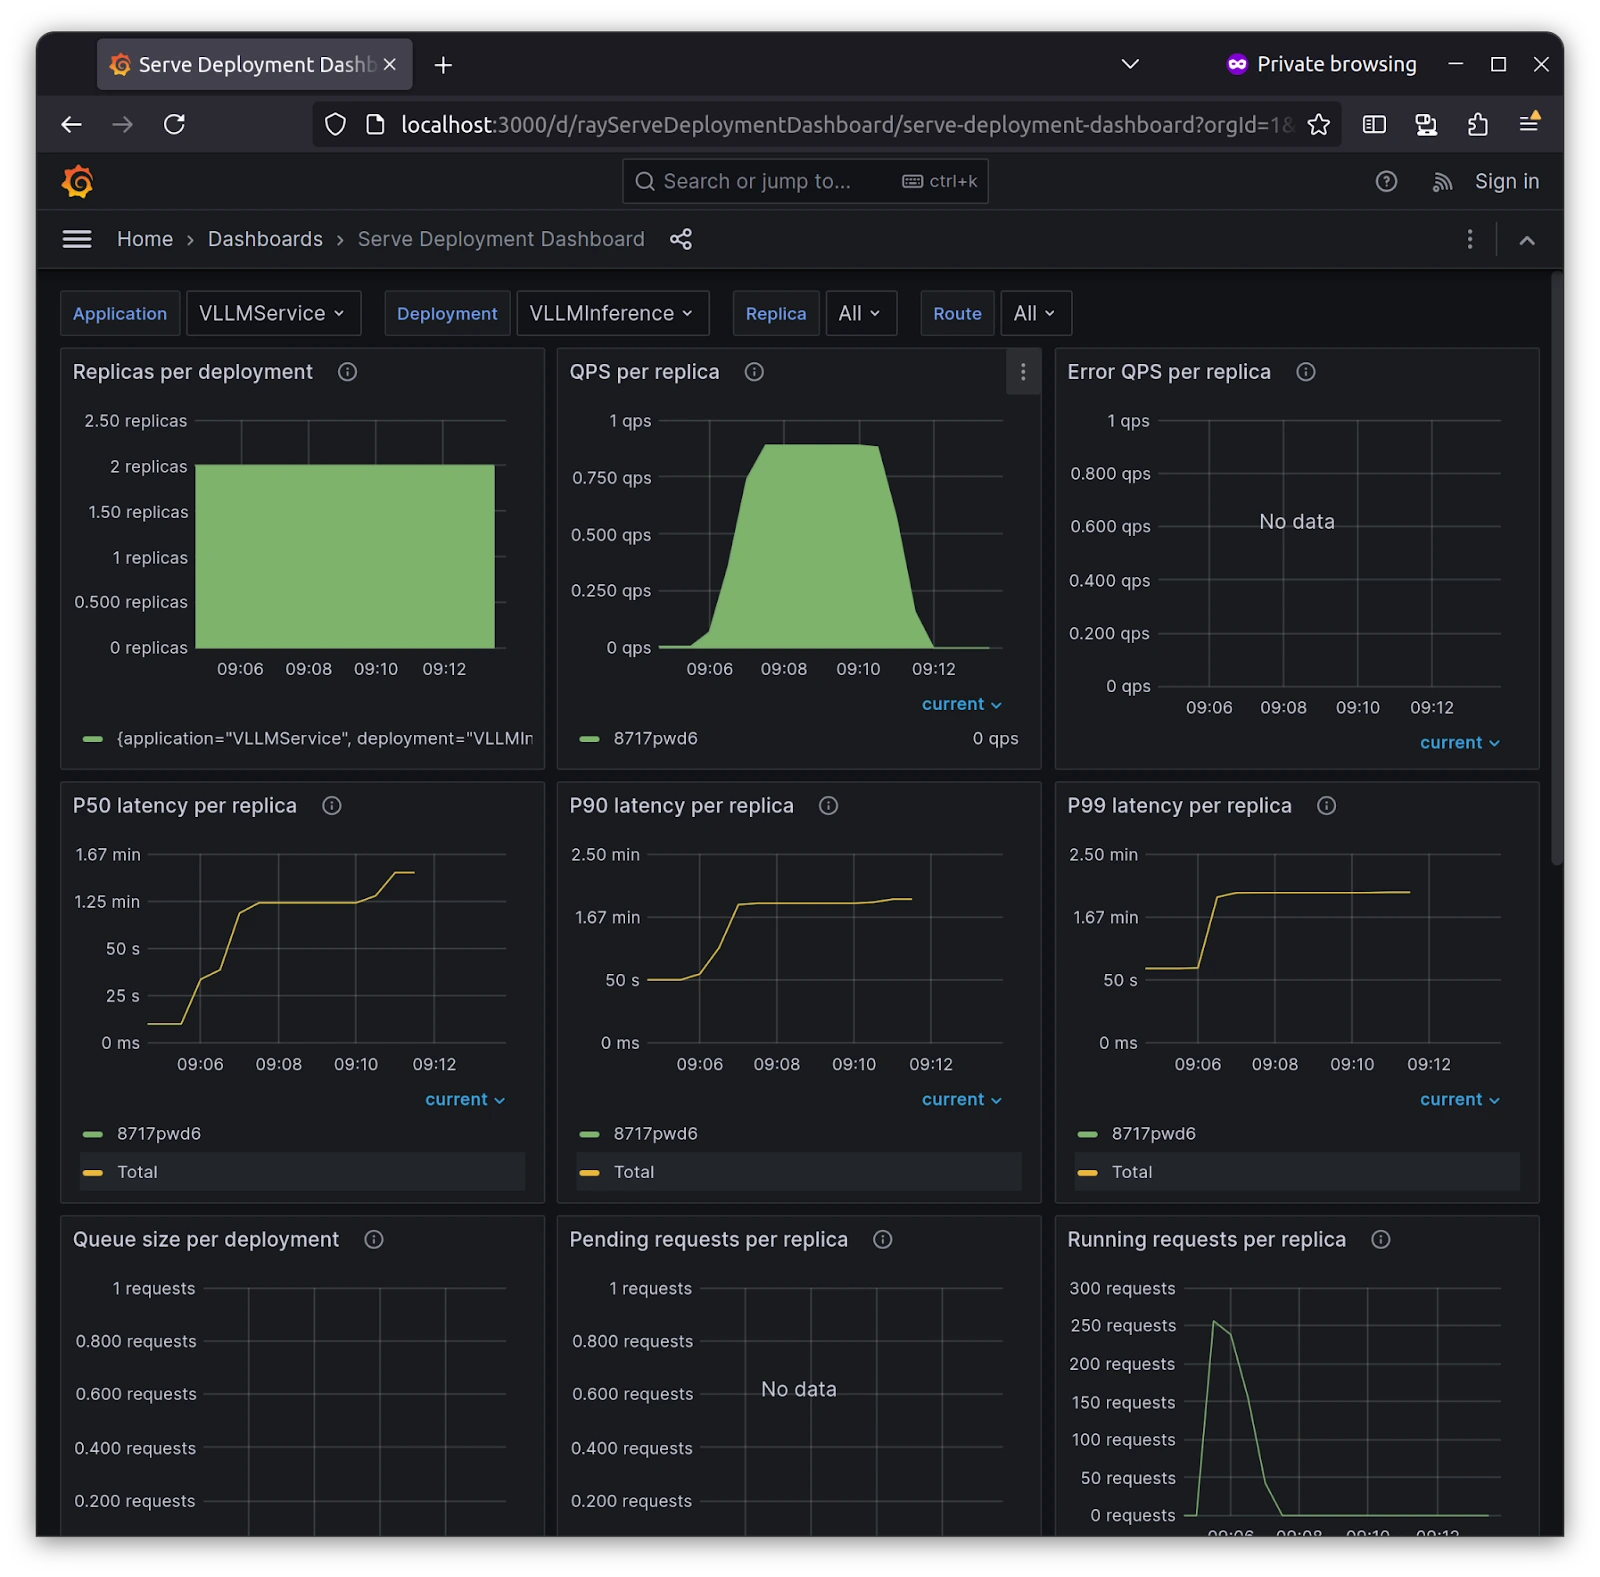
Running Phi 3 with vLLM and Ray Serve
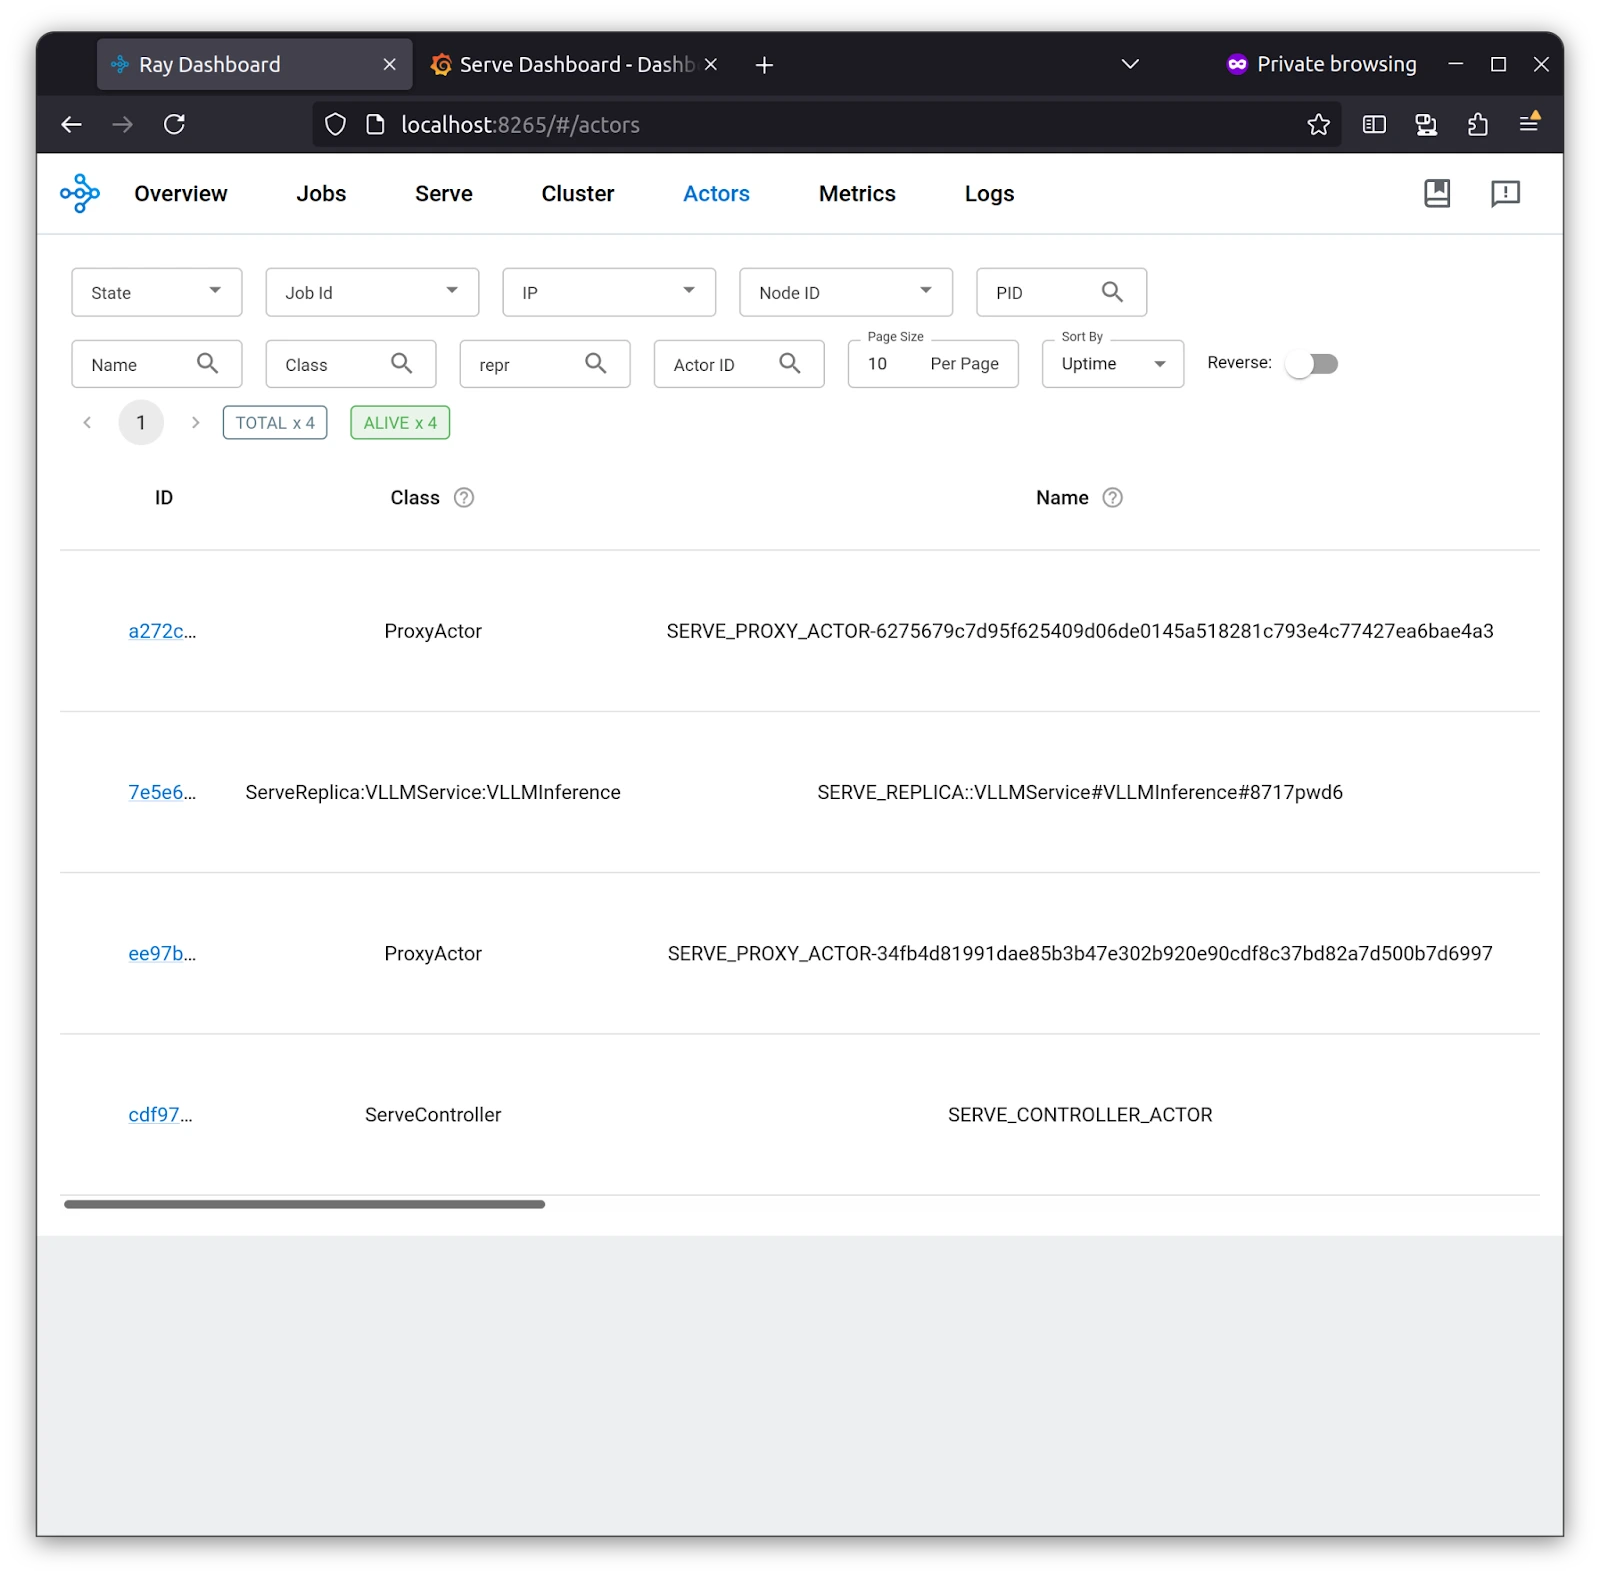
Running Phi 3 with vLLM and Ray Serve
[Usage]: VLLM + RAY encountered an error while executing the integrity ...
Fix: vLLM Not Working — CUDA OOM, Model Loading, and API Server Errors ...
Can't launch OpenAI API server on newly installed vLLM in Docker ...
[Misc]: Segmentation Fault in vLLM API Server during Model ...
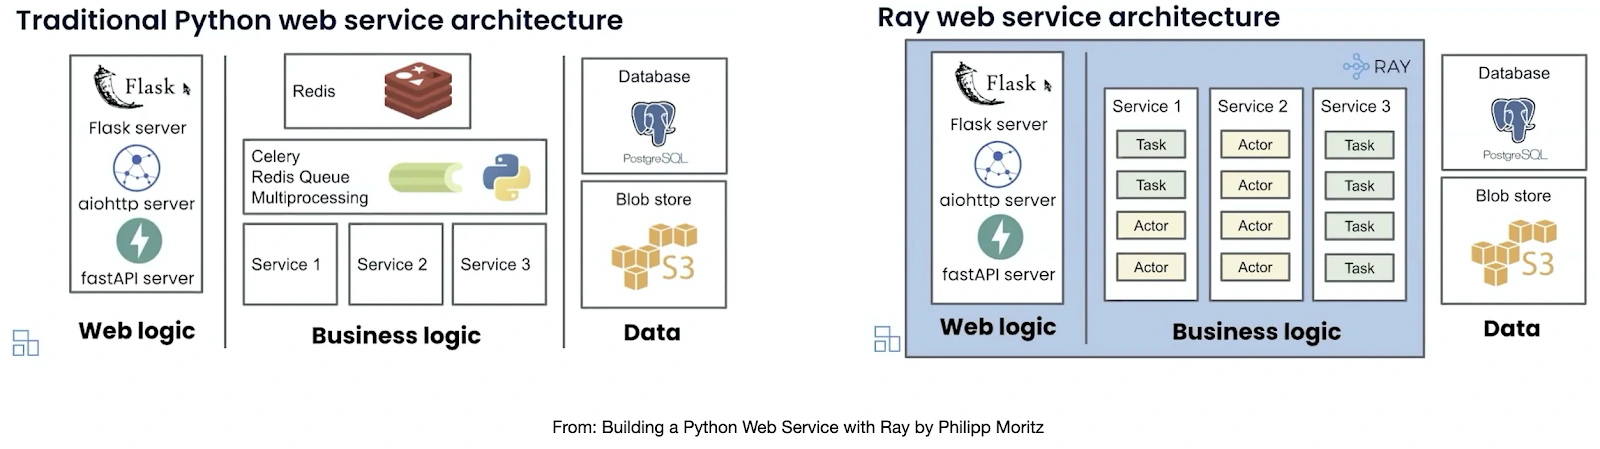
Running Phi 3 with vLLM and Ray Serve
openai.error.APIError: Invalid response object from API · Issue #1352 ...
[Bug]: vllm 0.8.3 serve error · Issue #15457 · vllm-project/vllm · GitHub
Advertisement Space (336x280)
RuntimeError: NVML_SUCCESS == DriverAPI::get() · Issue #2544 · vllm ...
[Bug]: "500 Internal Server Error" after upgrade to v0.5.4 · Issue ...
unable to run vllm model deployment · Issue #6464 · vllm-project/vllm ...
[Bug]: VLLM run very very slow in ARM cpu · Issue #10706 · vllm-project ...
[Installation]: vLLM does not work on old CPU · Issue #4542 · vllm ...
[Usage]: How to release GPU of vLLM model in python code · Issue #6544 ...