
Rllab Github
GitHub - rll/rllab: rllab is a framework for developing and evaluating ...

RLLAB · GitHub
GitHub - jfyao90/event-driven-rllab: Extending rllab to event-driven ...
Does RLLAB support joint angle constrain? · Issue #210 · rll/rllab · GitHub
GitHub - lerrel/rllab-adv: Code to train RL agents along with ...
GitHub - rllab-snu/Intelligent-Systems-Project
GitHub - rllab-snu/RNR-Map: Official Github repository for "Renderable ...

GitHub - thu-rllab/LaRe: [AAAI-25] Latent Reward: LLM-Empowered Credit ...

GitHub - thu-rllab/PDTS: [ICML 2025] Fast and Robust: Task Sampling ...

Adversarial Environment Design via Regret-Guided Diffusion Models | RLLAB
Advertisement Space (300x250)
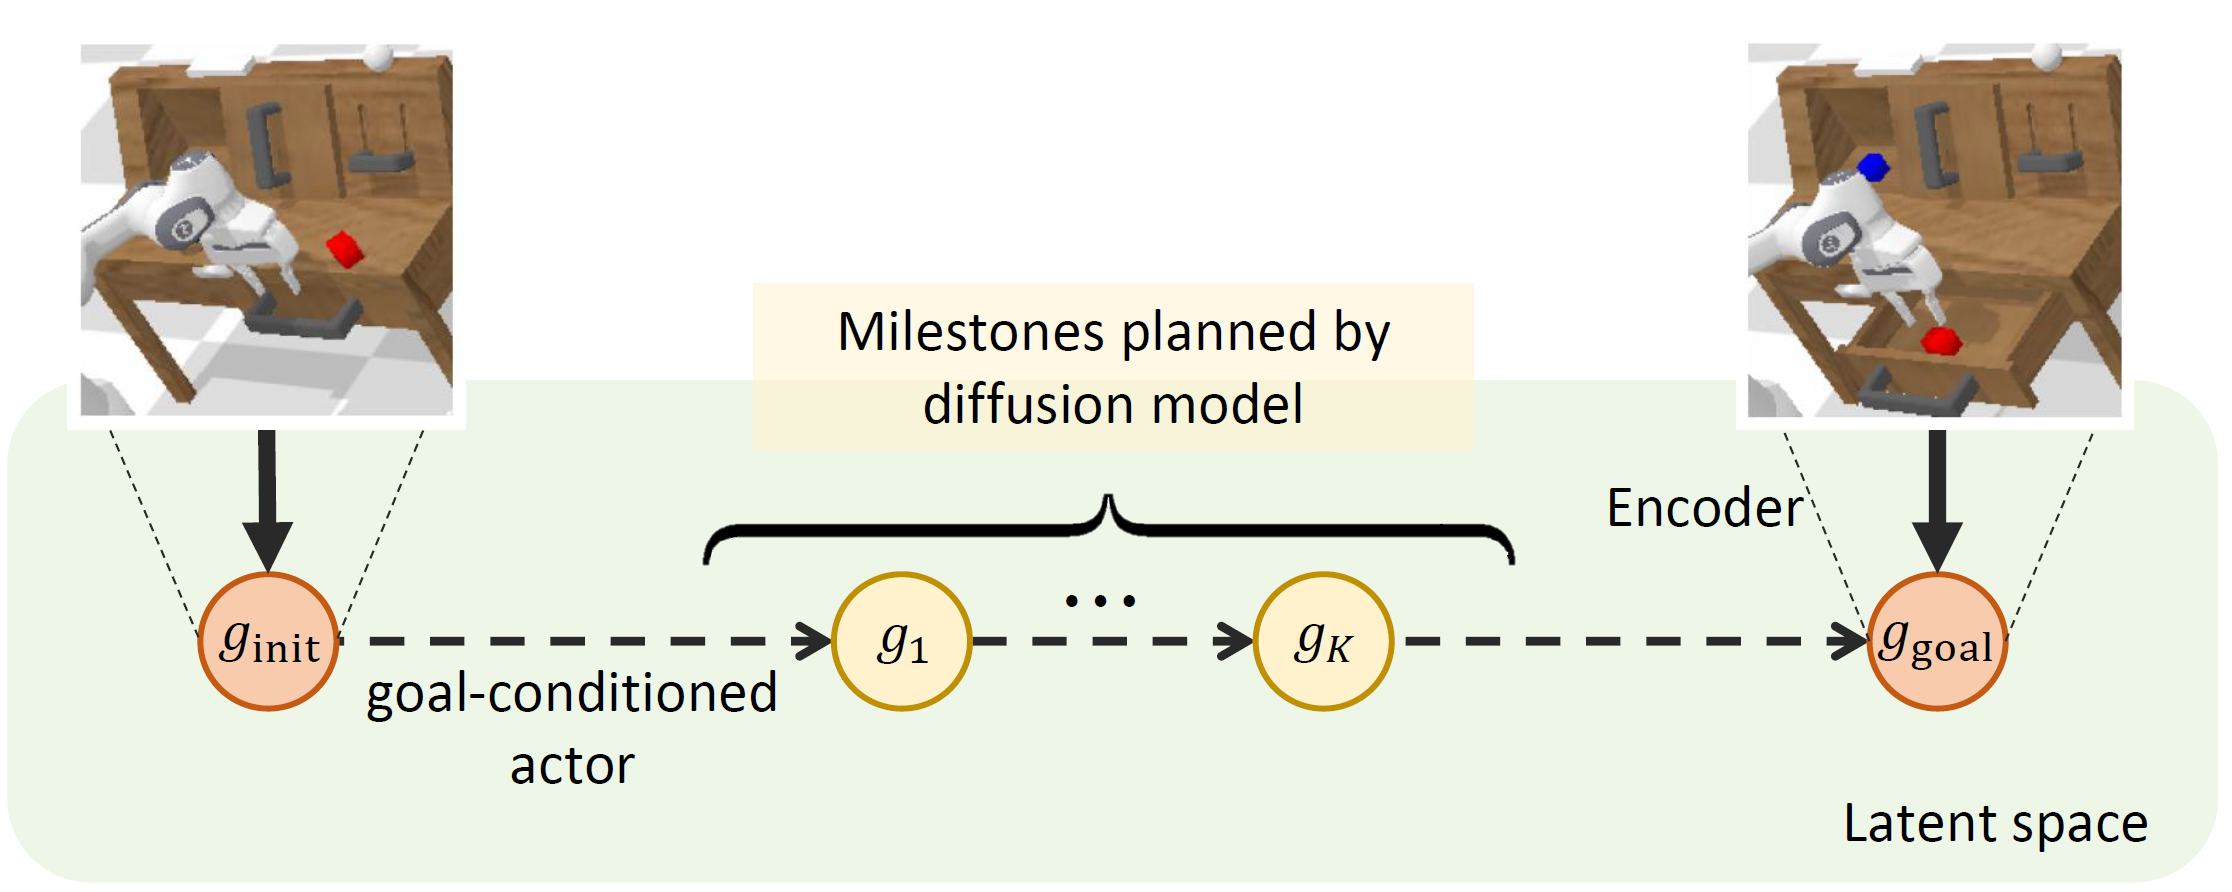
Diffused Task-Agnostic Milestone Planner | RLLAB

GitHub - thu-rllab/MPTS: Model Predictive Task Sampling · GitHub

rllab-postech repositories · GitHub
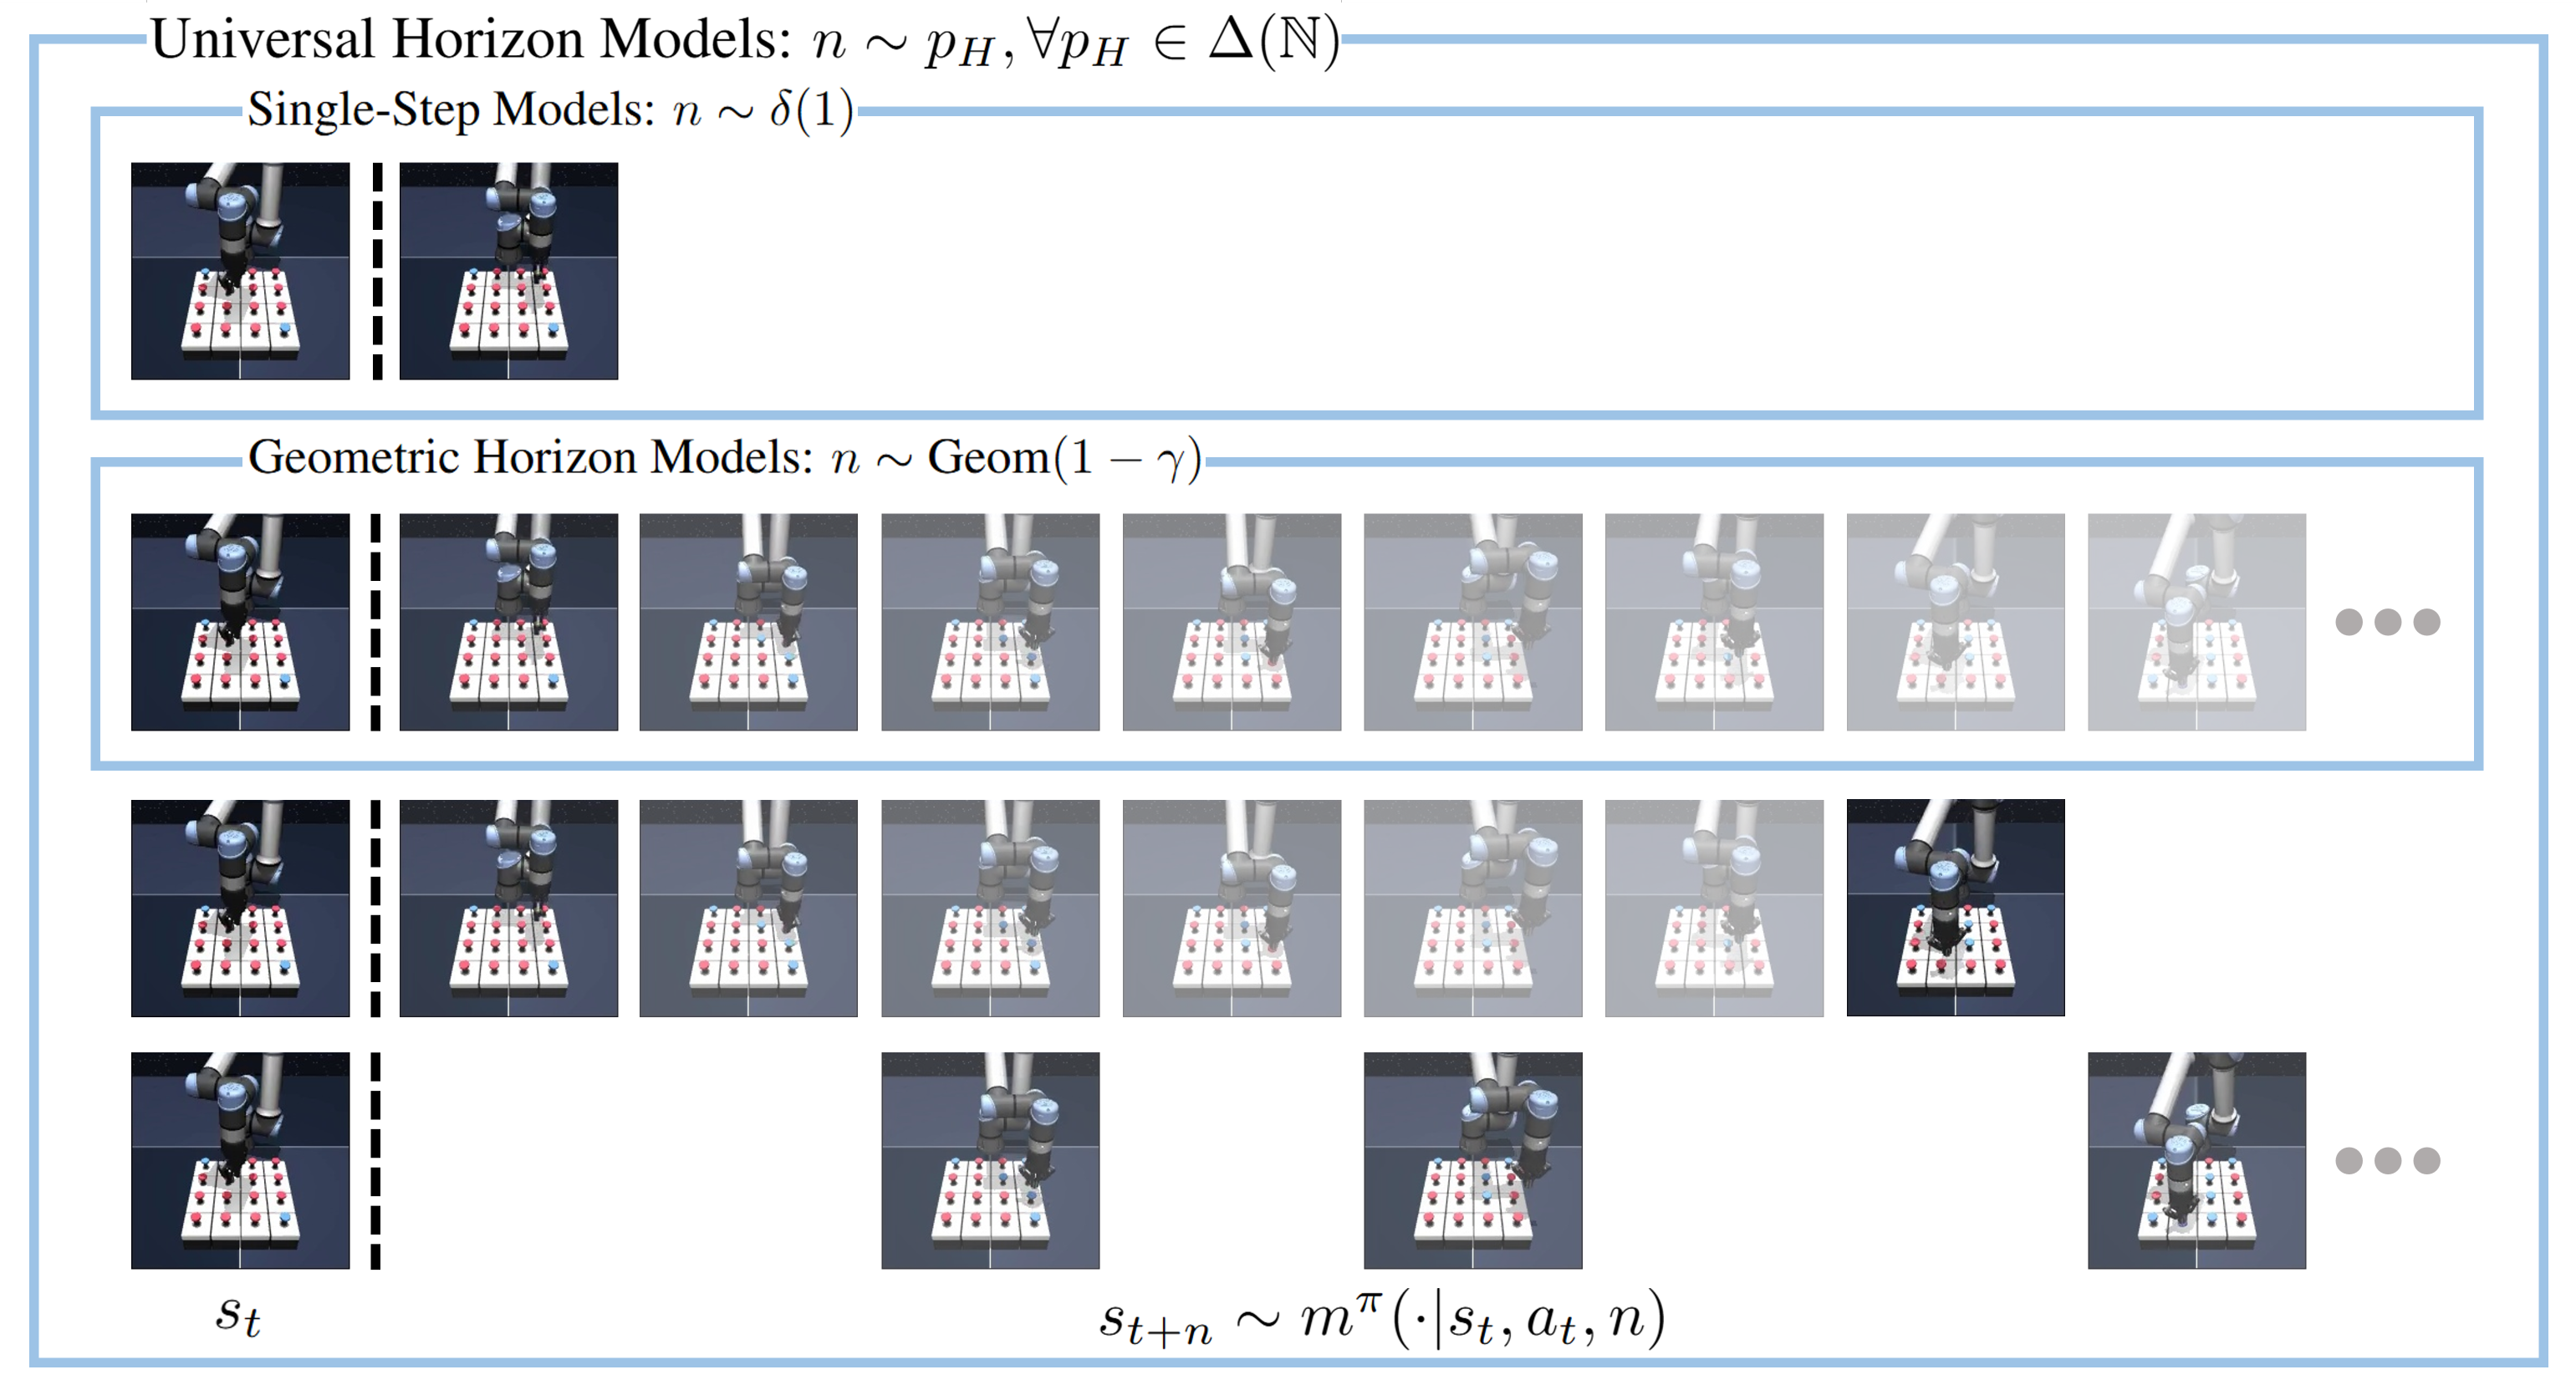
Offline Reinforcement Learning with Universal Horizon Models | RLLAB

Adversarial Environment Design via Regret-Guided Diffusion Models | RLLAB
rllab by rll - SourcePulse
GitHub - hybug/RL_Lab: reinforcement learning alogrithm implement with ...
GitHub - NeuralBind/R-LAB: Intro to R, Stat-tests and plotting LAB ...
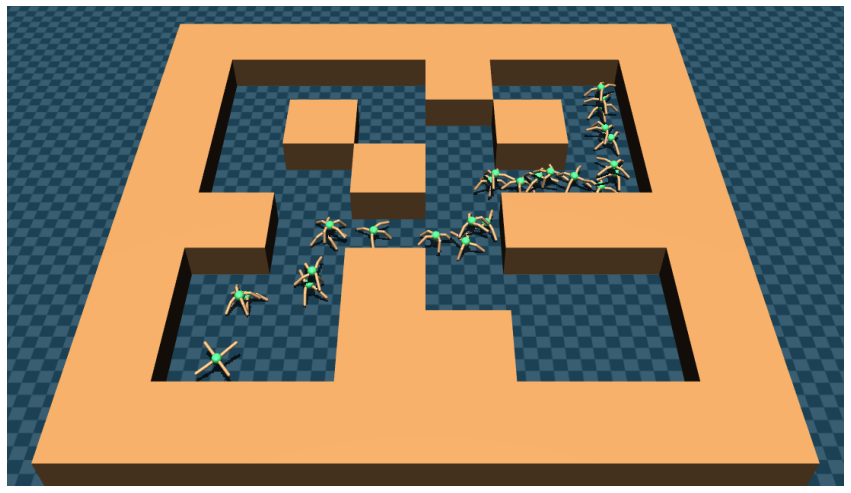
Diffused Task-Agnostic Milestone Planner | RLLAB
GitHub - RobolabGs2/AI_RL_Lab_01: Заготовка для лабораторной работы по ...
Advertisement Space (336x280)
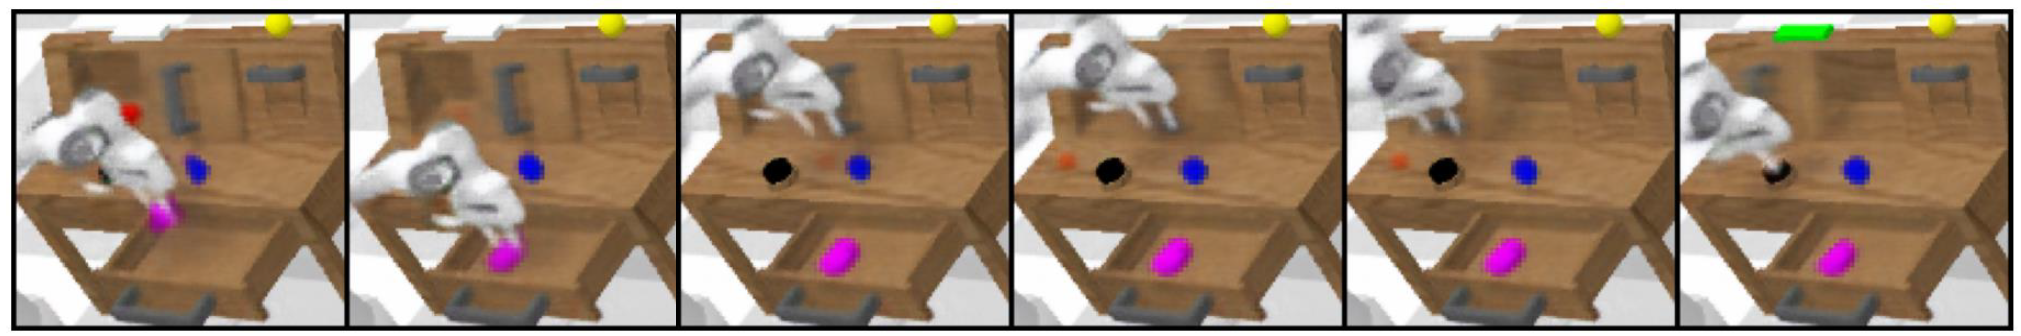
Diffused Task-Agnostic Milestone Planner | RLLAB

GitHub - rllab-snu/RNR-Map: Official Github repository for "Renderable ...
GitHub - rlglab/rlg-tutorial: Tutorials for reinforcement learning in games

RLLab (RLLab)
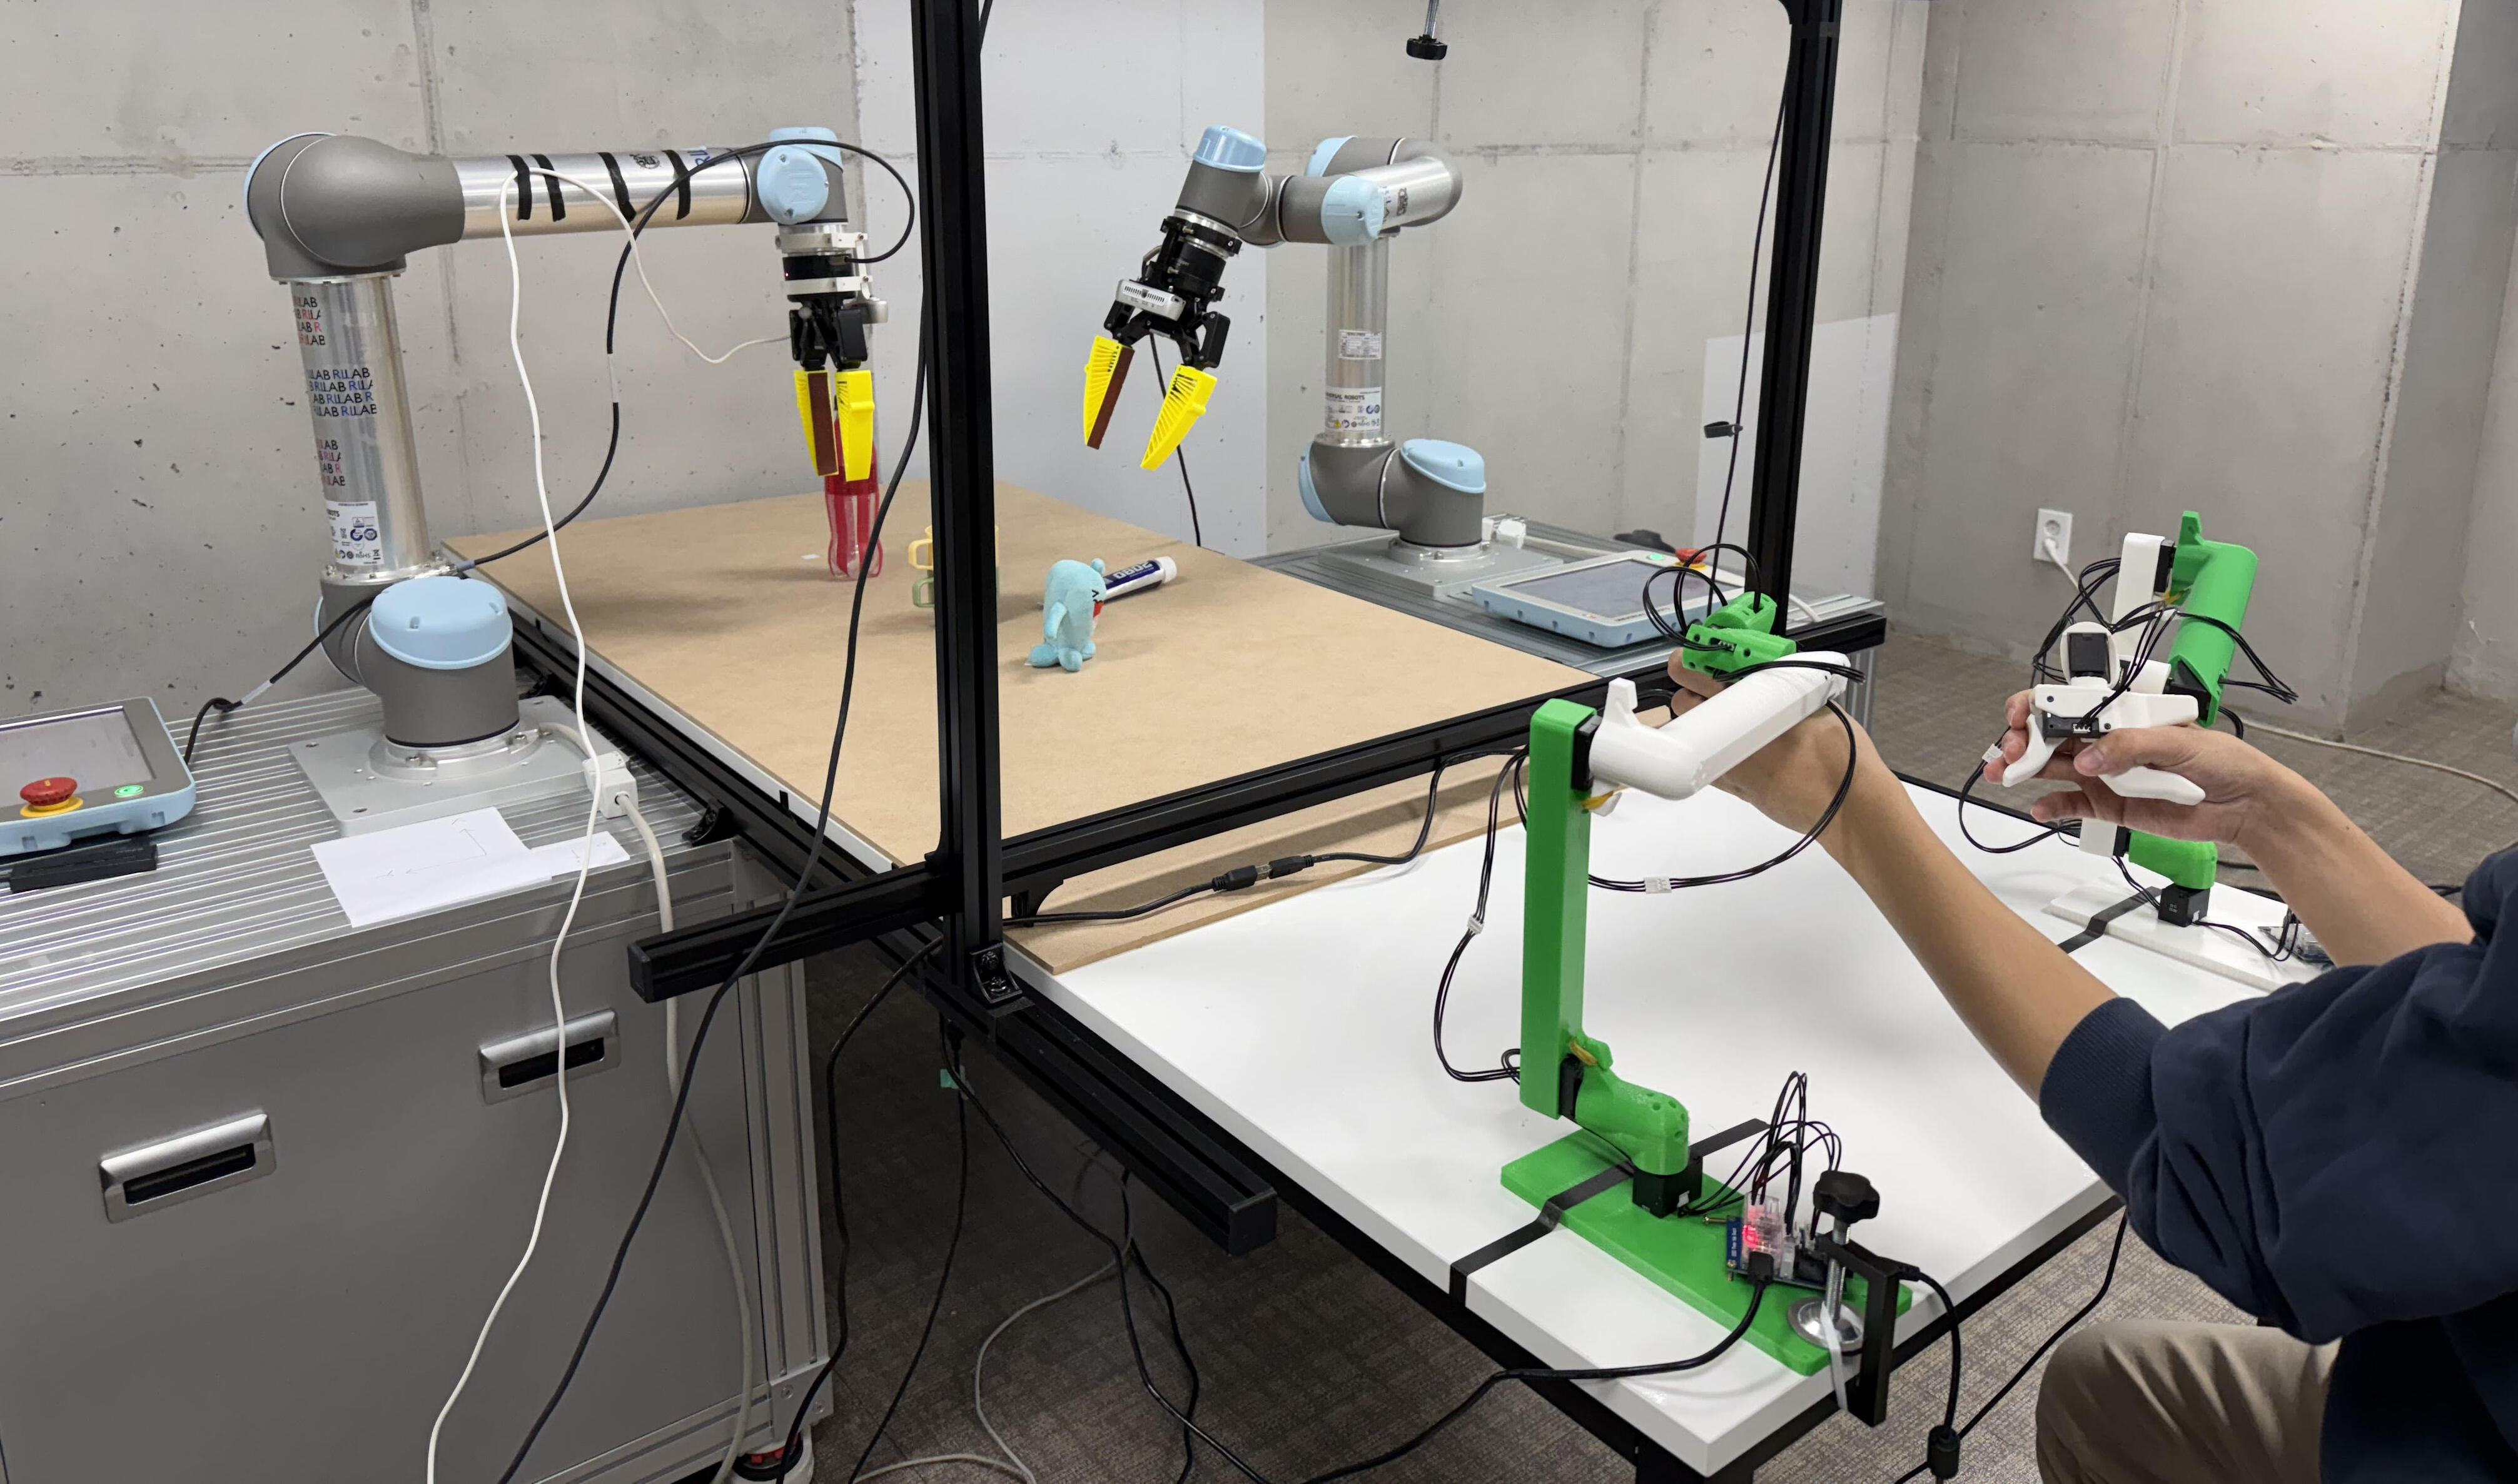
Home | RLLAB
Would like to contribute to openAI/rllab · Issue #154 · rll/rllab · GitHub

Adversarial Environment Design via Regret-Guided Diffusion Models | RLLAB
MetaIRL/rllab/README.md at master · ermongroup/MetaIRL · GitHub
Software from RLLAB

GitHub - rllab-snu/R3-Driving-Dataset
Advertisement Space (336x280)
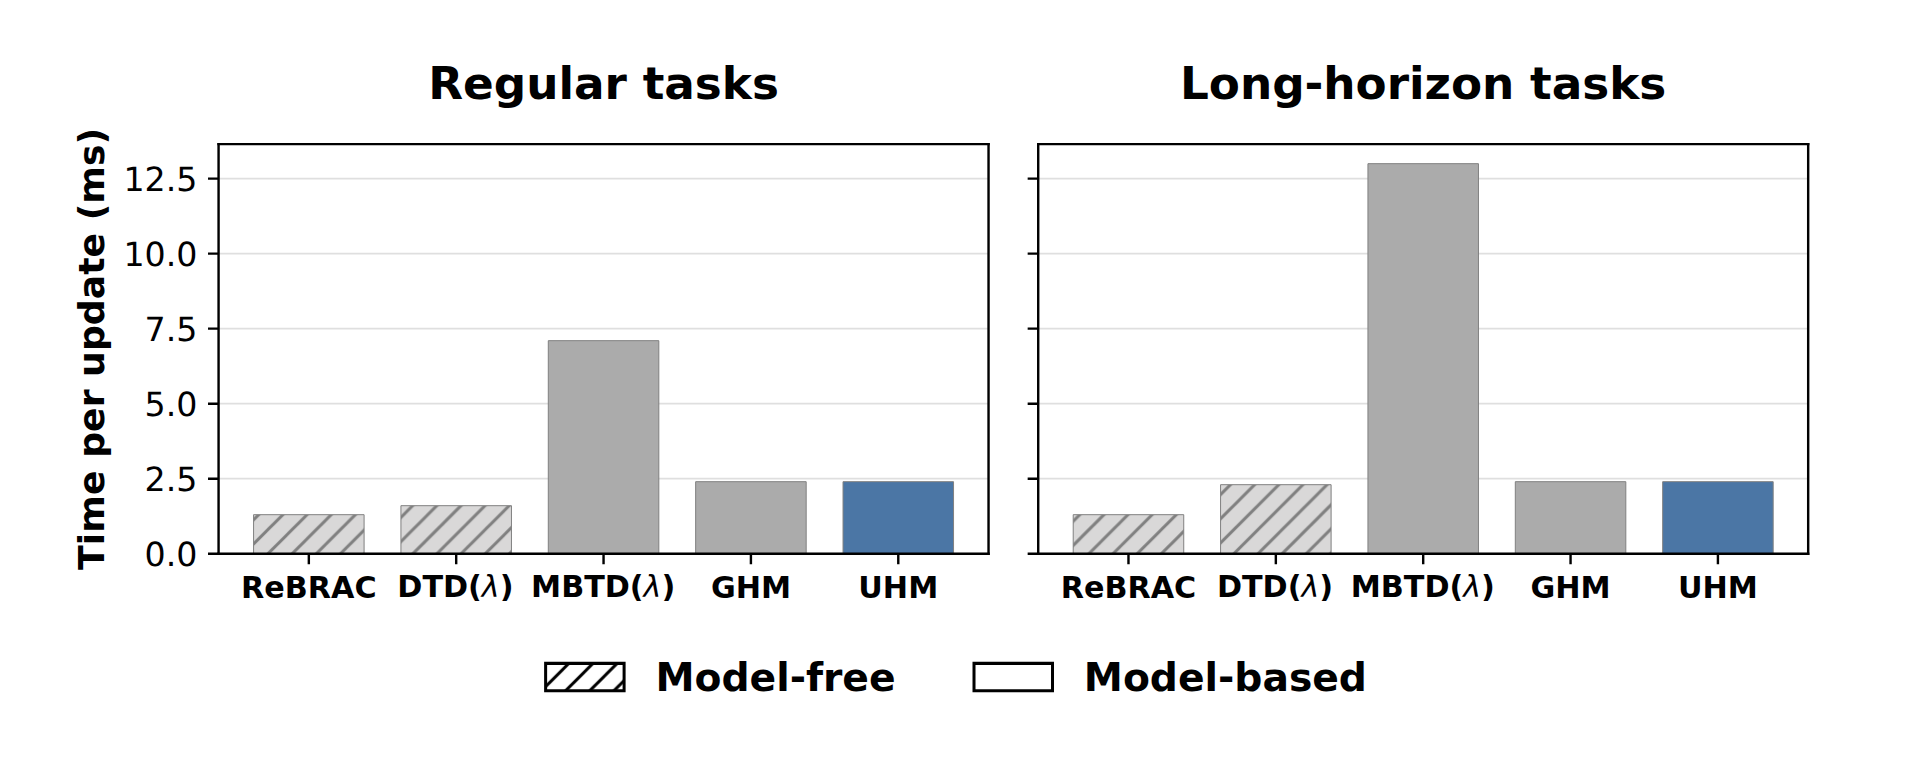
Offline Reinforcement Learning with Universal Horizon Models | RLLAB

rllab-humanoid · GitHub
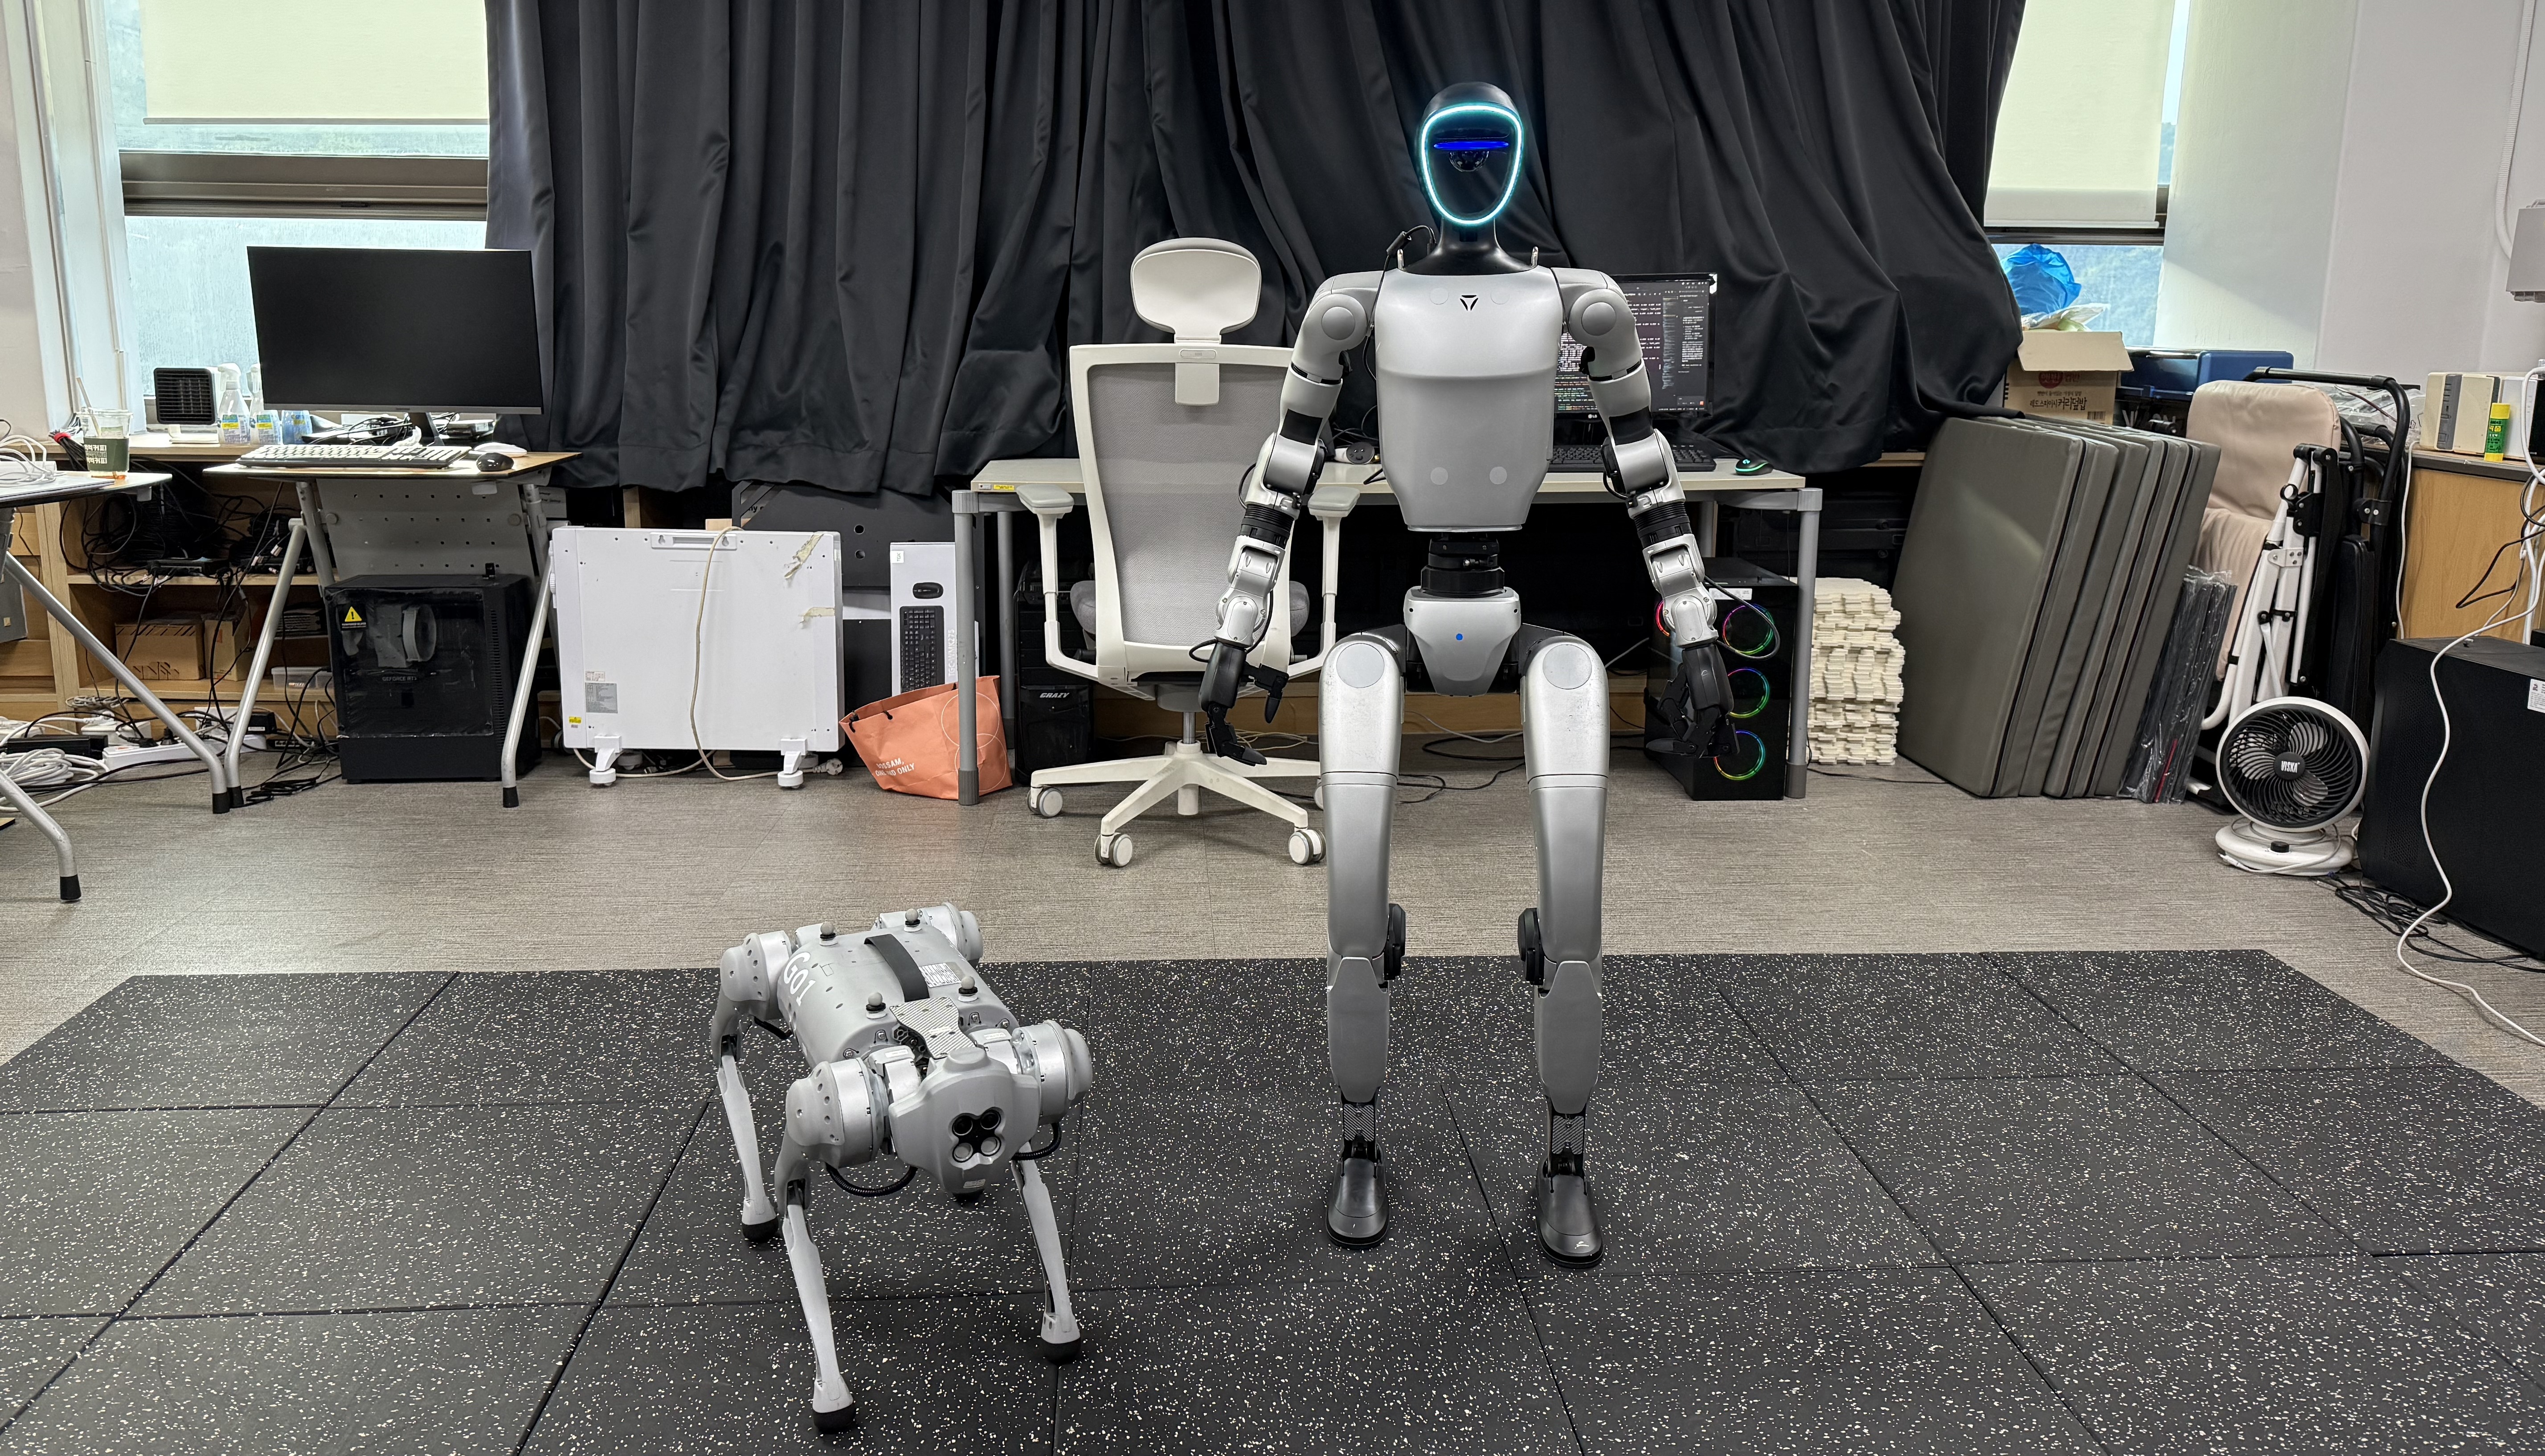
Home | RLLAB
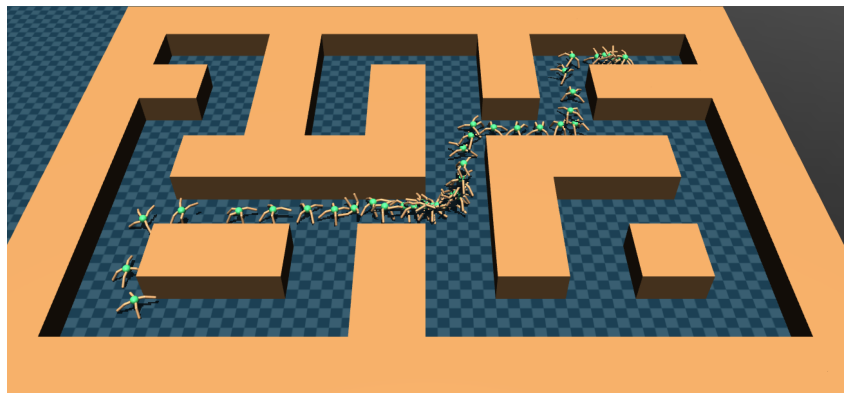
Diffused Task-Agnostic Milestone Planner | RLLAB
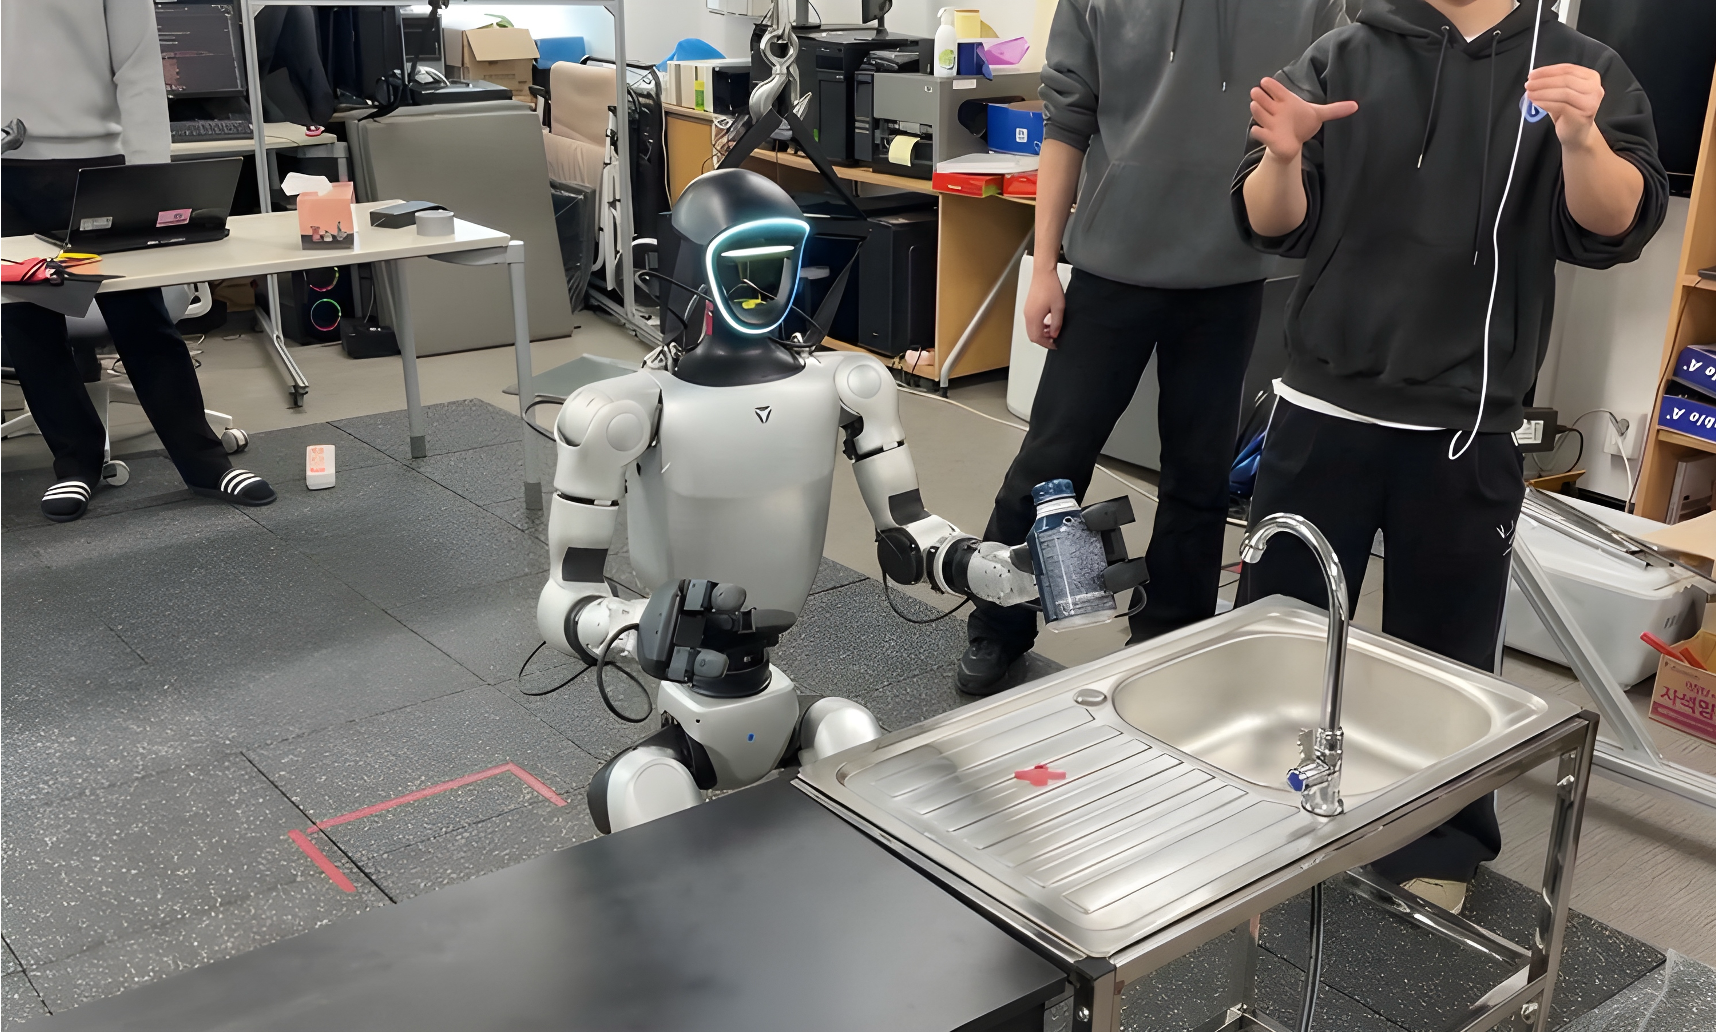
Home | RLLAB
GitHub - Accelemate/RayRLEnvLab: Customize your reinforcement learning ...