
Runtime Draft Model Training Adapting Speculative Decoding To Real
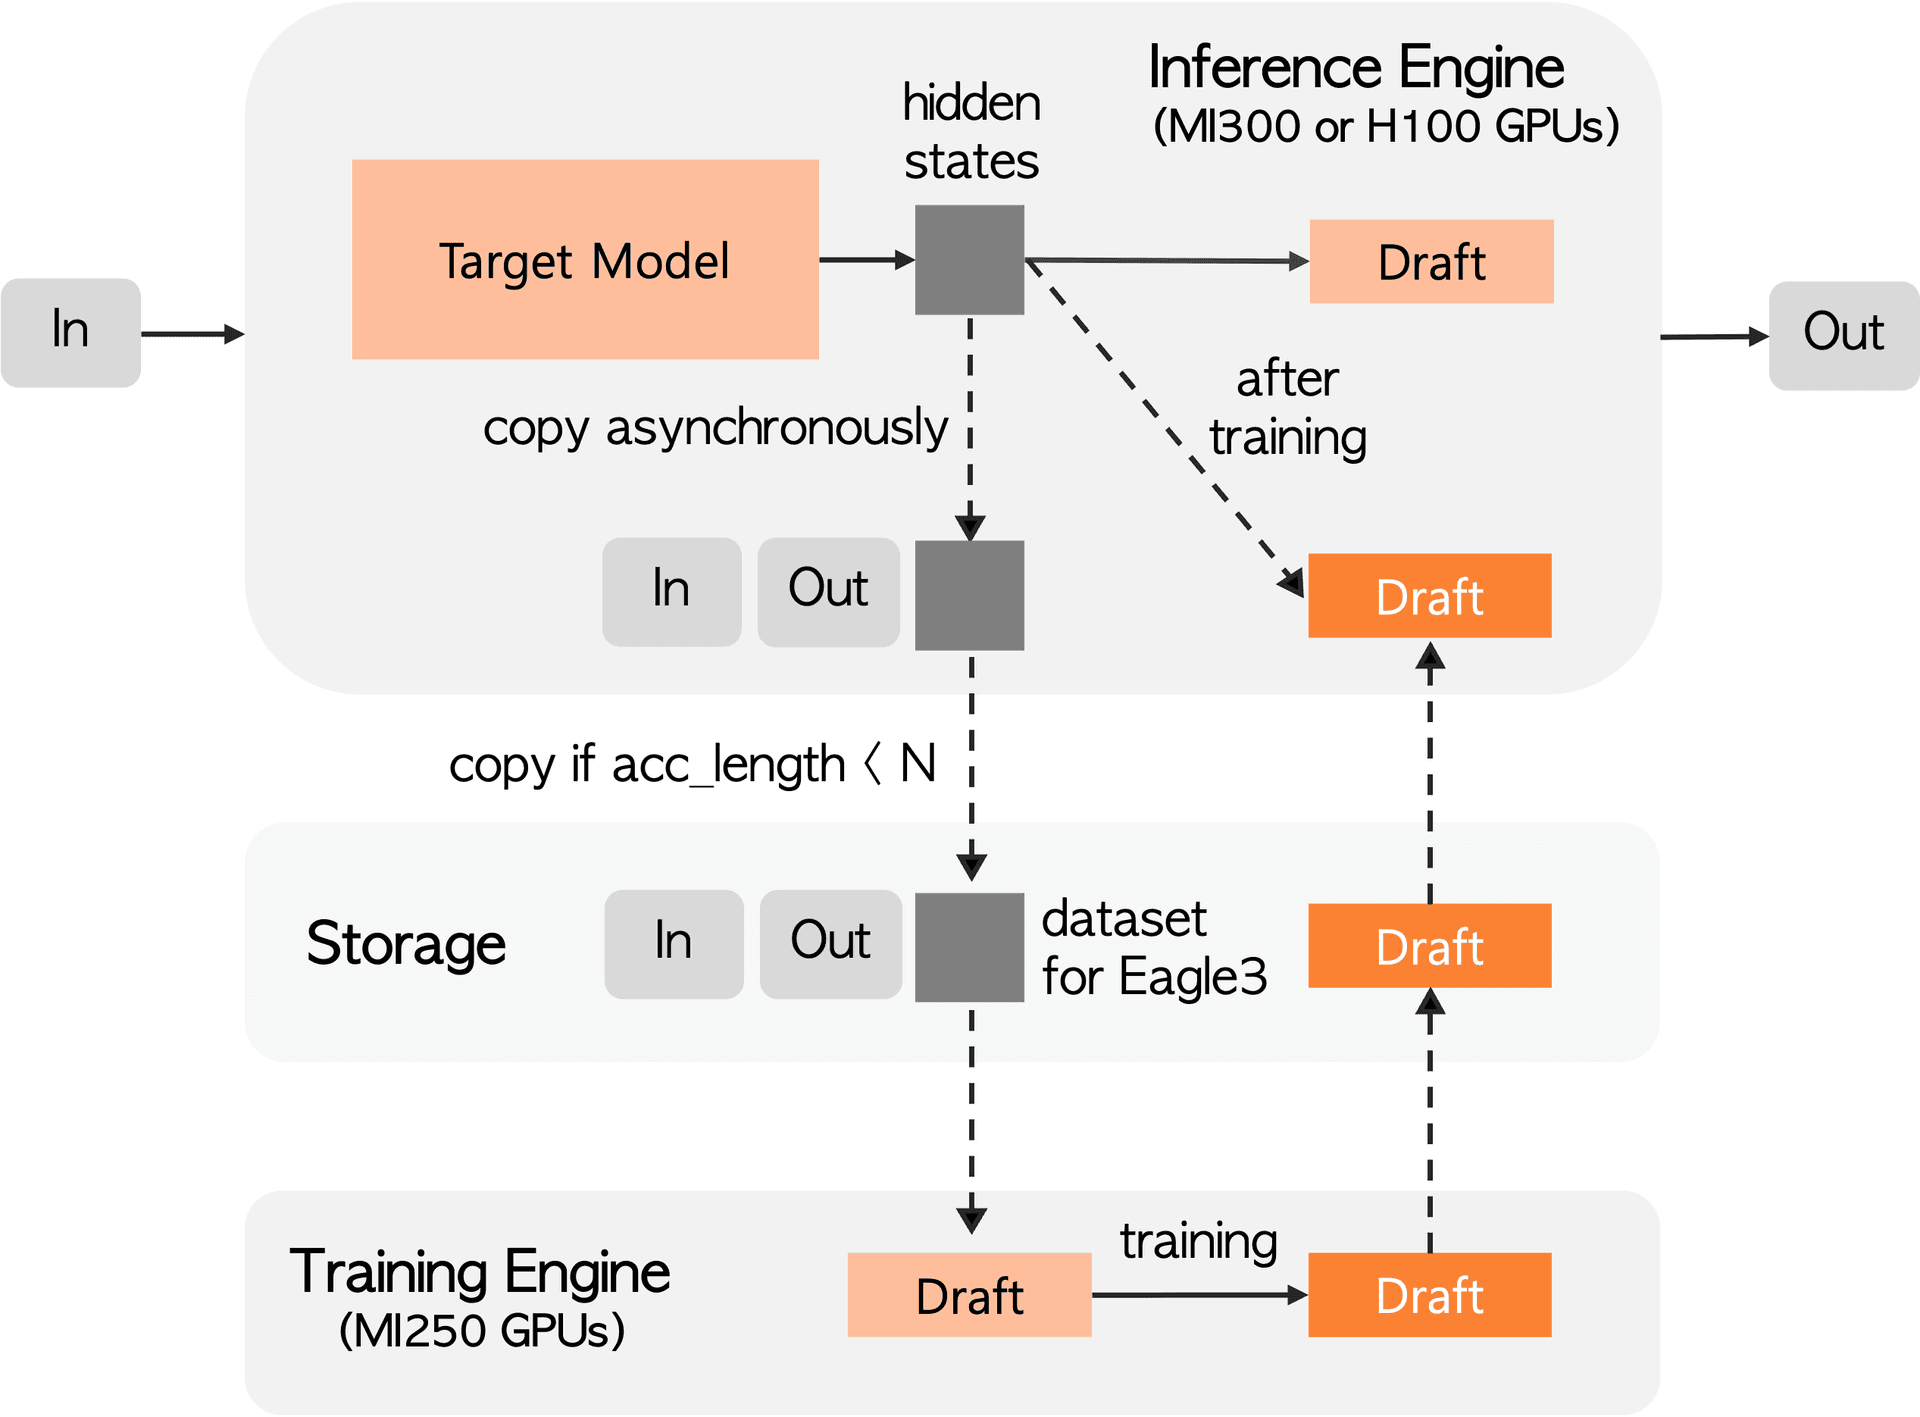
Runtime Draft Model Training: Adapting Speculative Decoding to Real ...
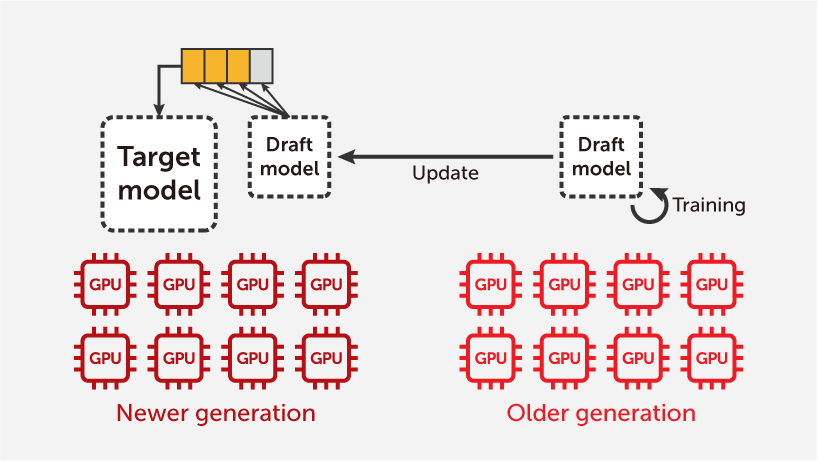
Runtime Draft Model Training: Adapting Speculative Decoding to Real ...
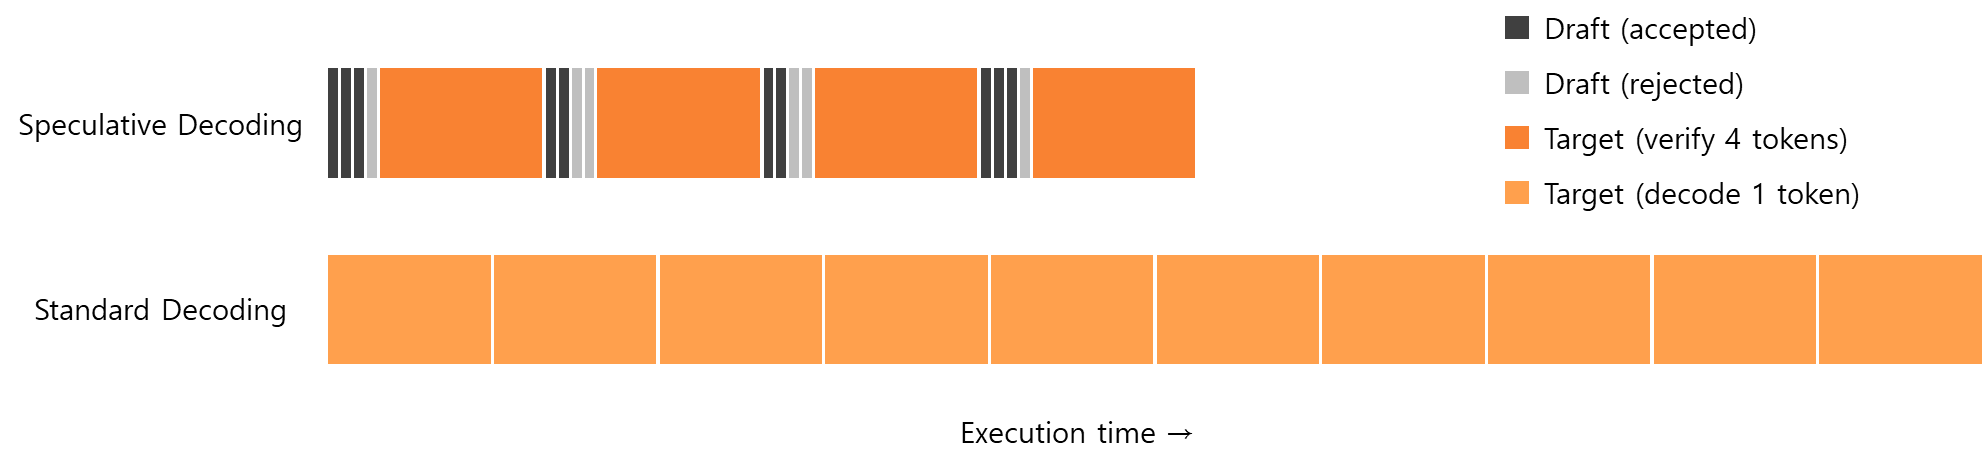
Runtime Draft Model Training: Adapting Speculative Decoding to Real ...
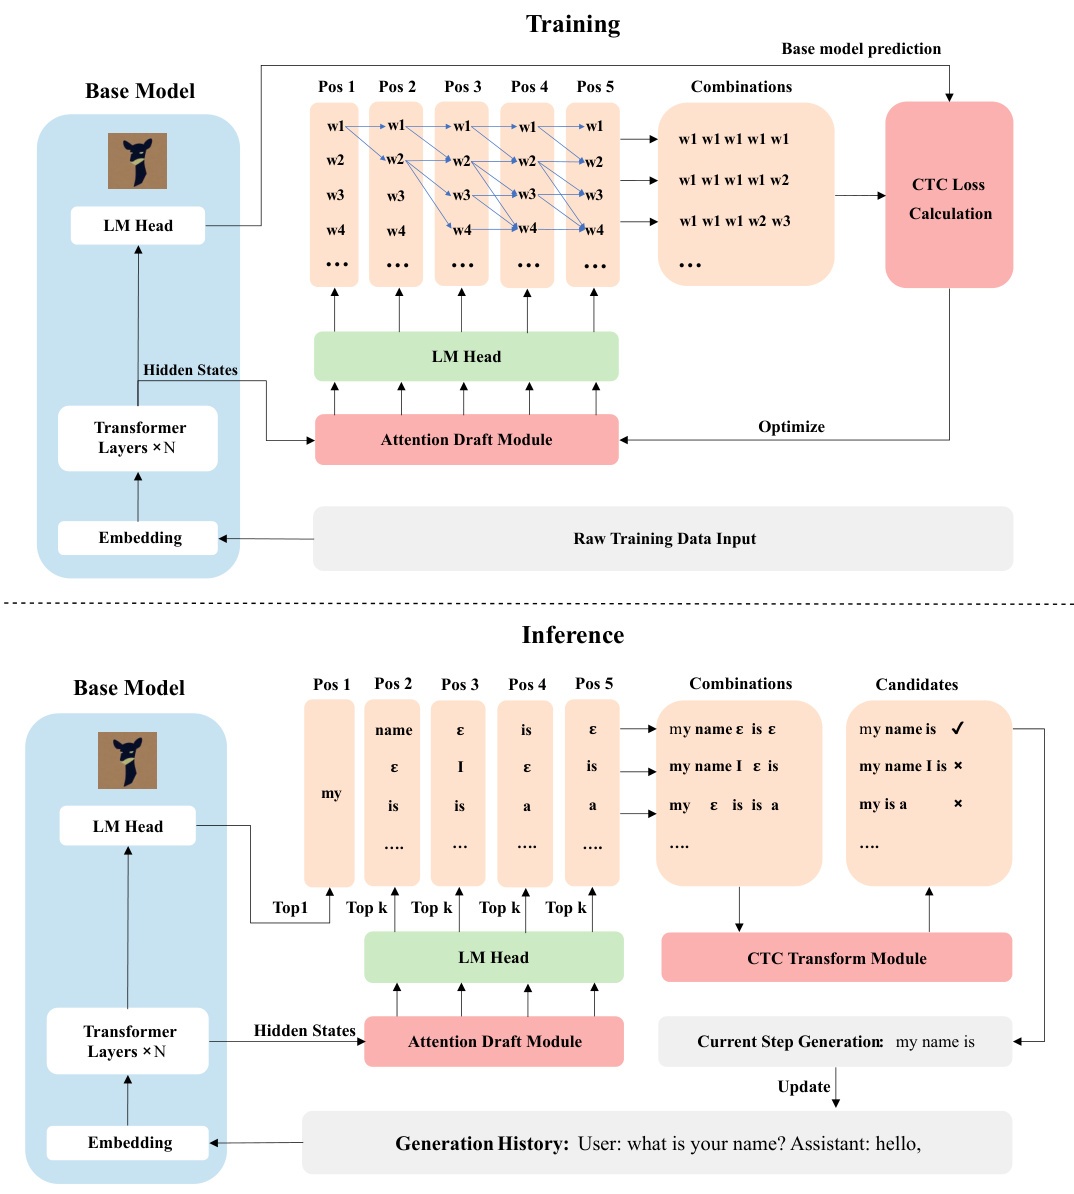
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
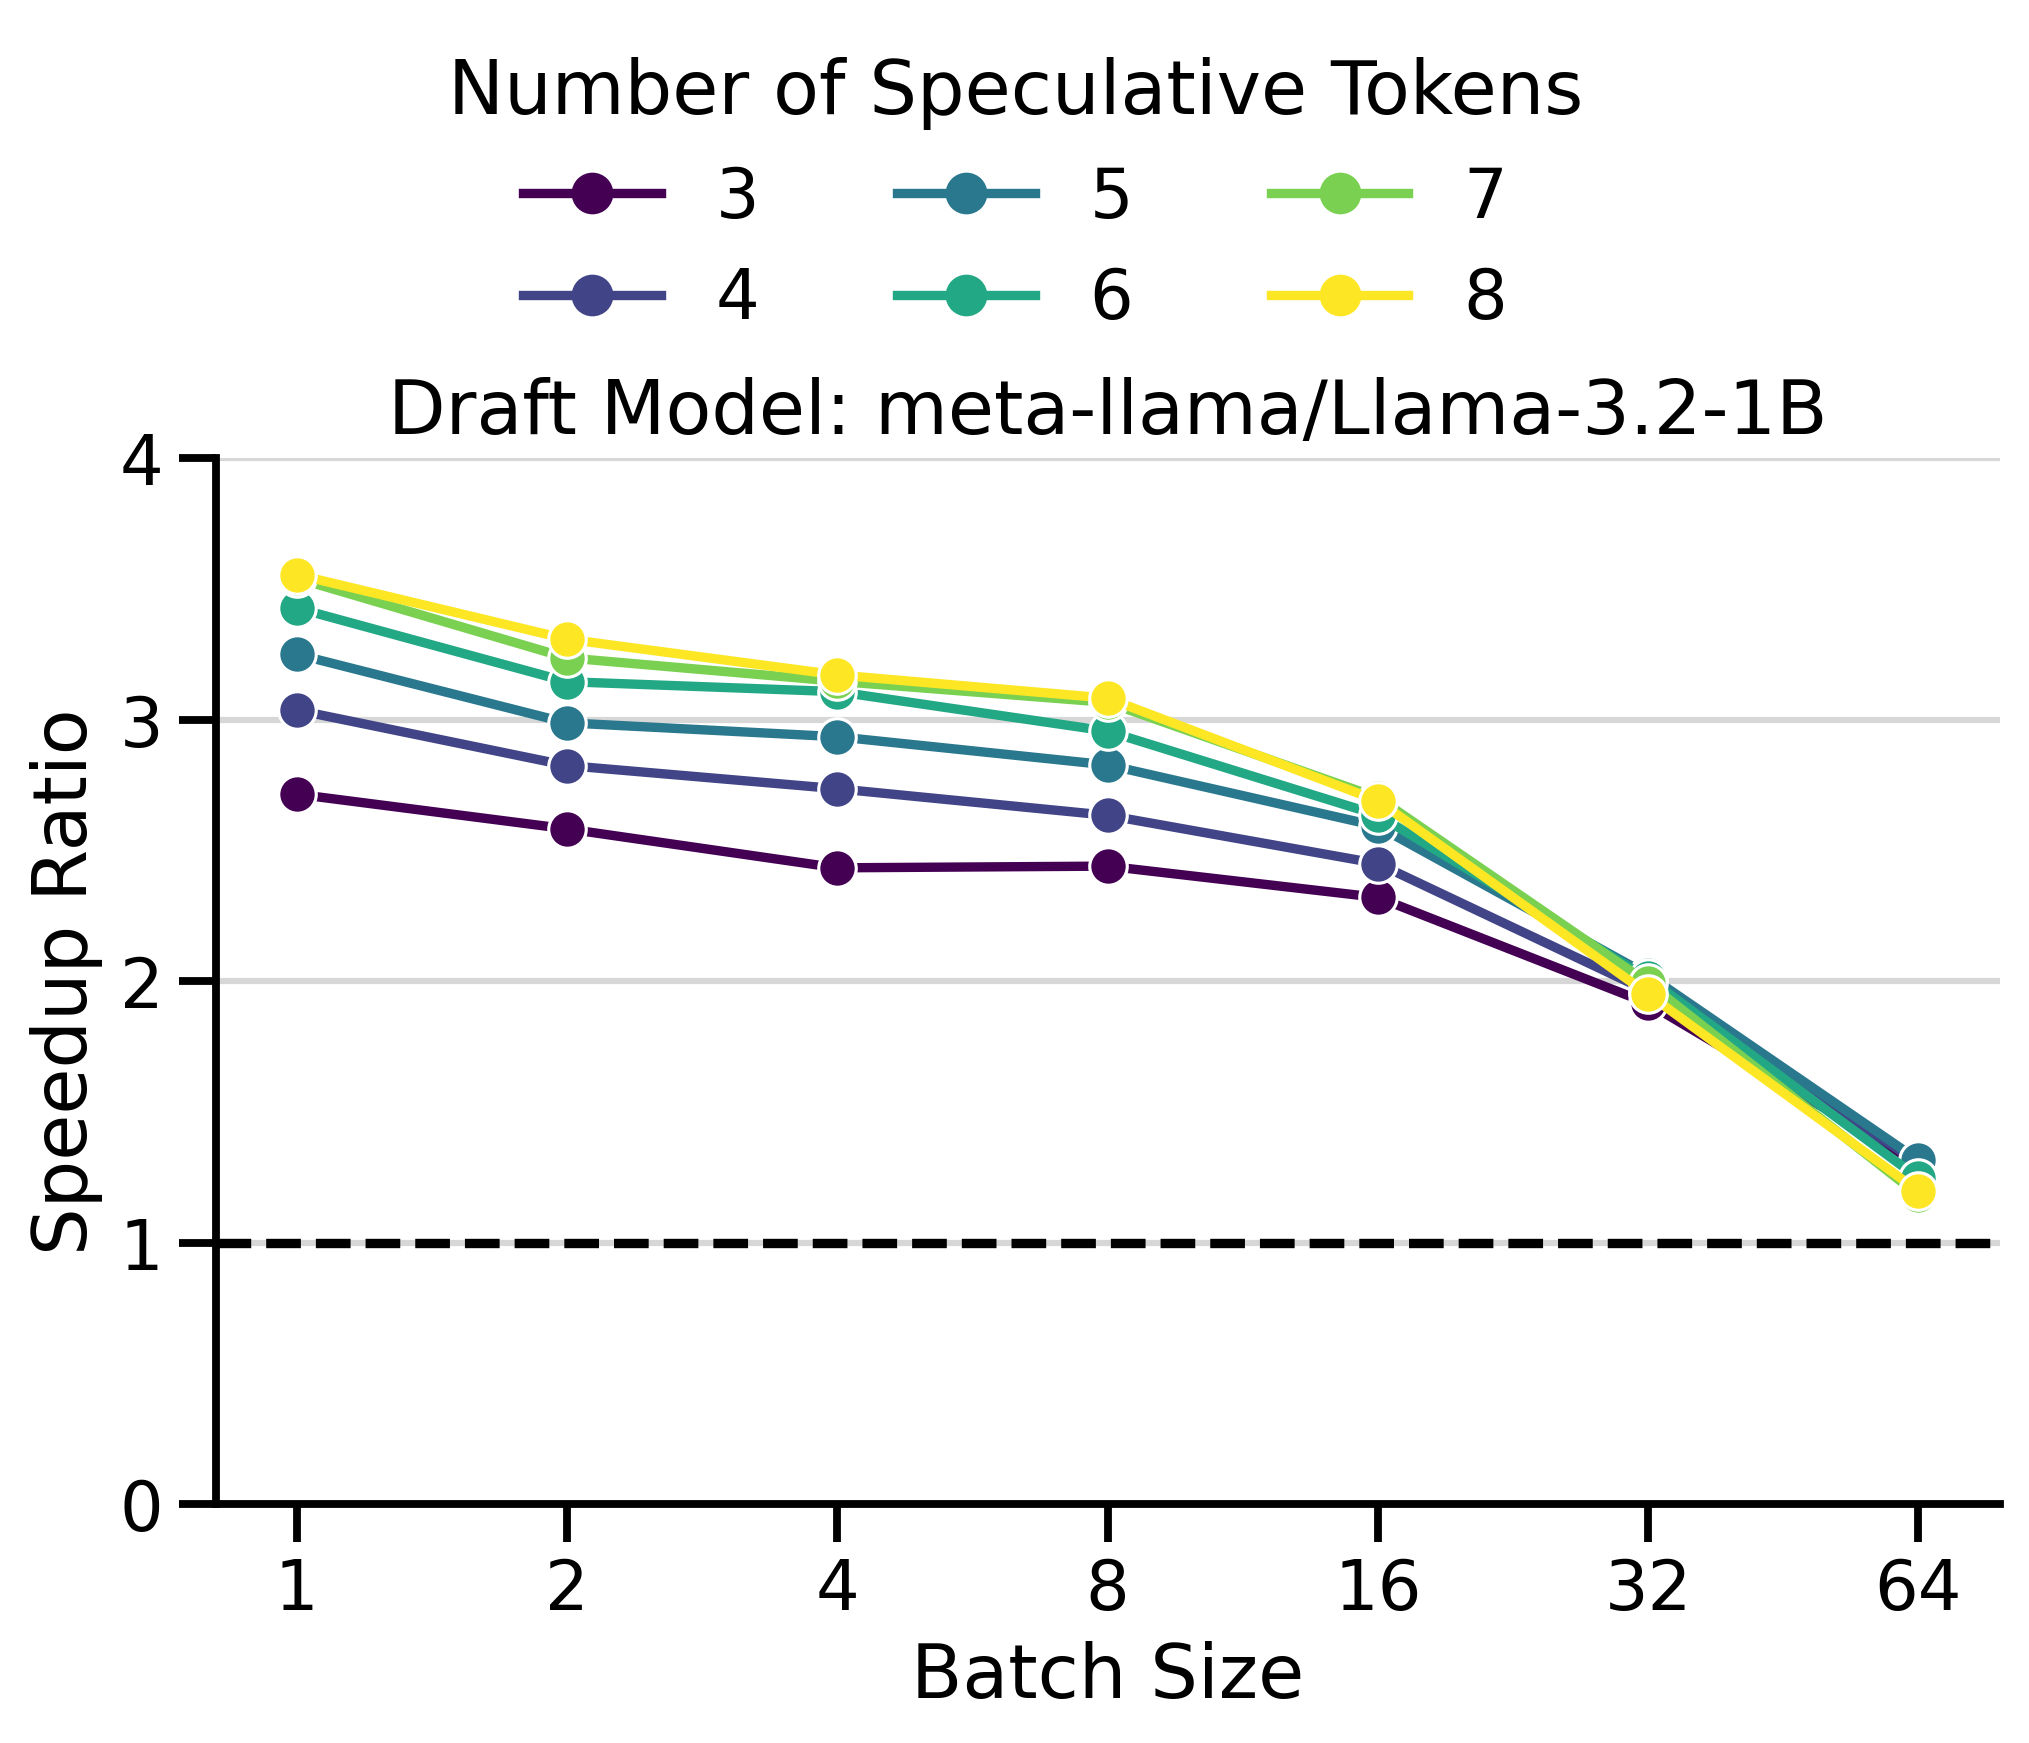
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...
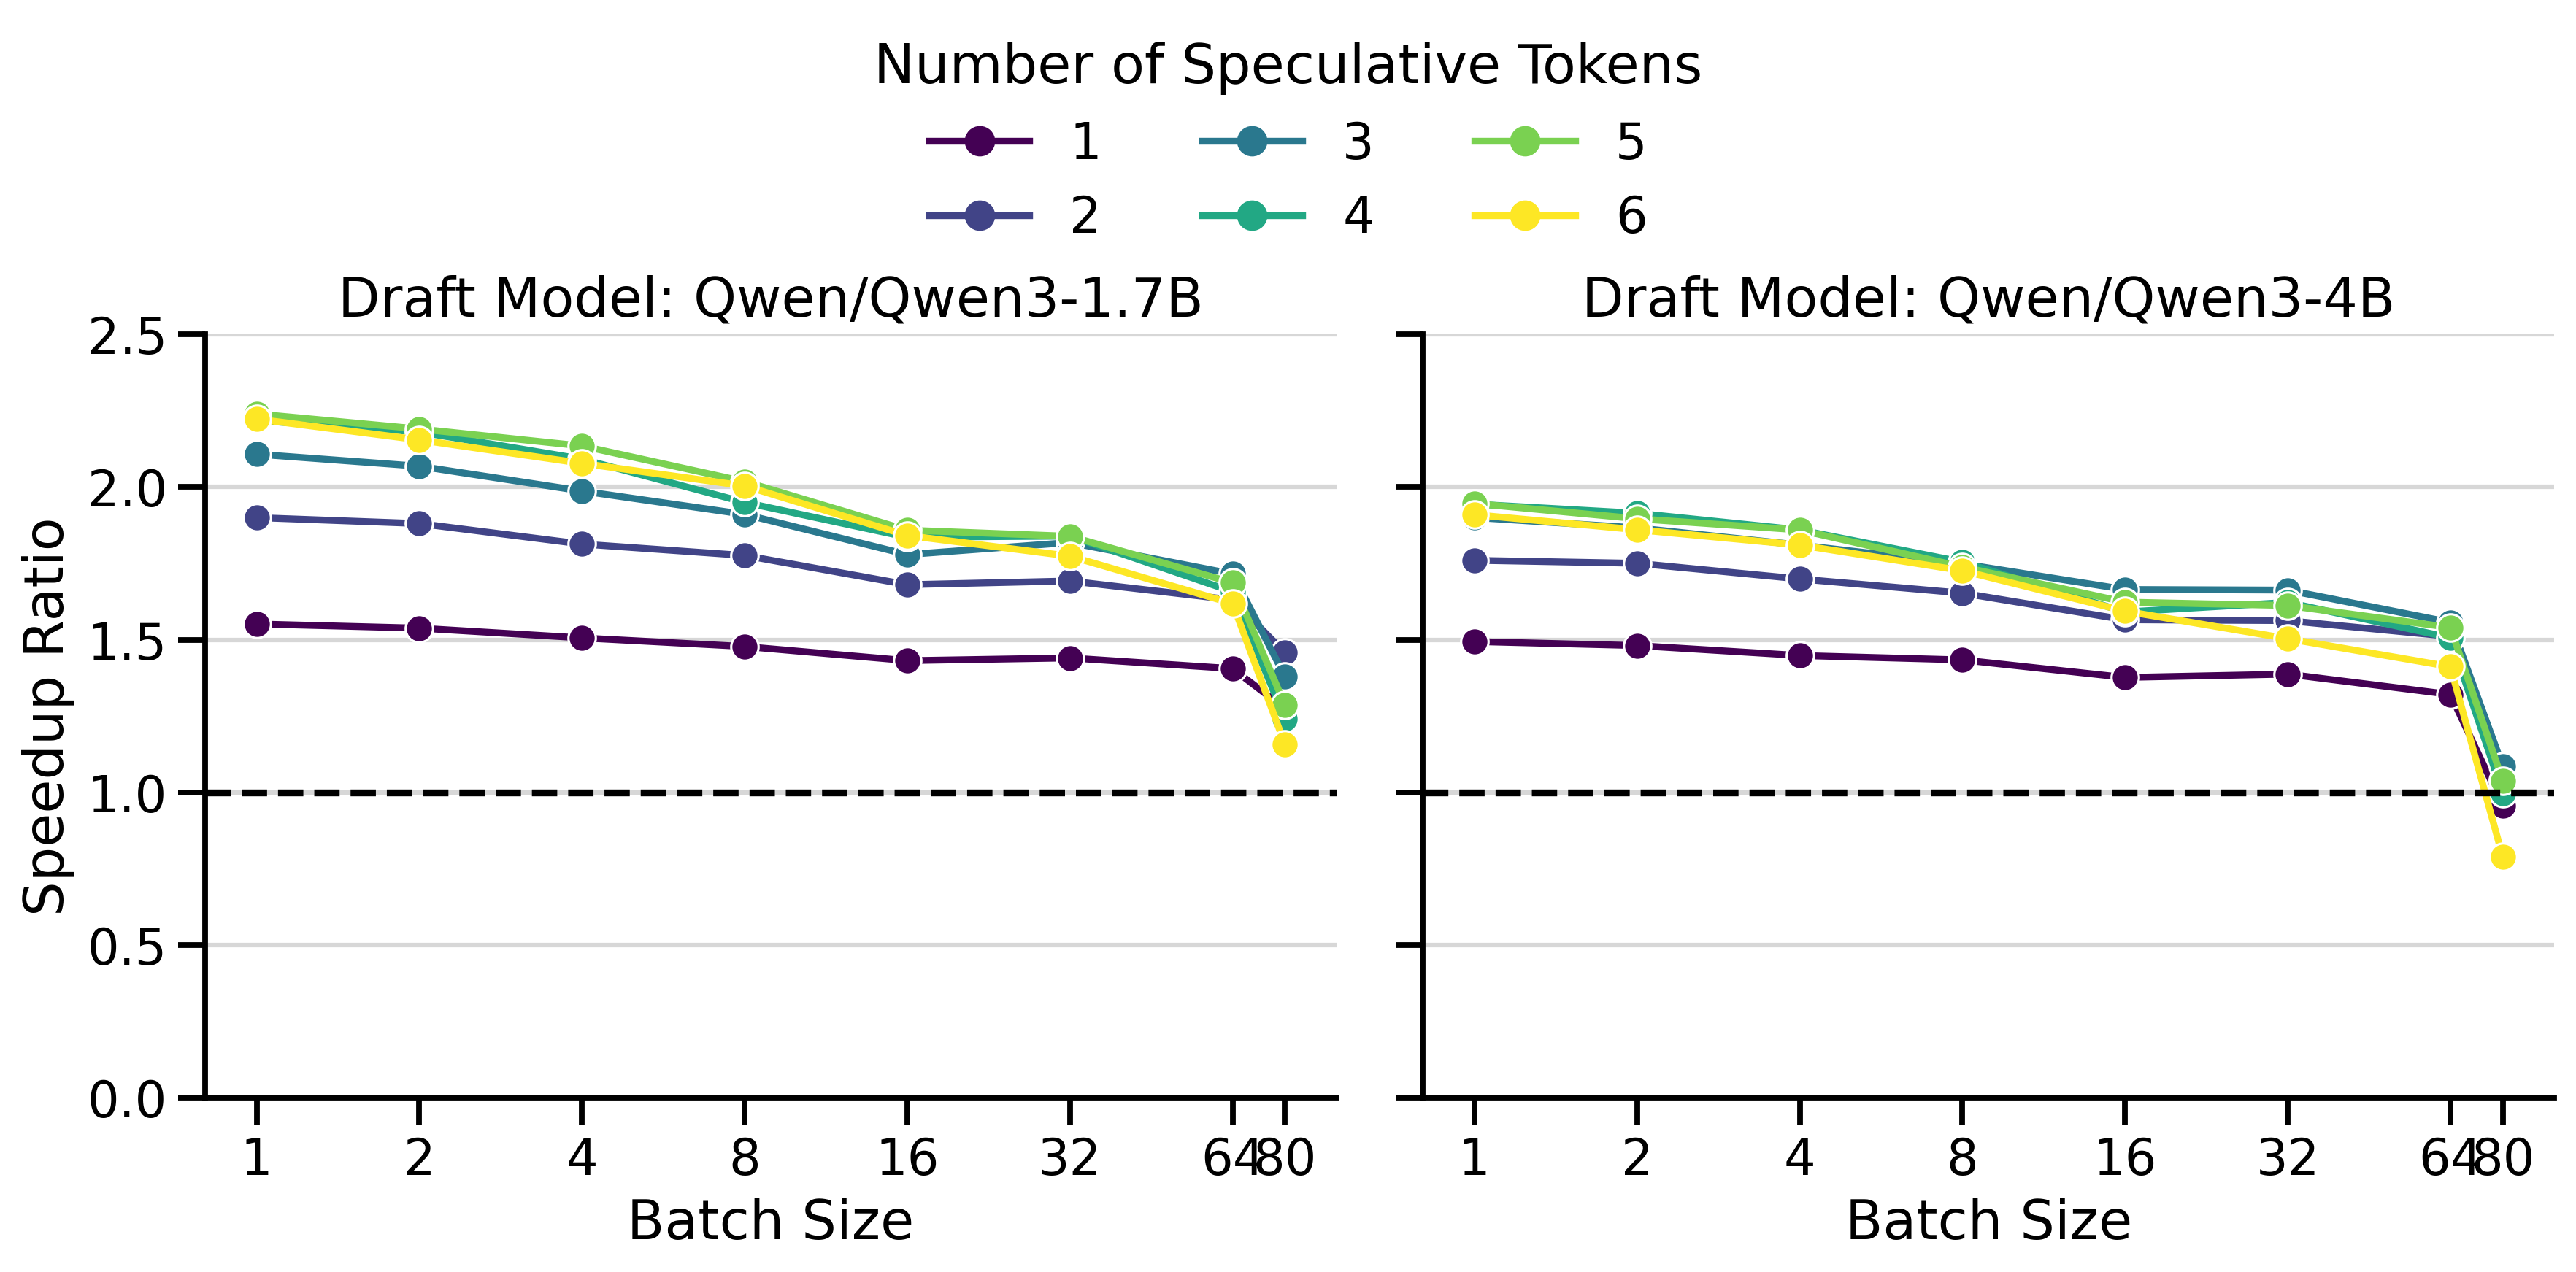
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...
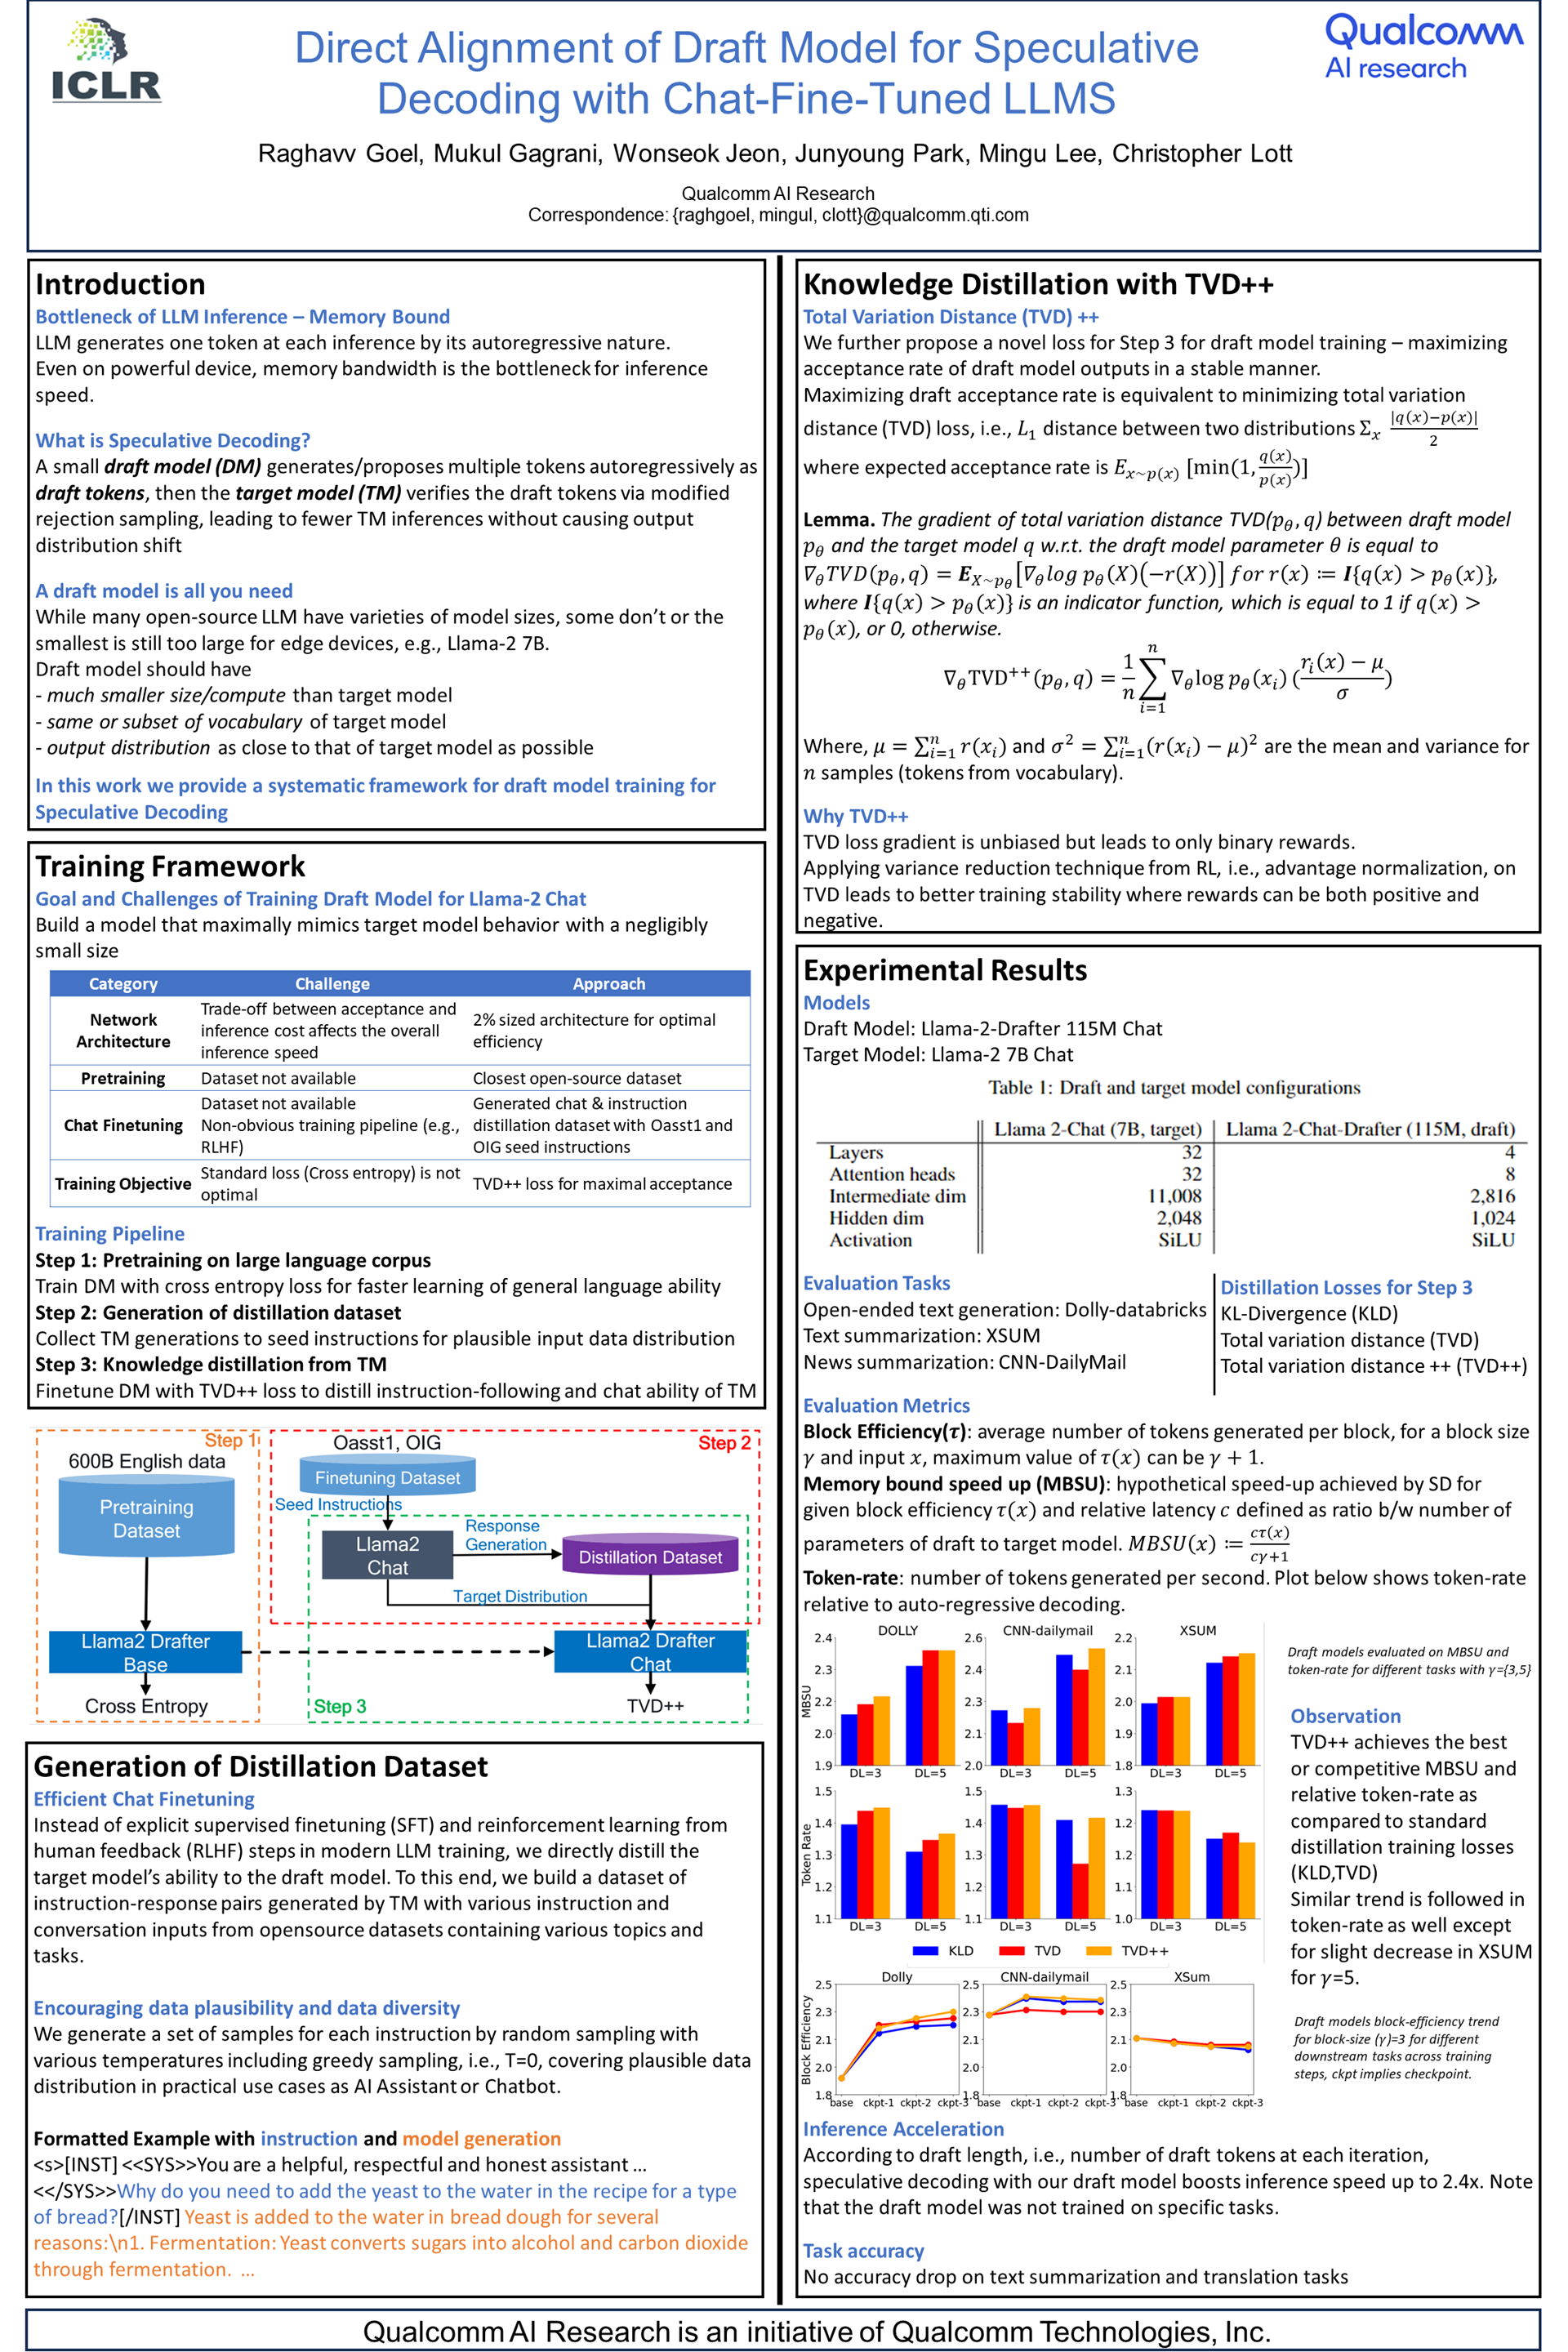
ICLR Direct Alignment of Draft Model for Speculative Decoding with Chat ...
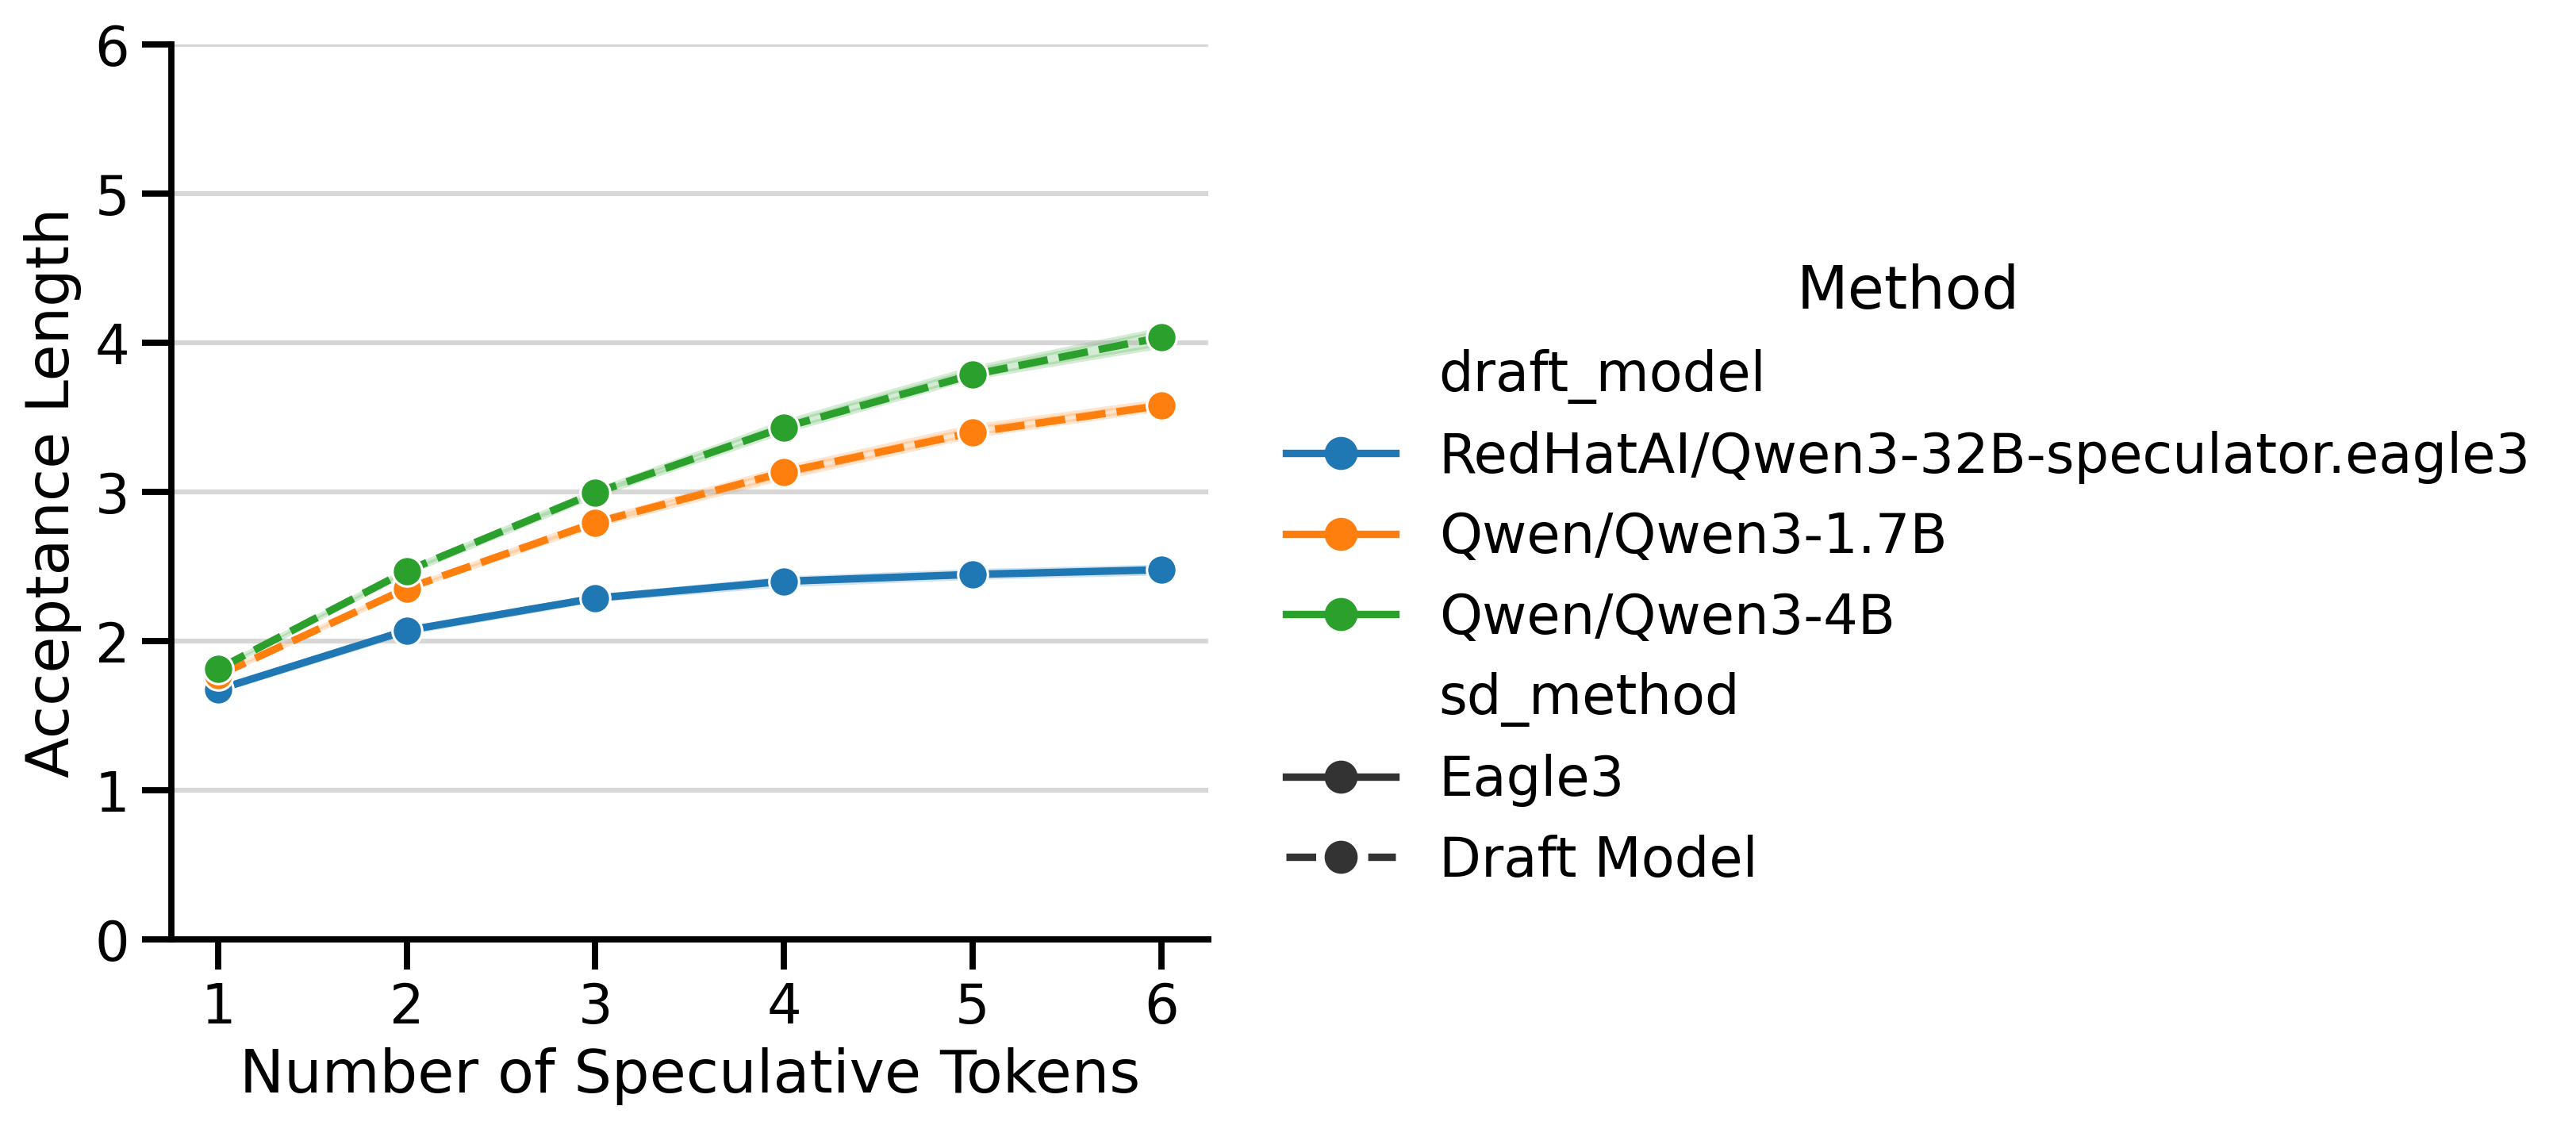
Up to 3.55x Faster: Contributing Speculative Decoding with Draft Models ...

Models - Speculative Decoding - Draft - Base Model - a matlok Collection

Figure 1 from Direct Alignment of Draft Model for Speculative Decoding ...
Advertisement Space (300x250)
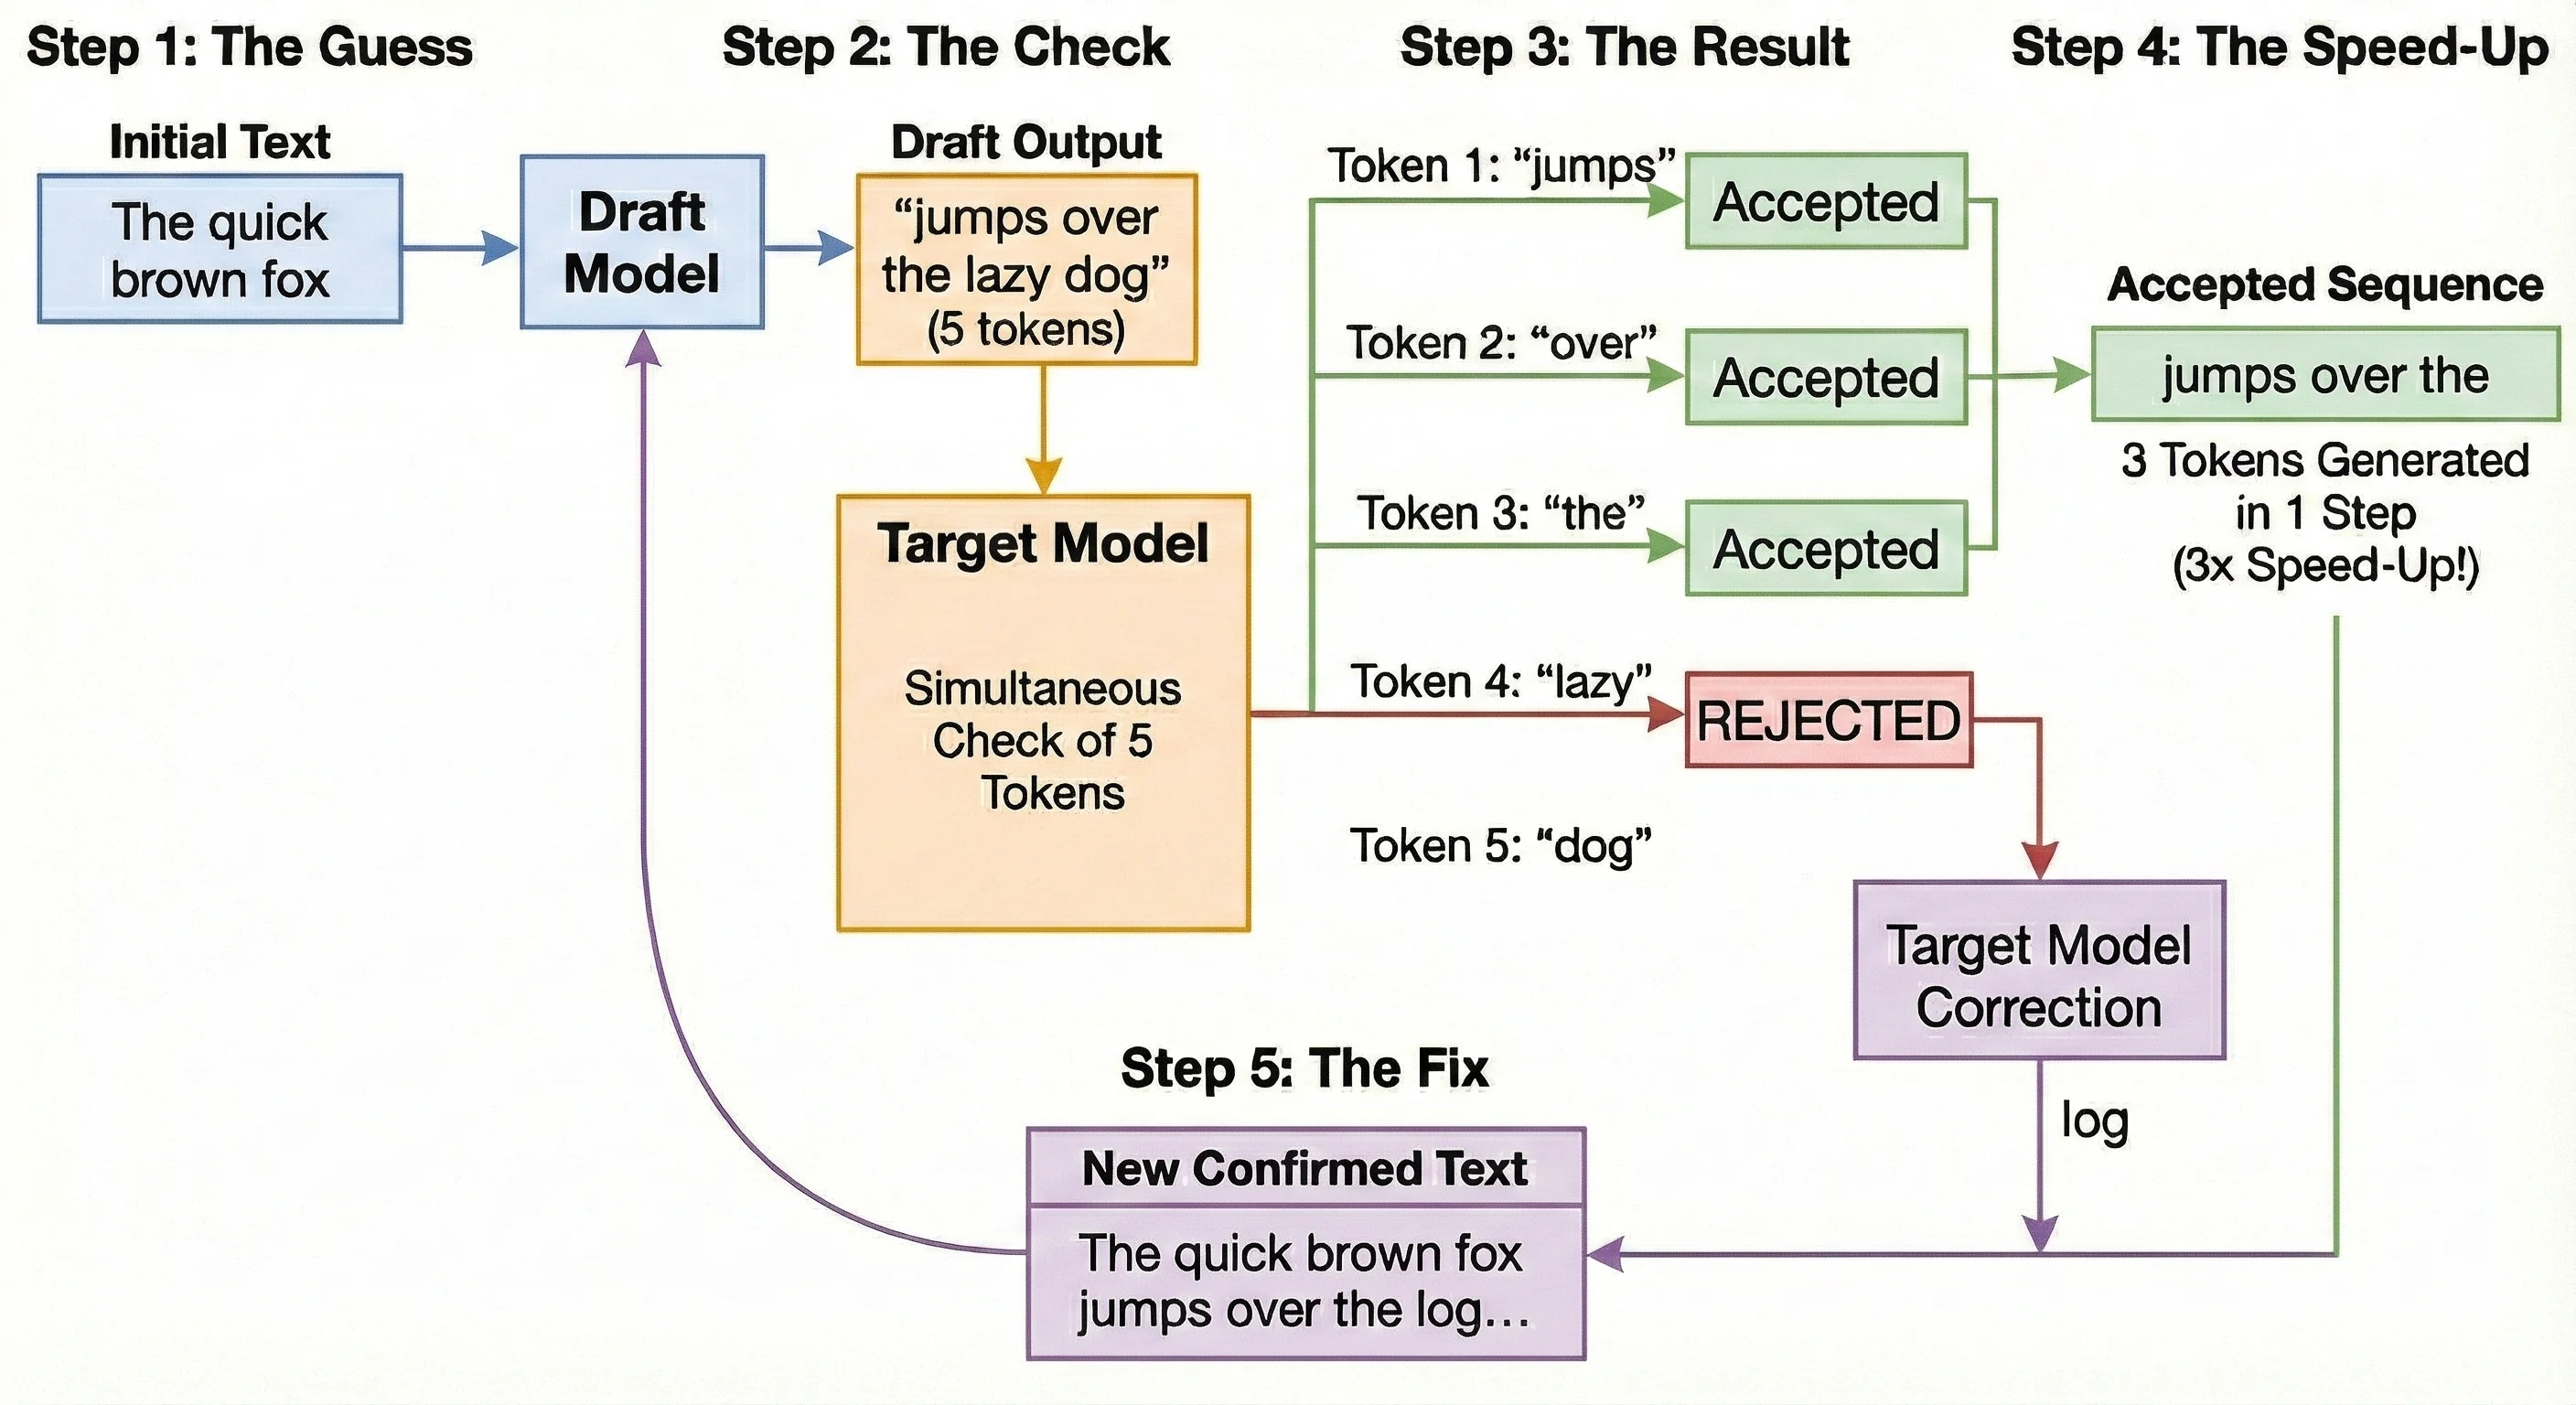
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

[论文评述] Training Domain Draft Models for Speculative Decoding: Best ...
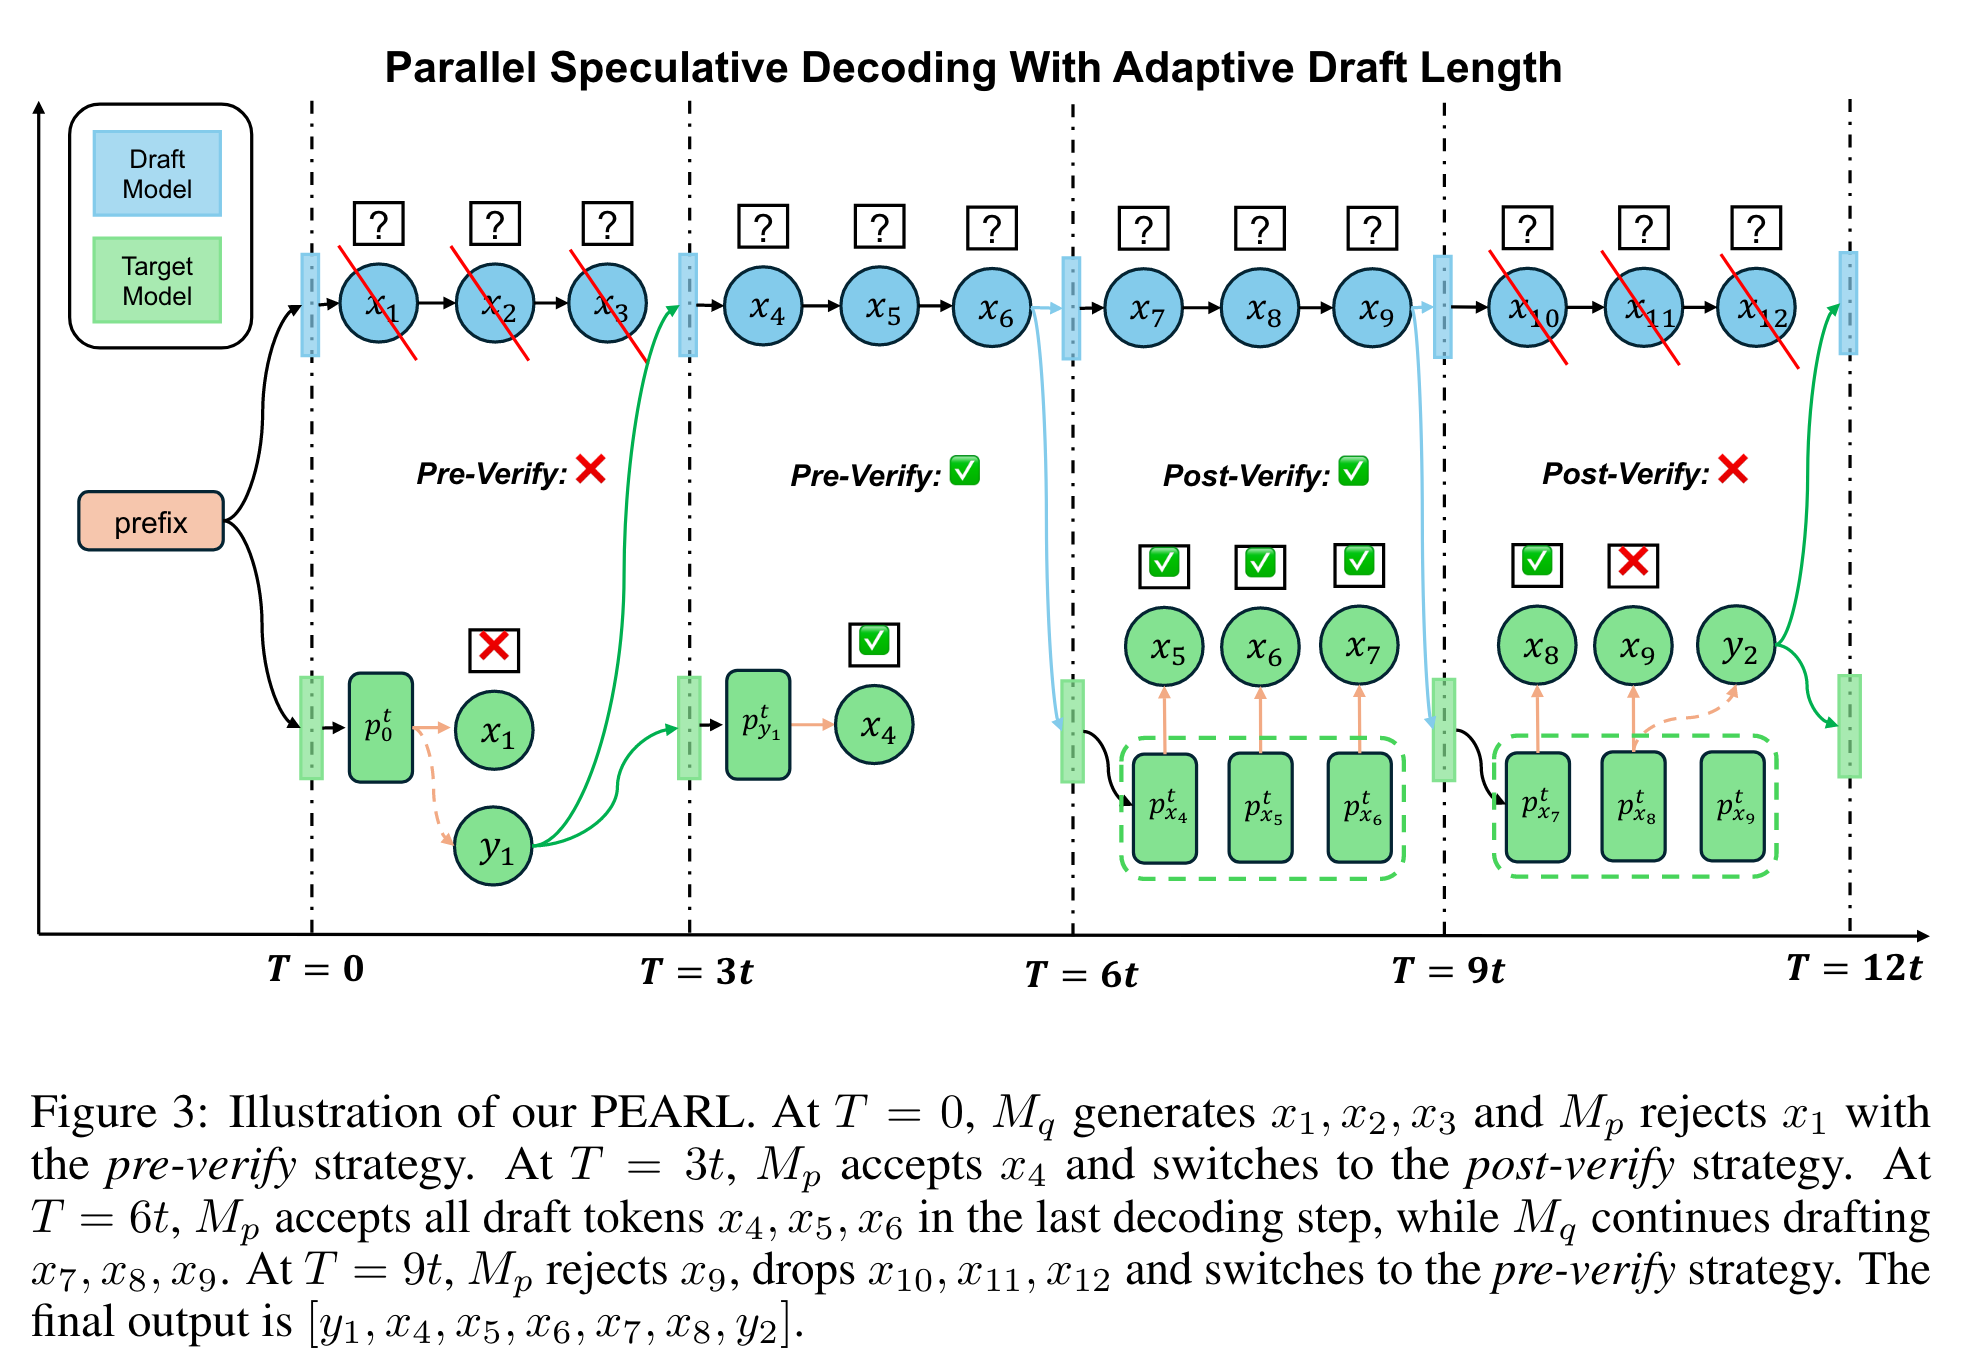
PEARL: Parallel Speculative Decoding with Adaptive Draft Length - 知乎

Parallel Speculative Decoding with Adaptive Draft Length

TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...
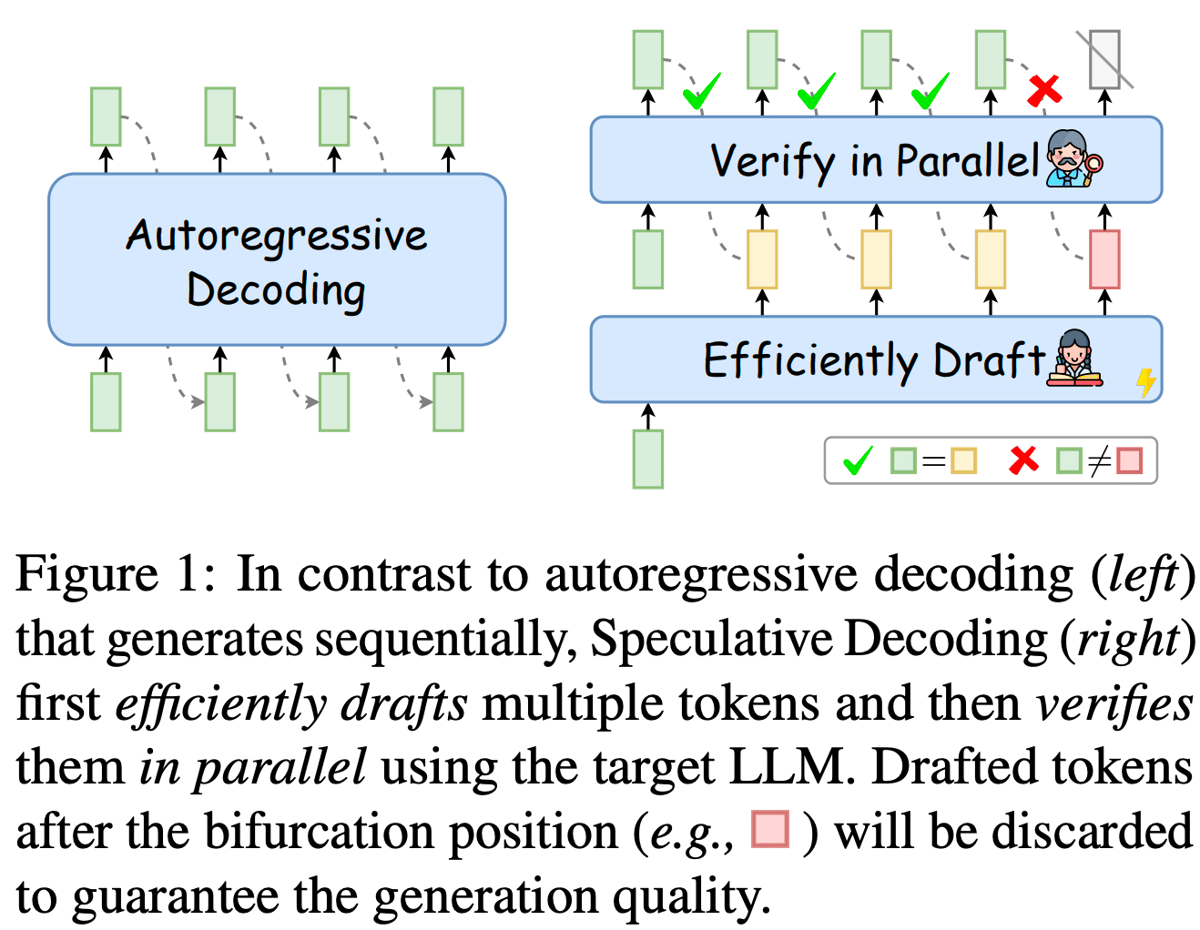
SGLang Speculative Decoding Tutorial: How to Deploy DeepSeek Models and ...

Learning to Draft: Adaptive Speculative Decoding with Reinforcement ...

Training Domain Draft Models for Speculative Decoding: Best Practices ...

An Introduction to Speculative Decoding for Reducing Latency in AI ...

(PDF) Training Domain Draft Models for Speculative Decoding: Best ...
Advertisement Space (336x280)

Speculative Decoding Draft Models - a OpenVINO Collection
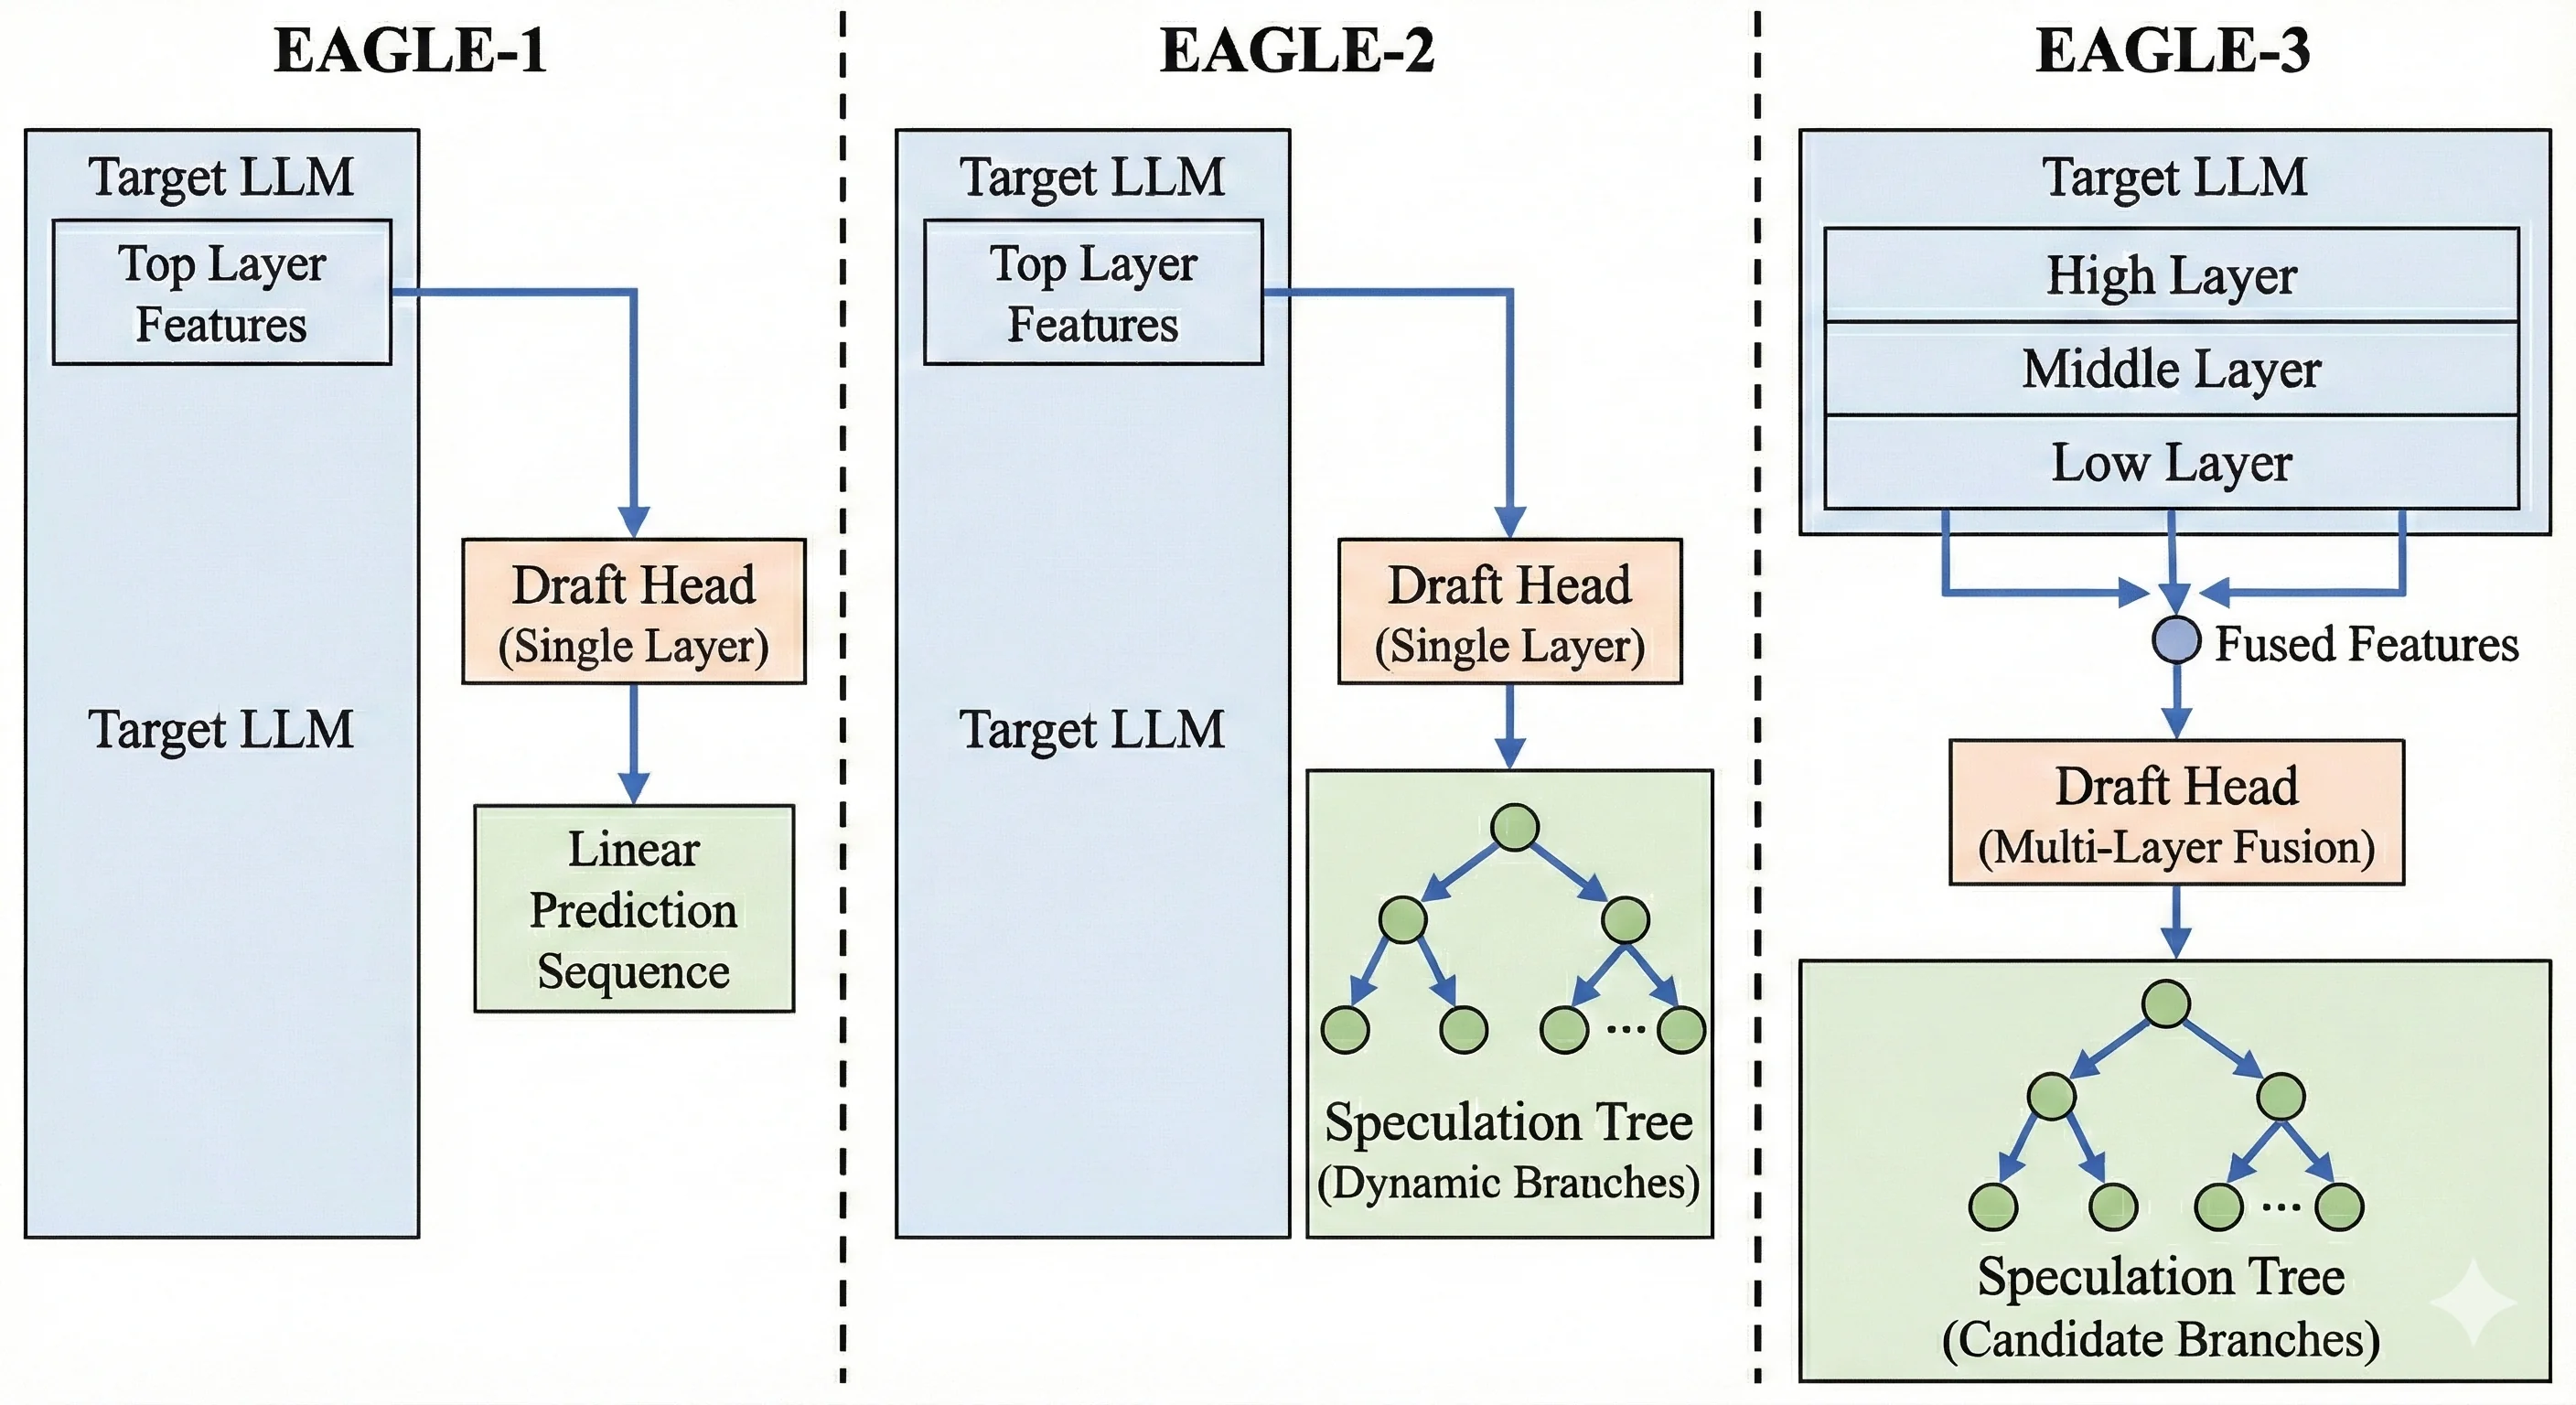
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
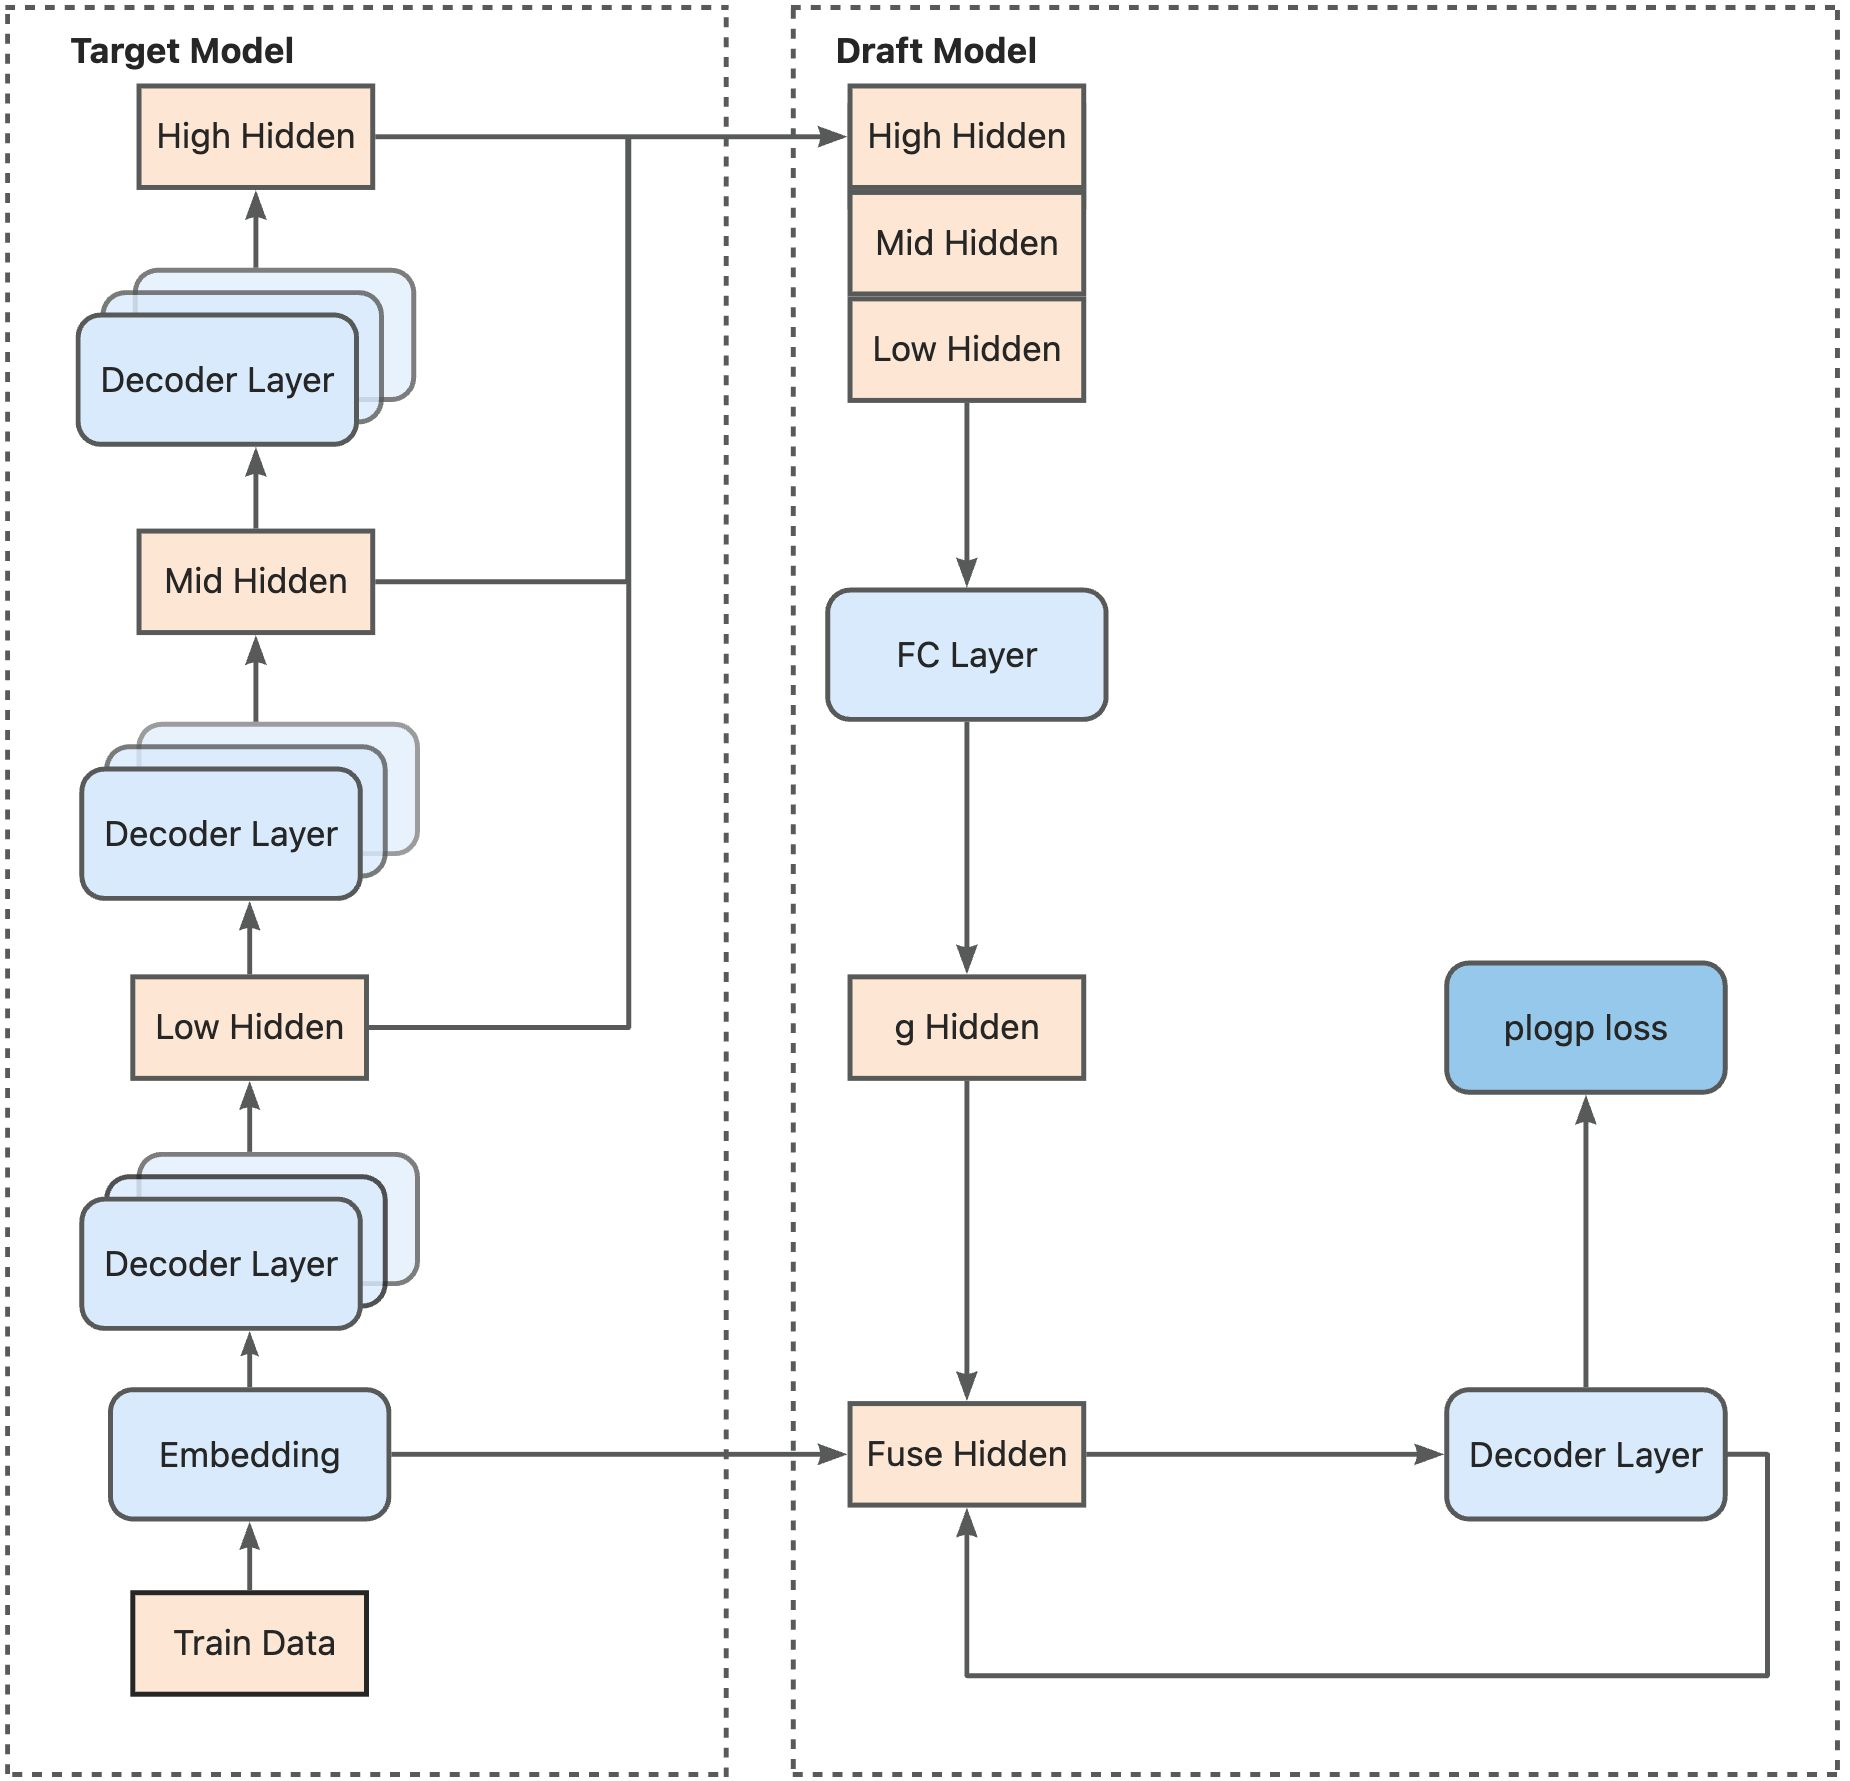
SpecForge: Accelerating Speculative Decoding Training for SGLang ...

[논문 리뷰] PEARL: Parallel Speculative Decoding with Adaptive Draft Length
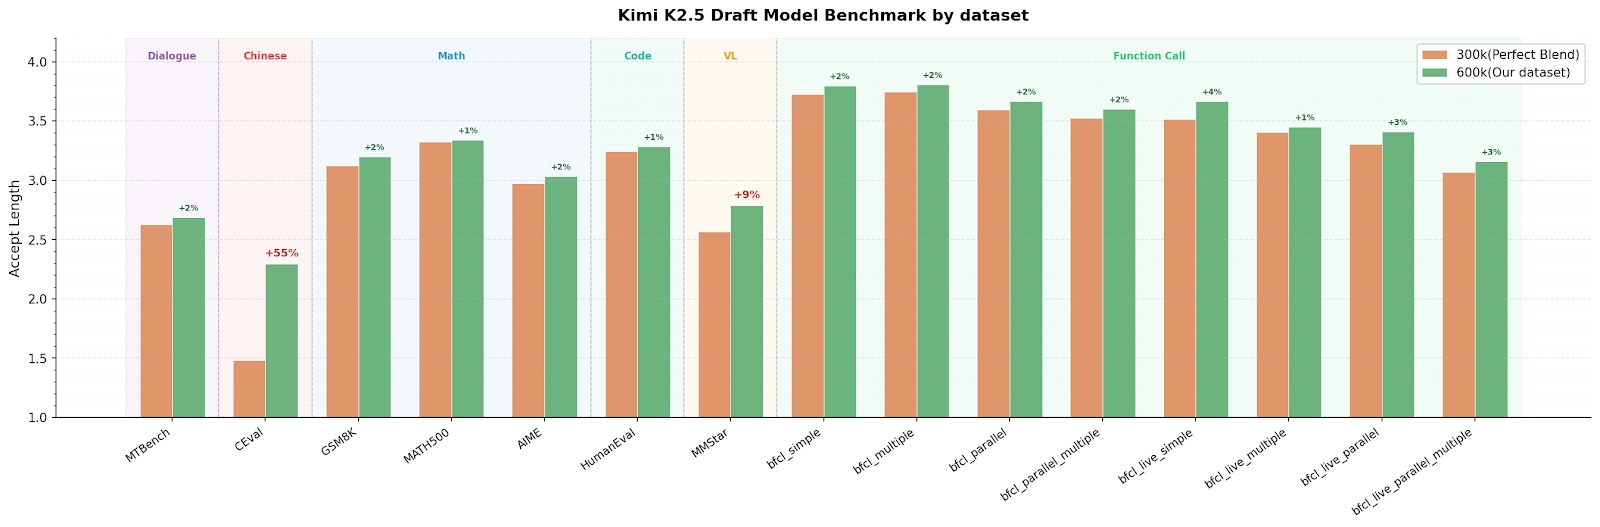
TorchSpec: Speculative Decoding Training at Scale – PyTorch
The Speculative Decoding as a Draft and Edit | Emberverse
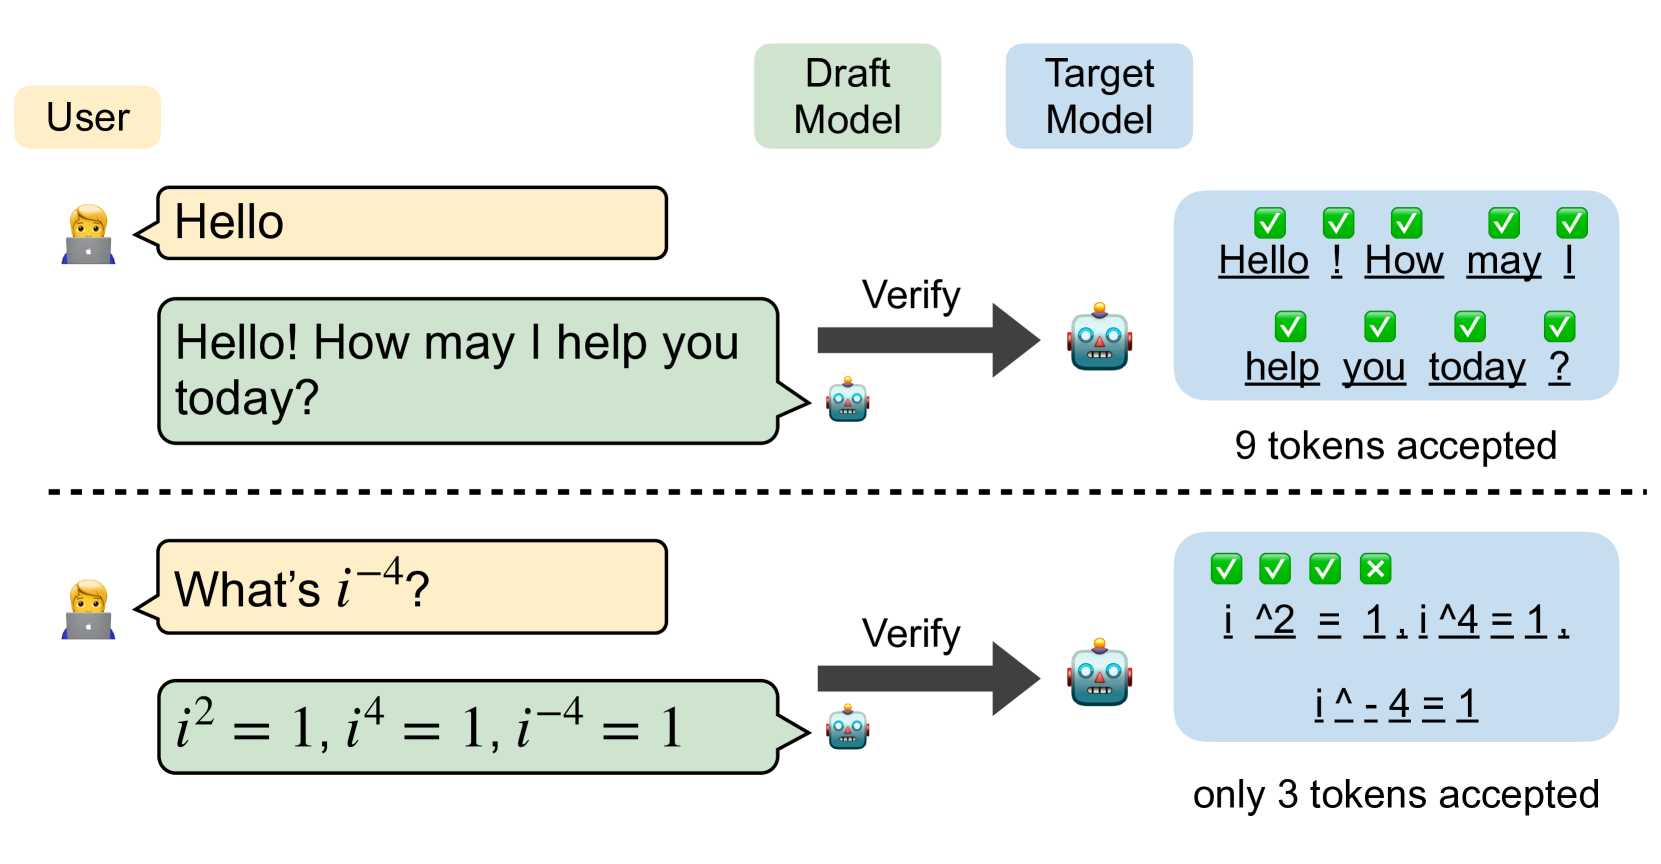
Draft Model Knows When to Stop: A Self-Verification Length Policy for ...

AdaSD: Adaptive Speculative Decoding for Efficient Language Model ...
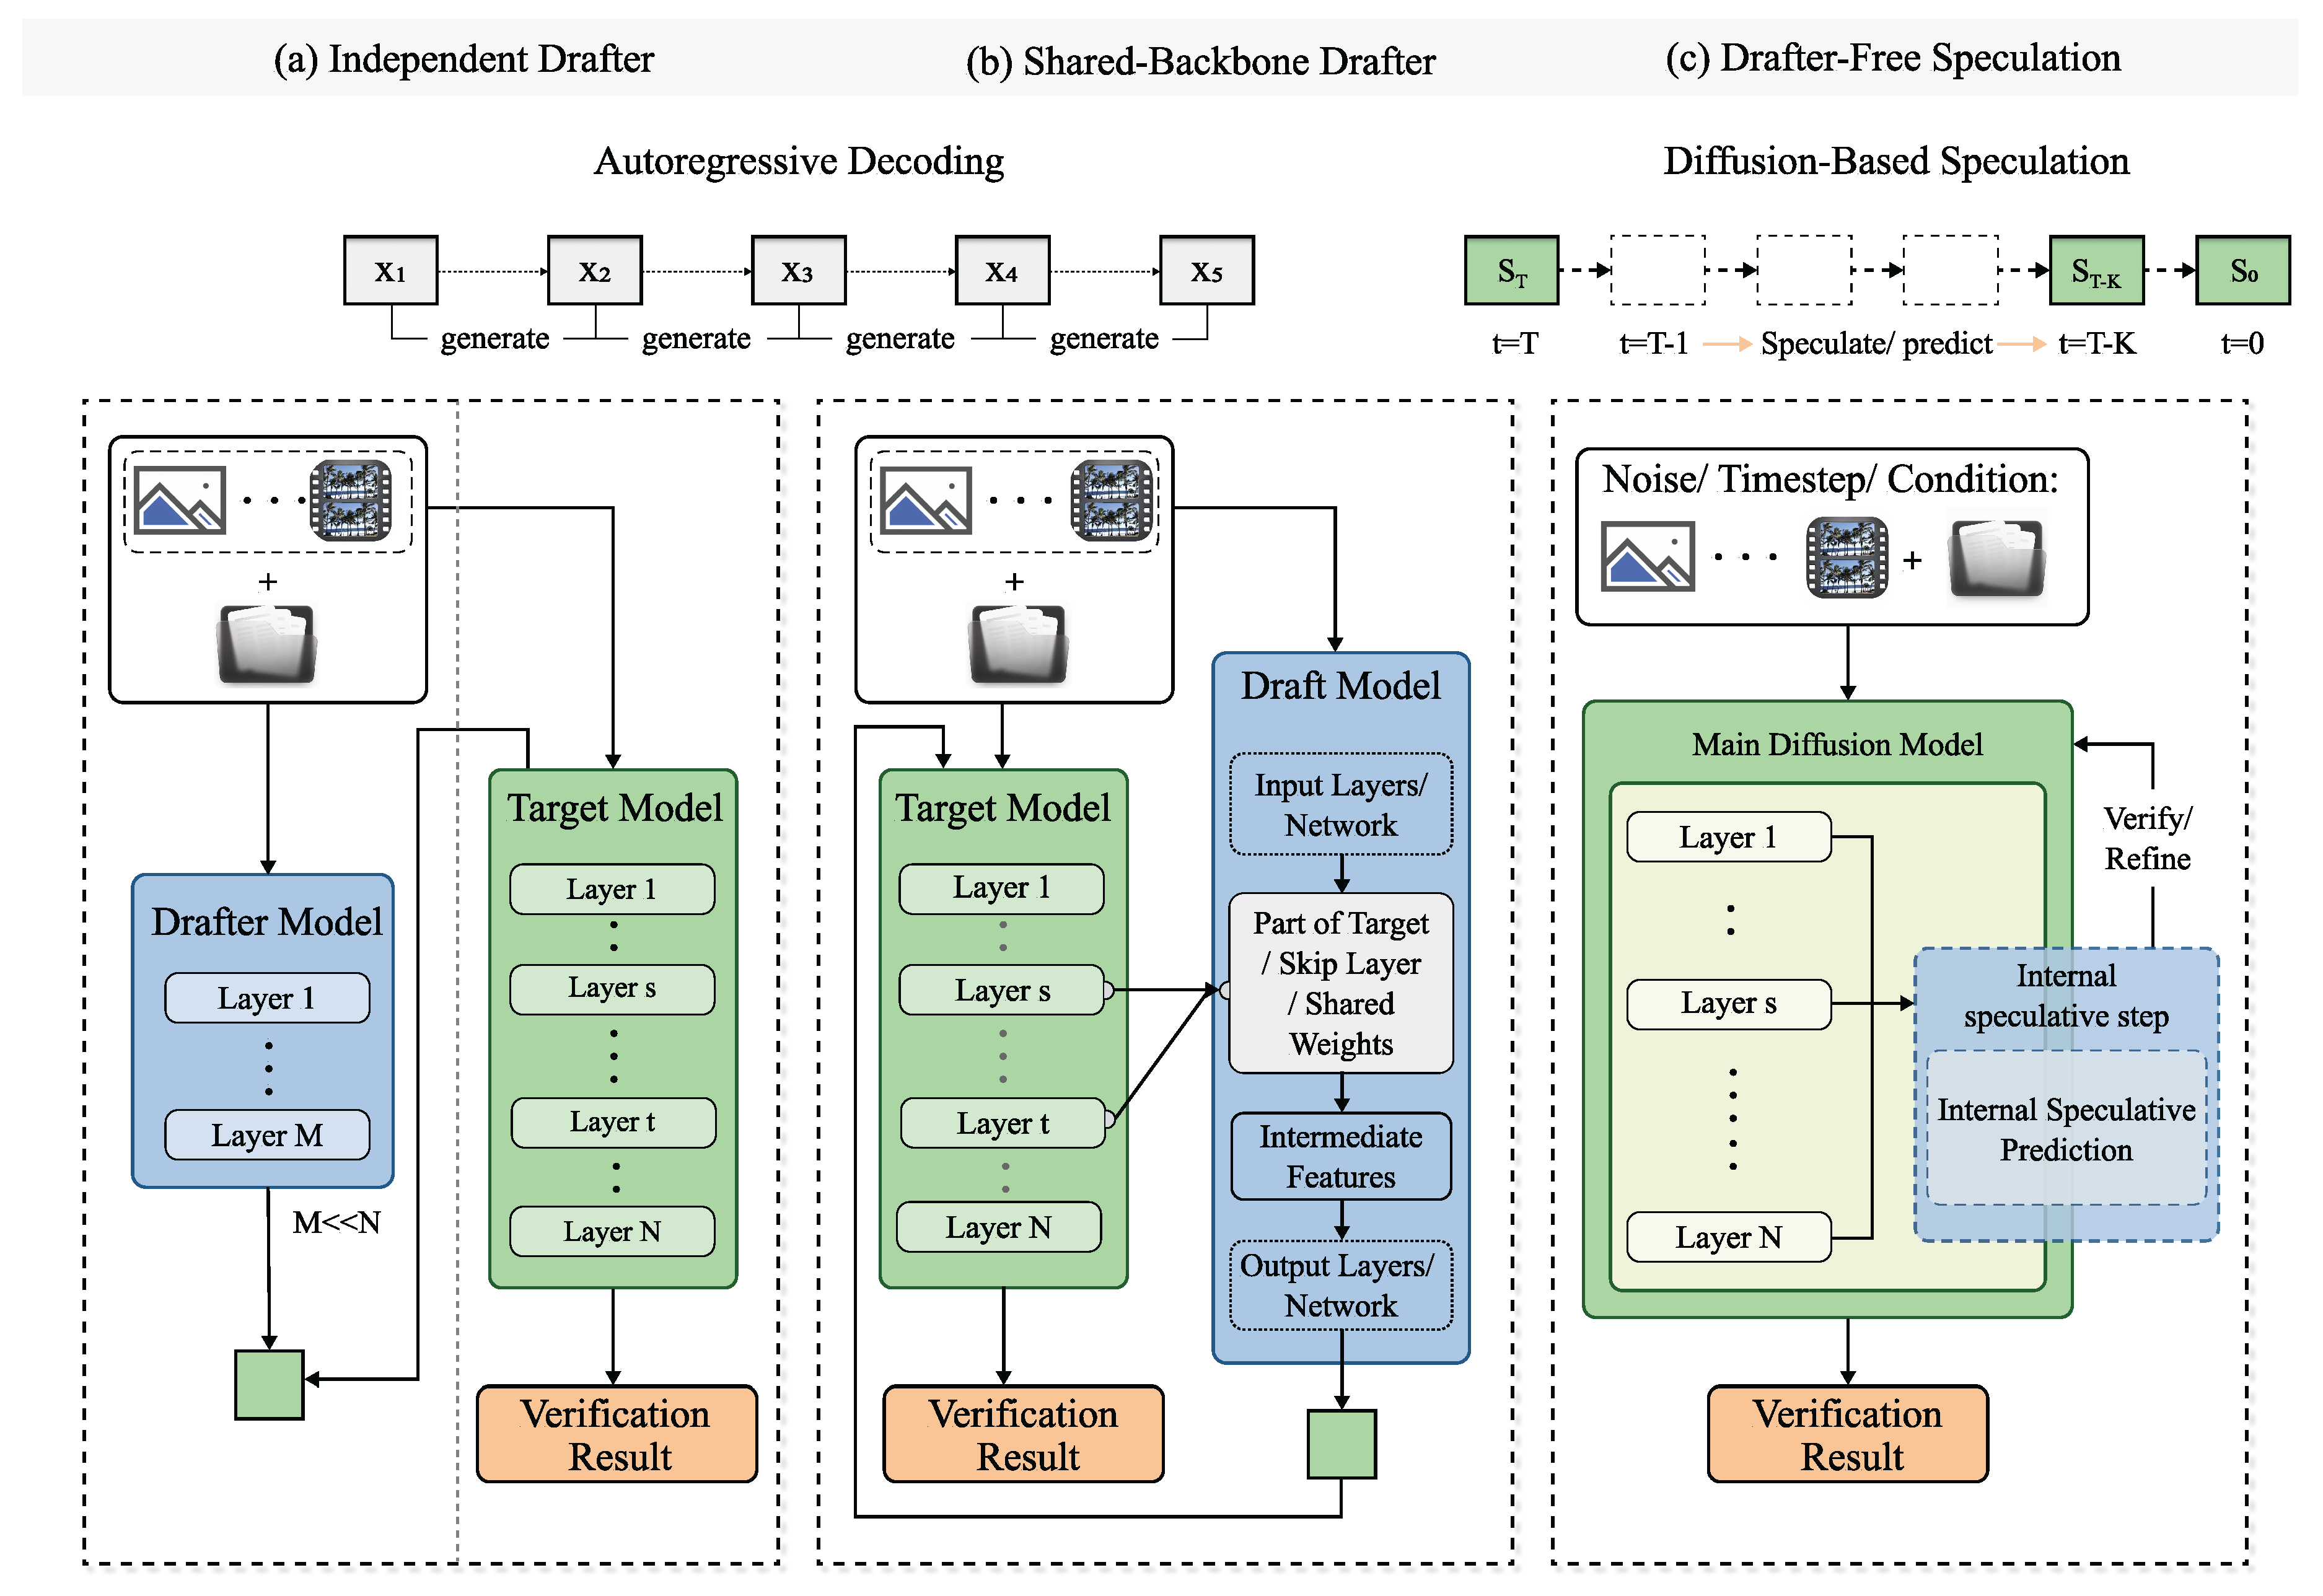
Speculative Decoding for Multimodal Models: A Survey[v2] | Preprints.org

When Drafts Evolve: Speculative Decoding Meets Online Learning
Advertisement Space (336x280)
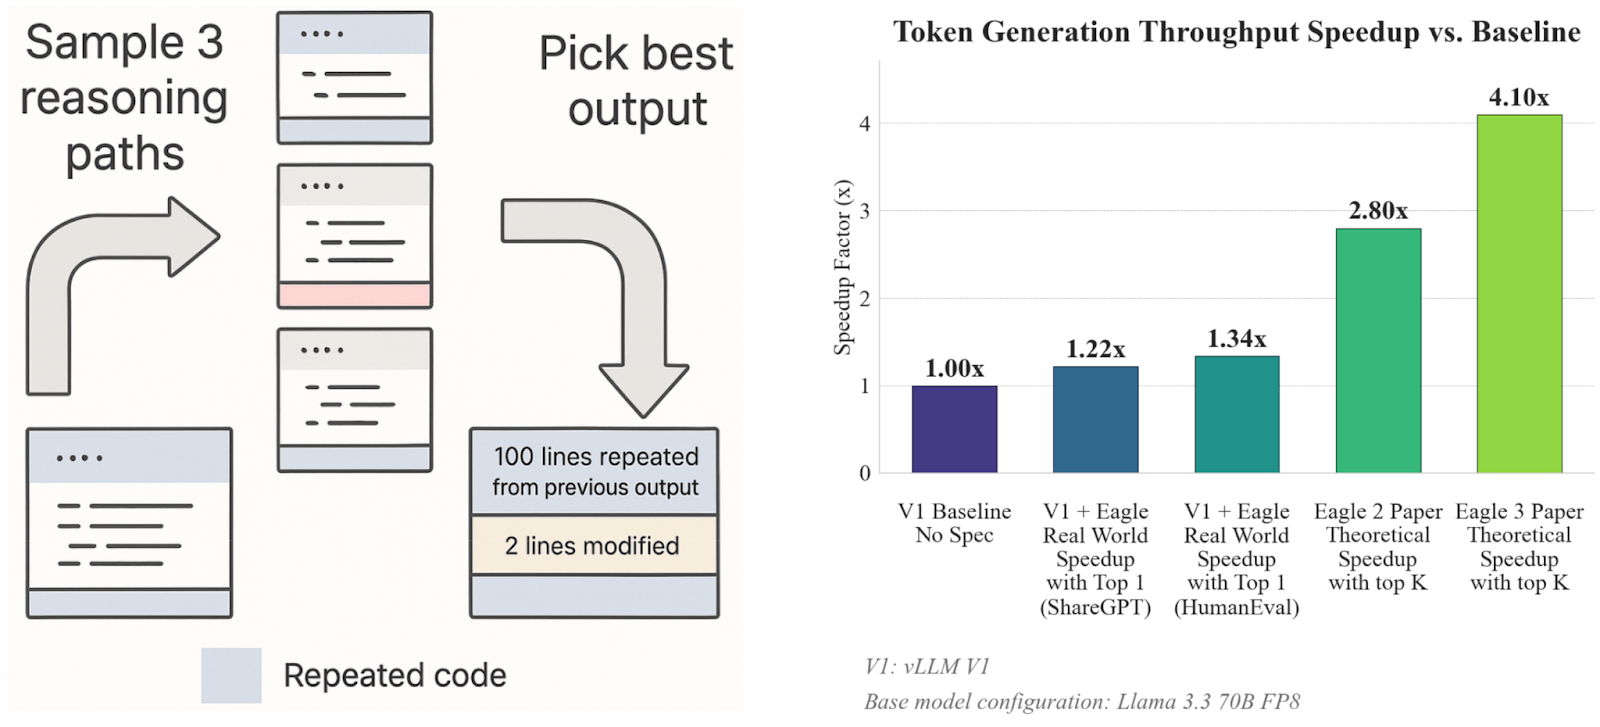
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
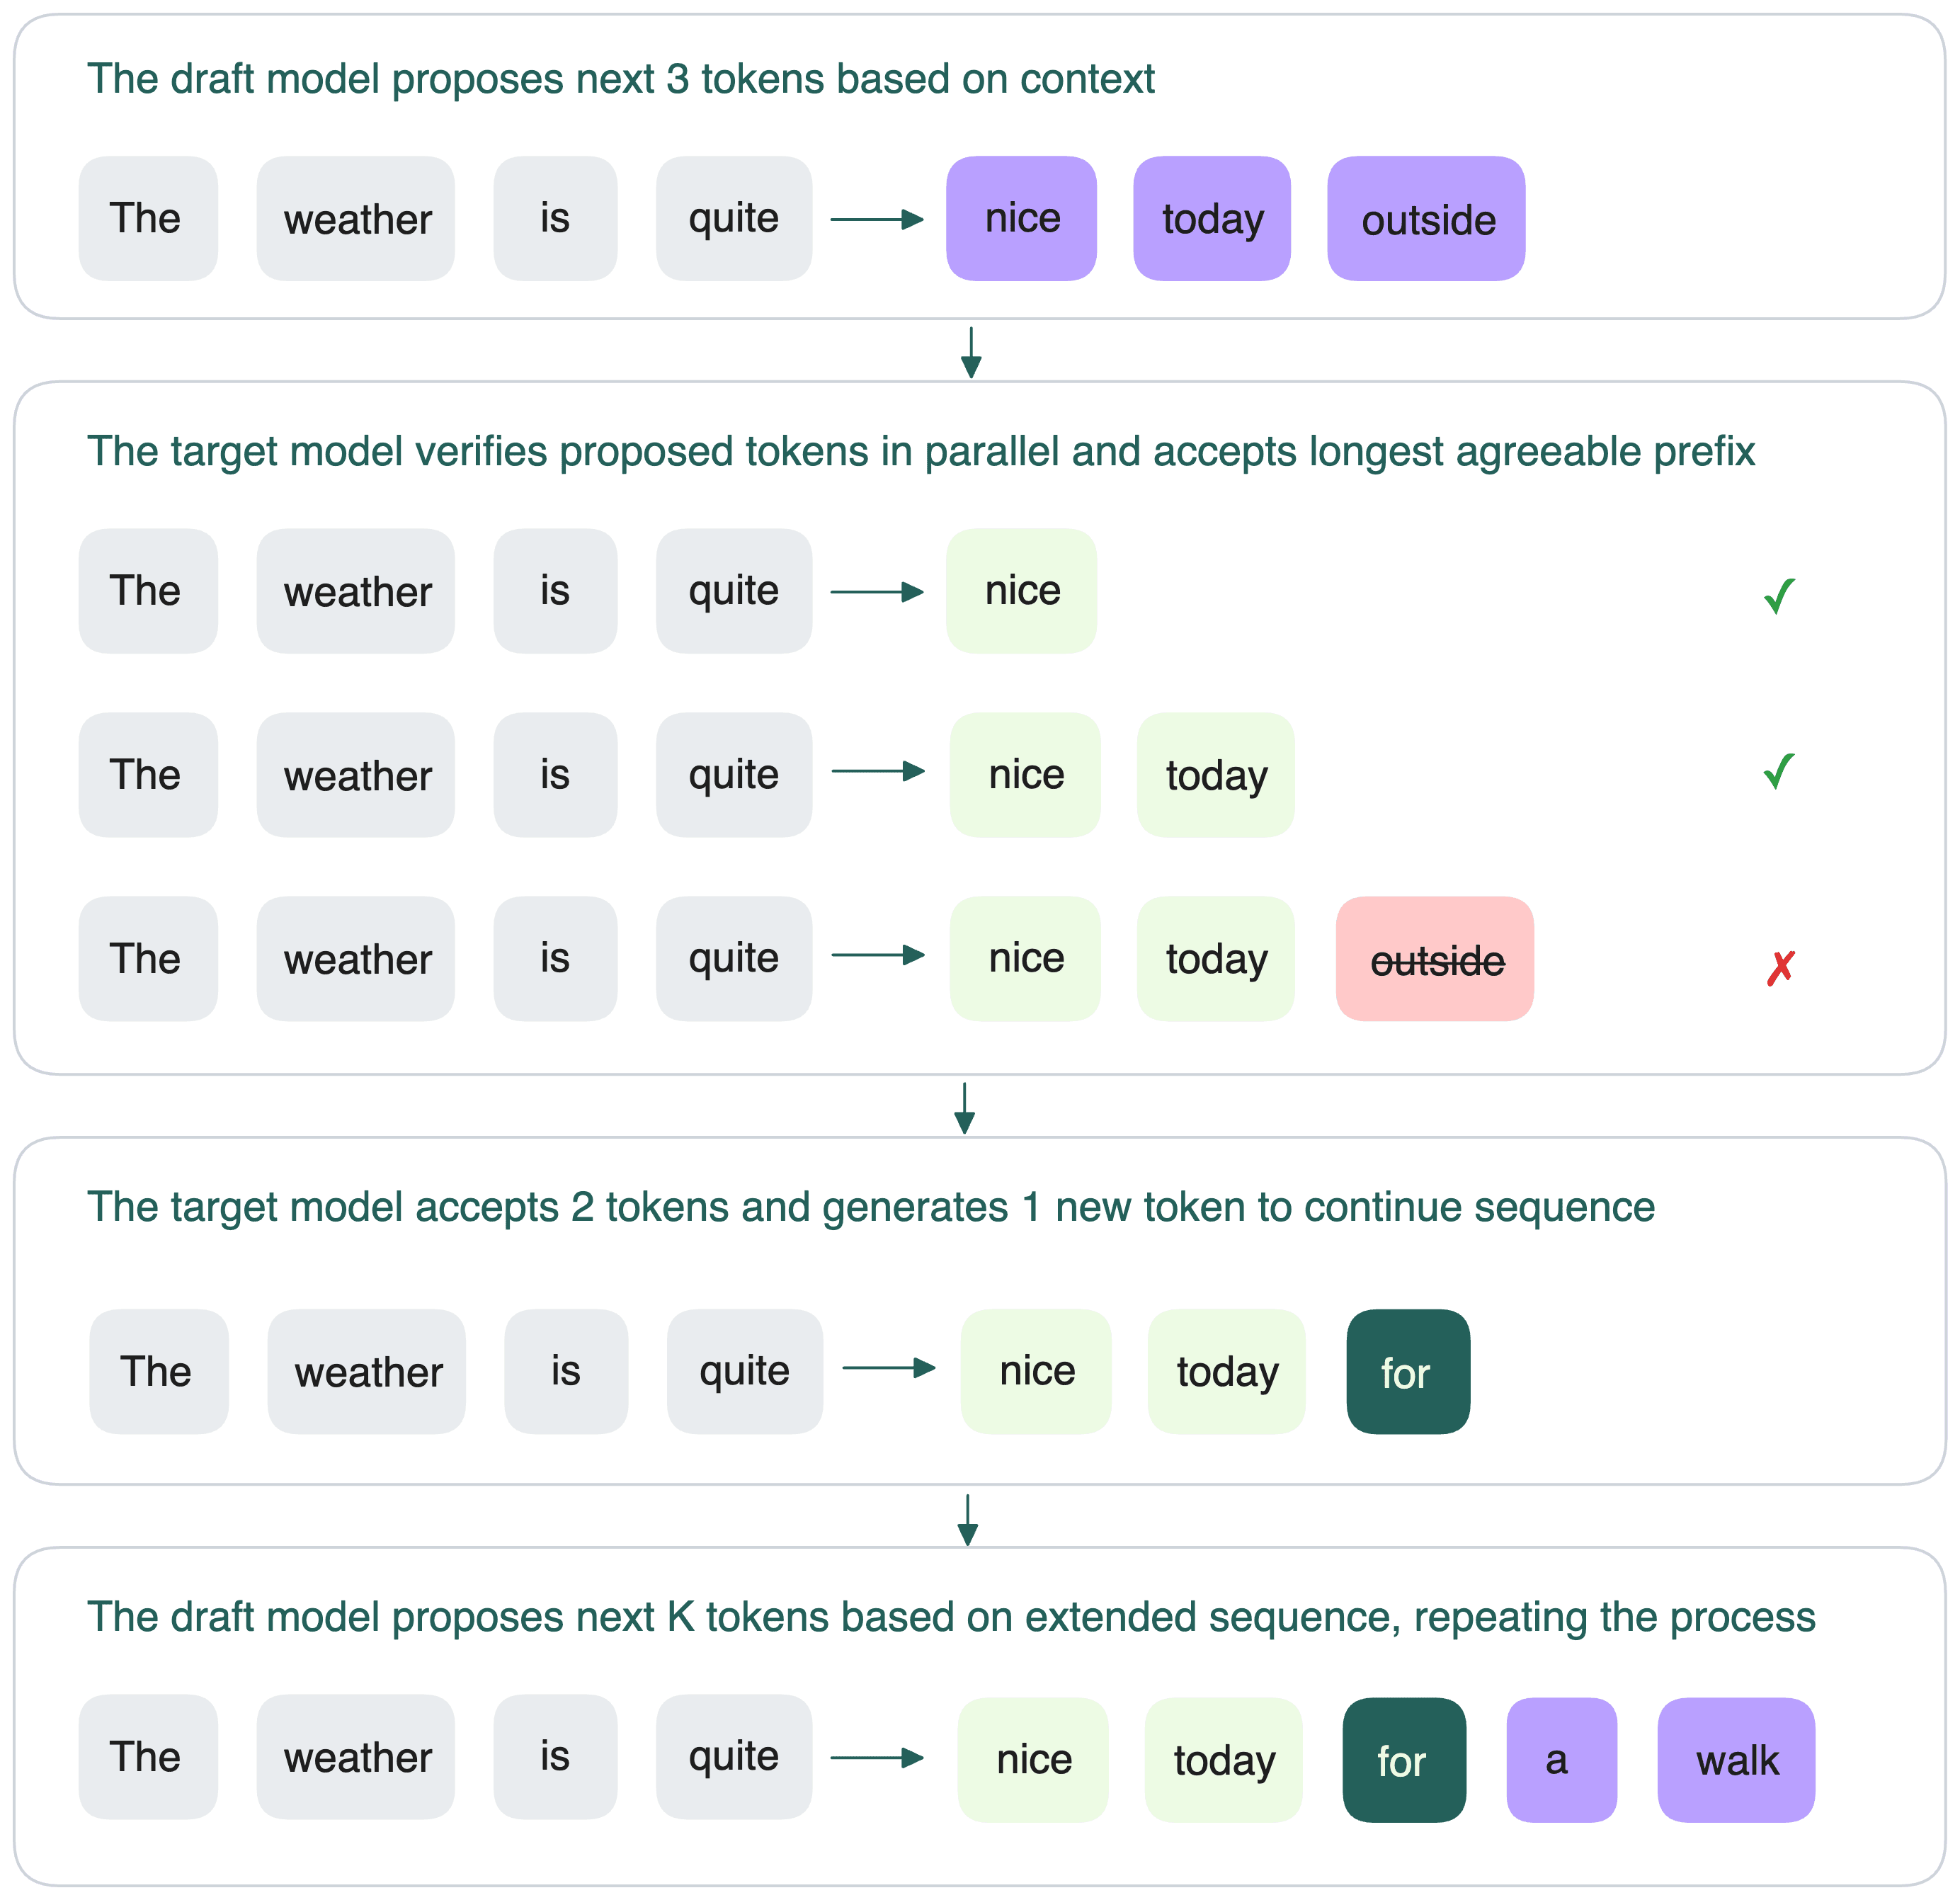
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
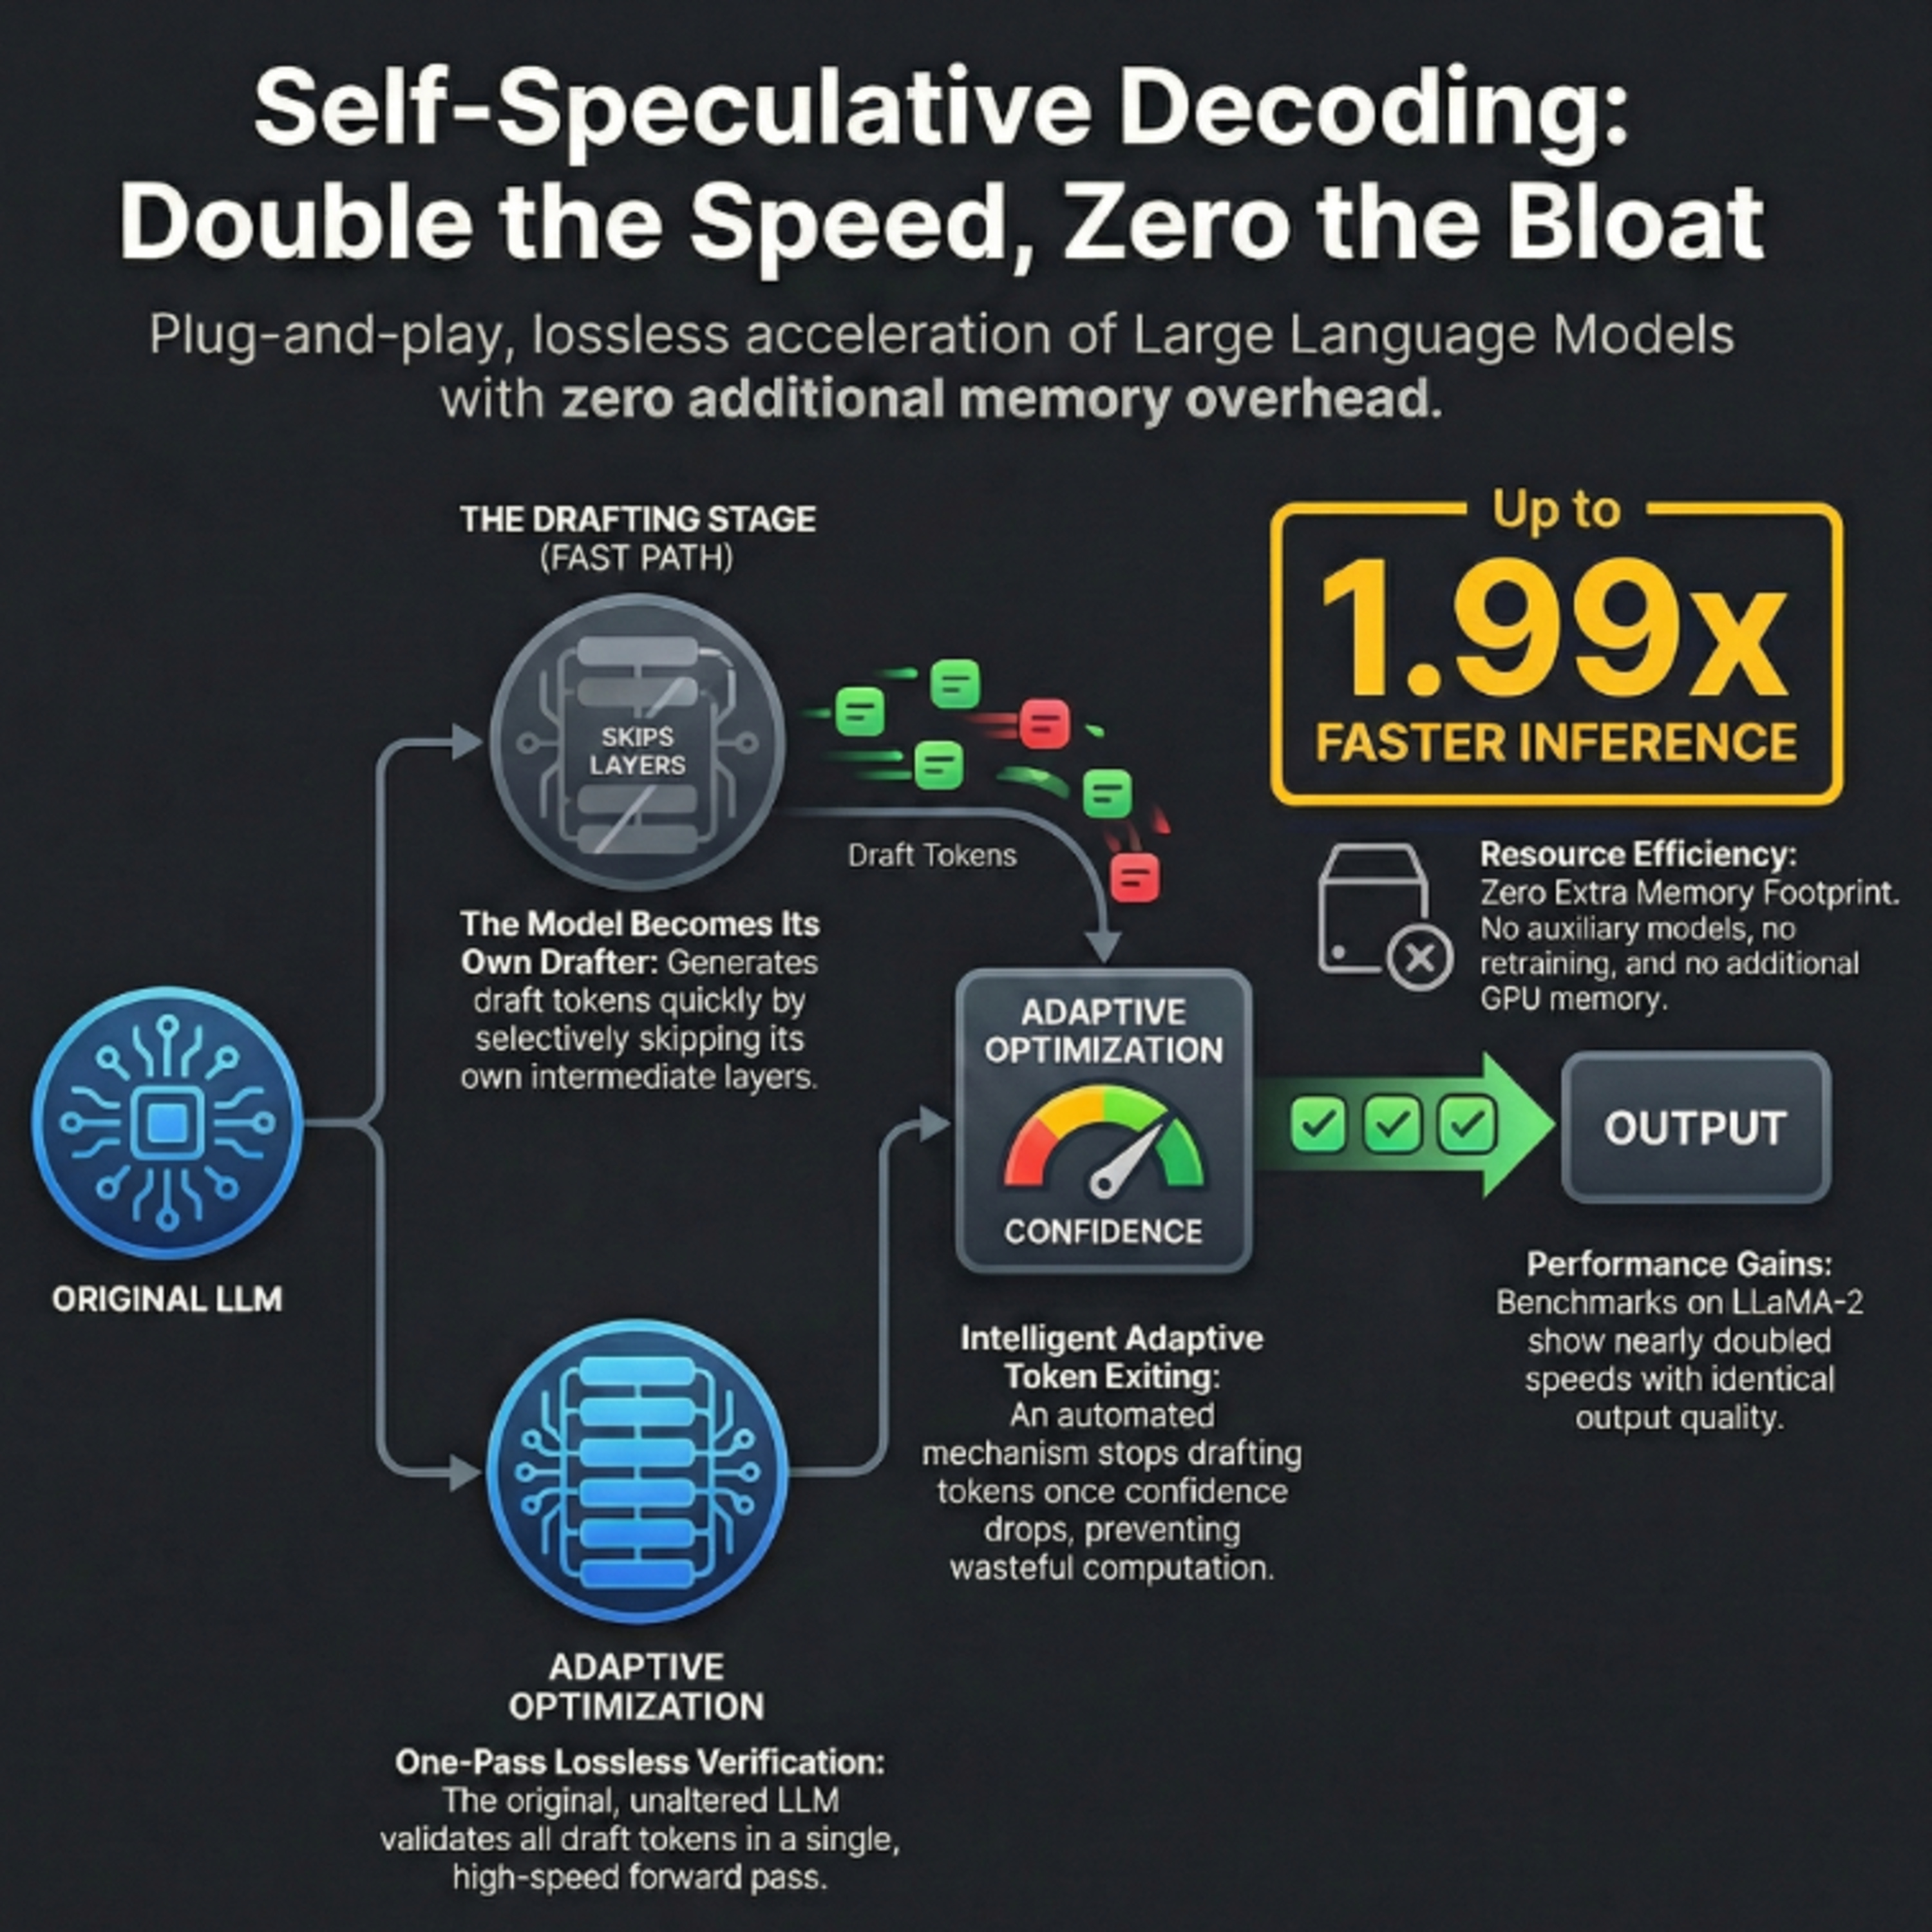
Draft & Verify: Lossless Large Language Model Acceleration via Self ...
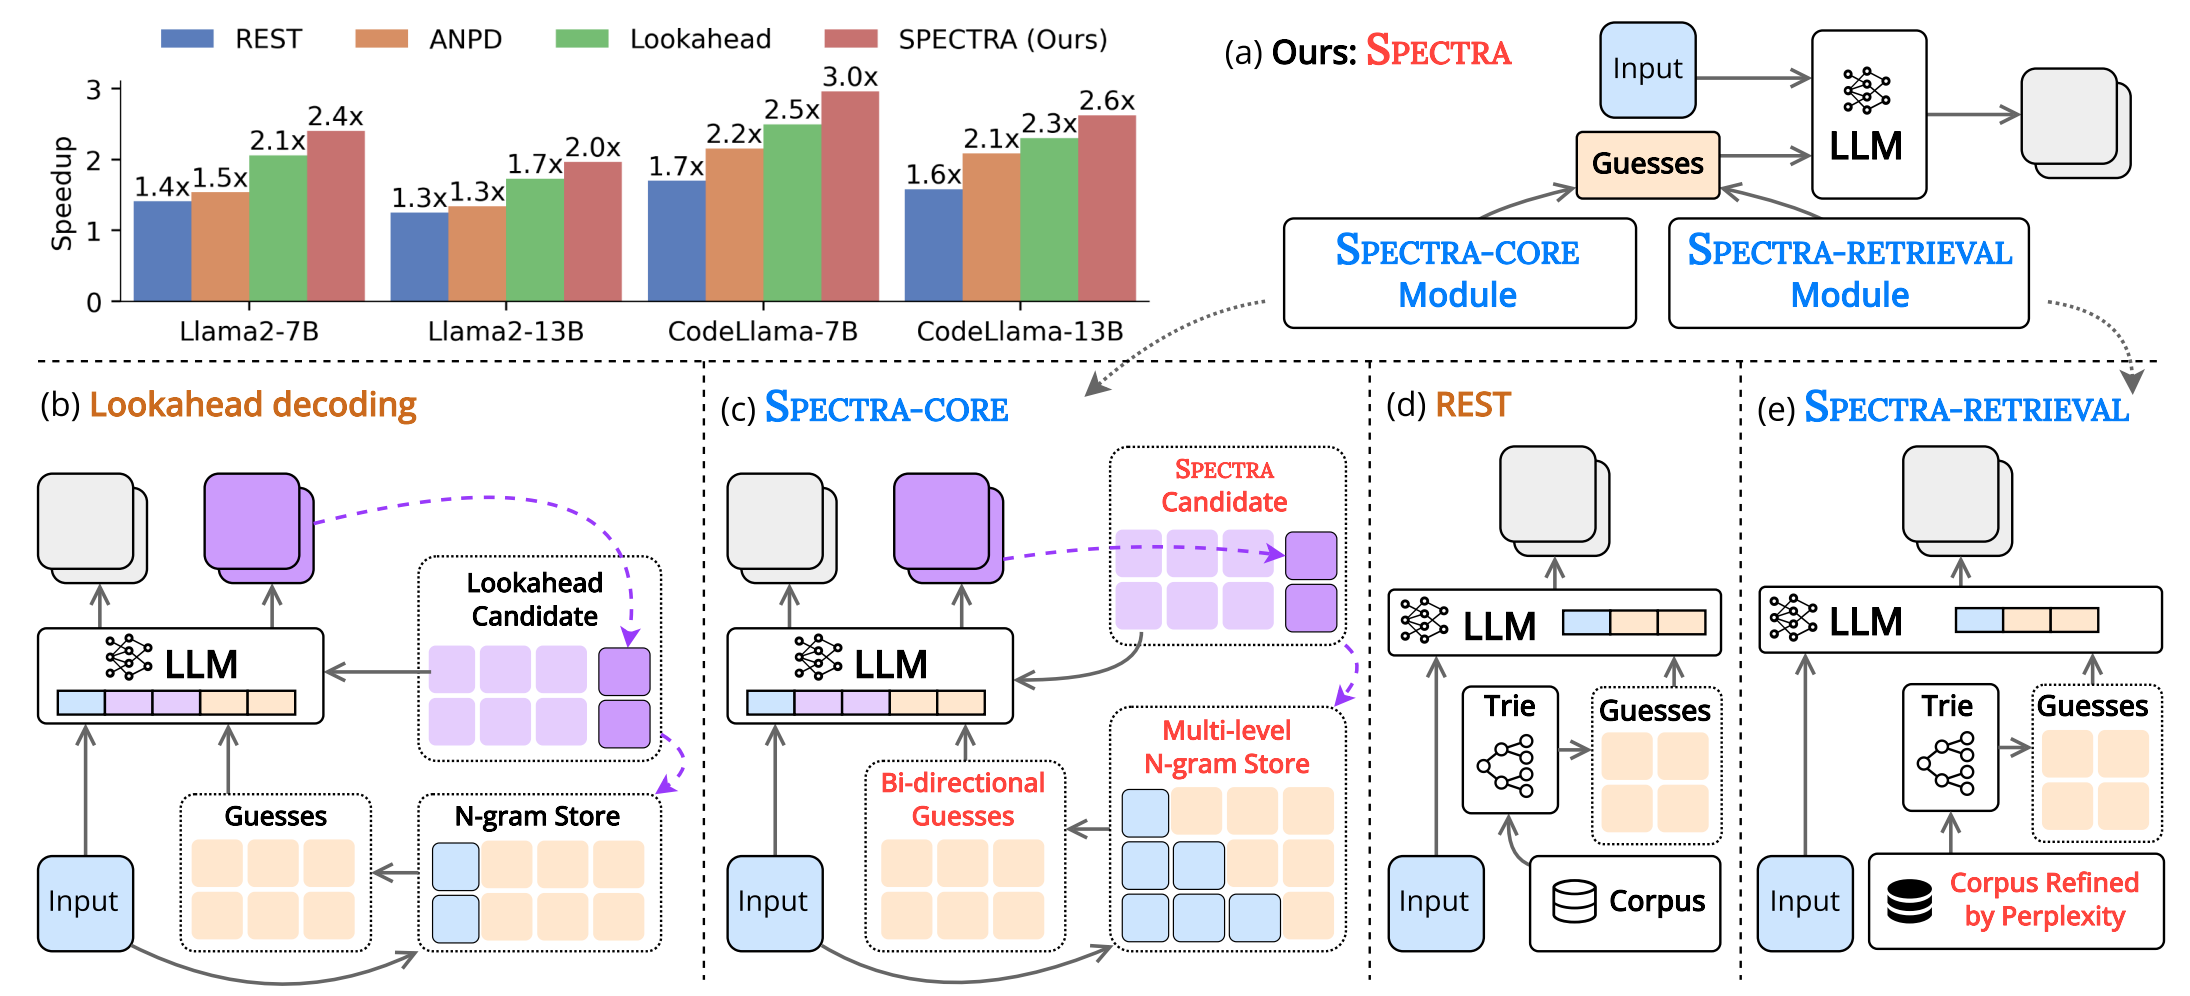
Nguyen Lab's Speculative Decoding Research Group
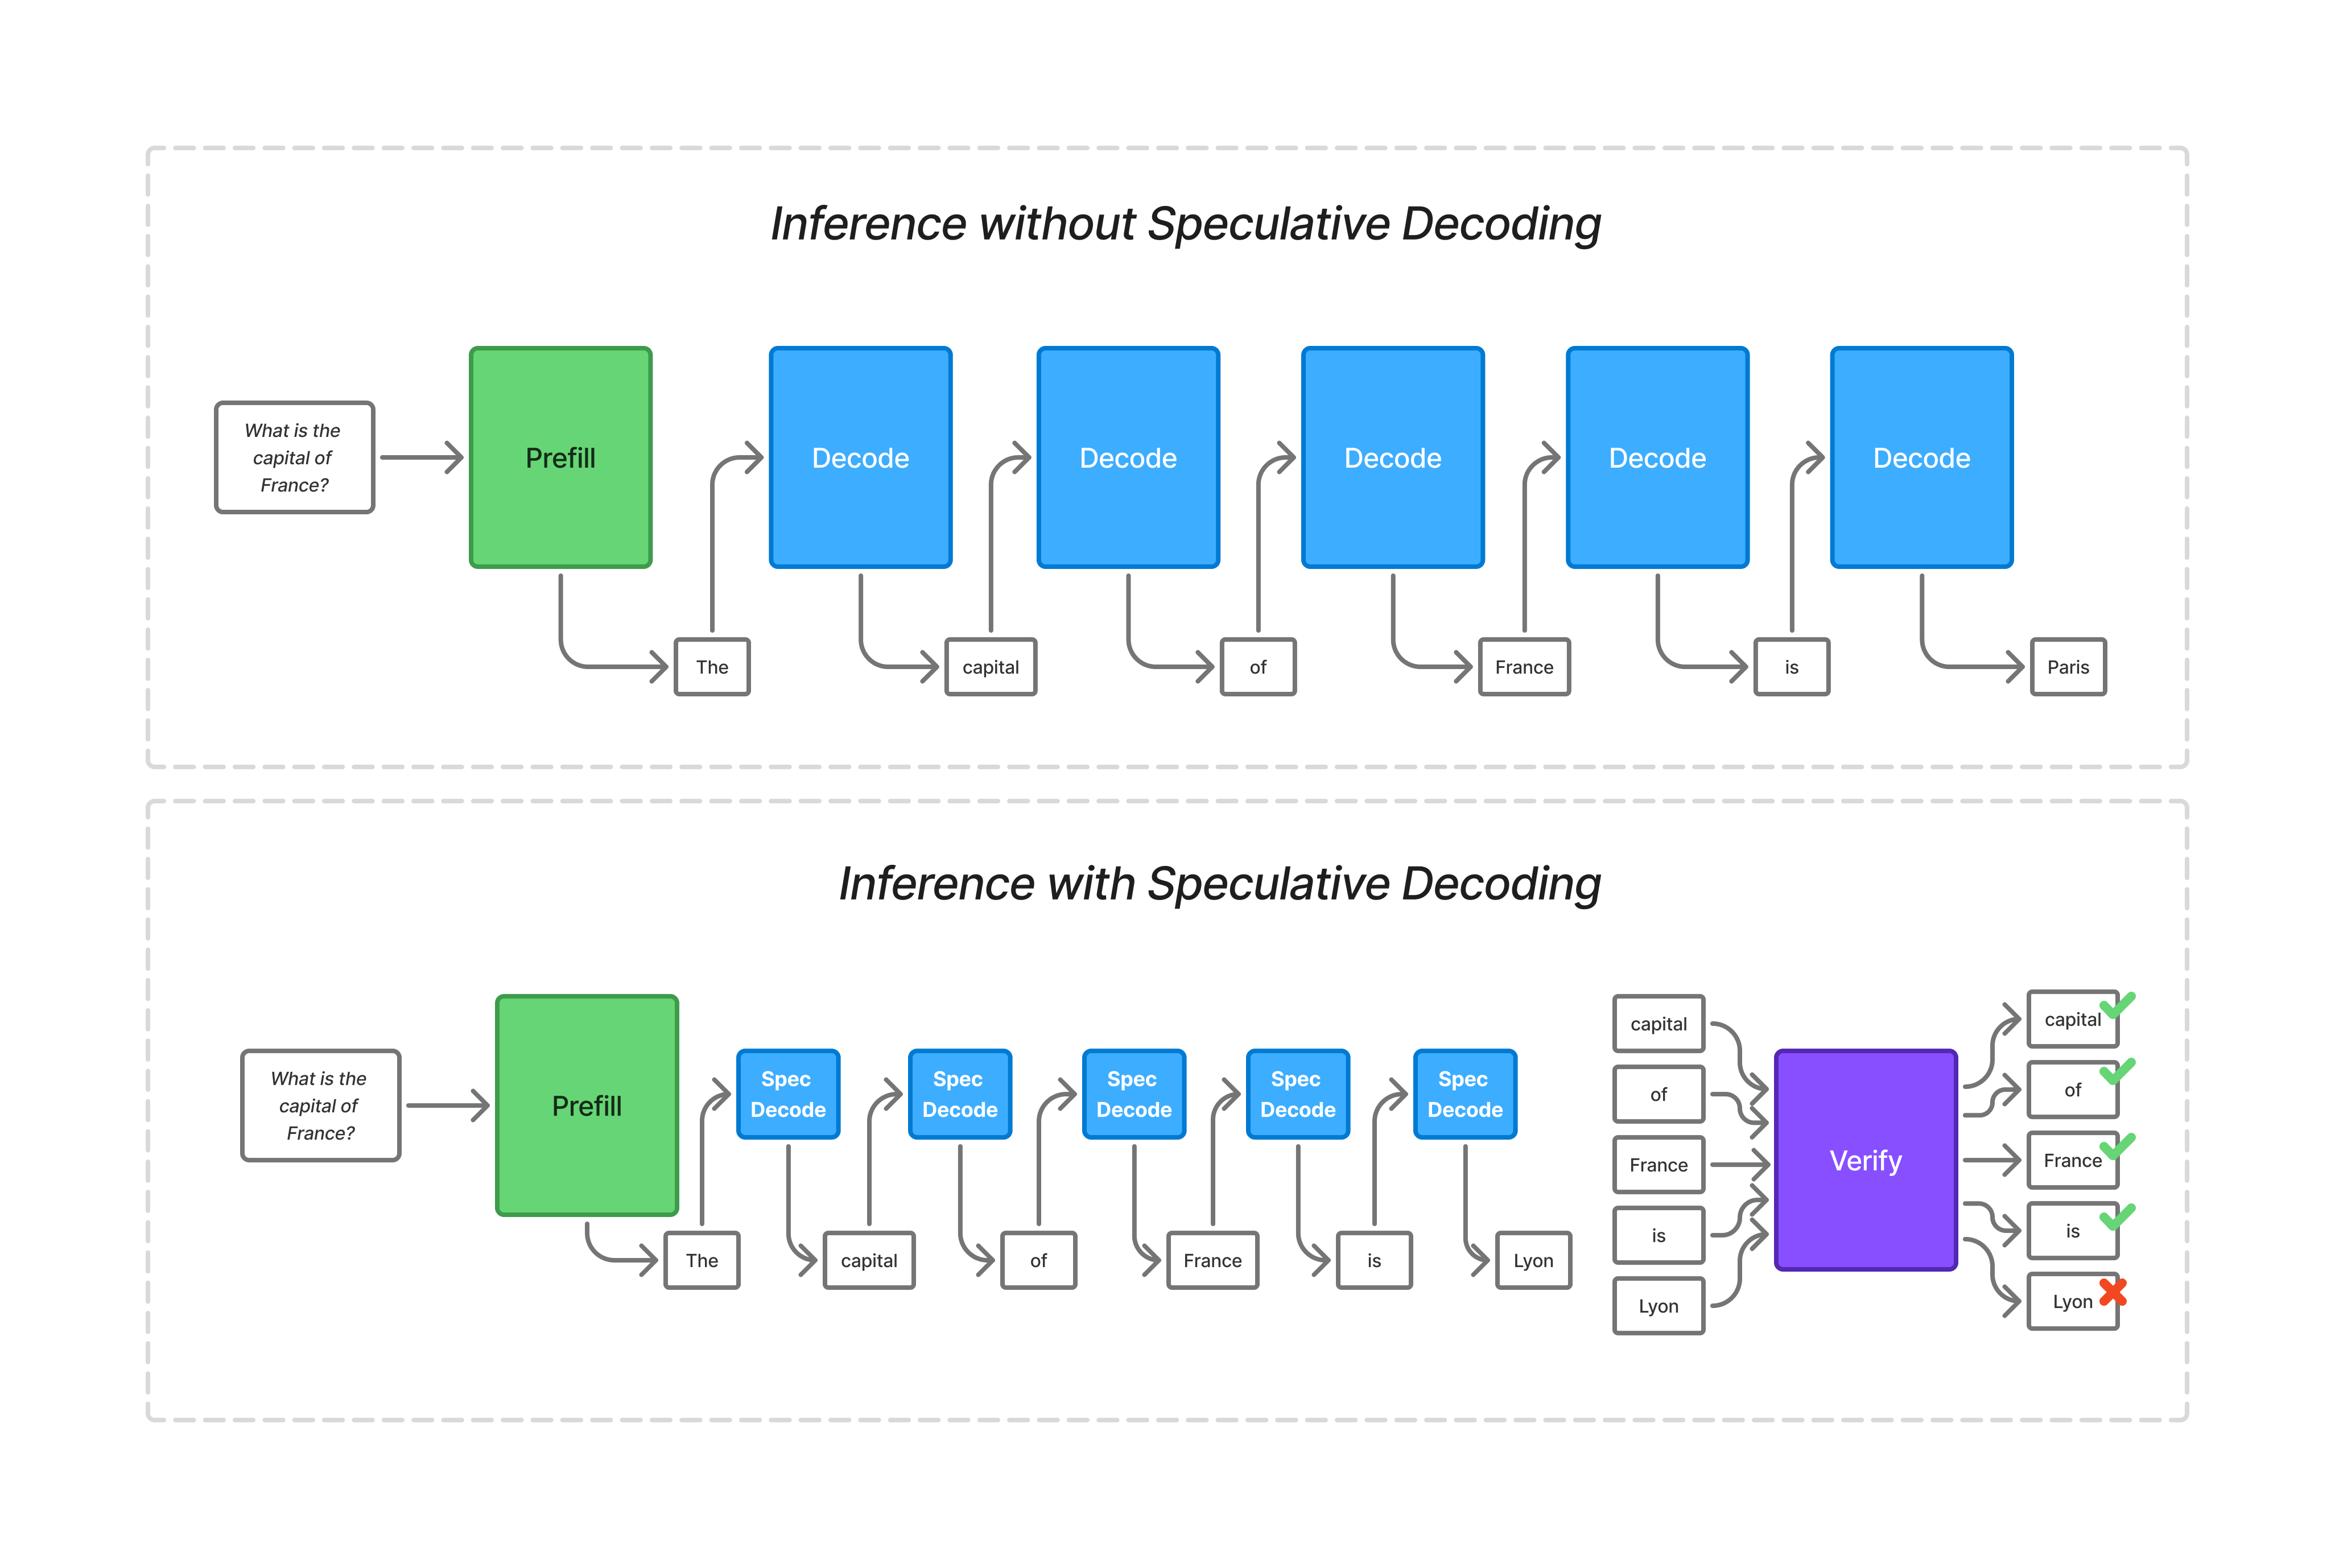
Low-Latency Inference with Speculative Decoding on d-Matrix Corsair and ...