
Scaled Dot Product Attention Explained The Core Of Transformers

Scaled Dot Product Attention Explained – The Core of Transformers ...
Scaled Dot-Product Attention — The Core Math of Transformers | tutorialQ
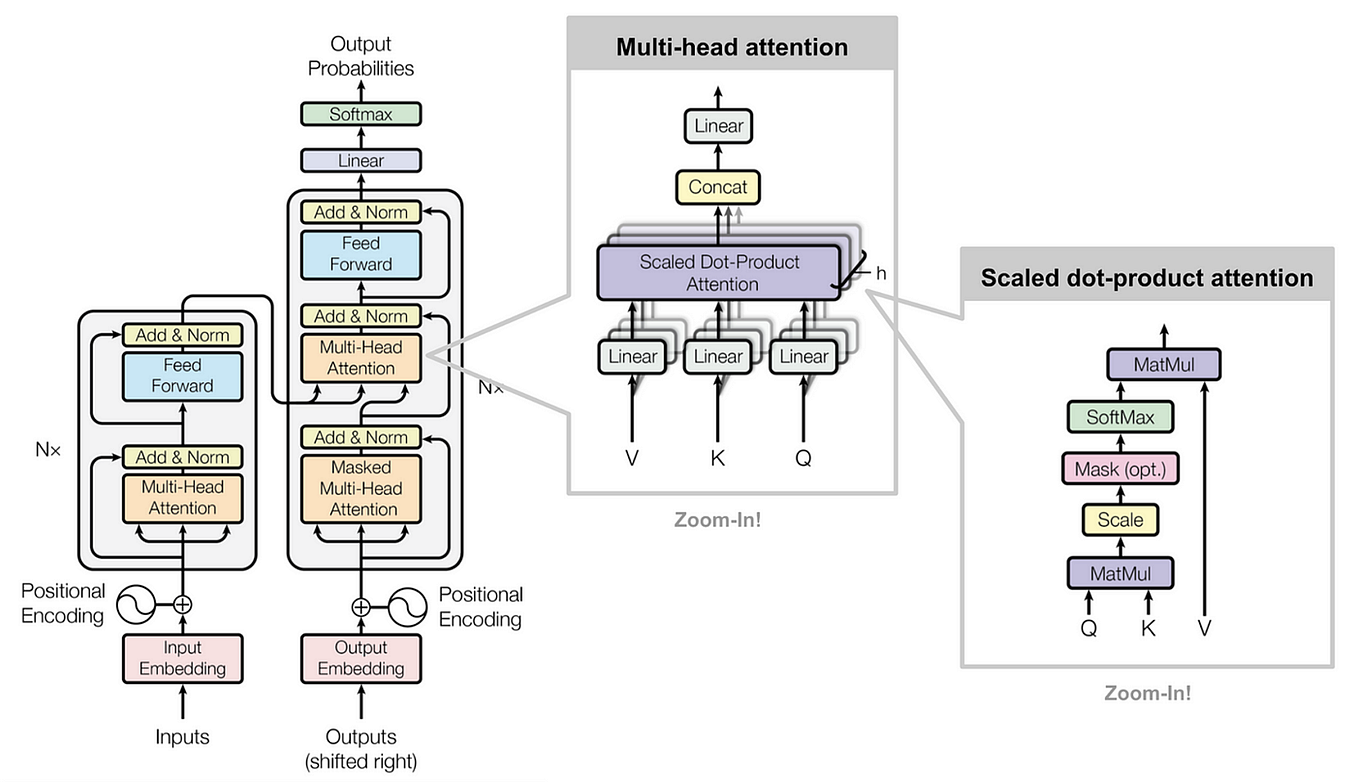
Self attention in transformers — Part 2 : Scaled Dot product Attention ...

1A - Scaled Dot Product Attention explained (Transformers) # ...

| Transformers use scaled dot product attention (A) and multi-head ...

| Transformers use scaled dot product attention (A) and multi-head ...

[PDF] Alternatives to the Scaled Dot Product for Attention in the ...

Graphical representations of scaled dot product attention (left) and ...

The structure of scaled dot-product attention (a) and multihead ...

Scaled dot product attention architecture. | Download Scientific Diagram
Advertisement Space (300x250)

Illustration of the scaled dot-product attention (left) and multi-head ...

Multi-head attention & scaled dot product attention (Vaswani et al ...
Illustration of the scaled dot-product attention (left) and multi-head ...

(i) Scaled dot product attention and (ii) Multi-head attention [25 ...

Scaled dot product attention architecture. | Download Scientific Diagram
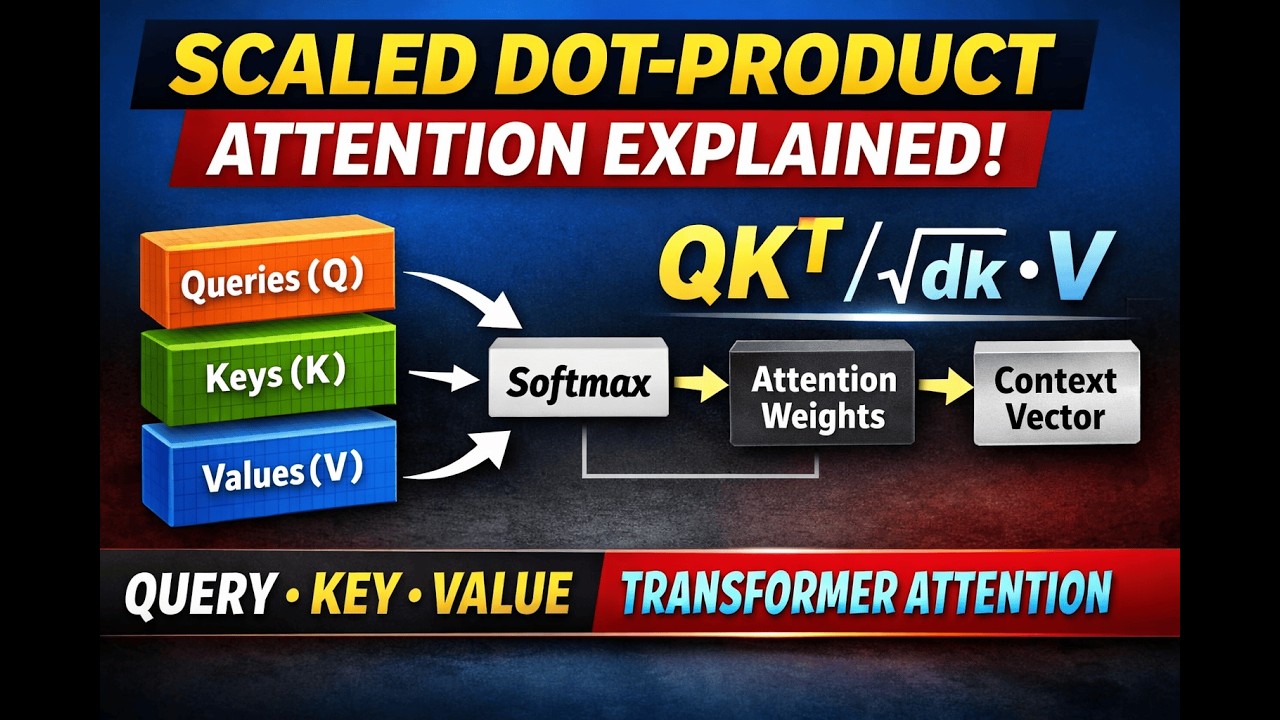
Scaled Dot-Product Attention Explained: How Transformers Use Queries ...

Understanding Attention Mechanisms: The Core Innovation Behind ...

, Architecture of Scaled Dot-Product Attention and Multi-Head Attention ...
Scaled Dot-Product Attention and Masking in Transformers | CodeSignal Learn

Transformer encoder block with multi-head attention and scaled dot ...
Advertisement Space (336x280)

a Scaled dot-product attention and b multi-head attention consisting of ...

[논문 리뷰] Implementing and Optimizing the Scaled Dot-Product Attention on ...

2. Illustration of scaled dot-product Left attention and multi-head ...

Scaled Dot-Product Attention (left). Multi-Head Attention consists of ...
Scaled Dot-Product Attention Explained
SCALED Dot-Product Attention Explained - YouTube

, Architecture of Scaled Dot-Product Attention and Multi-Head Attention ...

Multi-Head Attention model. See the h parallel Scaled Dot-Product ...
2: Transformer's Scaled Dot-Product Attention and Multi-Head Attention ...

Attention model in Transformer. (a) Scaled dot-product attention model ...
Advertisement Space (336x280)

Architecture of (a) scaled dot-product attention, (b) multi-head ...

(a) The Transformer model architecture. (b) Scaled Dot-Product ...

Making Sense of the Transformer | Subhasmita Swain

(PDF) A Survey of Visual Transformers

Scaled dot-product attention and multi-head attention in Transformer ...

Multi-Head Attention in Transformers Explained: Concepts, Math & Mechanics