
Self Attention Using Scaled Dot Product Approach Youtube

self attention using scaled dot product approach - YouTube

Scaled Dot Product Self Attention on all Inputs - YouTube

Scaled Dot Product Attention | Why do we scale Self Attention? - YouTube

Transformer Self attention - Scaled Dot Product Attention - YouTube

Scaled Dot Product Attention Explained + Implemented - YouTube
Self attention in transformers — Part 2 : Scaled Dot product Attention ...

Self-Attention Using Scaled Dot-Product Approach - YouTube

Scaled Dot Product Attention explained (Transformers) #transformers # ...

Scaled Dot Product Attention Explained – The Core of Transformers ...

scaled dot product and multi-head attention explained from scratch ...
Advertisement Space (300x250)

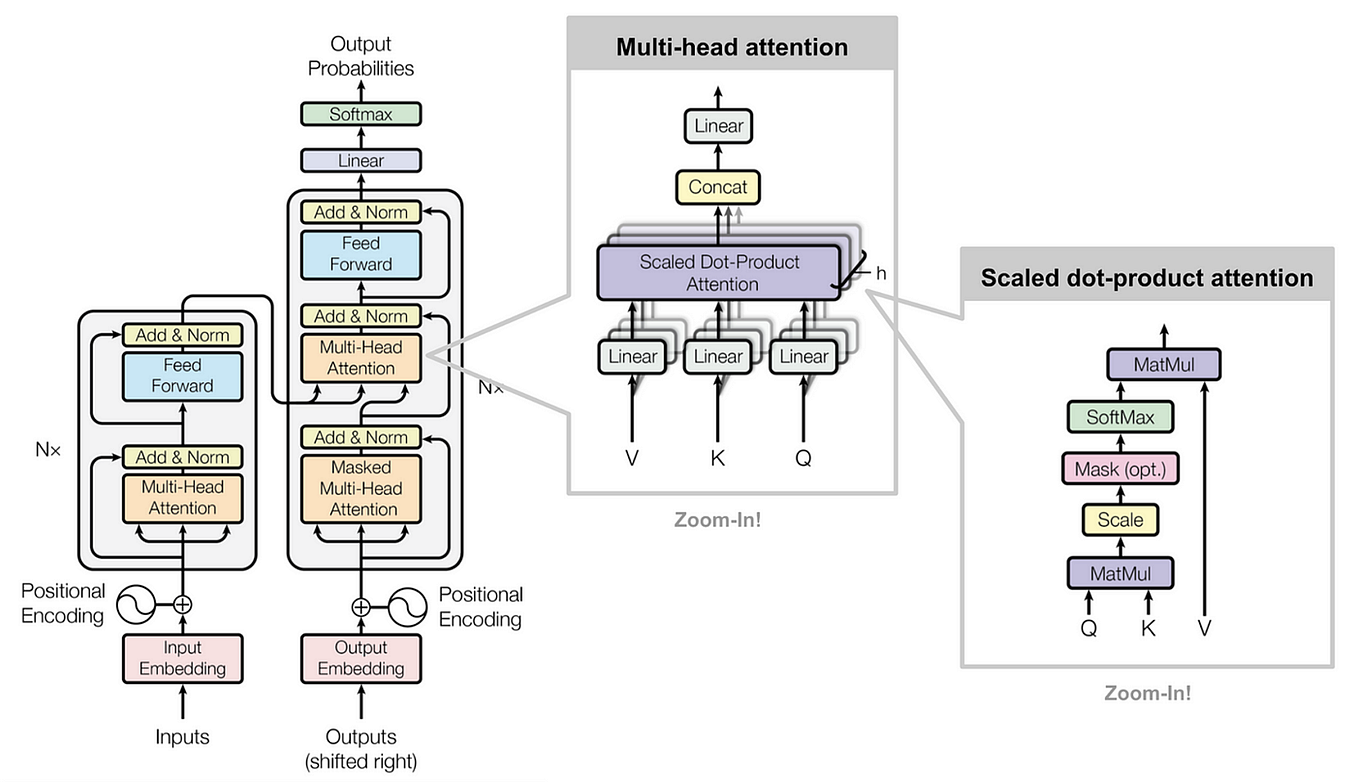
Multi-head attention & scaled dot product attention (Vaswani et al ...

Scaled dot product attention architecture. | Download Scientific Diagram

L19.4.2 Self-Attention and Scaled Dot-Product Attention - YouTube
SCALED Dot-Product Attention Explained - YouTube

2. Scaled dot-product attention - (2/3) - YouTube

2. Scaled dot-product attention - (1/3) - YouTube
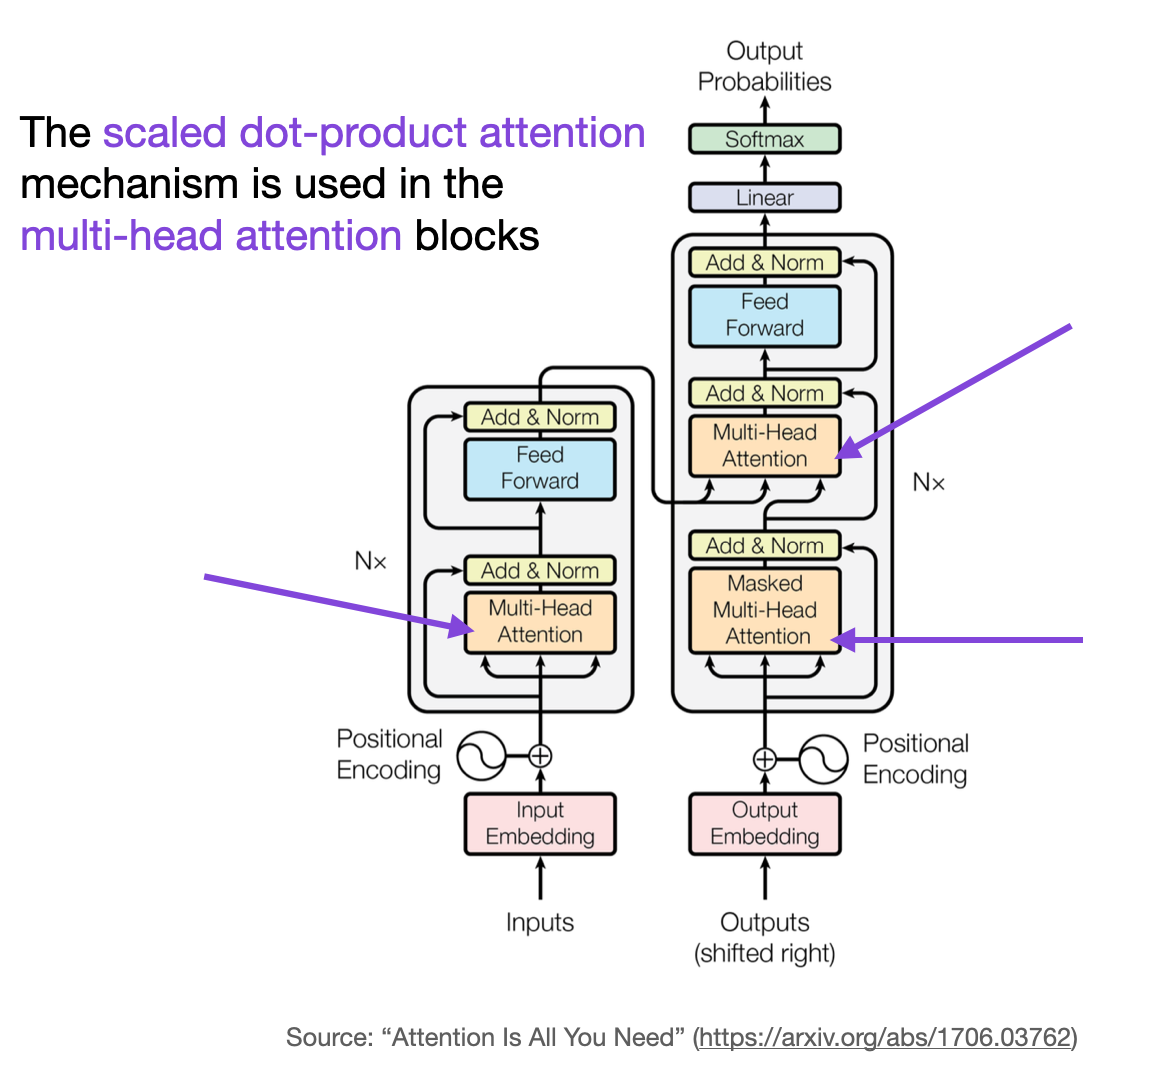
torch attention | torch nnn scaled dot – FYKH

Transformer encoder block with multi-head attention and scaled dot ...

Multi-head self-attention module (MSAM) computes scaled dot product ...
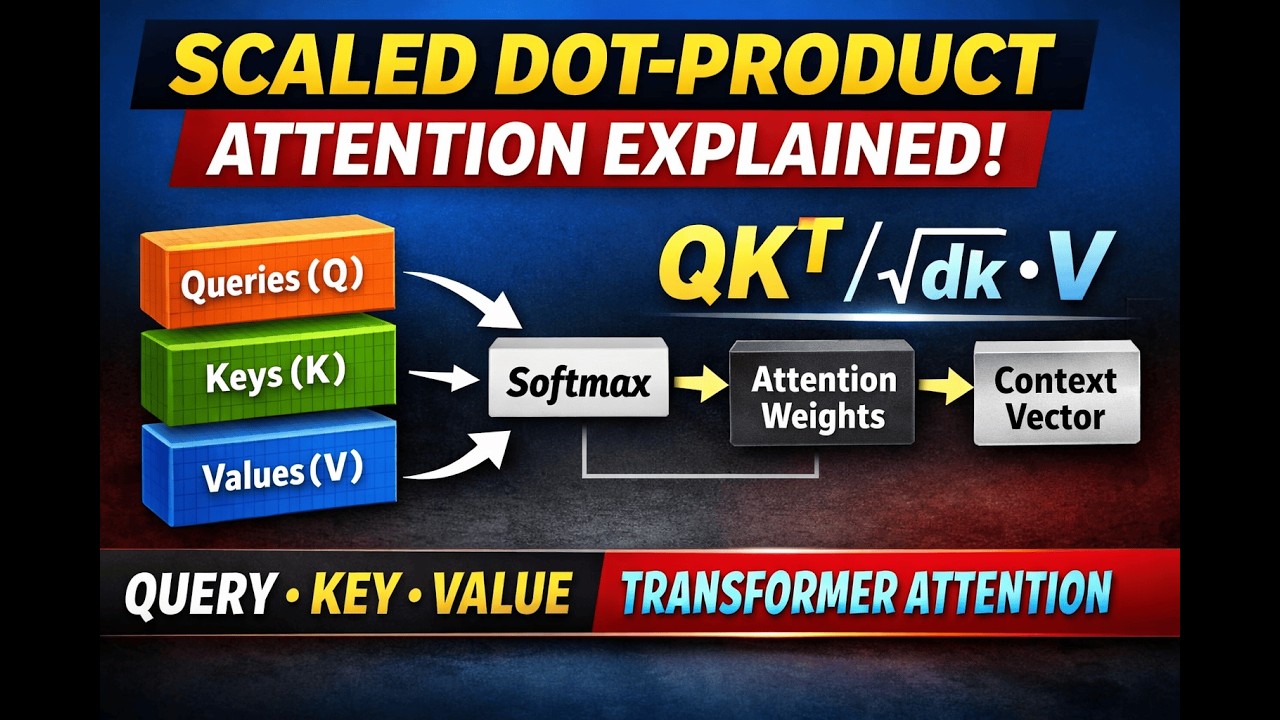
Scaled Dot-Product Attention Explained: How Transformers Use Queries ...
Advertisement Space (336x280)
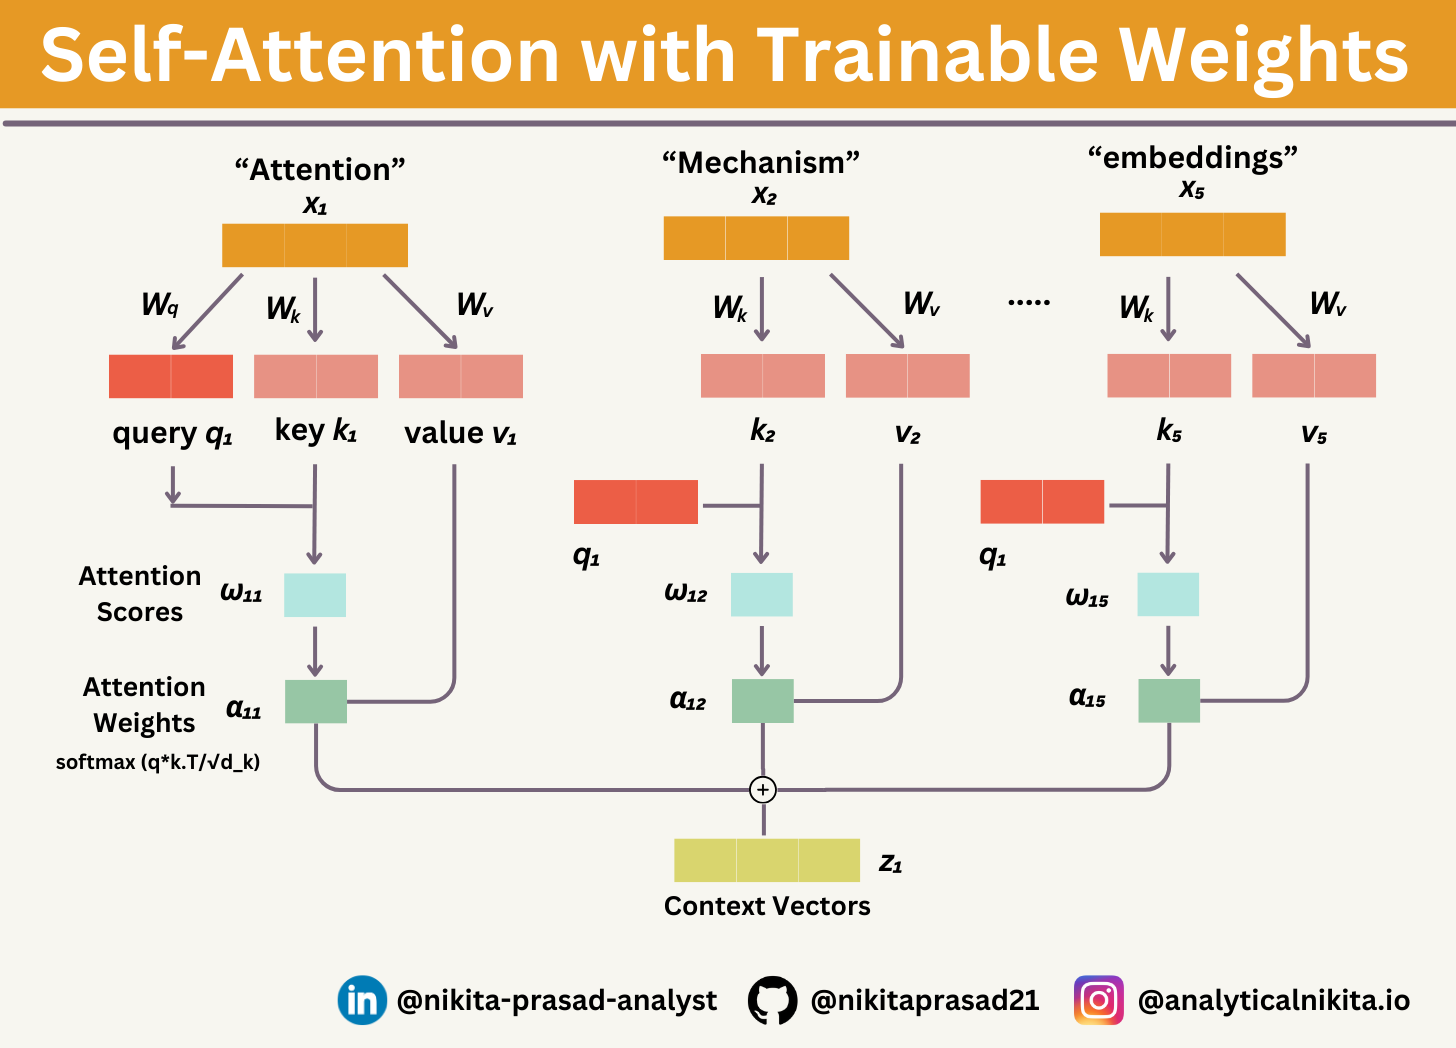
Scaled Dot-Product Attention Explained! - by Nikita Prasad

Scaled dot-product attention mechanism | Download Scientific Diagram

Attention model in Transformer. (a) Scaled dot-product attention model ...
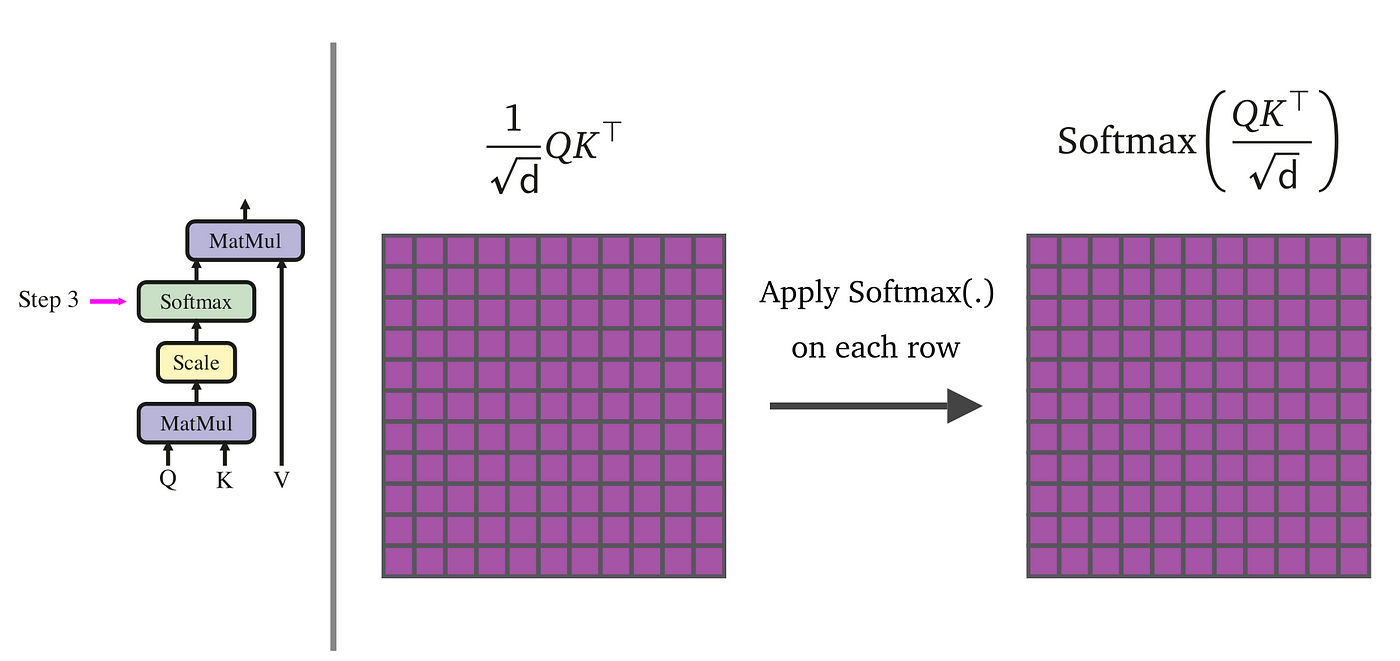
Demystifying Scaled Dot-Product Attention

(a) Scaled dot-product attention and (b) multi-head attention represent ...

How to Implement Scaled Dot-Product Attention from Scratch in ...

Scaled dot-product attention mechanism | Download Scientific Diagram
Multi-head attention schematic Scaled dot-product attention is the ...

The structure of scaled dot-product attention (a) and multihead ...

Scaled Dot-Product Attention implements projection of inputs onto a ...
Advertisement Space (336x280)

2. Illustration of scaled dot-product Left attention and multi-head ...

Scaled Dot-Product Attention Explained: Why We Divide by √dₖ in ...

Self-Attention Explained: Implementing Scaled Dot-Product Attention ...

Scaled Dot-Product Attention

Scaled dot‐product attention structure. | Download Scientific Diagram

Multi-Head Attention model. See the h parallel Scaled Dot-Product ...