
Sharding Large Models For Parallel Inference By Shashank Jain Medium
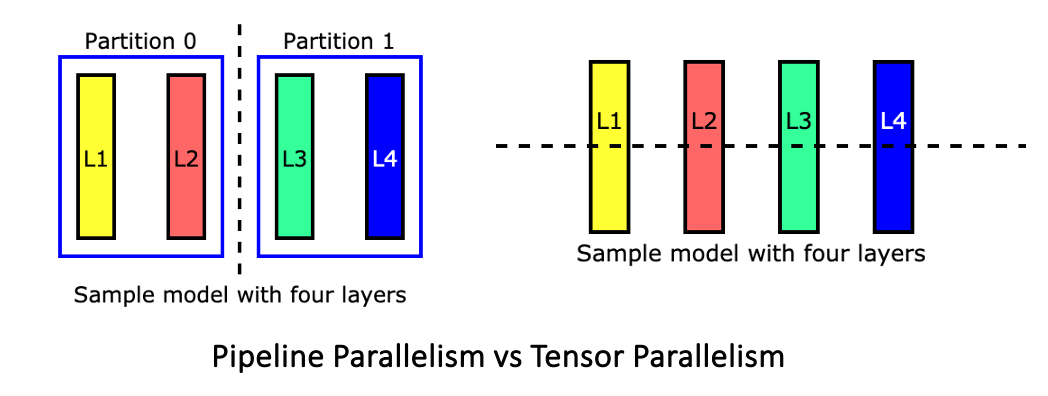
Sharding Large models for parallel inference | by shashank Jain | Medium
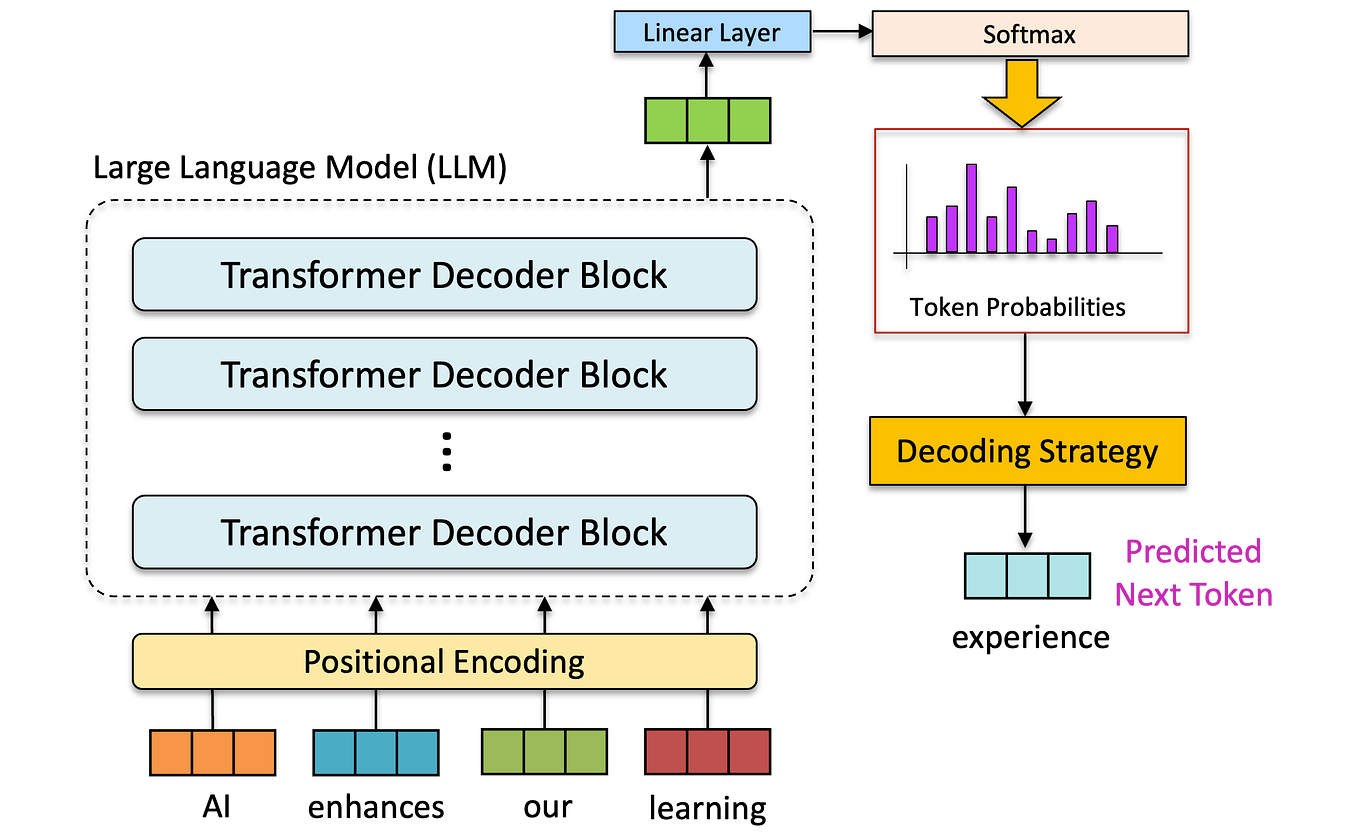
Embeddings in Large Language Models (LLMs) | by Shashank Agarwal | Medium

Falcon: Faster and Parallel Inference of Large Language Models through ...

Blogs generated by Nous-Hermes-13b LLM | by shashank Jain | Medium

[논문 리뷰] Falcon: Faster and Parallel Inference of Large Language Models ...

Sampling Techniques in Large Language Models (LLMs) | by Shashank ...

Figure 3 from Hybrid Parallel Inference for Large Model on ...

Sampling Techniques in Large Language Models (LLMs) | by Shashank ...

Paper page - HeteGen: Heterogeneous Parallel Inference for Large ...

[论文评述] Collaborative Inference for Large Models with Task Offloading ...
Advertisement Space (300x250)

Sharding Large Models with Tensor Parallelism

Sharding Large Models with Tensor Parallelism

7 JAX Sharding Patterns That Scale Without Pain | by Nexumo | Medium
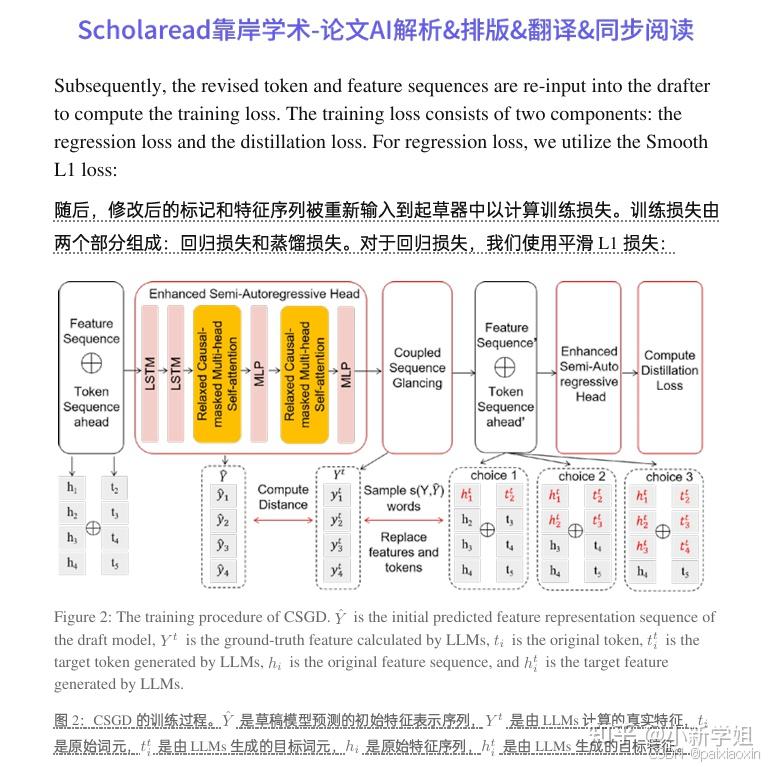
AAAI2025最新论文解读|Falcon: Faster and Parallel Inference of Large Language ...
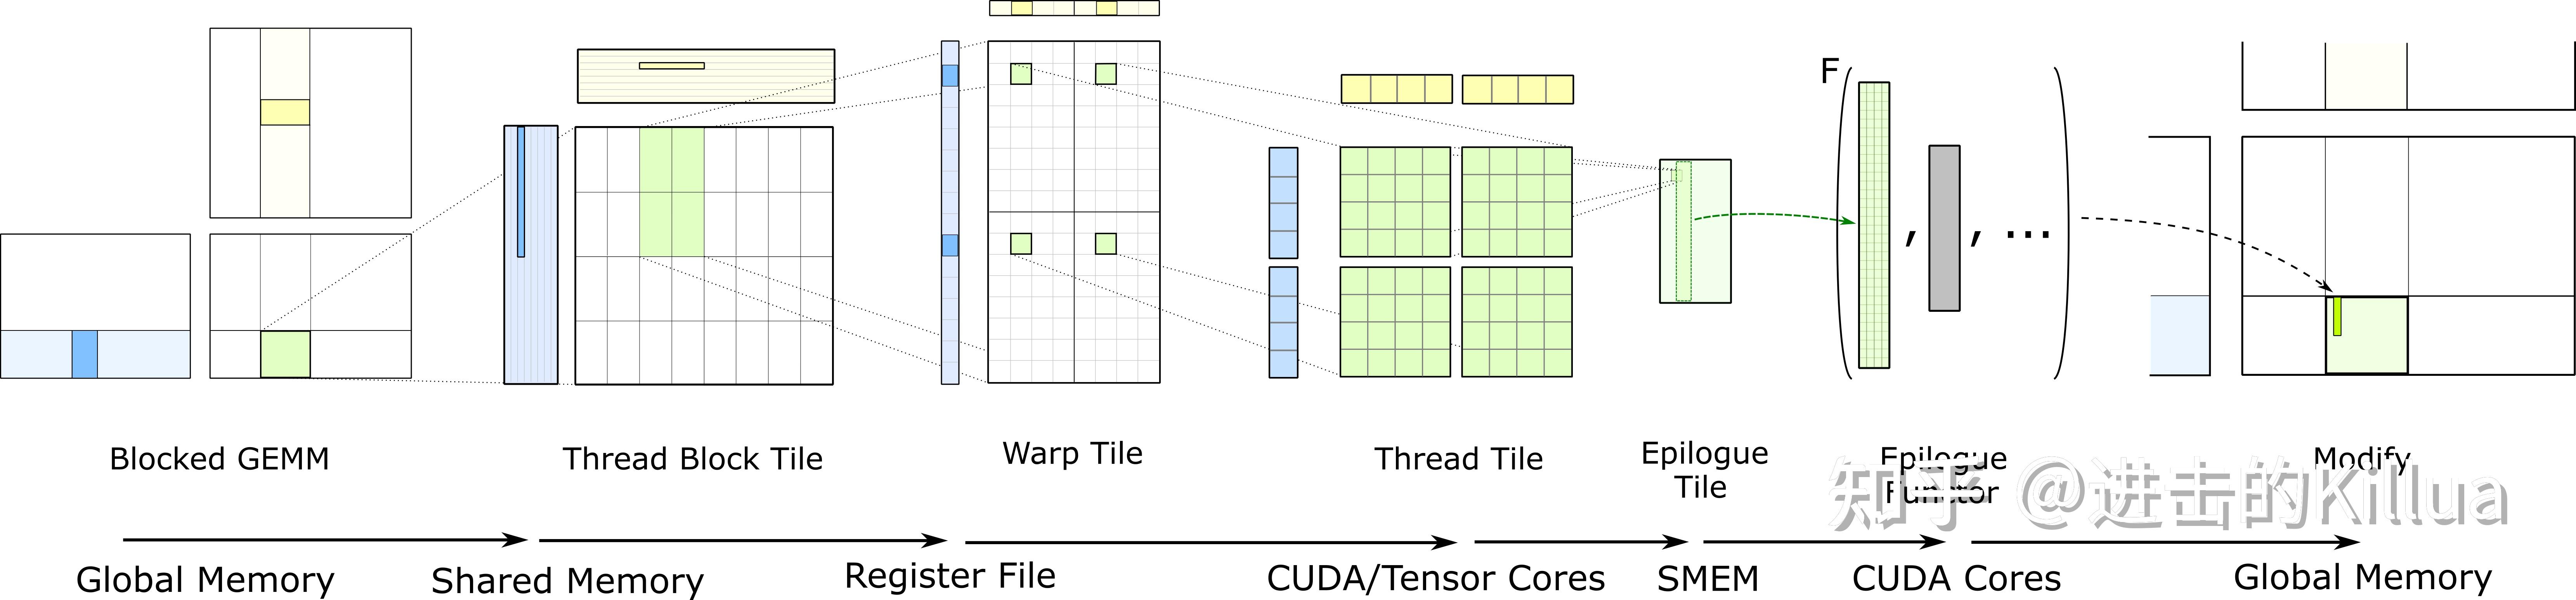
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large ...

DistriFusion: Distributed Parallel Inference for High-Resolution ...

MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large ...
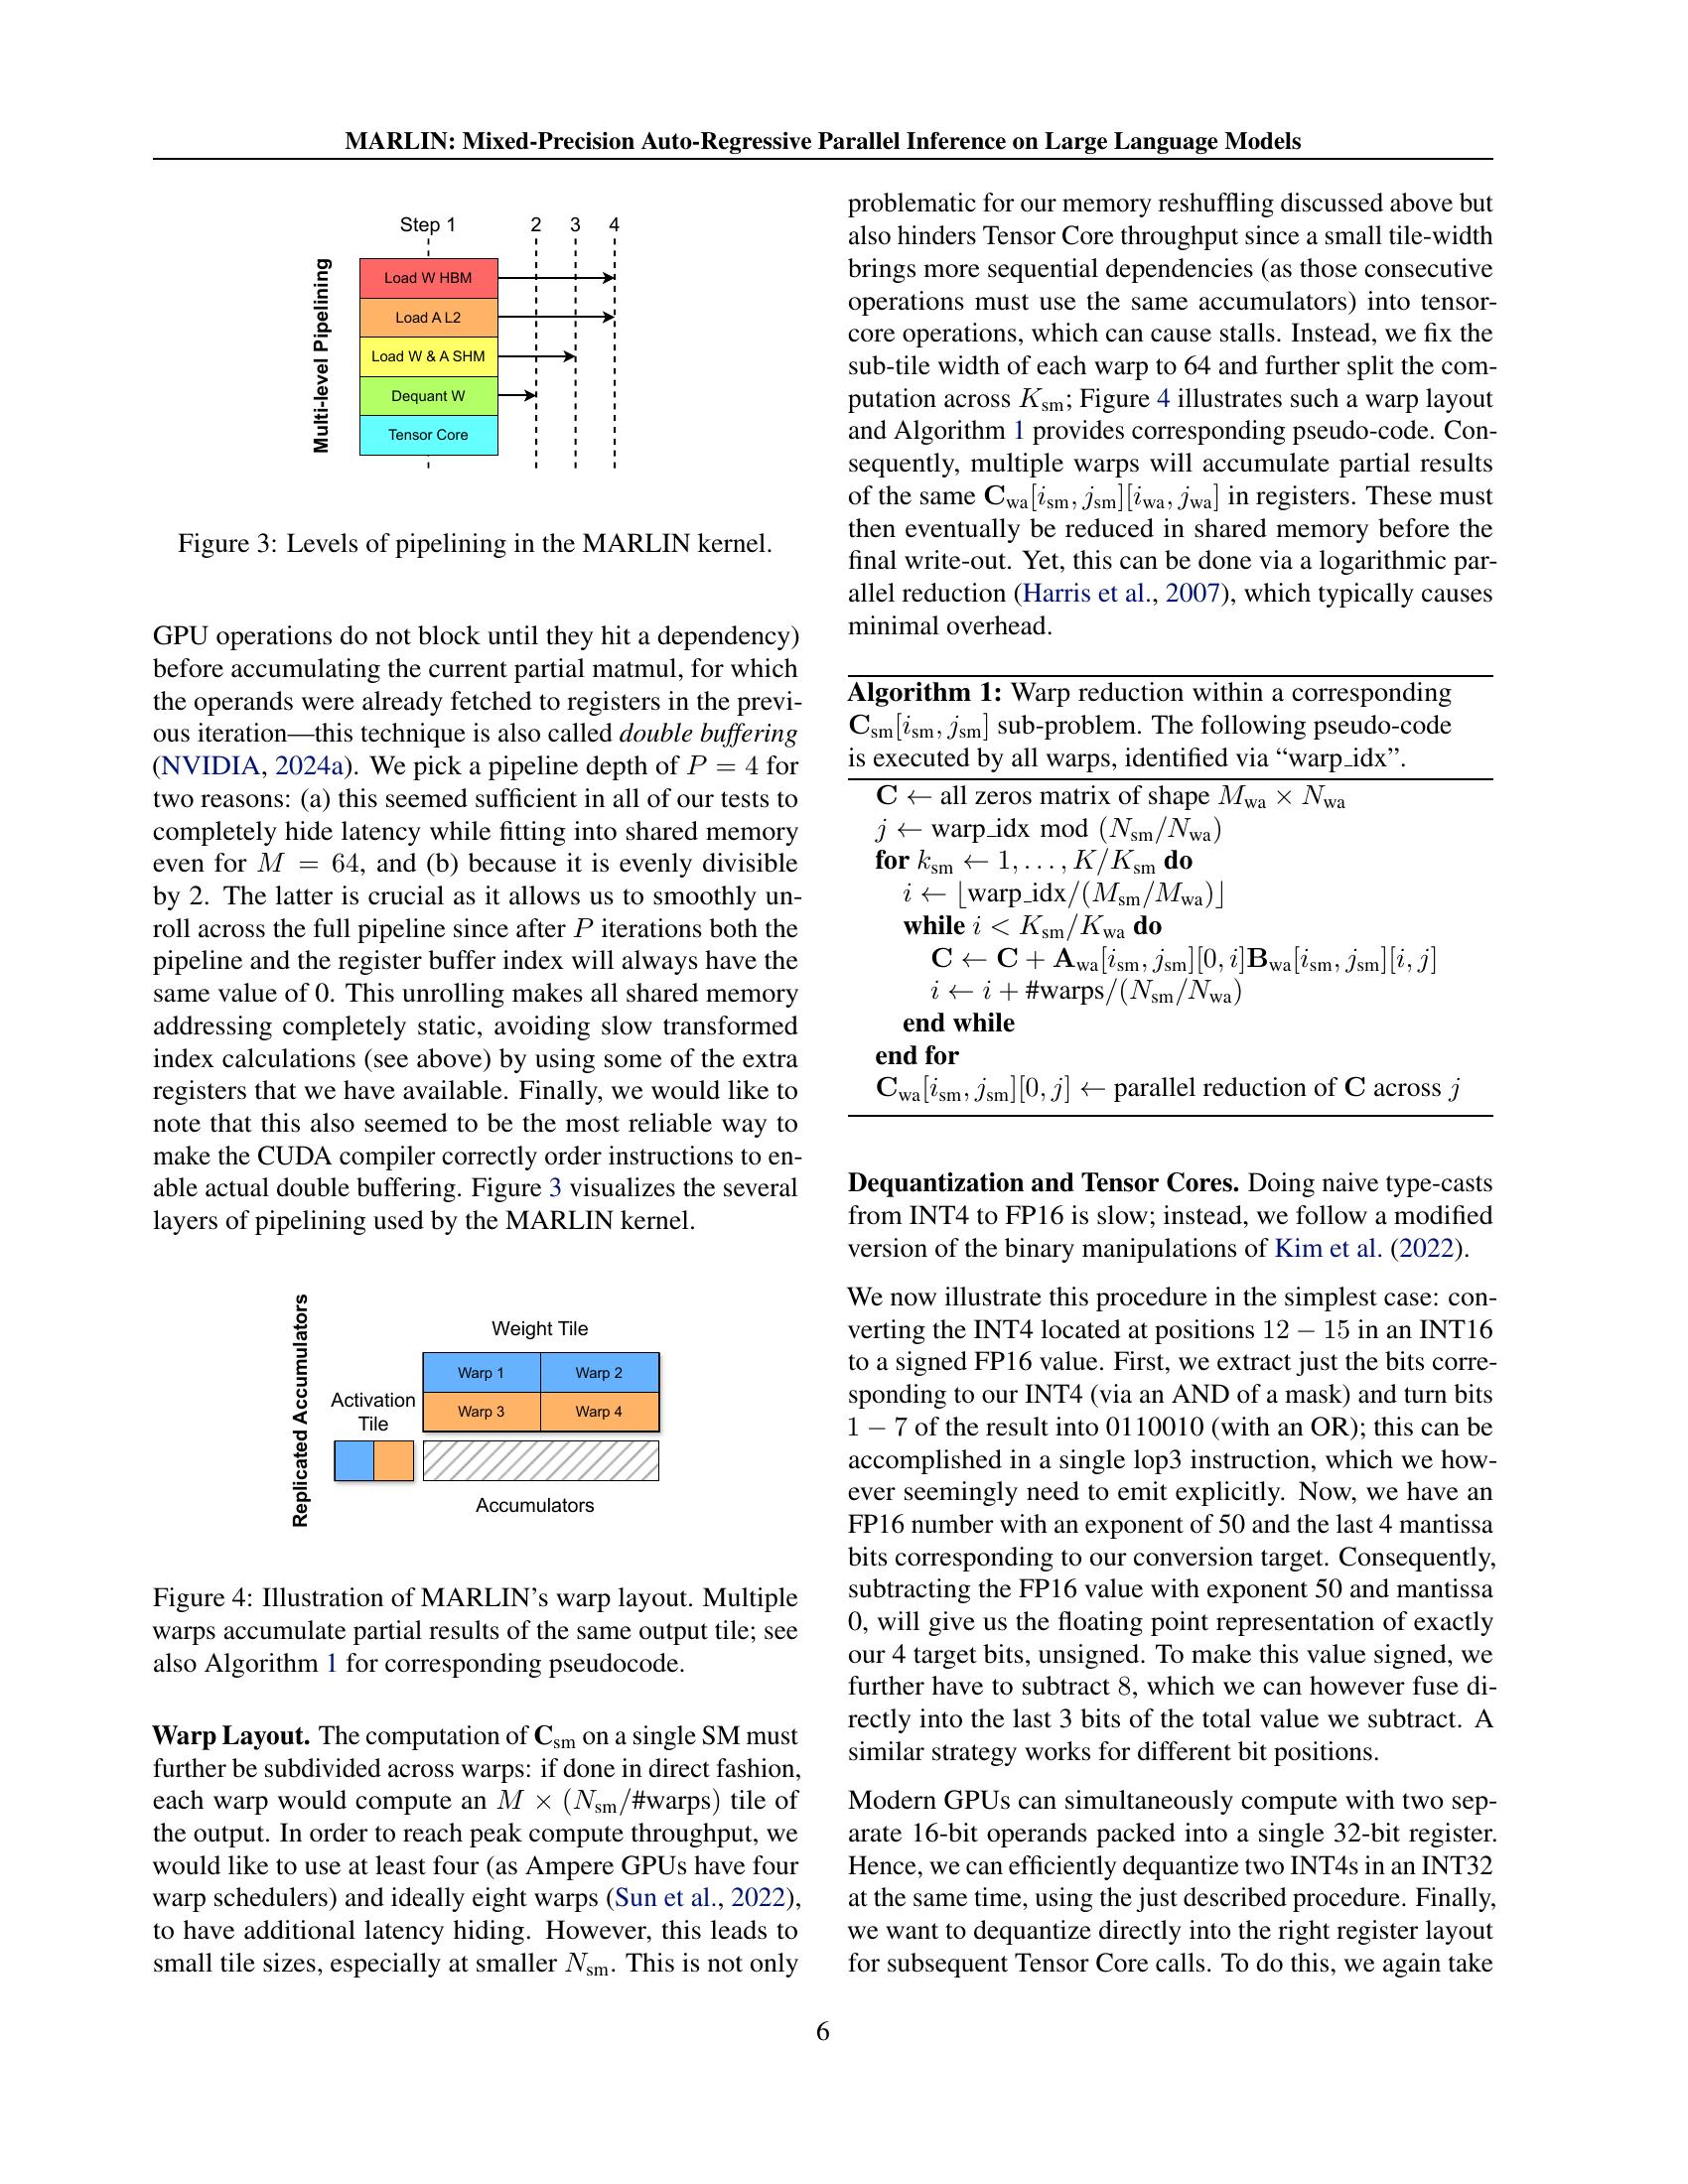
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large ...

Paper page - Efficient Inference for Large Reasoning Models: A Survey

Figure 2 from A parallel inference model for logic programming ...
Advertisement Space (336x280)

Up to 36x Speedup: Mask-based Parallel Inference Paradigm for Key ...

Accelerating Large Language Model Inference with Smart Parallel Auto ...
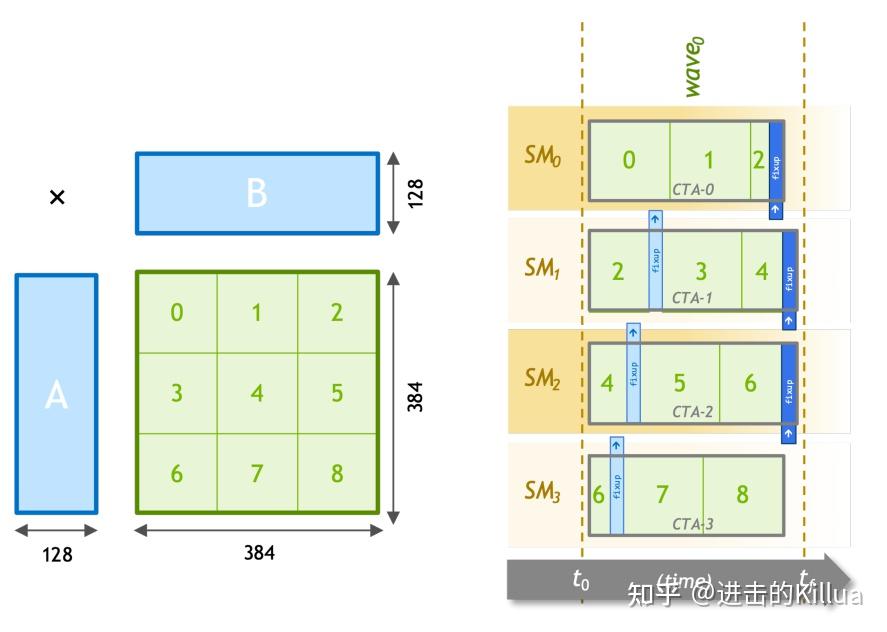
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large ...

Paper page - DistriFusion: Distributed Parallel Inference for High ...
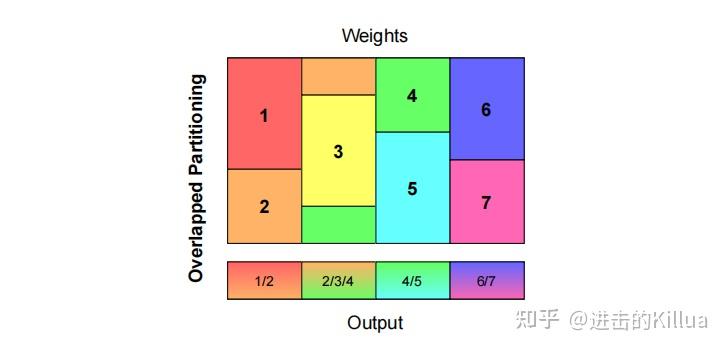
MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large ...
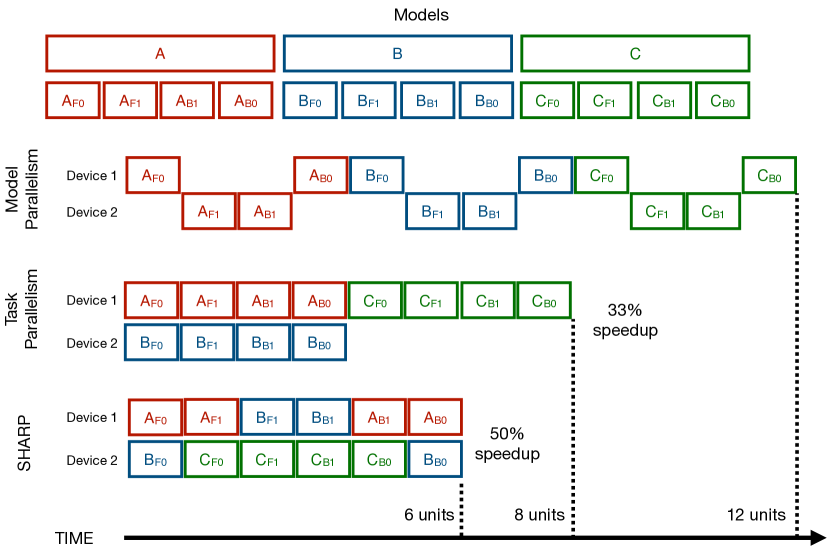
[2301.02691] Systems for Parallel and Distributed Large-Model Deep ...

Parallelism Techniques for LLM Inference — AWS Neuron Documentation
Implementing a Fully Automated Sharding Strategy on Kubernetes for ...

An Effective Sharding Consensus Algorithm for Blockchain Systems
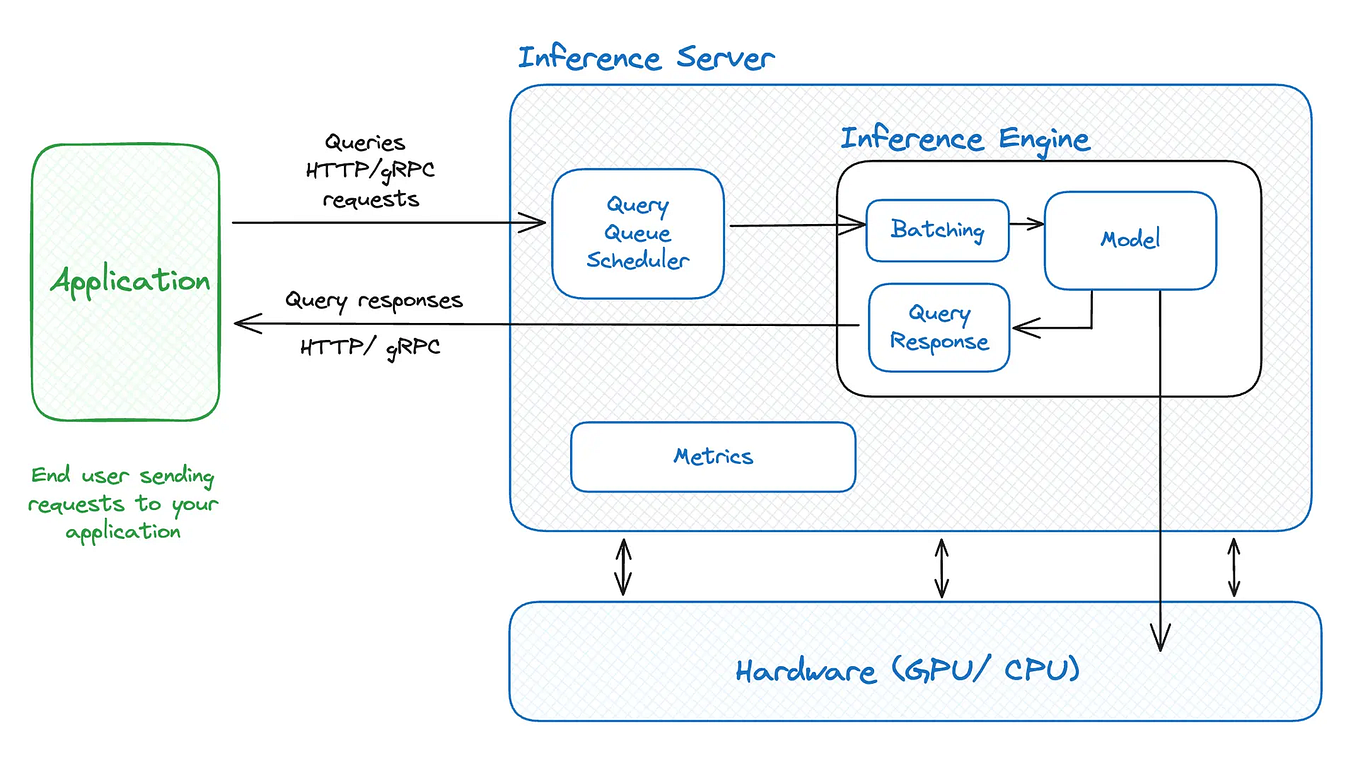
Harmonizing Multi-GPUs: Efficient Scaling of LLM Inference | by TitanML ...
Advertisement Space (336x280)
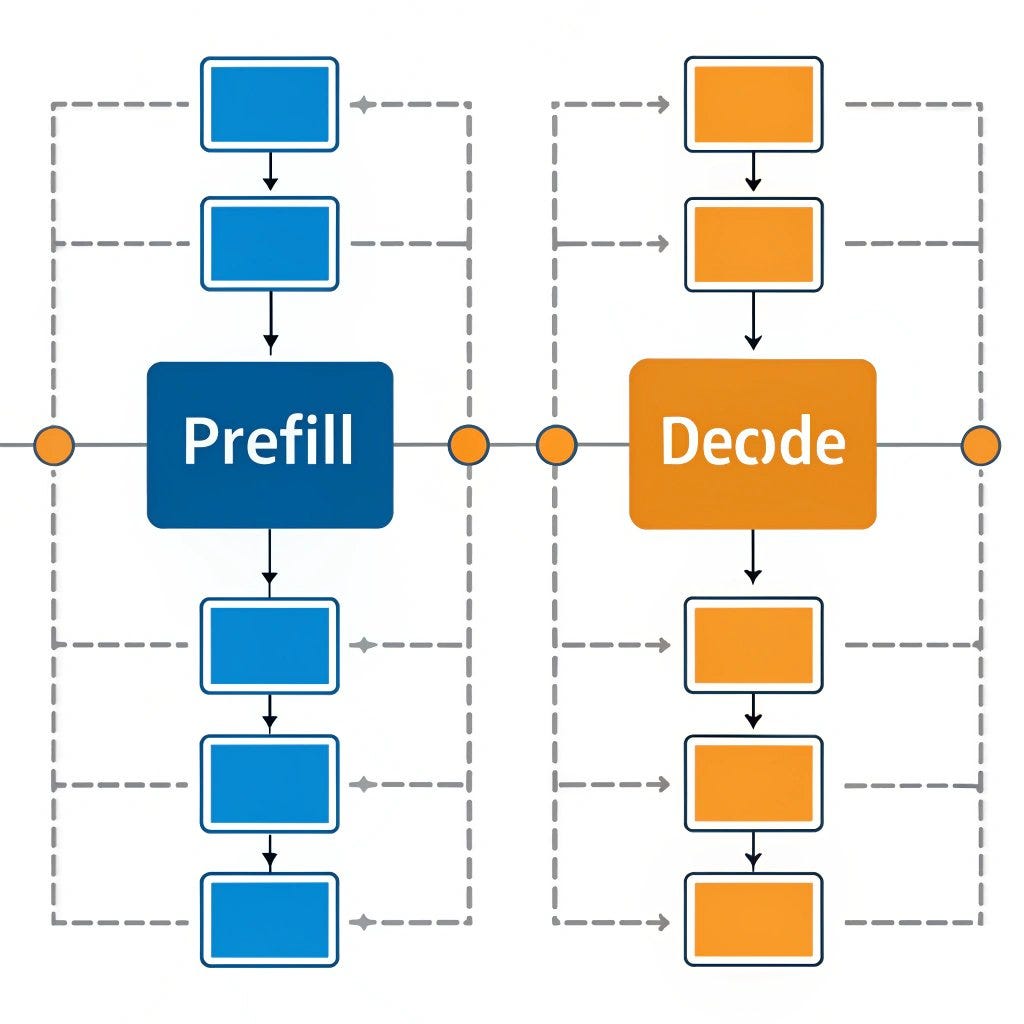
Accelerating Language Models with Multi-Token Prediction | by Himank ...
Decentralized Inference. Dynamic Sharding of Arbitrary Neural… | by ...
Sharding: Database Partitioning for Scalability | Inference Systems

A Review on Blockchain Sharding for Improving Scalability

Free Video: More Than Model Sharding - LWS and Distributed Inference ...
LLM Batch Inference. Overview | by Chang | Dec, 2024 | Medium