
Specoffload Unlocking Latent Gpu Capacity For Llm Inference On

[论文评述] SpecOffload: Unlocking Latent GPU Capacity for LLM Inference on ...

147SpecOffload Unlocking Latent GPU Capacity For | PDF | Graphics ...

Best Gpu For Llm Inference And Training – ONZVM

Practical offloading for fine-tuning LLM on commodity GPU via learned ...

Parallel CPU-GPU Execution for LLM Inference on Constrained GPUs | AI ...

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...

How to Give Your RTX GPU Nearly Infinite Memory for LLM Inference
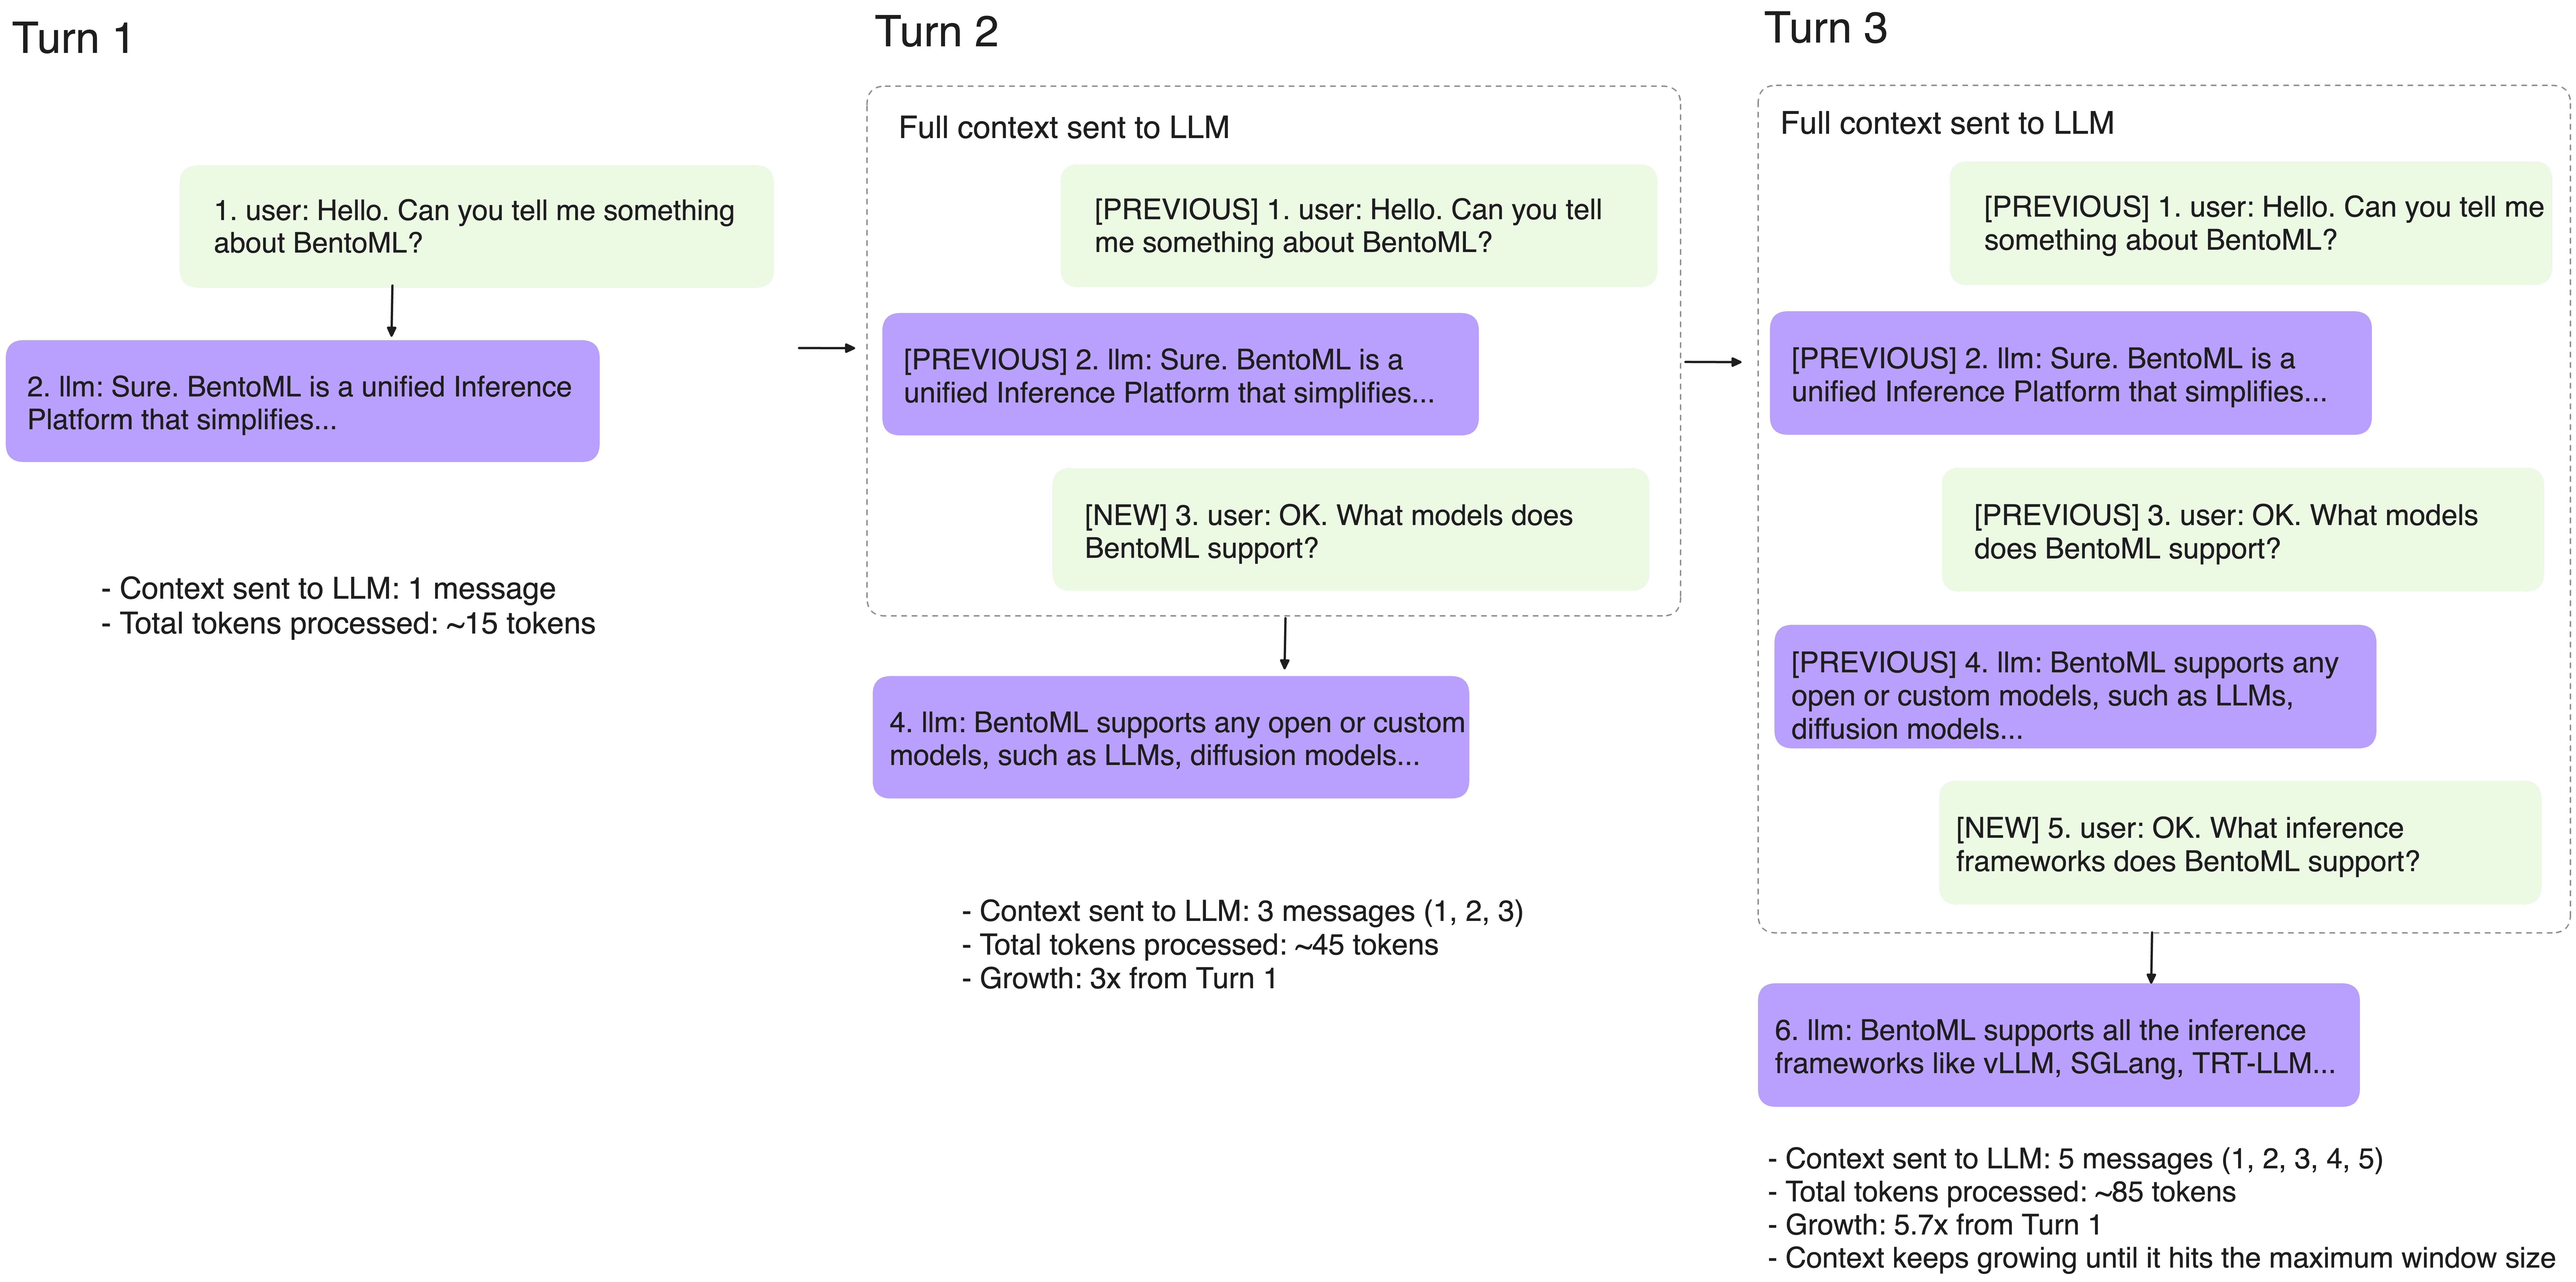
What is GPU Memory and Why it Matters for LLM Inference

Figure 1 from Practical Offloading for Fine-Tuning LLM on Commodity GPU ...

Top 10 GPU Wins for Cheaper LLM Inference (2025) | by Thinking Loop ...
Advertisement Space (300x250)

NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference
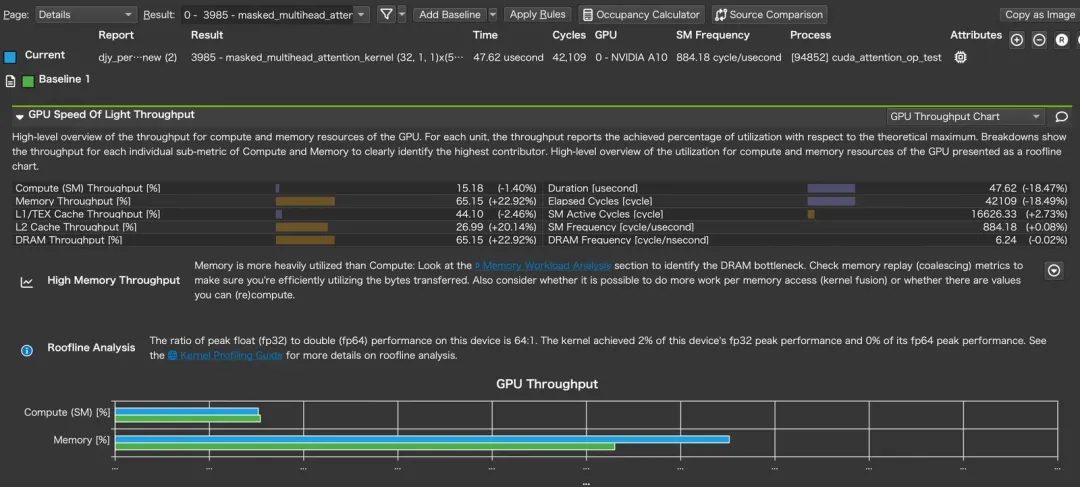
LLM Inference Acceleration: GPU Optimization for Attention in the ...

NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference
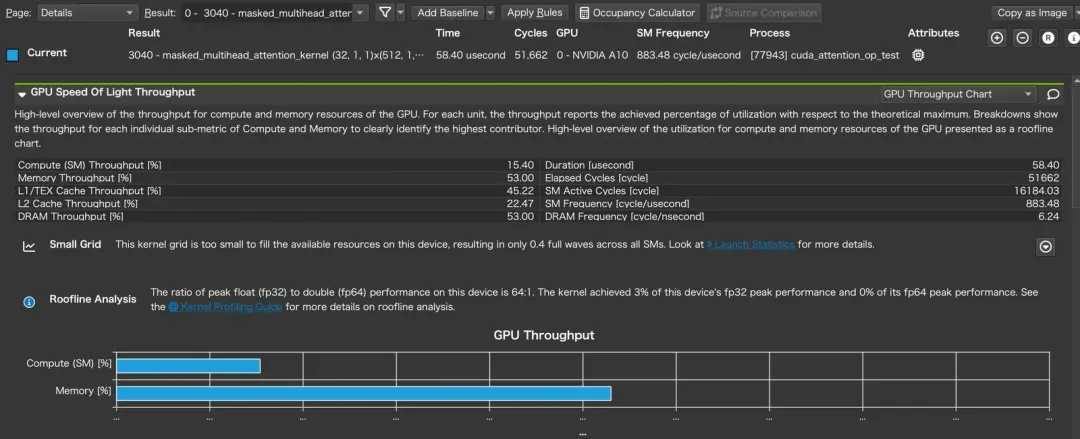
LLM Inference Acceleration: GPU Optimization for Attention in the ...

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...
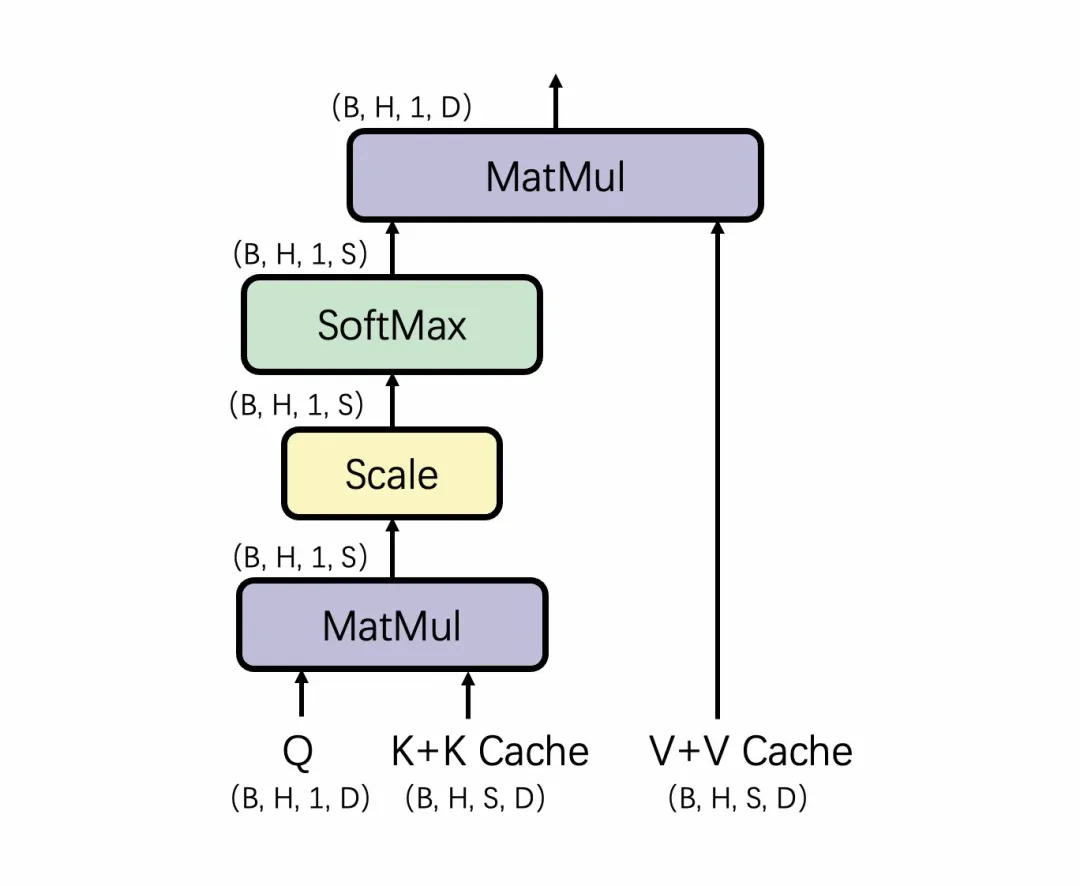
LLM Inference Acceleration: GPU Optimization for Attention in the ...
Test-Time Training on GPU Cloud: Deploy TTT Layers for Adaptive LLM ...

What is GPU Memory and Why it Matters for LLM Inference
Advertisement Space (336x280)
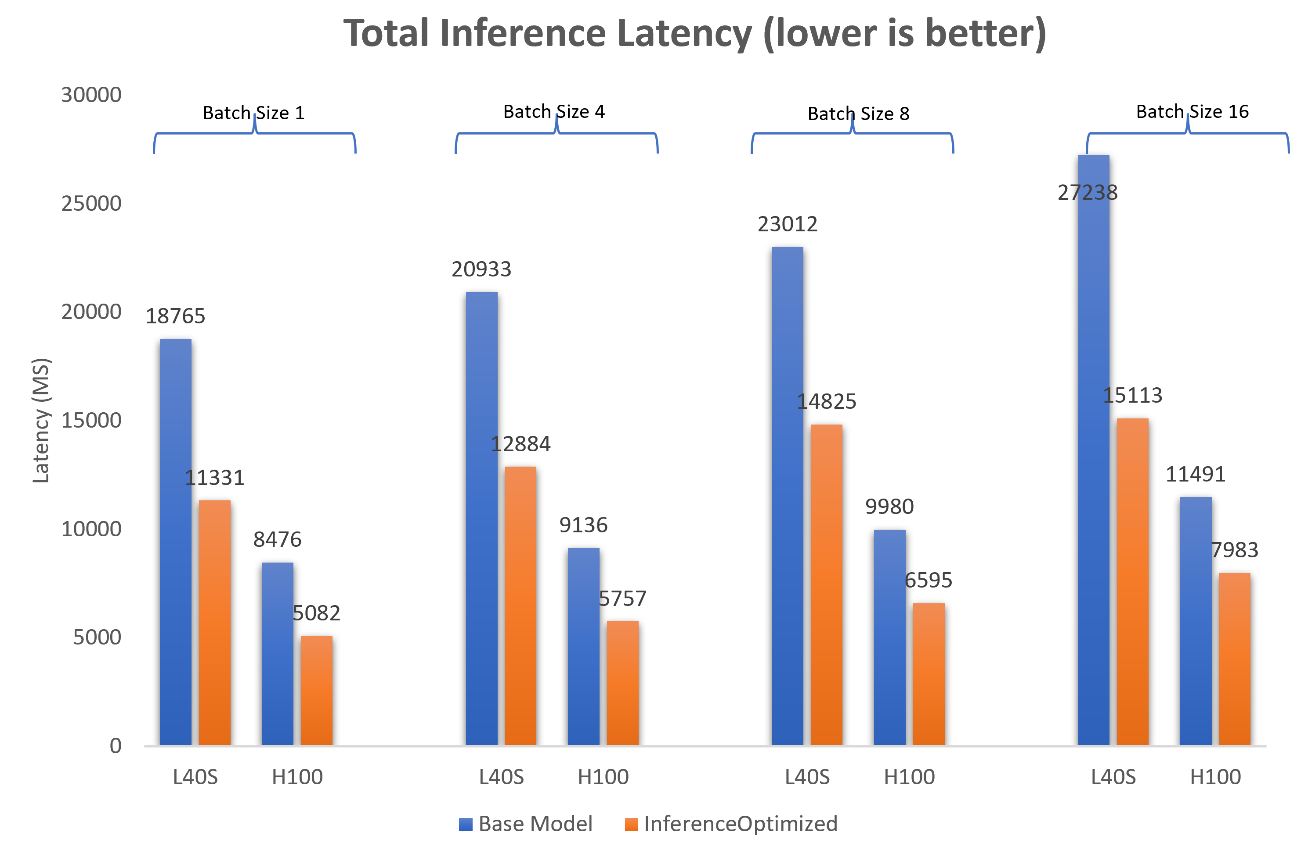
Unlocking LLM Performance: Advanced Inference Optimization Techniques ...

Advanced Optimization Strategies for LLM Training on NVIDIA Grace ...

Free Inference Serving Capacity Planner: GPU Sizing & Cost Optimization ...

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
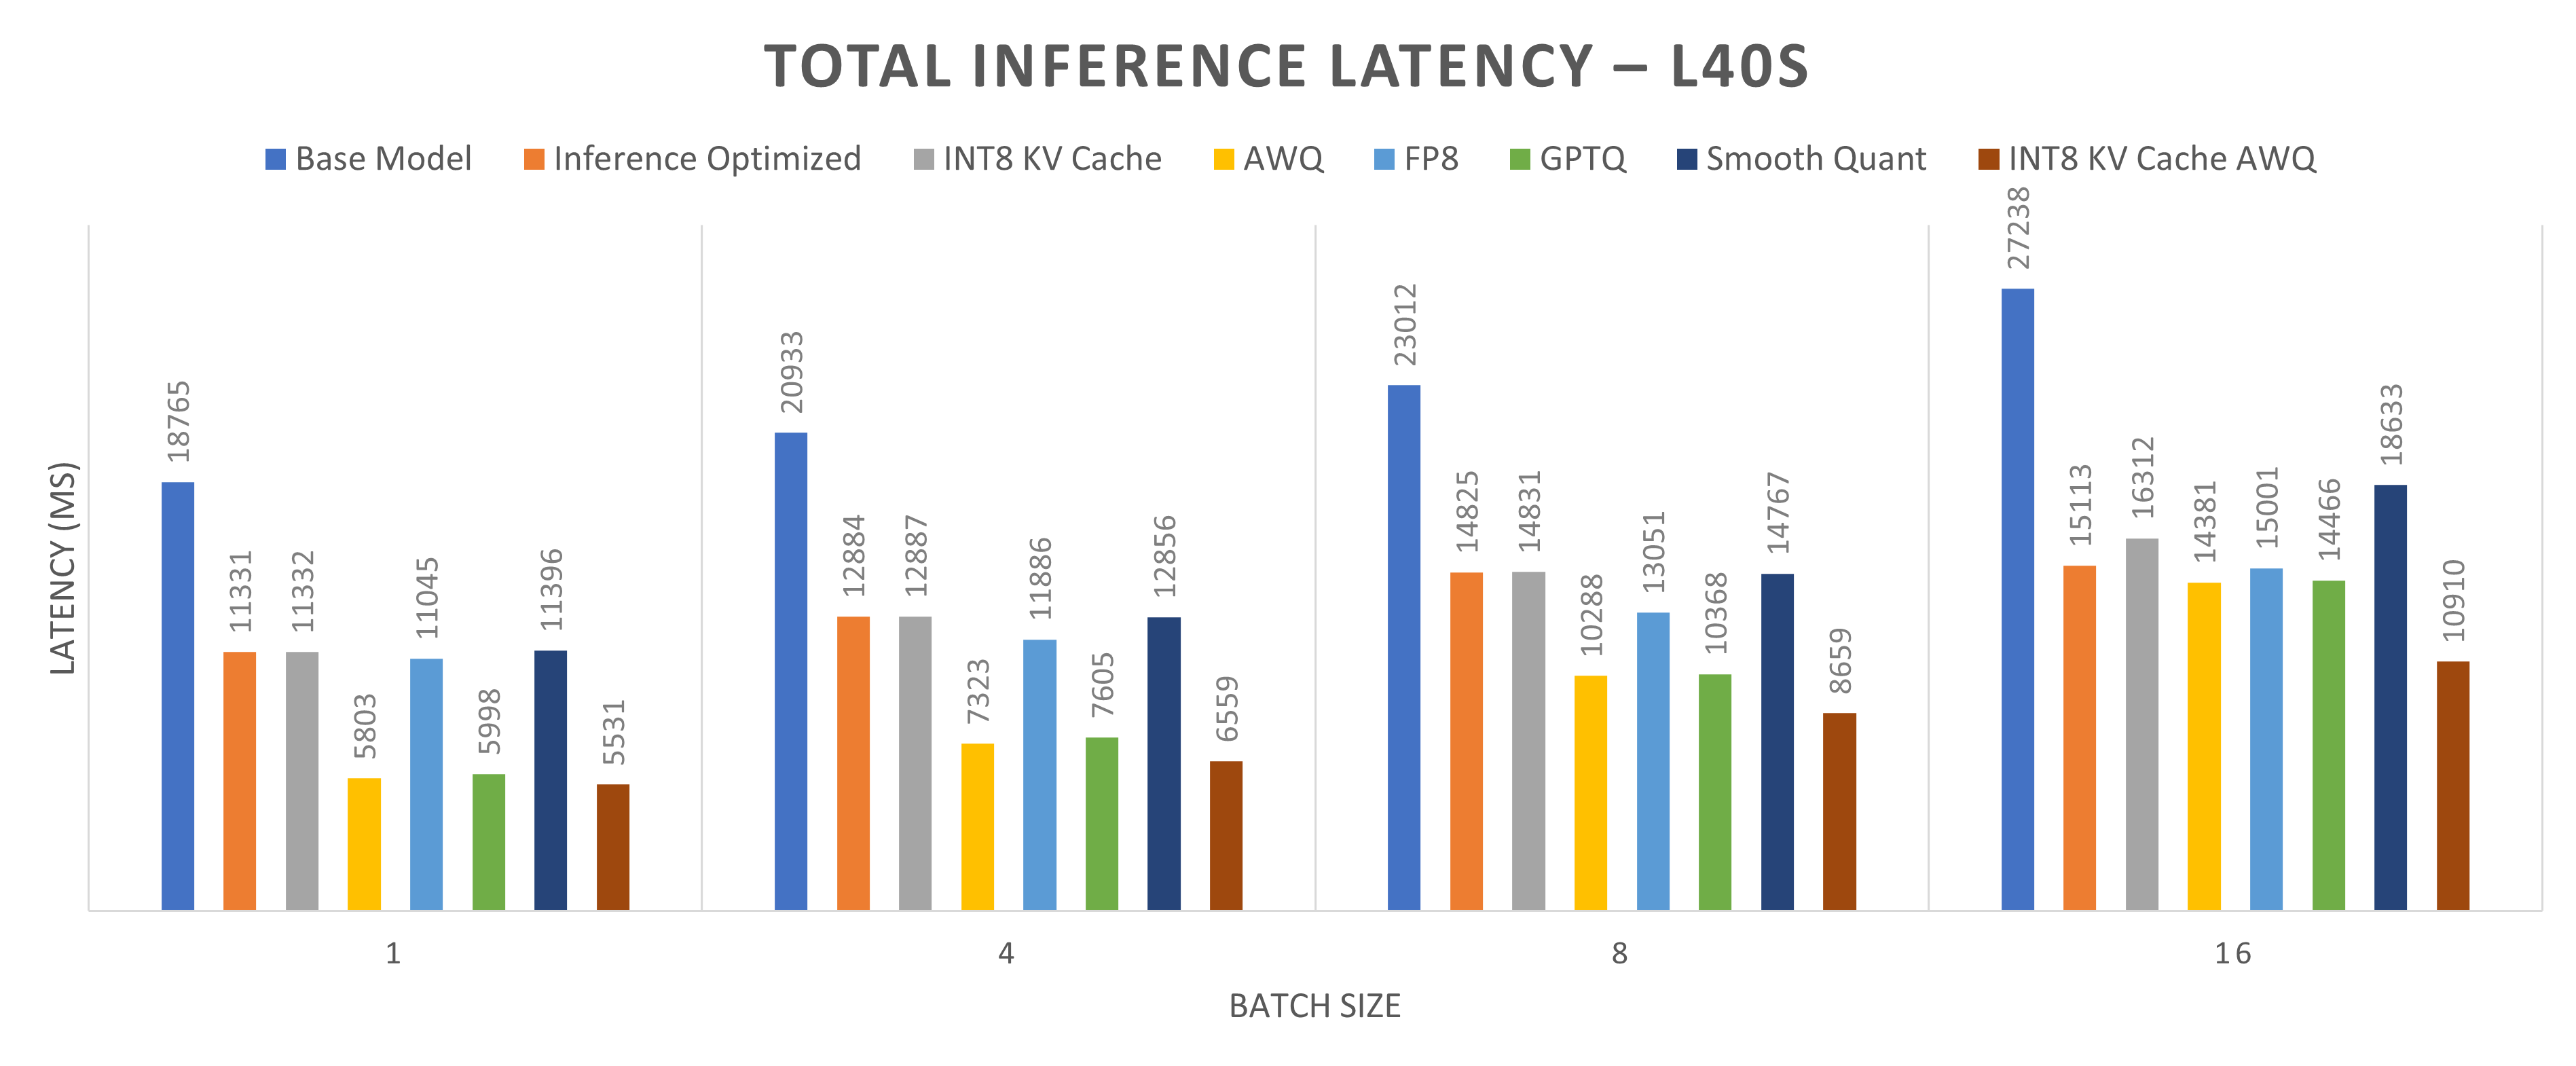
Unlocking LLM Performance: Advanced Quantization Techniques on Dell ...

Power Capping of GPU Servers for Machine Learning Inference ...

Understanding GPU for Inference in LLMs | Adaline

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...

How to Calculate GPU Requirements for LLM Inference?

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...
Advertisement Space (336x280)

This is the best blog post on LLM inference I've seen this year. They ...

Paper page - Exploring the Latent Capacity of LLMs for One-Step Text ...
LLM Inference - NVIDIA RTX GPU Performance | Puget Systems

(PDF) Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...

[논문 리뷰] Decoding in Latent Spaces for Efficient Inference in LLM-based ...

How to Calculate GPU Requirements for LLM Inference?