
Speeding Up Llm Output With Speculative Decoding Arabian Post

Speeding Up LLM Output with Speculative Decoding — Arabian Post
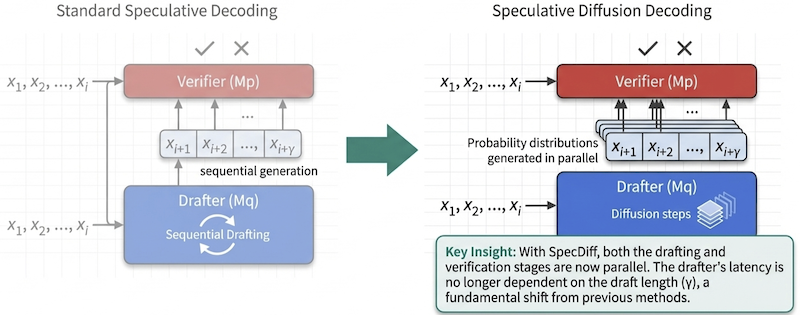
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
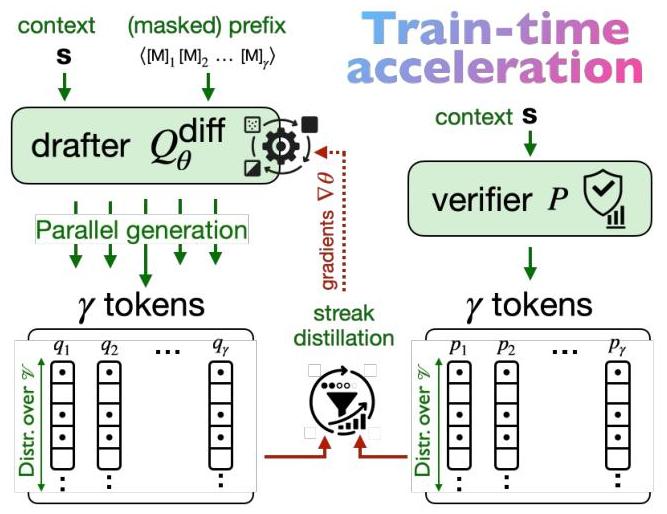
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...

Speeding up local LLM inference 2x with Speculative Decoding | Ovi's ...
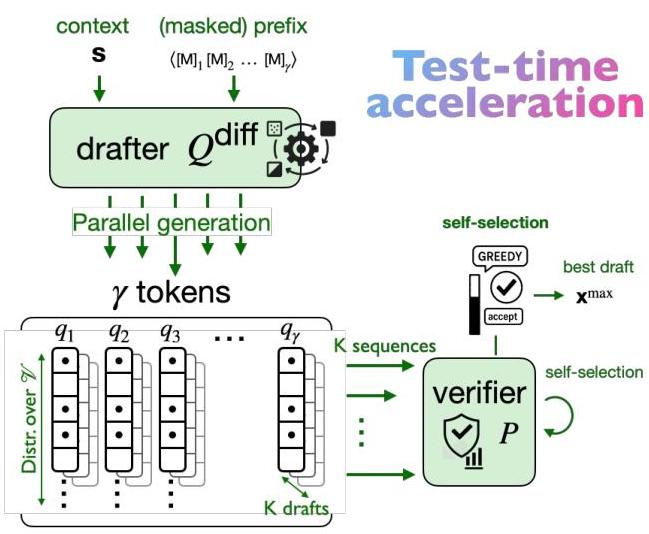
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
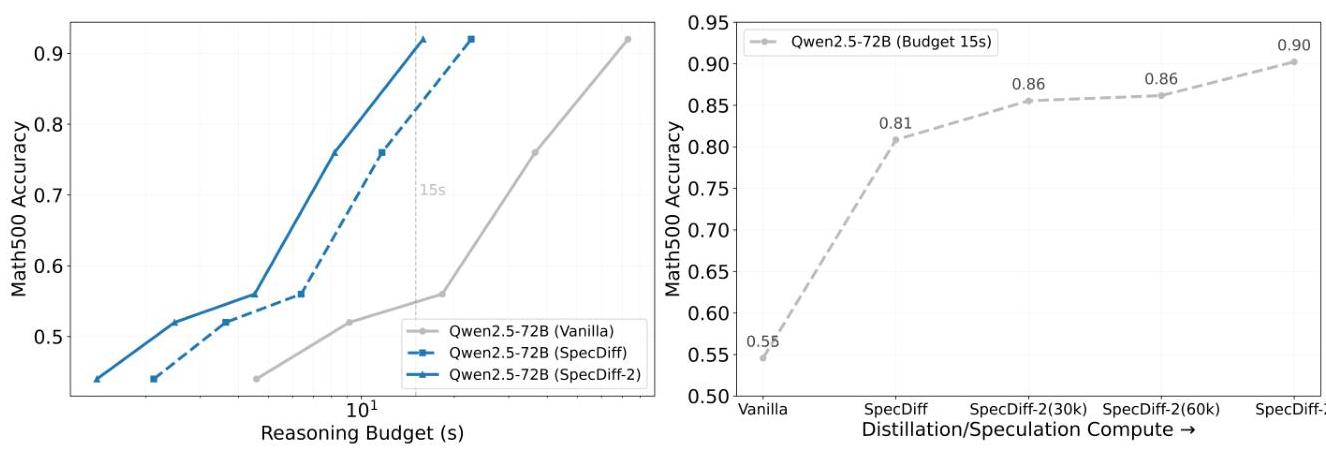
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...

Speeding Up LLM Decoding with Advanced Universal Assisted Generation ...

Speeding Up LLM Inference : Speculative Decoding Explained in the ...
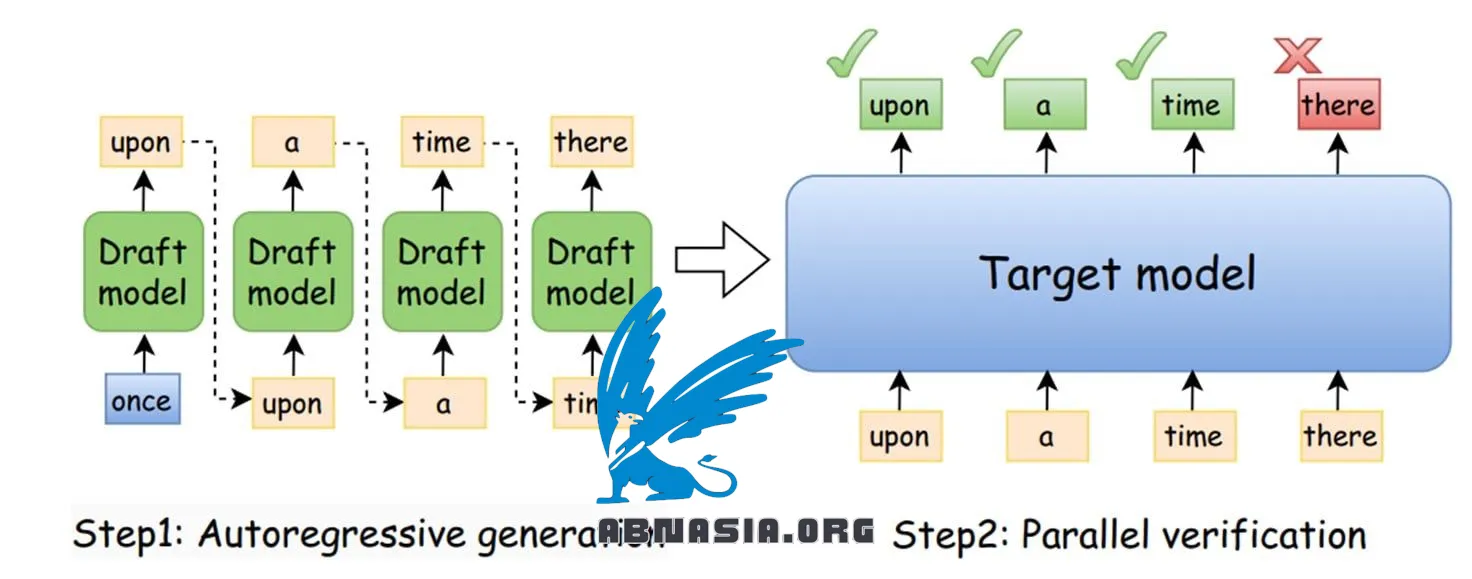
Speed Up LLM Inference with Speculative Decoding | ABN Software
Speculative Decoding Guide: Speed Up LLM Inference with Draft and ...
Advertisement Space (300x250)
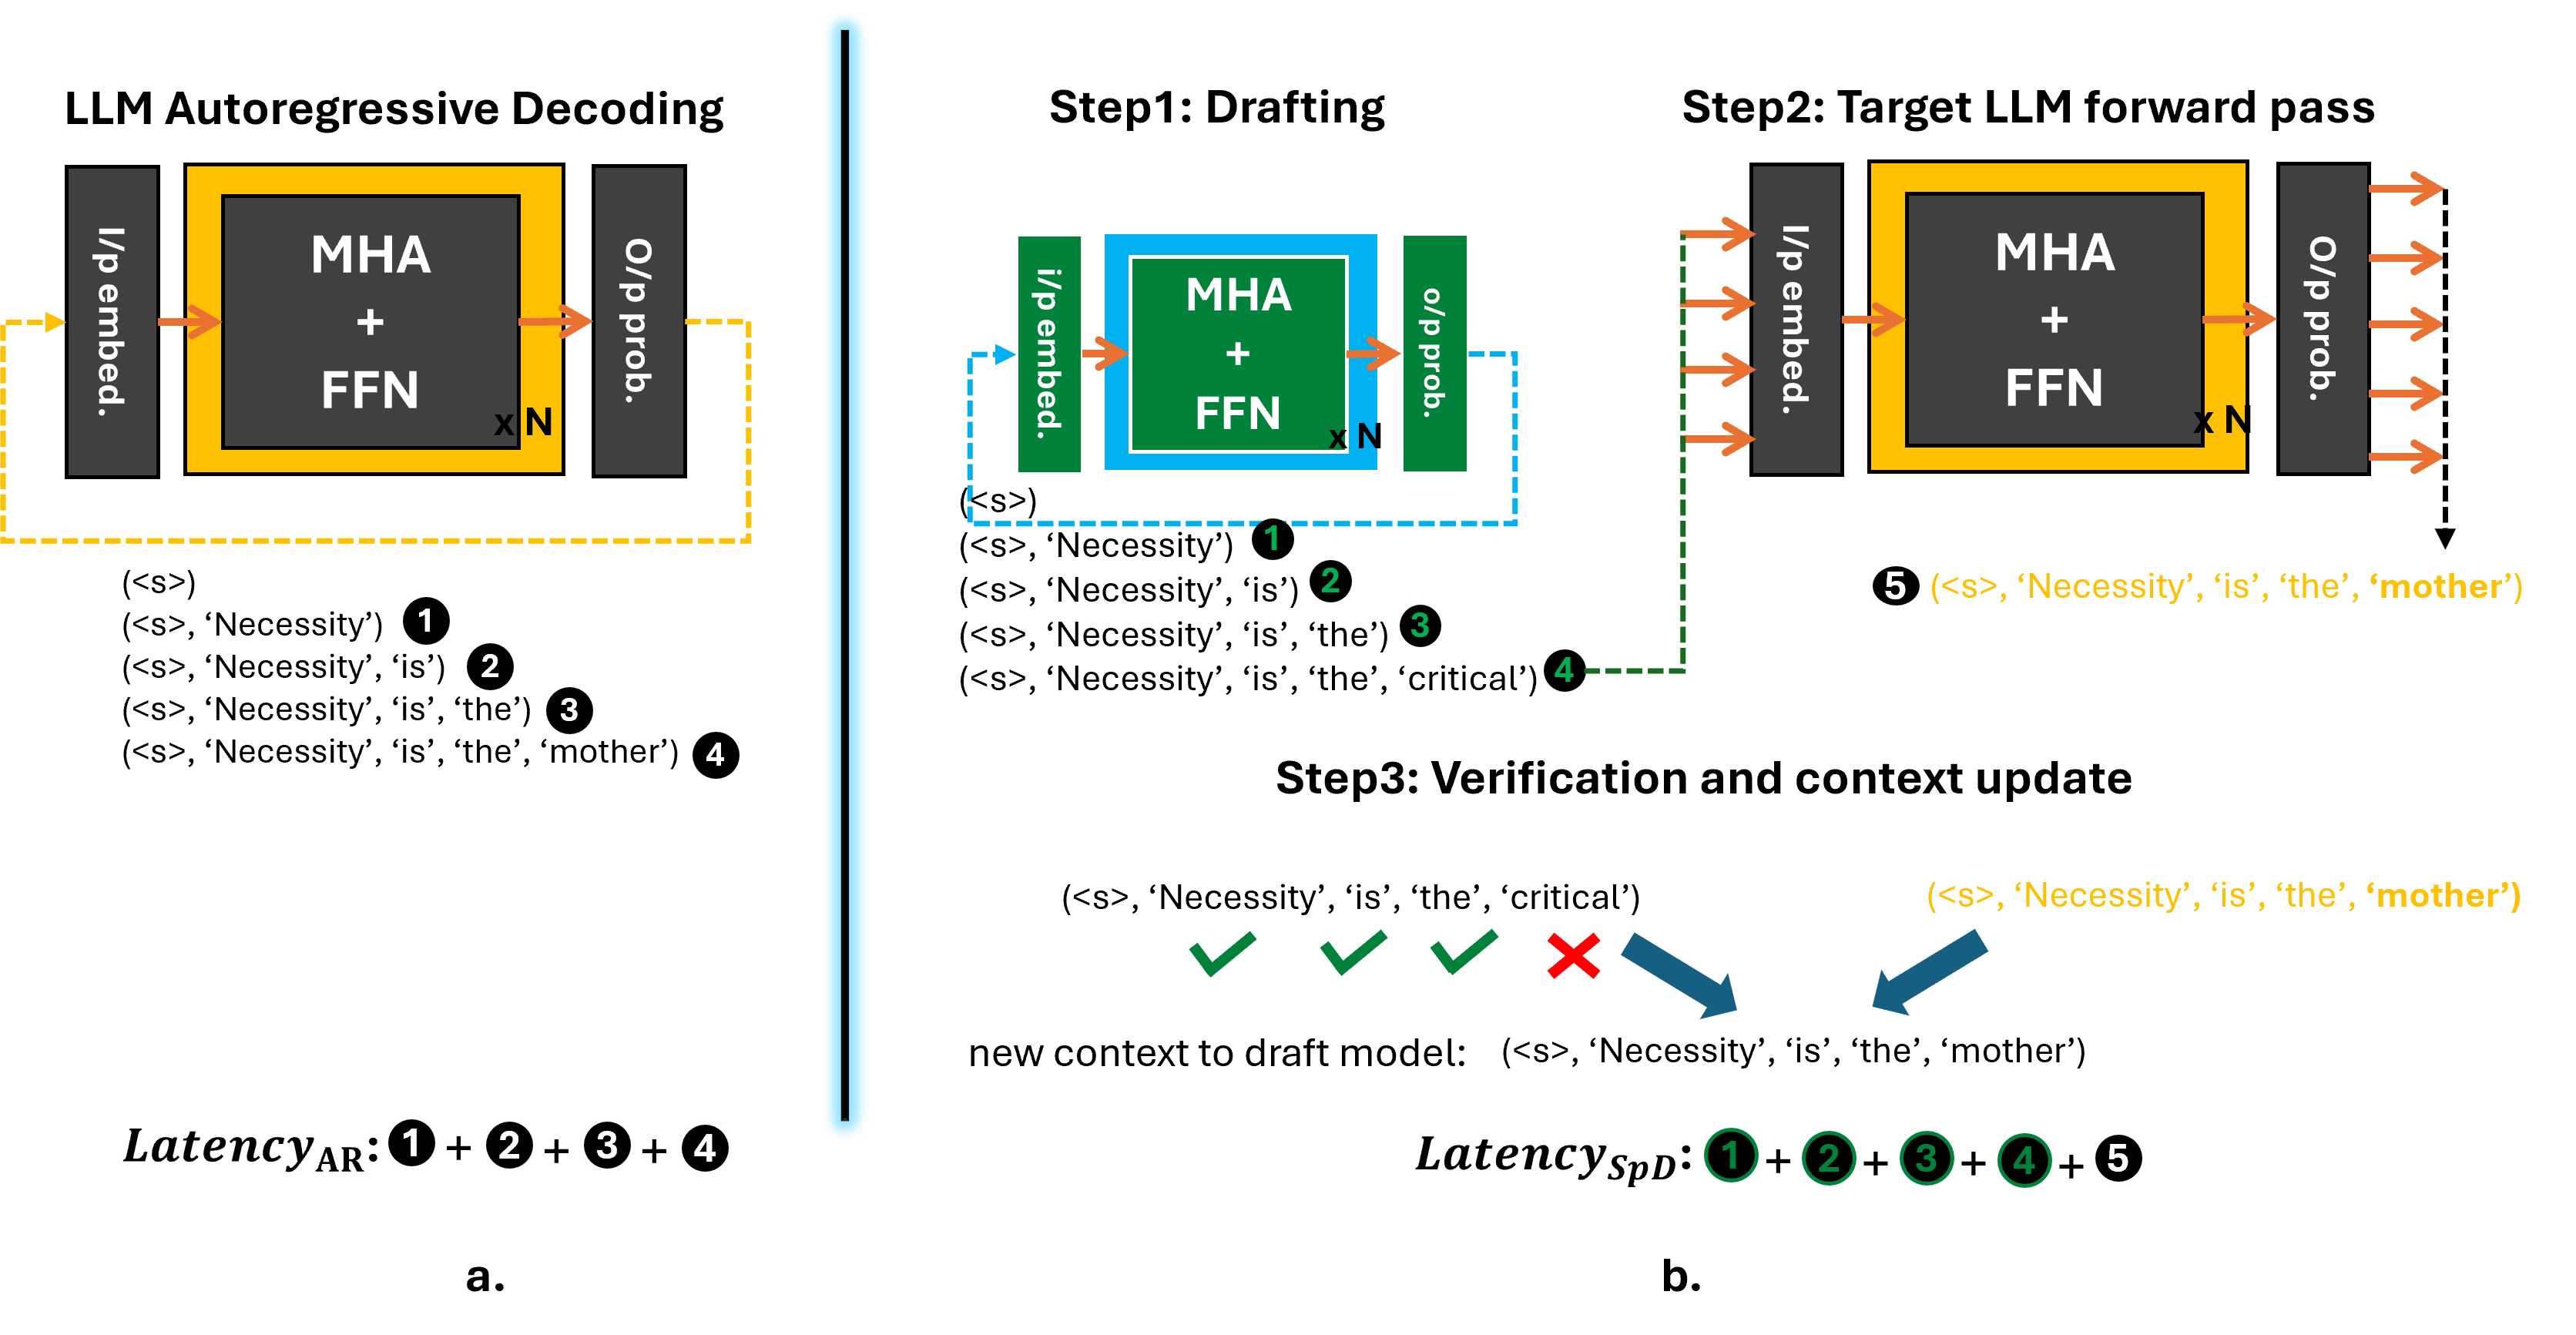
Accelerating LLM Inference: Up to 3x Speedup on MI300X with Speculative ...
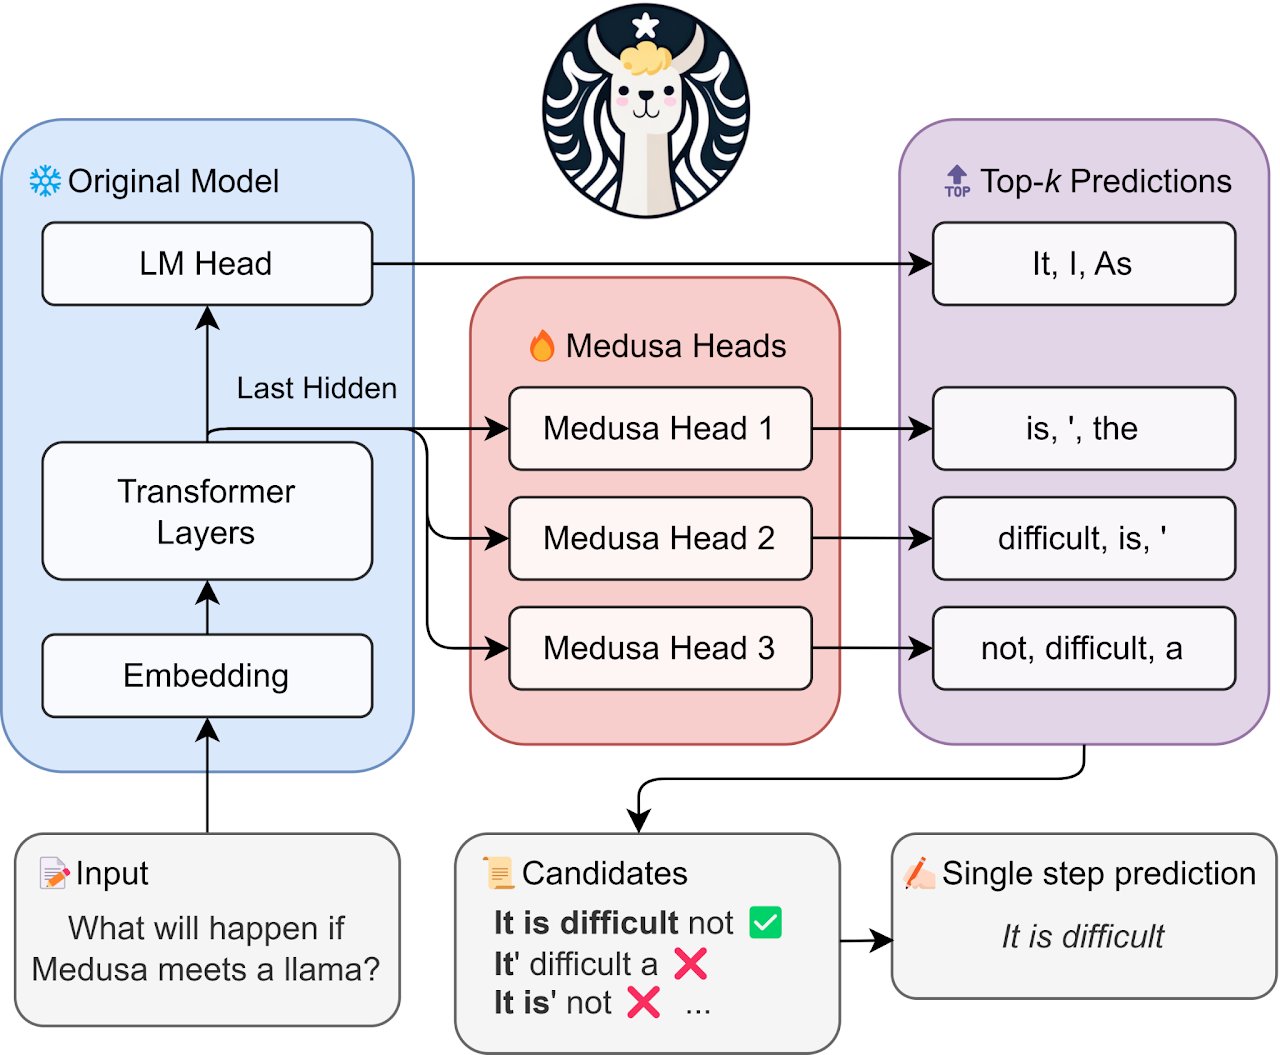
Accelerate LLM Inference with Speculative Decoding | Charles Xu
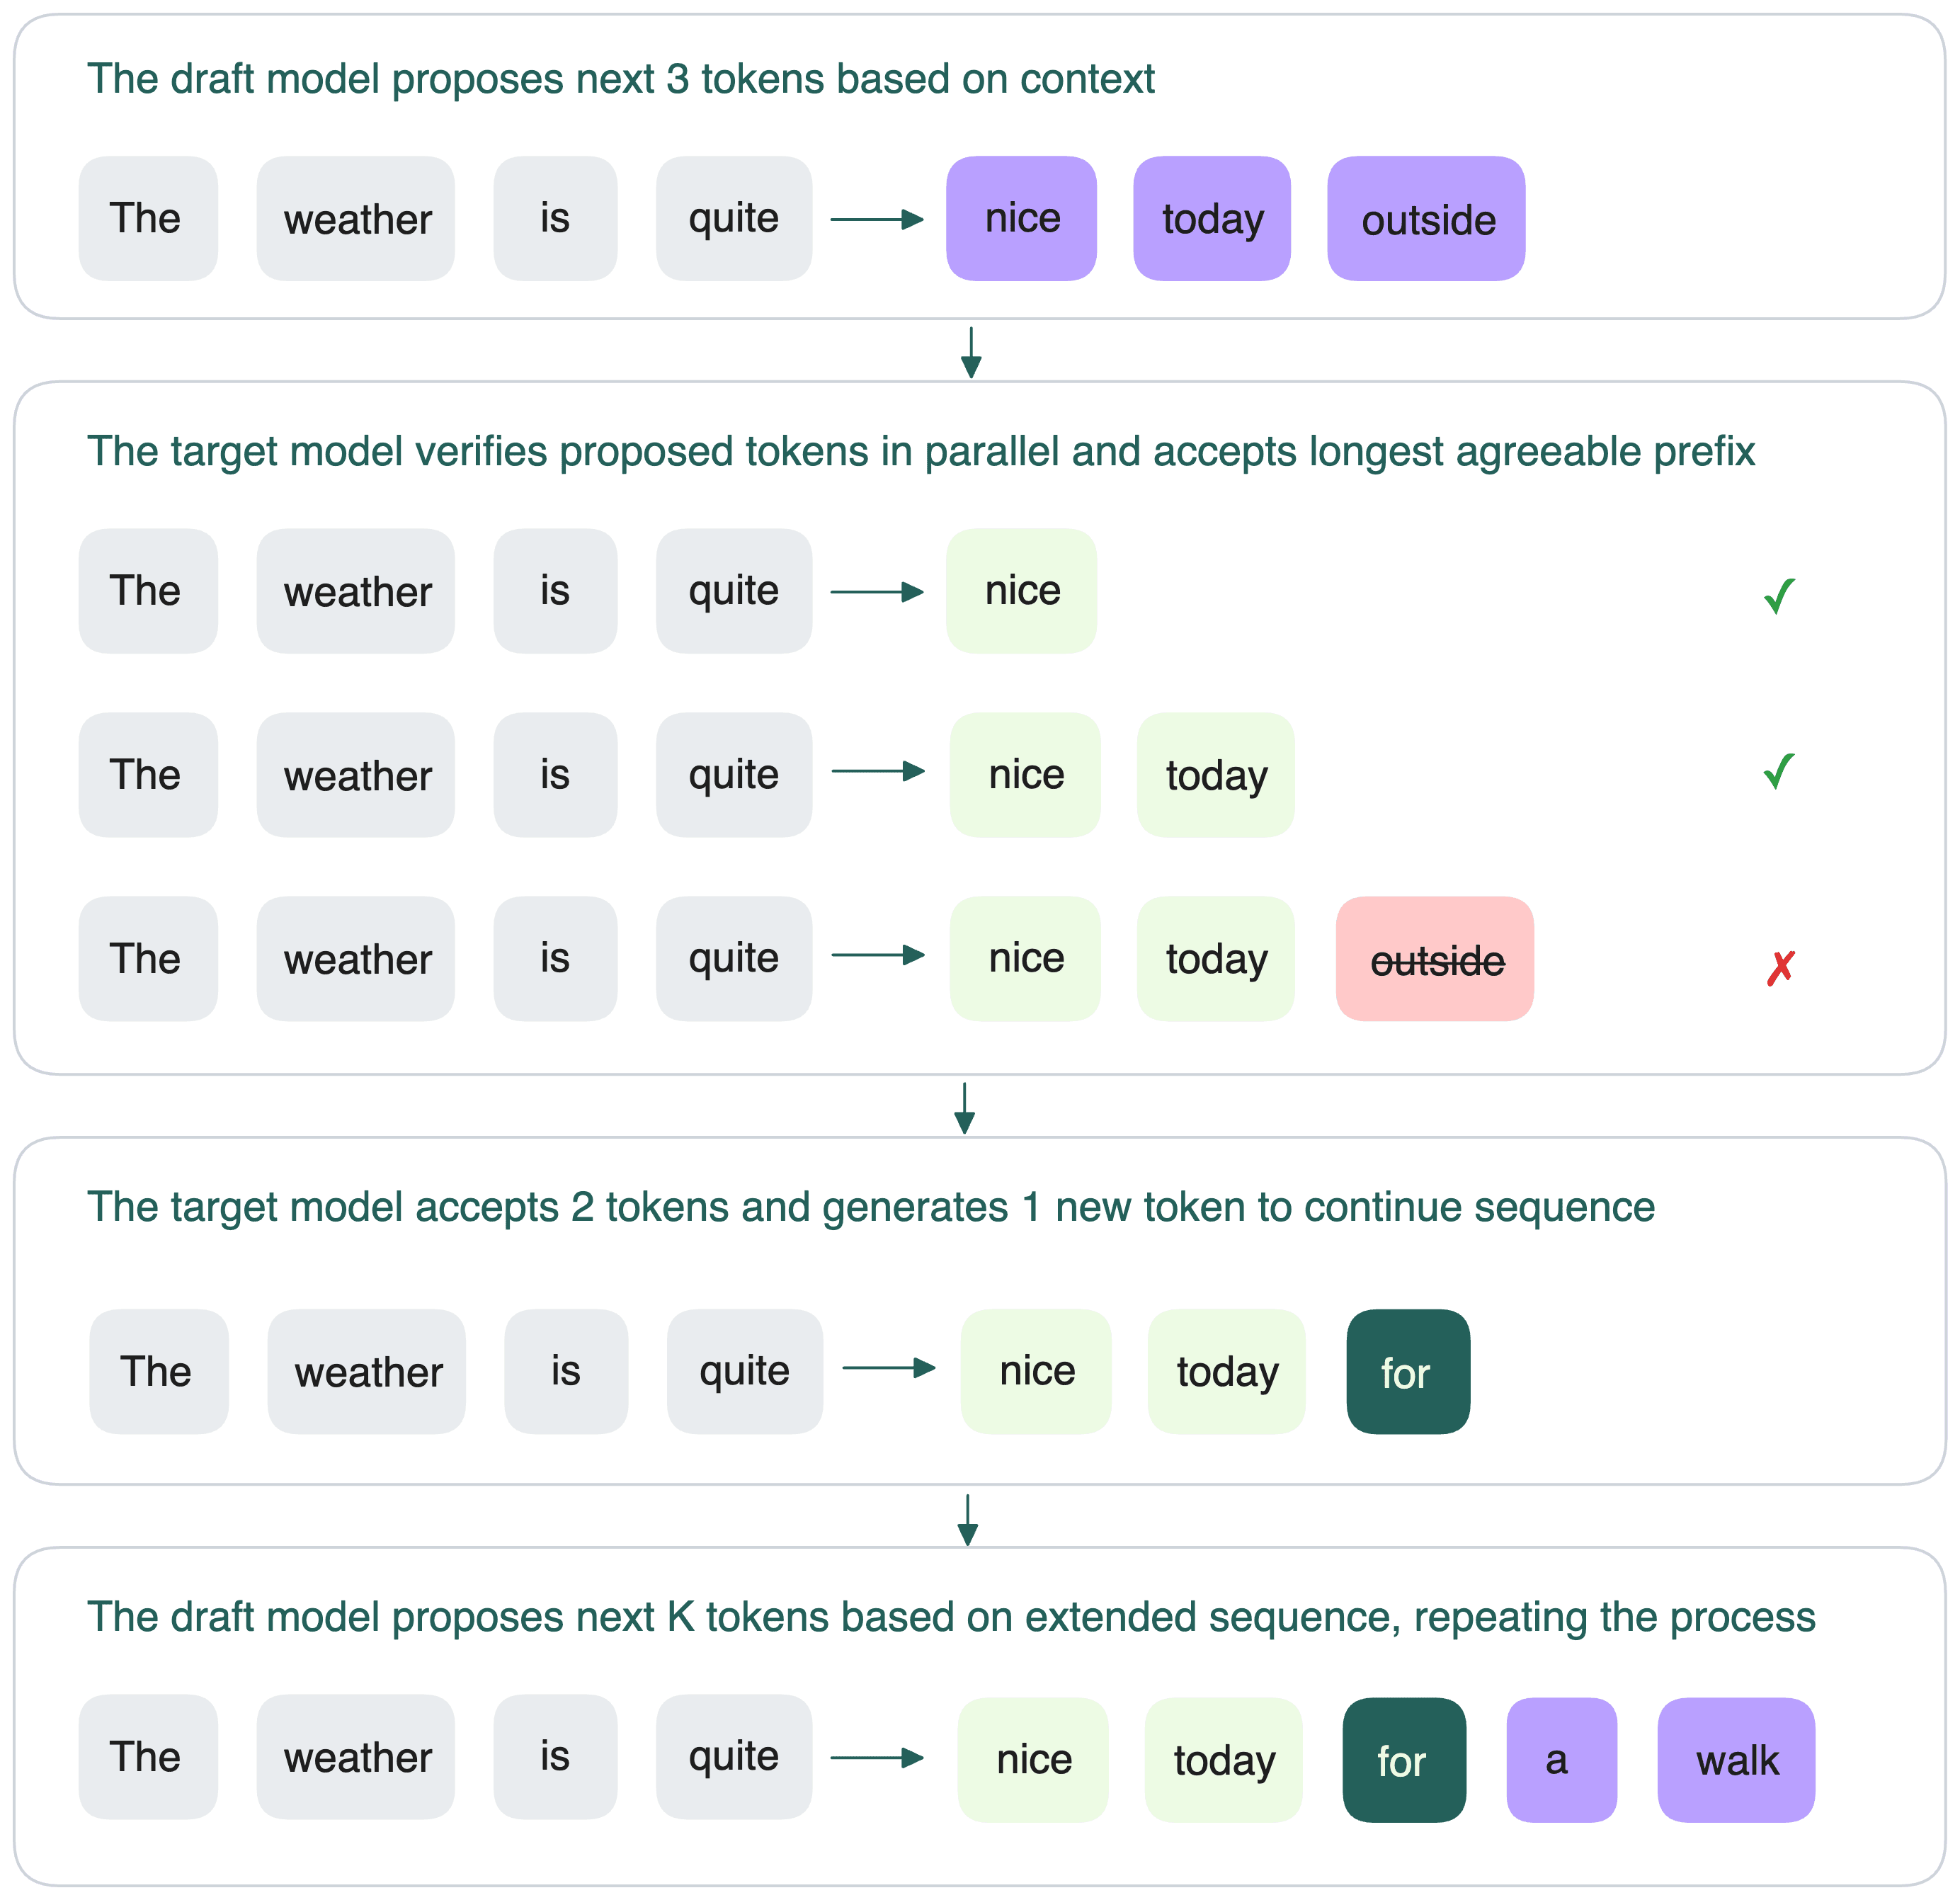
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
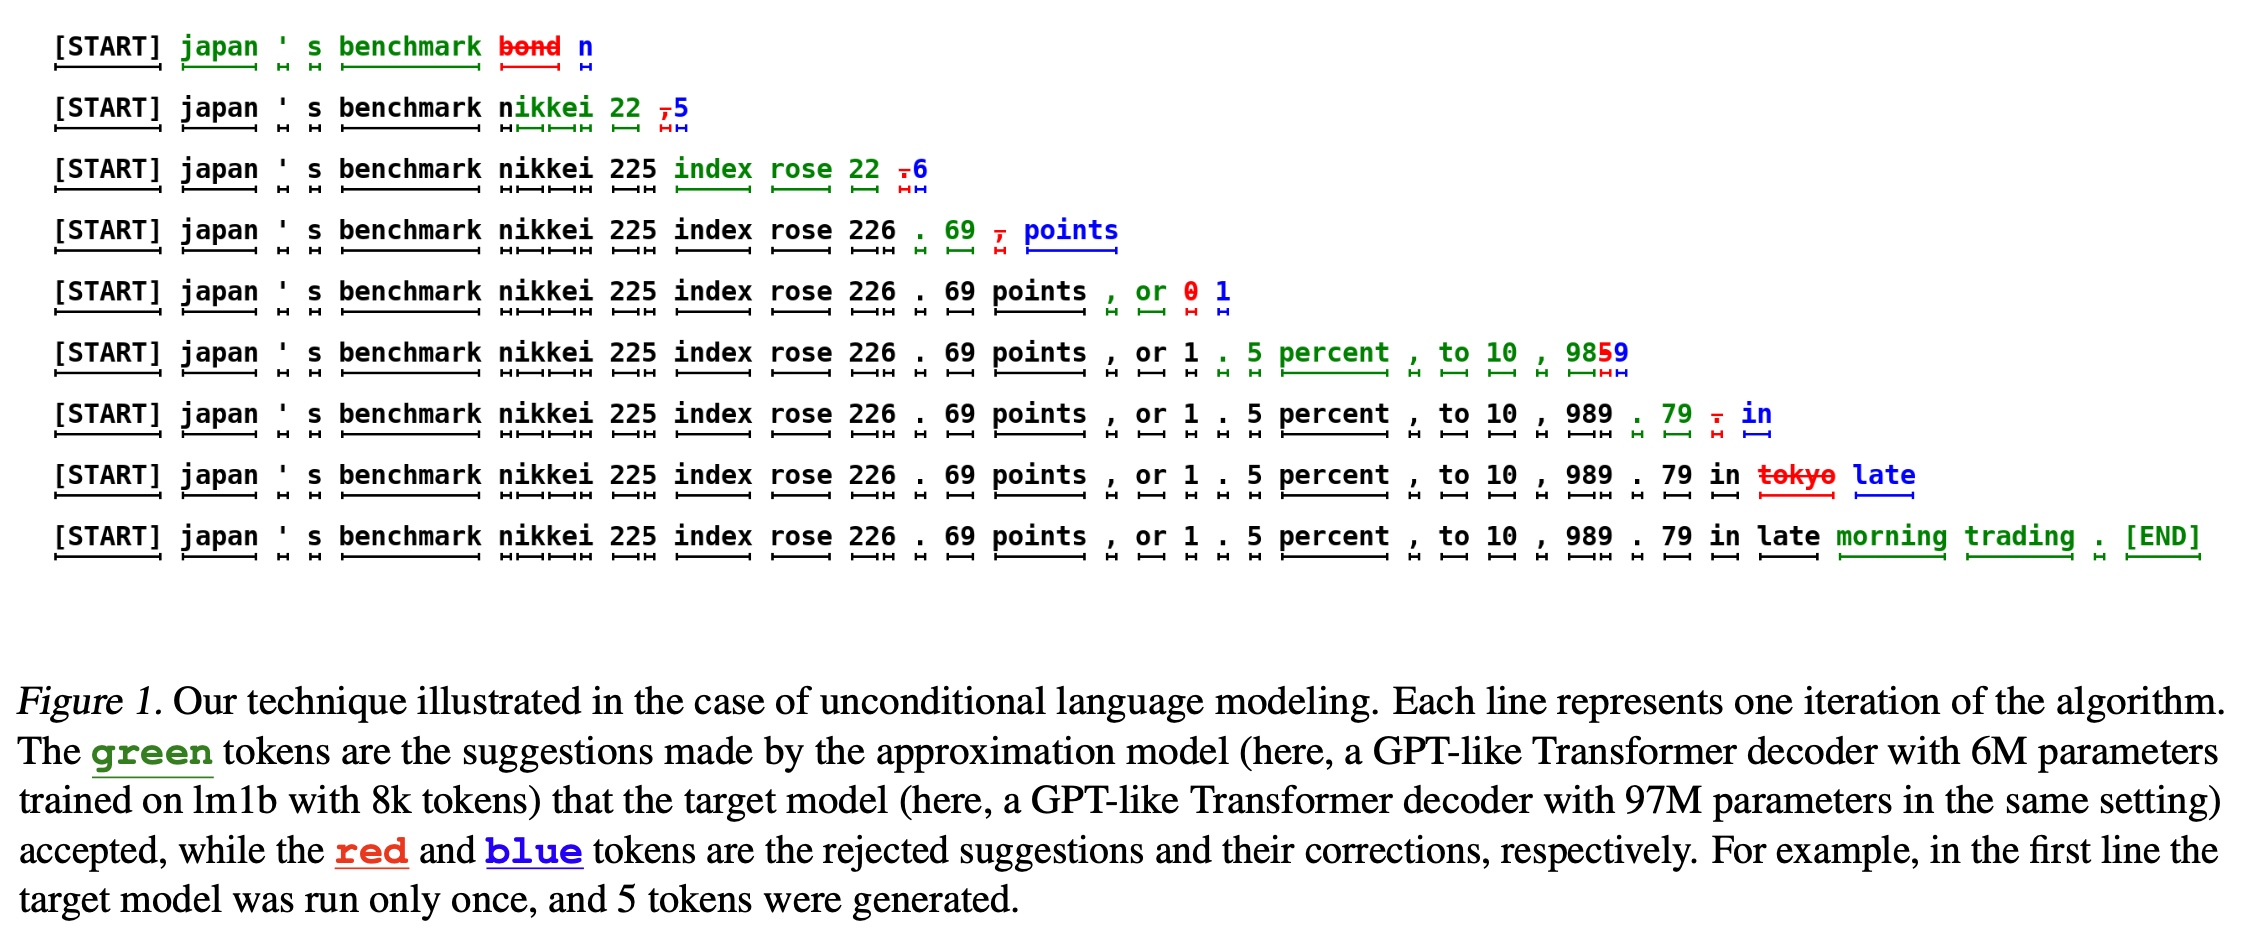
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speeding up Speculative Decoding via Approximate Verification | AI ...
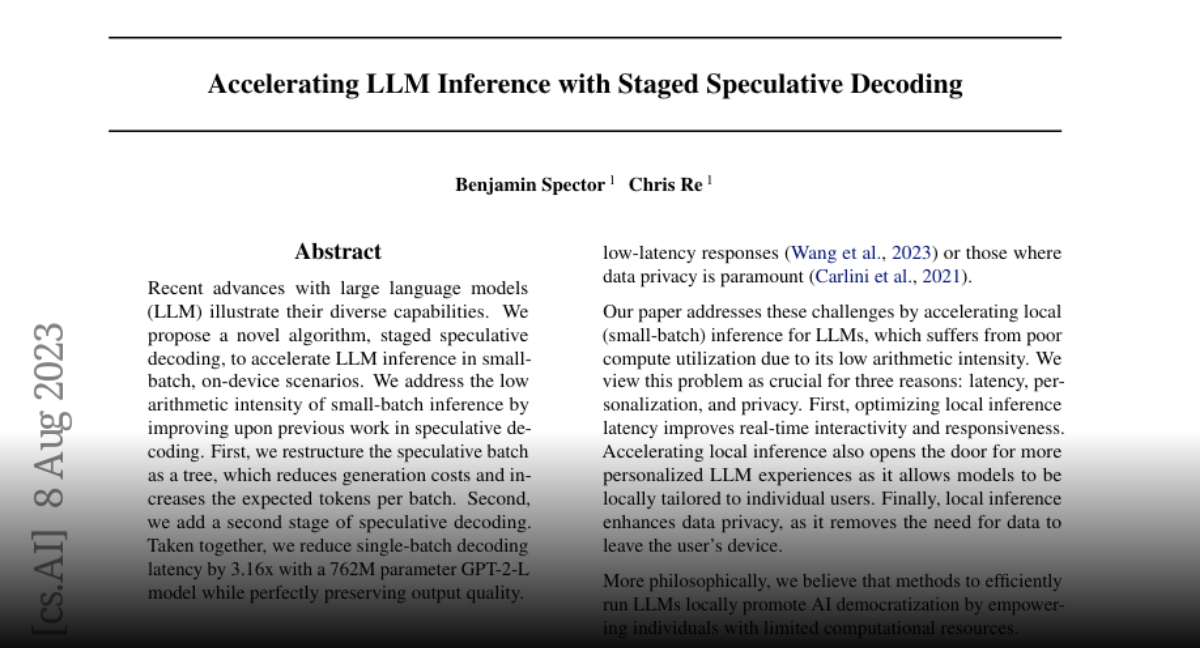
Paper page - Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
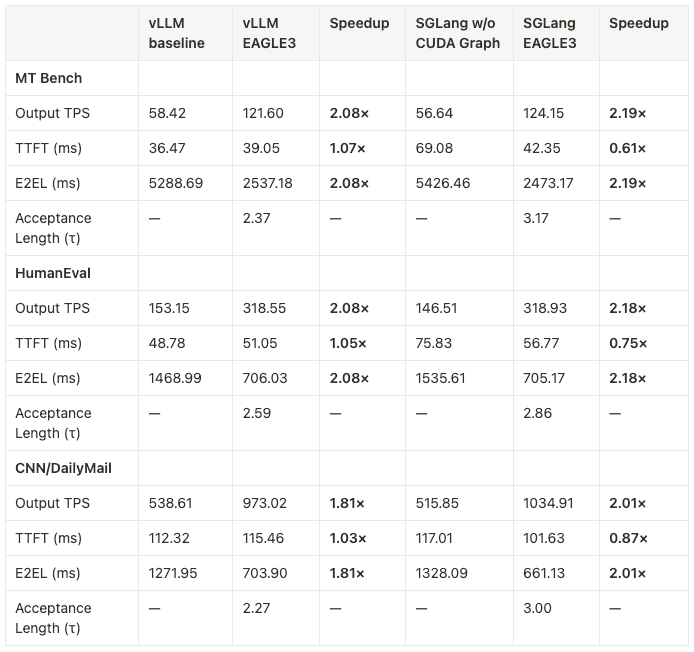
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
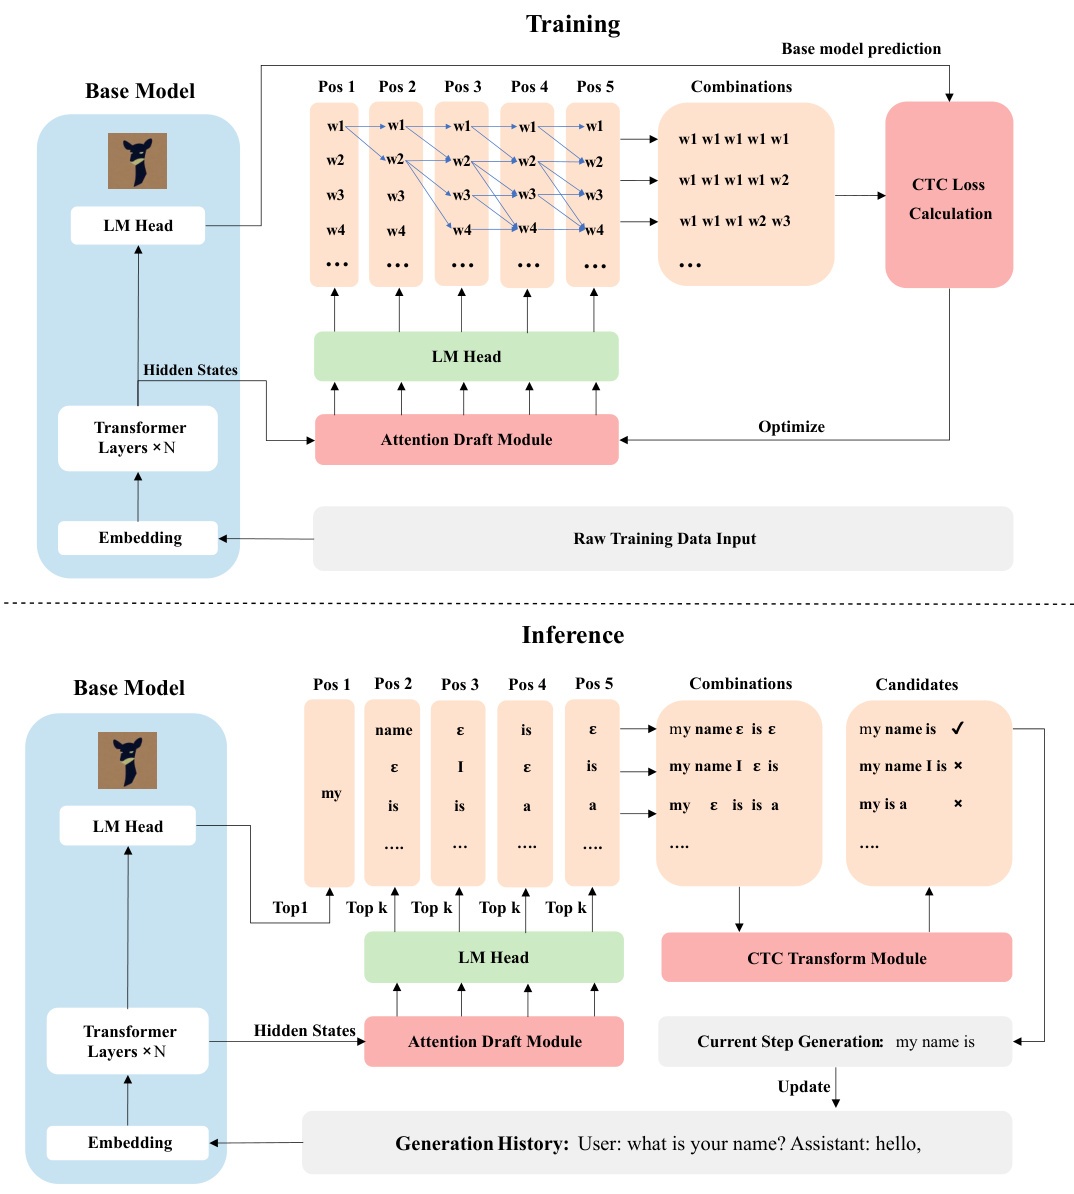
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
Advertisement Space (336x280)
Accelerating LLM Inference with Staged Speculative Decoding - Paper Details
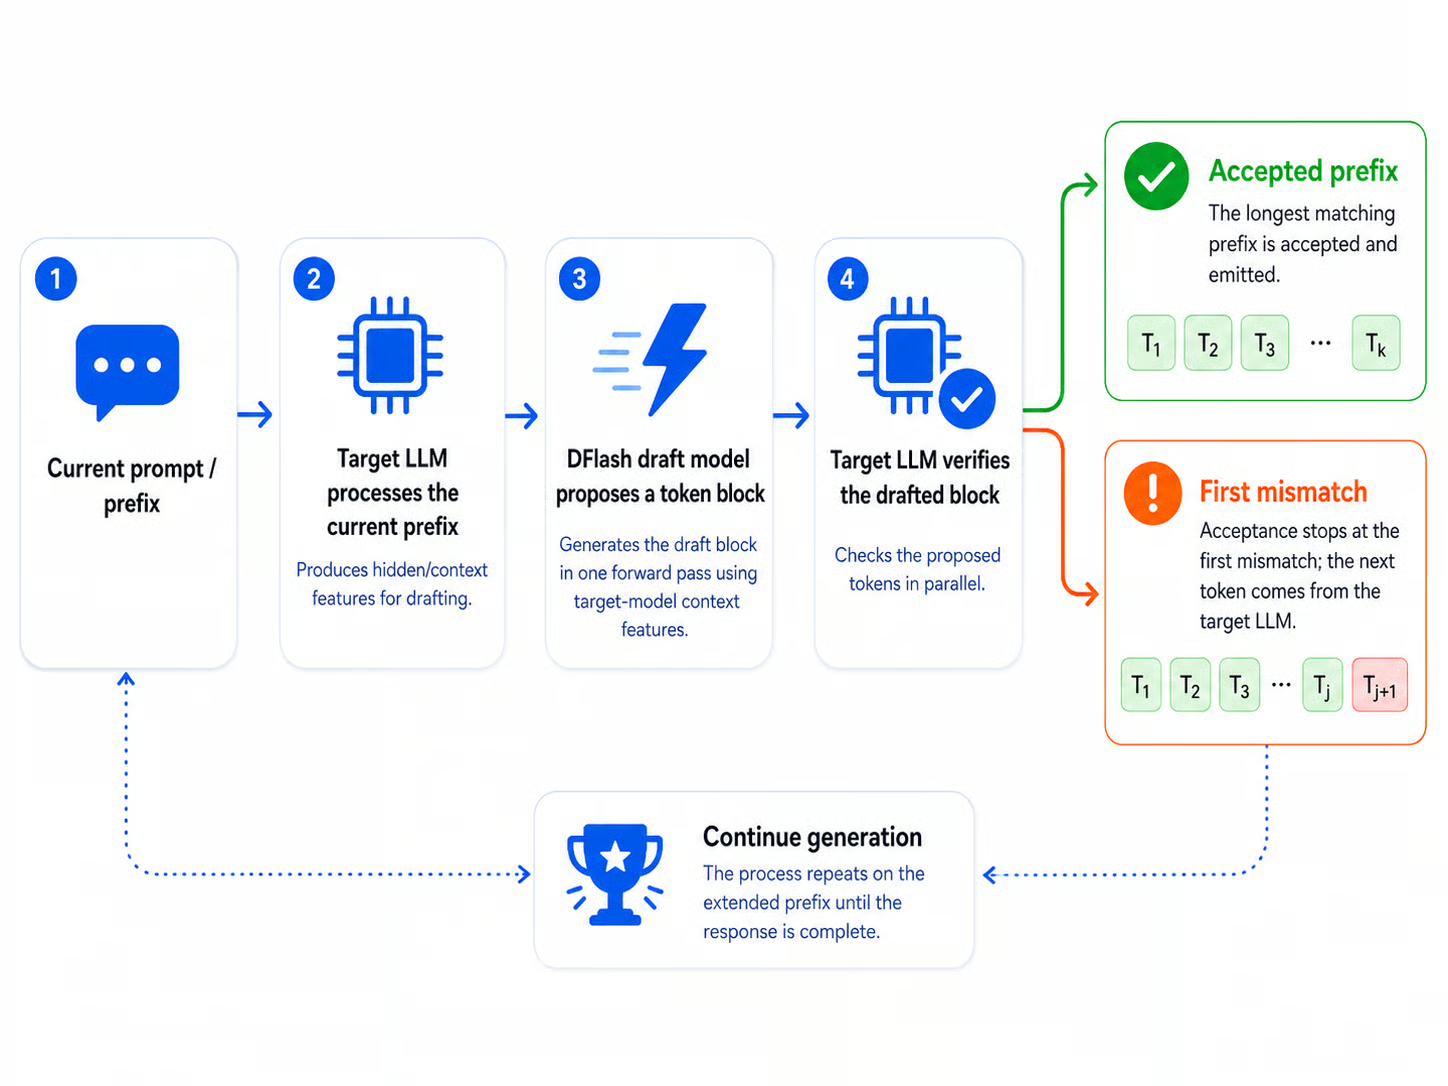
How to Speed Up Local LLMs with DFlash Speculative Decoding | DataCamp
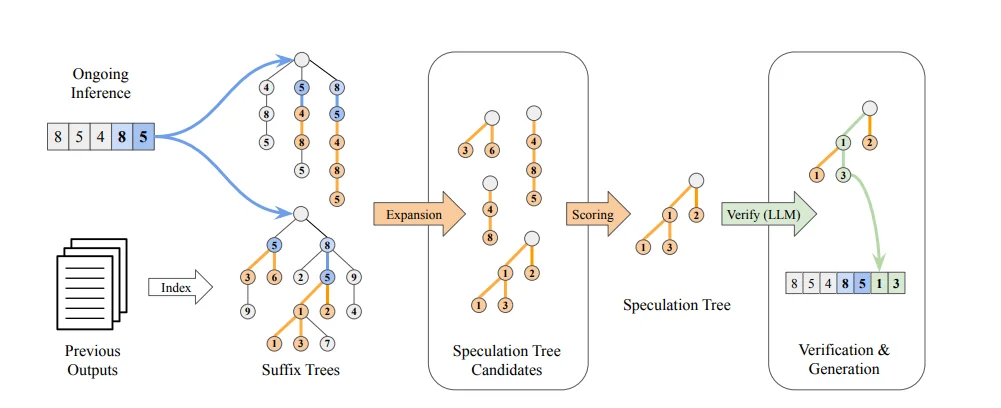
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
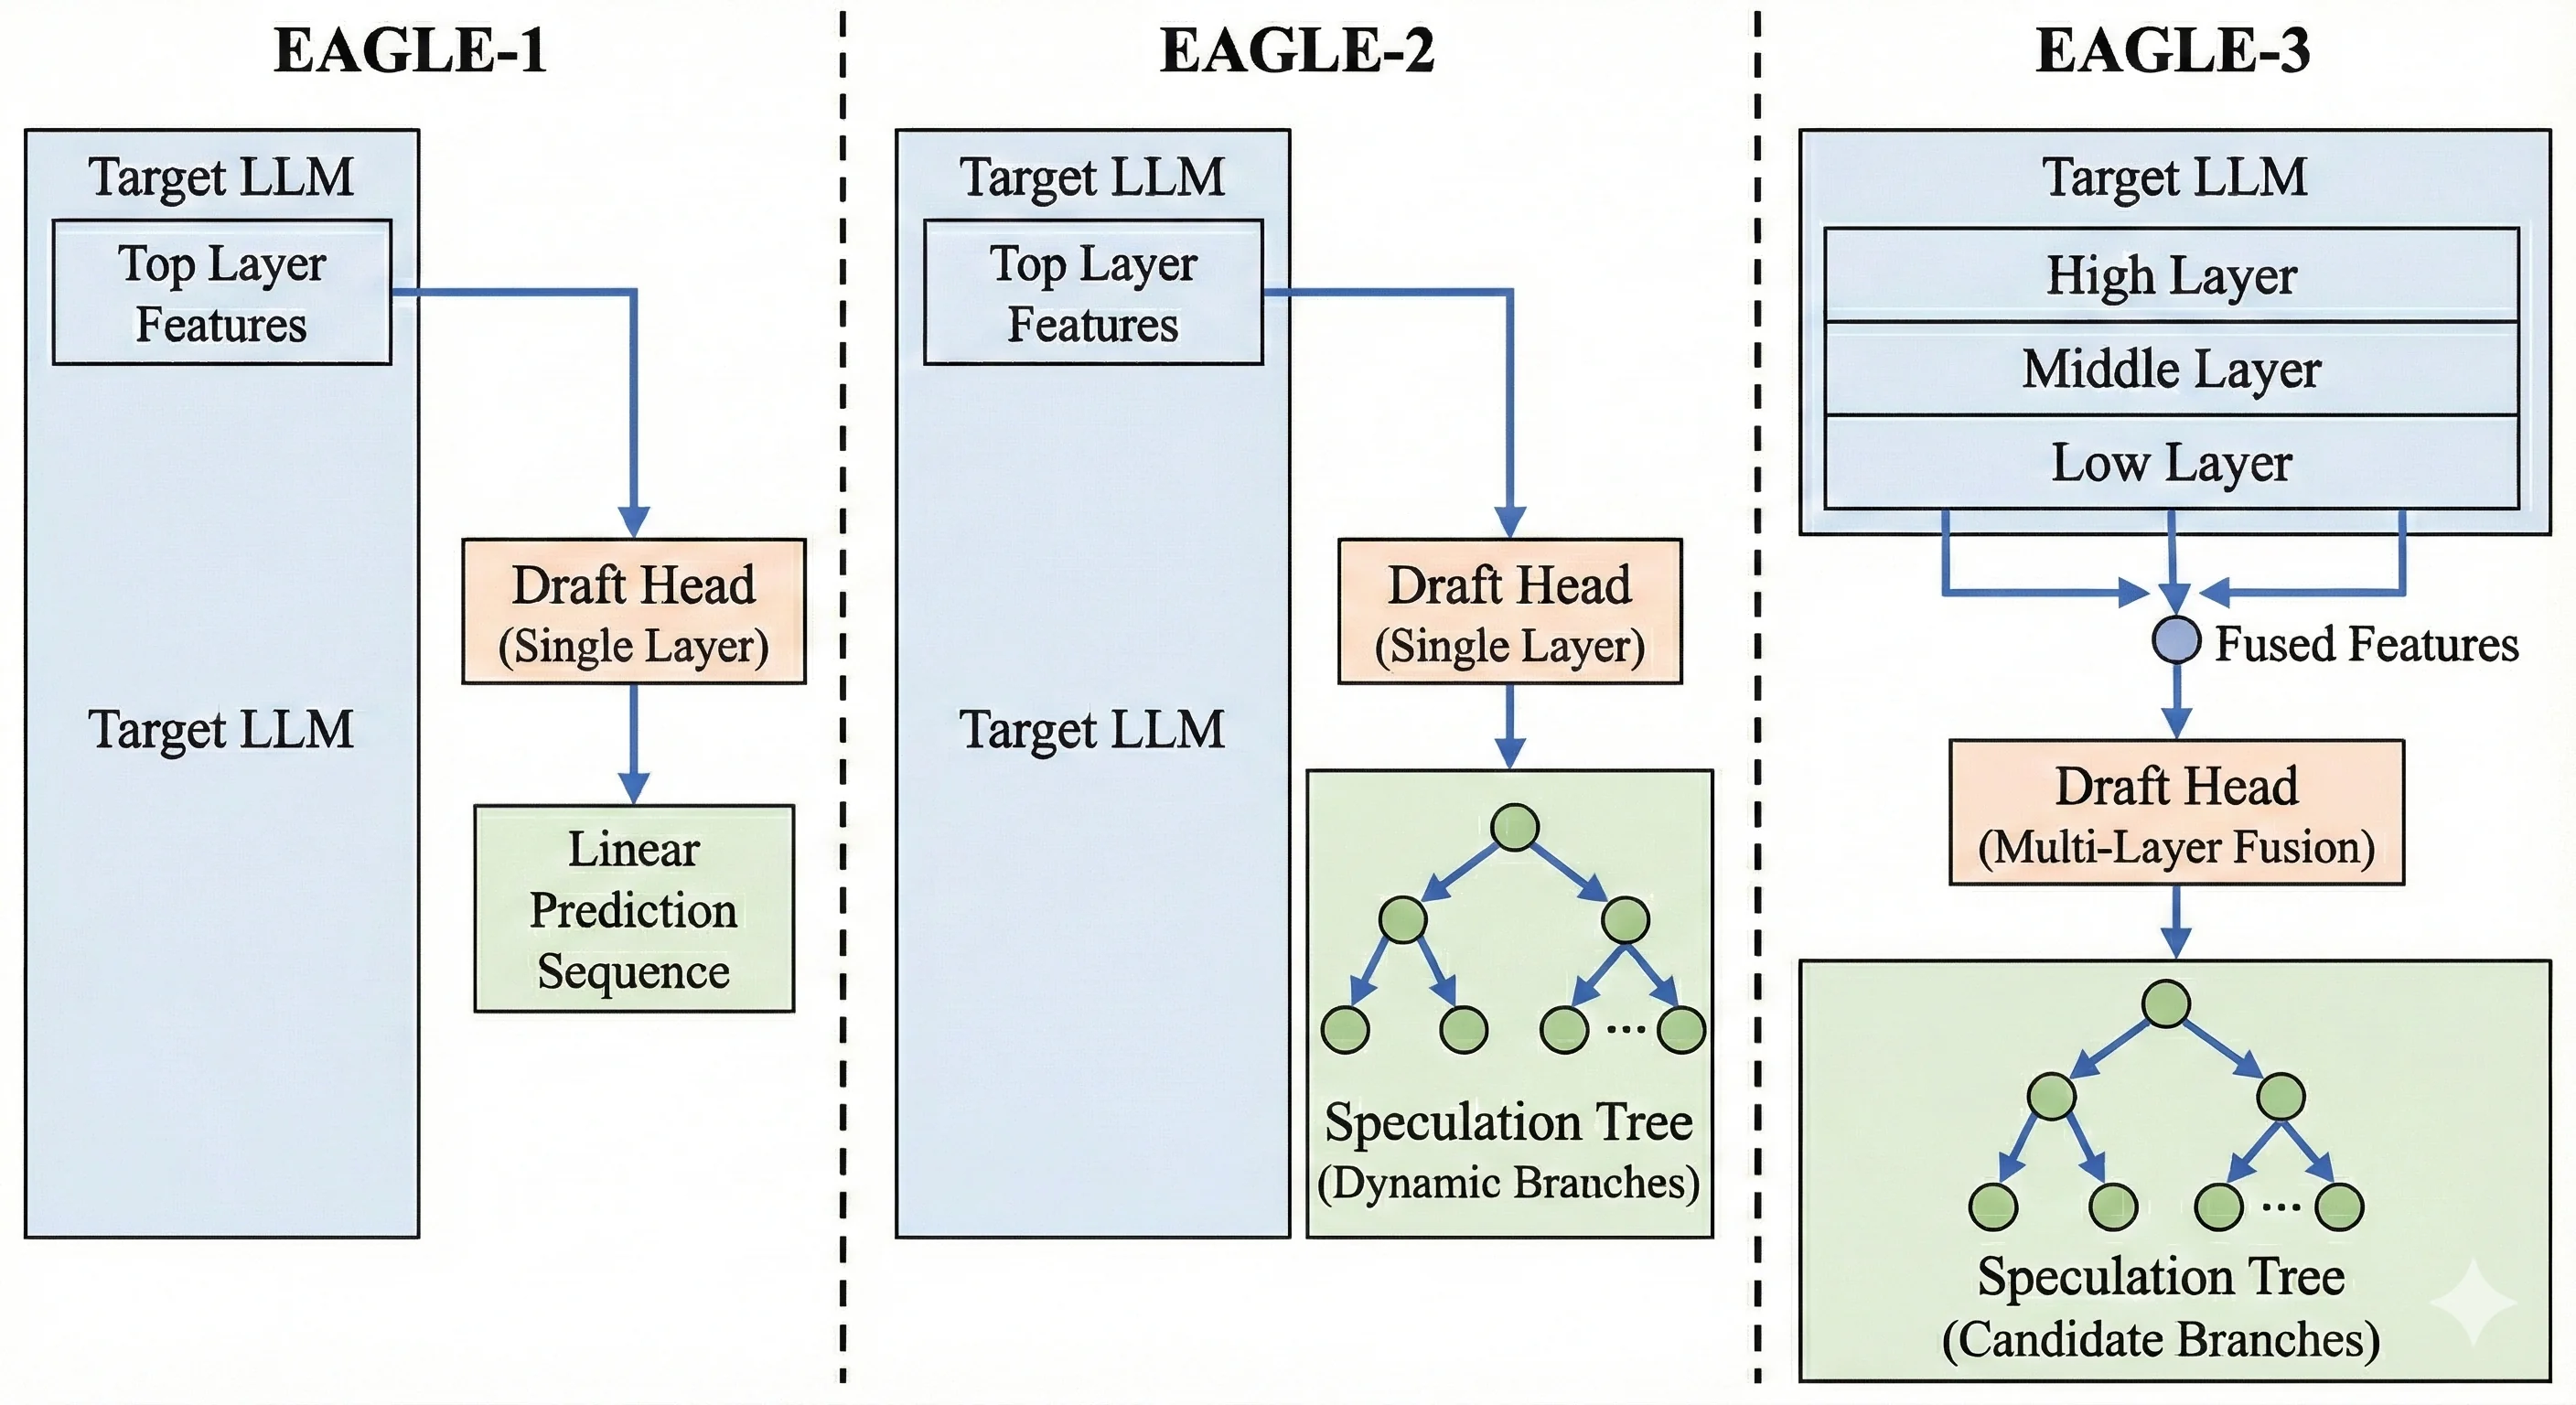
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
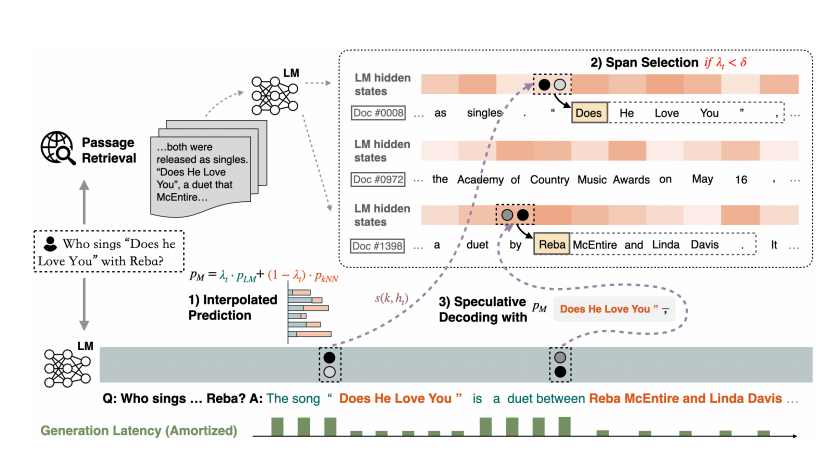
Santosh Sawant - Nearest Neighbor Speculative Decoding for LLM ...

TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
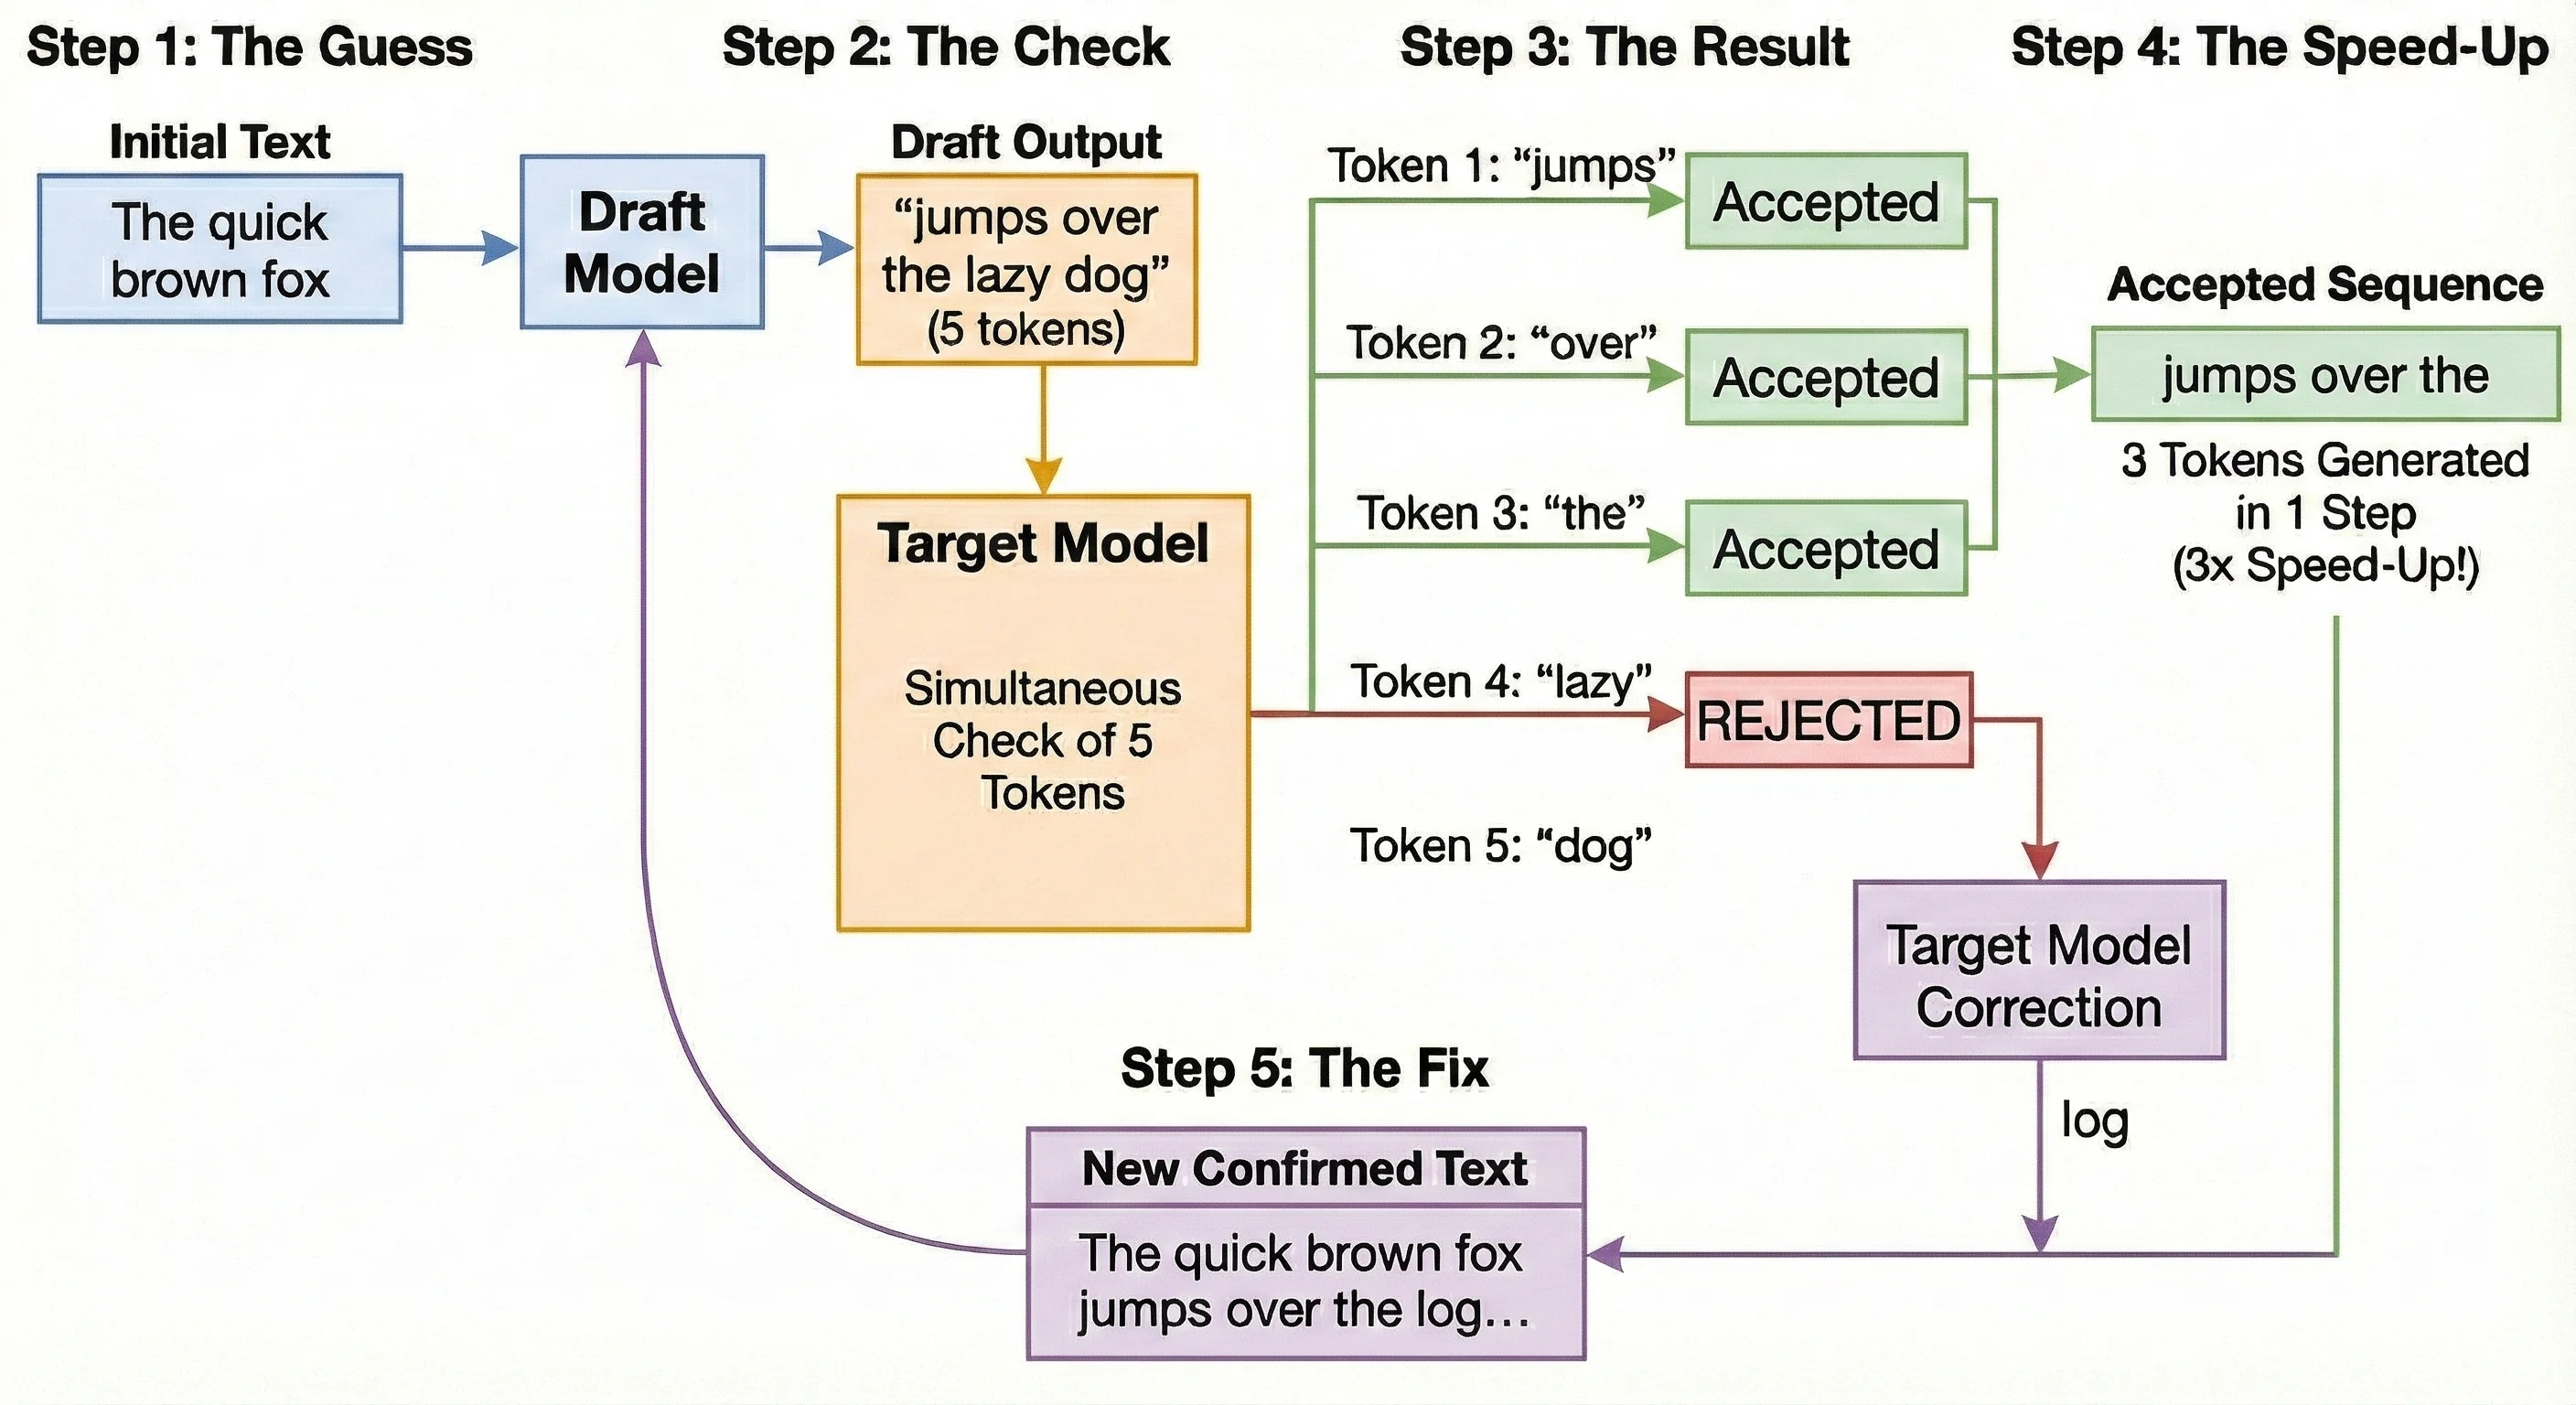
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Paper page - Speculative Decoding via Early-exiting for Faster LLM ...

Nearest Neighbor Speculative Decoding for LLM Generation and ...
Advertisement Space (336x280)
How we built production-ready speculative decoding with TensorRT-LLM
Introducing LM Studio 0.3.10 with 🔮 Speculative Decoding! It's an LLM ...
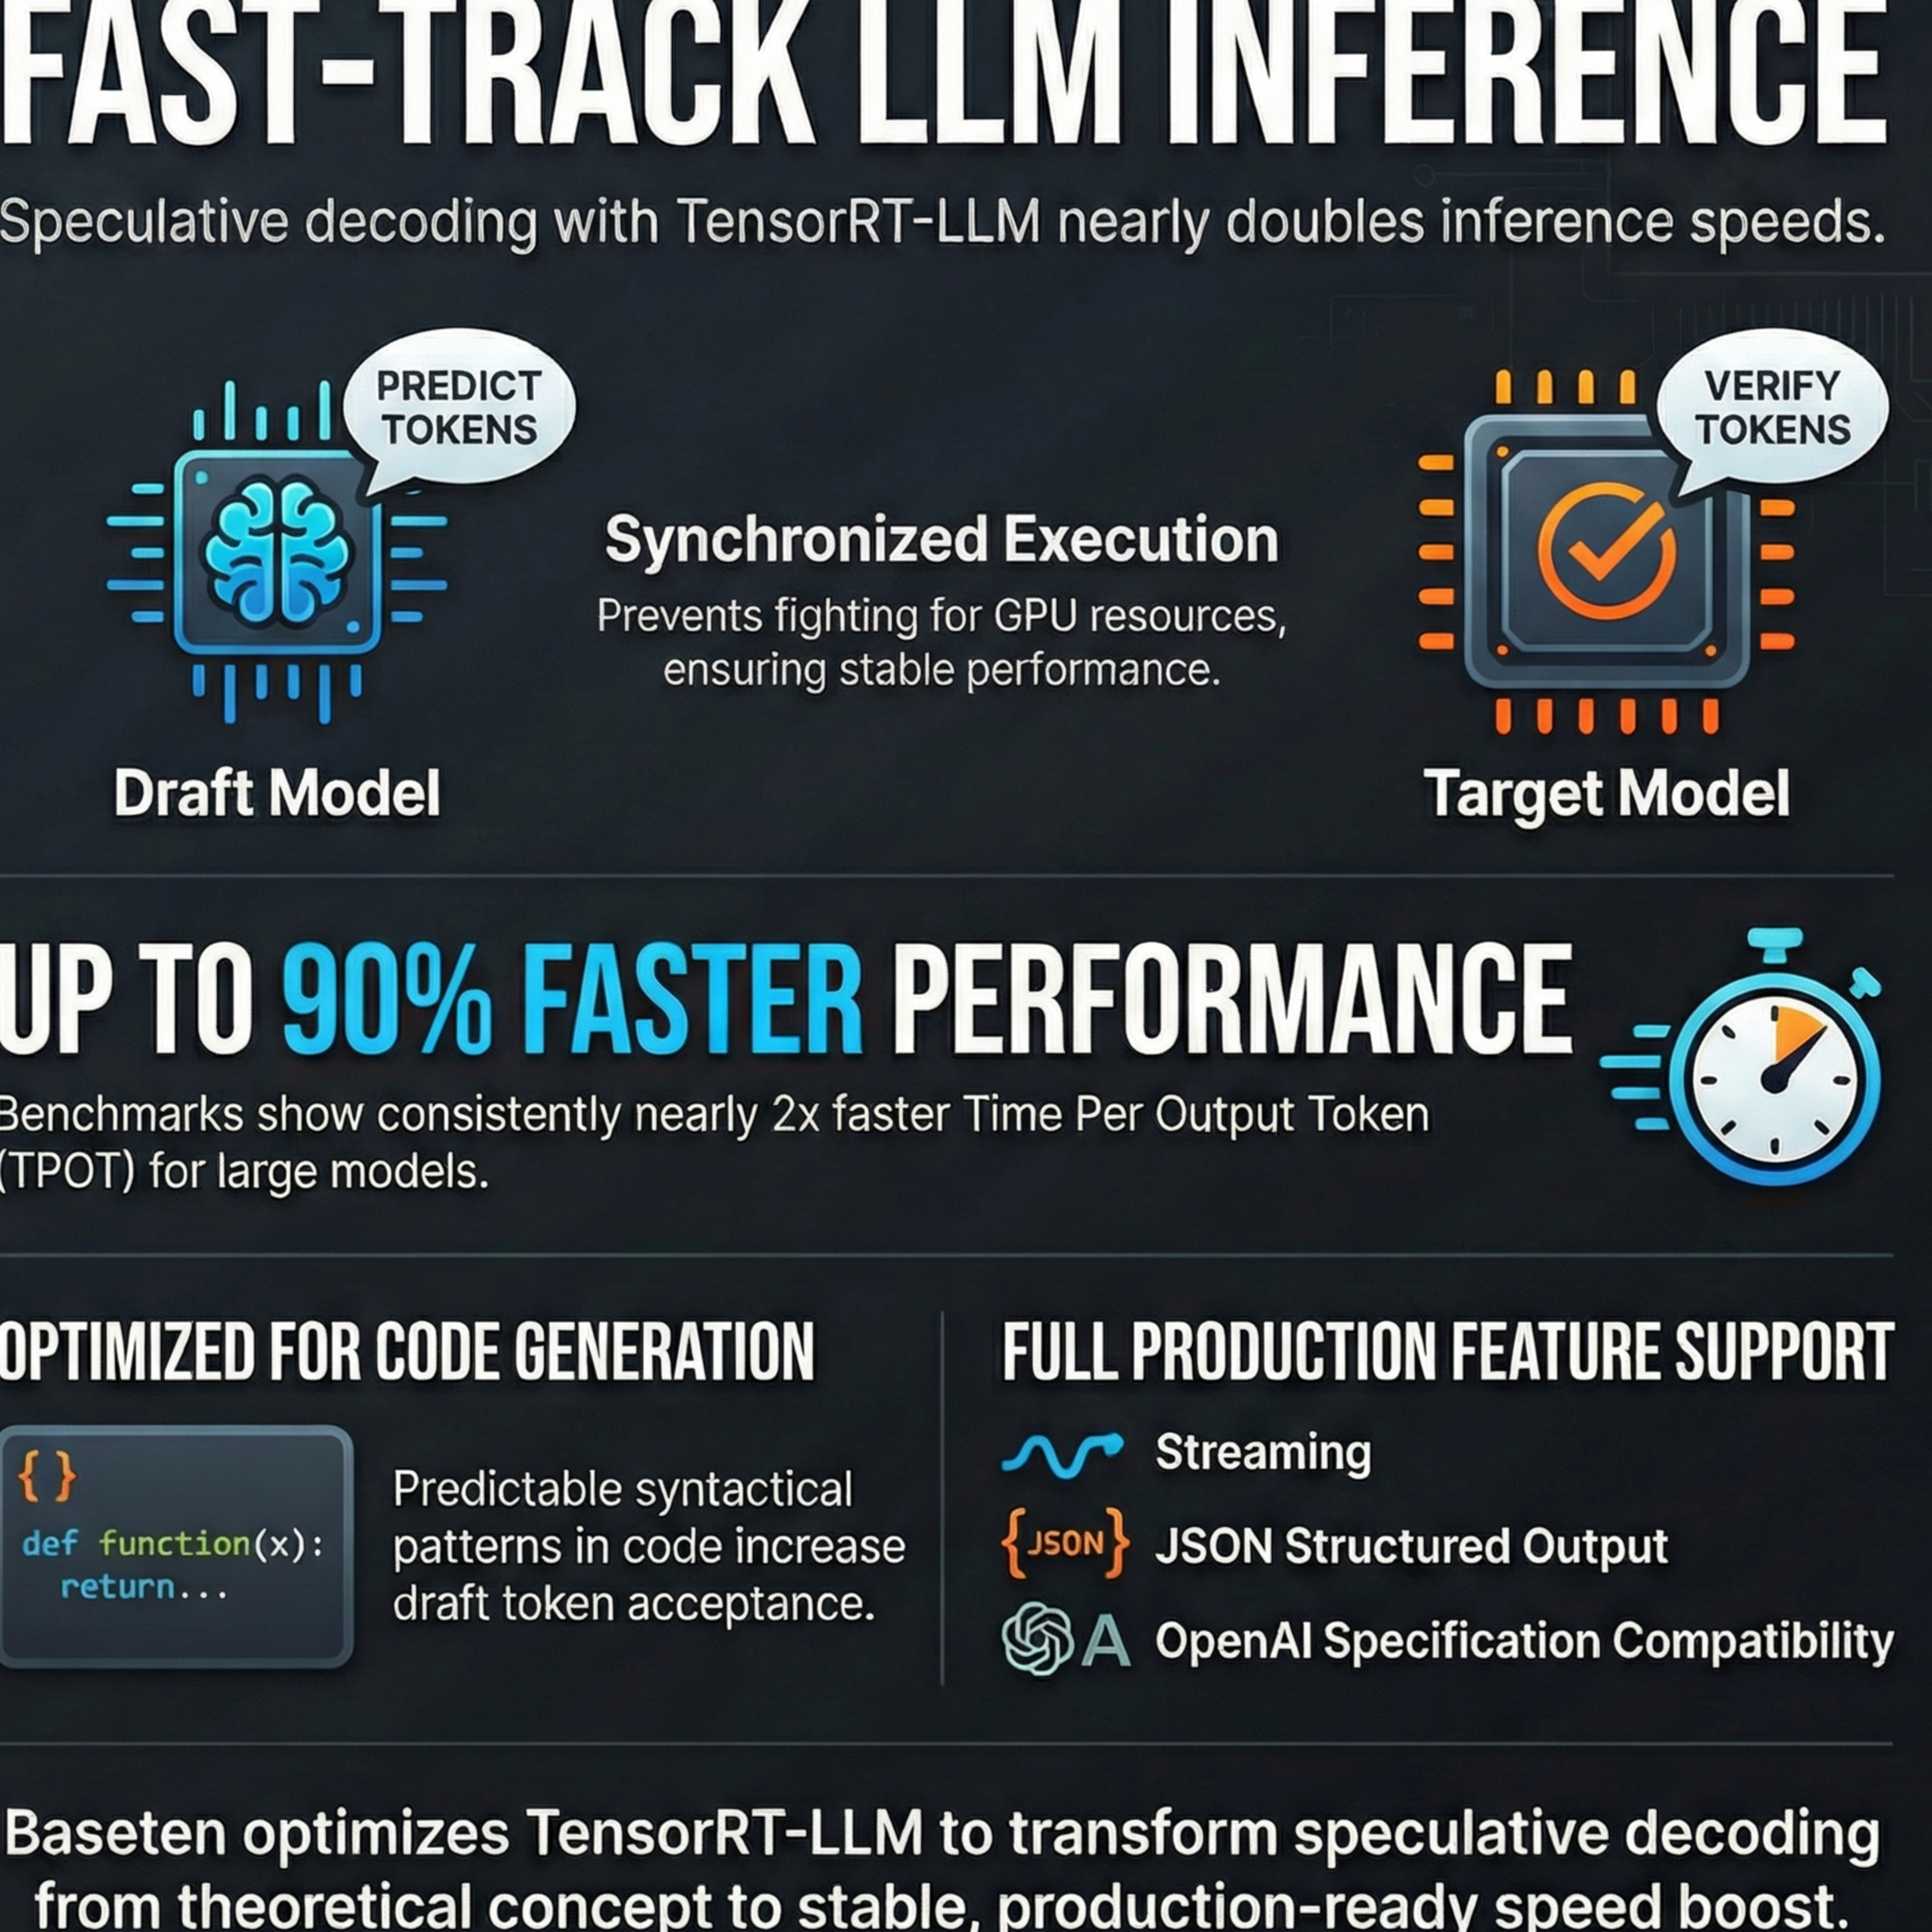
Building Production-Ready Speculative Decoding with TensorRT-LLM — AI ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...