
Speeding Up Speculative Decoding Via Approximate Verification

[논문 리뷰] Speeding up Speculative Decoding via Approximate Verification

Speeding up Speculative Decoding via Approximate Verification | AI ...
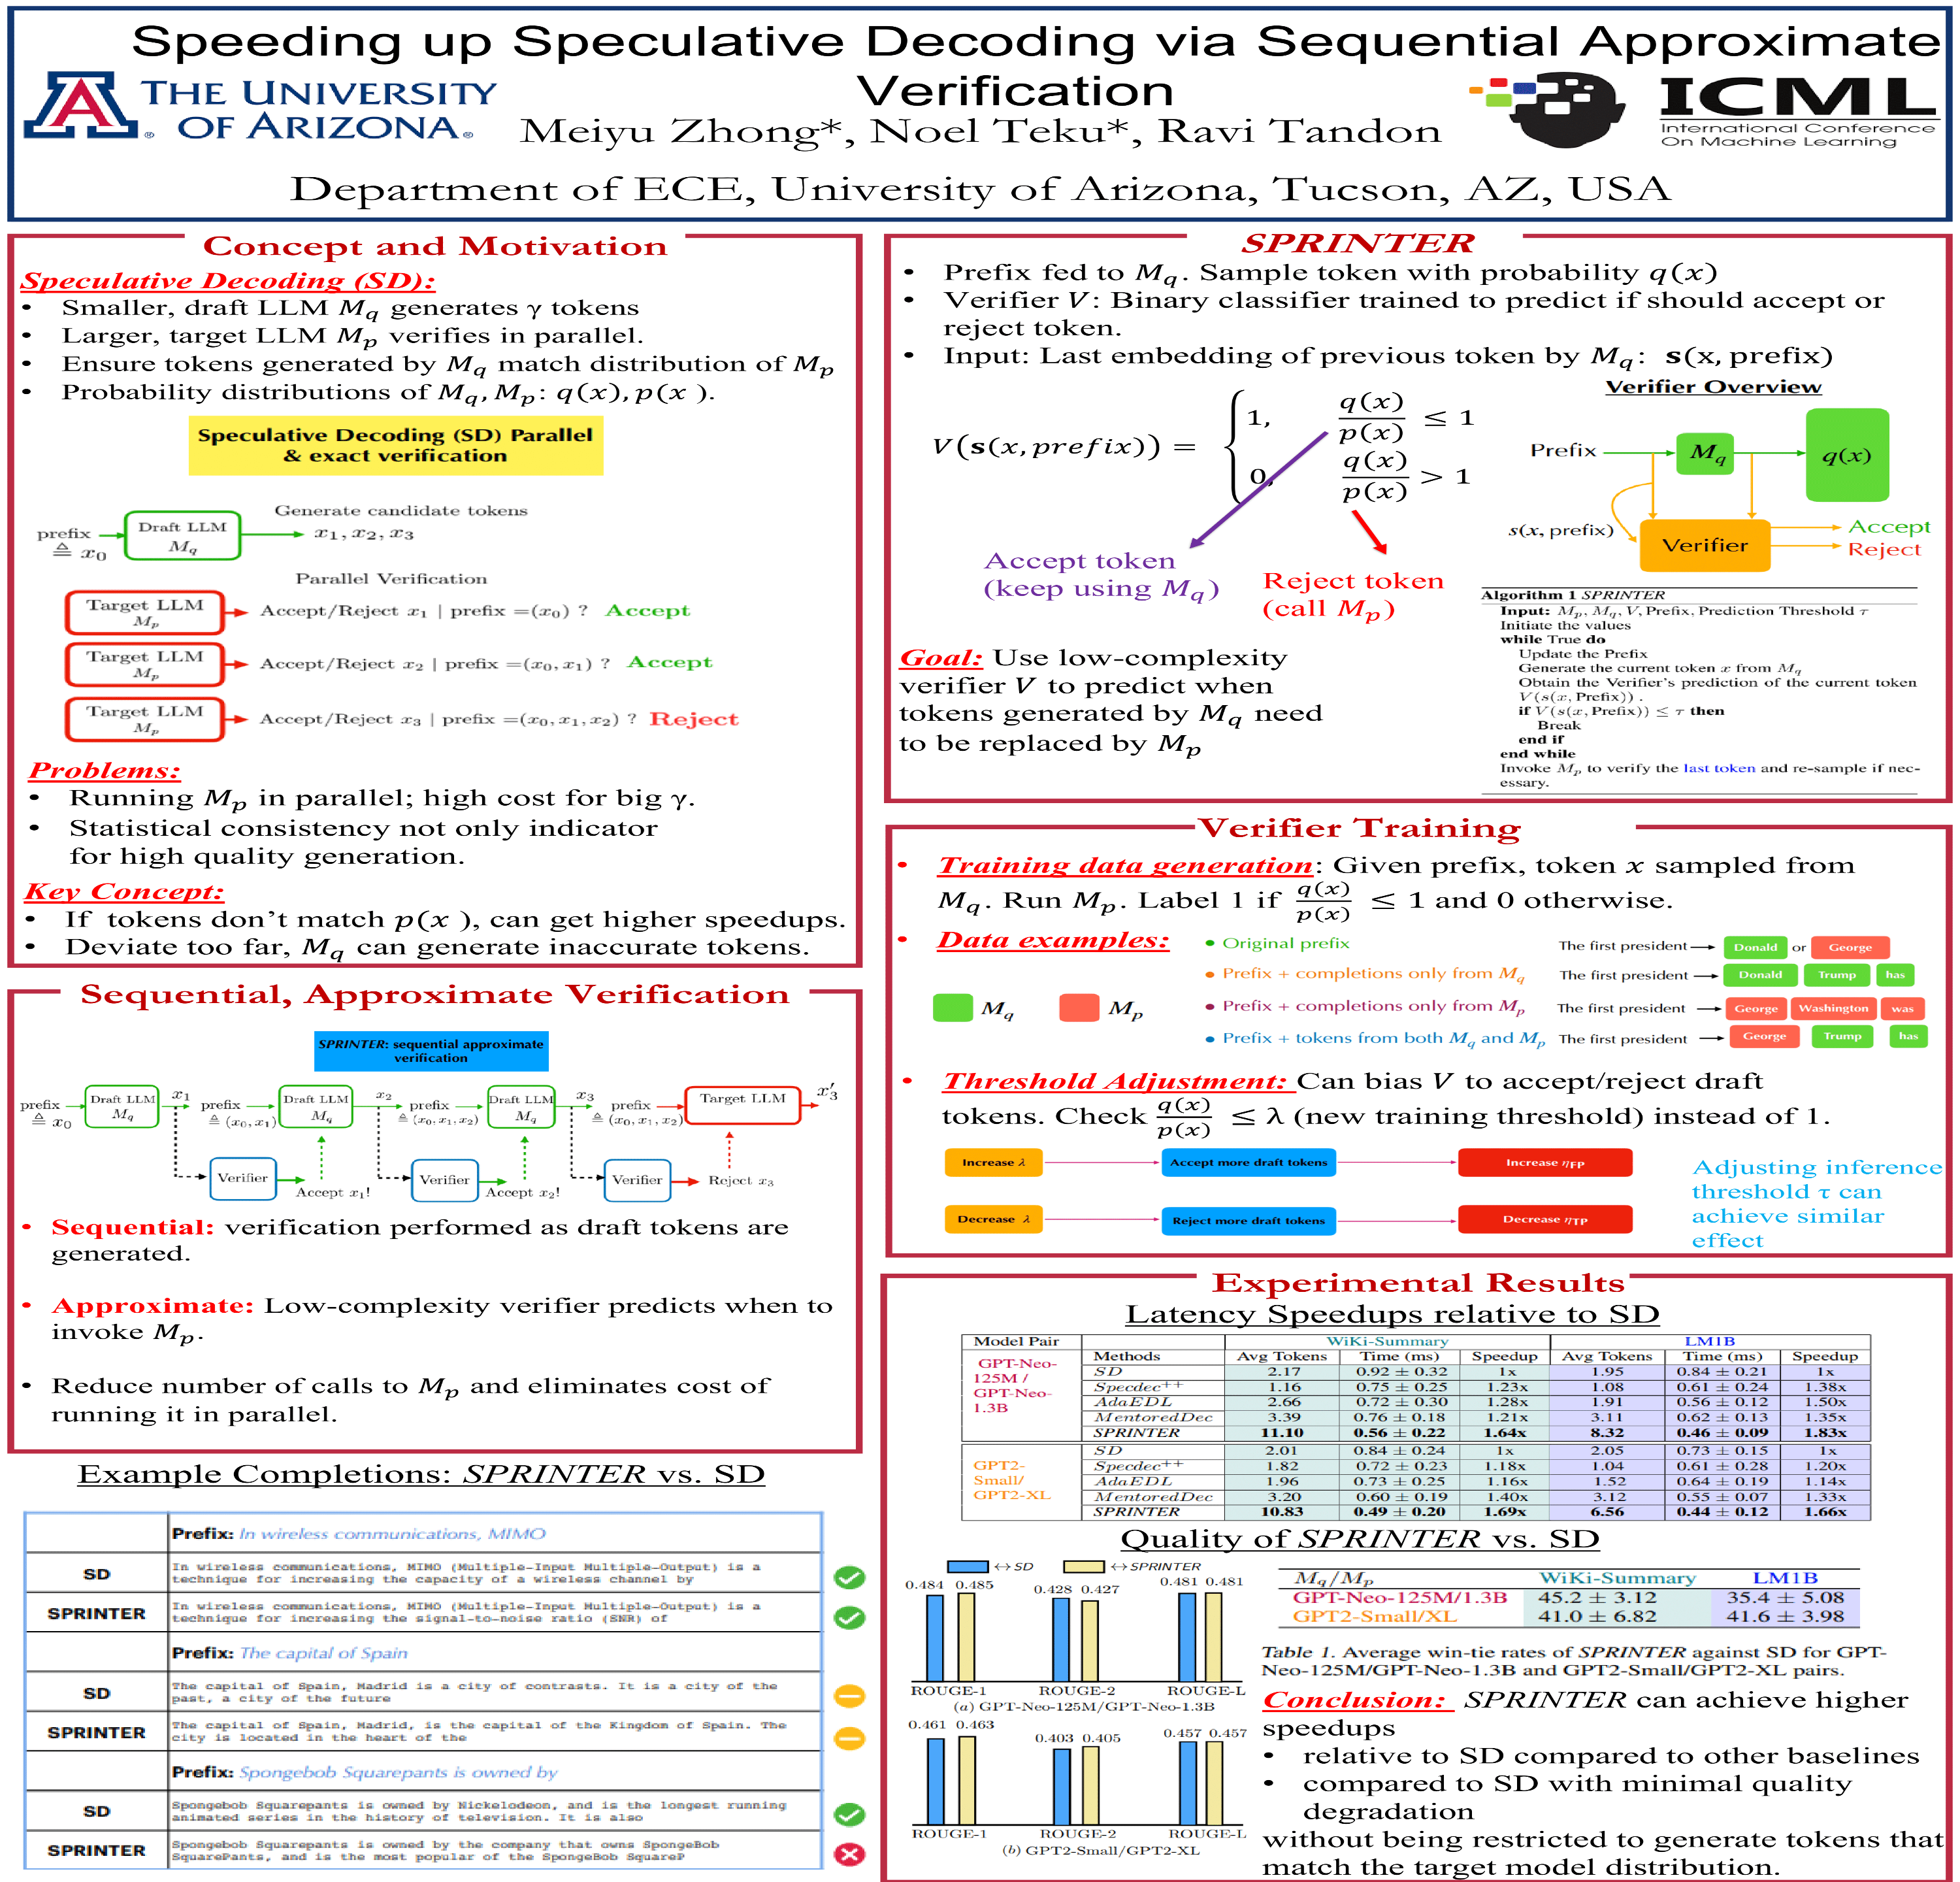
ICML Speeding up Speculative Decoding via Sequential Approximate ...
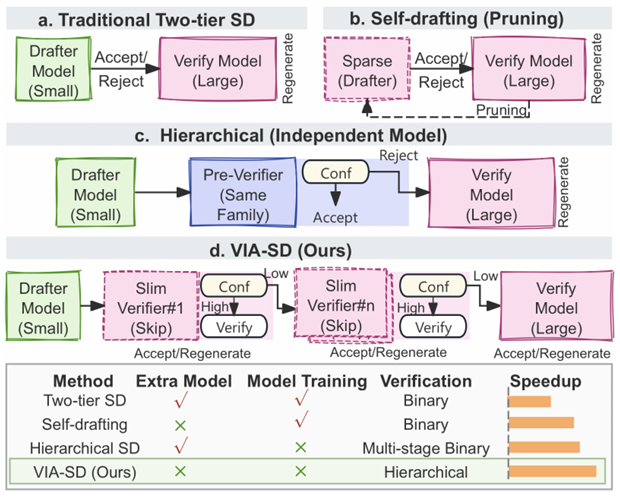
VIA-SD: Verification via Intra-Model Routing for Speculative Decoding ...

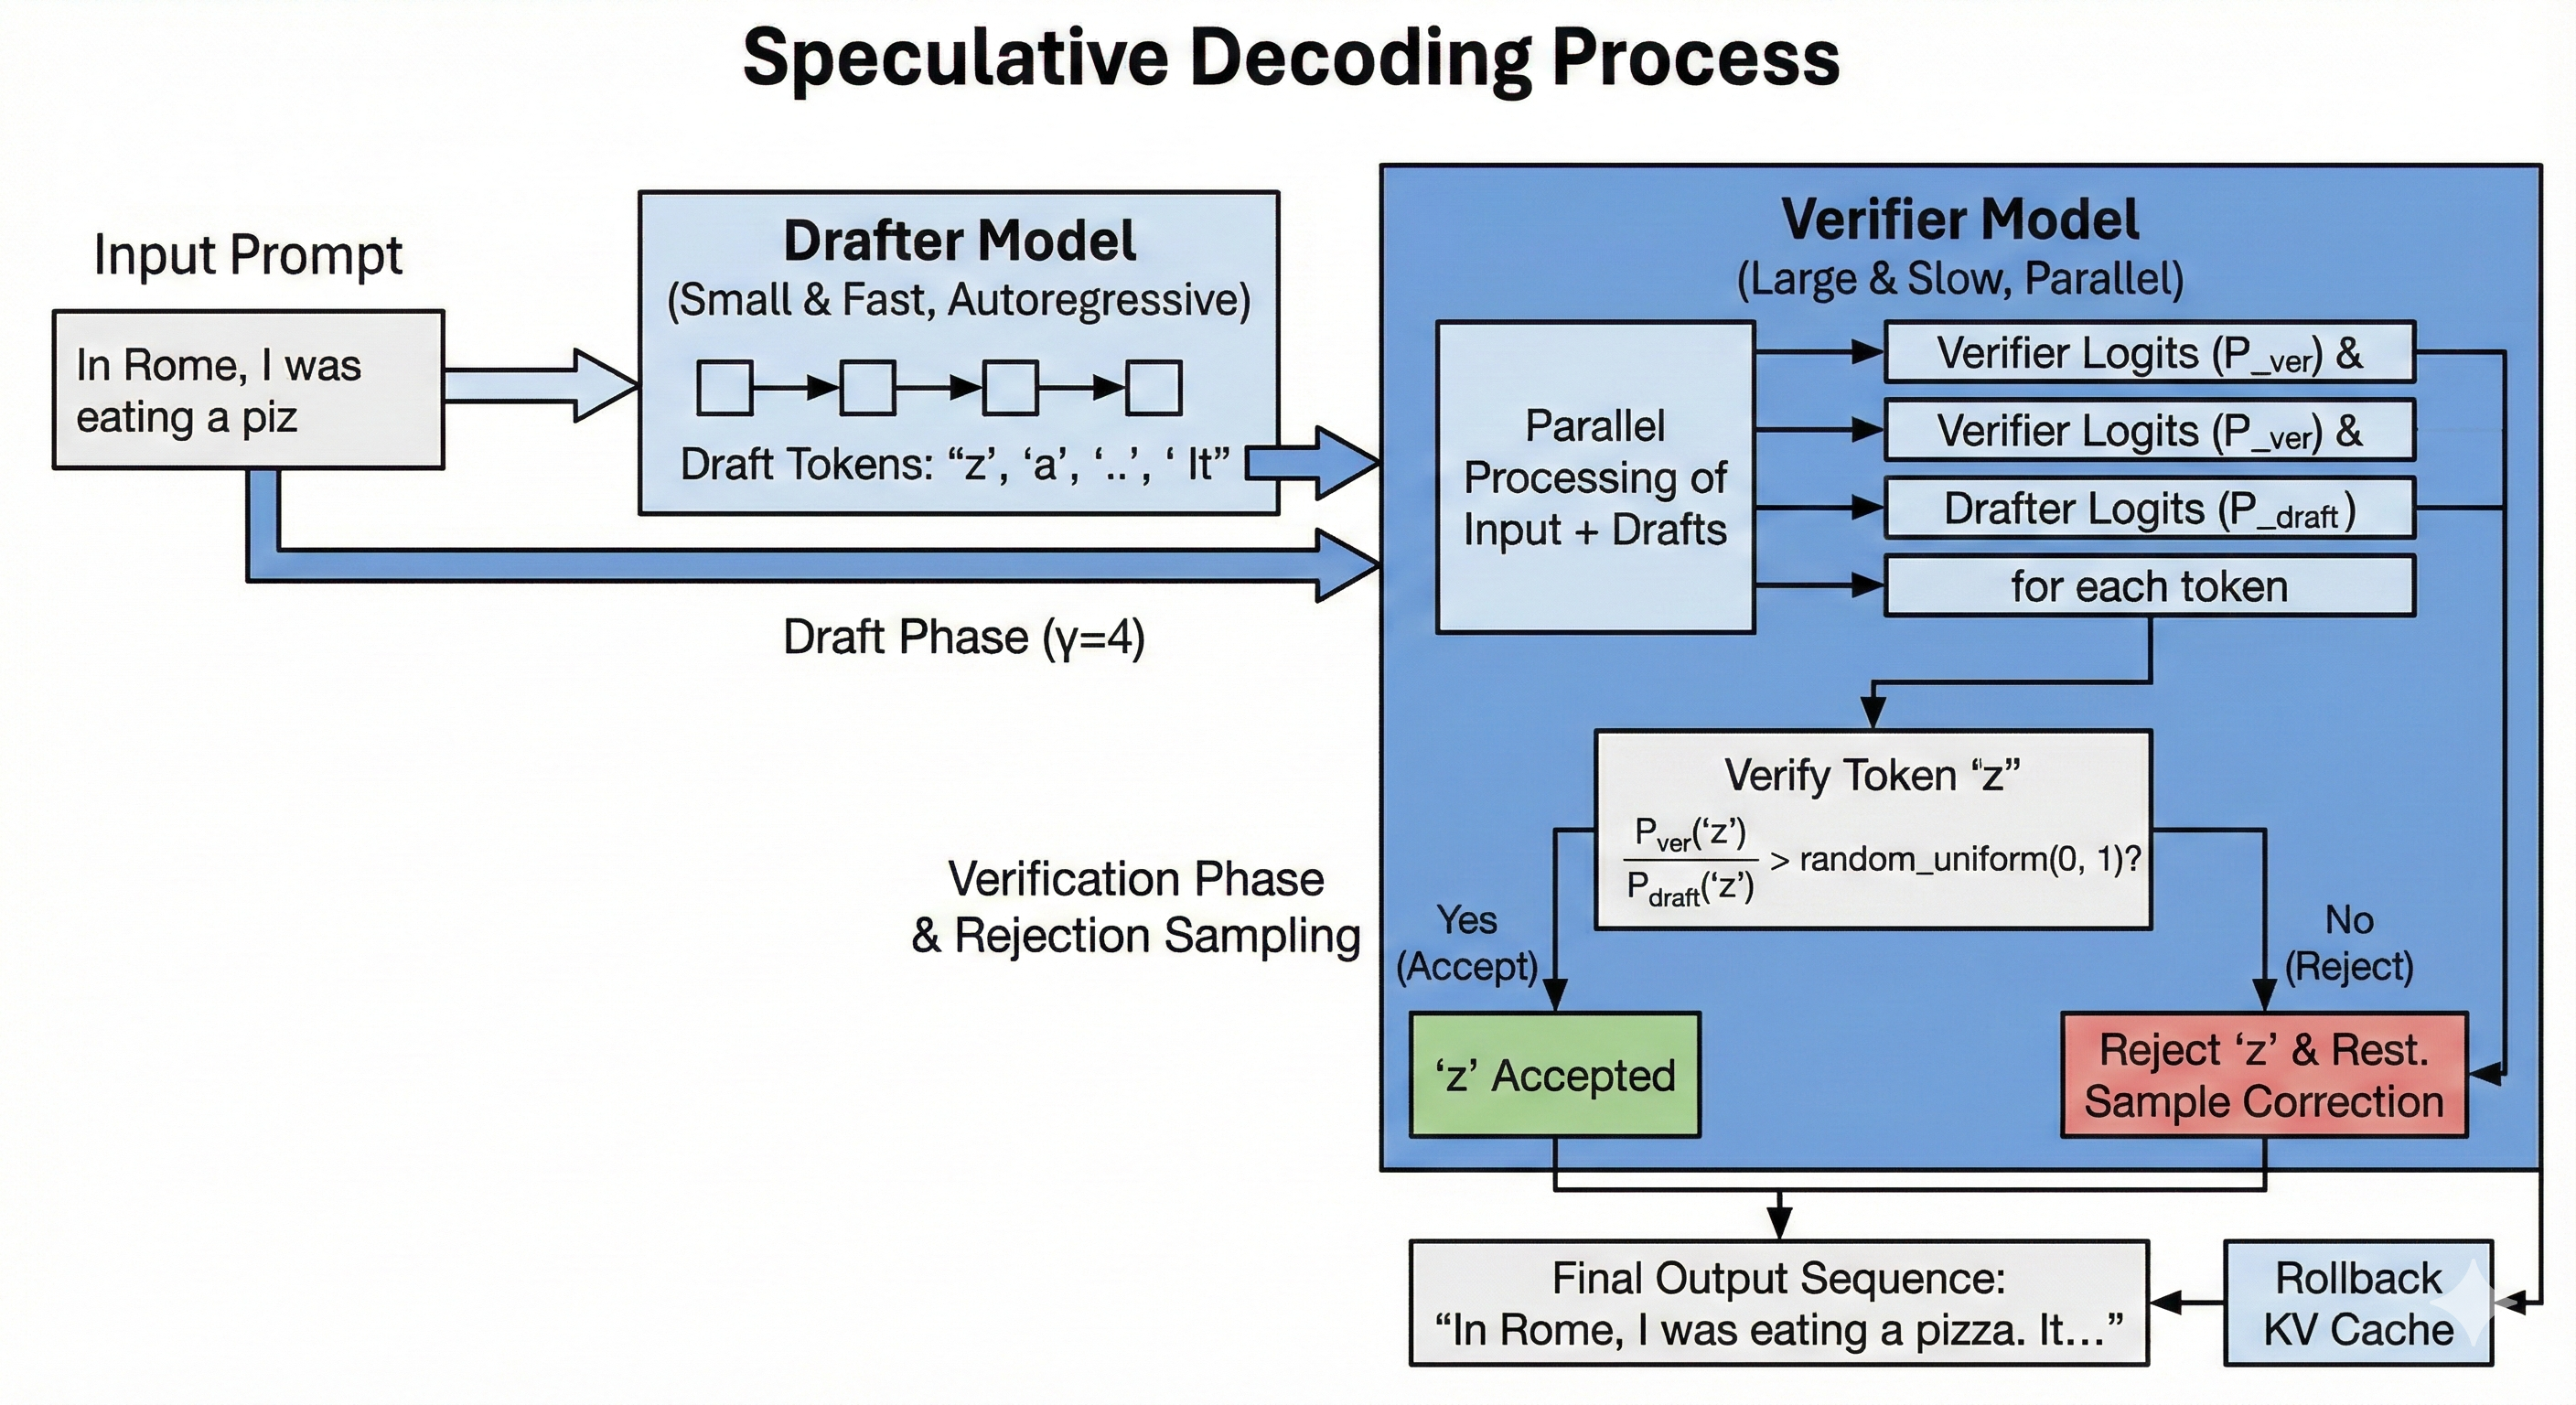
Speeding Up LLM Inference : Speculative Decoding Explained in the ...

SAM Decoding: Speculative Decoding via Suffix Automaton | AI Research ...

[New paper] TL;DR We speed up speculative decoding (for free) using ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
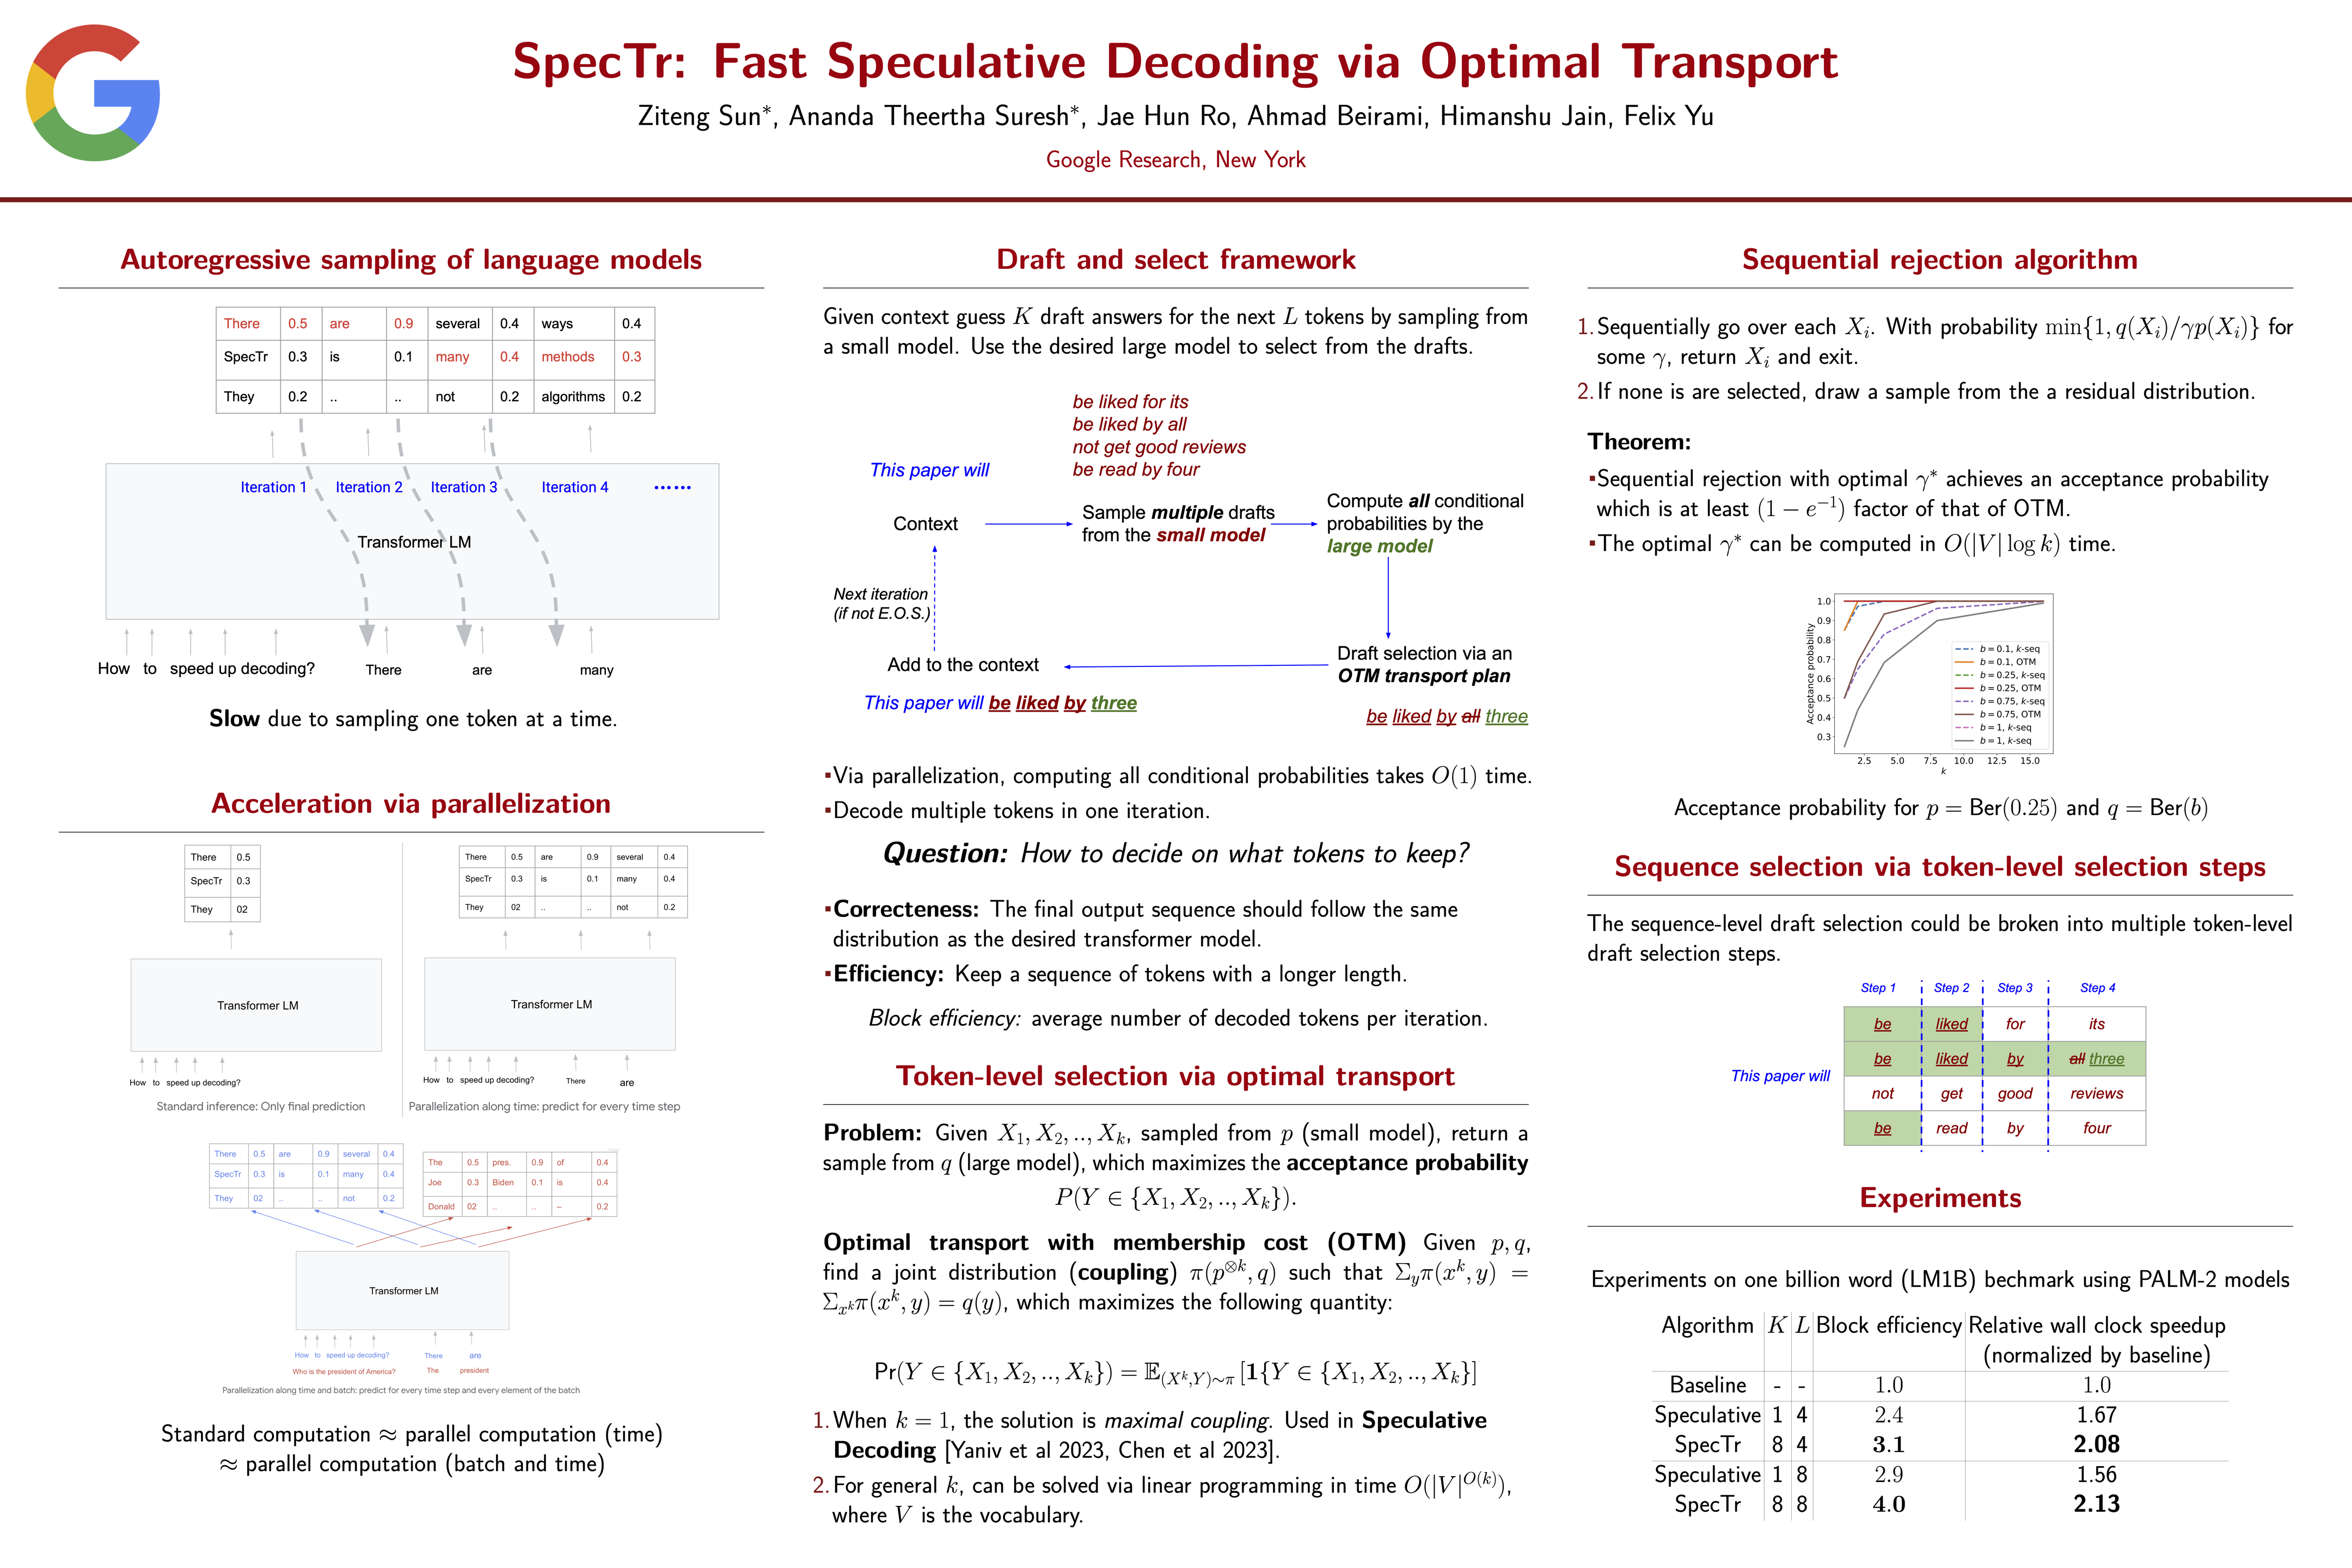
NeurIPS Poster SpecTr: Fast Speculative Decoding via Optimal Transport
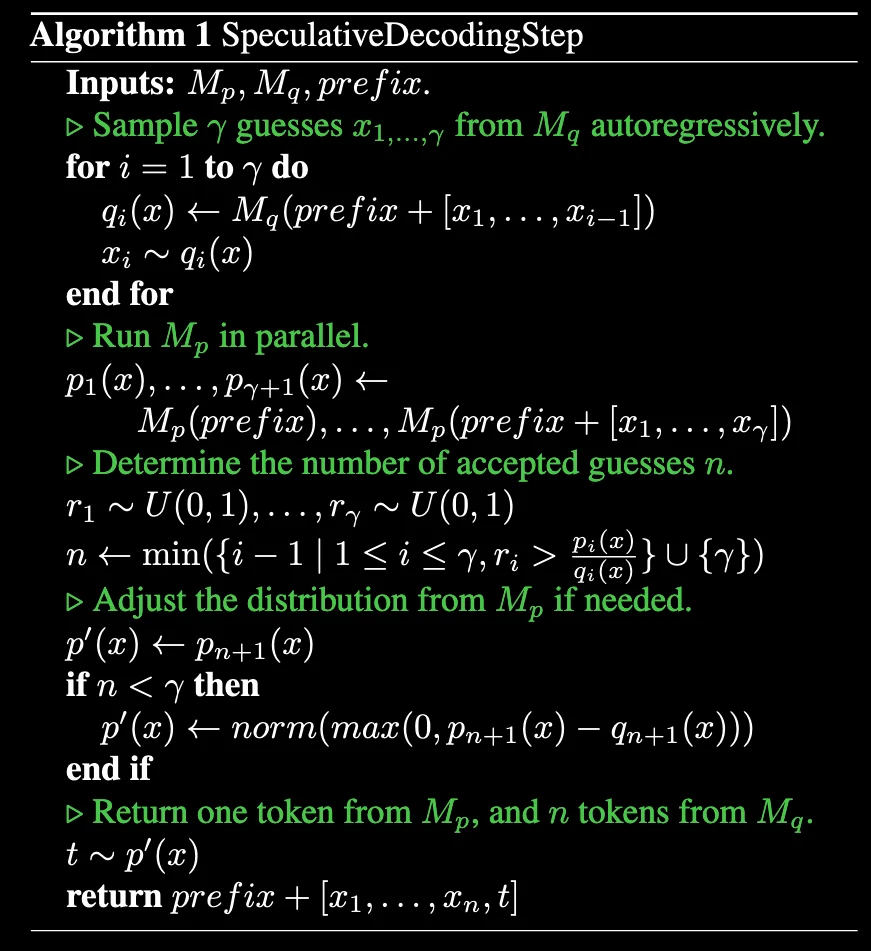
Fast Inference from Transformer via Speculative Decoding • Nadya Yuki ...
Advertisement Space (300x250)

TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...

[논문 리뷰] BanditSpec: Adaptive Speculative Decoding via Bandit Algorithms

Figure 1 from Block Verification Accelerates Speculative Decoding ...

(PDF) Block Verification Accelerates Speculative Decoding
Speculative Decoding - ML Performance
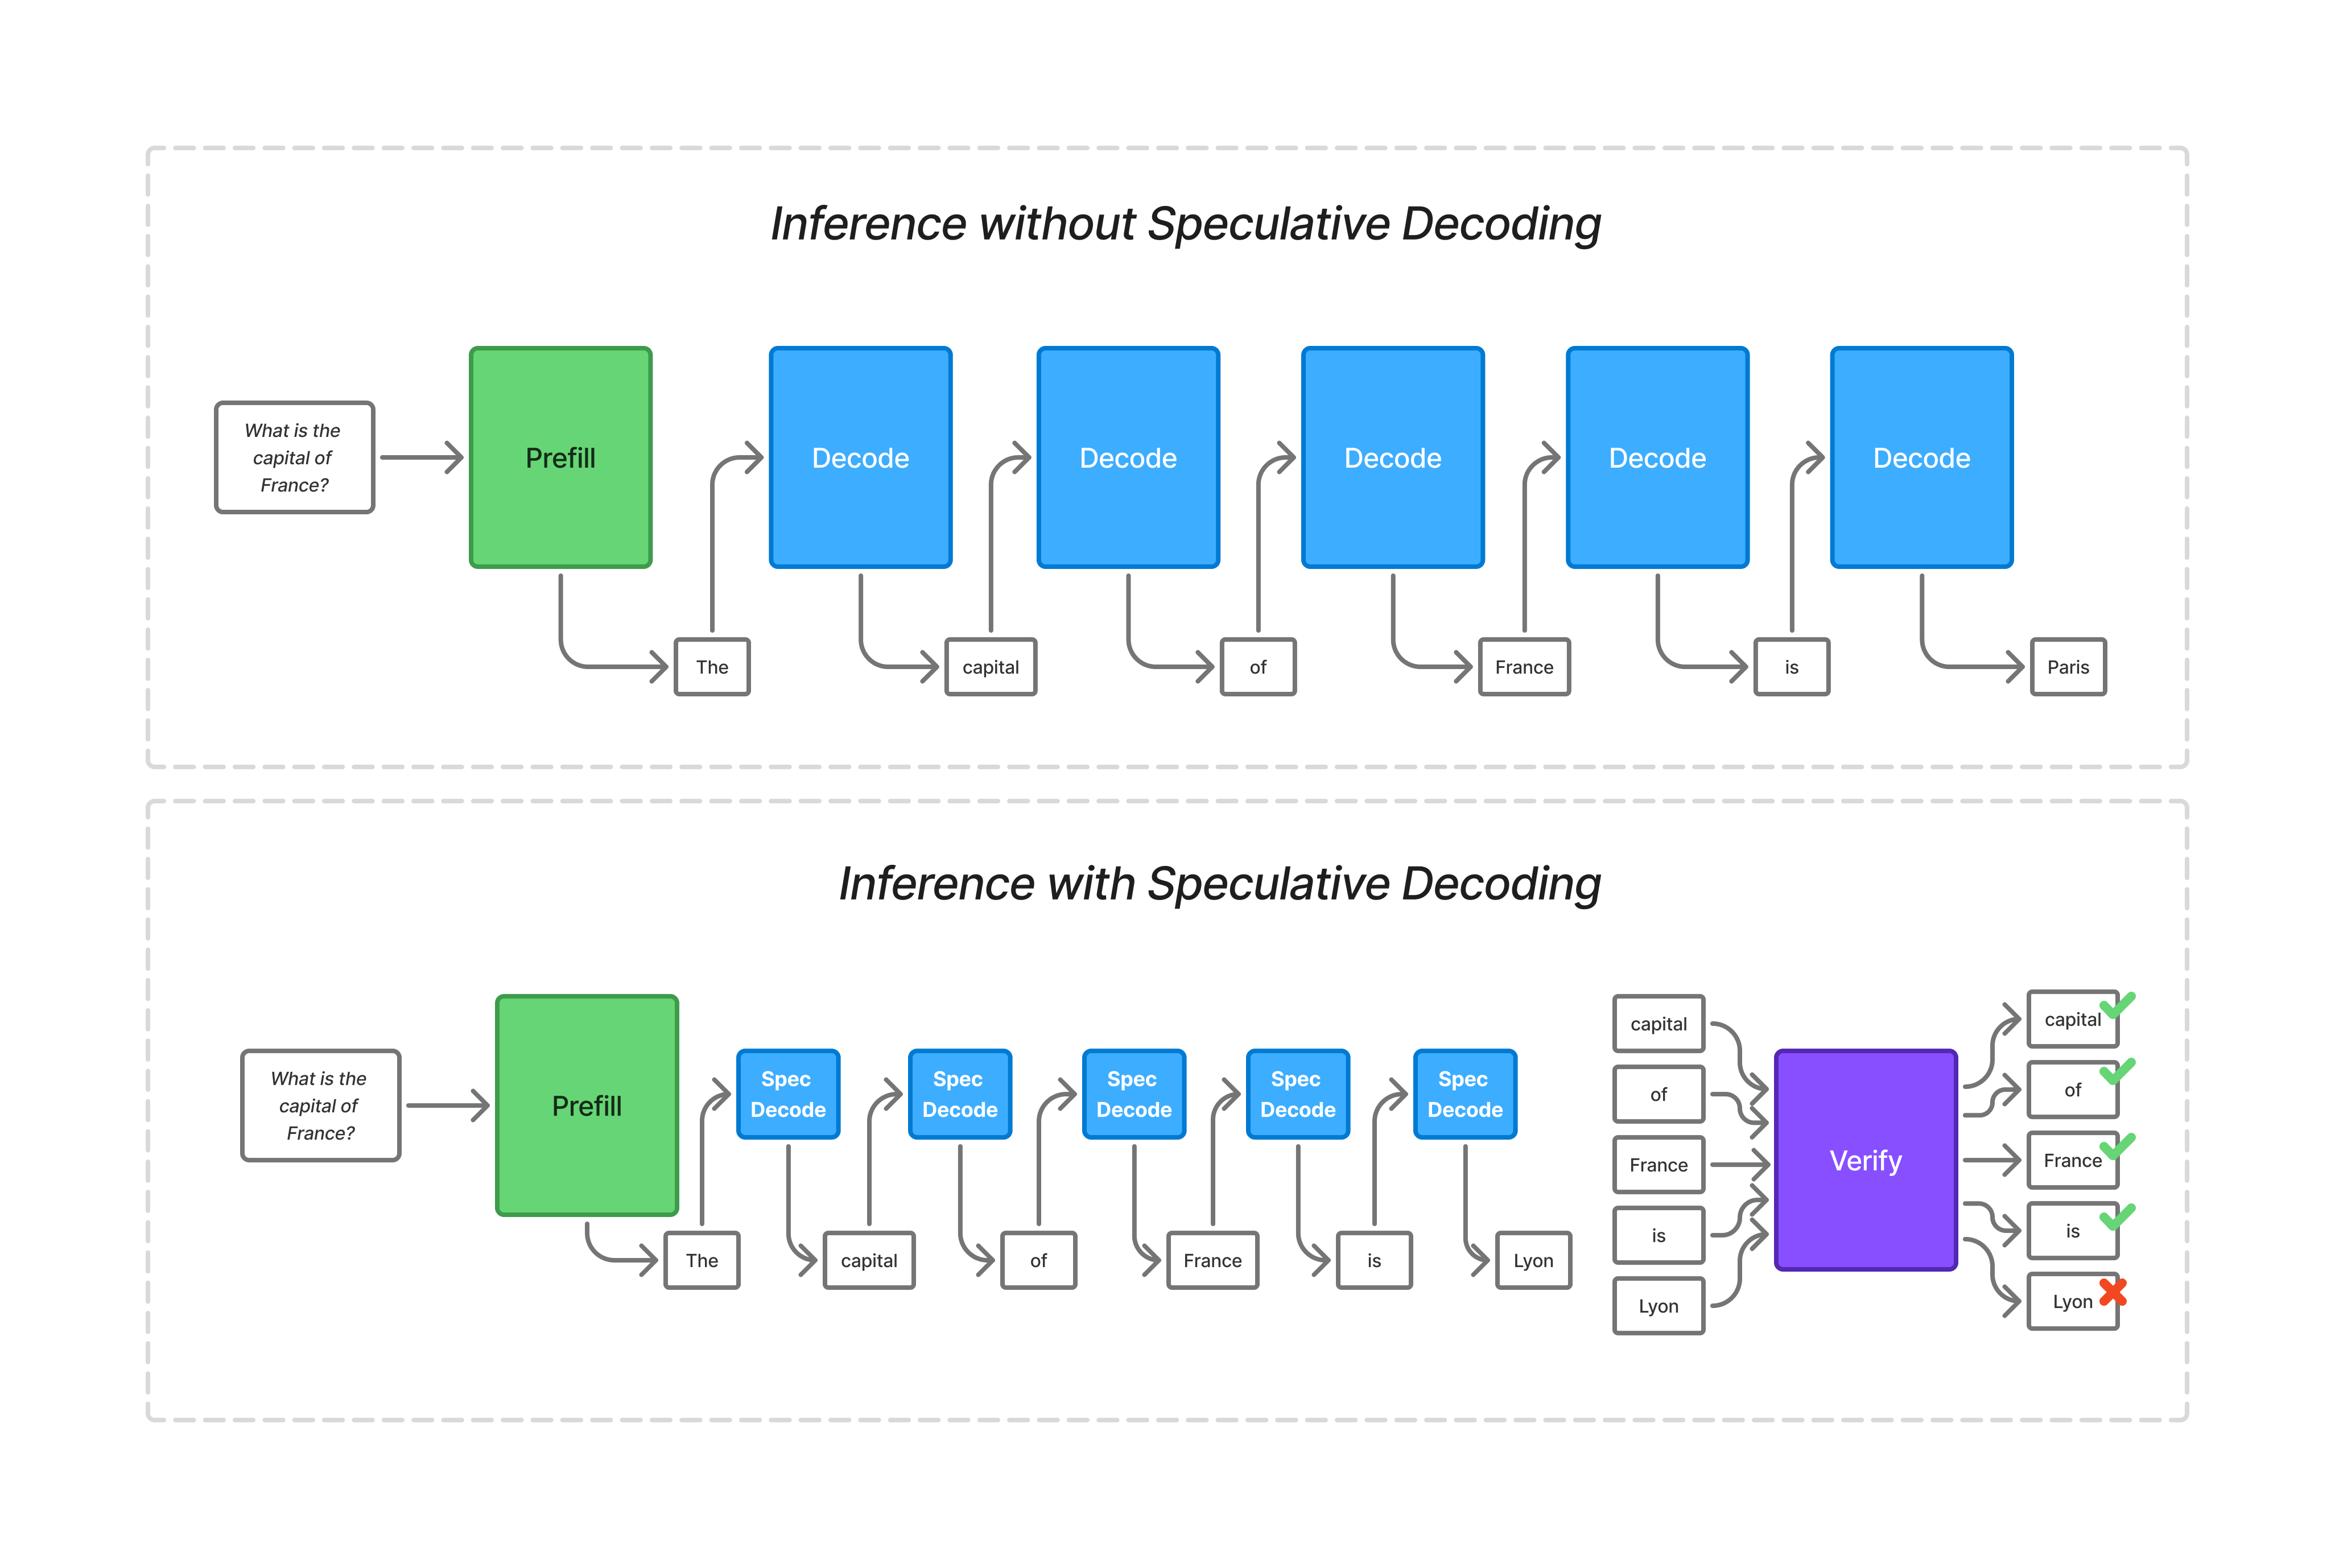
Low-Latency Inference with Speculative Decoding on d-Matrix Corsair and ...
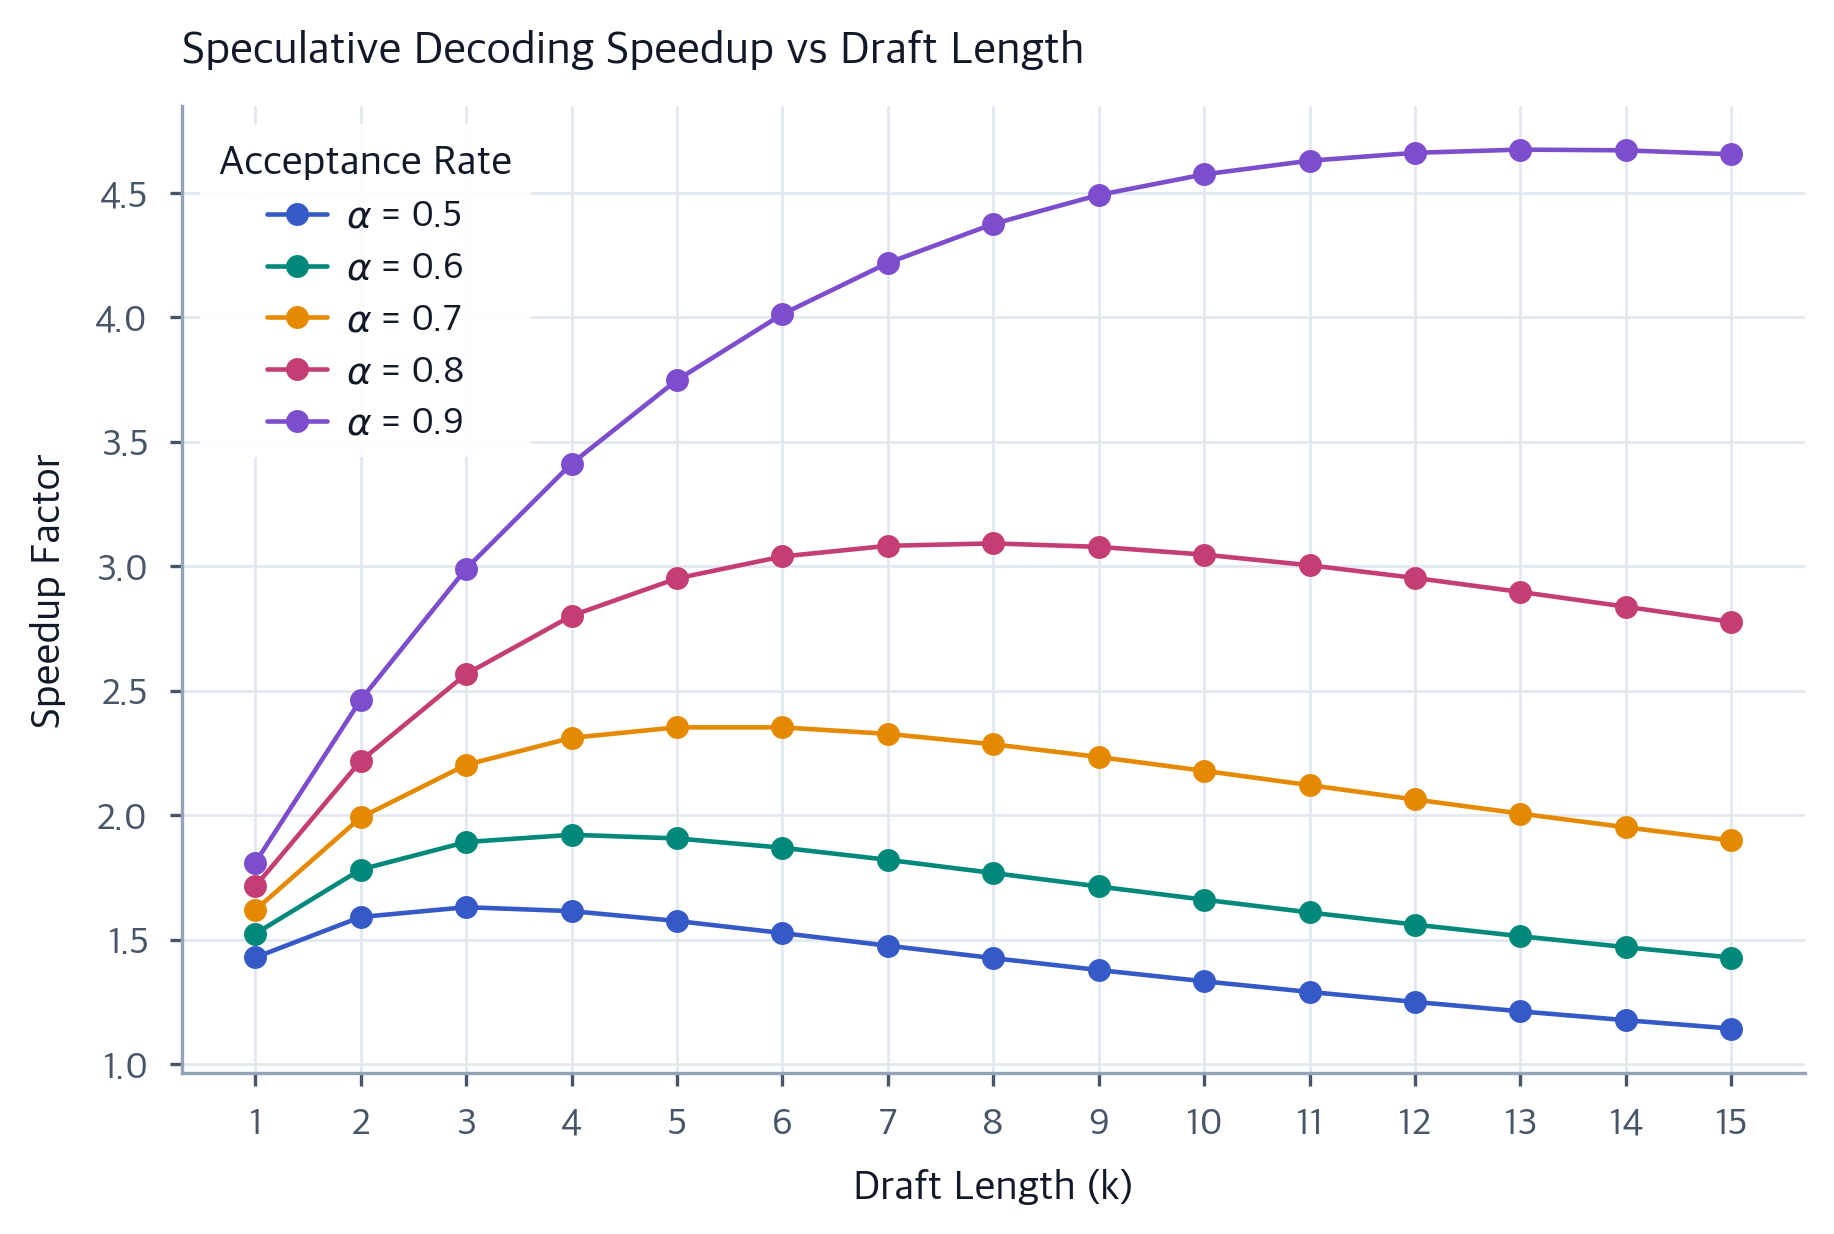
Speculative Decoding Math: Algorithms & Speedup Limits - Interactive ...
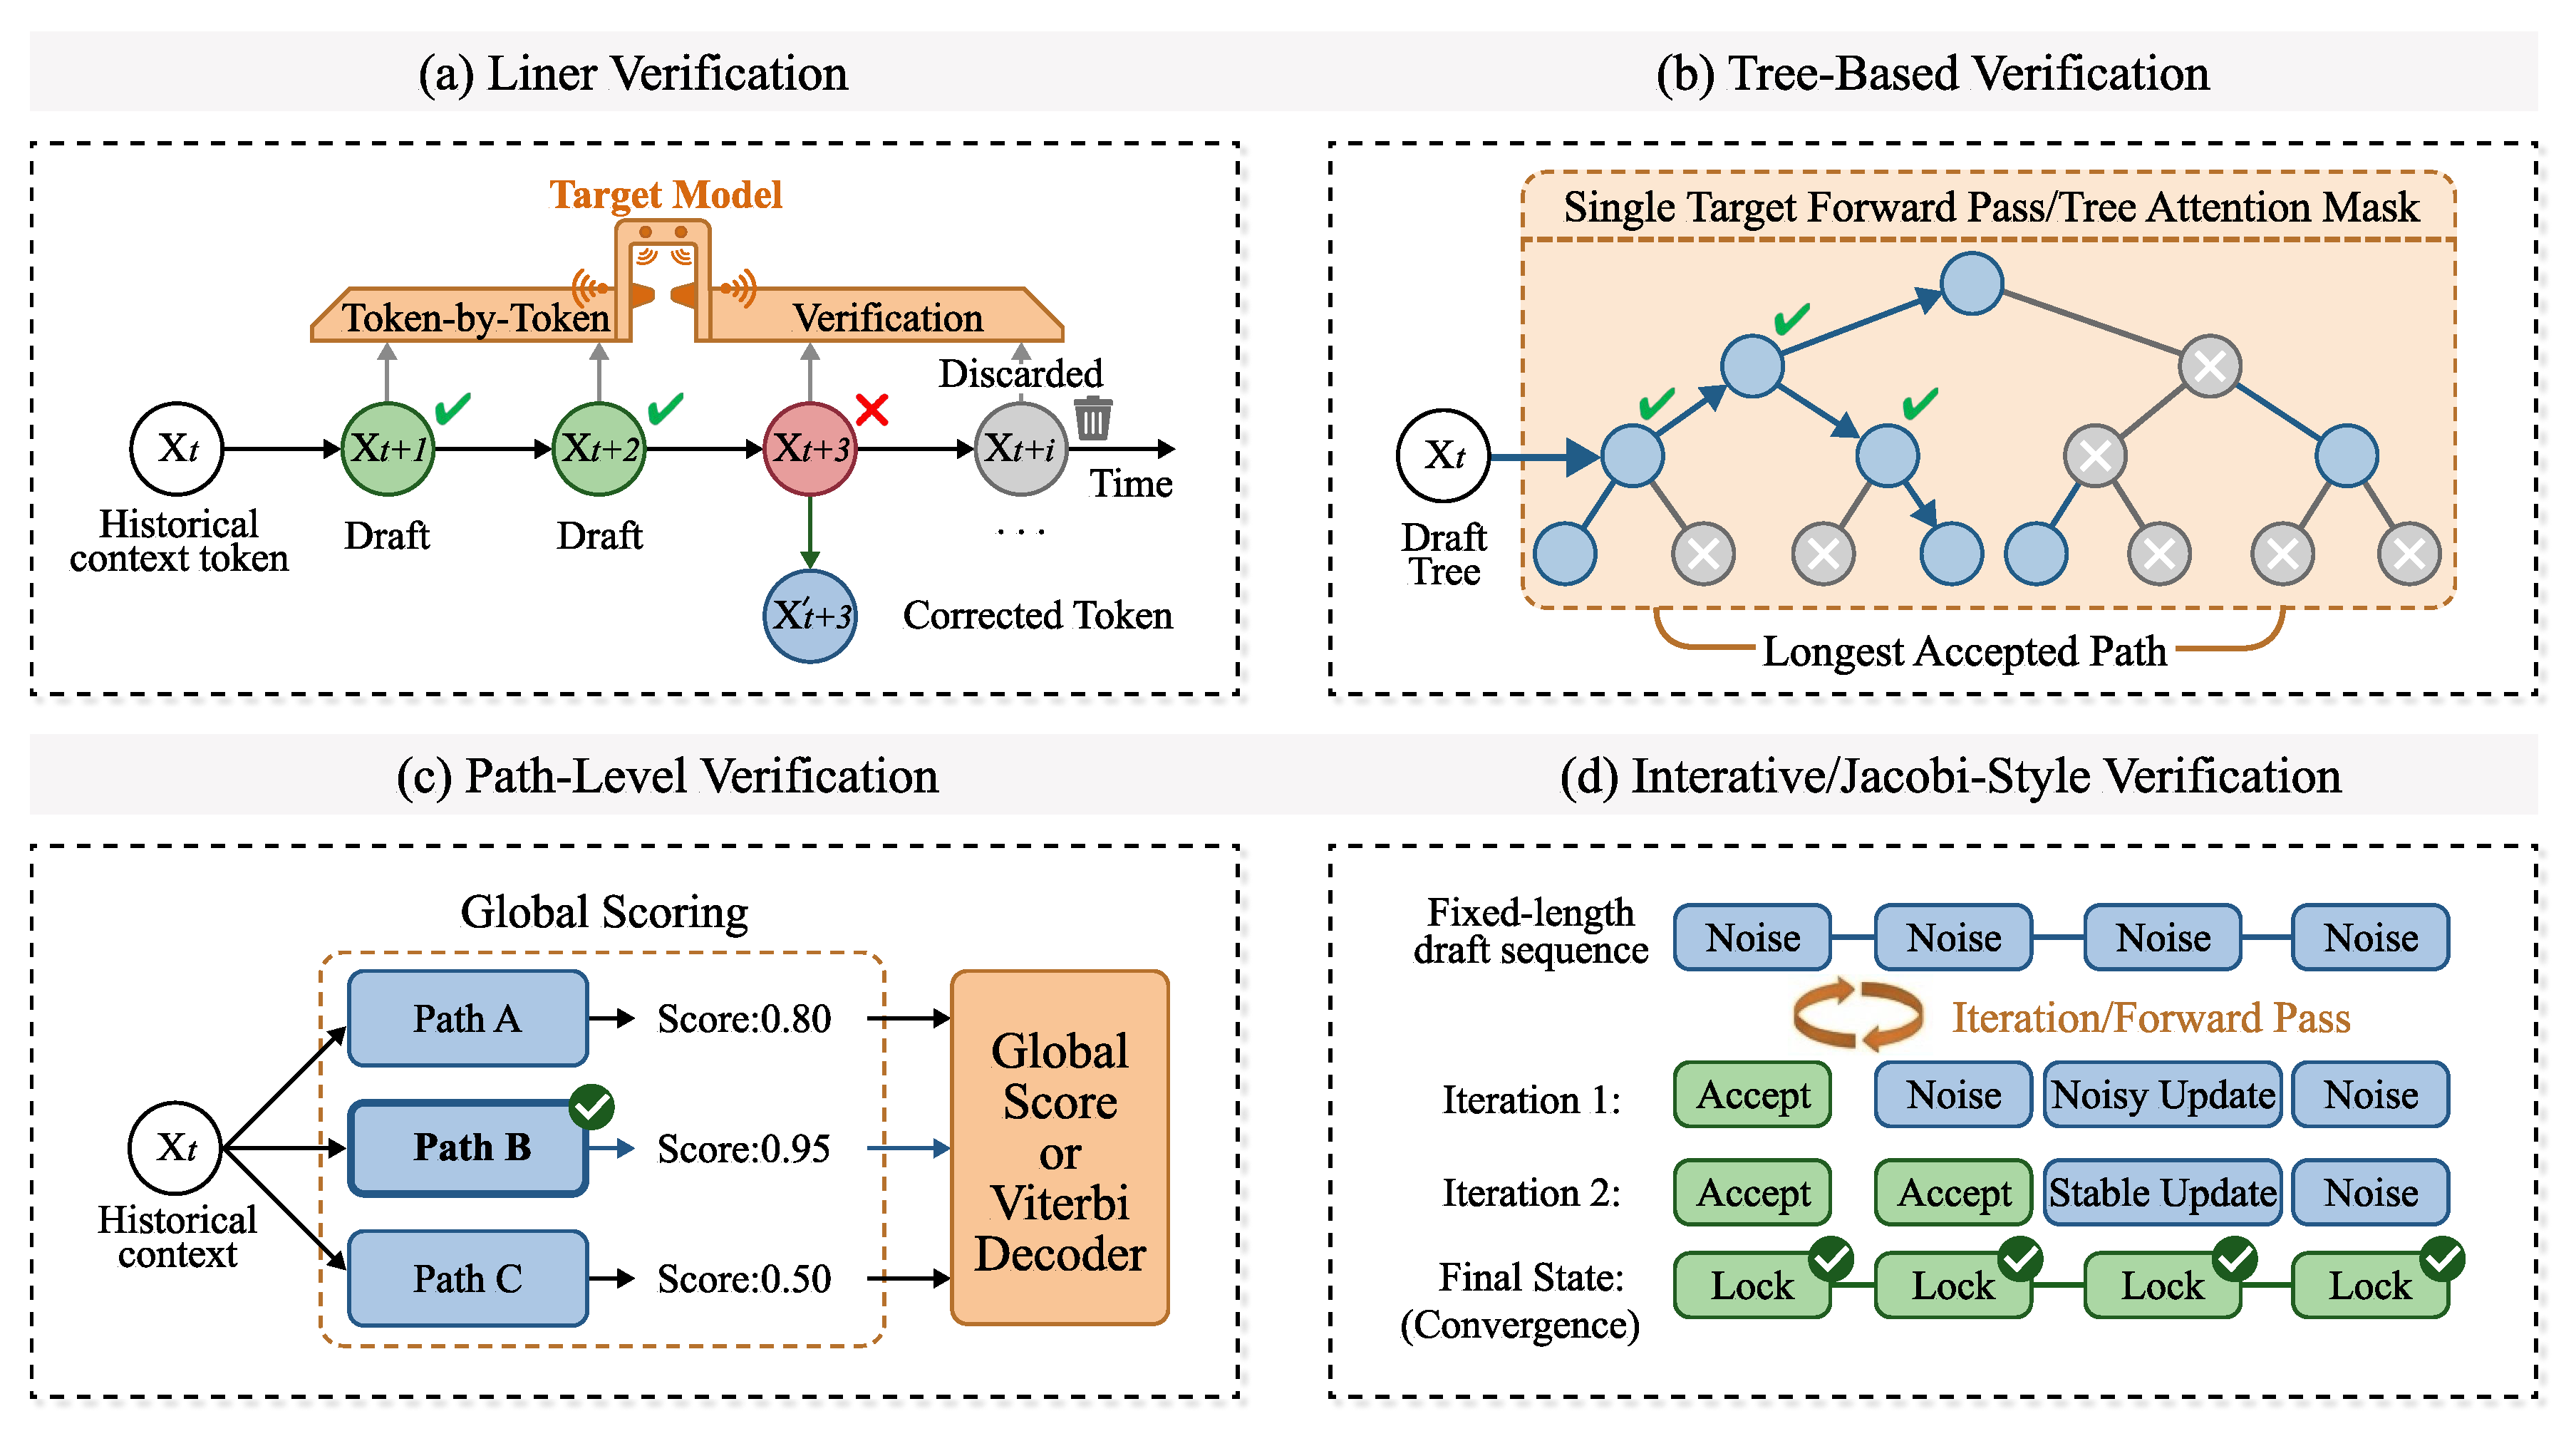
Speculative Decoding for Multimodal Models: A Survey[v2] | Preprints.org
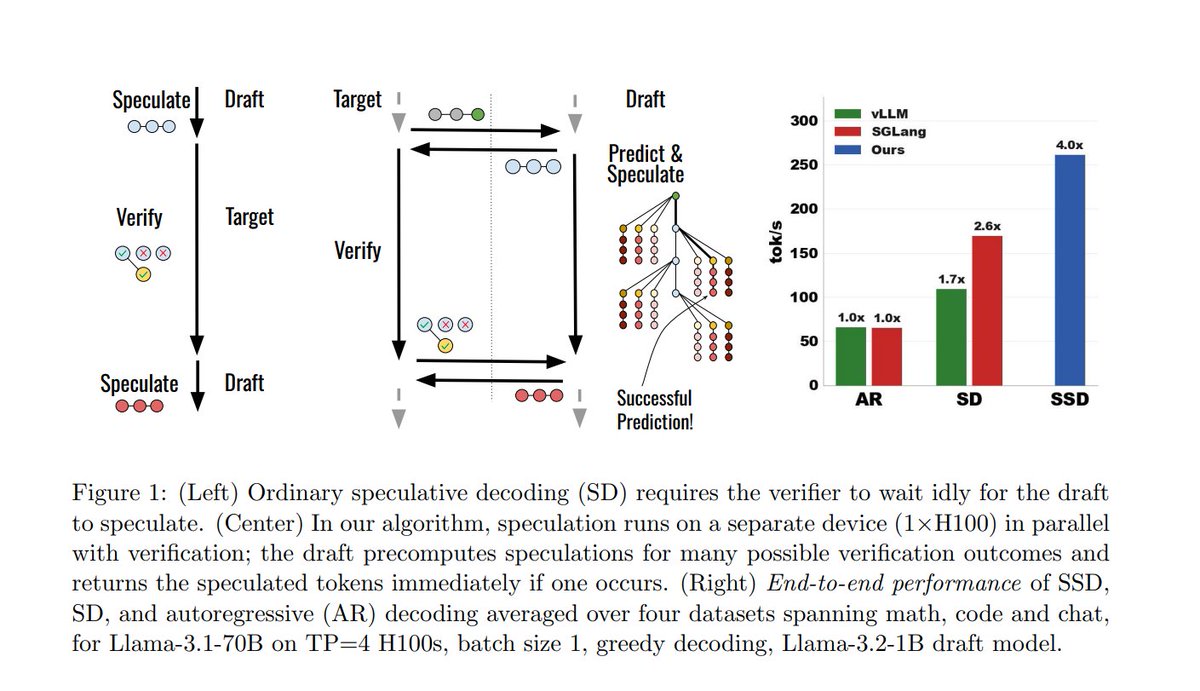
Speculative Speculative Decoding Author's Explanation: https://t.co ...
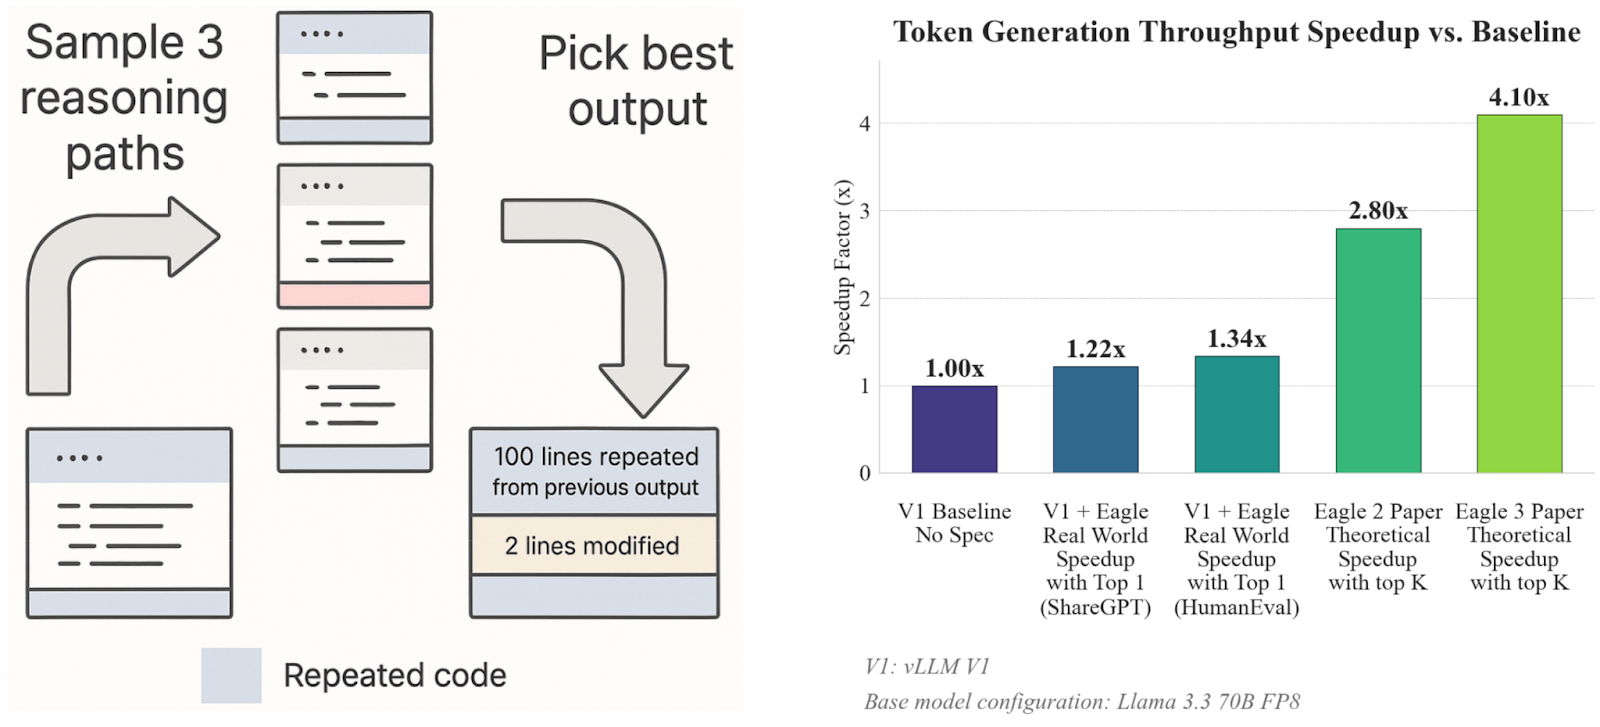
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
Advertisement Space (336x280)

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
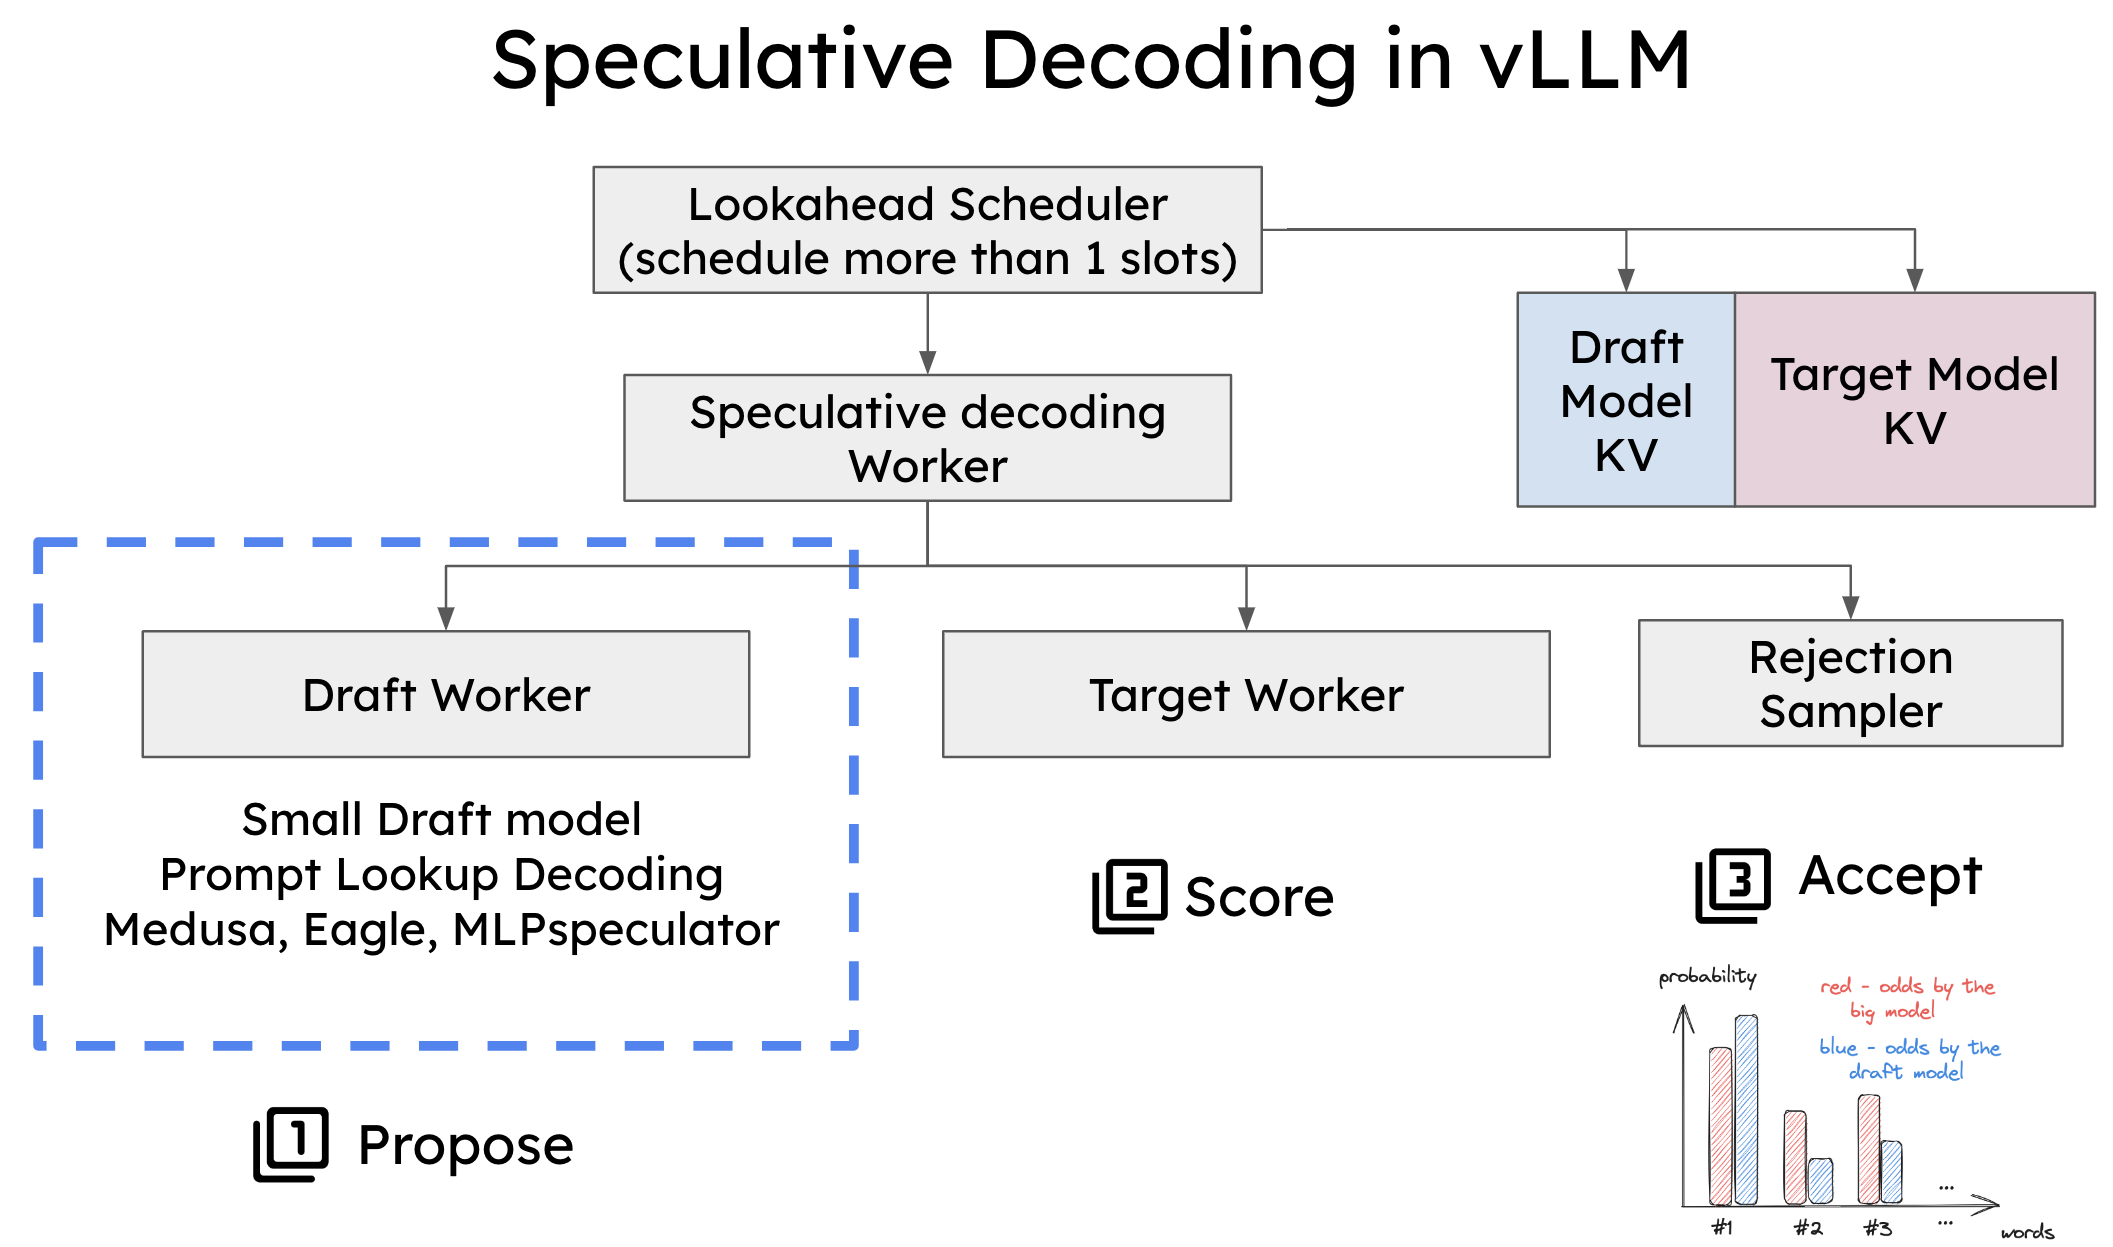
Speculative Decoding in vLLM | OpenLM.ai
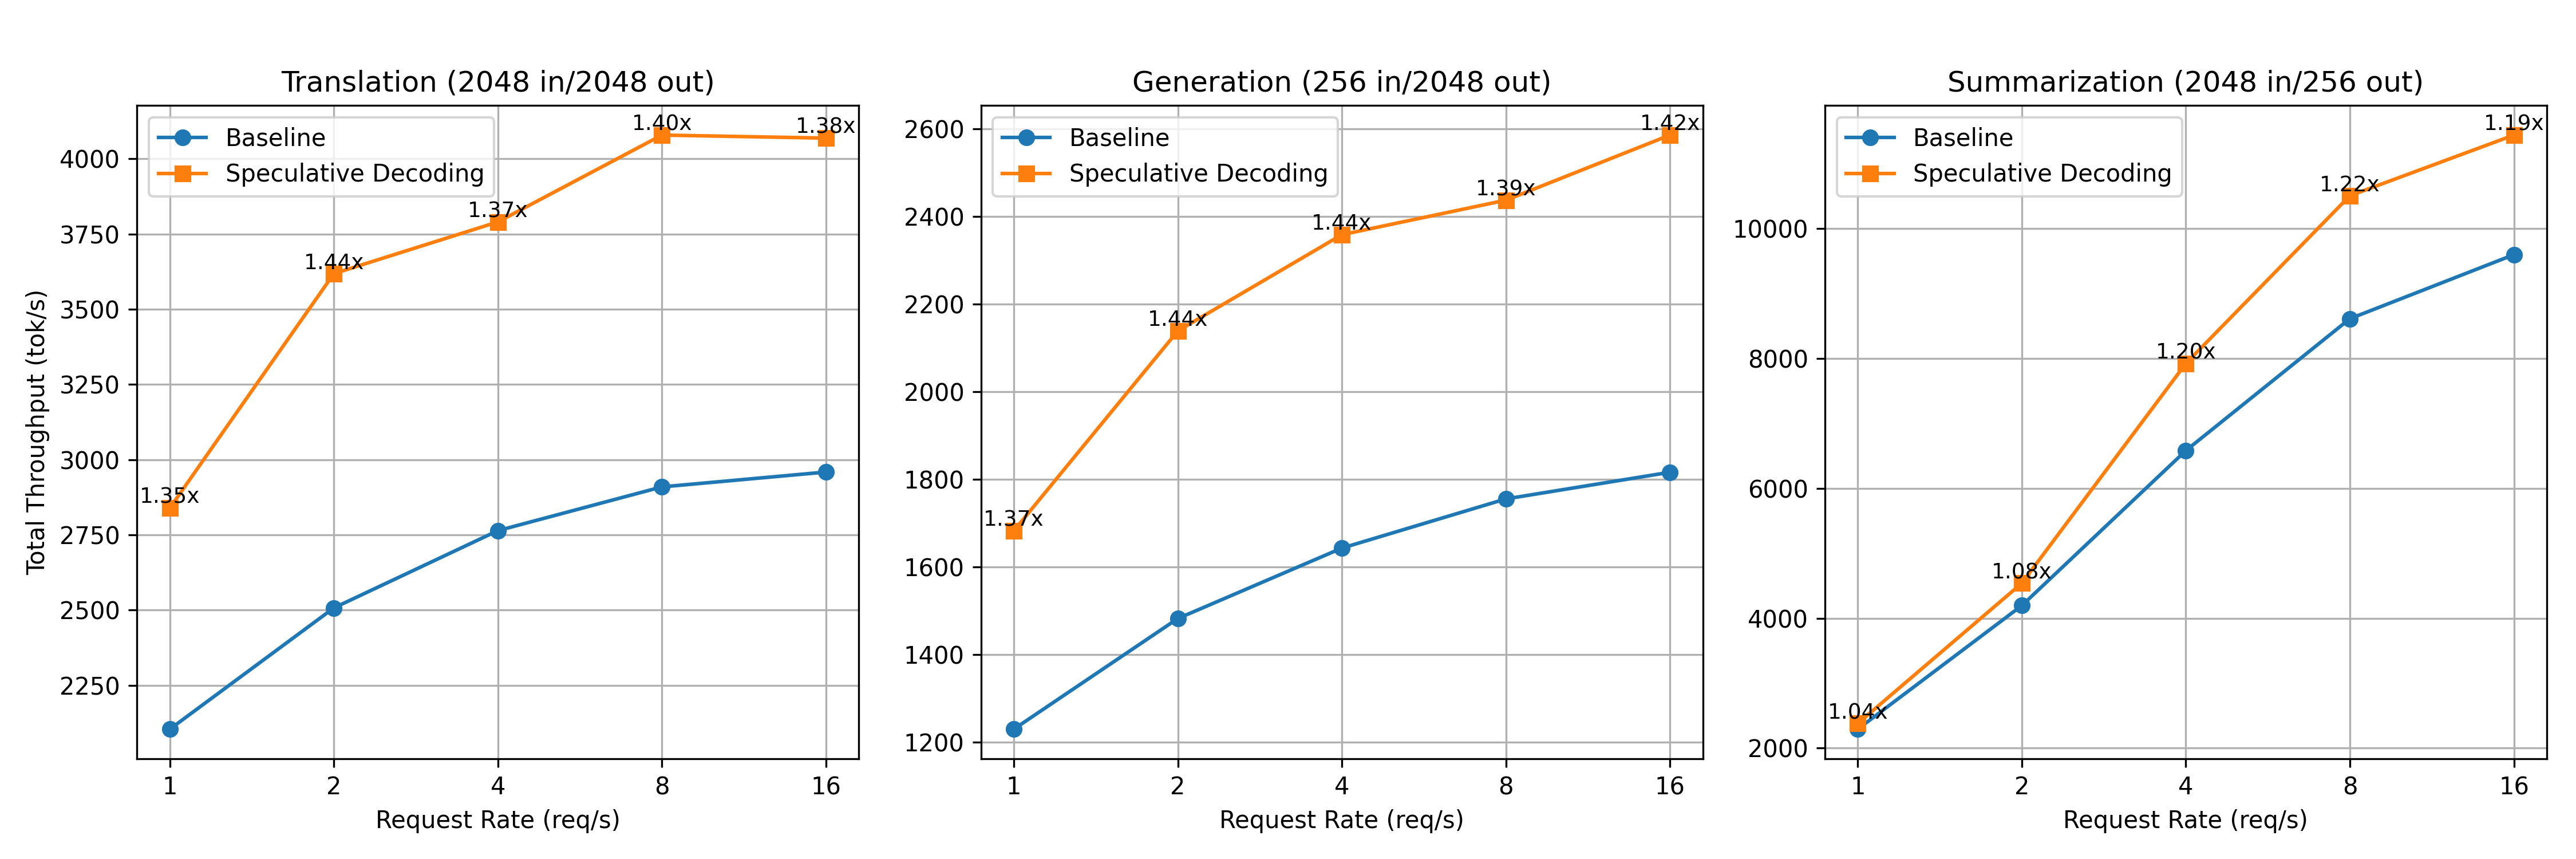
SGLang Speculative Decoding Tutorial: How to Deploy DeepSeek Models and ...
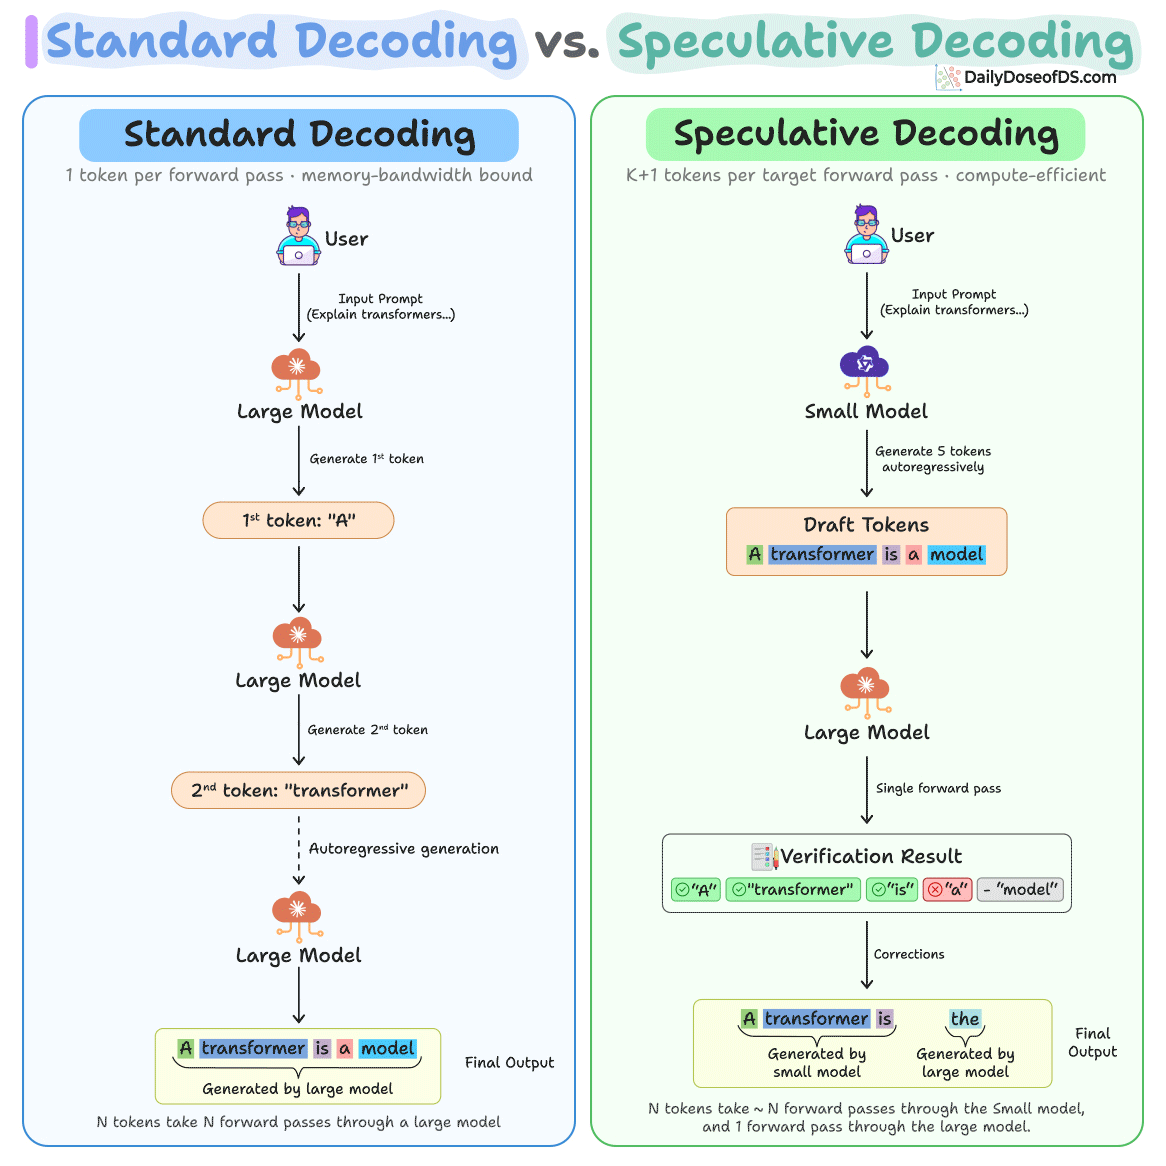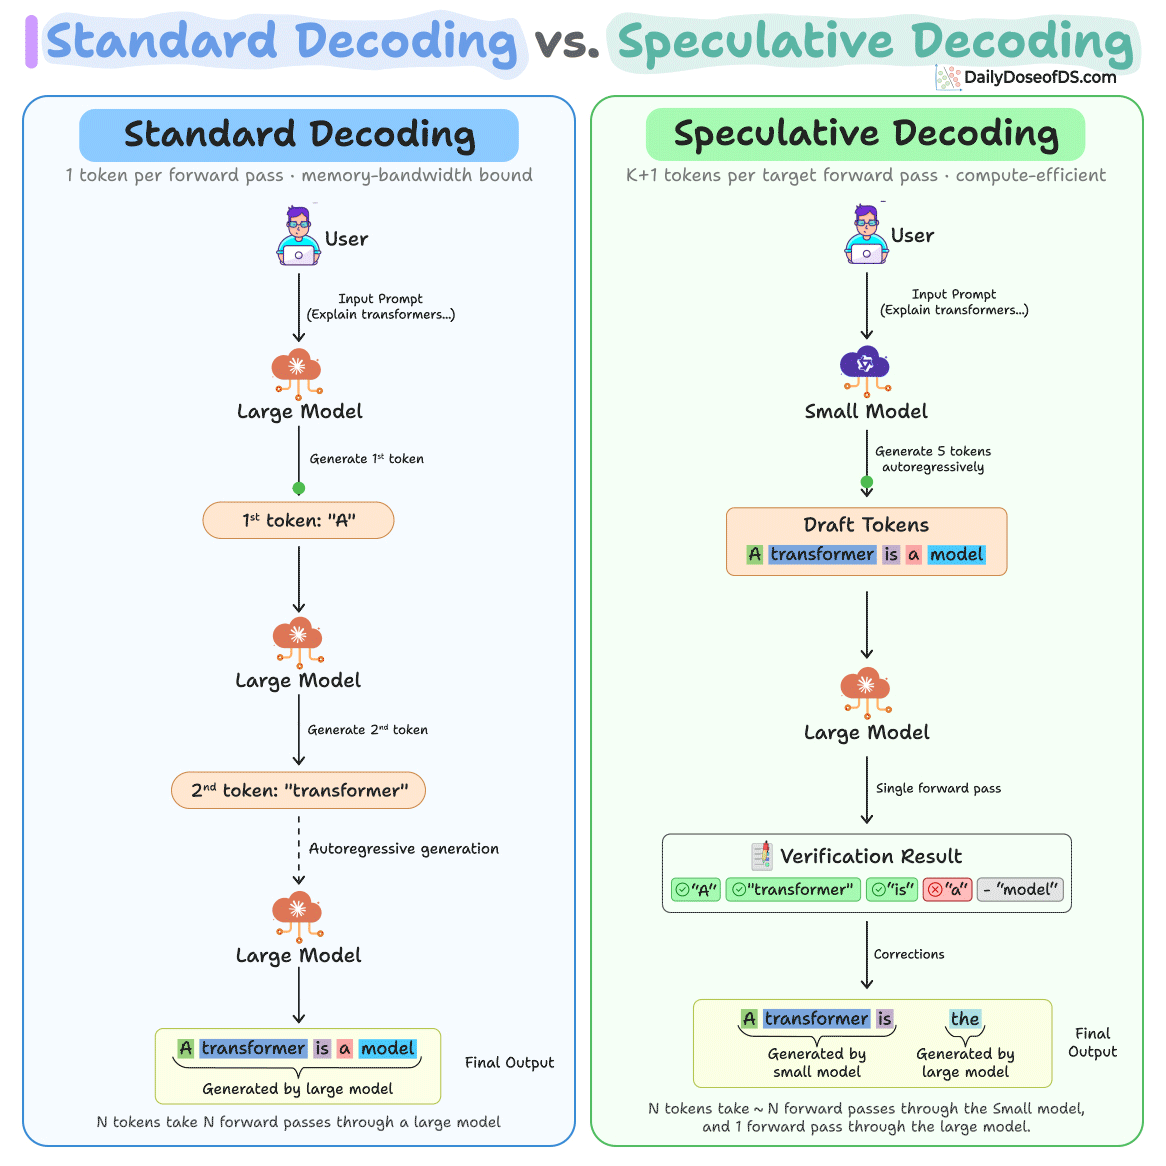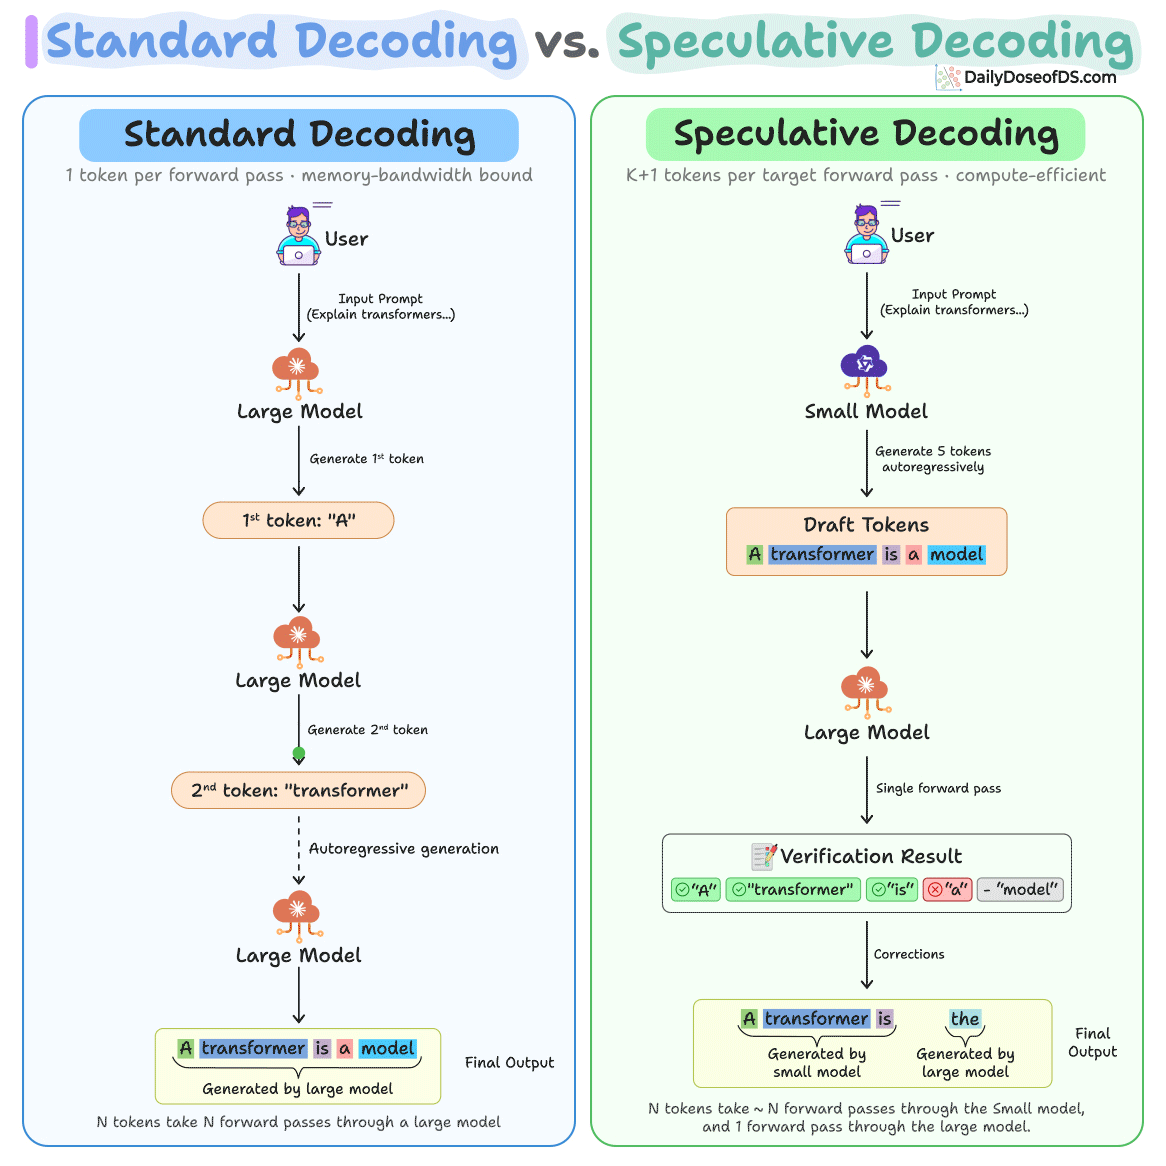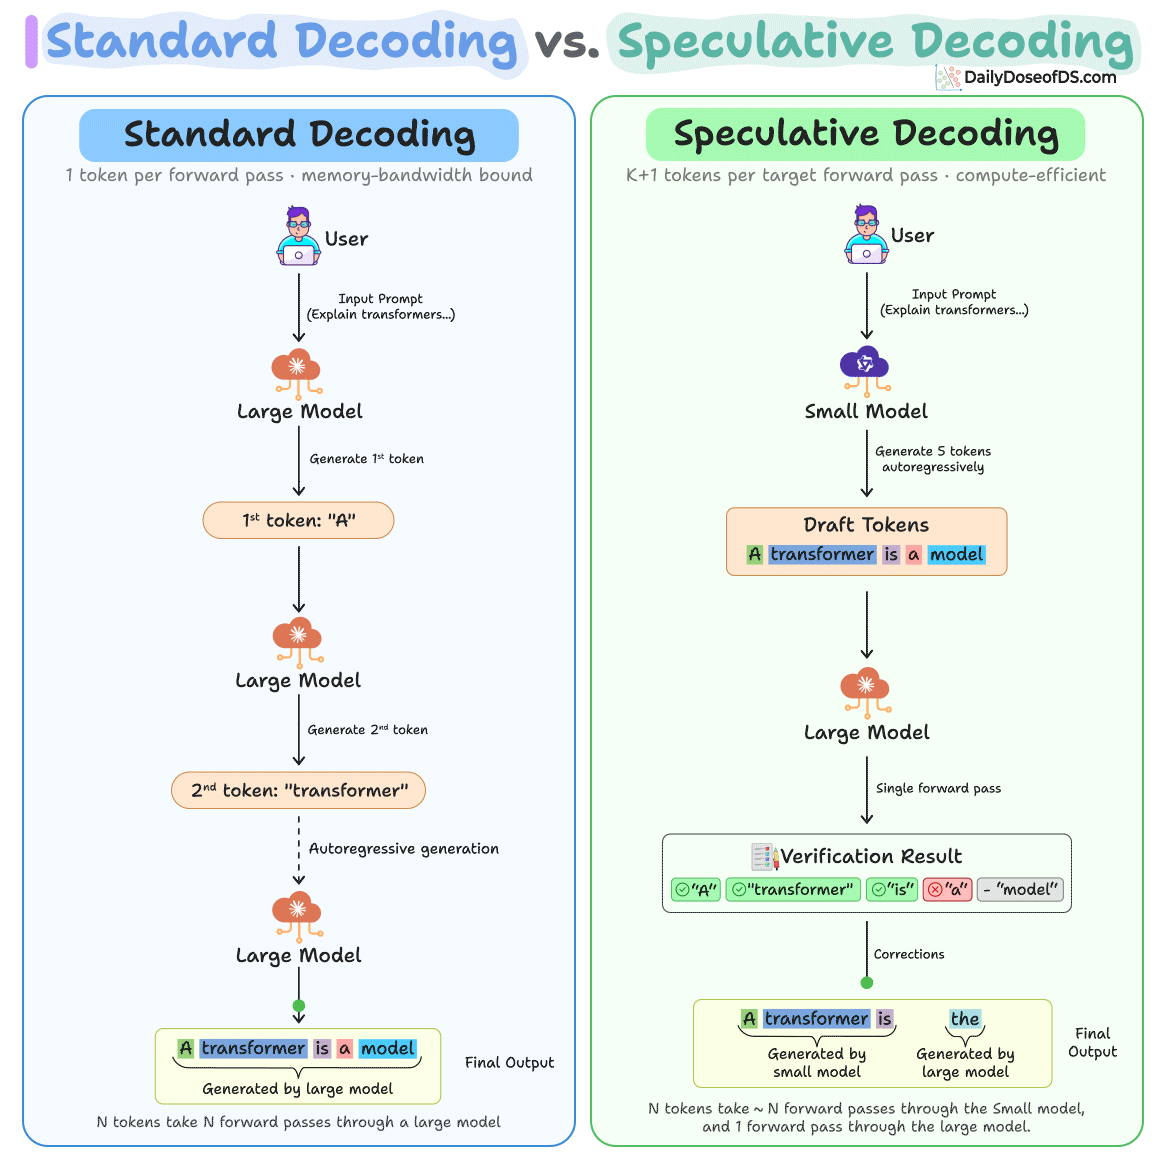
Speculative Decoding in LLMs
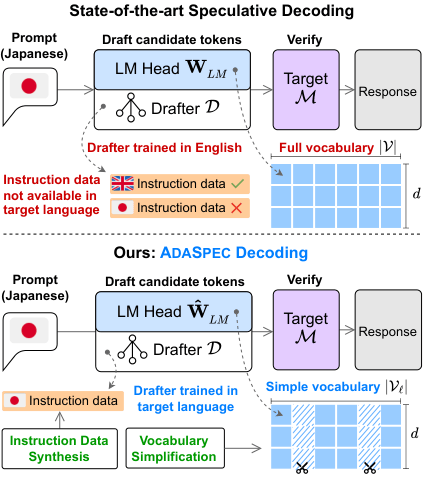
Nguyen Lab's Speculative Decoding Research Group

HiSpec: Hierarchical Speculative Decoding for LLMs
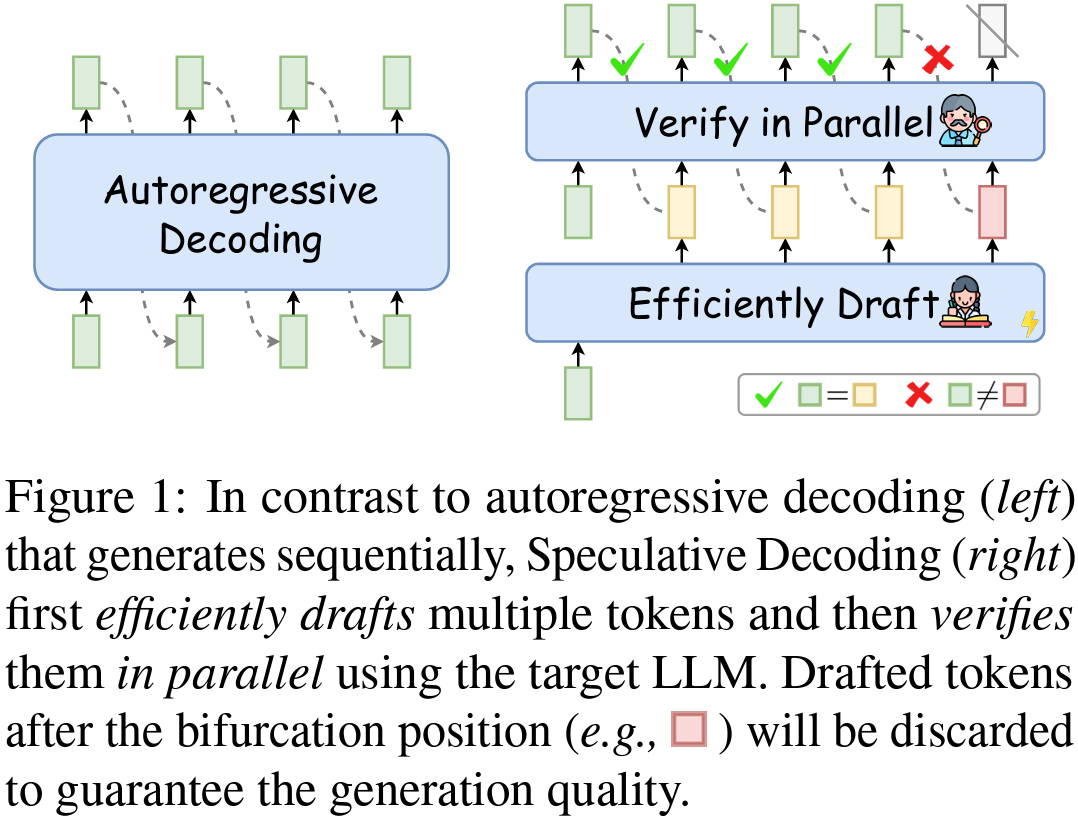
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
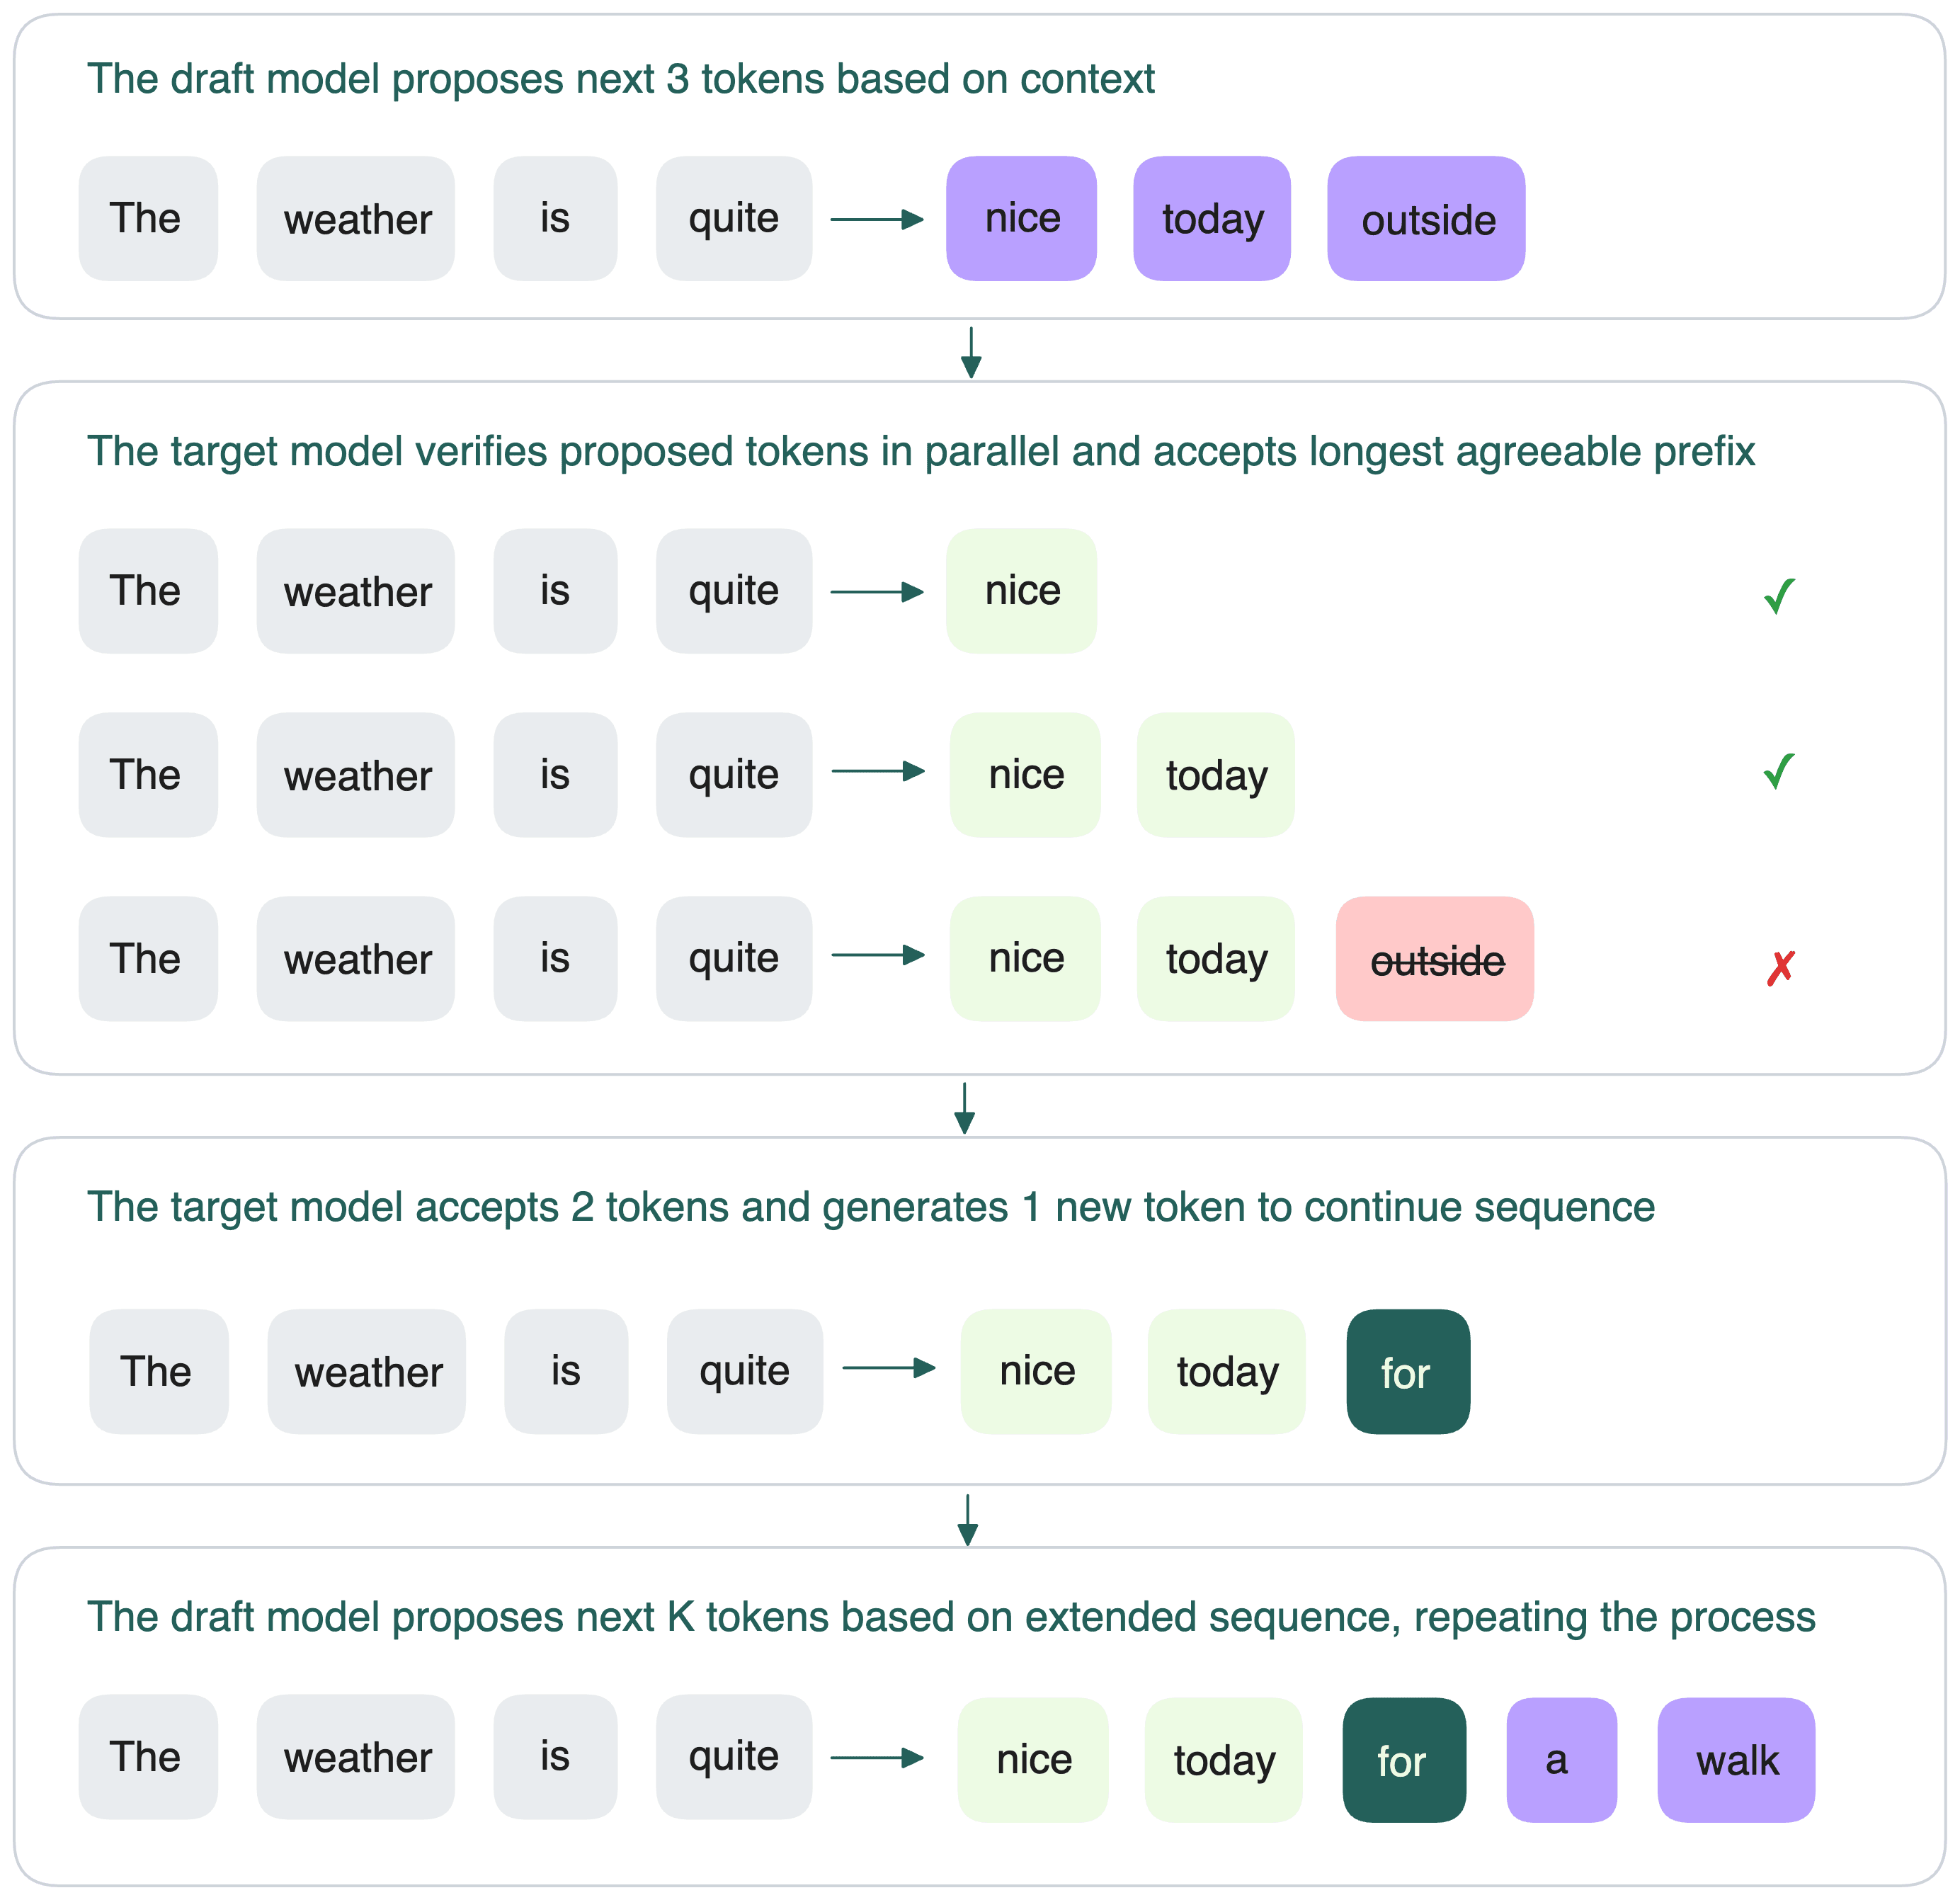
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Speculative Decoding Explained: Faster Inference Without Quality Loss
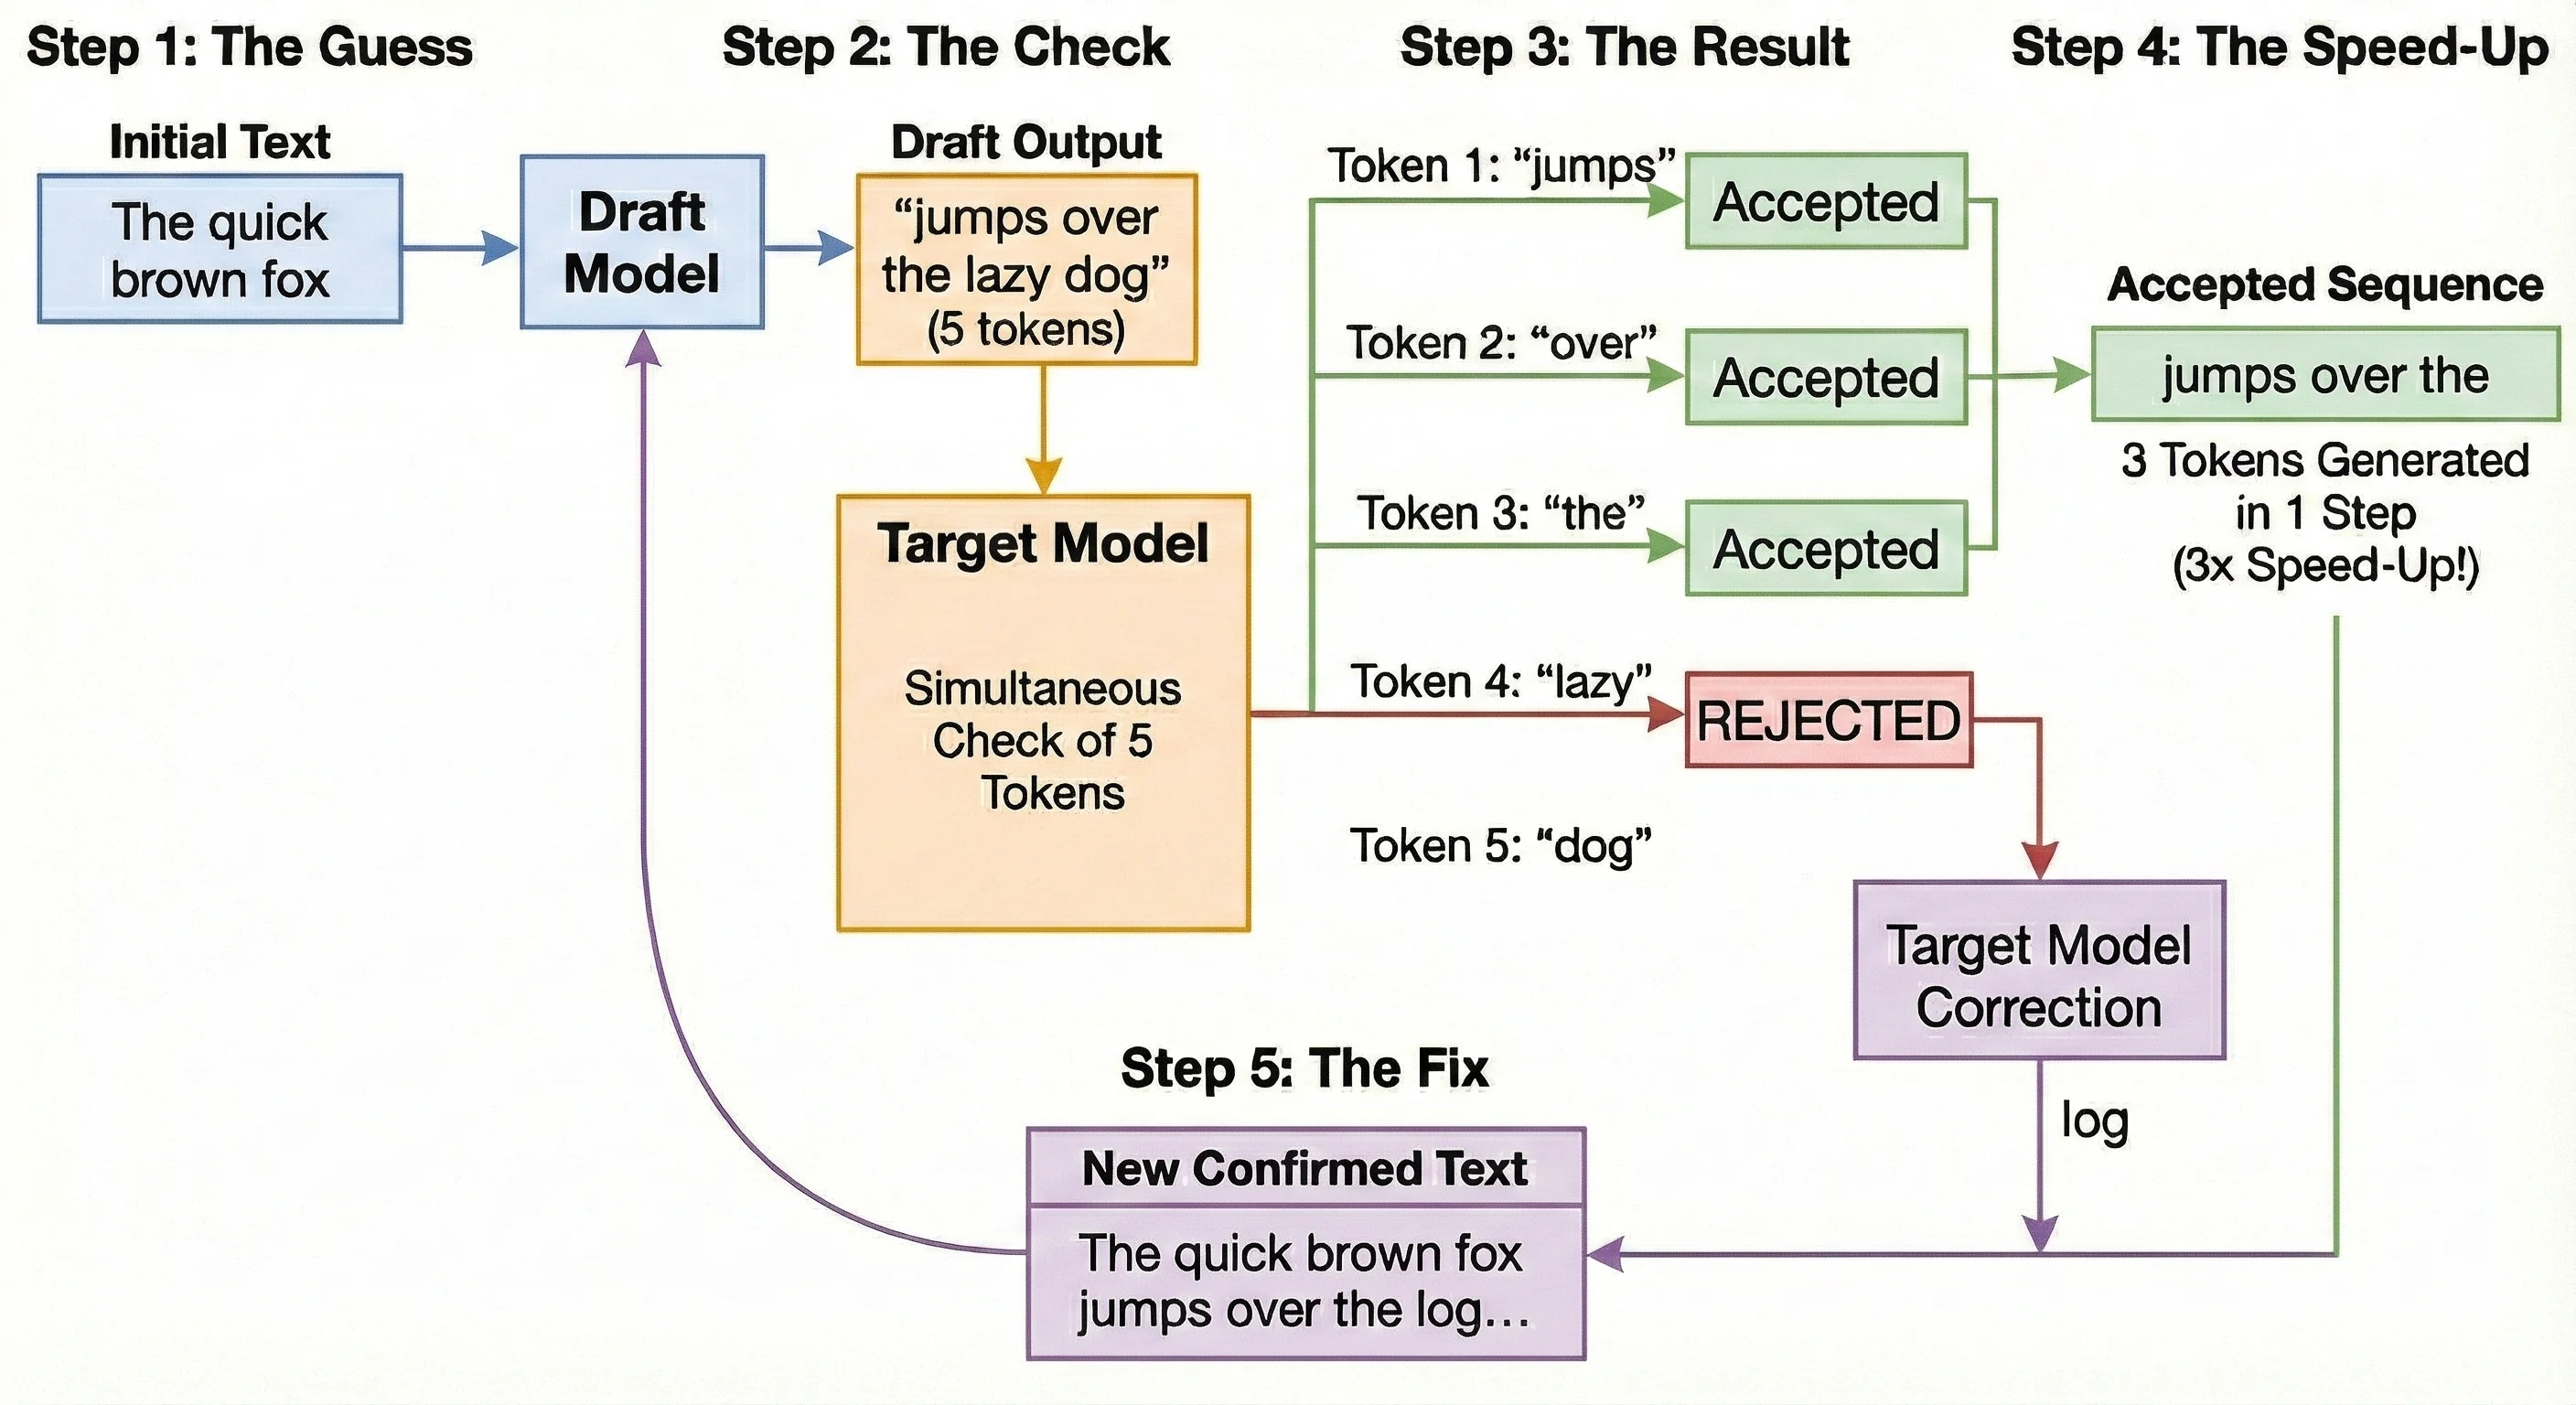
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)

Speculative Decoding - Making Language Models Generate Faster Without ...
Speculative Decoding - Infocusp

Figure 1 from Speculative Speculative Decoding | Semantic Scholar

Speculative decoding: when and why it actually speeds up inference ...

Parallel Prefix Verification for Speculative Generation
Speculative Speculative Decoding Achieves 2x Speedup Over Standard ...