
Support Model Reload Mode Issue 847 Lm Sysfastchat Github
Support model reload mode · Issue #847 · lm-sys/FastChat · GitHub
LoRA support for ModelWorker · Issue #2685 · lm-sys/FastChat · GitHub
stream mode error · Issue #3299 · lm-sys/FastChat · GitHub
How do I load the bge model and start the service? · Issue #2439 · lm ...
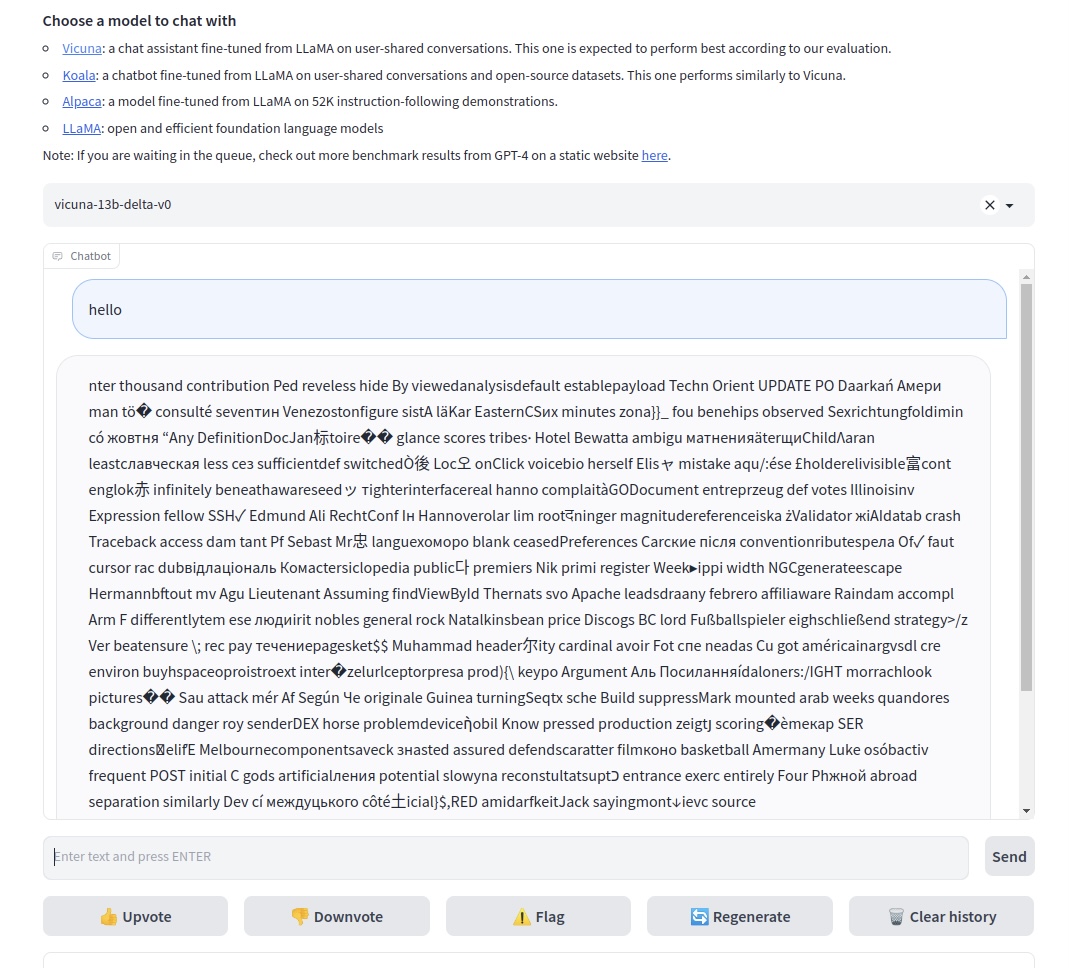
8bit Model output garbled · Issue #285 · lm-sys/FastChat · GitHub
Langchain Support · Issue #95 · lm-sys/FastChat · GitHub
Can support the new model about Llama3 · Issue #3263 · lm-sys/FastChat ...
Llama-2-7b-hf model loading · Issue #2005 · lm-sys/FastChat · GitHub
Unable to use --gpus to load model onto specific GPU · Issue #2360 · lm ...
What's model deluxe-chat-v1 ? · Issue #2527 · lm-sys/FastChat · GitHub
Advertisement Space (300x250)
support finetune on Qwen14B · Issue #2476 · lm-sys/FastChat · GitHub
the model always repeat some words · Issue #1878 · lm-sys/FastChat · GitHub
The output of the model is weird · Issue #446 · lm-sys/FastChat · GitHub
Add support for MPT-7B. · Issue #983 · lm-sys/FastChat · GitHub
inference about lora model · Issue #2787 · lm-sys/FastChat · GitHub
1.8.9 support · Issue #847 · SkriptLang/Skript · GitHub
Does it support batch inference? · Issue #2327 · lm-sys/FastChat · GitHub
Can you support the 4-bit loading model? · Issue #2764 · lm-sys ...
This version does not support function_call yet? · Issue #2214 · lm-sys ...
fastchat.serve.model_worker does not support --load-8bit · Issue #2572 ...
Advertisement Space (336x280)
Implement GLM-4 models · Issue #3395 · lm-sys/FastChat · GitHub
chatglm3-6b run fastchat.serve.vllm_worker no output · Issue #2782 · lm ...
How to specify which GPU to run the model in background mode on ...
Loss reaches 0 when finetuning 7B model using 2xA100 80G · Issue #1948 ...
Version 0.2.22 support model vicuna-13b-v1.5-16k, but why are Max ...
Unable to save the mode weights - GPU OOM · Issue #256 · lm-sys ...
safe_save_model_for_hf_trainer function save mode is very small · Issue ...
Error : model.embed_tokens.weight · Issue #854 · lm-sys/FastChat · GitHub
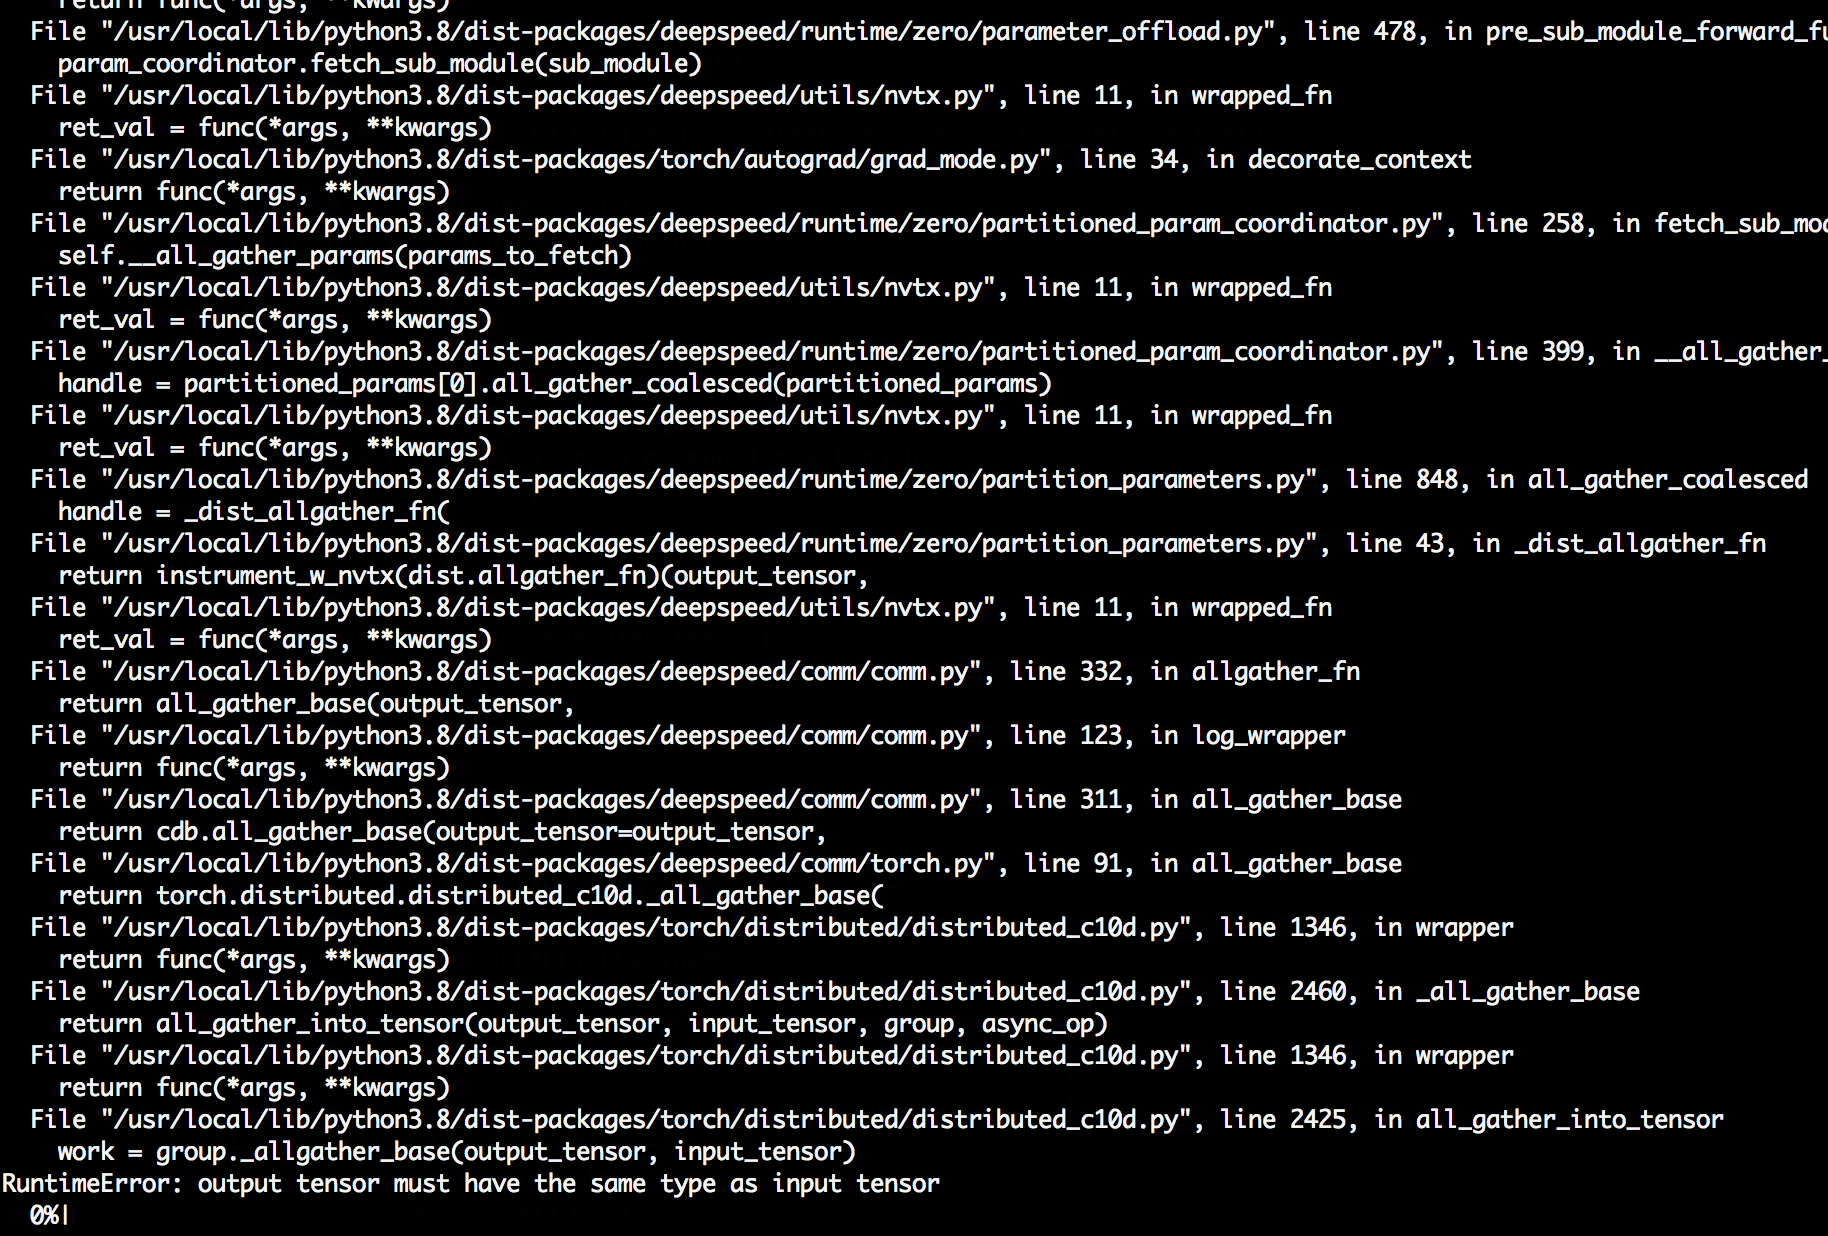
Issue · GitHub

Error when saving the model after training · Issue #841 · lm-sys ...
Advertisement Space (336x280)
load new models to fastchat · Issue #2610 · lm-sys/FastChat · GitHub
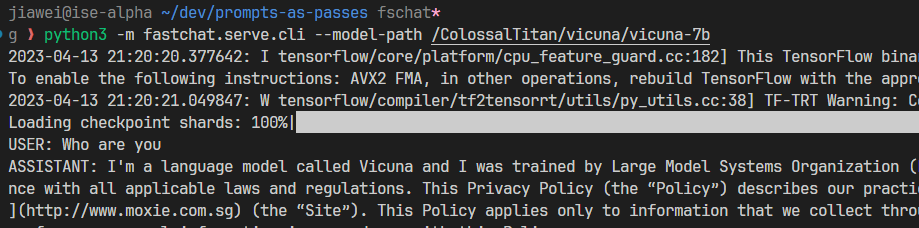
Multi-gpu demo failed on two A6000 · Issue #418 · lm-sys/FastChat · GitHub
ChatGLM-PTuning +Fastchat · Issue #1165 · lm-sys/FastChat · GitHub
Can't load model Qwen-14B-Chat-Int4 · Issue #2486 · lm-sys/FastChat ...
使用vllm做workloader报错 · Issue #2179 · lm-sys/FastChat · GitHub

improve readme file readability · Issue #118 · lm-sys/FastChat · GitHub