
Table 1 From Cross Modal Collaborative Representation Learning For Text
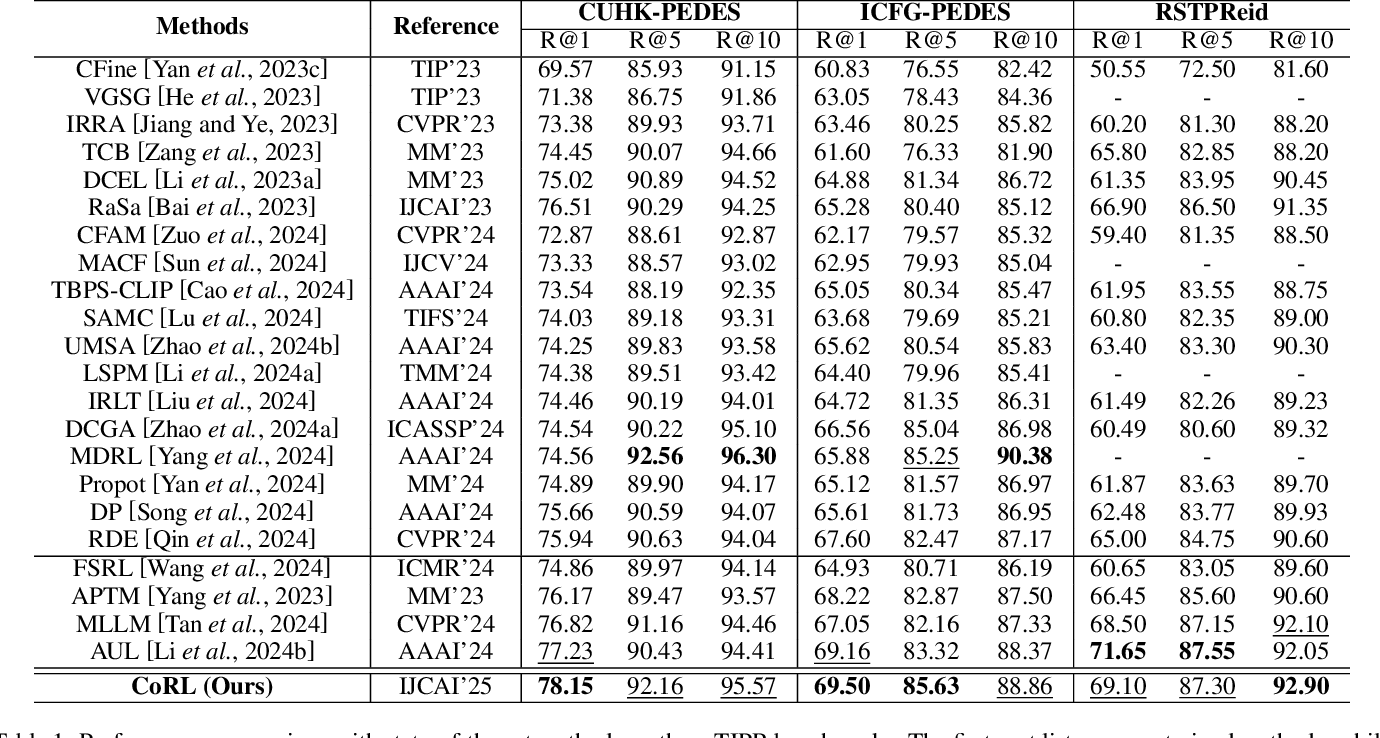
Table 1 from Cross-modal Collaborative Representation Learning for Text ...
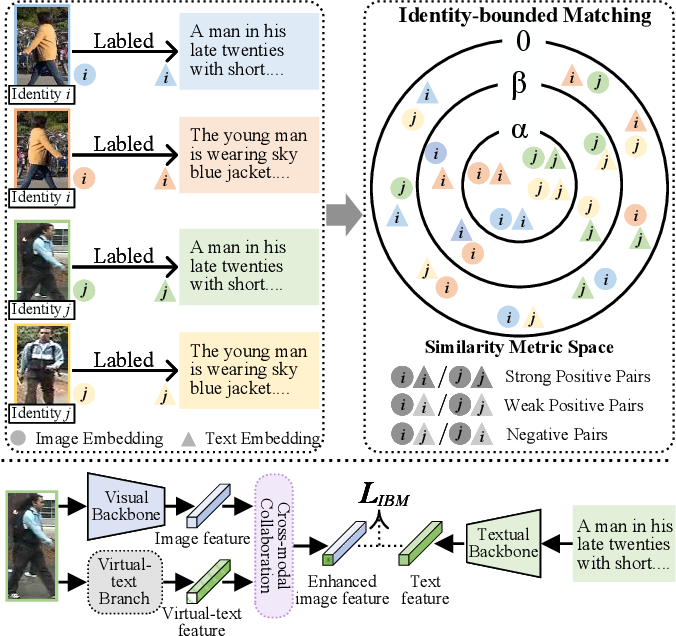
Figure 1 from Cross-modal Collaborative Representation Learning for ...
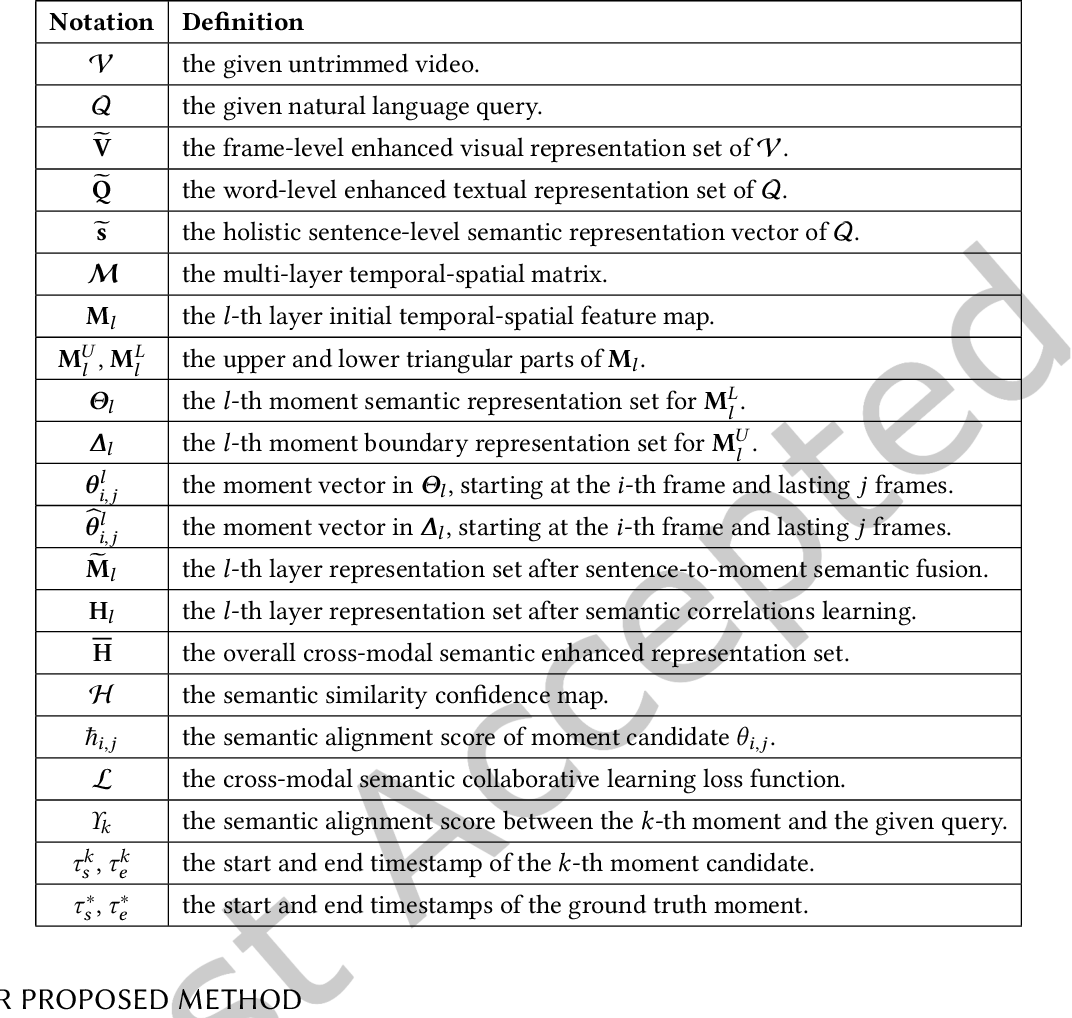
Table 1 from Semantic Collaborative Learning for Cross-Modal Moment ...
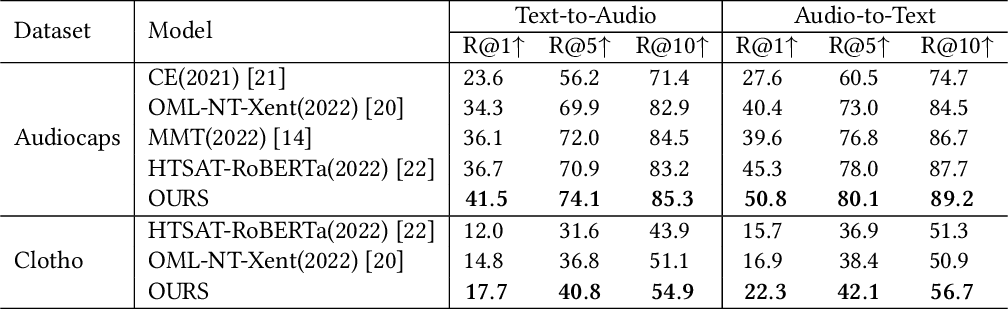
Table 1 from Multi-grained Representation Learning for Cross-modal ...
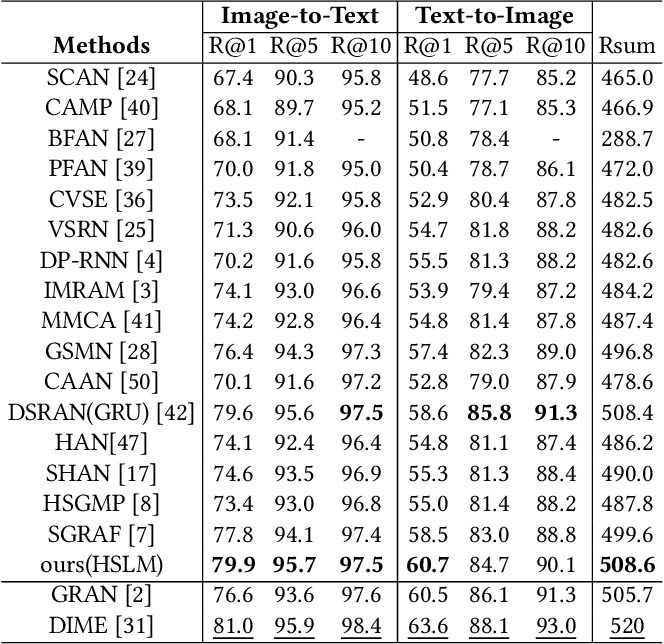
Table 1 from Learning Hierarchical Semantic Correspondences for Cross ...
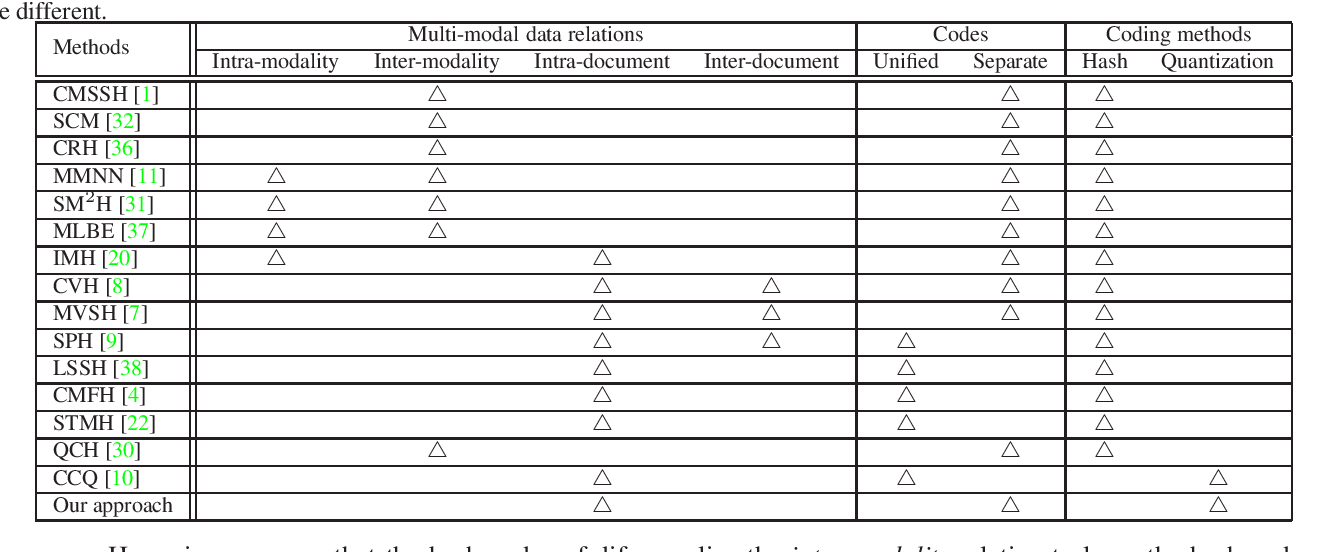
Table 1 from Collaborative Quantization for Cross-Modal Similarity ...
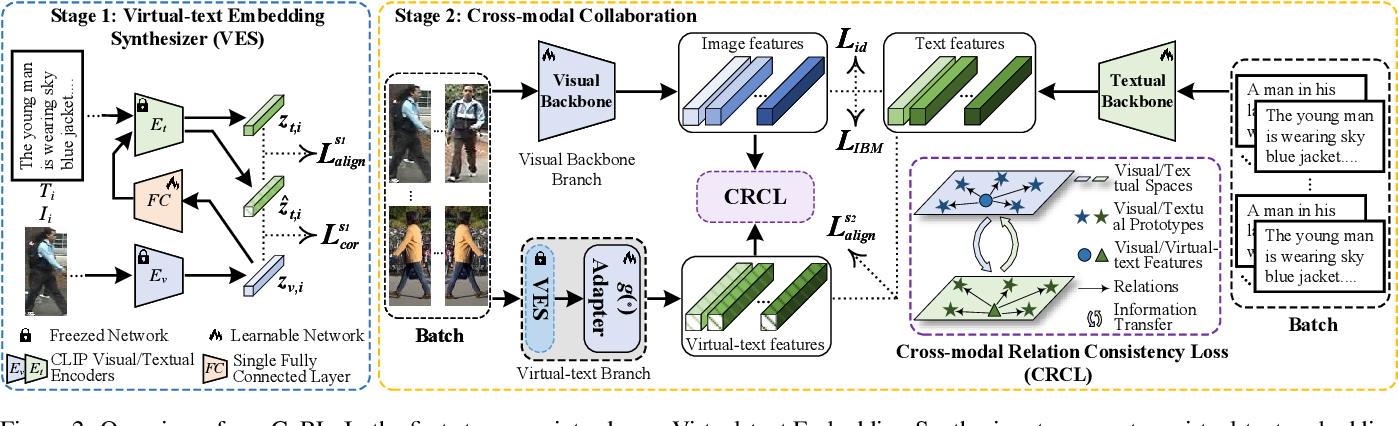
Figure 2 from Cross-modal Collaborative Representation Learning for ...

Table 2 from Multi-modal Contrastive Representation Learning for Entity ...
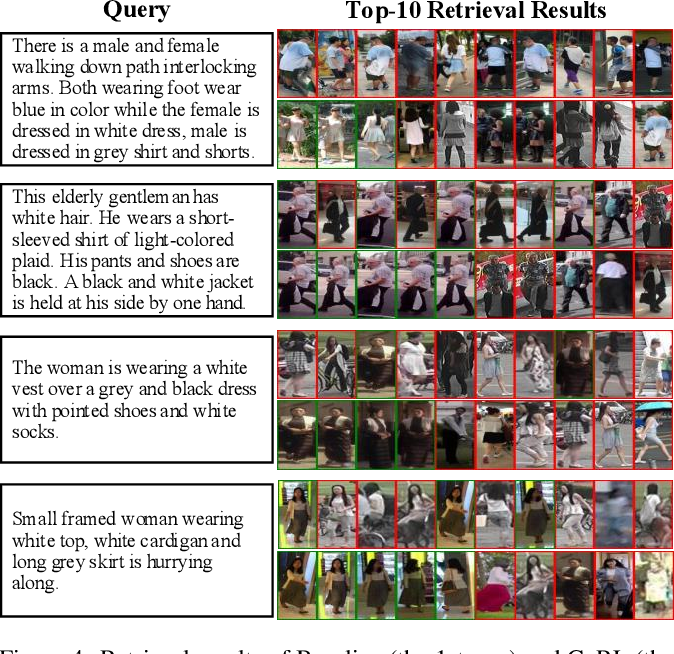
Figure 4 from Cross-modal Collaborative Representation Learning for ...
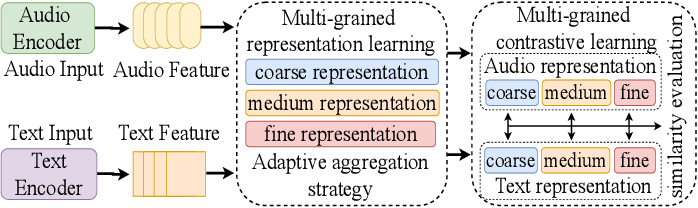
Figure 1 from Multi-grained Representation Learning for Cross-modal ...
Advertisement Space (300x250)

Table 1 from On Metric Learning for Audio-Text Cross-Modal Retrieval ...
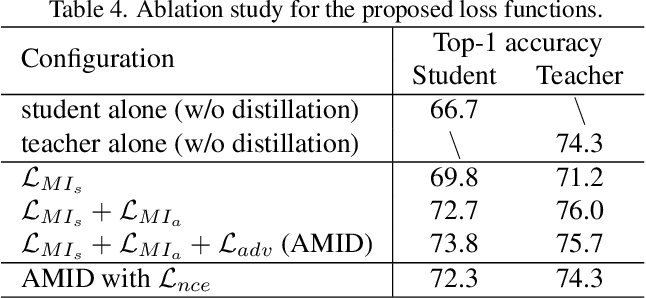
Table 4 from Enhanced Multimodal Representation Learning with Cross ...
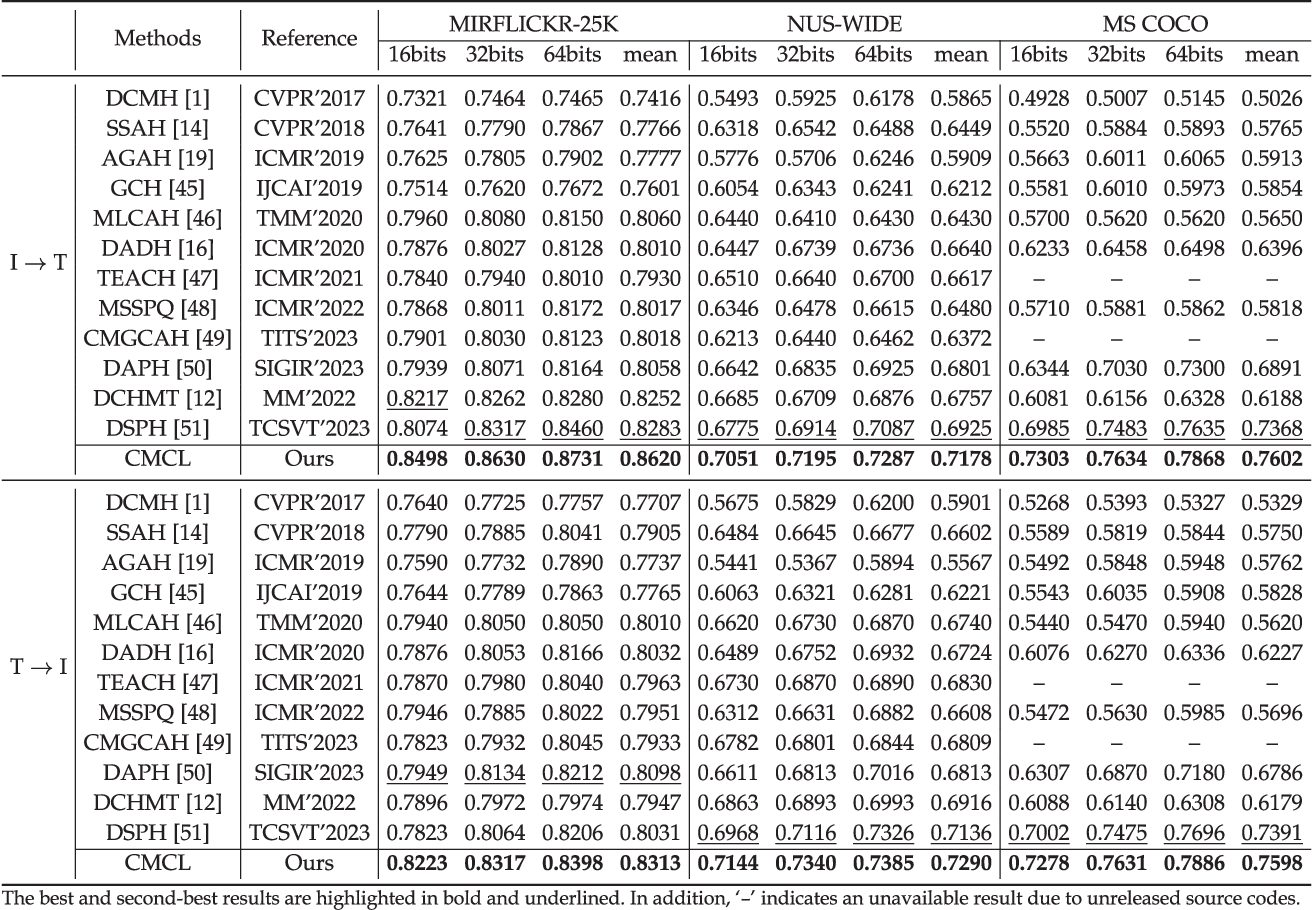
Table II from Contrastive Multi-Bit Collaborative Learning for Deep ...

Y2Seq2Seq: Cross-Modal Representation Learning for 3D Shape and Text by ...

Y2Seq2Seq: Cross-Modal Representation Learning for 3D Shape and Text by ...

Y2Seq2Seq: Cross-Modal Representation Learning for 3D Shape and Text by ...

Y2Seq2Seq: Cross-Modal Representation Learning for 3D Shape and Text by ...
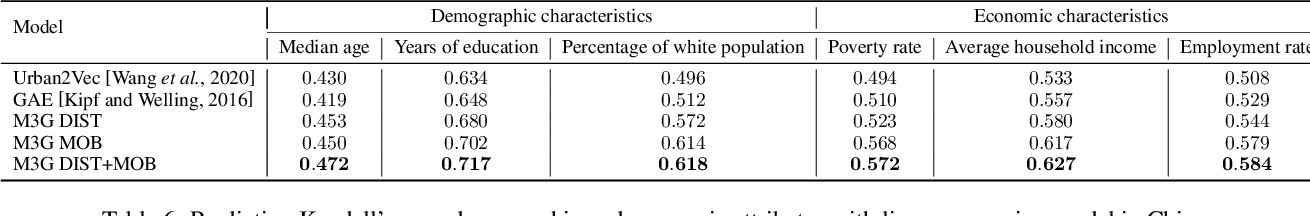
Table 6 from Learning Neighborhood Representation from Multi-Modal ...
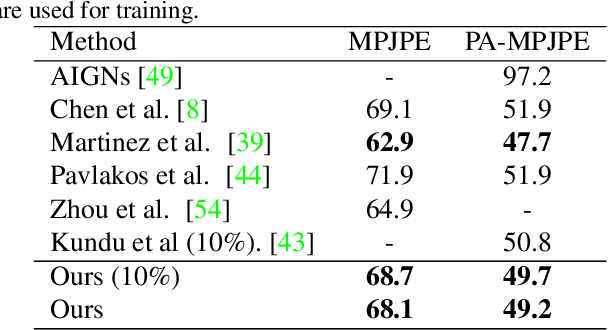
Table 1 from Semi-Supervised Learning of Disentangled Representations ...
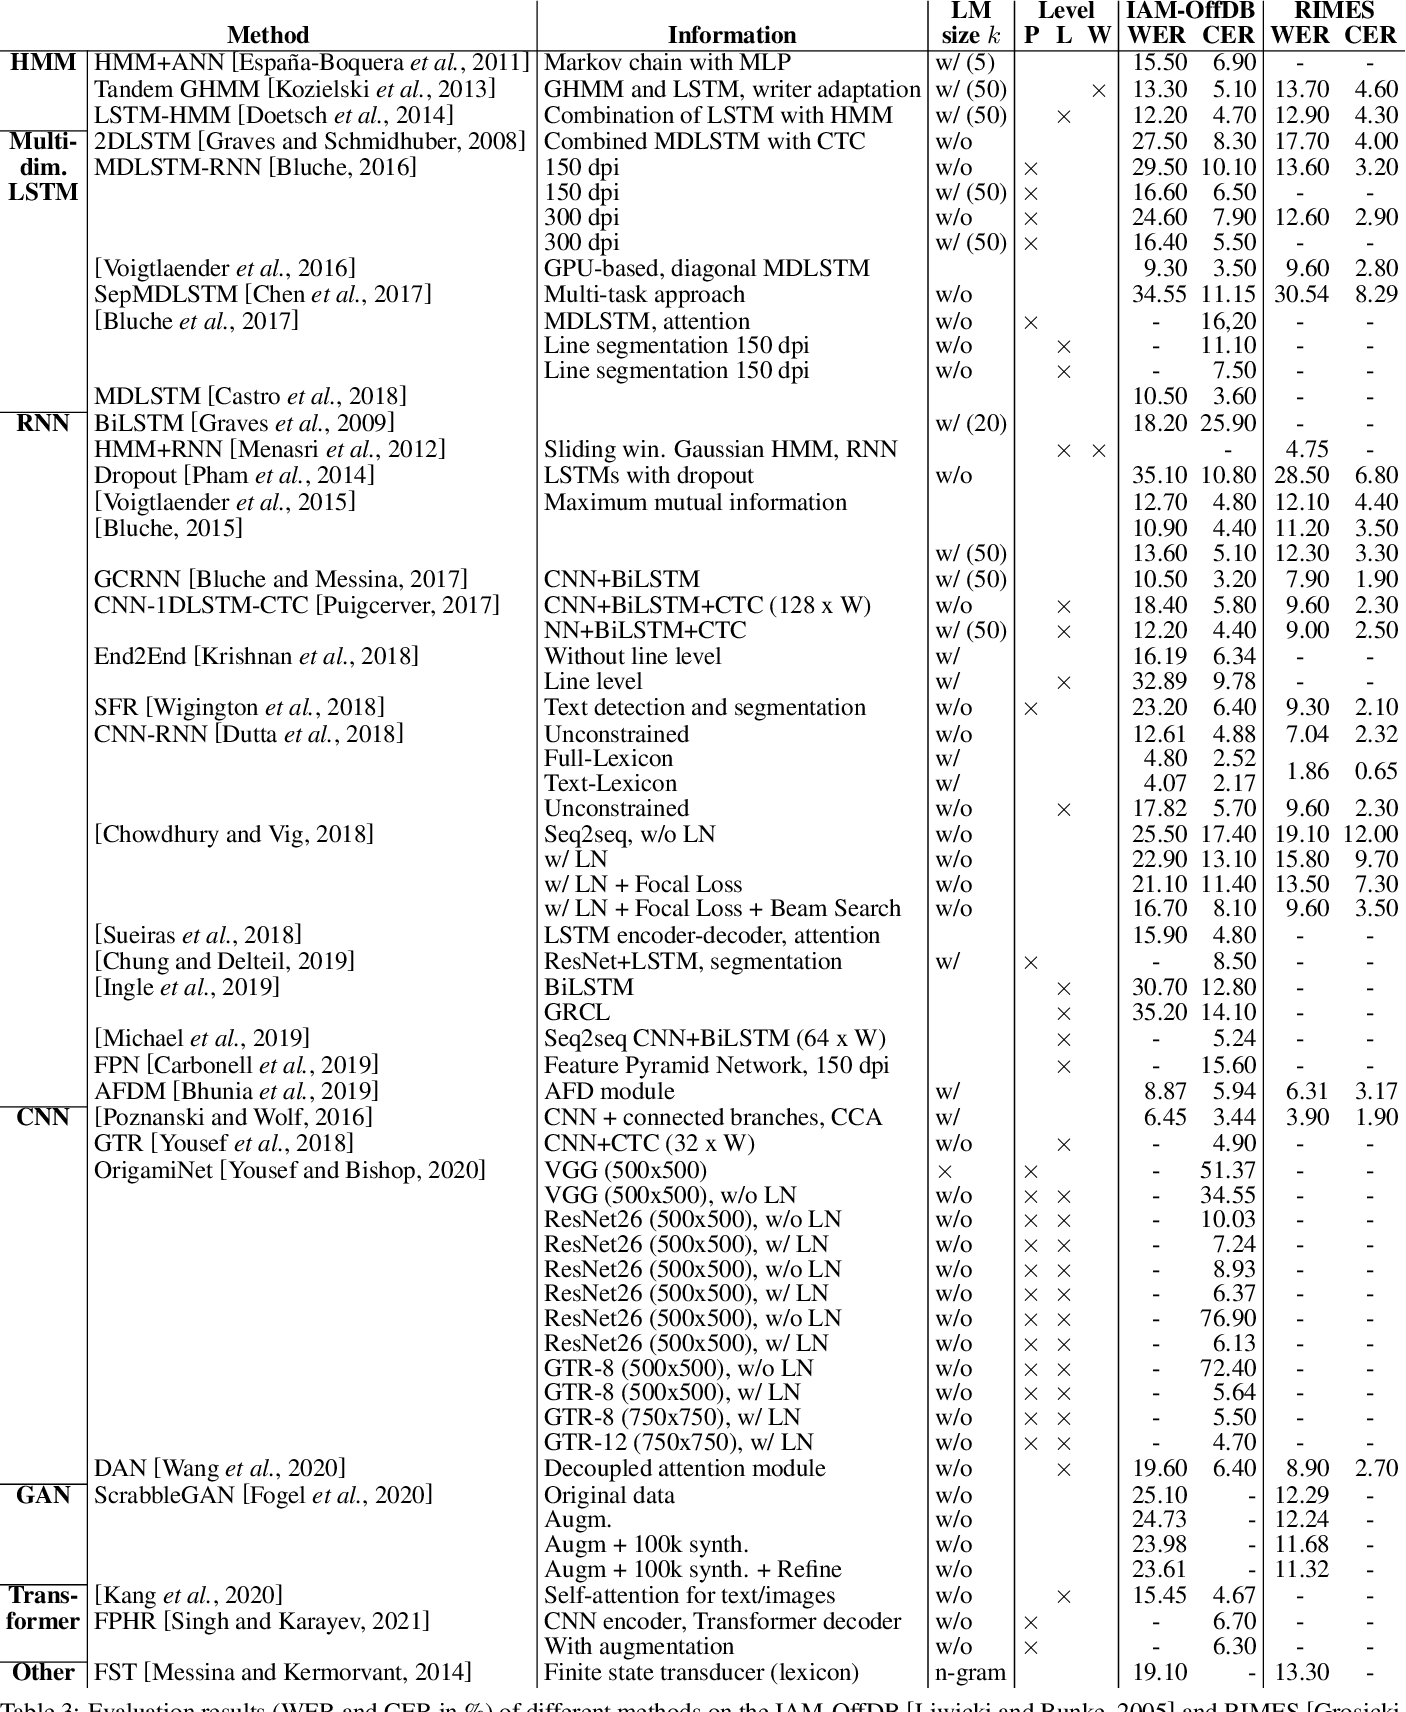
Table 3 from Cross-Modal Common Representation Learning with Triplet ...
Advertisement Space (336x280)
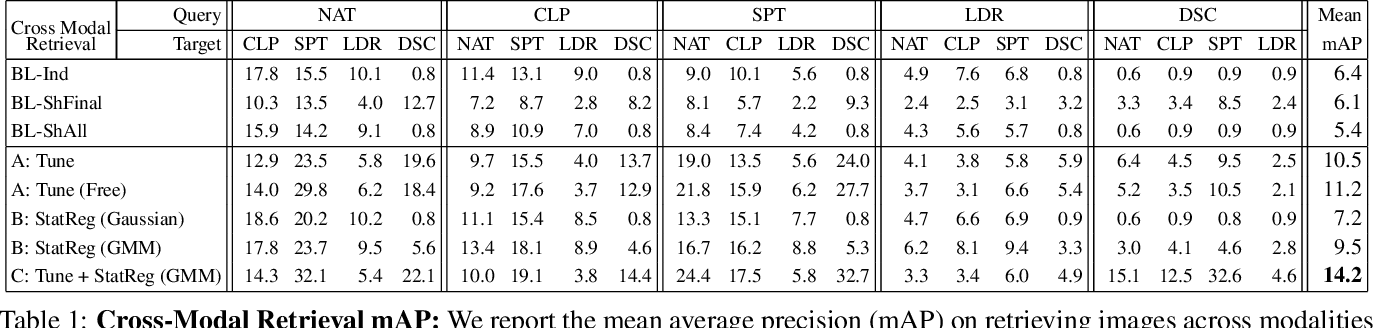
Table 1 from Learning Aligned Cross-Modal Representations from Weakly ...

(PDF) Effective Collaborative Representation Learning for Multilabel ...
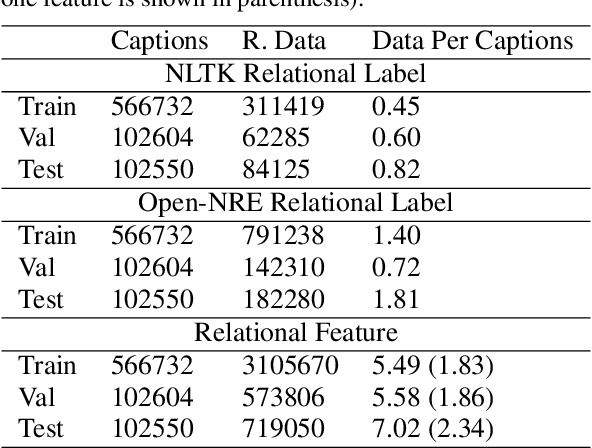
Table 1 from Learning Cross-modal Representations with Multi-relations ...

Table 2 from Cross-Modal Common Representation Learning with Triplet ...

Figure 1 from Inter-Intra Modal Representation Augmentation With ...

Figure 1 from Leveraging Cross-Modal Neighbor Representation for ...
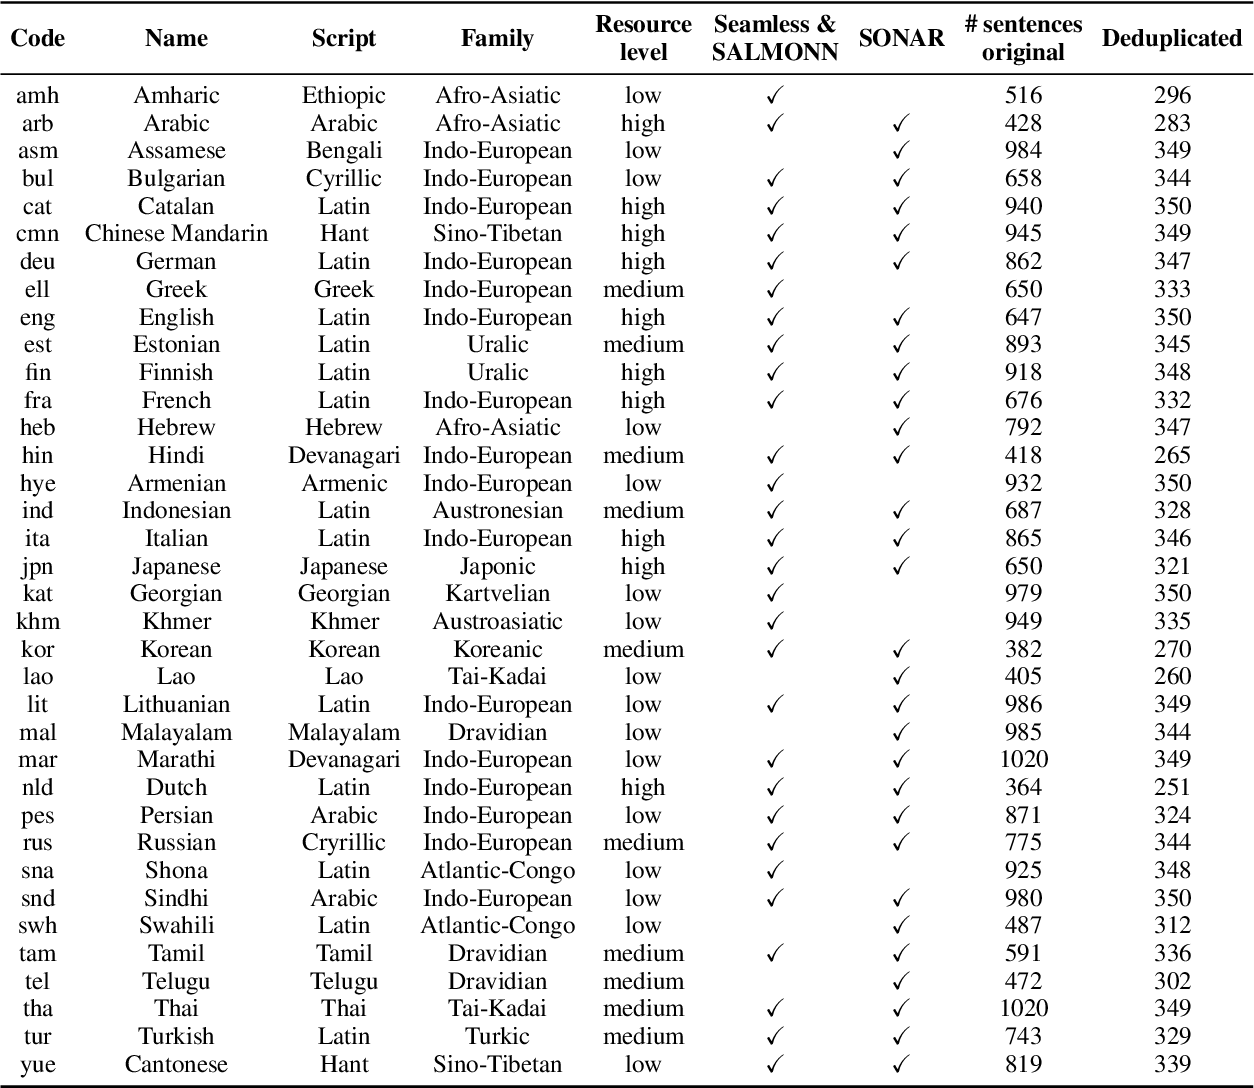
Table 1 from How do Multimodal Foundation Models Encode Text and Speech ...

Figure 1 from Cross-modal Shared Concept Learning for Text-to-Image ...

Table 1 from Multi-Granularity Cross-modal Alignment for Generalized ...

Paper page - Cross-Modal Collaborative Representation Learning and a ...
Advertisement Space (336x280)

Figure 1 from Multimodal Federated Learning via Contrastive ...
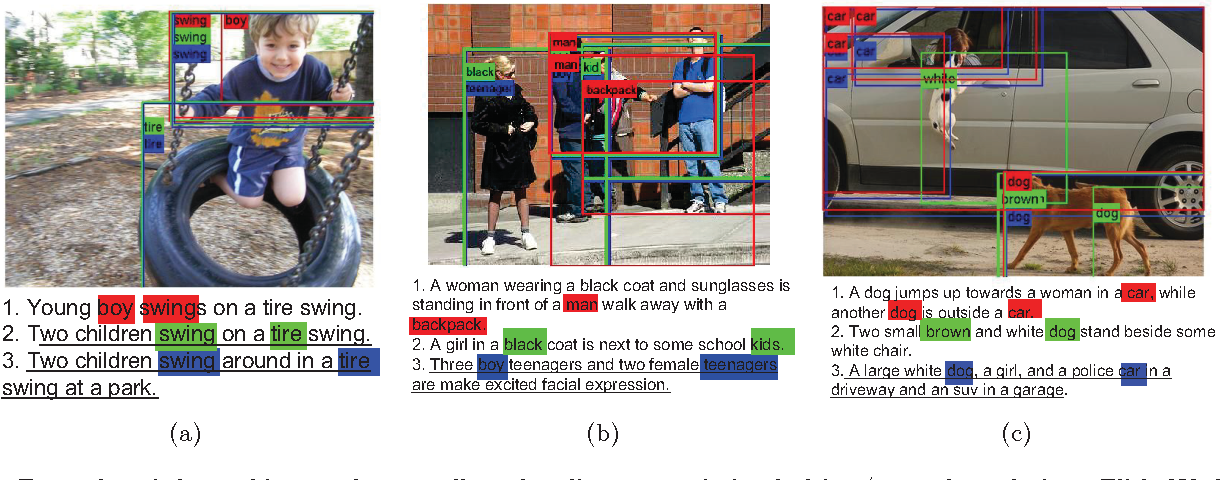
Figure 1 from Deep Compositional Cross-modal Learning to Rank via Local ...

(PDF) Cross-Modal Collaborative Representation Learning and a Large ...

Collaborative Distributed Representation Learning (CDRL). | Download ...

Cross-Modal Collaborative Representation Learning and a Large-Scale ...

(PDF) CMC2R: Cross‐modal collaborative contextual representation for ...