
Table 1 From Generation Based Target Speech Extraction With Speech

Table 1 from Generation-Based Target Speech Extraction with Speech ...

Table 1 from Generation-Based Target Speech Extraction with Speech ...
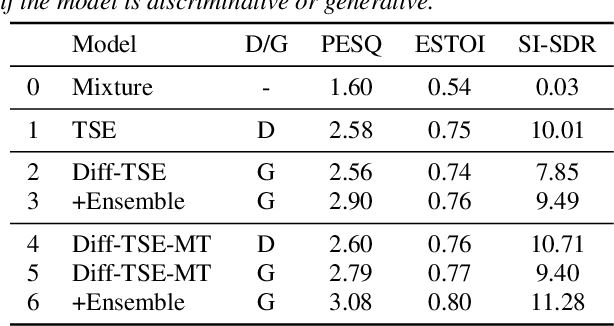
Table 1 from Target Speech Extraction with Conditional Diffusion Model ...
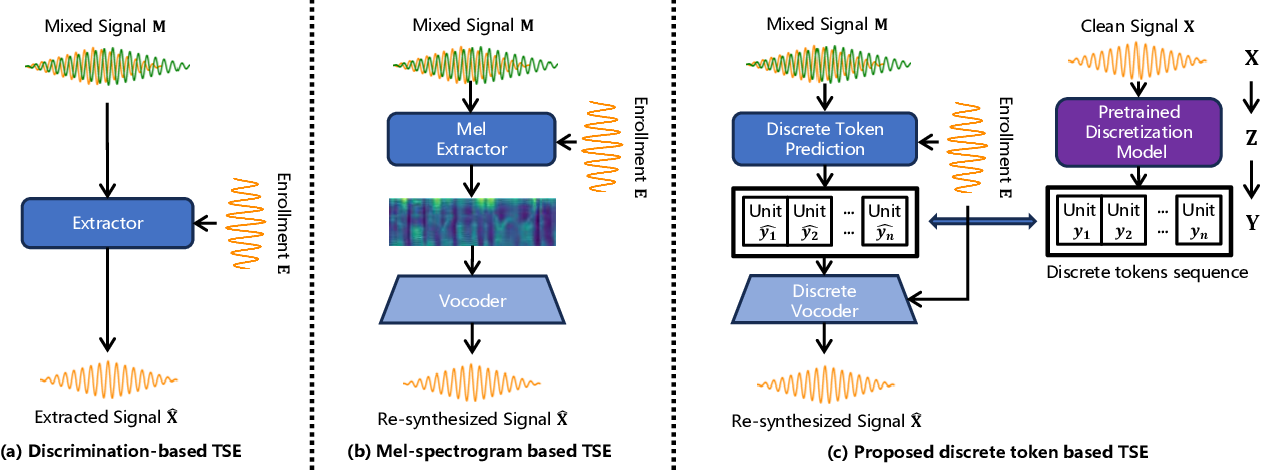
Figure 1 from Generation-Based Target Speech Extraction with Speech ...
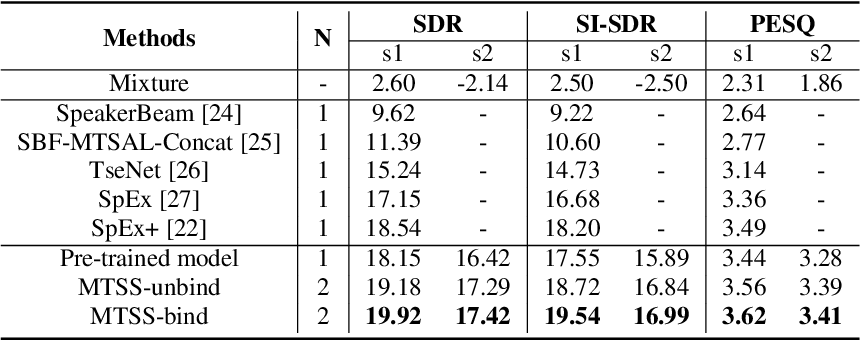
Table 1 from Simultaneous Speech Extraction for Multiple Target ...

Figure 1 from A Multimodal Target Speech Extraction Algorithm Based on ...

Table 1 from Probing Self-Supervised Learning Models With Target Speech ...

Figure 1 from Target Speech Extraction with Conditional Diffusion Model ...

Figure 1 from Target Speech Extraction with Conditional Diffusion Model ...
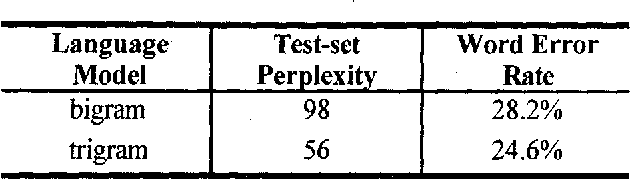
Table 1 from Topic extraction based on continuous speech recognition in ...
Advertisement Space (300x250)
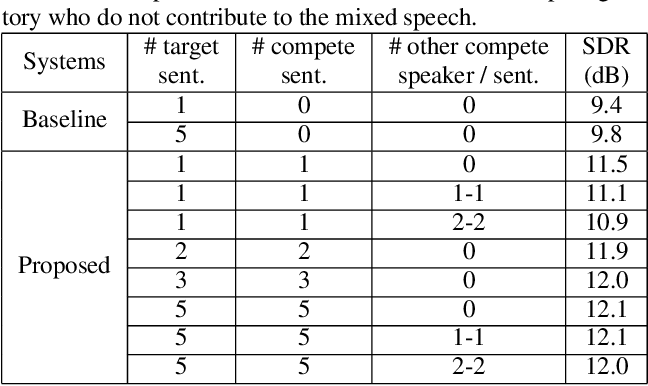
Table 1 from Single-channel Speech Extraction Using Speaker Inventory ...

Table 1 from Feature Extraction Techniques for Speech Processing: A ...

Table 1 from FEATURE EXTRACTION TECHNIQUES IN SPEECH IDENTIFICATION ...

Table 1 from Evaluation of speech signal features extraction methods ...

Table 1 from A Unified Speech Enhancement System Based on Neural ...
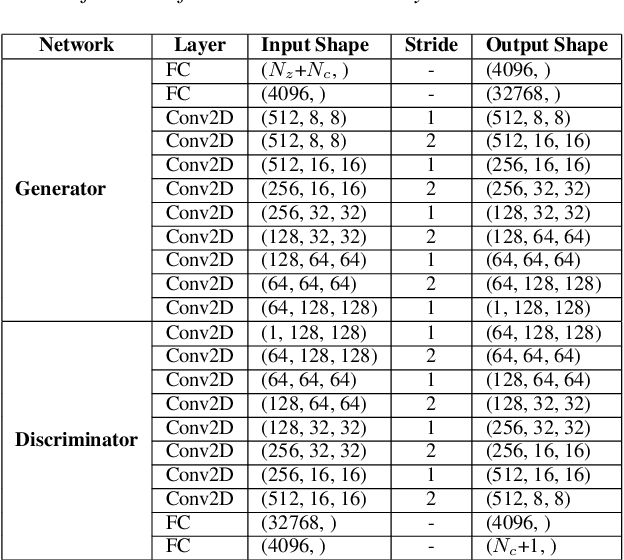
Table 1 from GAN-Based Data Generation for Speech Emotion Recognition ...

Figure 4 from Target Speech Extraction with Conditional Diffusion Model ...

Figure 2 from Target Speech Extraction with Pre-trained AV-HuBERT and ...

Table 1 from Adapting Large Language Model with Speech for Fully ...

Figure 1 from Simultaneous Speech Extraction for Multiple Target ...
Advertisement Space (336x280)
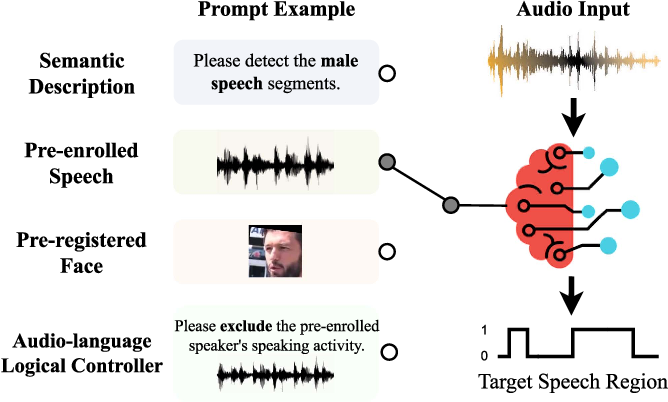
Figure 1 from Target Speech Detection With Multimodal Prompts ...

Table II from Application of Speech Feature Extraction Method Based on ...
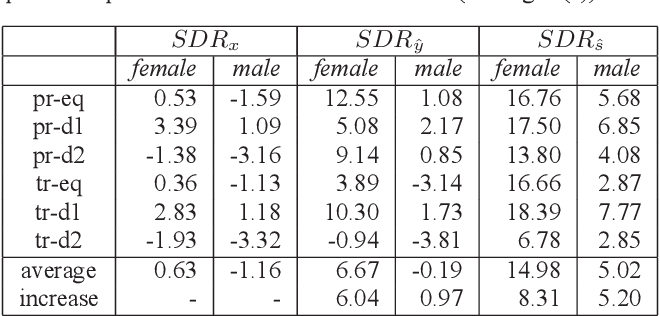
Table 1 from Target speech extractionwith learned spectral bases ...
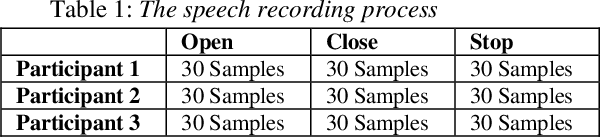
Table 1 from A Speech to Machine Interface Based on Perceptual Linear ...

Table 1 from Speech Emotion Recognition Using Clustering Based GA ...

Figure 1 from Speech extraction from vibration signals based on deep ...
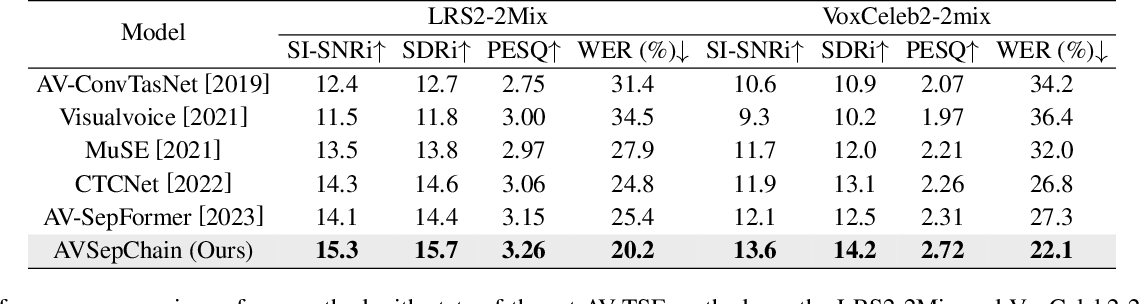
Table 1 from Separate in the Speech Chain: Cross-Modal Conditional ...
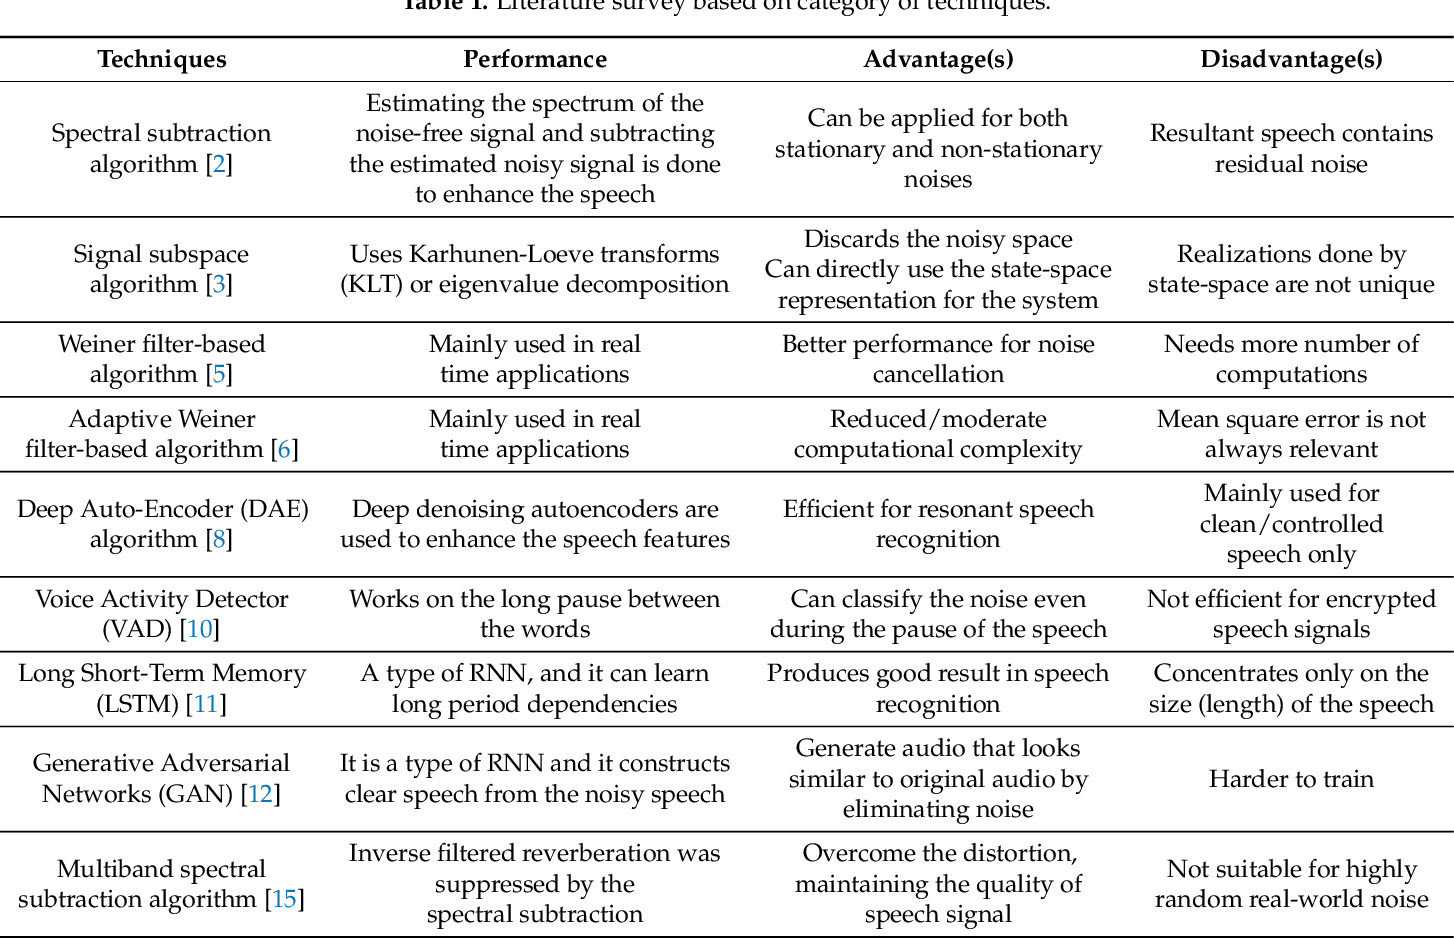
Table 1 from A Hybrid Speech Enhancement Algorithm for Voice Assistance ...

Table 2 from Target Speaker Extraction with Ultra-Short Reference ...
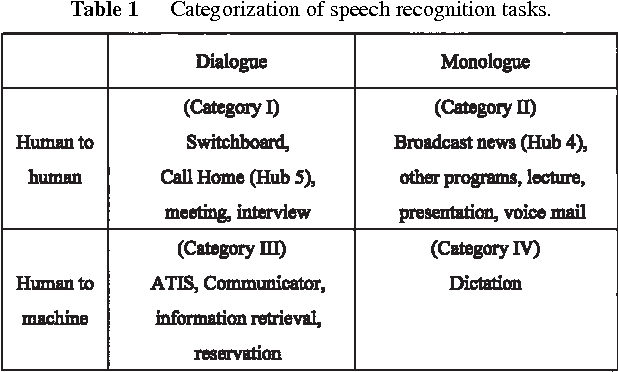
Table 1 from Recent Progress in Corpus-Based Spontaneous Speech ...
Advertisement Space (336x280)

Target Speech Extraction with Pre-trained Self-supervised Learning Models
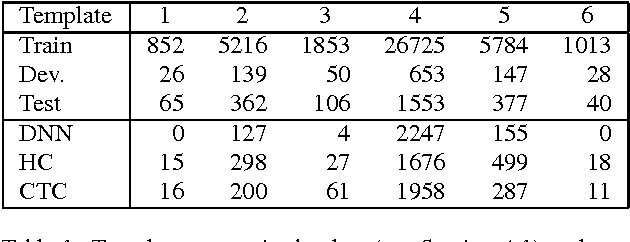
Table 1 from A Template-Based Approach for Speech Synthesis Intonation ...
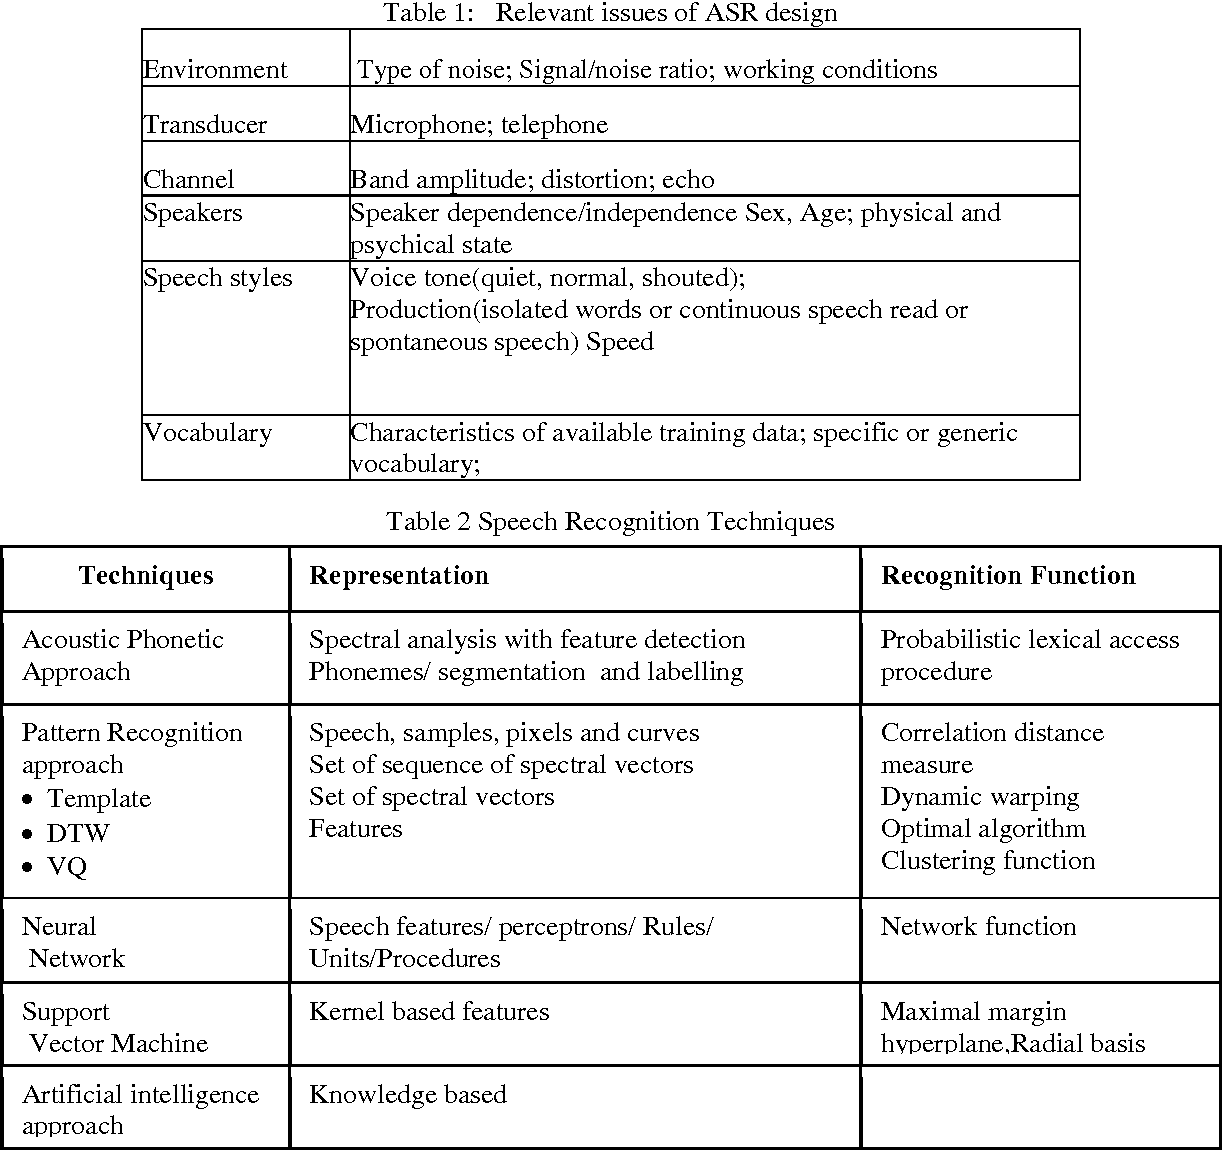
Table 1 from An Overview of Technical Progress in Speech Recognition ...
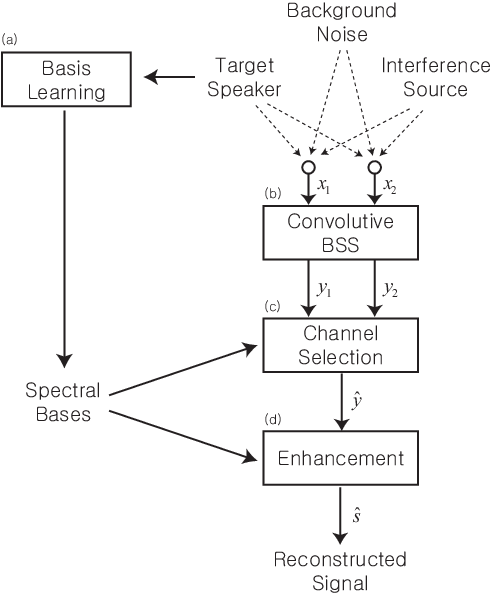
Figure 1 from Target speech extractionwith learned spectral bases ...

Table 1 from An Overview of End-to-End Automatic Speech Recognition ...
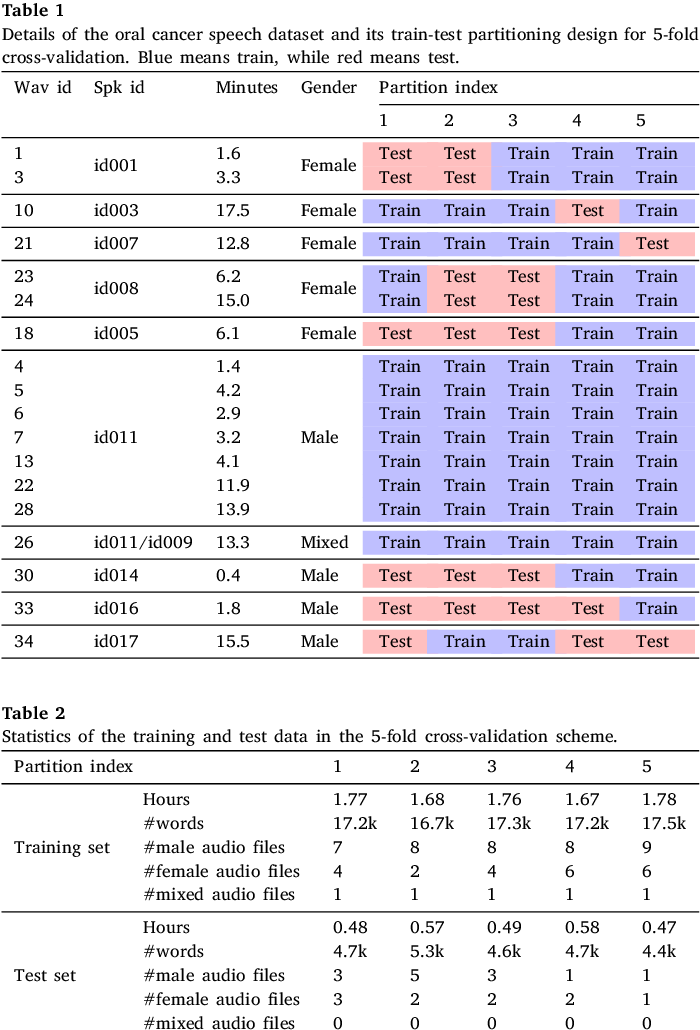
Table 1 from Low-resource automatic speech recognition and error ...