
Table 1 From High Quality And Similarity One Shot Voice Conversion

Table 1 from High Quality and Similarity One-Shot Voice Conversion ...

Table 1 from High Quality and Similarity One-Shot Voice Conversion ...

Figure 2 from High Quality and Similarity One-Shot Voice Conversion ...
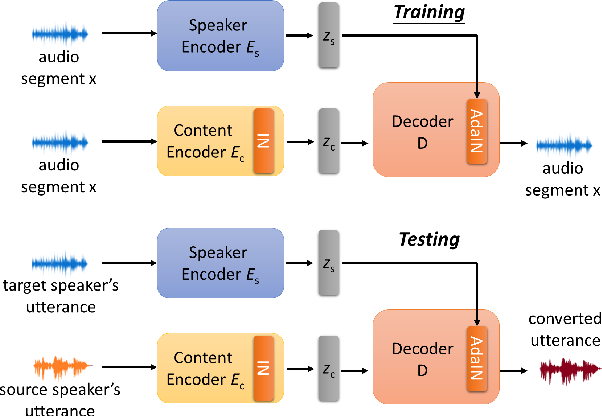
Table 1 from One-shot Voice Conversion by Separating Speaker and ...

Table 1 from One-shot Voice Conversion by Separating Speaker and ...
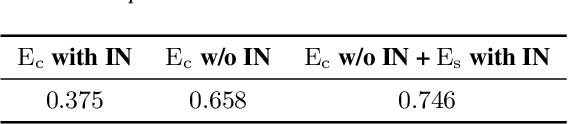
Table 1 from One-shot Voice Conversion by Separating Speaker and ...
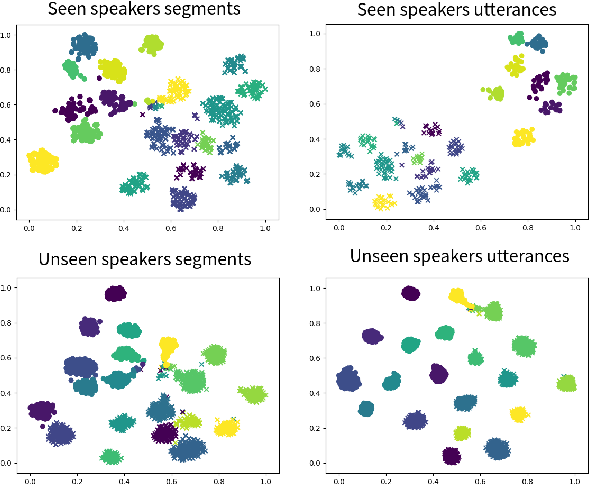
Table 1 from One-shot Voice Conversion by Separating Speaker and ...

Table 1 from One-shot Voice Conversion by Separating Speaker and ...
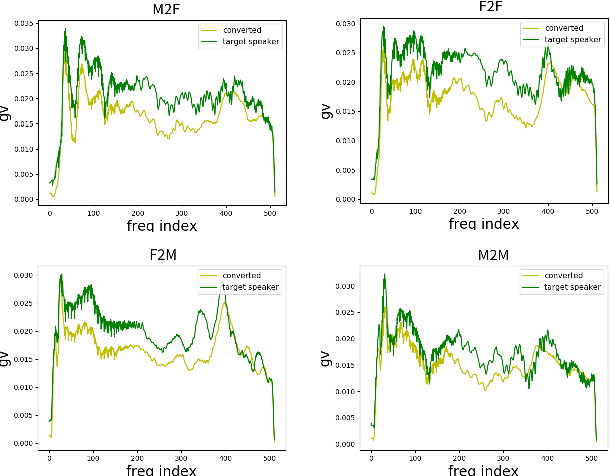
Table 1 from One-shot Voice Conversion by Separating Speaker and ...
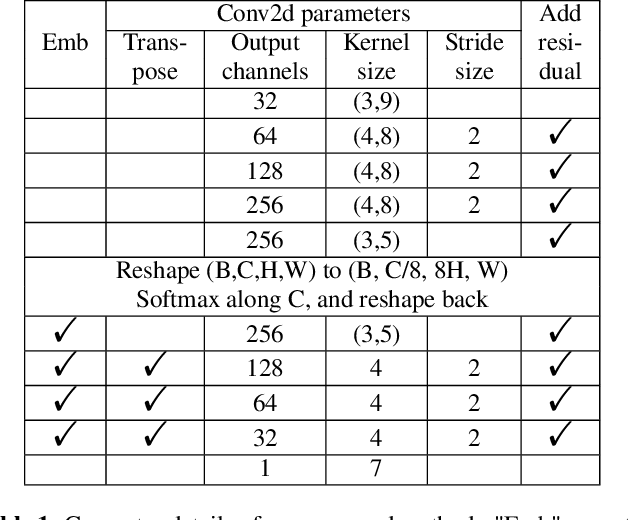
Table 1 from One-Shot Voice Conversion Using Star-Gan | Semantic Scholar
Advertisement Space (300x250)

Table 1 from Improving robustness of one-shot voice conversion with ...
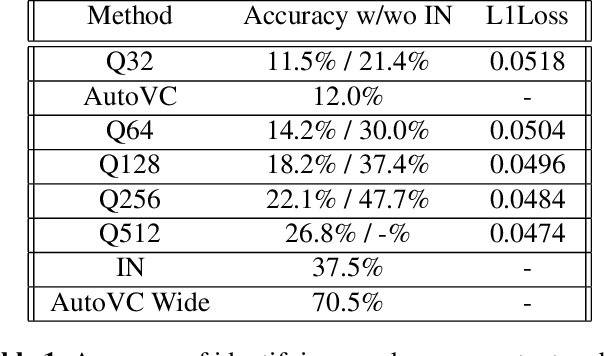
Table 1 from One-Shot Voice Conversion by Vector Quantization ...
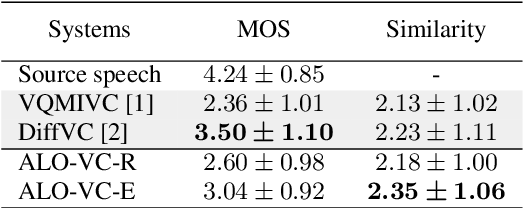
Table 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...

Table 1 from Voice Conversion for Stuttered Speech, Instruments, Unseen ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Table 1 from Zero-shot Voice Conversion with Diffusion Transformers ...
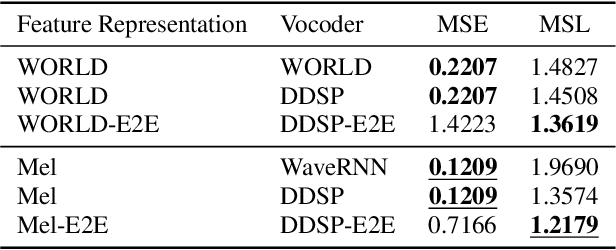
Table 1 from End-to-End Zero-Shot Voice Conversion Using a DDSP Vocoder ...
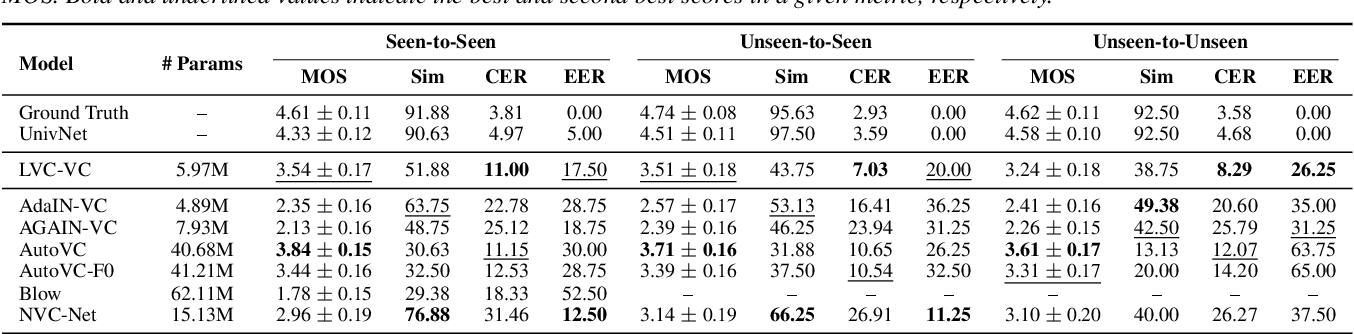
Table 1 from End-to-End Zero-Shot Voice Conversion with Location ...

Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Table 1 from Streamable Speech Representation Disentanglement and Multi ...
Advertisement Space (336x280)
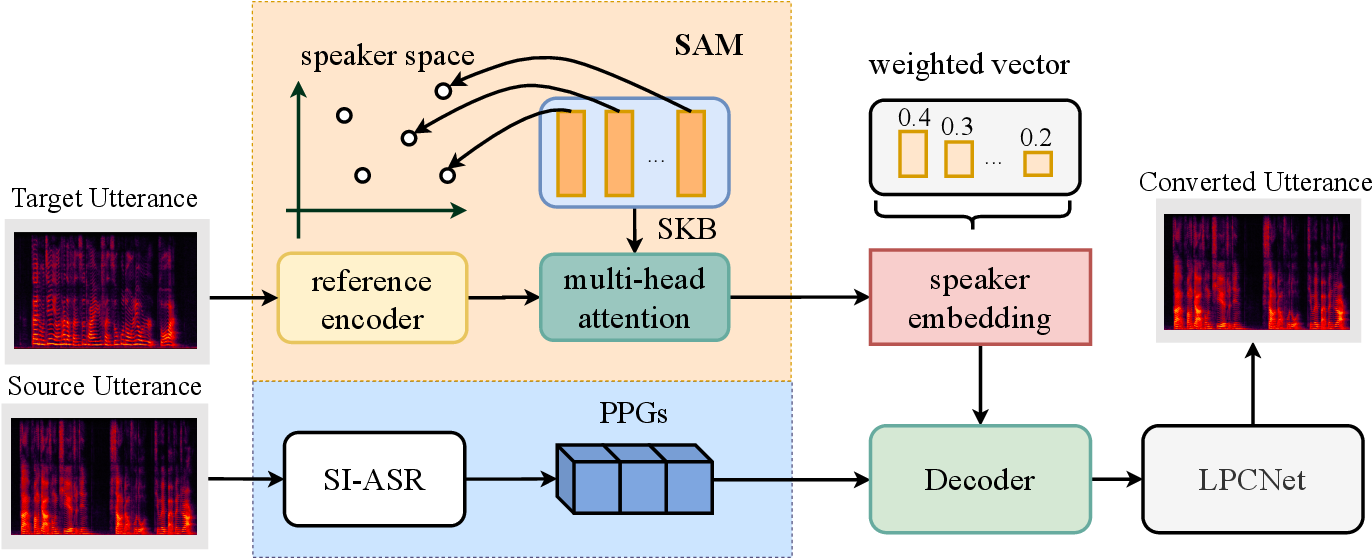
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from One-Shot Voice Conversion Using Star-Gan | Semantic Scholar
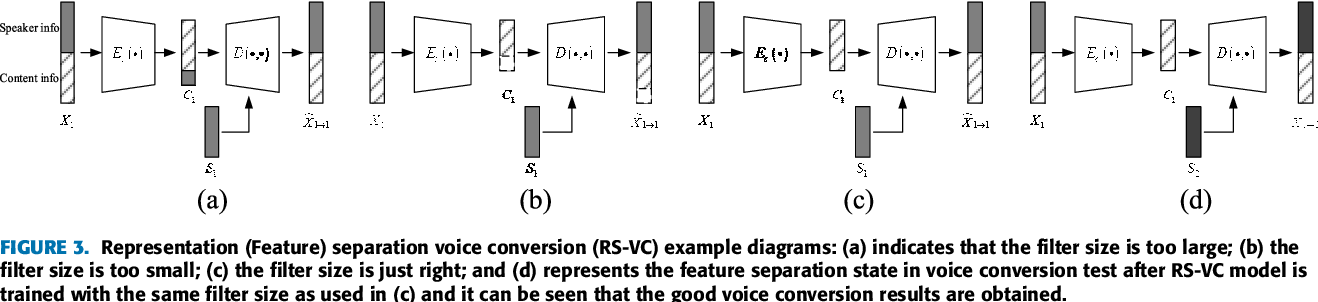
Figure 1 from One-Shot Voice Conversion Algorithm Based on ...
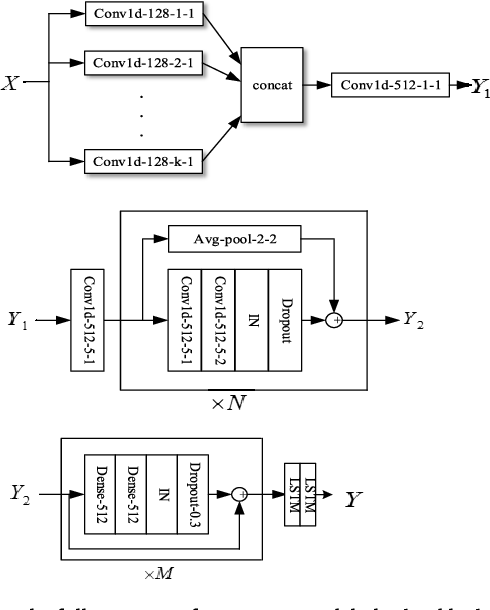
Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

Figure 1 from Improving robustness of one-shot voice conversion with ...
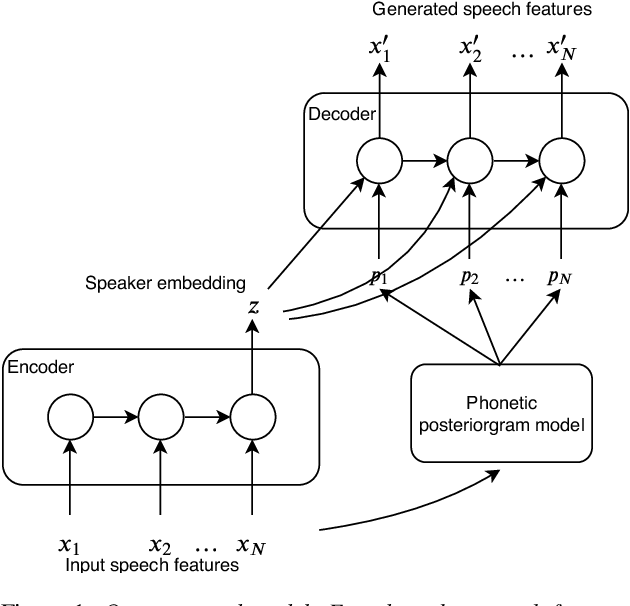
Figure 1 from One-Shot Voice Conversion with Disentangled ...
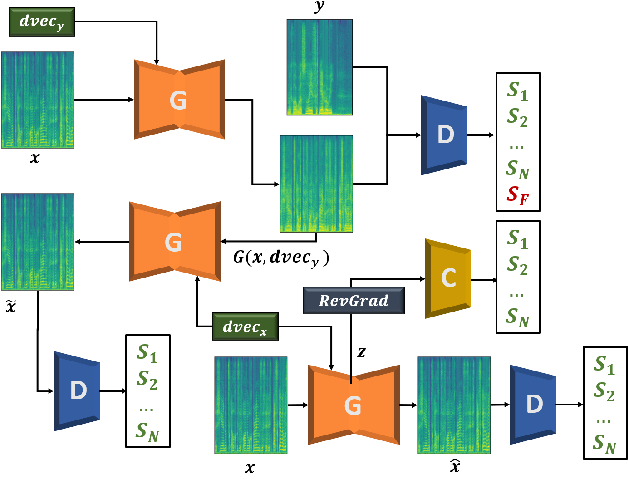
Figure 1 from One-Shot Voice Conversion with Speaker-Agnostic StarGAN ...
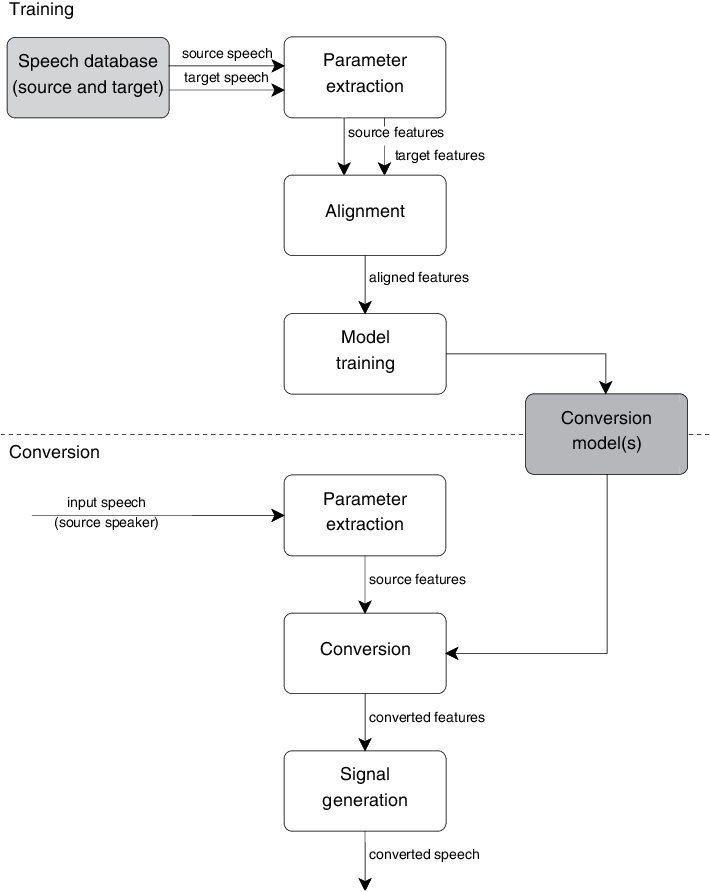
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from An overview of voice conversion systems | Semantic Scholar
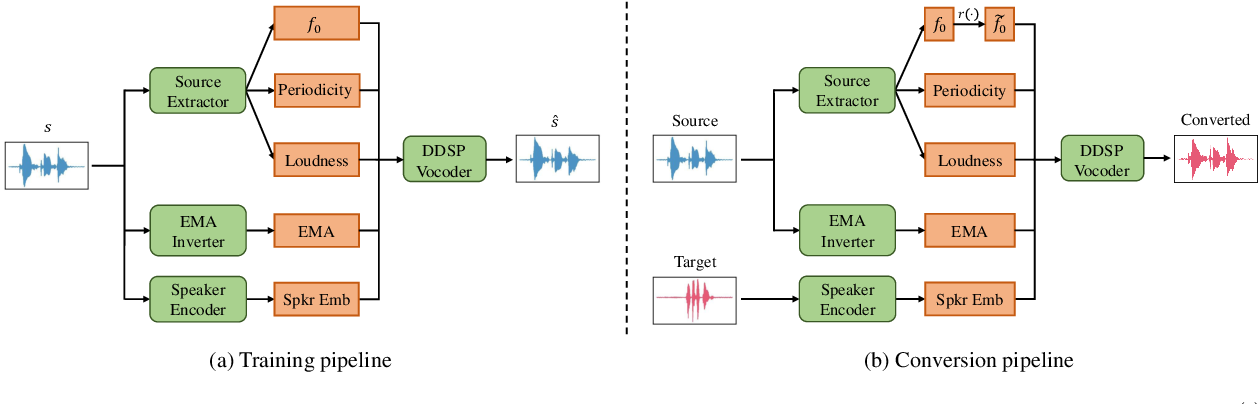
Figure 1 from RT-VC: Real-Time Zero-Shot Voice Conversion with Speech ...
Advertisement Space (336x280)
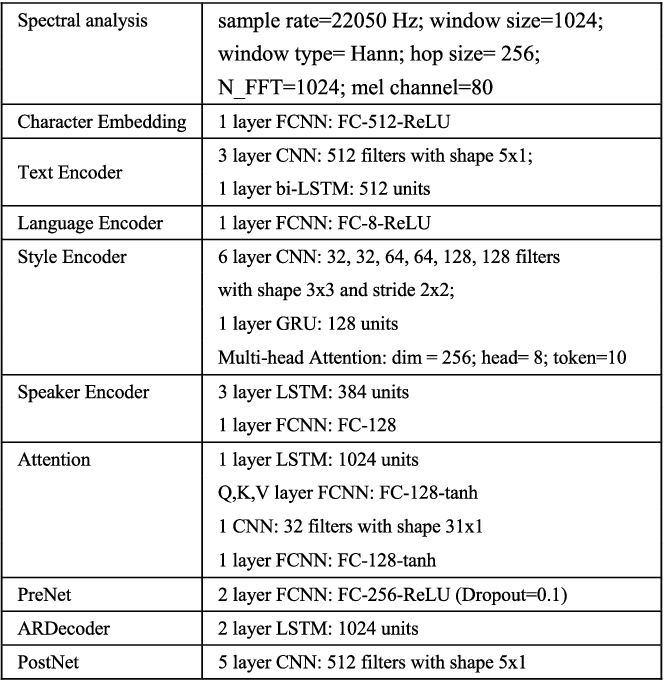
Table 1 from Zero-Shot Voice Cloning Text-to-Speech for Dysphonia ...

Figure 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...

Table 1 from Speech Representation Disentanglement with Adversarial ...
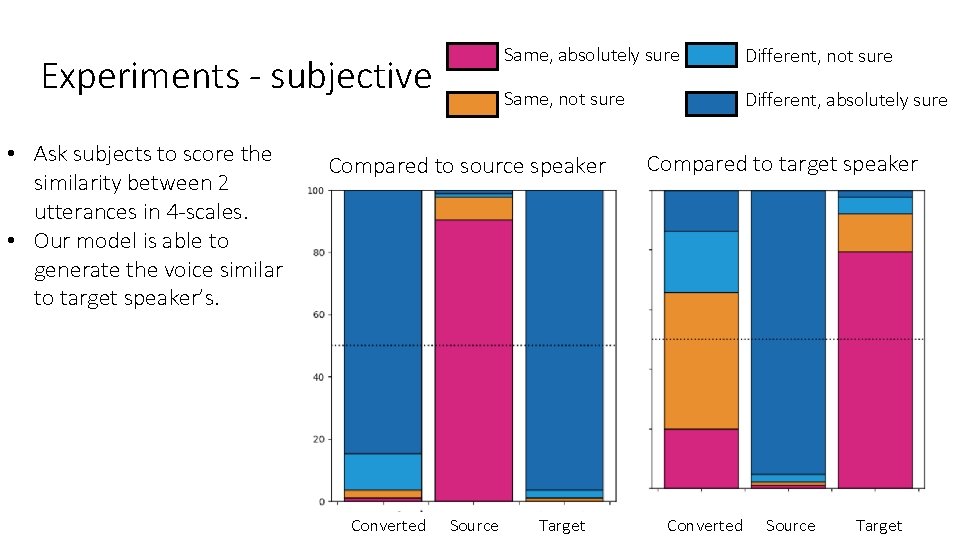
Oneshot Voice Conversion by Separating Speaker and Content
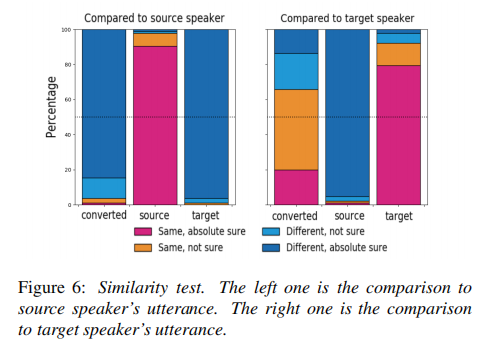
【论文学习】《One-shot Voice Conversion by Separating Speaker and Content ...

VQVC+: One-Shot Voice Conversion by Vector Quantization and U-Net ...