
Table 1 From Tree Knowledge Distillation For Compressing Transformer

Table 1 from Tree Knowledge Distillation for Compressing Transformer ...

Figure 1 from Tree Knowledge Distillation for Compressing Transformer ...

Table 1 from Knowledge Distillation via the Target-aware Transformer ...
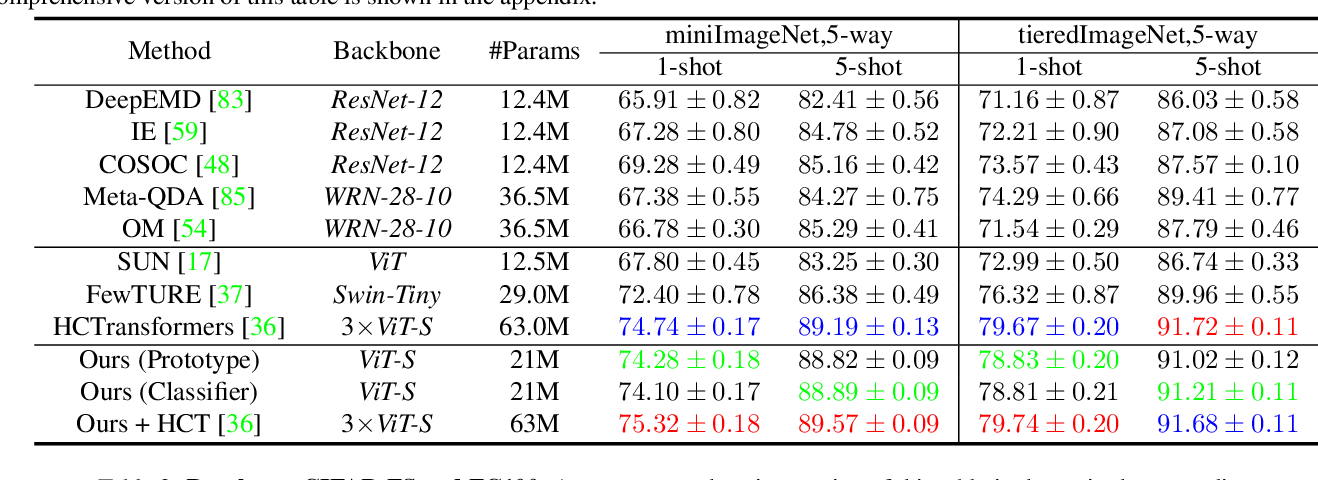
Table 1 from Supervised Masked Knowledge Distillation for Few-Shot ...

Figure 1 from Multi-view knowledge distillation transformer for human ...

Table 1 from Understanding and Improving Knowledge Distillation for ...
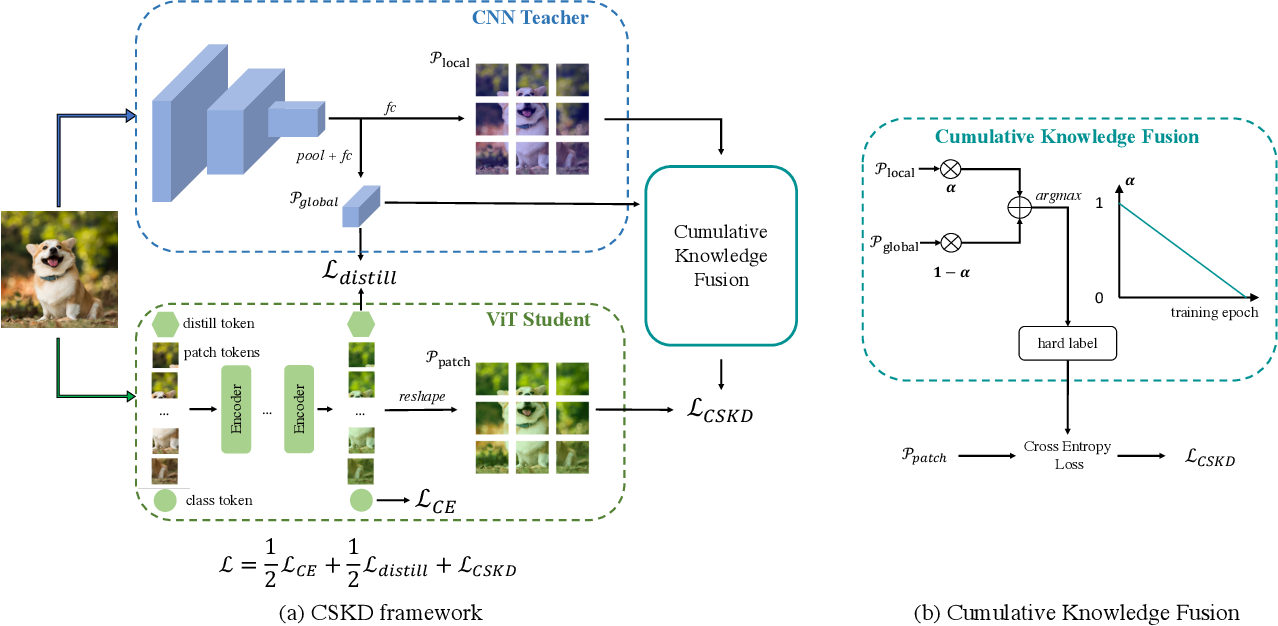
Figure 1 from Cumulative Spatial Knowledge Distillation for Vision ...

Figure 1 from Triple-View Knowledge Distillation for Semi-Supervised ...

Figure 1 from PaCKD: Pattern-Clustered Knowledge Distillation for ...

Figure 1 from On Compressing U-net Using Knowledge Distillation ...
Advertisement Space (300x250)
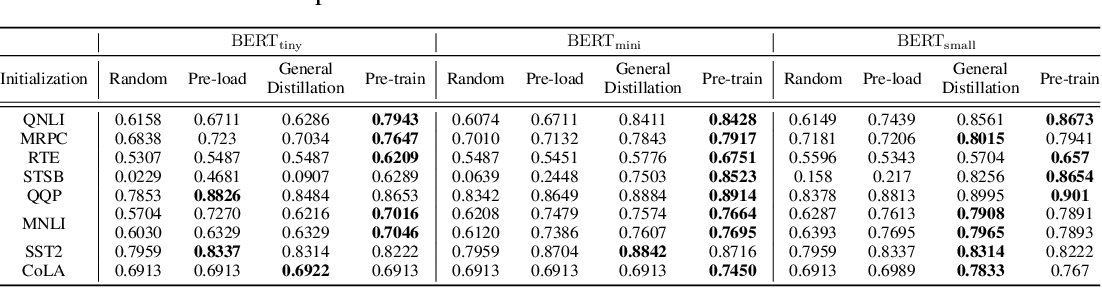
Table 1 from Knowledge Distillation of Transformer-based Language ...
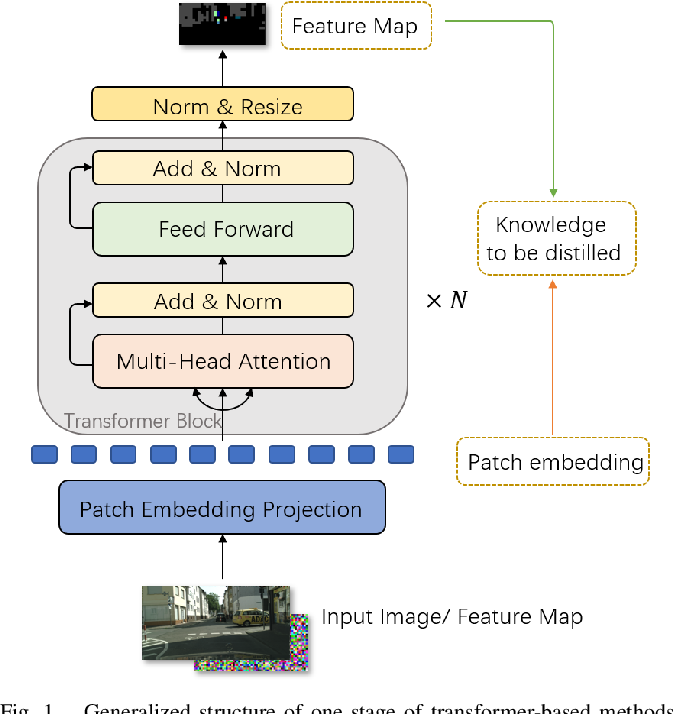
Figure 1 from Transformer-based Knowledge Distillation for Efficient ...

Figure 1 from Knowledge Distillation from BERT Transformer to Speech ...
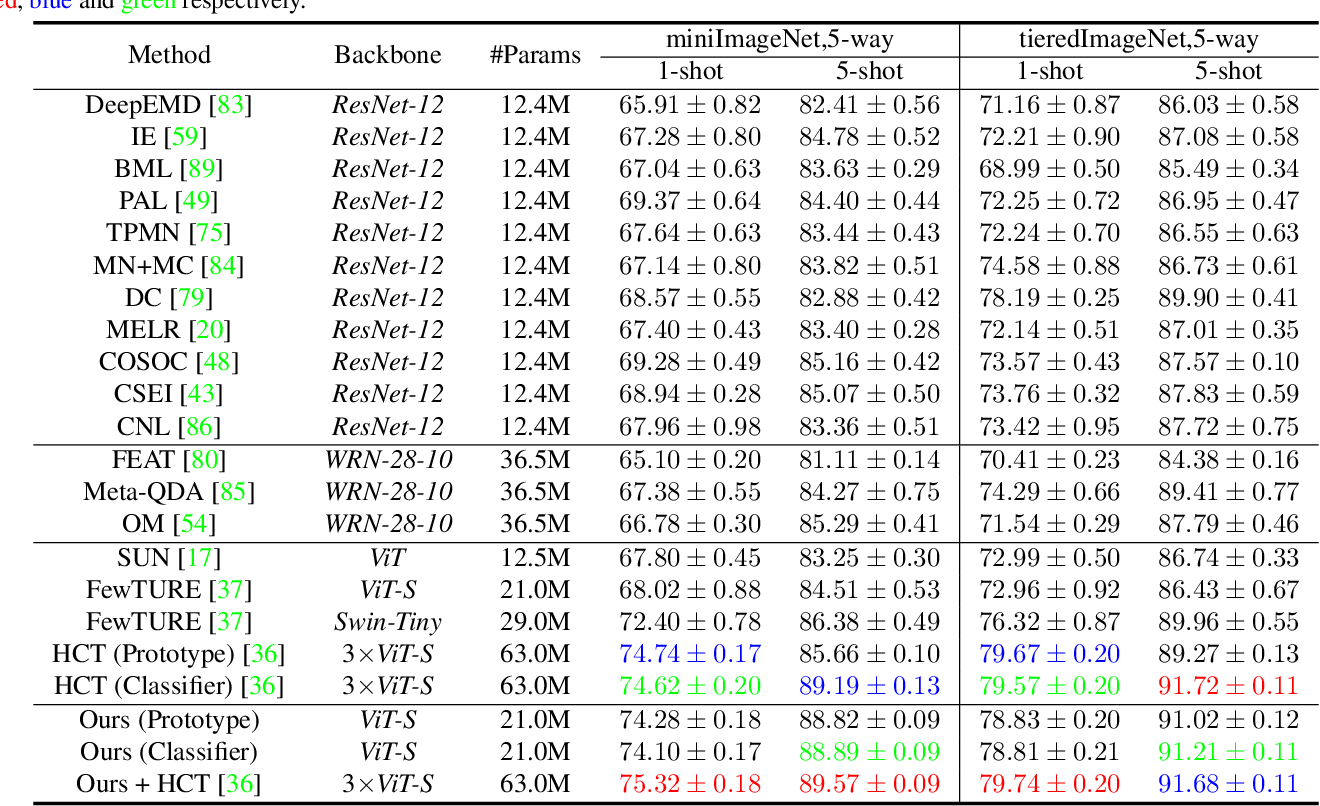
Table 9 from Supervised Masked Knowledge Distillation for Few-Shot ...

Table 9 from m2mKD: Module-to-Module Knowledge Distillation for Modular ...
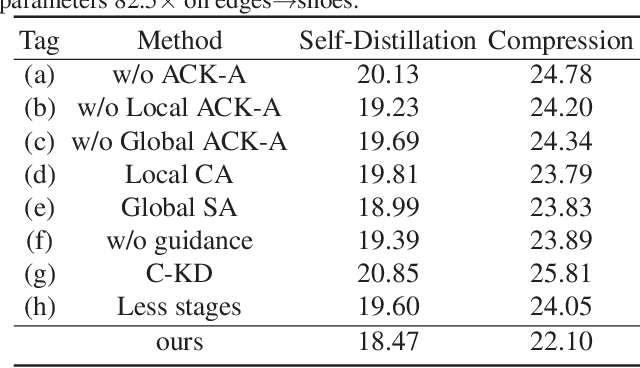
Table 4 from Accumulation Knowledge Distillation for Conditional GAN ...

Table 1 from Efficient Encoder-Decoder Transformer Decoding for ...

Table 11 from Automated Knowledge Distillation via Monte Carlo Tree ...
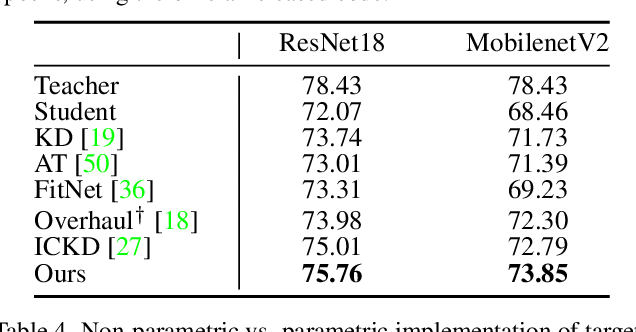
Table 3 from Knowledge Distillation via the Target-aware Transformer ...
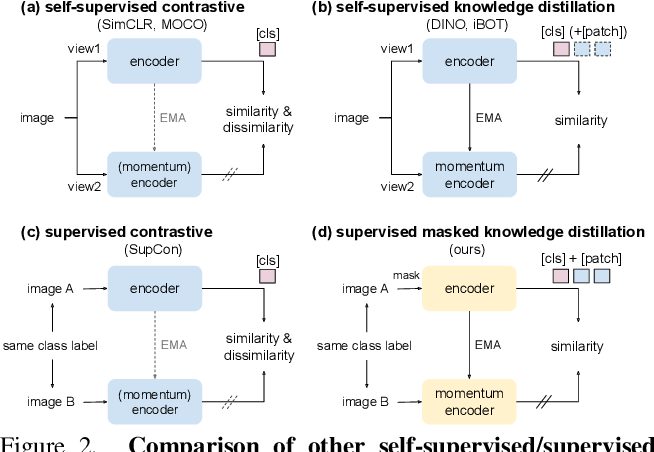
Figure 2 from Supervised Masked Knowledge Distillation for Few-Shot ...
Advertisement Space (336x280)

Figure 4 from A Transformer-Based Knowledge Distillation Network for ...

(PDF) Knowledge Distillation for Detection Transformer with Consistent ...
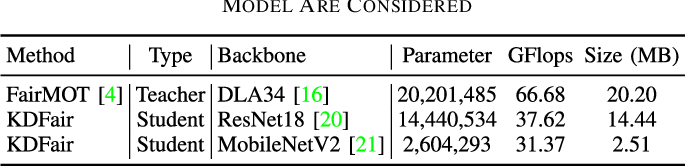
Table I from Compressing the Multiobject Tracking Model via Knowledge ...

Table 2 from Knowledge Distillation of Transformer-based Language ...

Table 1 from No Head Left Behind - Multi-Head Alignment Distillation ...
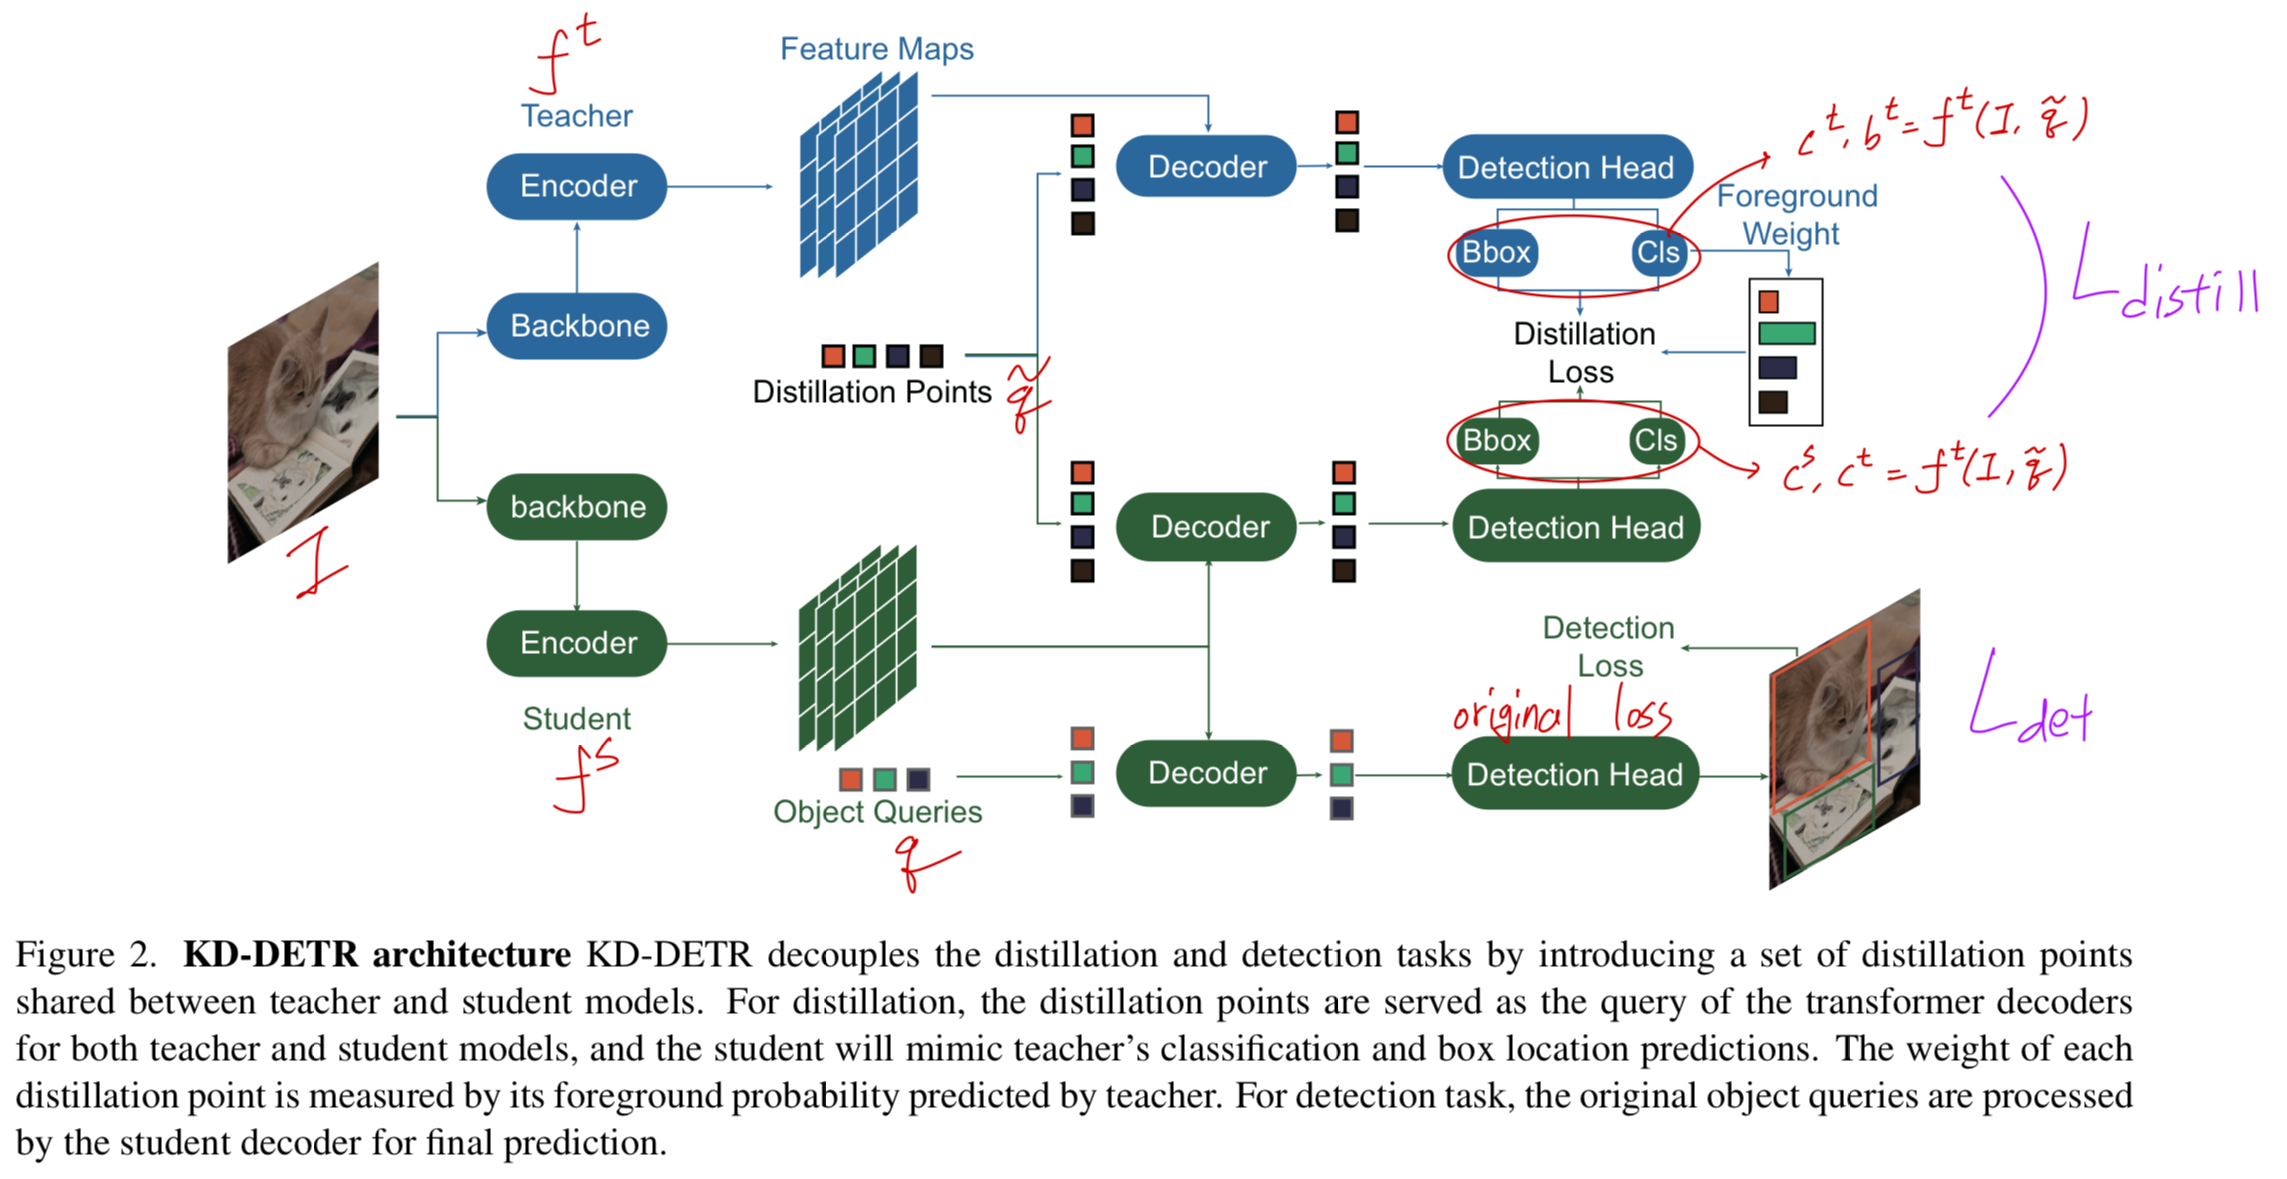
KD-DETR: Knowledge Distillation for Detection Transformer with ...
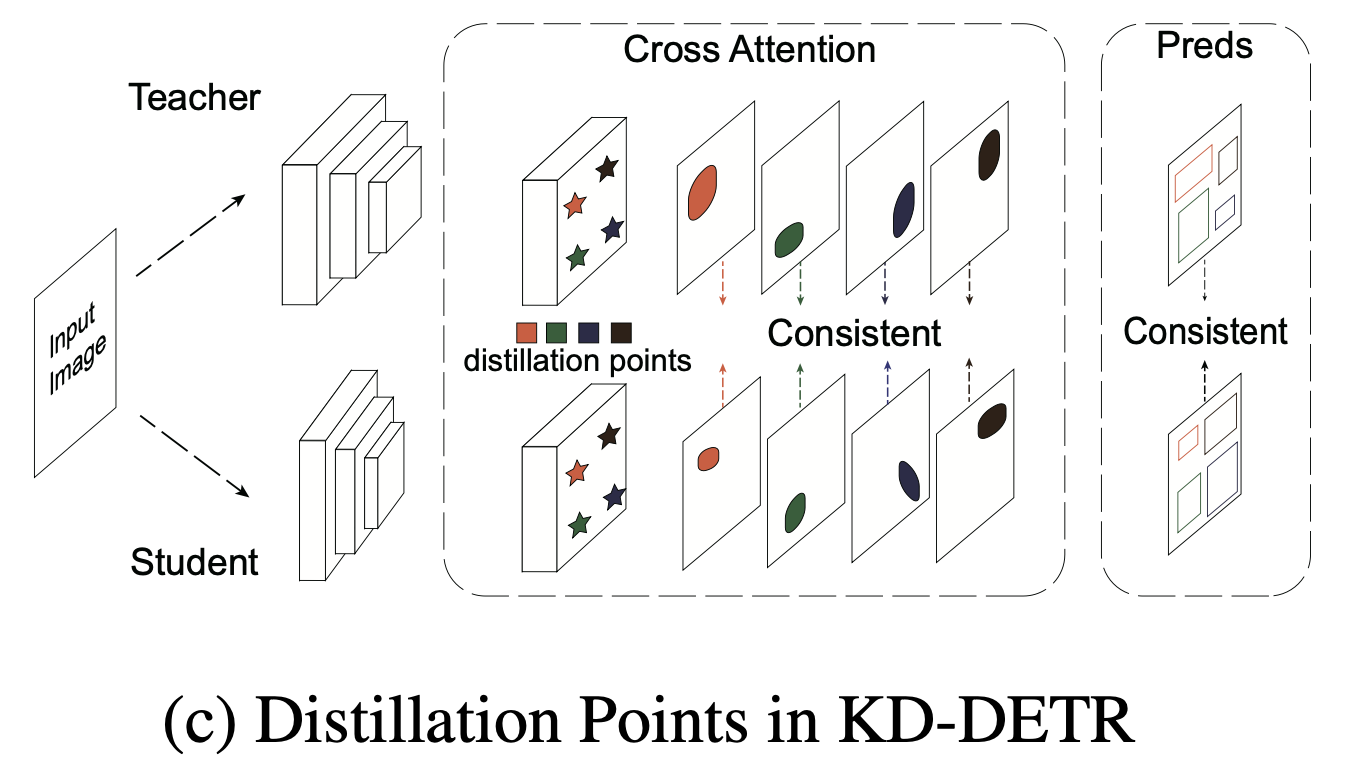
KD-DETR: Knowledge Distillation for Detection Transformer with ...

Figure 1 from Compressing Transfer: Mutual Learning- Empowered ...
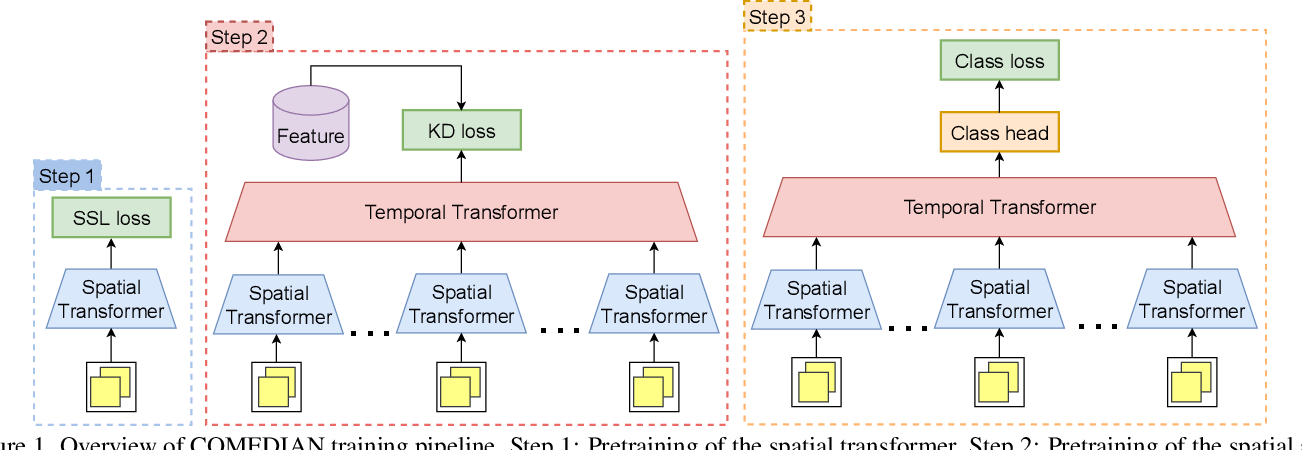
Figure 1 from COMEDIAN: Self-Supervised Learning and Knowledge ...

(PDF) Compressing Visual-linguistic Model via Knowledge Distillation
Advertisement Space (336x280)

(PDF) Empirical Evaluation of Knowledge Distillation from Transformers ...

Figure 1 from Lightweight Self-Knowledge Distillation with Multi-source ...
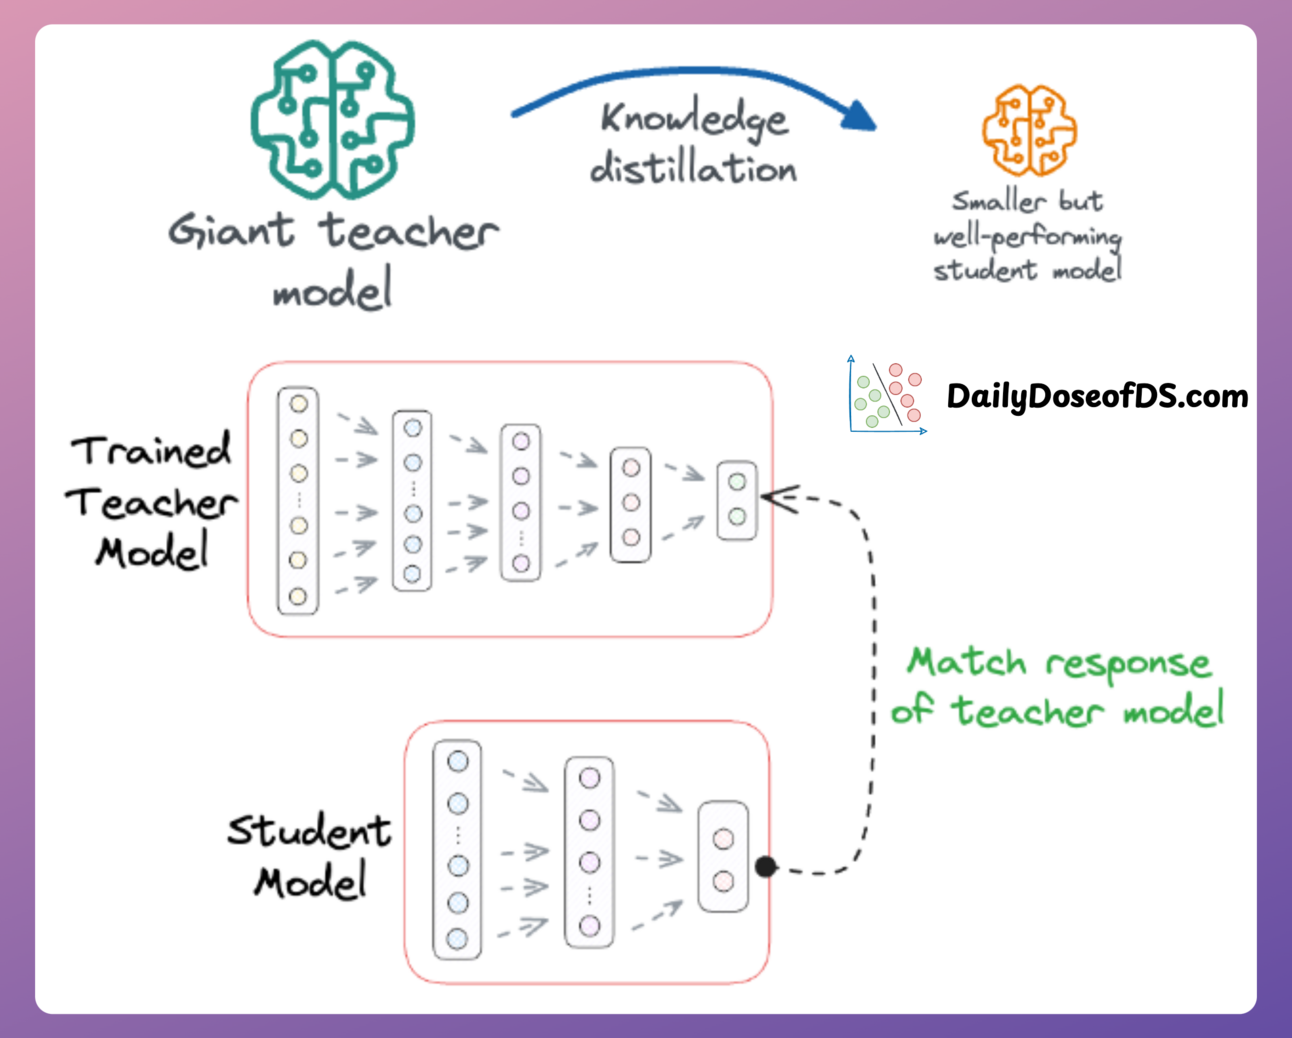
Knowledge Distillation for Model Compression
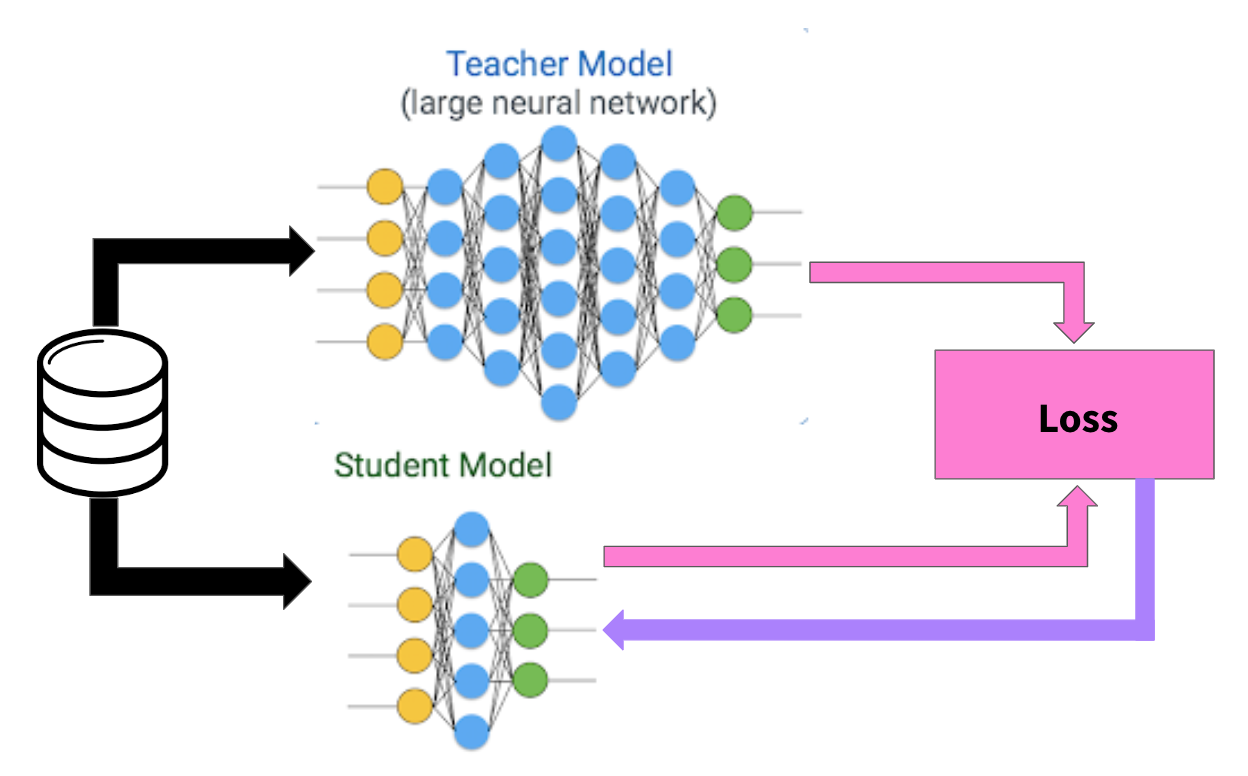
Final Project: Transformer Knowledge Distillation - Home

Knowledge Distillation for Efficient Transformer-Based Reinforcement ...

(PDF) PET: Parameter-efficient Knowledge Distillation on Transformer