
Table 2 From Model Compression And Efficient Inference For Large

Table 2 from Model Compression and Efficient Inference for Large ...

Figure 2 from Model Compression and Efficient Inference for Large ...

Table 3 from Model Compression and Efficient Inference for Large ...

Table 6 from Model Compression and Efficient Inference for Large ...
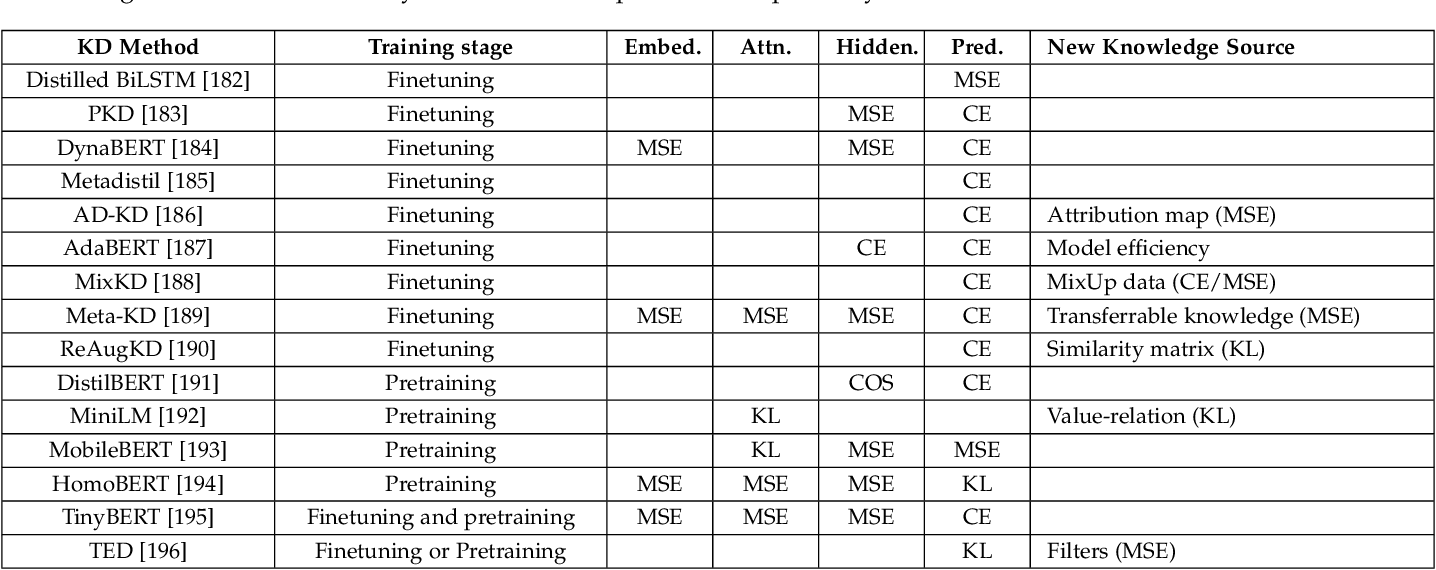
Table 4 from Model Compression and Efficient Inference for Large ...

Figure 8 from Model Compression and Efficient Inference for Large ...

Figure 10 from Model Compression and Efficient Inference for Large ...

Figure 5 from Model Compression and Efficient Inference for Large ...
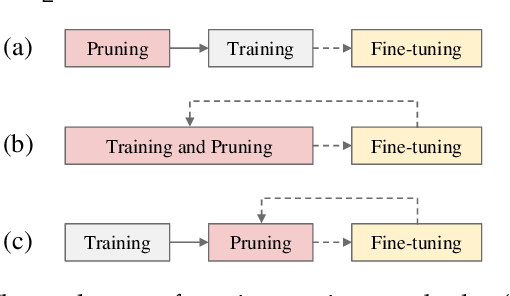
Figure 3 from Model Compression and Efficient Inference for Large ...

Figure 4 from Model Compression and Efficient Inference for Large ...
Advertisement Space (300x250)

Table 2 from A Survey on Efficient Inference for Large Language Models ...

Model Compression and Efficient Inference For Large Language Models: A ...

Paper page - Model Compression and Efficient Inference for Large ...

[2402.09748] Model Compression and Efficient Inference for Large ...

[2402.09748] Model Compression and Efficient Inference for Large ...

Table 1 from Large Multimodal Model Compression via Efficient Pruning ...

Table 2 from Adaptive Control of Local Updating and Model Compression ...

Table 2 from Efficient Graph Neural Network Inference at Large Scale ...
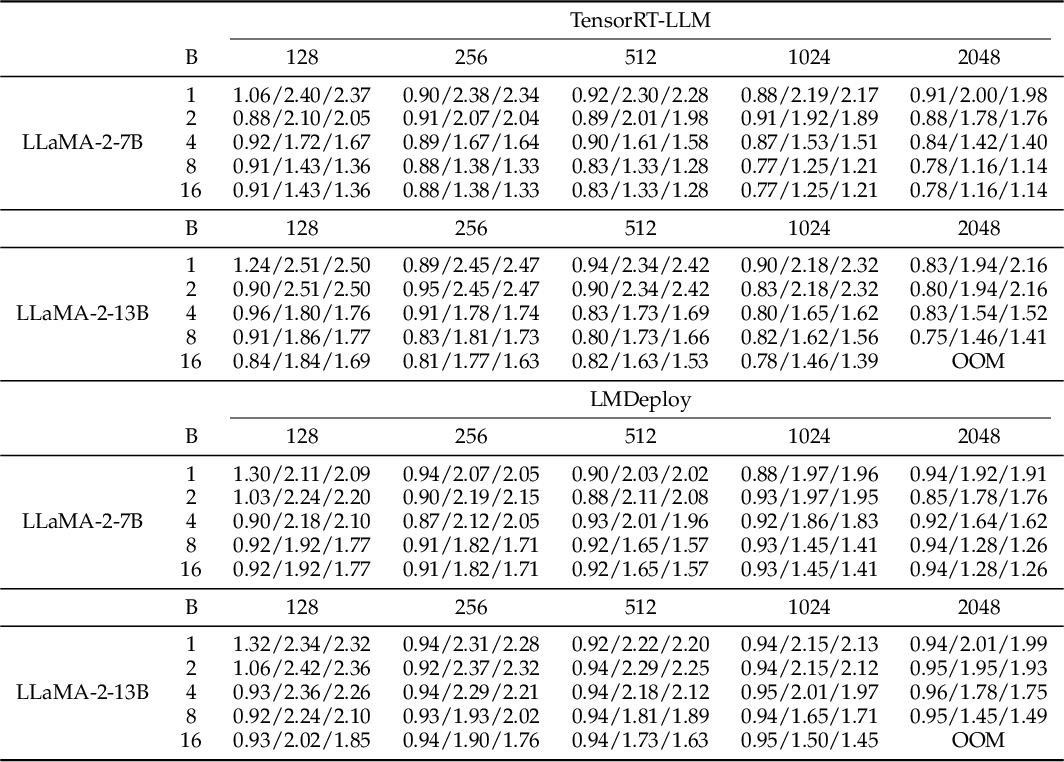
Table 4 from A Survey on Efficient Inference for Large Language Models ...

Table 4 from Layer-Condensed KV Cache for Efficient Inference of Large ...
Advertisement Space (336x280)

Table 1 from Layer-Condensed KV Cache for Efficient Inference of Large ...
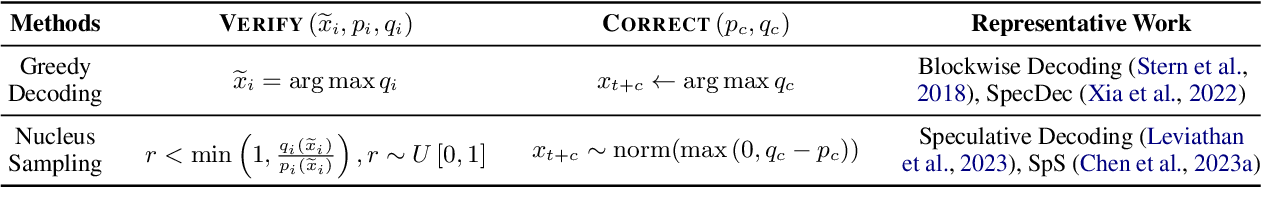
Table 2 from Unlocking Efficiency in Large Language Model Inference: A ...
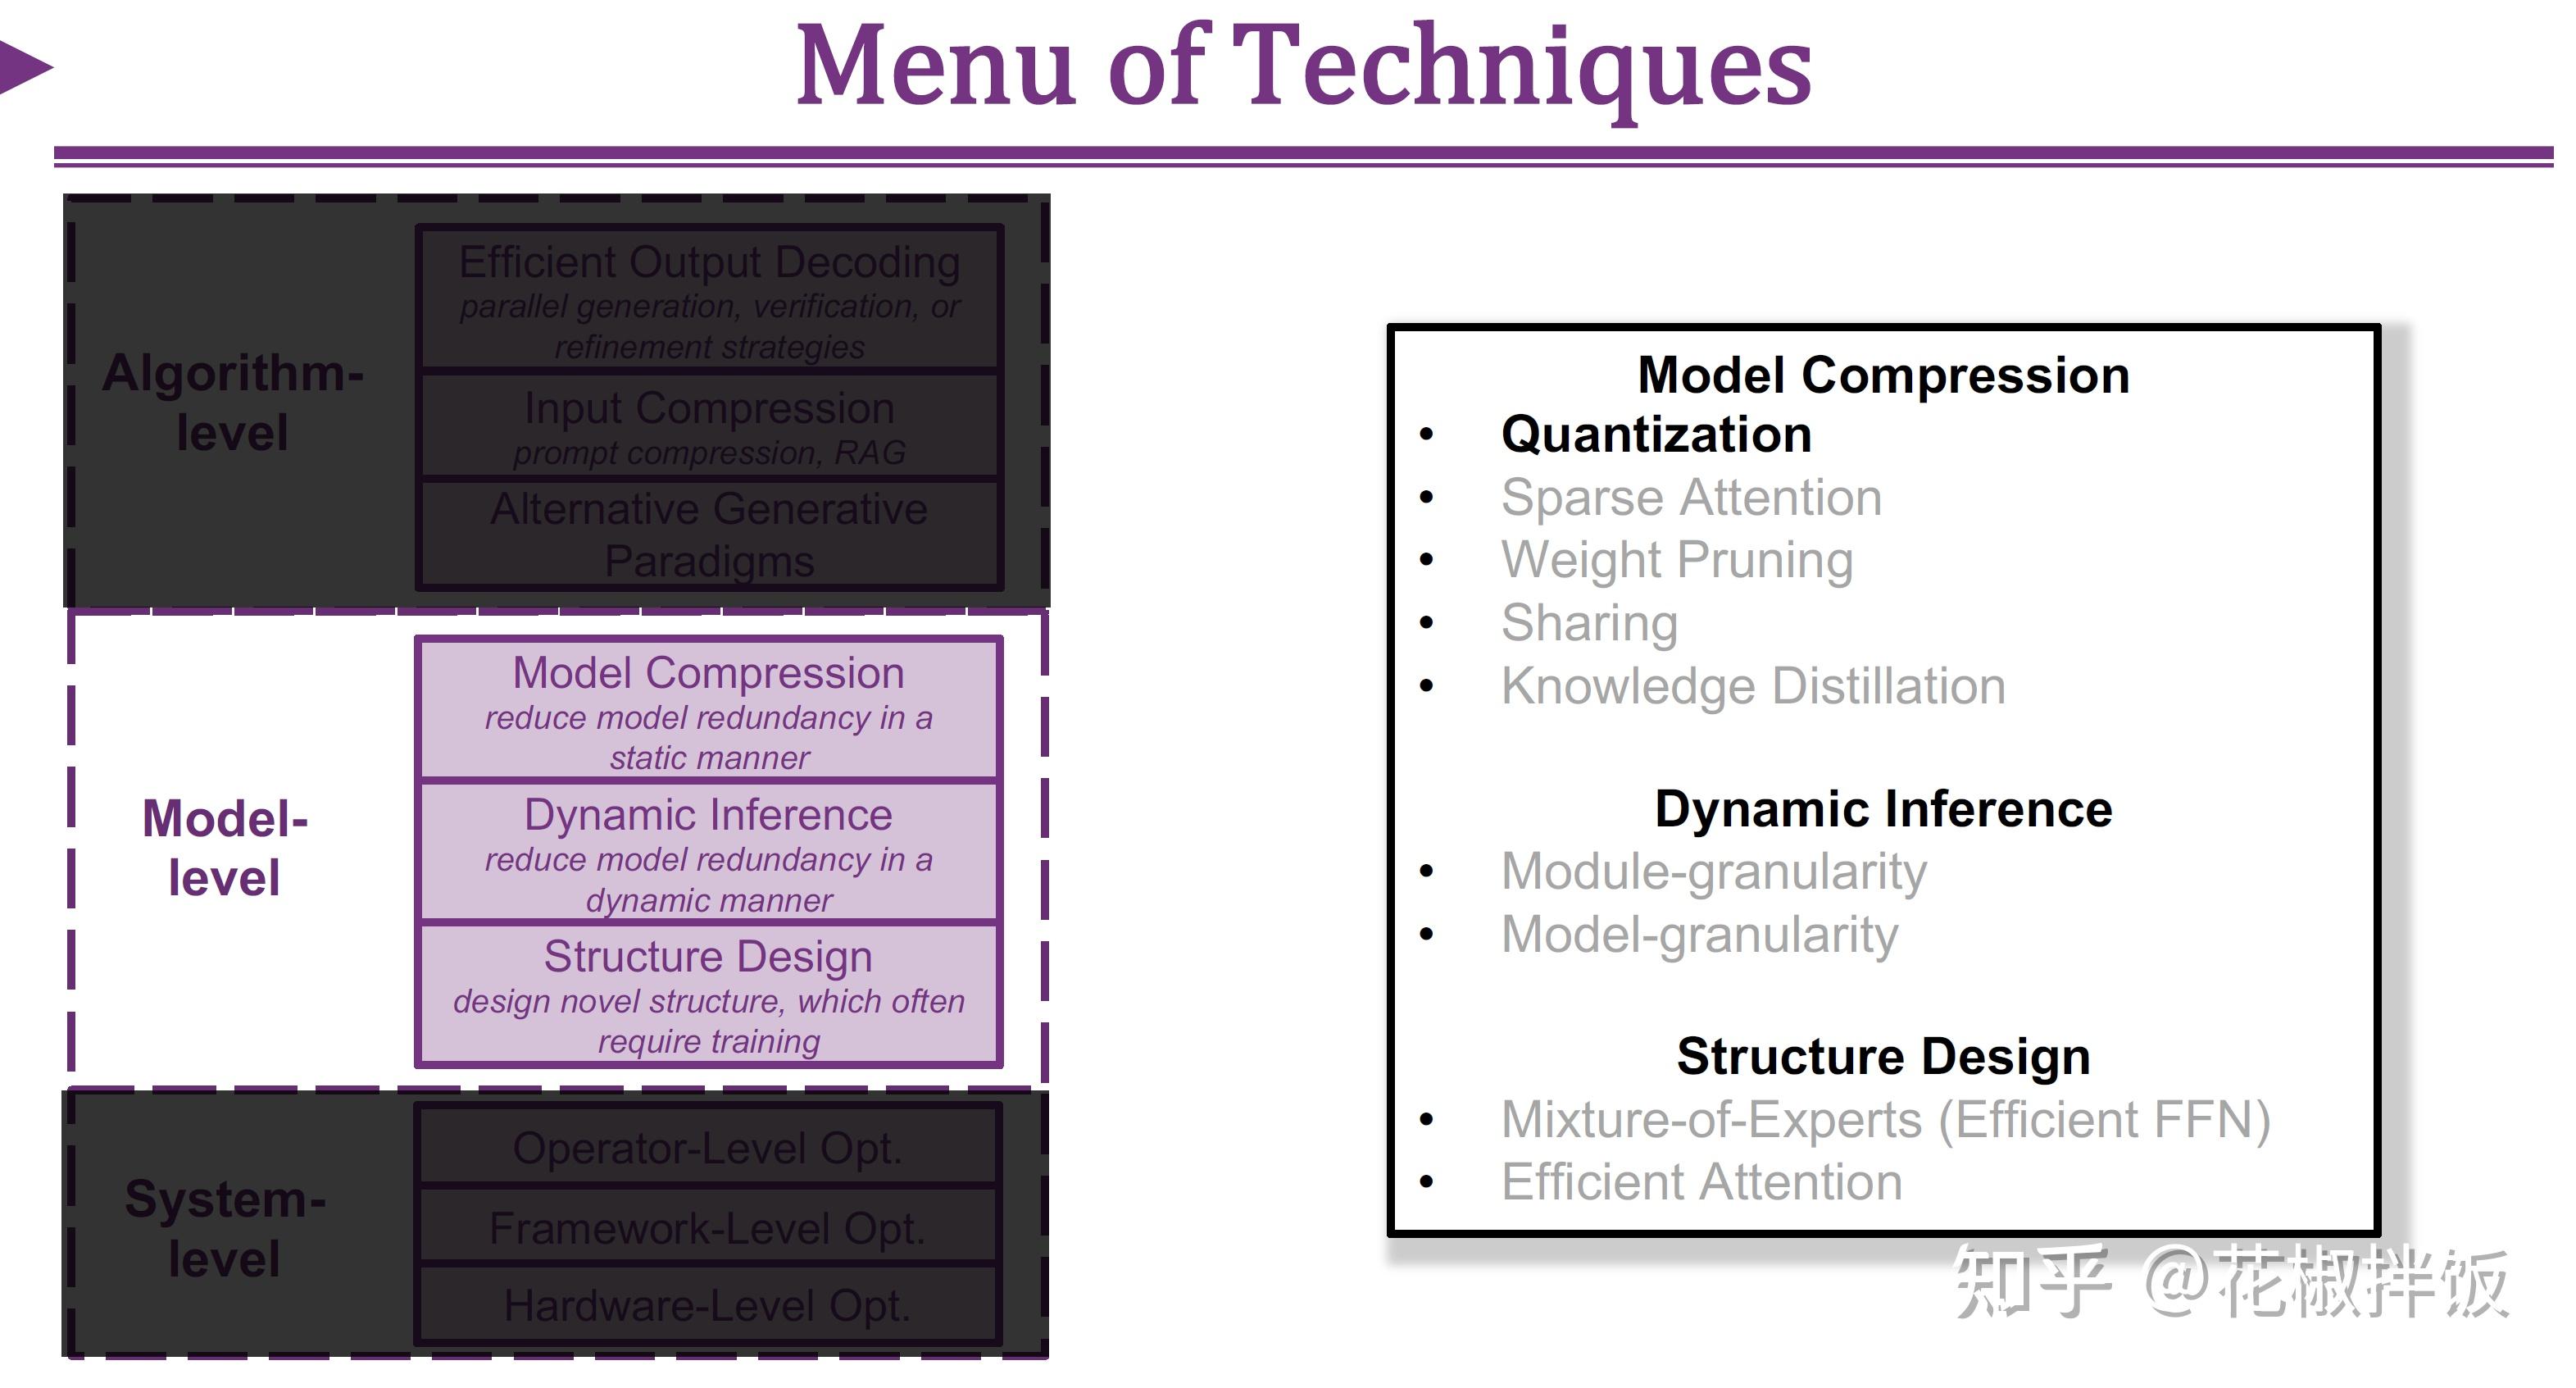
Efficient Inference for Large Language Models – Algorithm, Model, and ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...
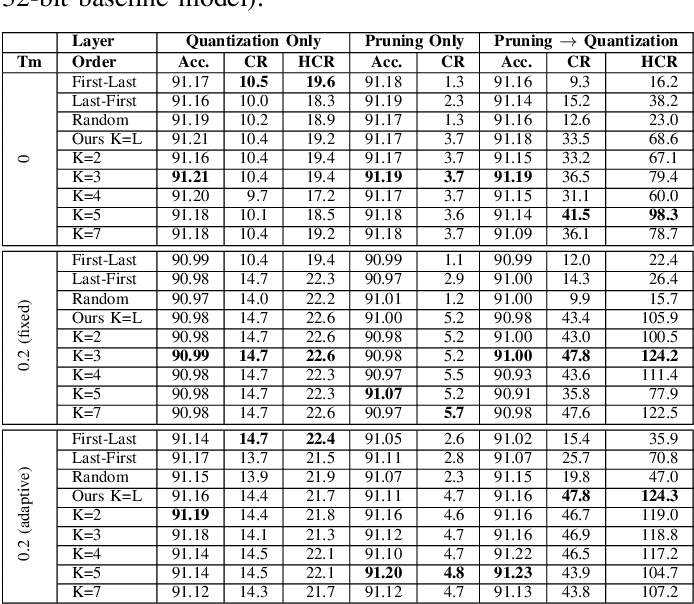
Table I from Towards Optimal Layer Ordering for Efficient Model ...

Figure 1 from Efficient Inference for Large Language Model-based ...

LLMCBench: Benchmarking Large Language Model Compression for Efficient ...
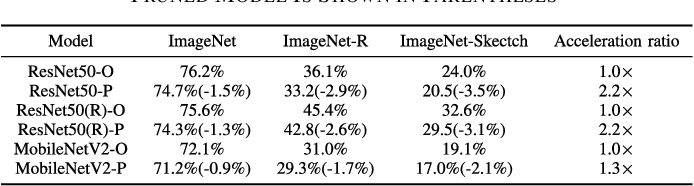
Table XIII from All-in-One Hardware-Oriented Model Compression for ...
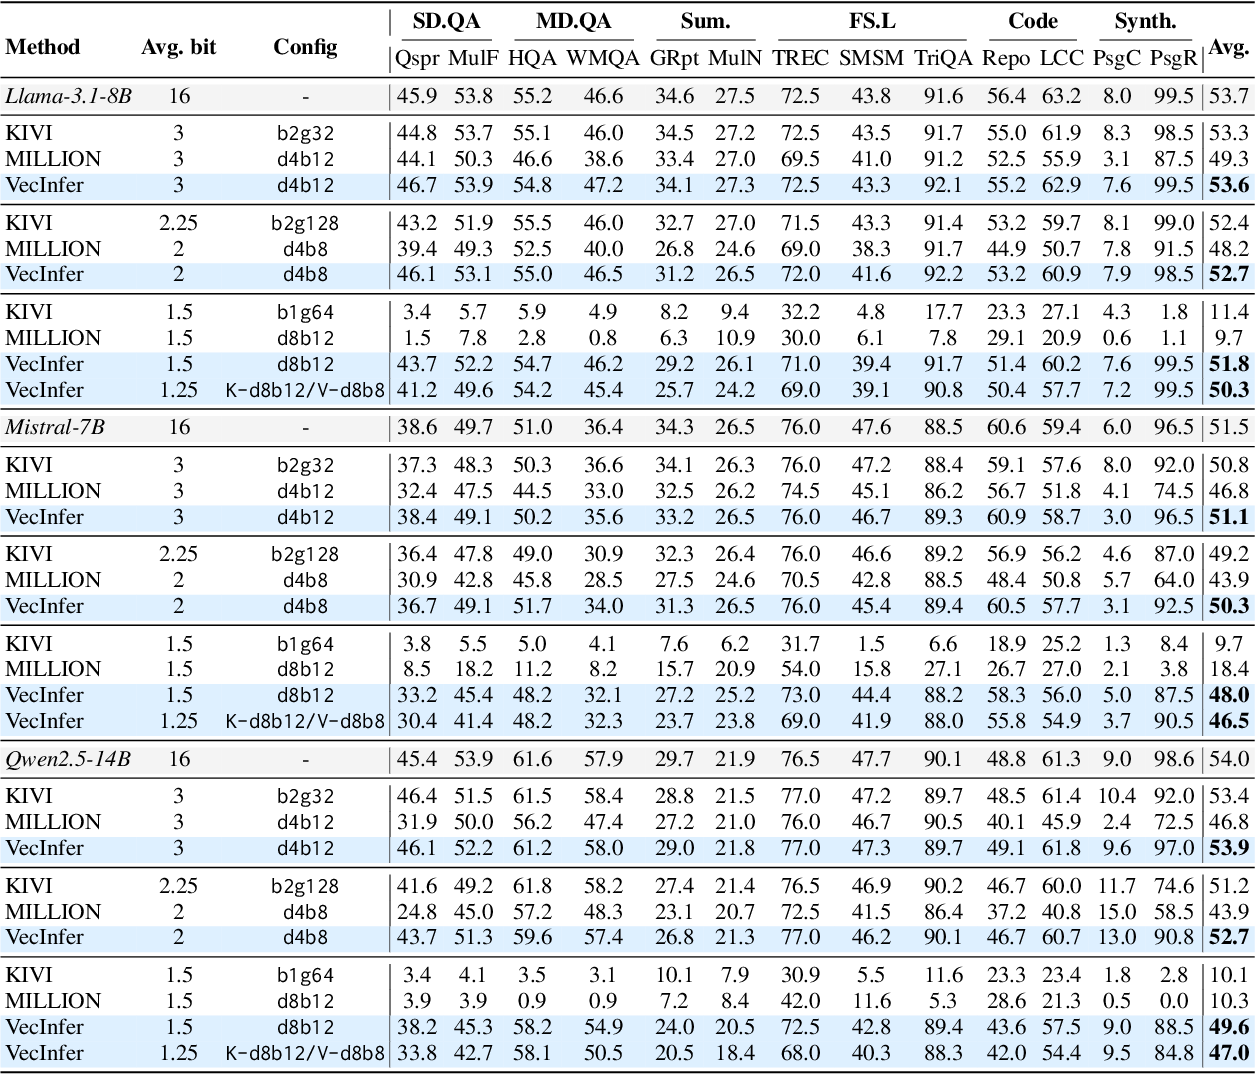
Table 2 from VecInfer: Efficient LLM Inference with Low-Bit KV Cache ...
Advertisement Space (336x280)

Table 1 from Designing Large Foundation Models for Efficient Training ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

Table 3 from Adaptive Control of Local Updating and Model Compression ...
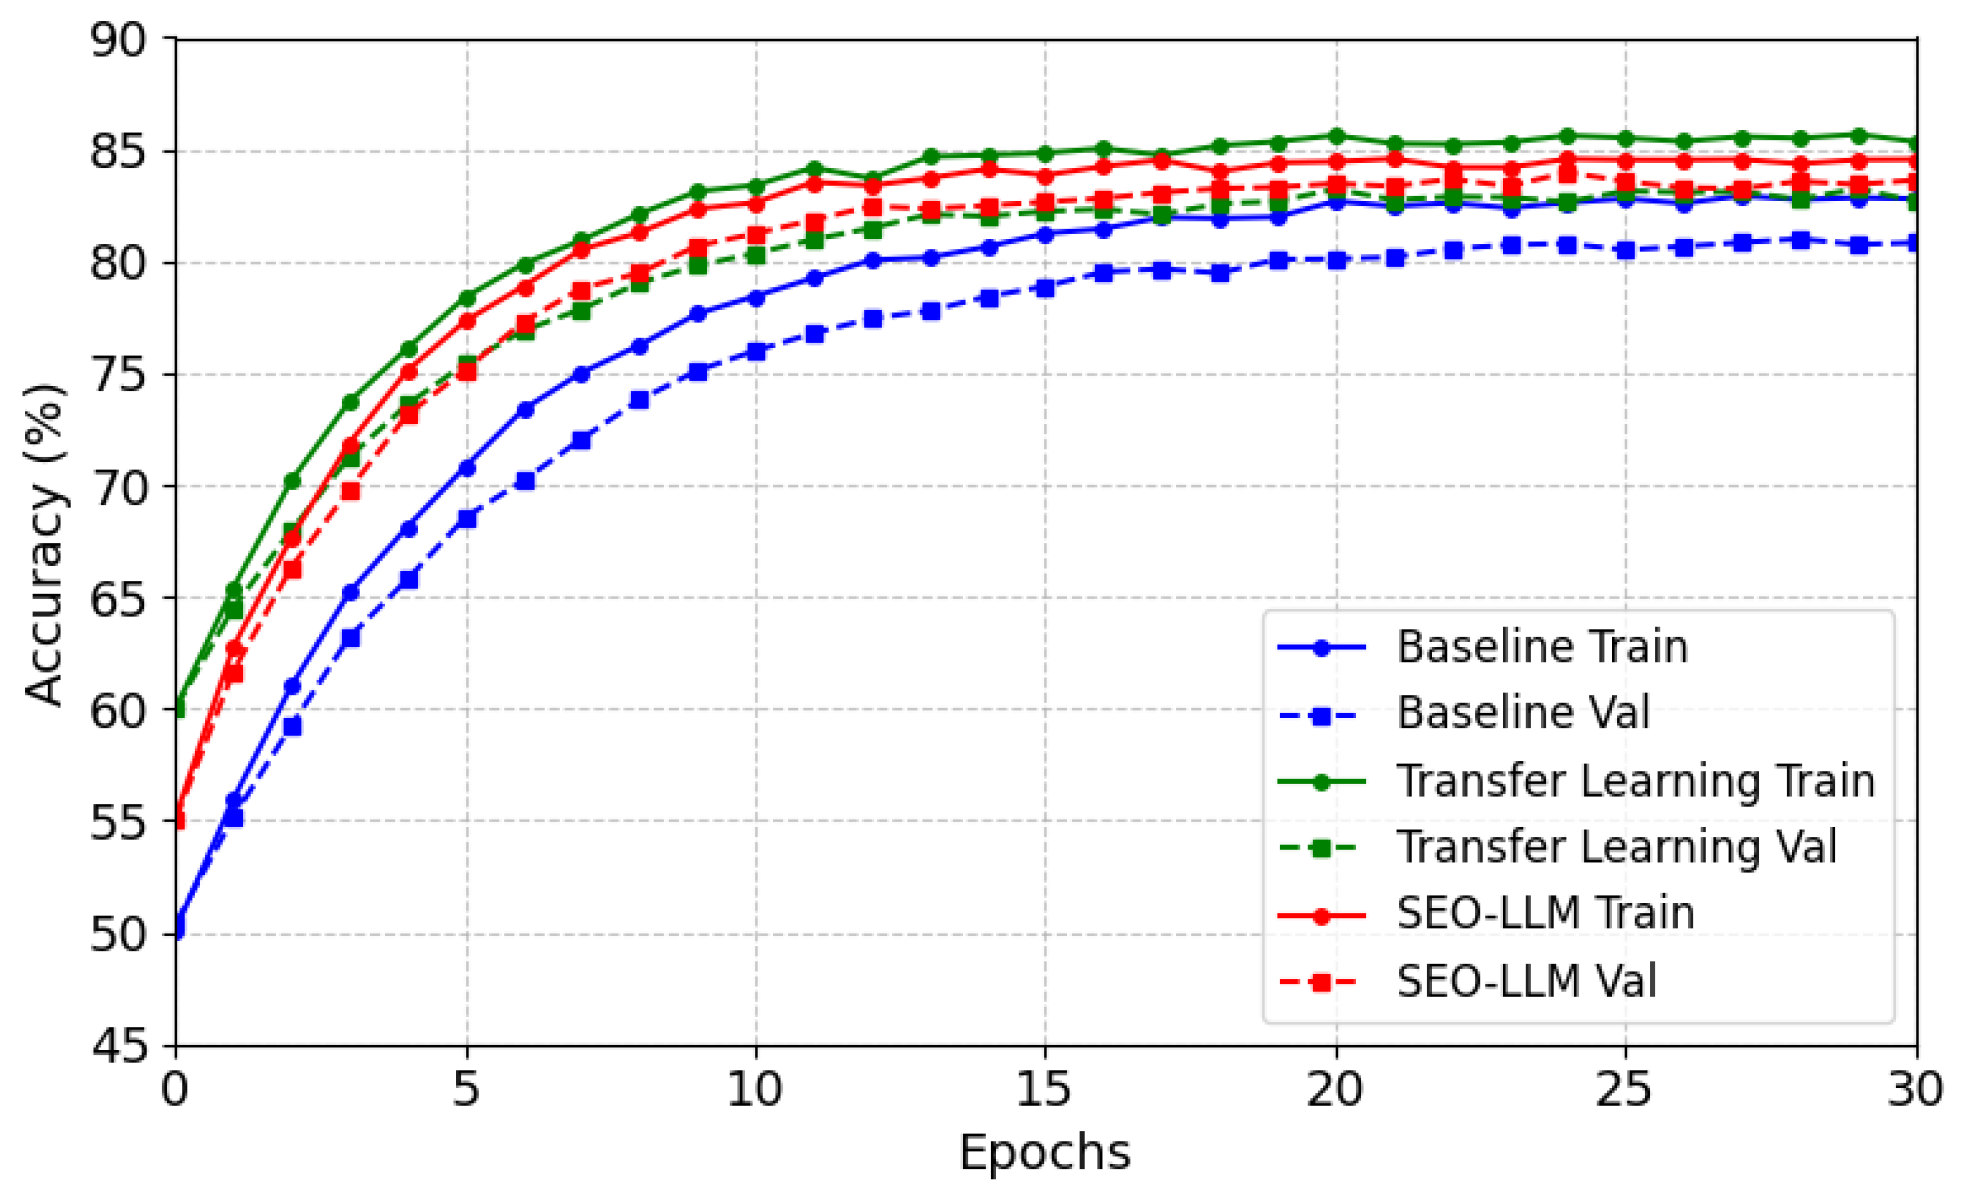
Synergized Data Efficiency and Compression (SEC) Optimization for Large ...

[PDF] A Survey on Efficient Inference for Large Language Models ...

Figure 1 from Hermes: Memory-Efficient Pipeline Inference for Large ...