
Table 4 From Rsunivlm A Unified Vision Language Model For Remote

Table 4 from RSUniVLM: A Unified Vision Language Model for Remote ...
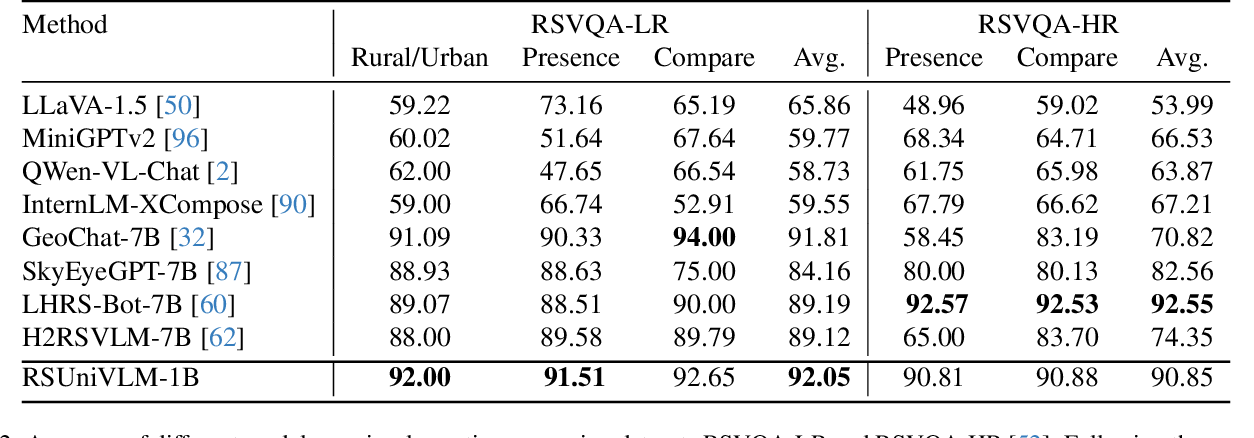
Table 2 from RSUniVLM: A Unified Vision Language Model for Remote ...

Table 11 from RSUniVLM: A Unified Vision Language Model for Remote ...
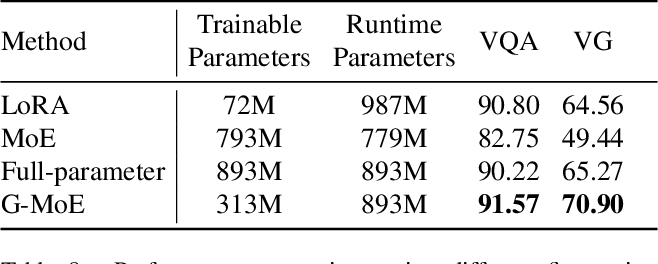
Table 8 from RSUniVLM: A Unified Vision Language Model for Remote ...

RSUniVLM: A Unified Vision Language Model for Remote Sensing via ...

RemoteCLIP: A Vision Language Foundation Model for Remote Sensing | AI ...
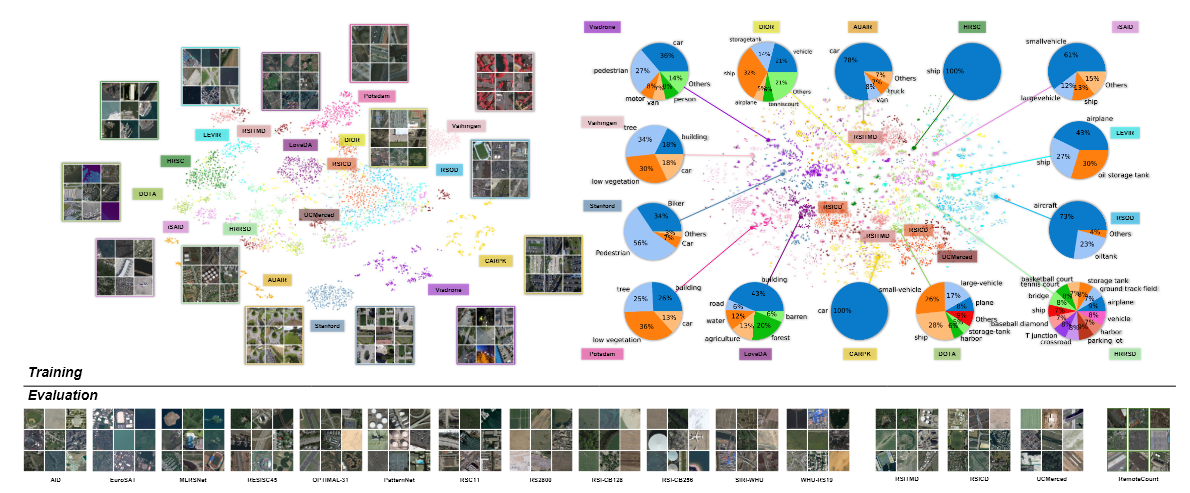
RemoteCLIP: A Vision Language Foundation Model for Remote Sensing

Figure 1 from Co-Training Vision Language Models for Remote Sensing ...

Figure 1 from LoHoVLA: A Unified Vision-Language-Action Model for Long ...

Figure 3 from NavForesee: A Unified Vision-Language World Model for ...
Advertisement Space (300x250)

Figure 2 from NavForesee: A Unified Vision-Language World Model for ...

Table 1 from Modeling Cross-vision Synergy for Unified Large Vision ...
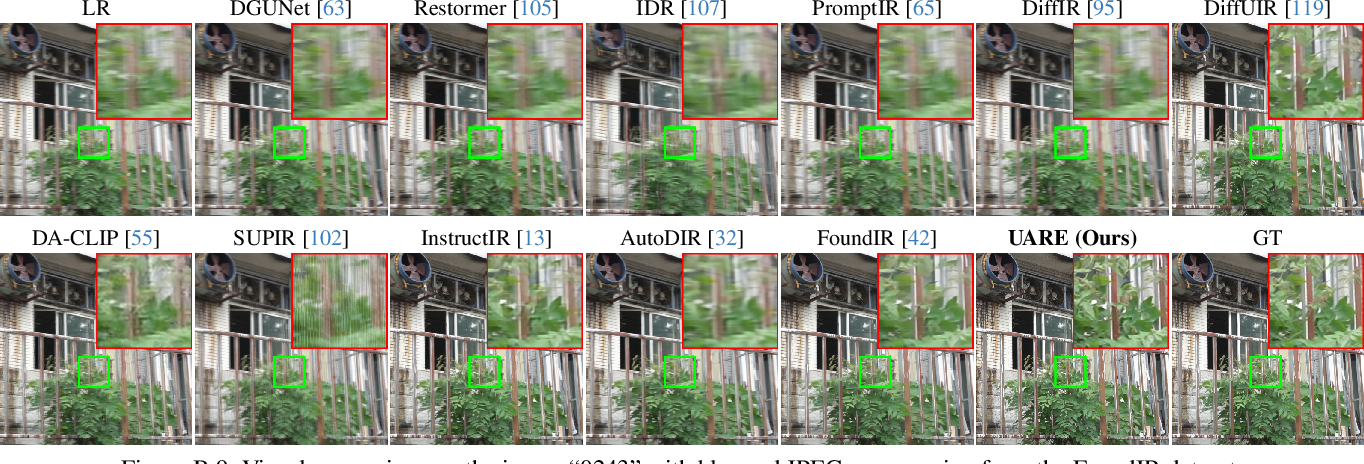
Figure B.9 from UARE: A Unified Vision-Language Model for Image Quality ...

VLM-RL: A Unified Vision Language Models and Reinforcement Learning ...

VLM-RRT: Vision Language Model Guided RRT Search for Autonomous UAV ...

Table I from Enhancing Remote Sensing Vision-Language Models for Zero ...
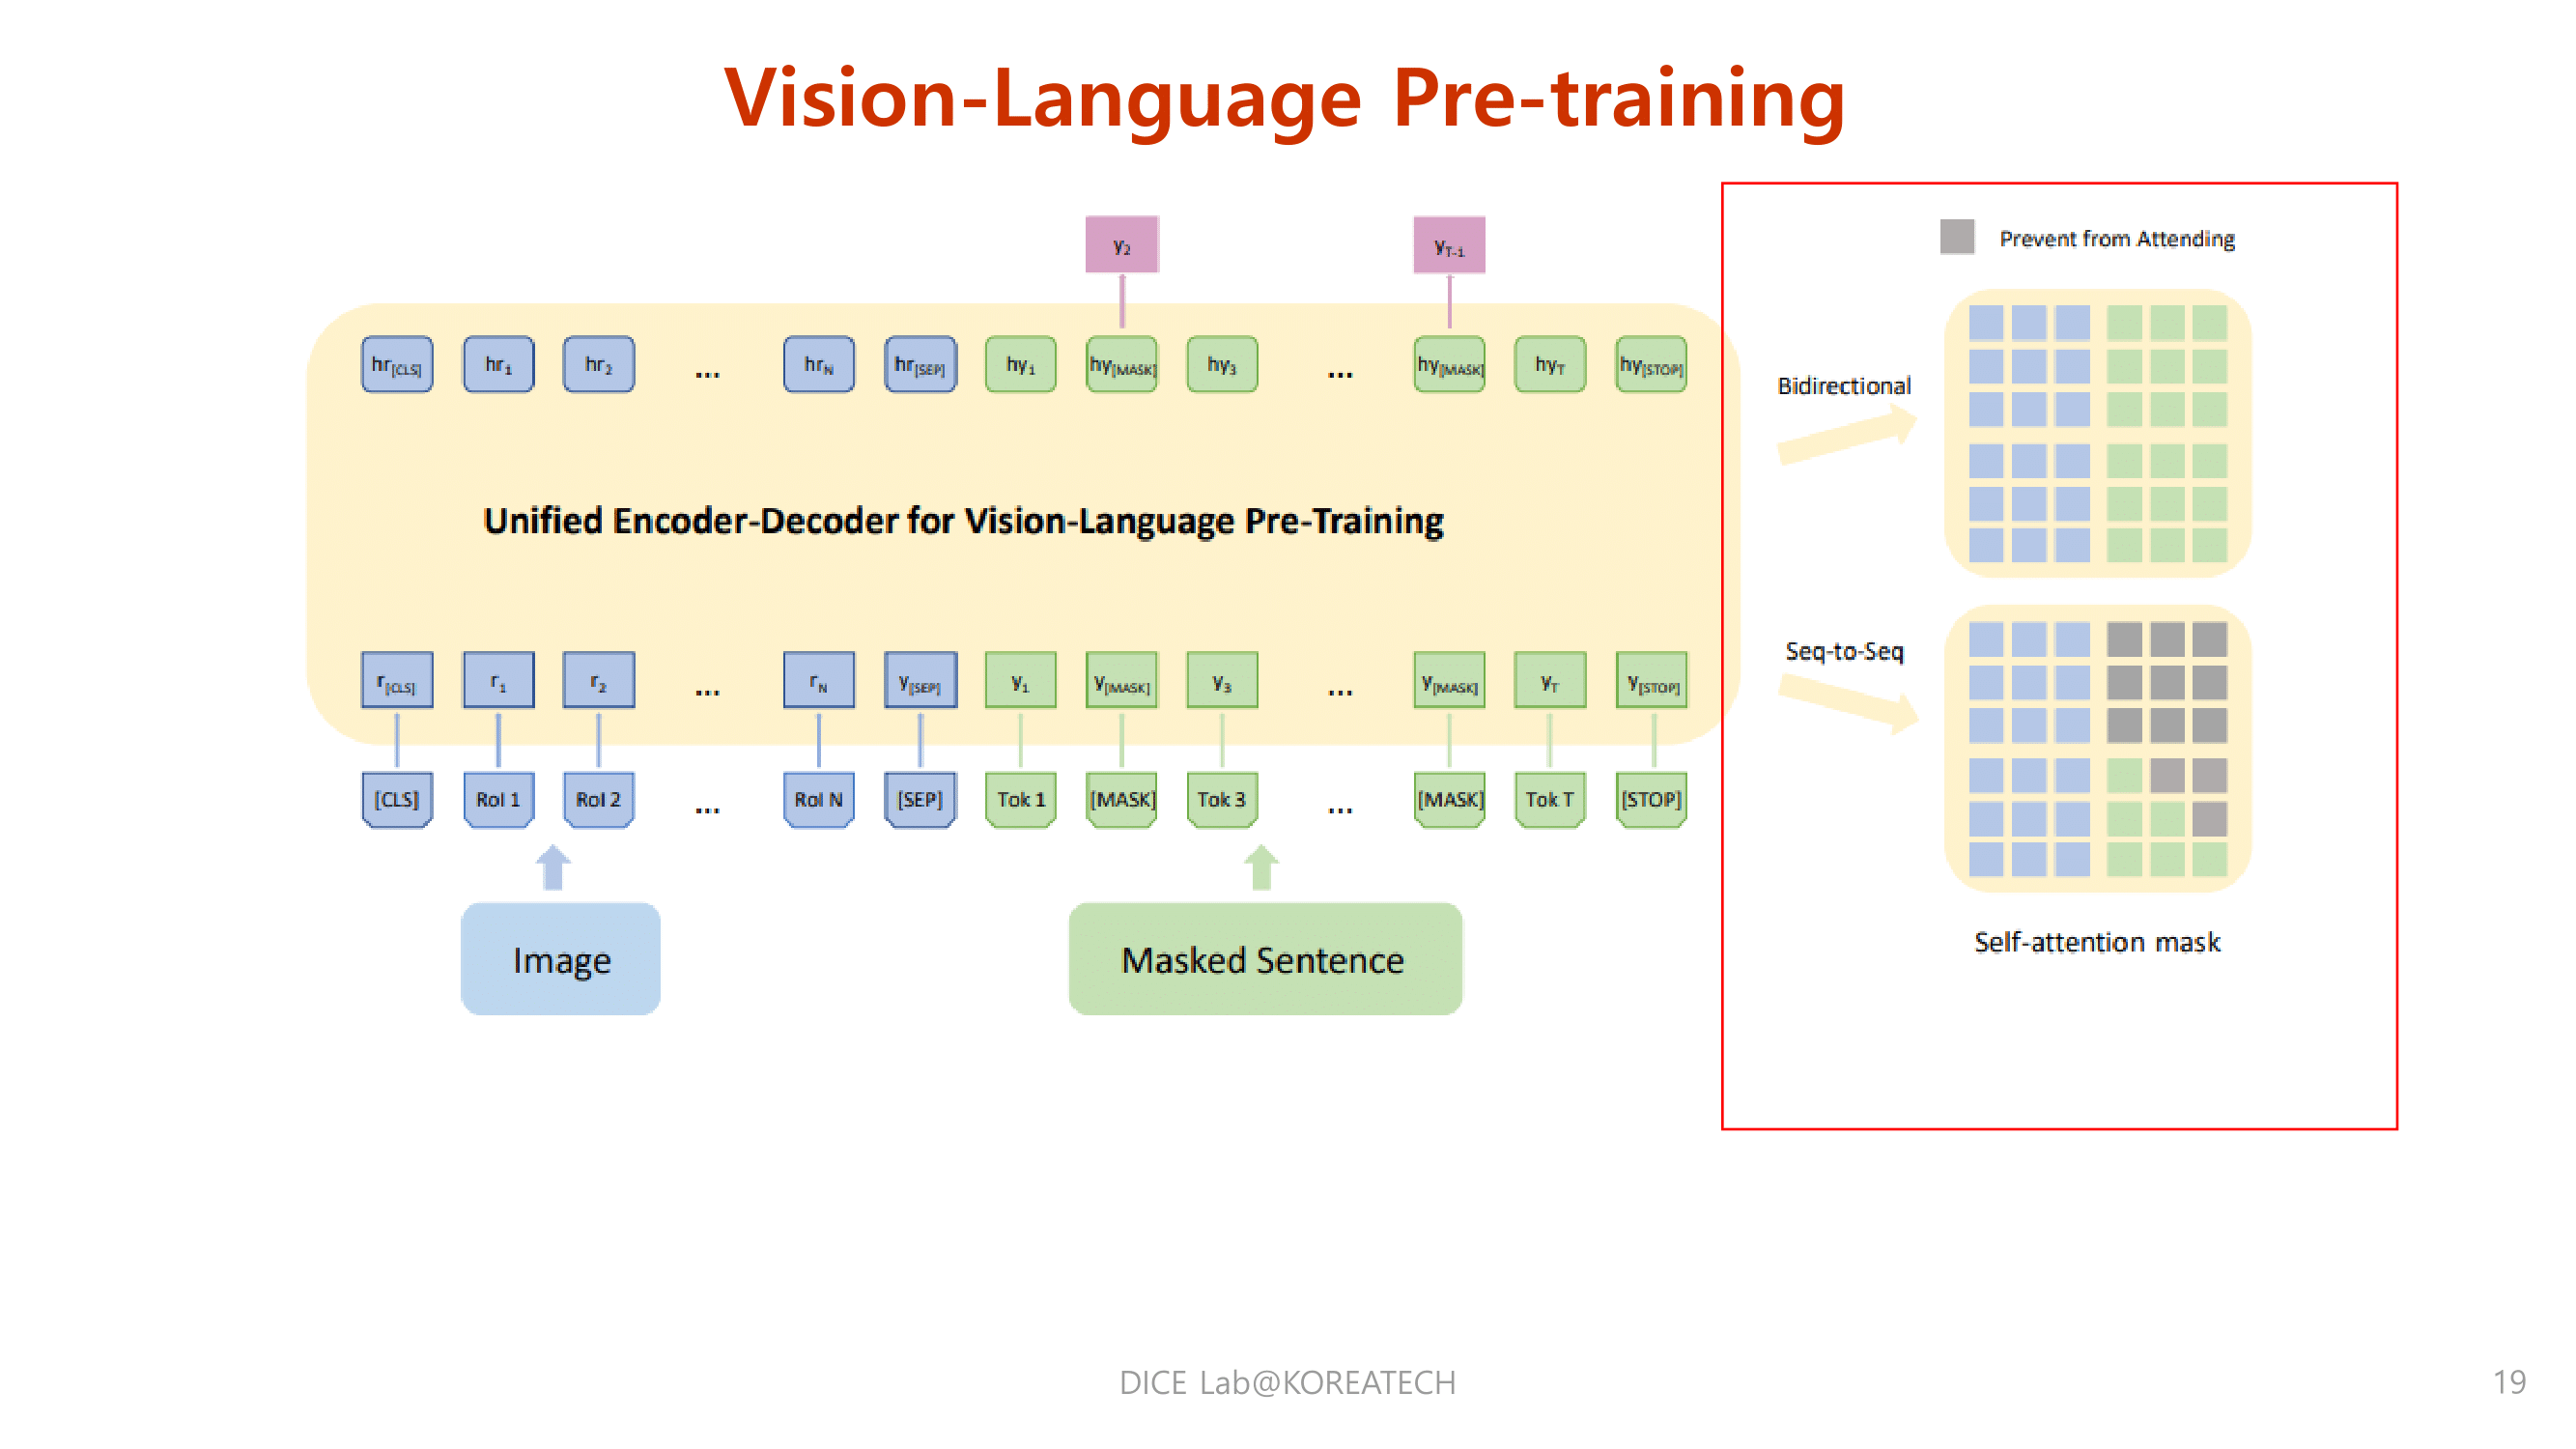
Paper Review. Unified Vision Language Pre-Training for Image Captioning ...
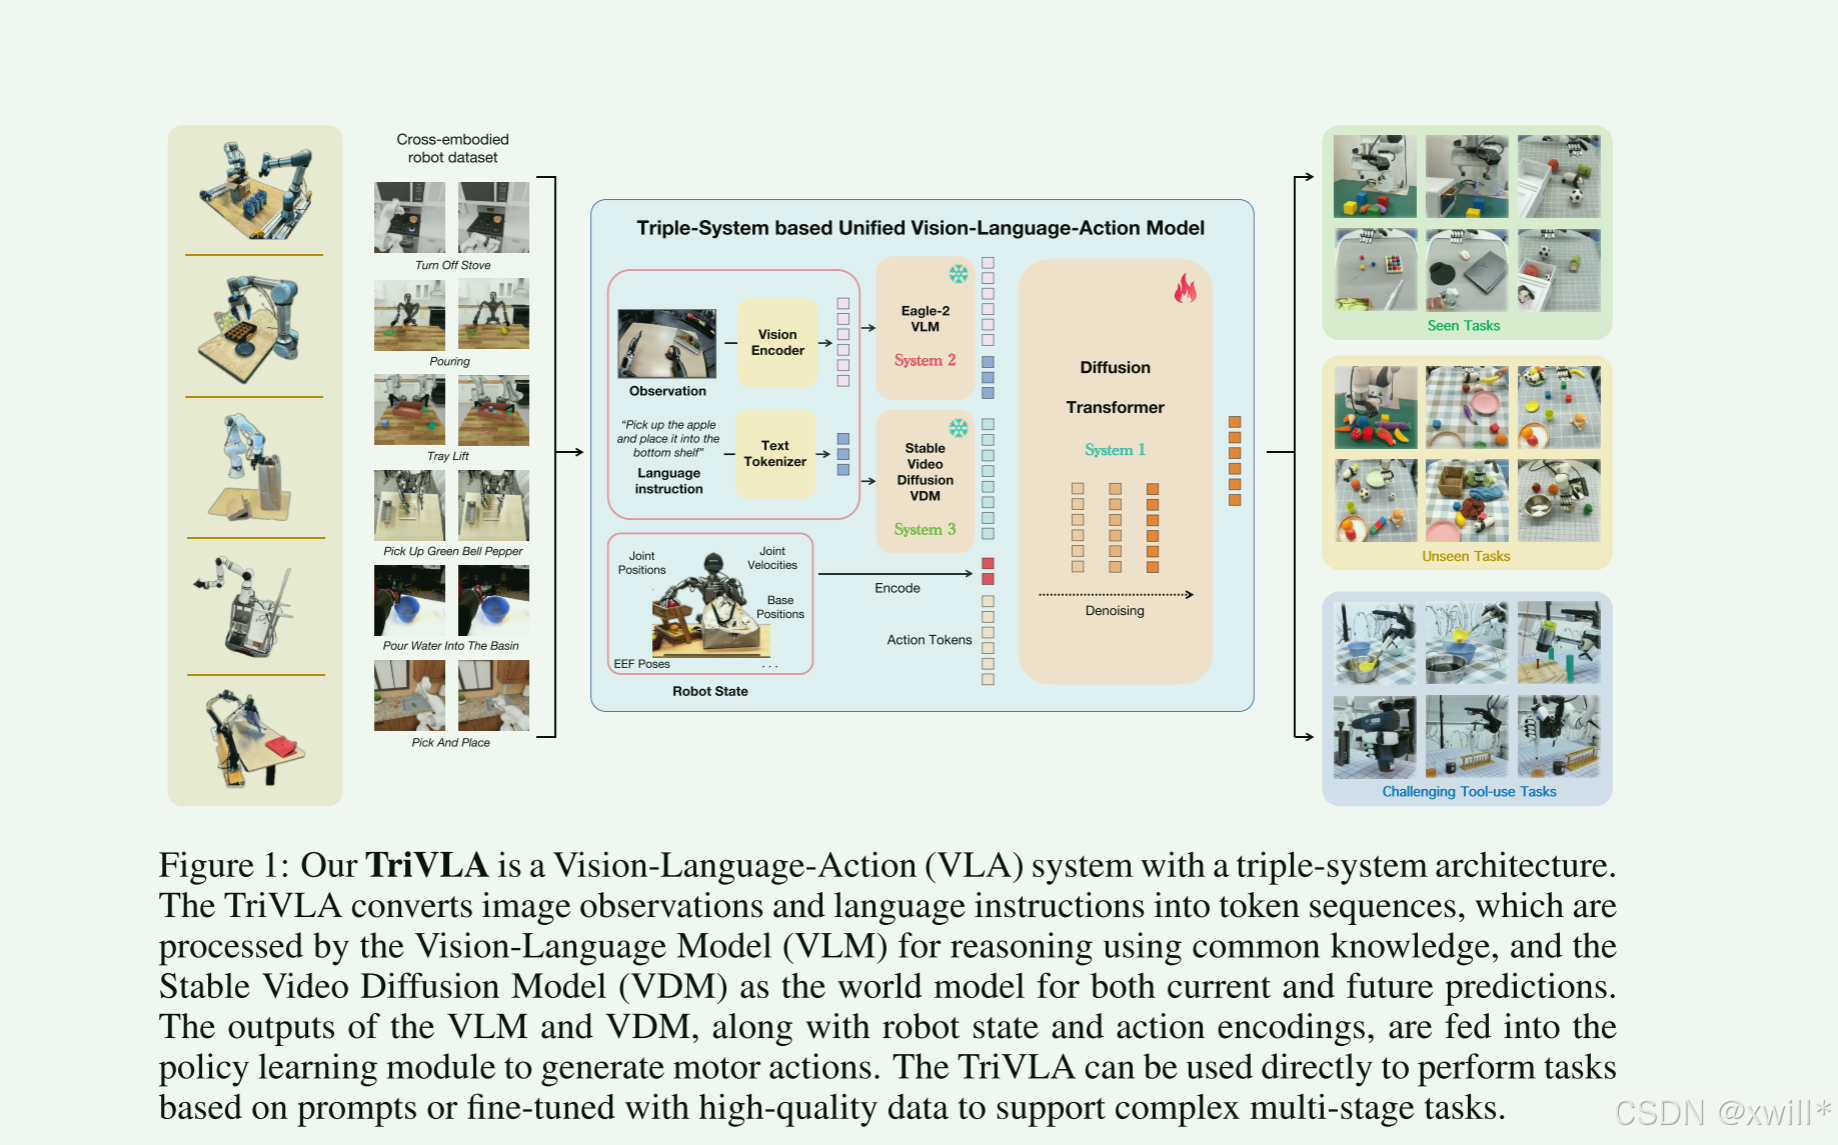
TRIVLA: A TRIPLE-SYSTEM-BASED UNIFIED VISION-LANGUAGE-ACTION MODEL FOR ...

(PDF) Towards Unified Vision Language Models for Forest Ecological ...

Paper page - VLM-RL: A Unified Vision Language Models and Reinforcement ...
Advertisement Space (336x280)
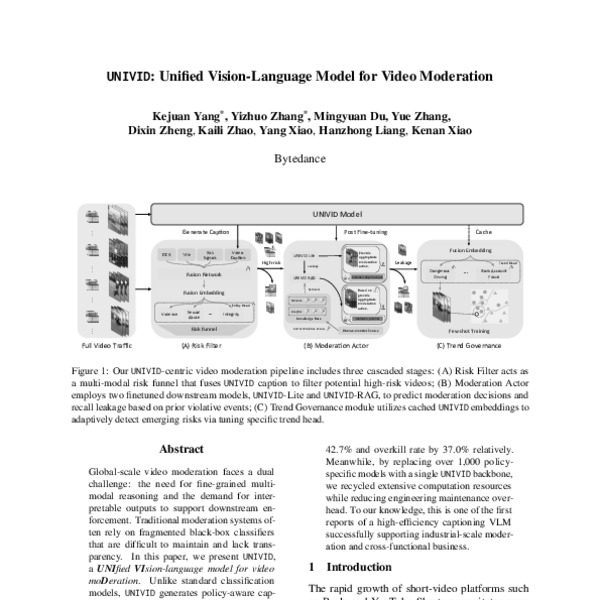
UNIVID: Unified Vision-Language Model for Video Moderation - ACL Anthology

FUSE-RSVLM: Feature Fusion Vision-Language Model for Remote Sensing ...

(PDF) RynnVLA-002: A Unified Vision-Language-Action and World Model
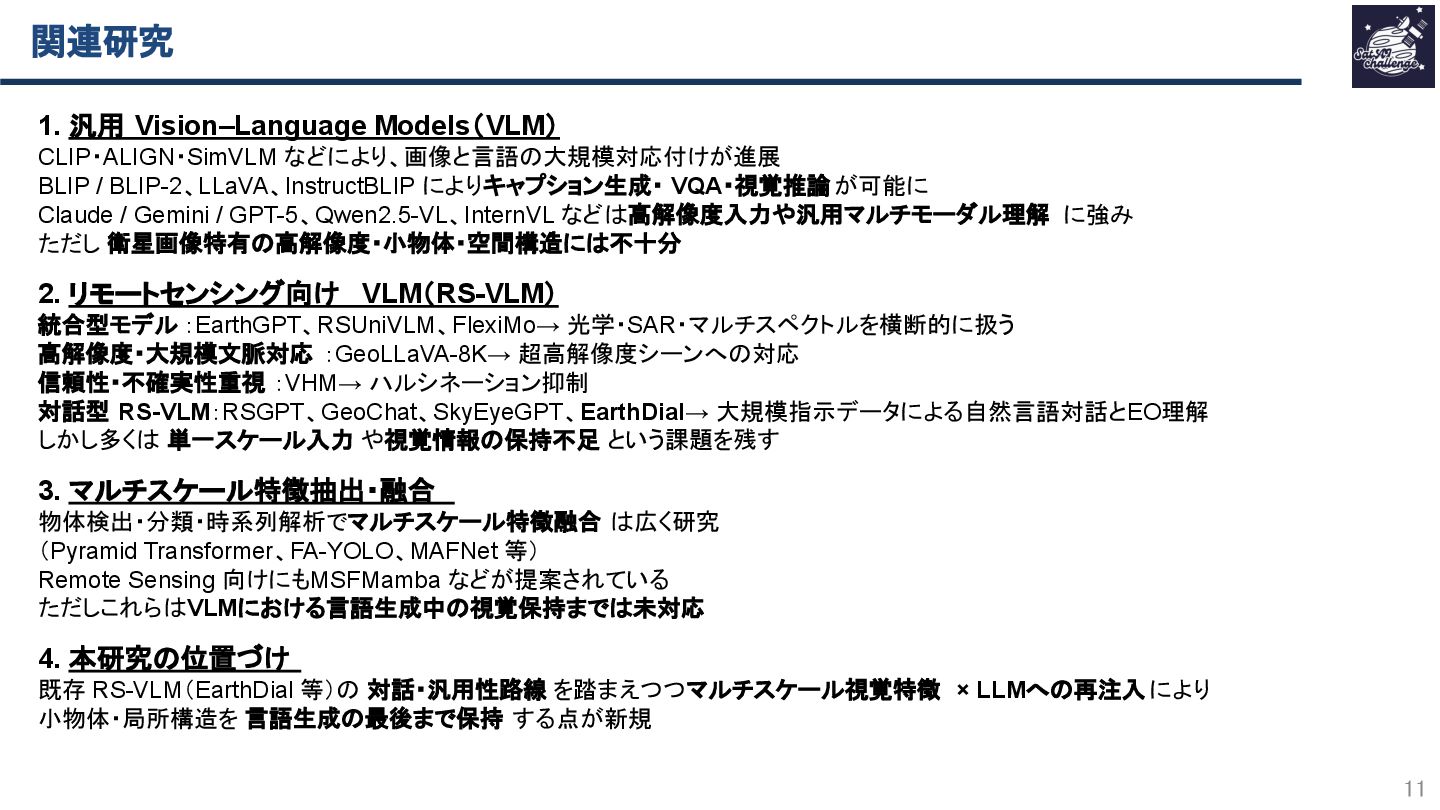
FUSE-RSVLM: Feature Fusion Vision-Language Model for Remote Sensing ...

[2511.17502] RynnVLA-002: A Unified Vision-Language-Action and World Model

FUSE-RSVLM: Feature Fusion Vision-Language Model for Remote Sensing ...
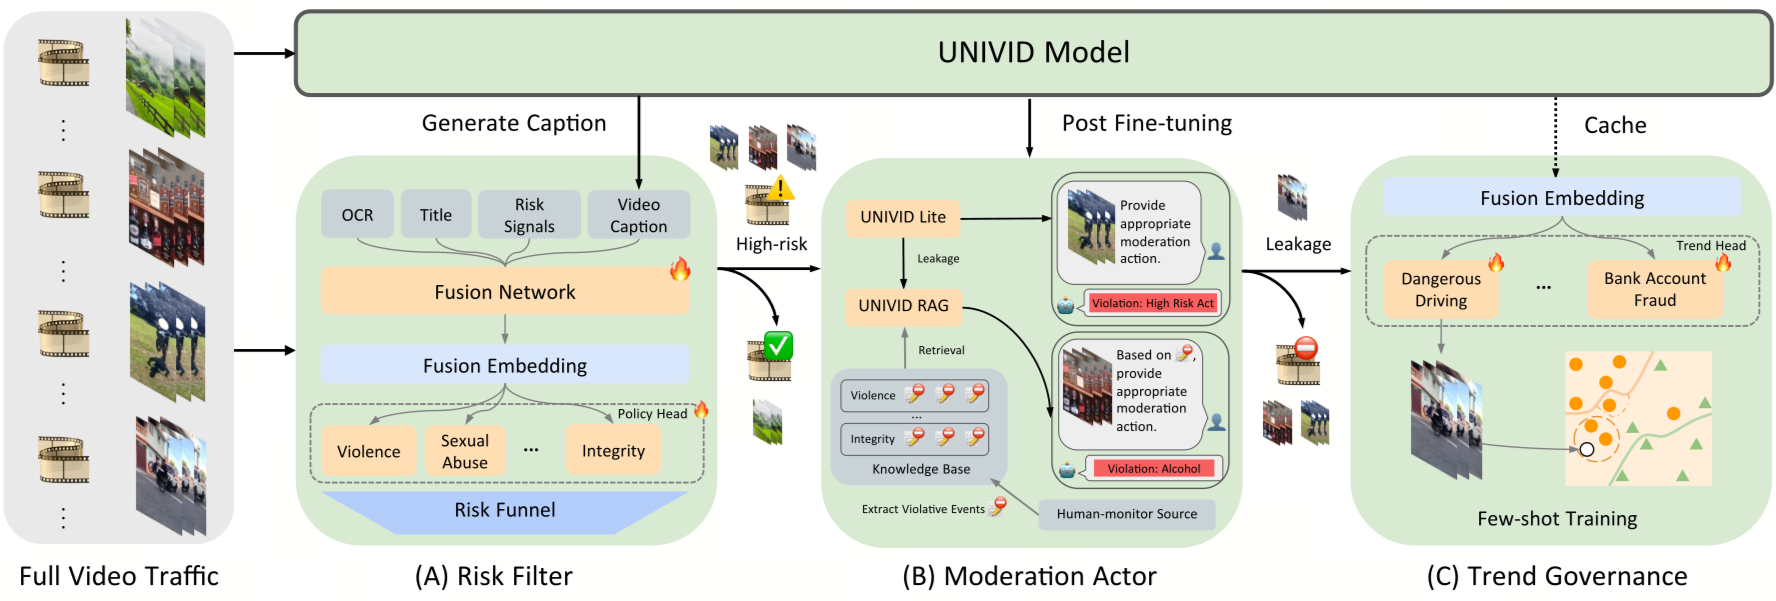
[Literature Review] UNIVID: Unified Vision-Language Model for Video ...
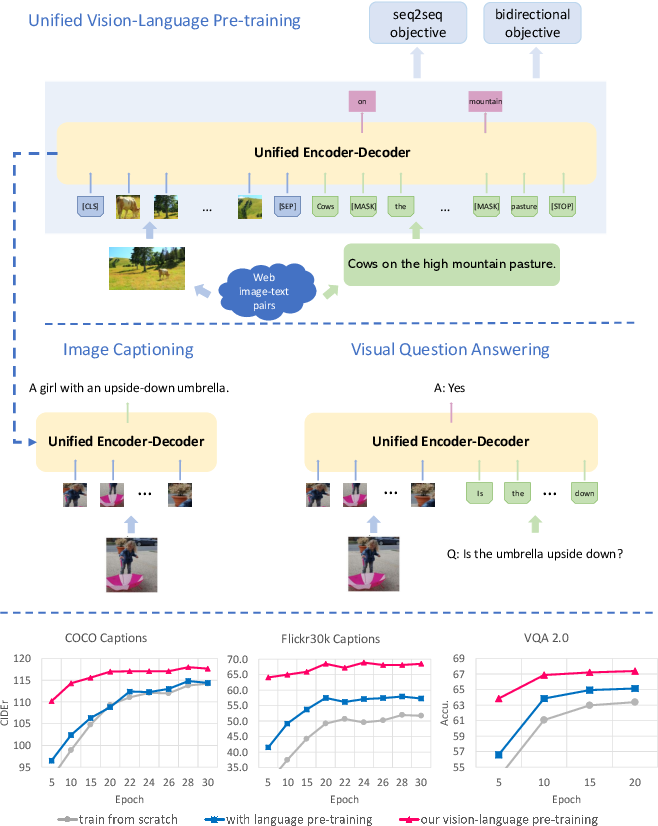
Figure 1 from Unified Vision-Language Pre-Training for Image Captioning ...

(PDF) RS-LLaVA: A Large Vision-Language Model for Joint Captioning and ...
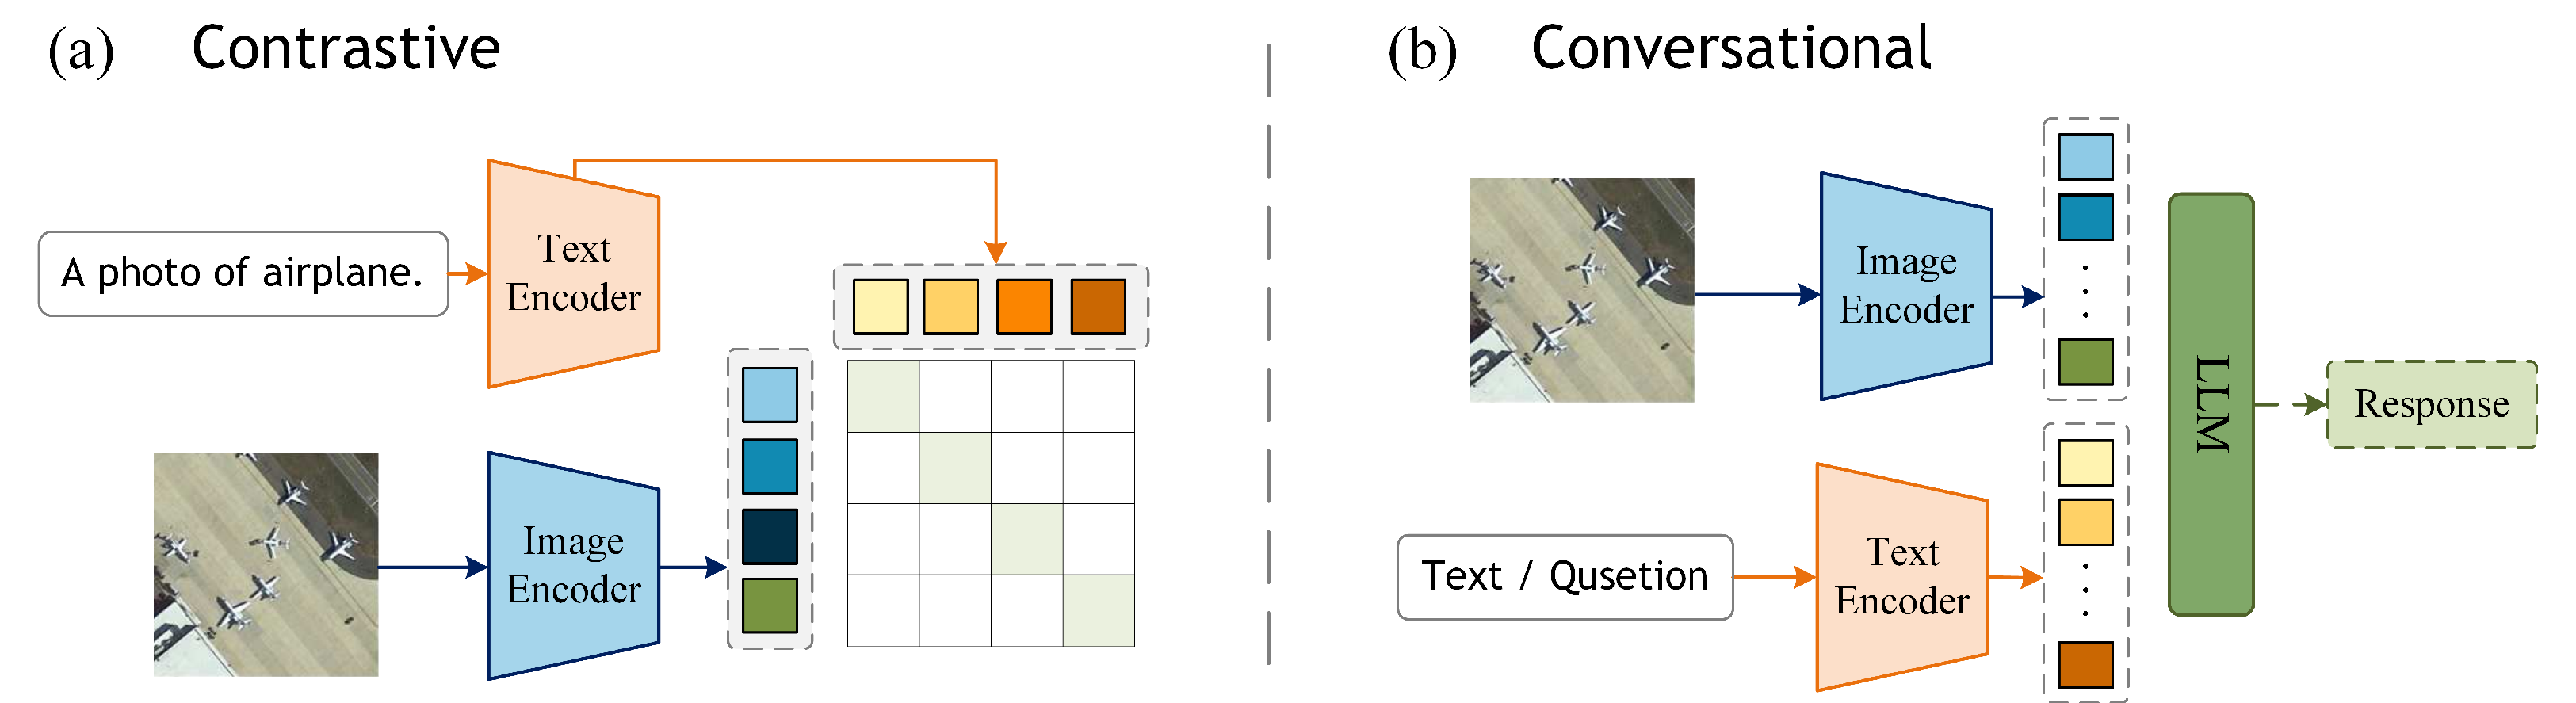
Vision–Language Models for Remote Sensing: A New Era of Multimodal ...
Advertisement Space (336x280)

[论文评述] UVLM: A Universal Vision-Language Model Loader for Reproducible ...
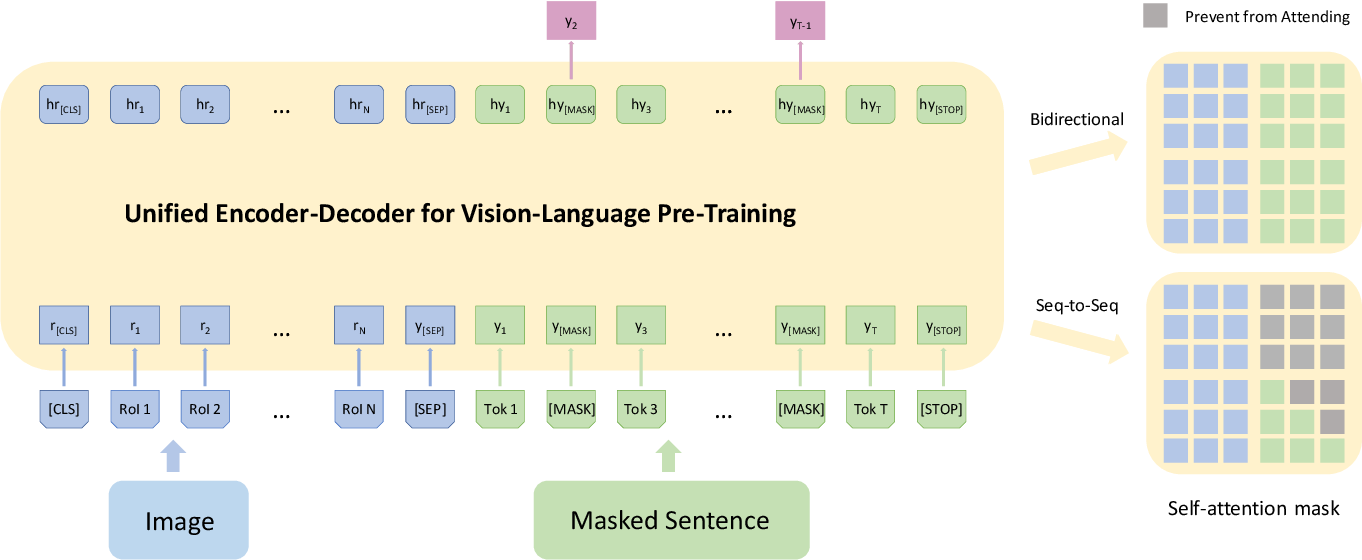
Figure 2 from Unified Vision-Language Pre-Training for Image Captioning ...

UNIFIED VISION AND LANGUAGE PROMPT LEARNING-CSDN博客

Vision-Language Models for Vision Tasks: A Survey - 知乎

HuBo-VLM: Unified Vision-Language Model designed for HUman roBOt ...

Vision-Language Models for Vision Tasks: A Survey - 知乎