
Table 6 From End To End Video Text Spotting With Transformer Semantic

Table 6 from End-to-End Video Text Spotting with Transformer | Semantic ...

Table 4 from Towards Accurate Video Text Spotting with Text-wise ...

Figure 2 from Text Spotting with a Unified Transformer Decoder ...

(PDF) End-to-End Video Text Spotting with Transformer

End-to-End Video Text Spotting with Transformer

Figure 1 from Towards Accurate Video Text Spotting with Text-wise ...
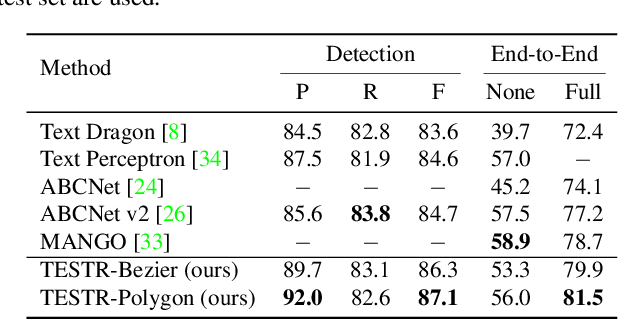
Table 2 from Text Spotting Transformers | Semantic Scholar
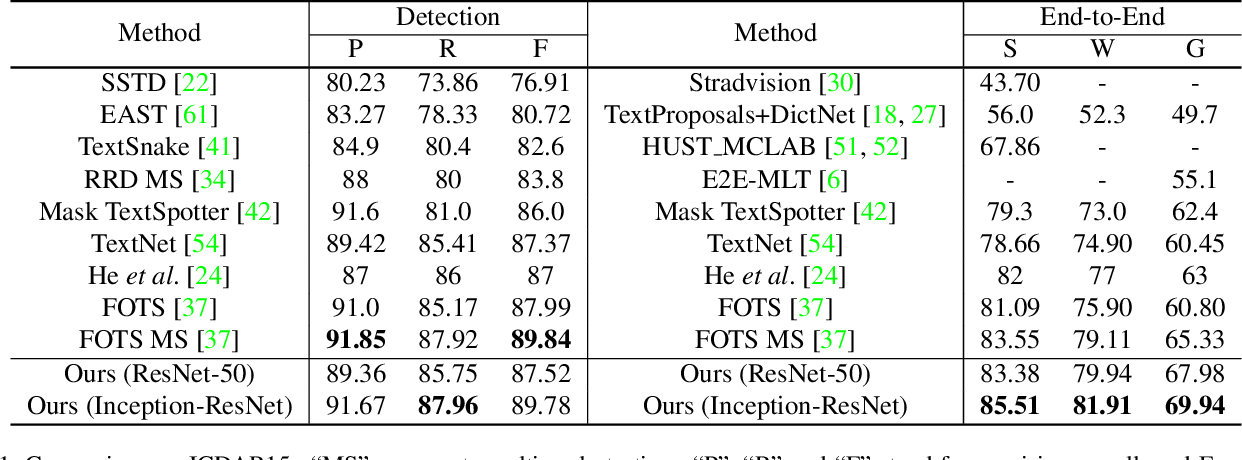
Table 1 from Towards Unconstrained End-to-End Text Spotting | Semantic ...

Figure 3 from Towards Accurate Video Text Spotting with Text-wise ...

Table 1 from Towards End-to-End Text Spotting with Convolutional ...
Advertisement Space (300x250)
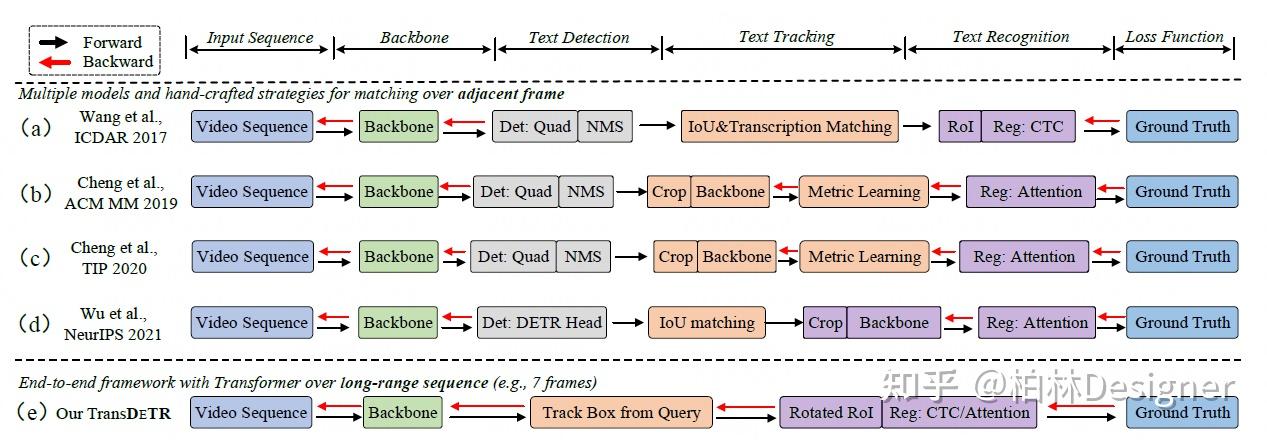
End-to-end Video Text Spotting with Transformer(一种草鸡简单的pipeline) - 知乎

Table 6 from Bridging the Gap Between End-to-End and Two-Step Text ...
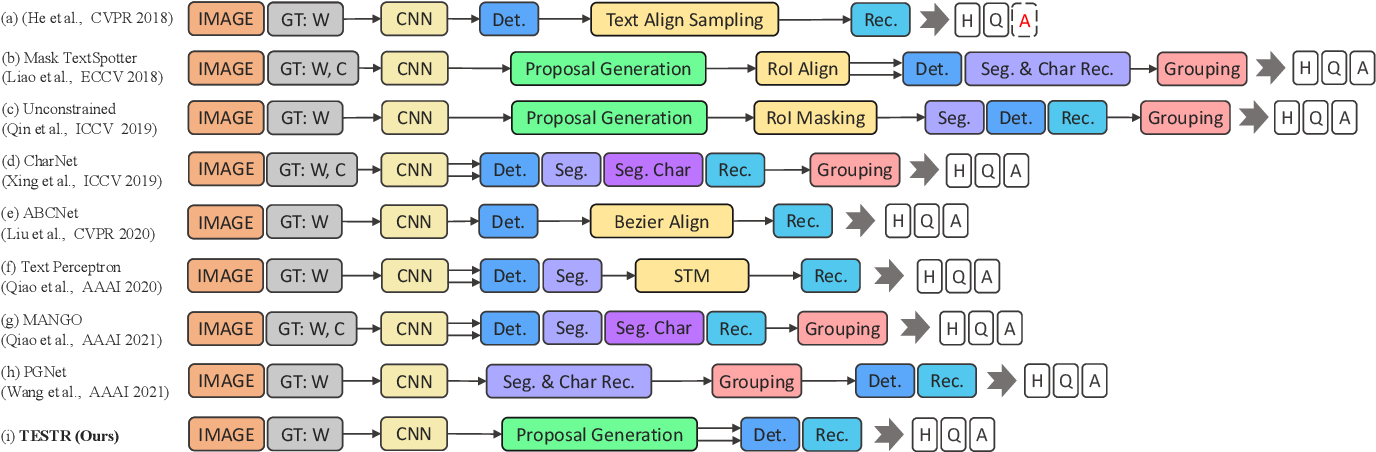
Figure 2 from Text Spotting Transformers | Semantic Scholar

Figure 5 from Towards End-to-End Text Spotting with Convolutional ...
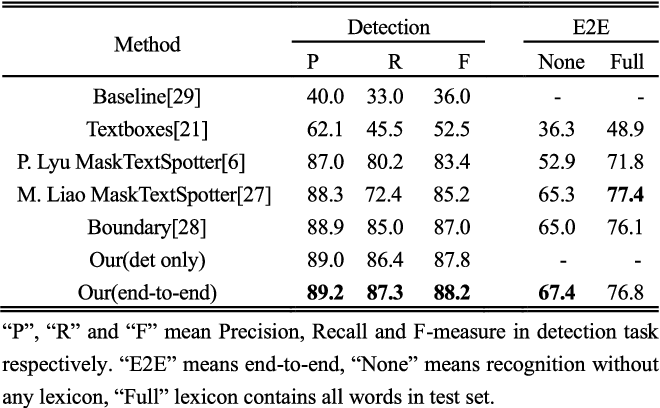
Table 1 from Toward Arbitrary-Shaped Text Spotting Based on End-to-End ...
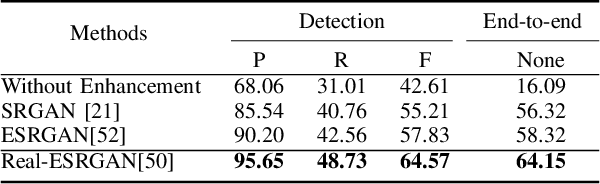
Table VI from Diving into the Depths of Spotting Text in Multi-Domain ...
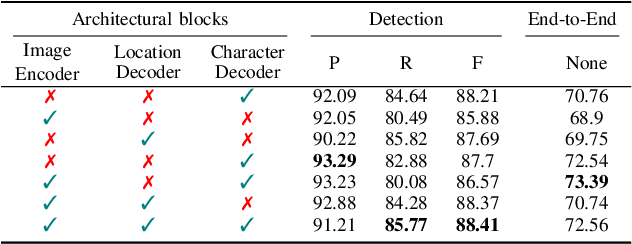
Table VII from Diving into the Depths of Spotting Text in Multi-Domain ...

Table 2 from SwinTextSpotter: Scene Text Spotting via Better Synergy ...

Table V from Diving into the Depths of Spotting Text in Multi-Domain ...
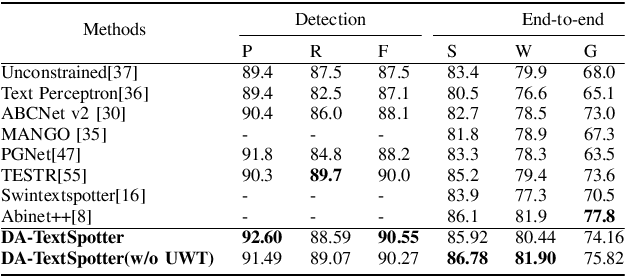
Table II from Diving into the Depths of Spotting Text in Multi-Domain ...
Advertisement Space (336x280)

Table 1 from Towards Weakly-Supervised Text Spotting using a Multi-Task ...
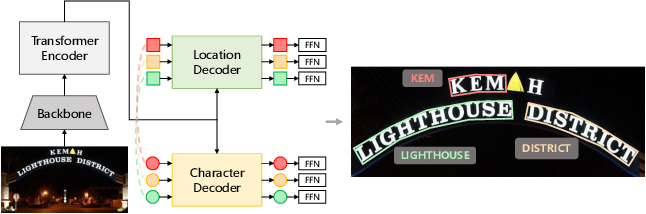
Figure 1 from Text Spotting Transformers | Semantic Scholar
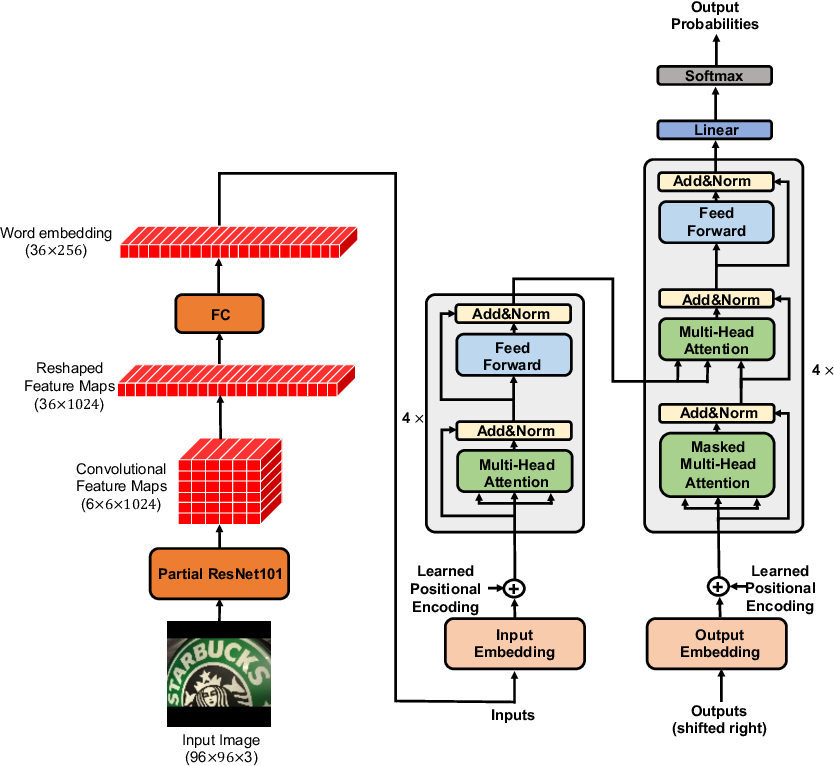
Figure 2 from Scene Text Recognition via Transformer | Semantic Scholar

Table 1 from SwinTextSpotter: Scene Text Spotting via Better Synergy ...

Table 11 from DeepSolo++: Let Transformer Decoder with Explicit Points ...
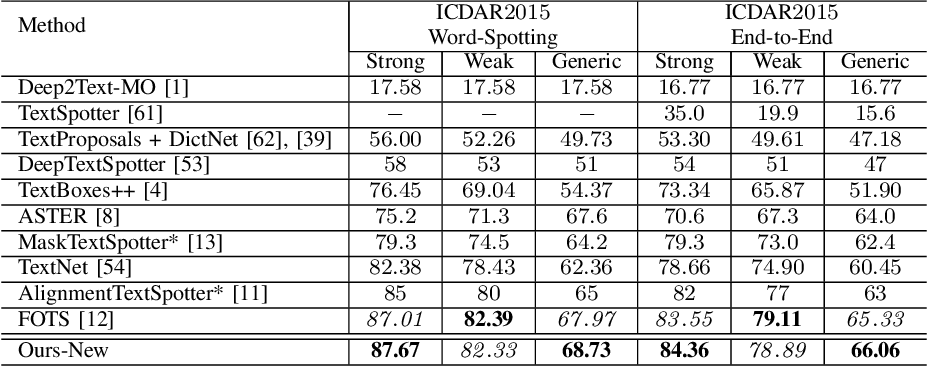
Table III from Towards End-to-End Text Spotting in Natural Scenes ...
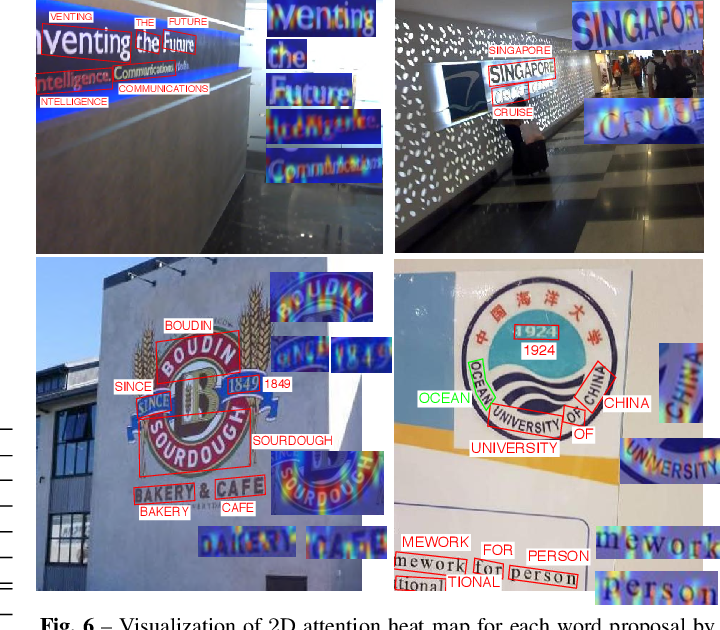
Figure 6 from Towards End-to-End Text Spotting in Natural Scenes ...
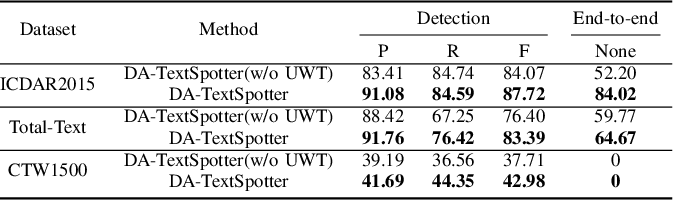
Table IV from Diving into the Depths of Spotting Text in Multi-Domain ...
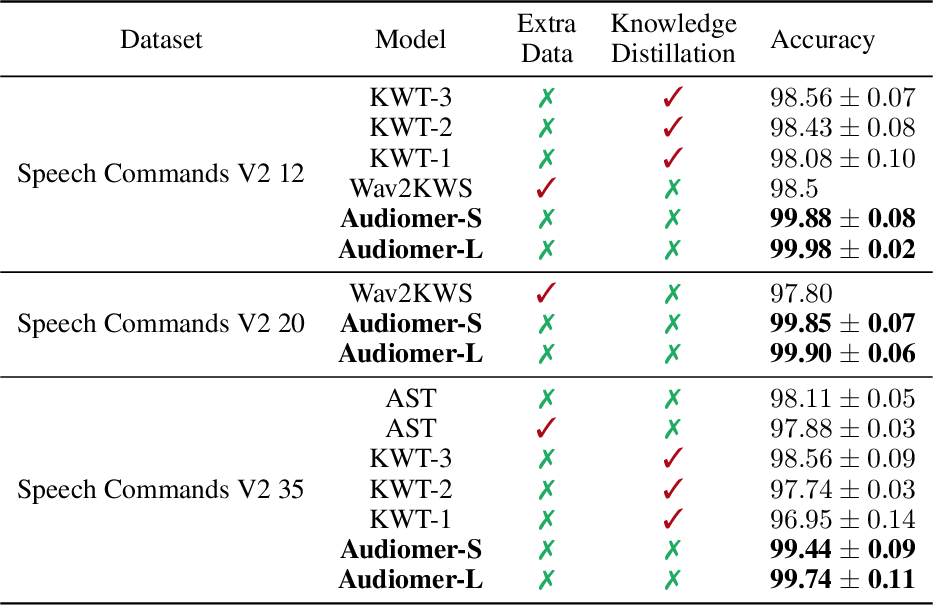
Table 1 from Audiomer: A Convolutional Transformer for Keyword Spotting ...

Table 1 from Scene Text Segmentation via Multi-Task Cascade Transformer ...
Advertisement Space (336x280)

Table 2 from Synthetic Data Generation for Text Spotting on Printed ...

Table 3 from Bridging the Gap Between End-to-End and Two-Step Text ...

Figure 2 from Towards Weakly-Supervised Text Spotting using a Multi ...

【论文笔记】End-to-End Text Spotting Transformer 系列之TTS模型 - 知乎
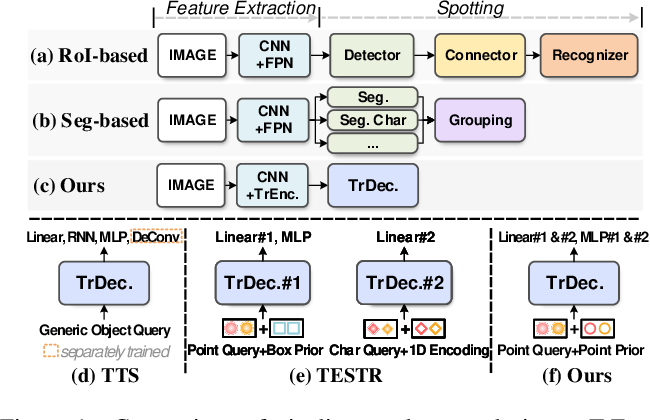
DeepSolo: Let Transformer Decoder with Explicit Points Solo for Text ...

Figure 1 from Diving into the Depths of Spotting Text in Multi-Domain ...