
Techniques For Kv Cache Optimization In Large Language Models
Techniques for KV Cache Optimization in Large Language Models
Techniques for KV Cache Optimization in Large Language Models
Techniques for KV Cache Optimization in Large Language Models
Techniques for KV Cache Optimization in Large Language Models
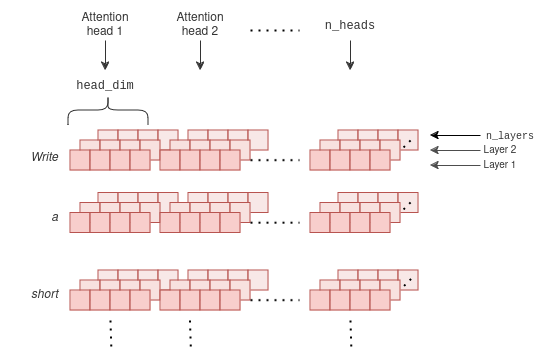
Techniques for KV Cache Optimization in Large Language Models
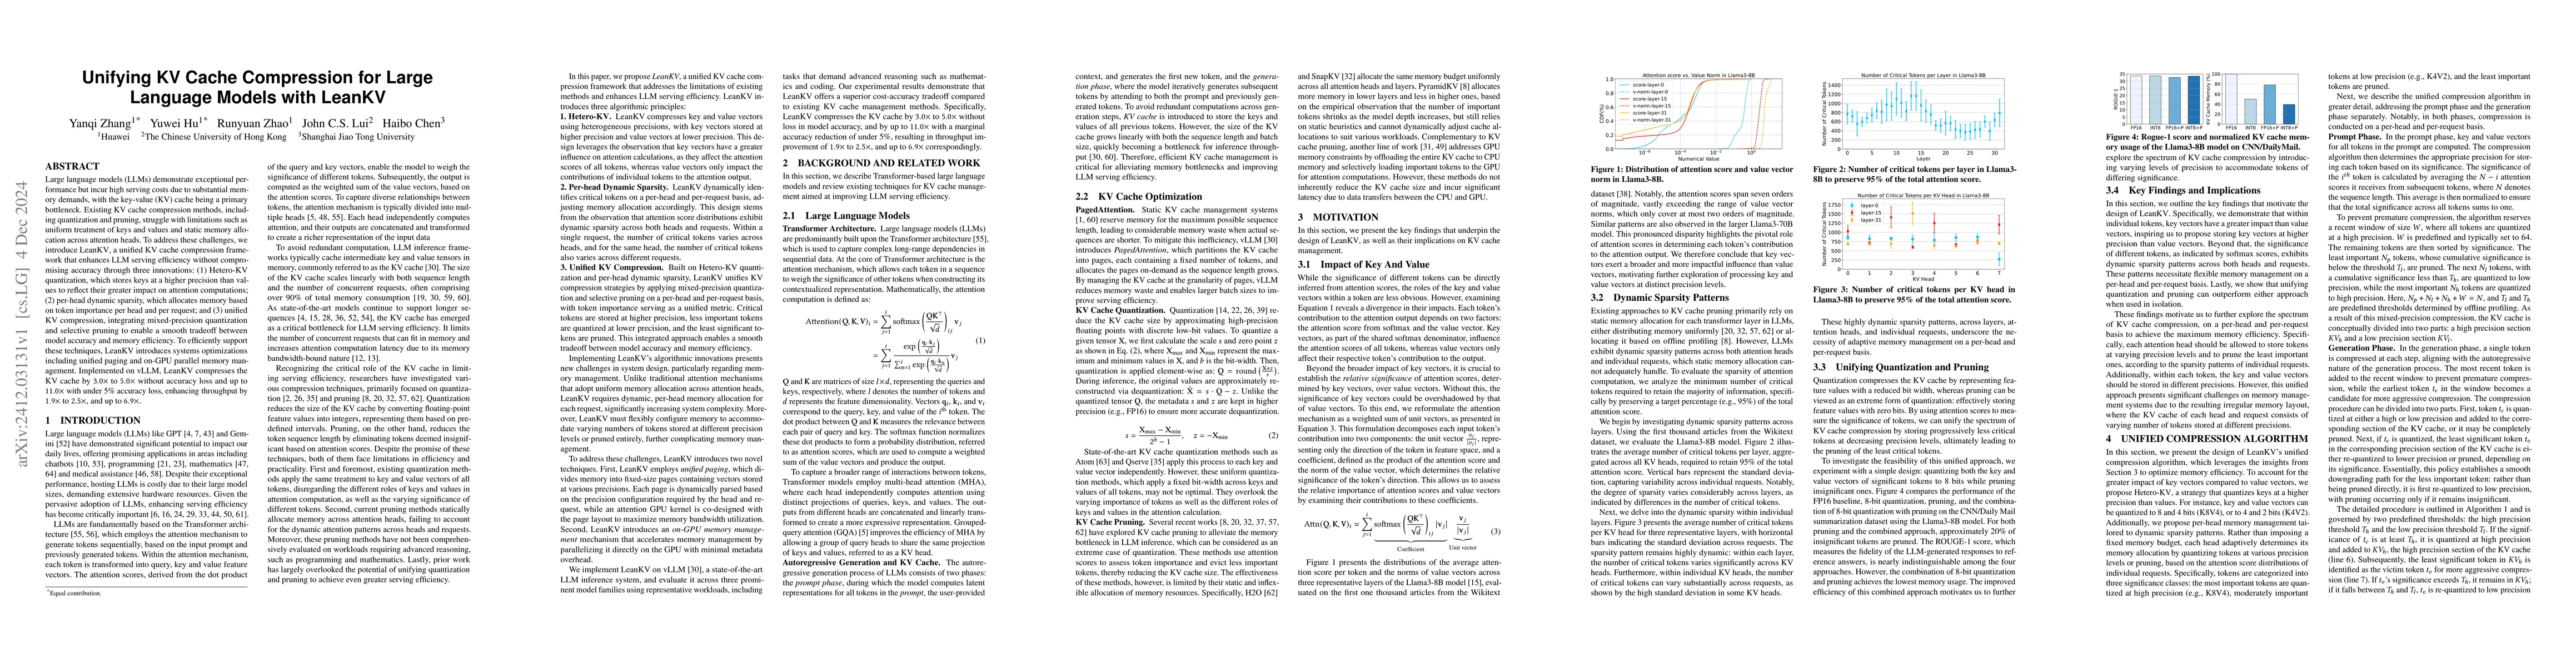
Unifying KV Cache Compression for Large Language Models with LeanKV ...

[논문 리뷰] Unifying KV Cache Compression for Large Language Models with LeanKV

A Method for Building Large Language Models with Predefined KV Cache ...

Layer-Condensed KV Cache for Efficient Inference of Large Language Models

Rethinking Key-Value Cache Compression Techniques for Large Language ...
Advertisement Space (300x250)

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...

KV Cache Demystified: Speeding Up Large Language Models - YouTube

[论文评述] MiniCache: KV Cache Compression in Depth Dimension for Large ...

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

KV Cache in Large Language Models: Design, Optimization, and Inference ...
How KV Caching Works in Large Language Models | MatterAI Blog

KV Cache in Large Language Models: Design, Optimization, and Inference ...

Optimizing KV Cache for Faster Large Language Model Processing | Course ...
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

Layer-Condensed KV Cache for Efficient Inference of Large Language ...
Advertisement Space (336x280)

KV Cache 101: How Large Language Models Remember and Reuse Information ...
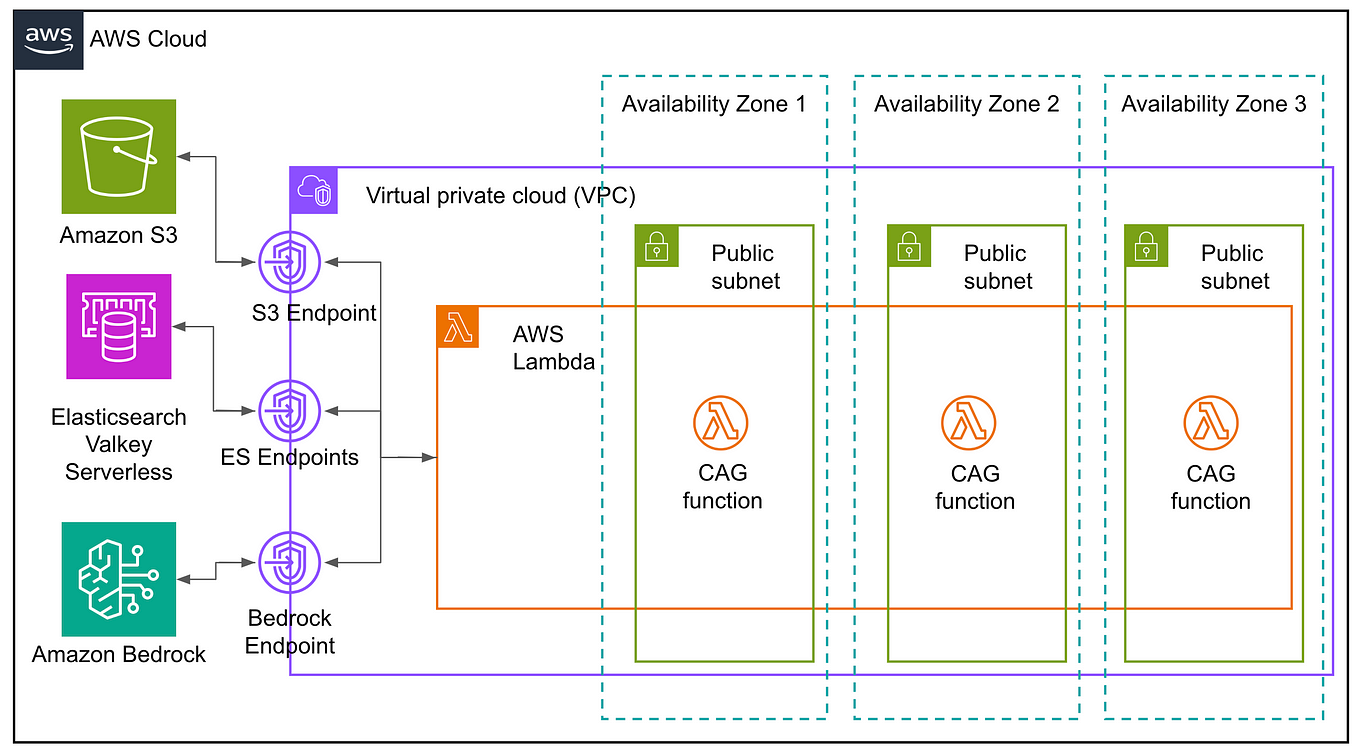
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...

Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
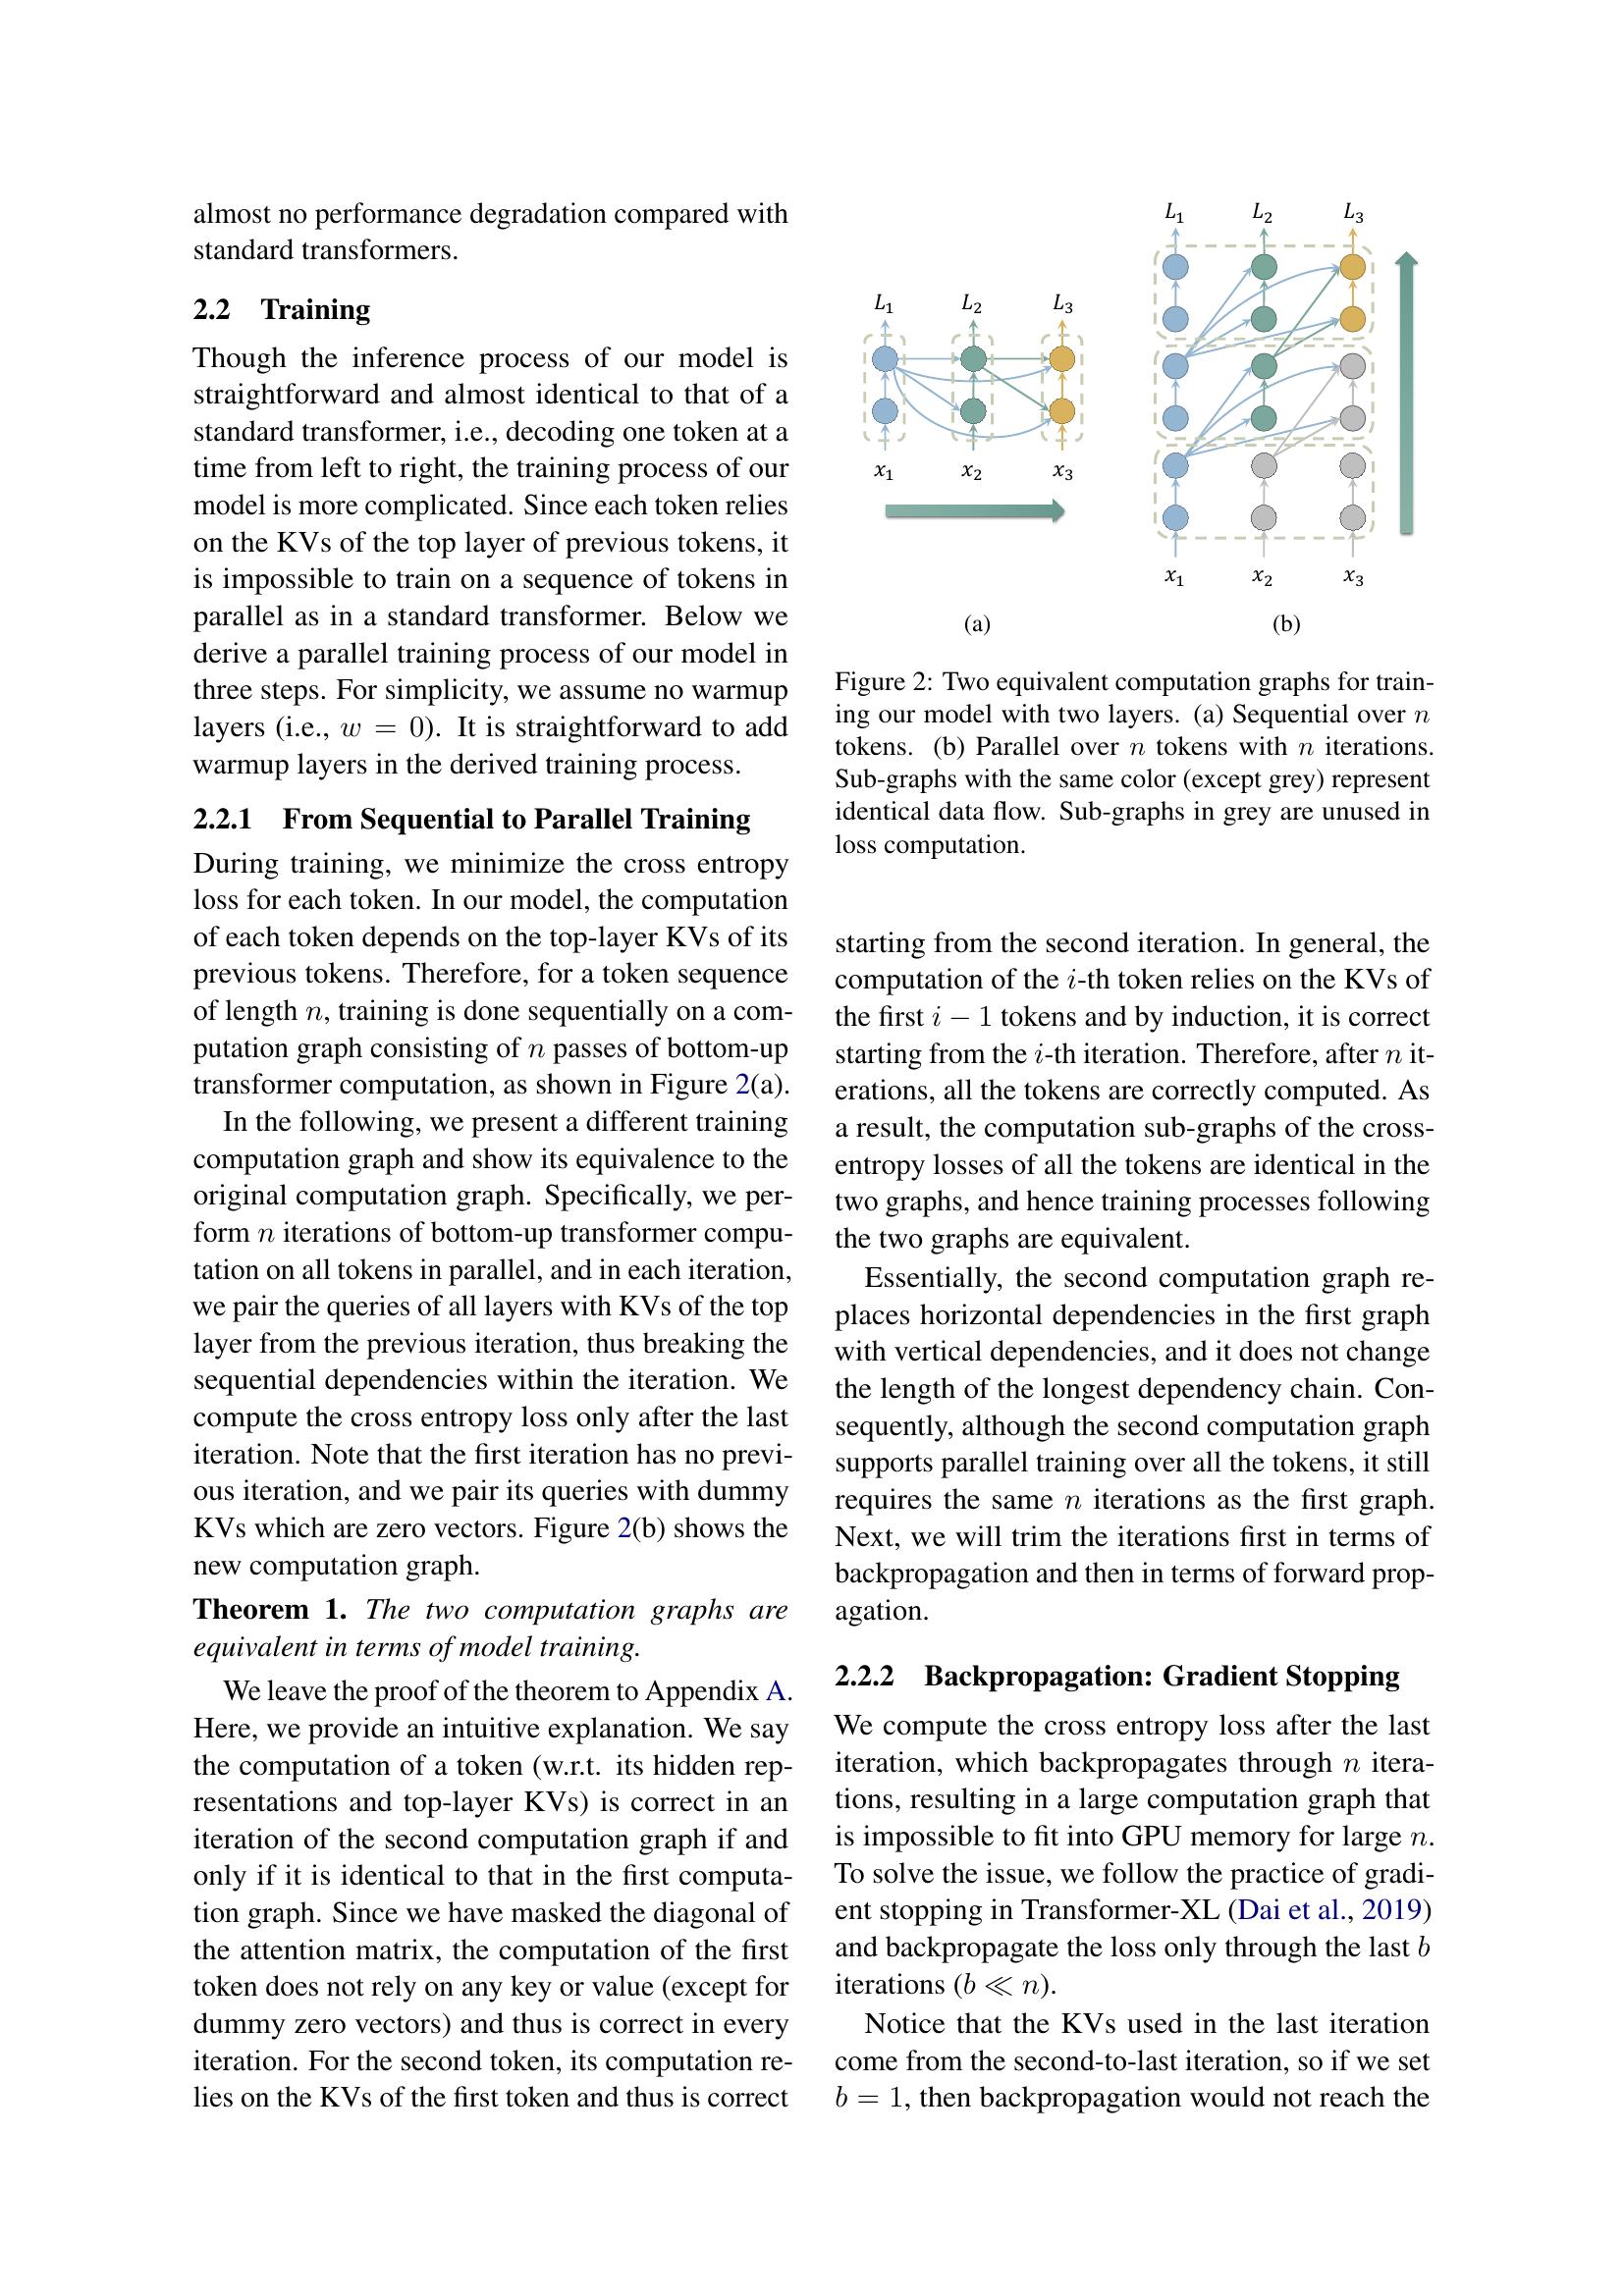
Layer-Condensed KV Cache for Efficient Inference of Large Language ...

SimLayerKV: An Efficient Solution to KV Cache Challenges in Large ...

[论文评述] KVLink: Accelerating Large Language Models via Efficient KV ...

Empowering Large Language Models (LLMs) with KV Cache: A Deep Dive into ...

UX - SimLayerKV: An Efficient Solution to KV Cache Challenges in Large ...
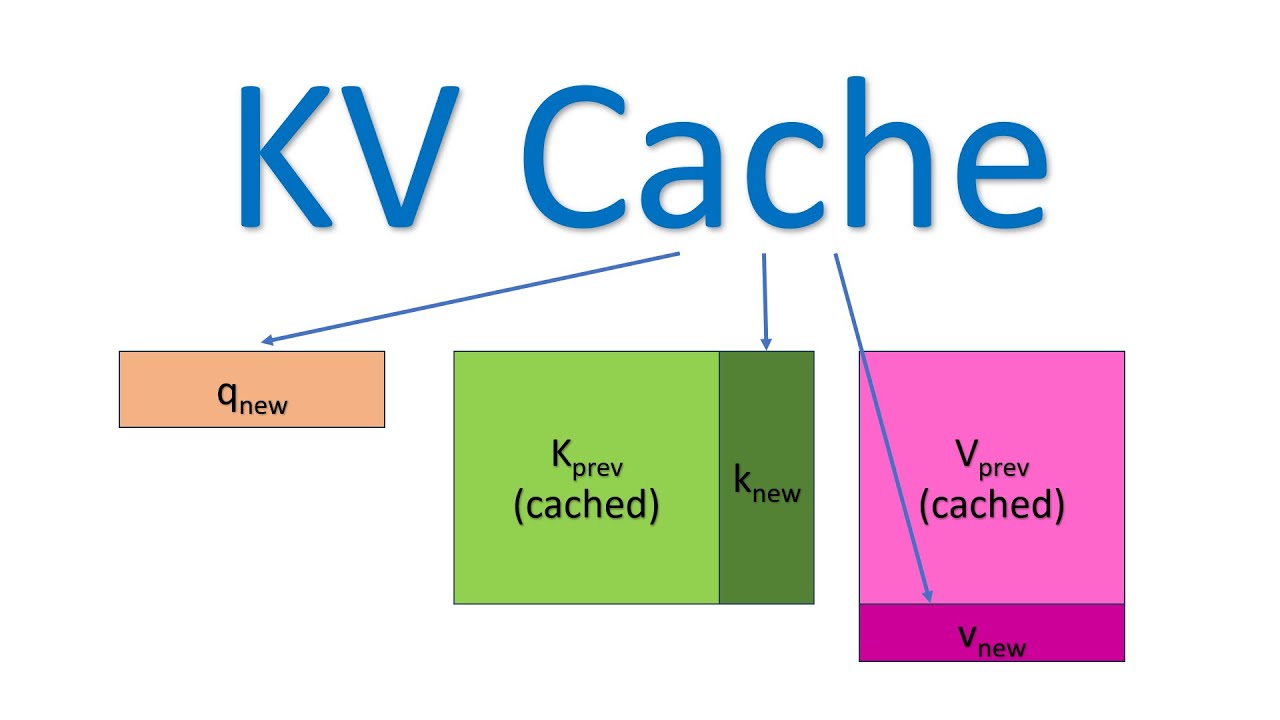
GPU memory requirements for serving Large Language Models | UnfoldAI

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...
Advertisement Space (336x280)
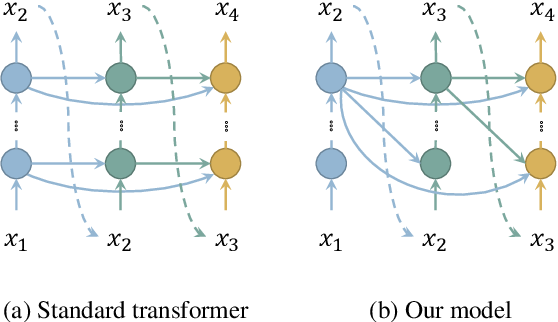
Figure 1 from Layer-Condensed KV Cache for Efficient Inference of Large ...

[논문 리뷰] A Survey on Large Language Model Acceleration based on KV Cache ...
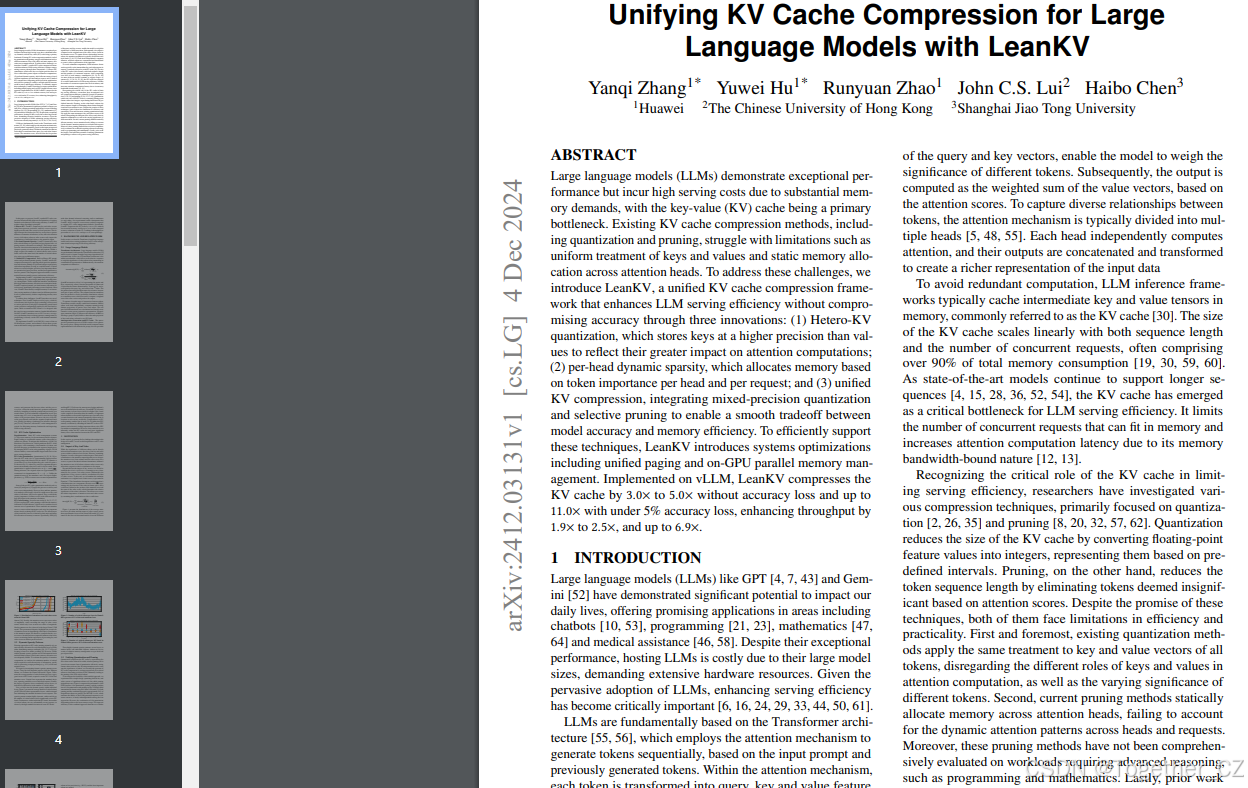
Unifying KV Cache Compression for LargeLanguage Models with LeanKV——使用 ...

KV Cache is 1 Bit Per Channel: Efficient Large Language Model Inference ...
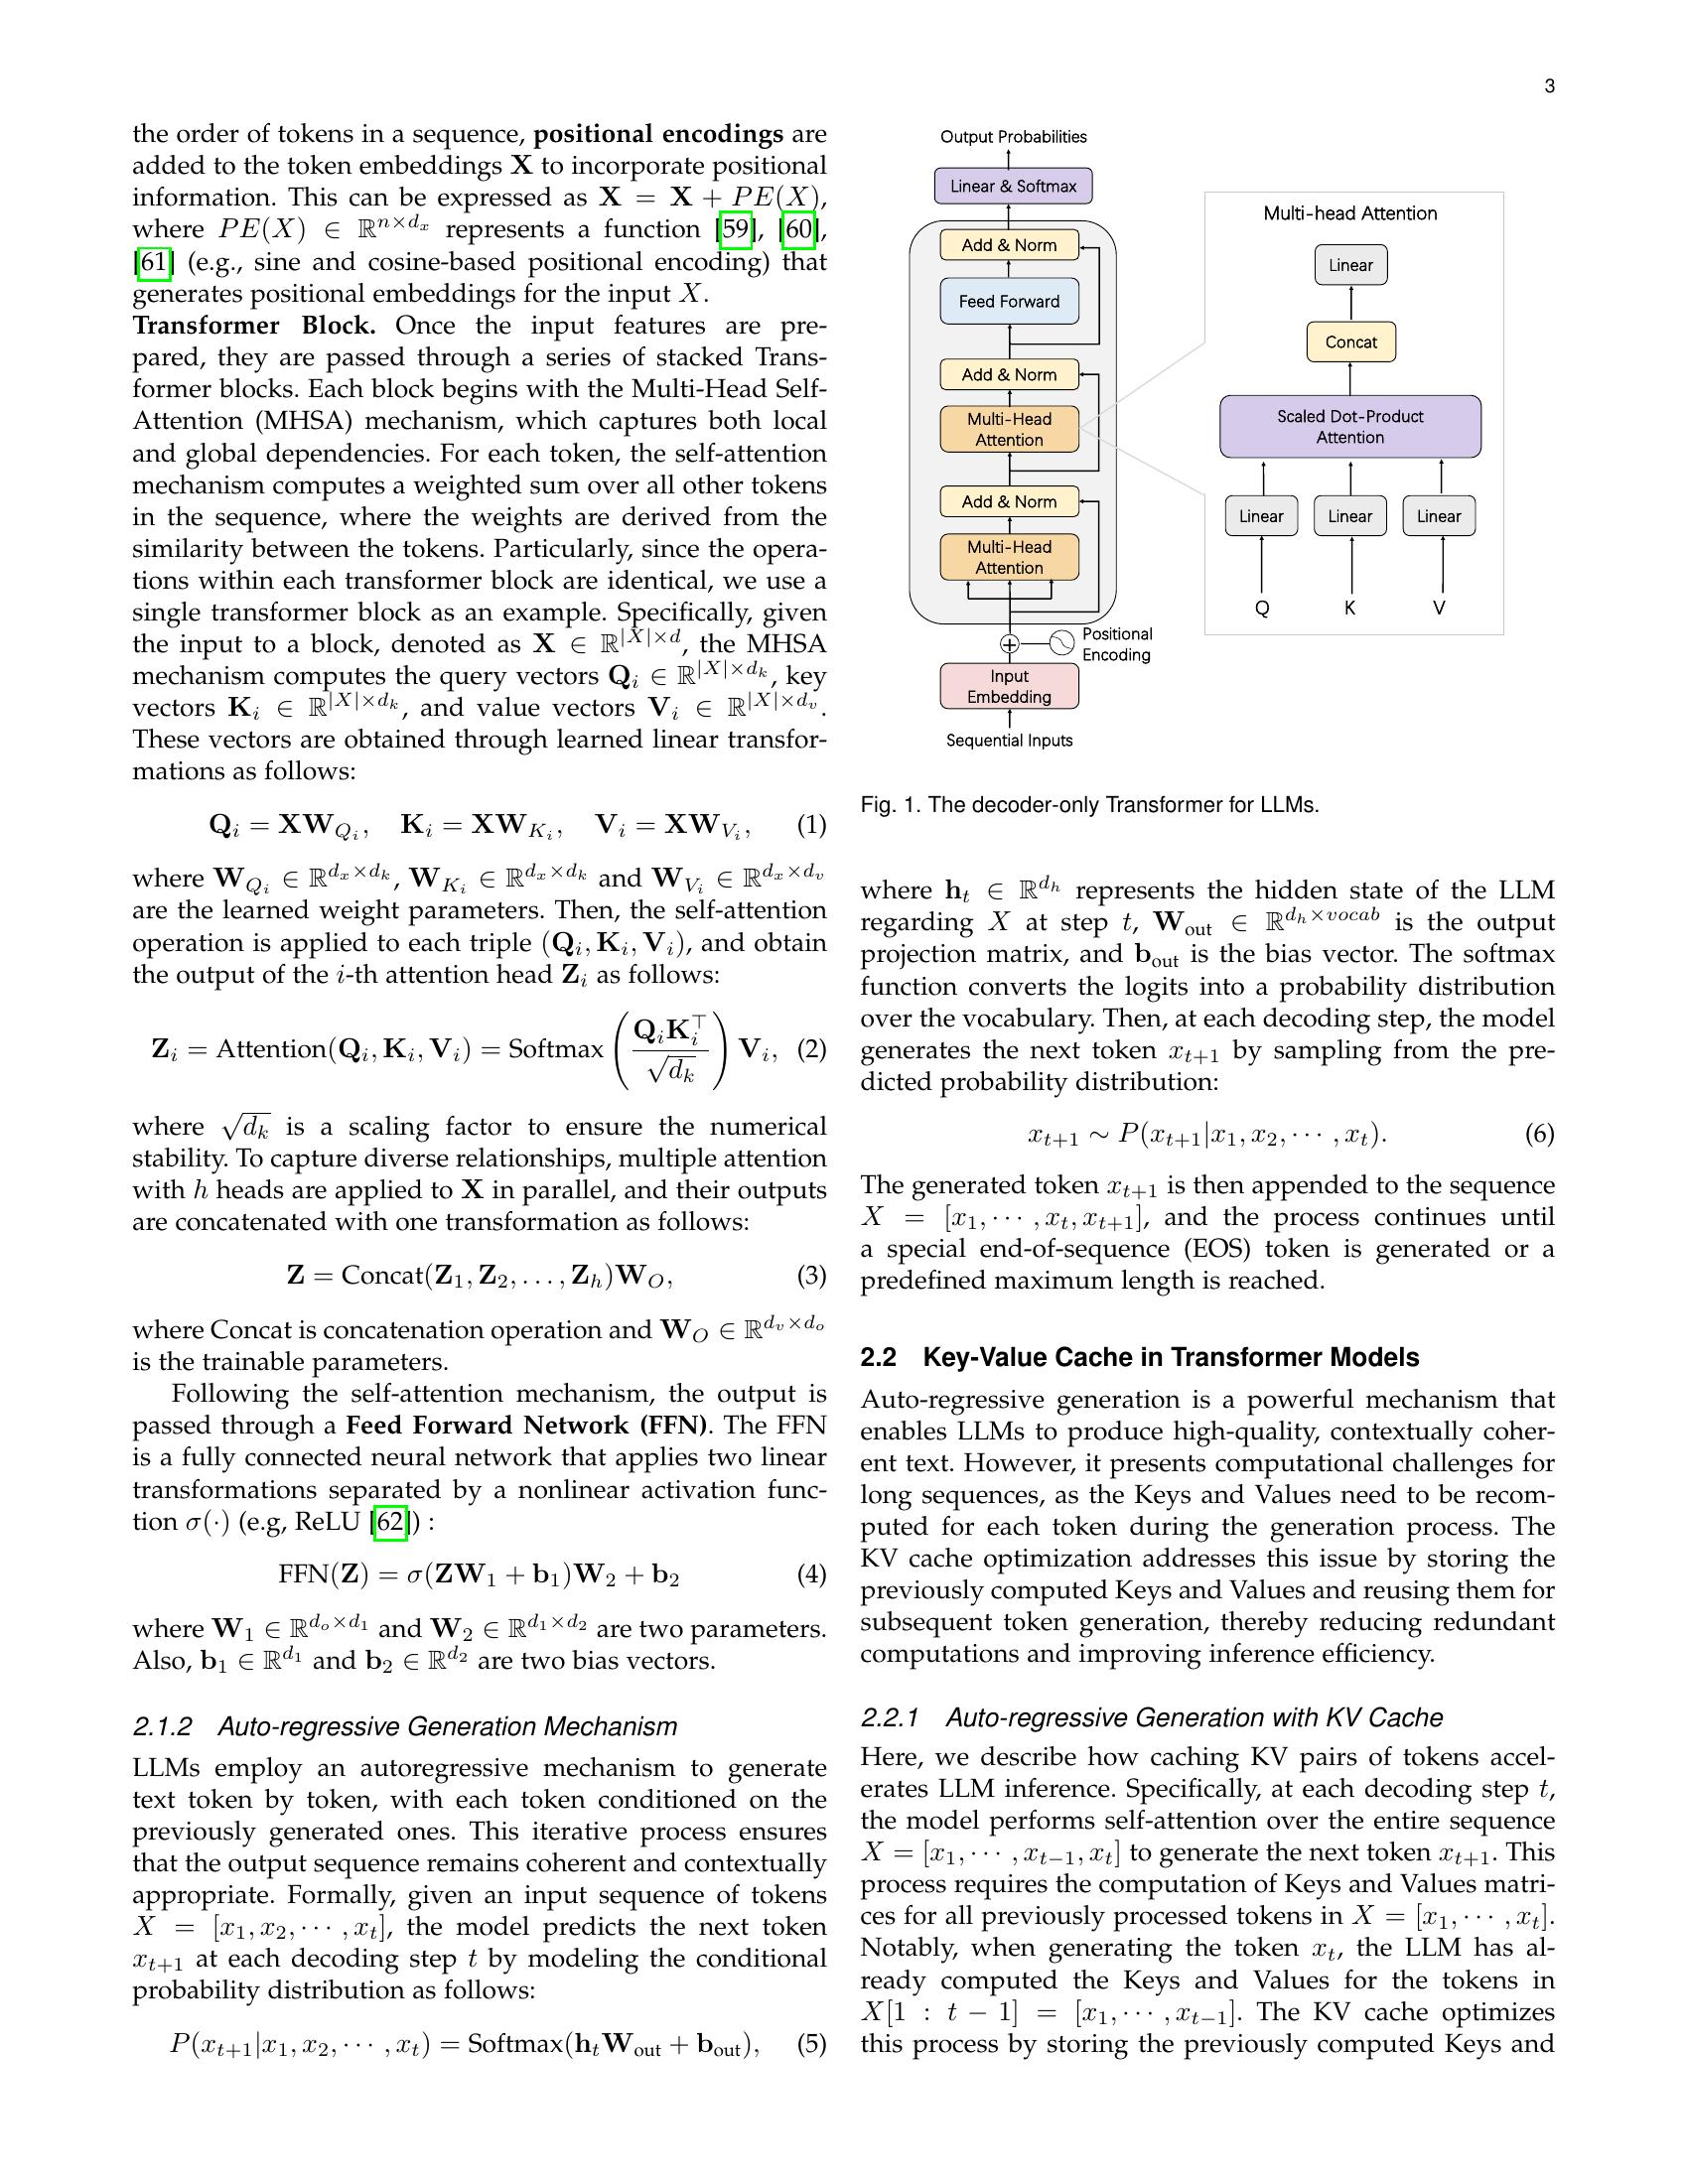
A Survey on Large Language Model Acceleration based on KV Cache ...

[논문 리뷰] KV Cache Transform Coding for Compact Storage in LLM Inference