
Torchdistributedlaunch Outputs All Processes To Stdout Single Node
torch.distributed.launch outputs all processes to stdout (single node ...
Single Node distributed multiprocessing training is not working · Issue ...
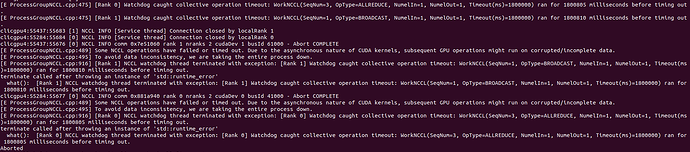
Program hangs when node trying to wrap torch model with DDP ...
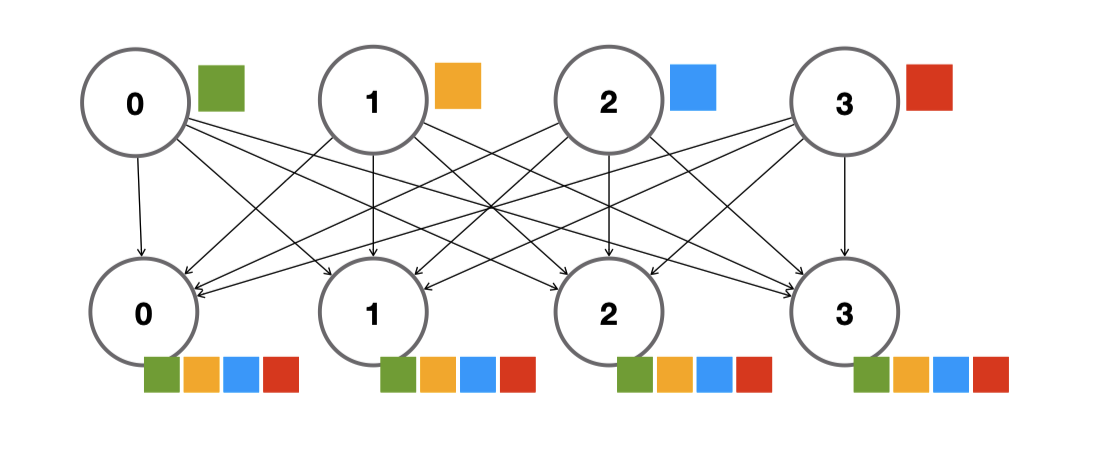
From Single GPU to Clusters: A Practical Journey into Distributed ...
Process Stdout Write Node – Process – VYTT
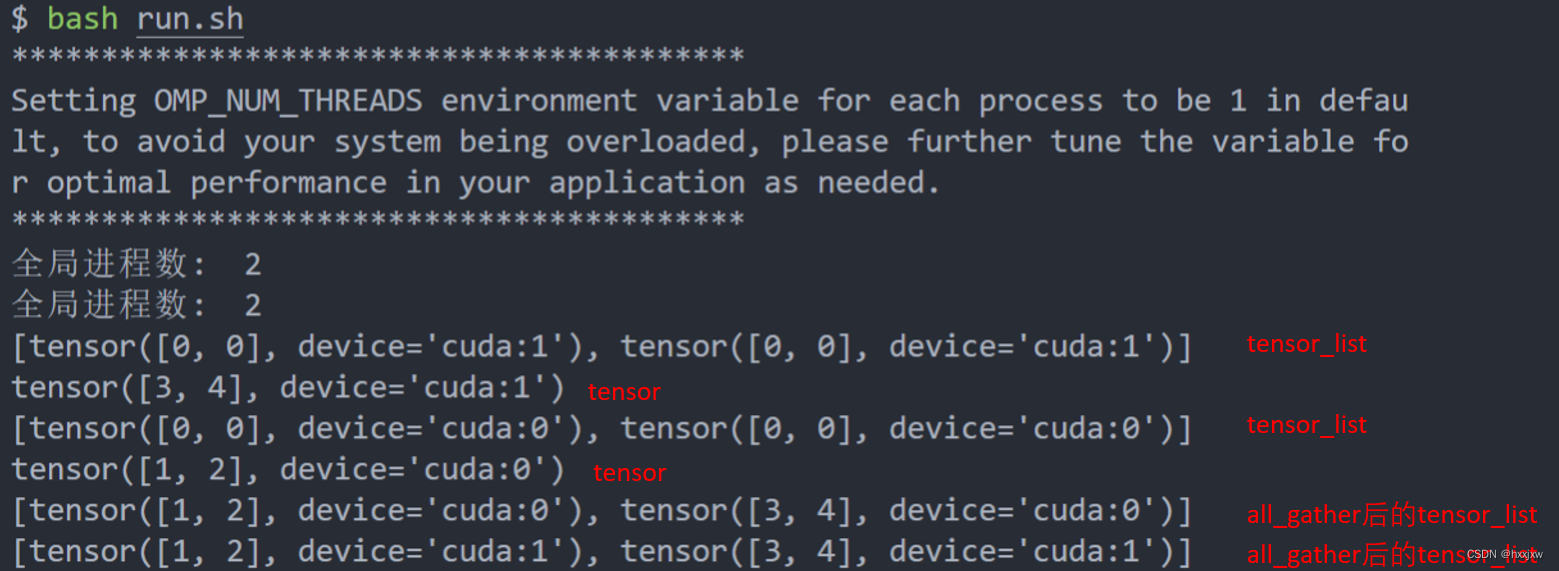
torch.distributed多卡/多GPU/分布式DPP(一) —— torch.distributed.launch & all ...
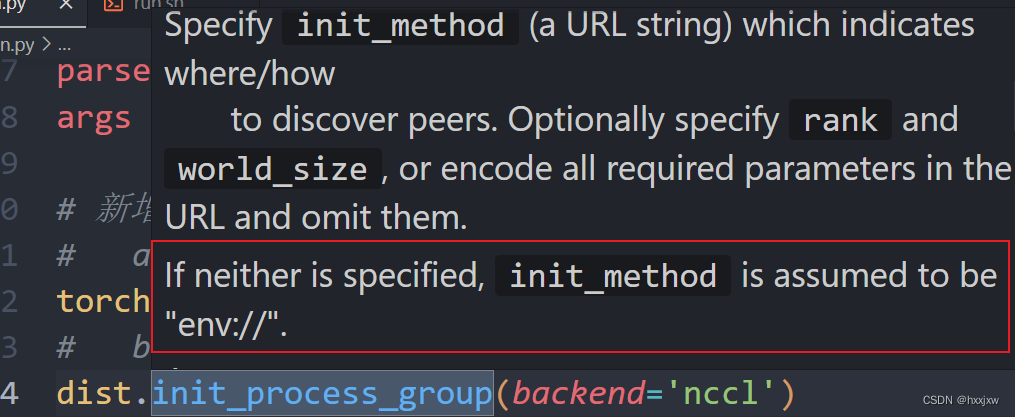
torch.distributed多卡/多GPU/分布式DPP(一) —— torch.distributed.launch & all ...
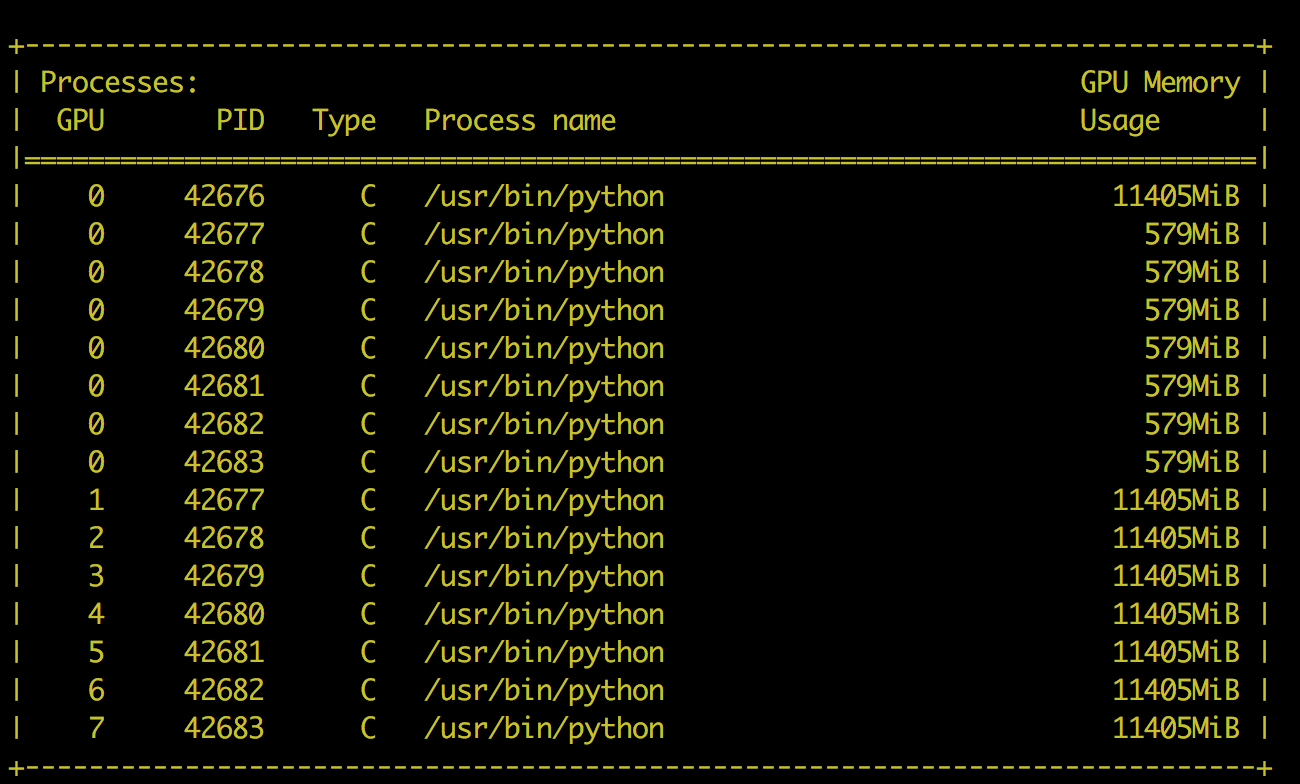
Torch not able to utilize GPU ram properly - distributed - PyTorch Forums
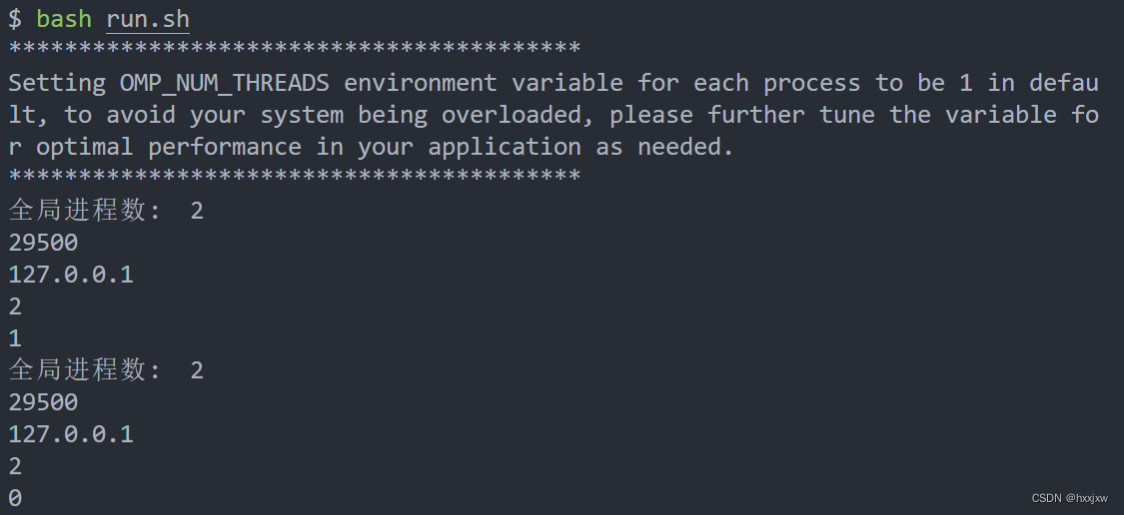
torch.distributed多卡/多GPU/分布式DPP(一) —— torch.distributed.launch & all ...

Multi node training with PyTorch DDP, torch.distributed.launch ...
Advertisement Space (300x250)

Add alltoall collective communication support to torch.distributed ...

Separate subtest stdout from TAP output · Issue #45529 · nodejs/node ...

Same inputs but get different outputs - PyTorch Forums
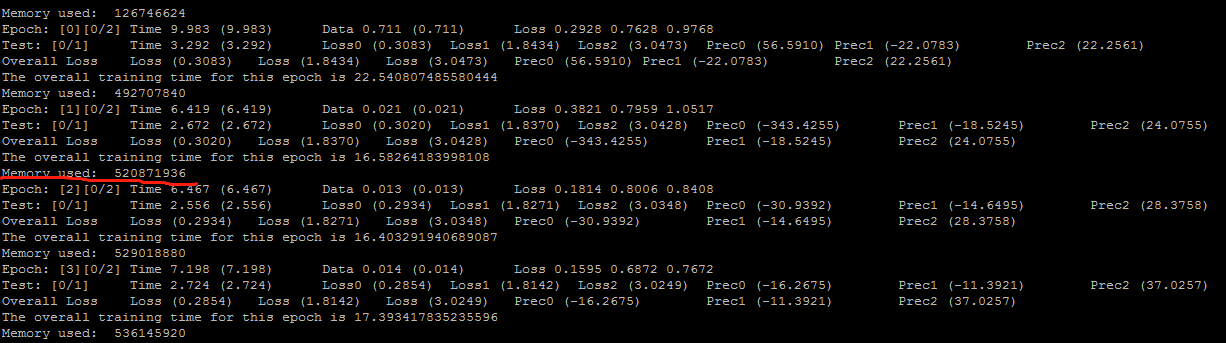
Why pytorch needs so much memory to execute distributed training ...
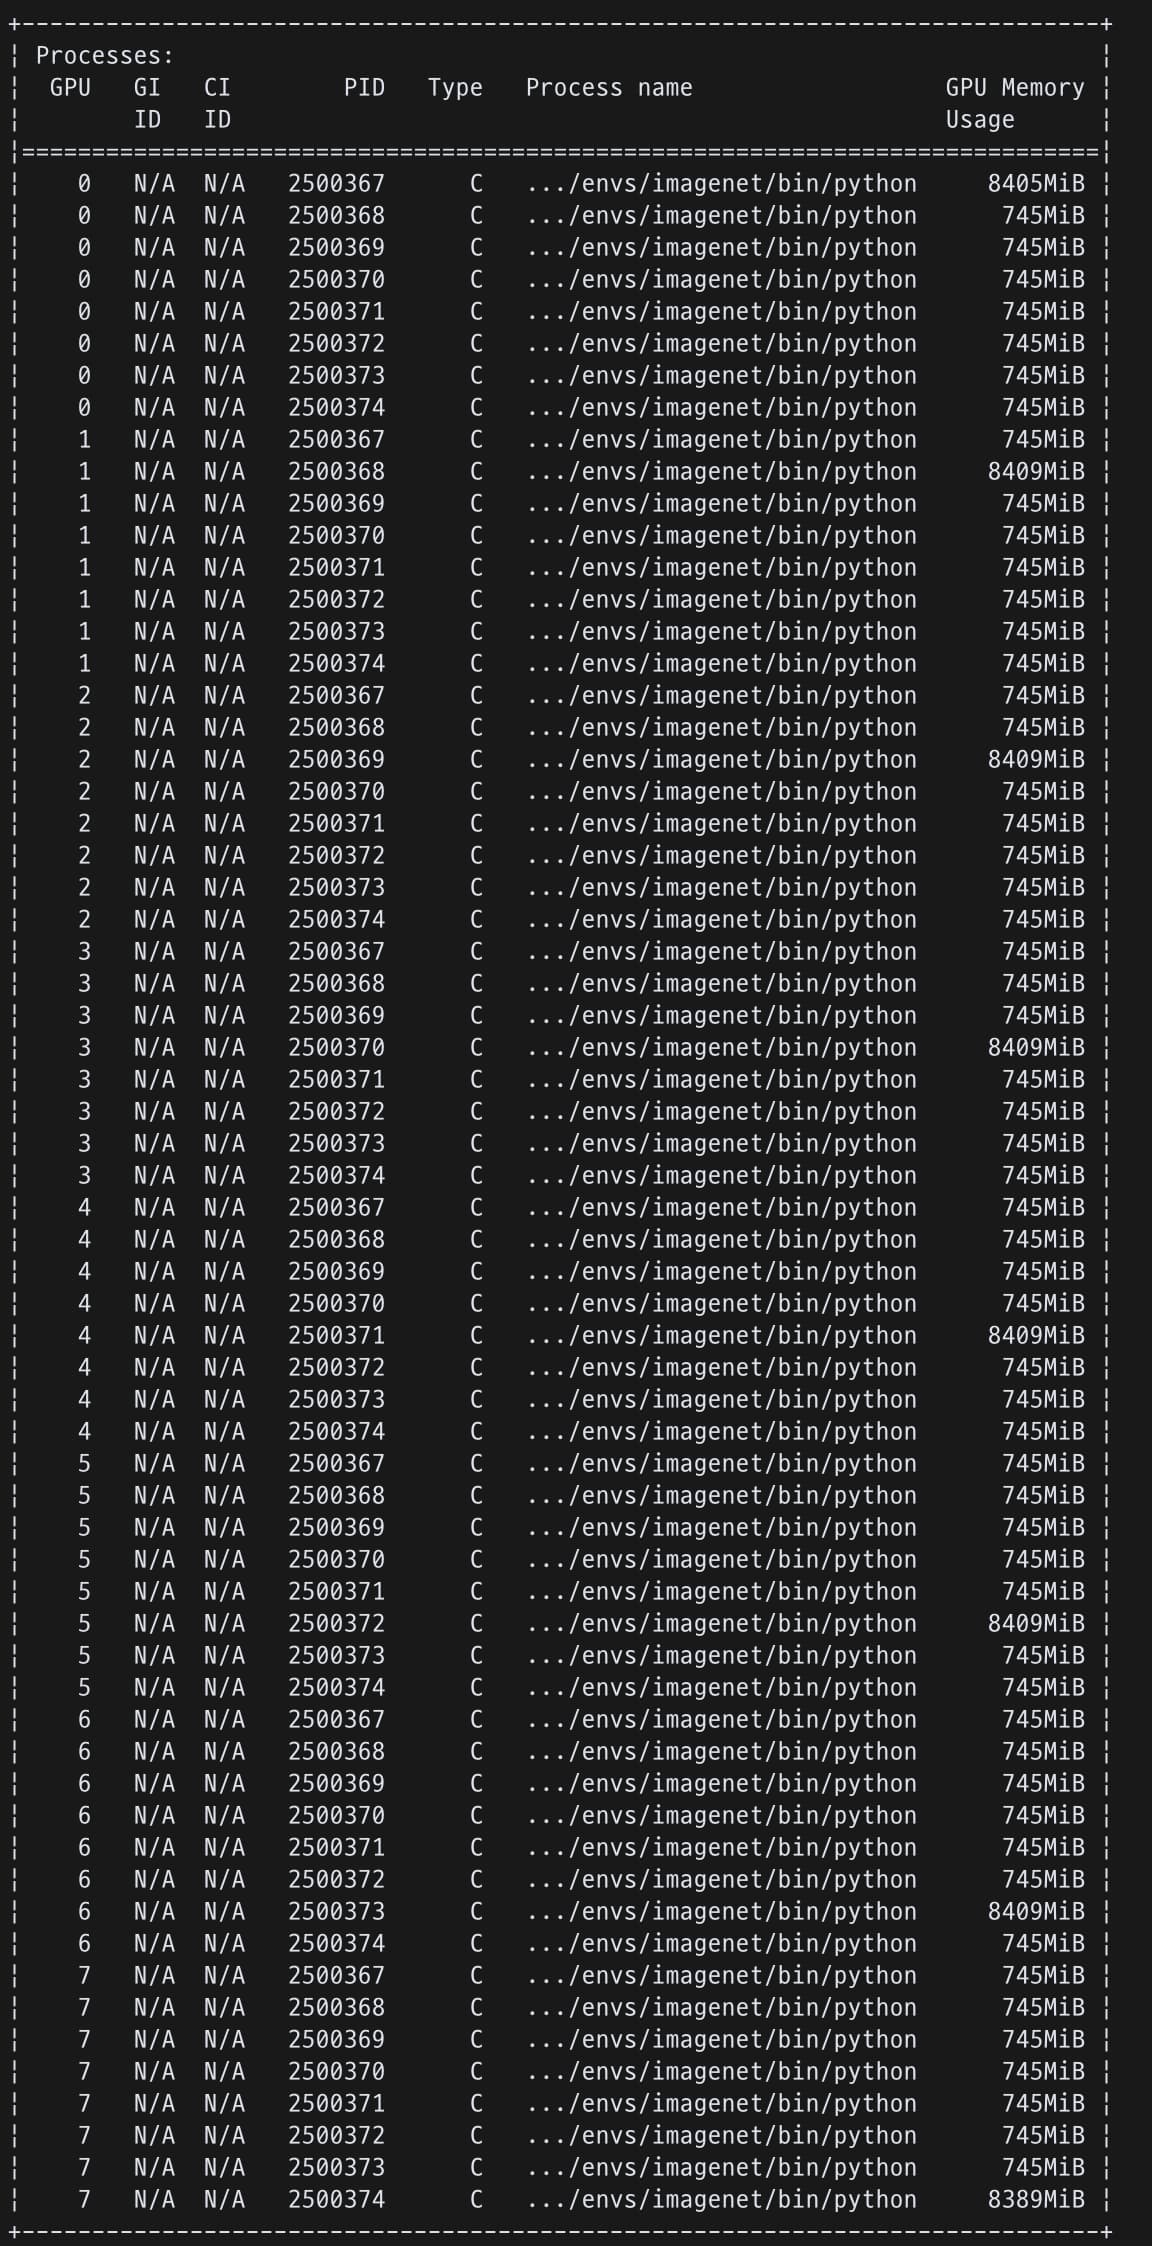
distributed.all_gather_object() produces multiple additional processes ...
Alternative to torch distributed launch for multi-gpu ...
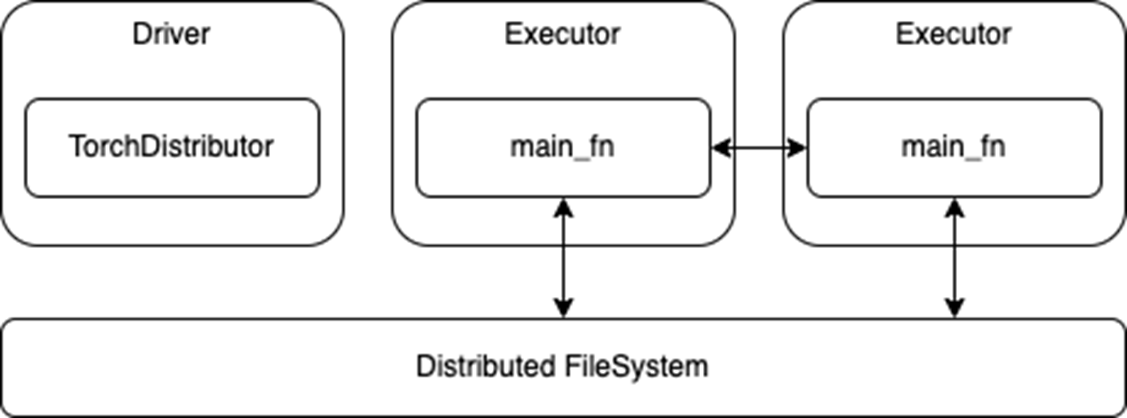
Distributed Deep Learning Made Easy with Spark 3.4 – GIXtools
Medium
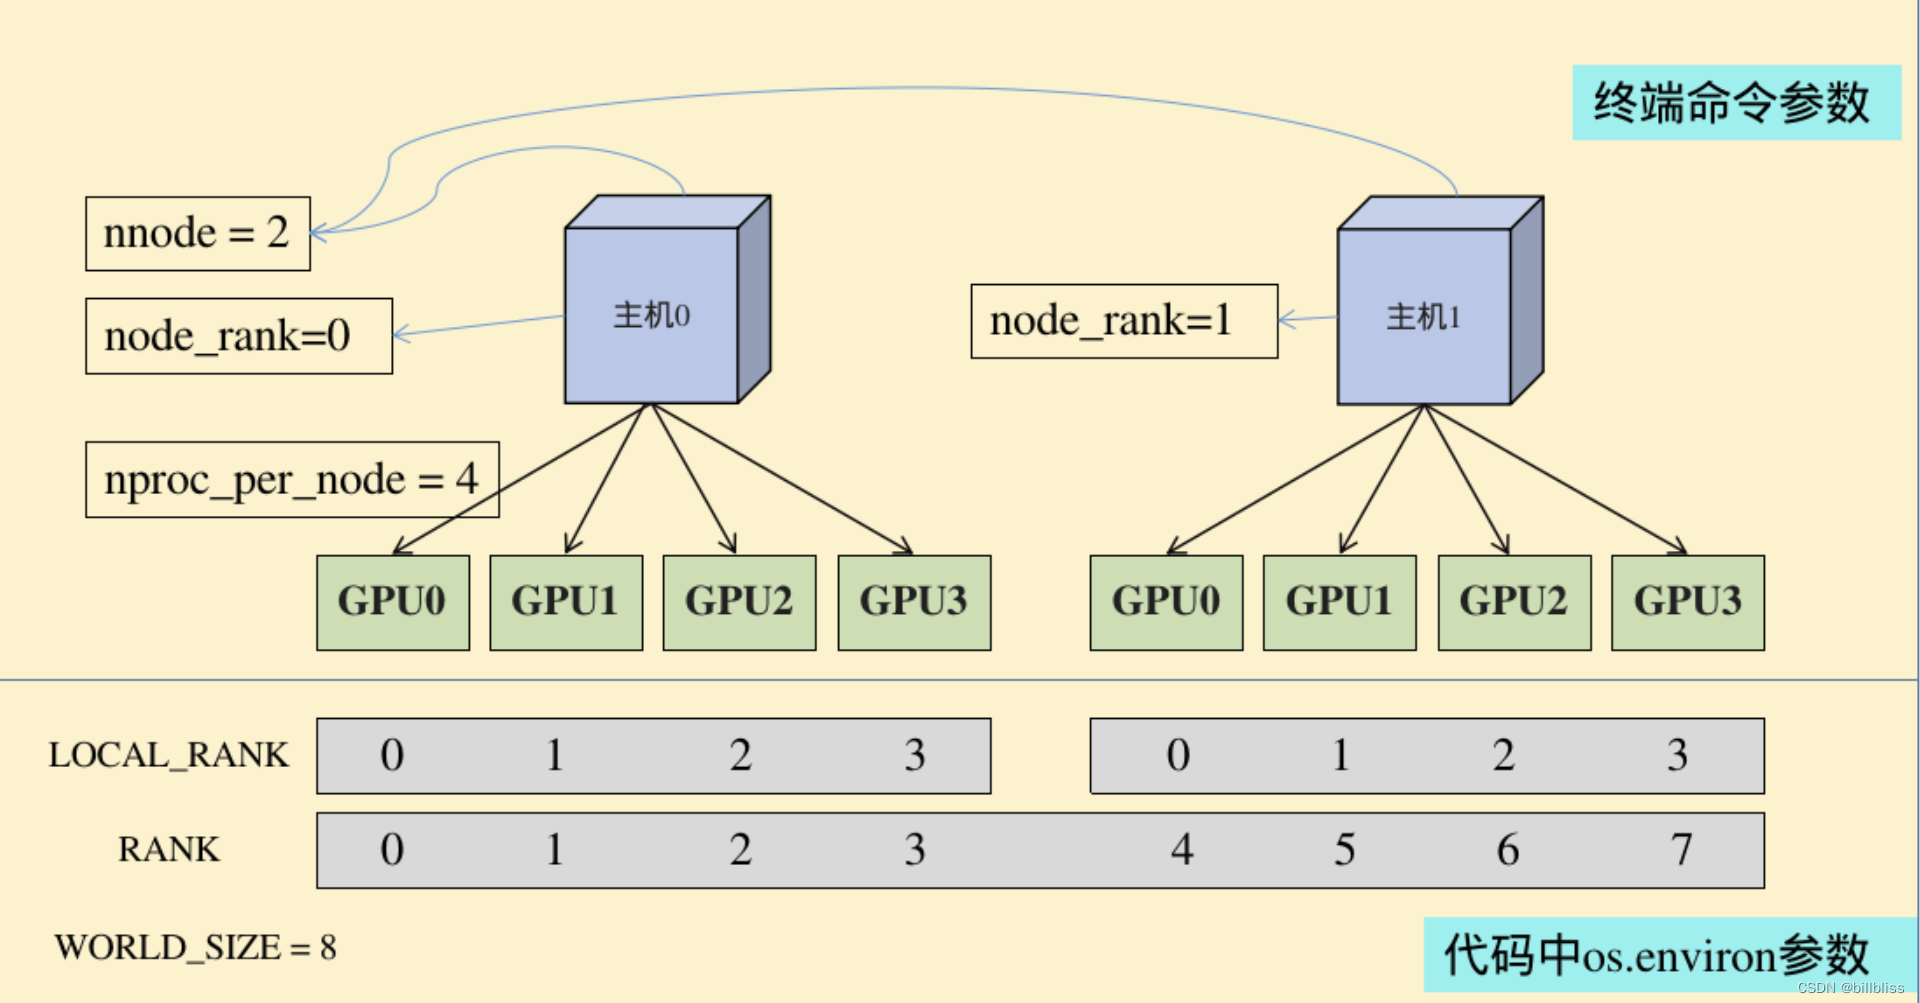
torch.distributed.launch多卡多机_torch.distributed.launch多机多卡训练命令-CSDN博客

Distributed and Parallel Training for PyTorch - Speaker Deck
Advertisement Space (336x280)
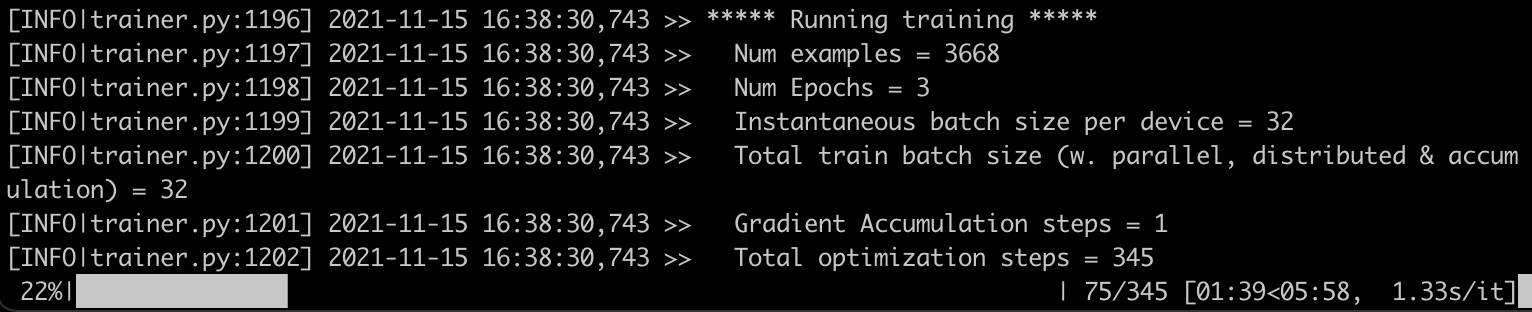
Accelerating PyTorch distributed fine-tuning with Intel technologies
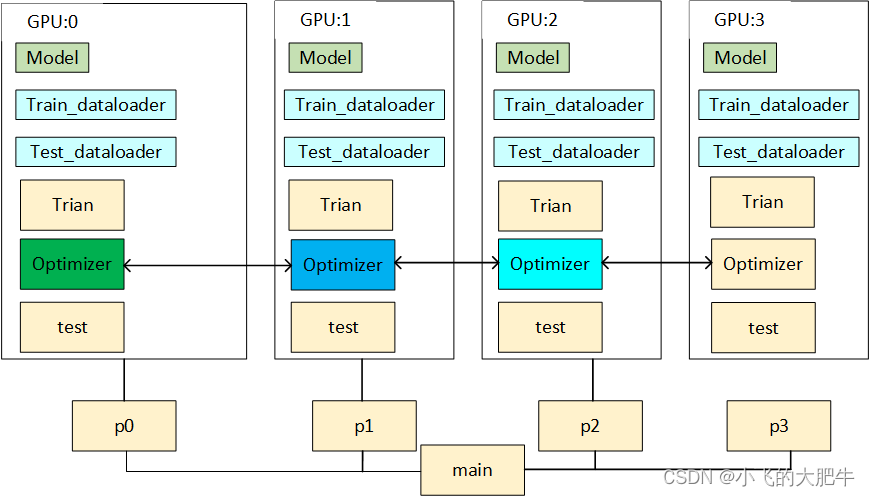
多GPU联合训练深度学习模型_模型联合训练-CSDN博客

PyTorch训练之分布式_pytorch分布式训练-CSDN博客
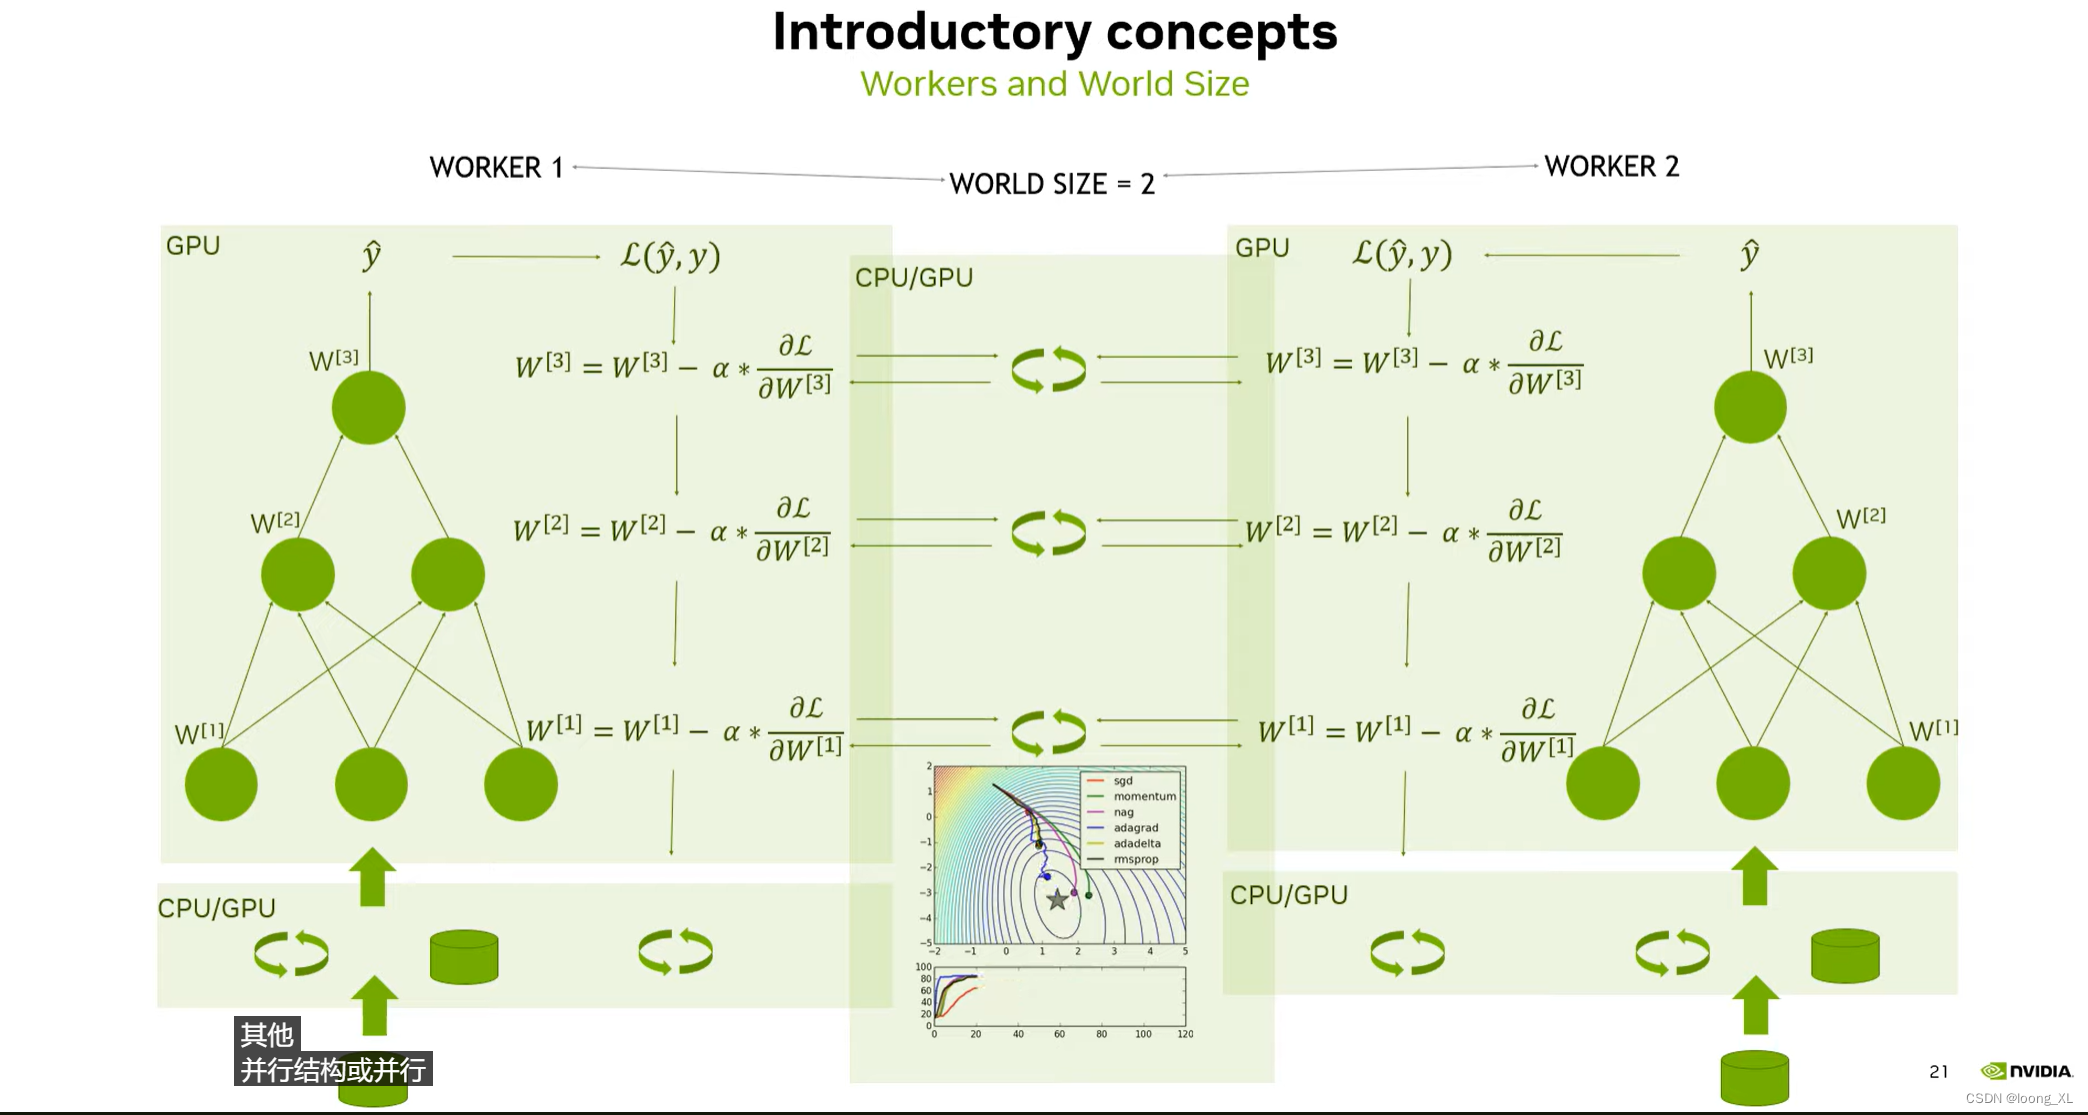
torchrun、 torch.distributed.launch 多节点分布式训练使用案例-CSDN博客

Distributed and Parallel Training for PyTorch - Speaker Deck

Distributed Training for PyG
PyTorch : Distributed Data Parallel 详解Distributed Data Para - 掘金

Process unexpectedly hangs up in torch.distributed.init_process_group ...
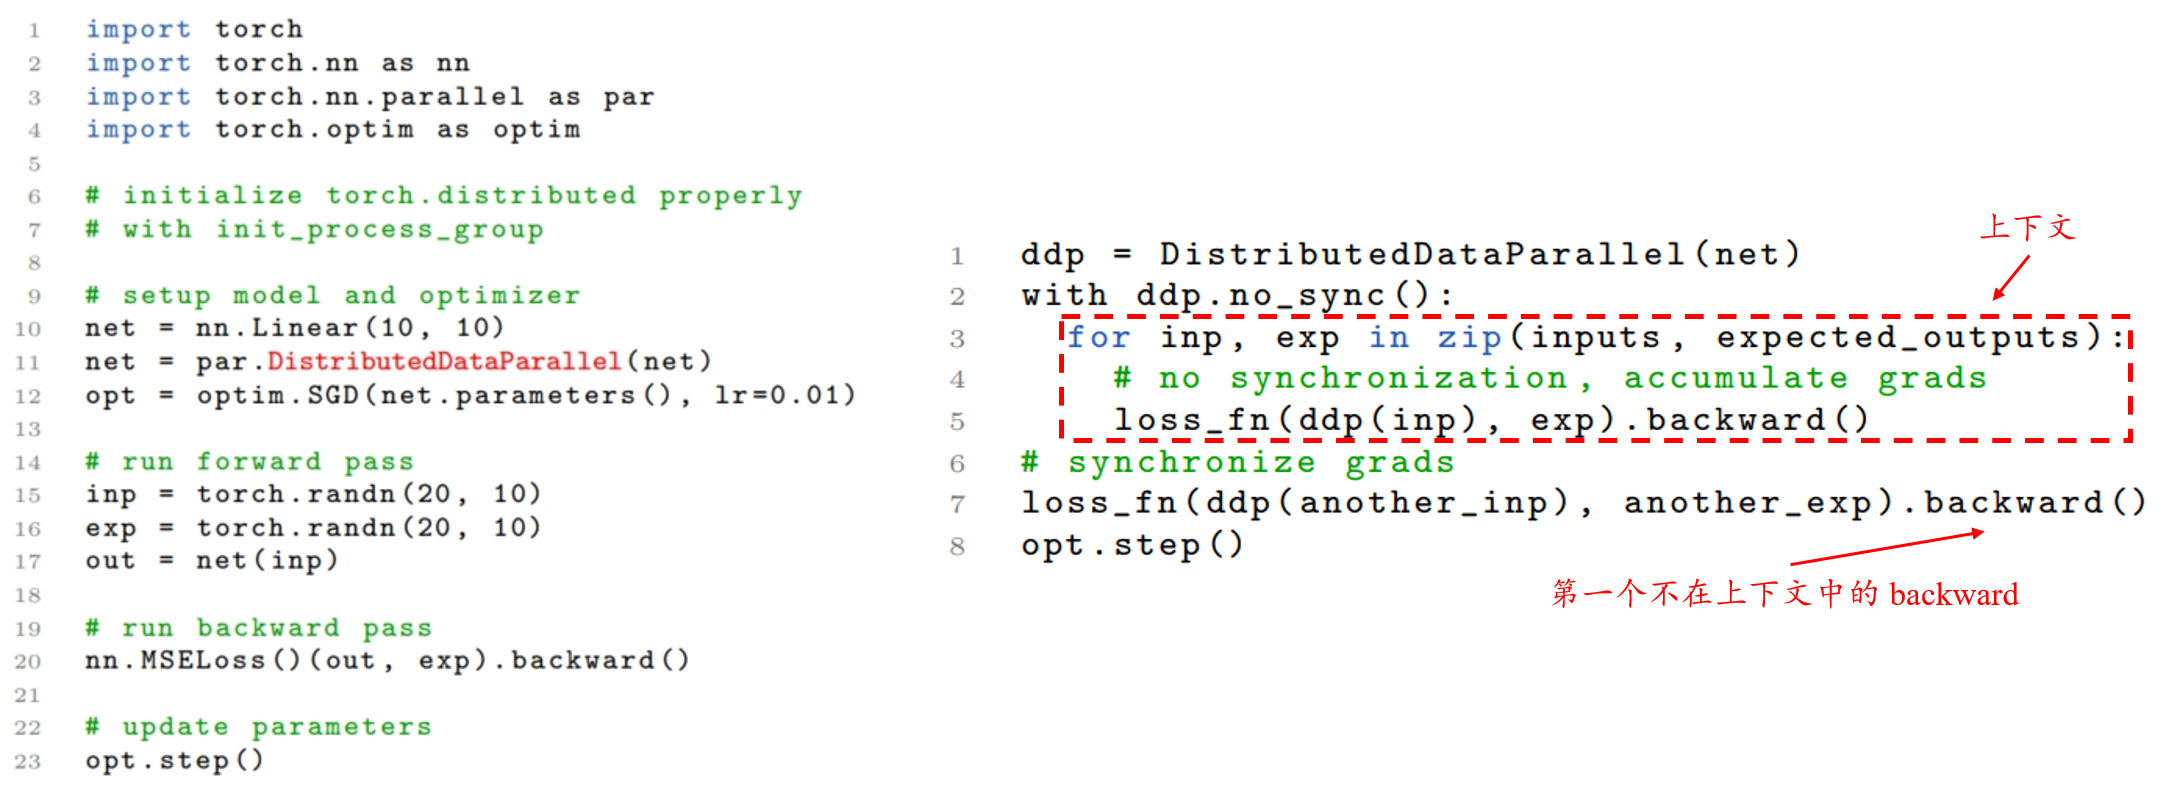
Torch Distributed Example at JENENGE blog

Torch Distributed Example at JENENGE blog
Advertisement Space (336x280)

Torch.distributed.launch Github at George Maple blog

Torch DDP入门 - 知乎
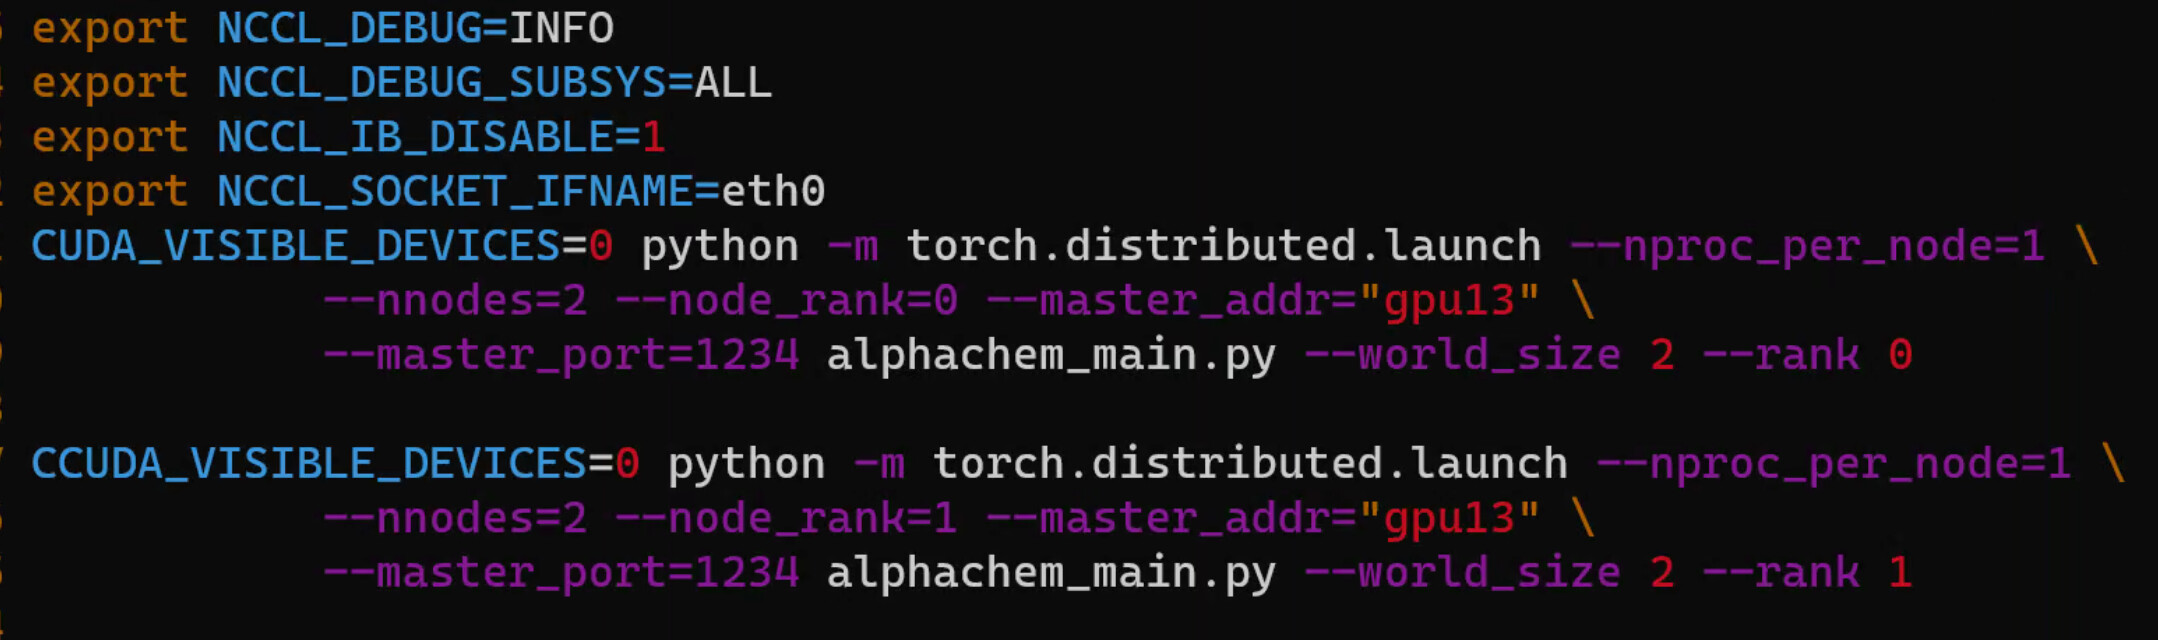
Process unexpectedly hangs up in torch.distributed.init_process_group ...
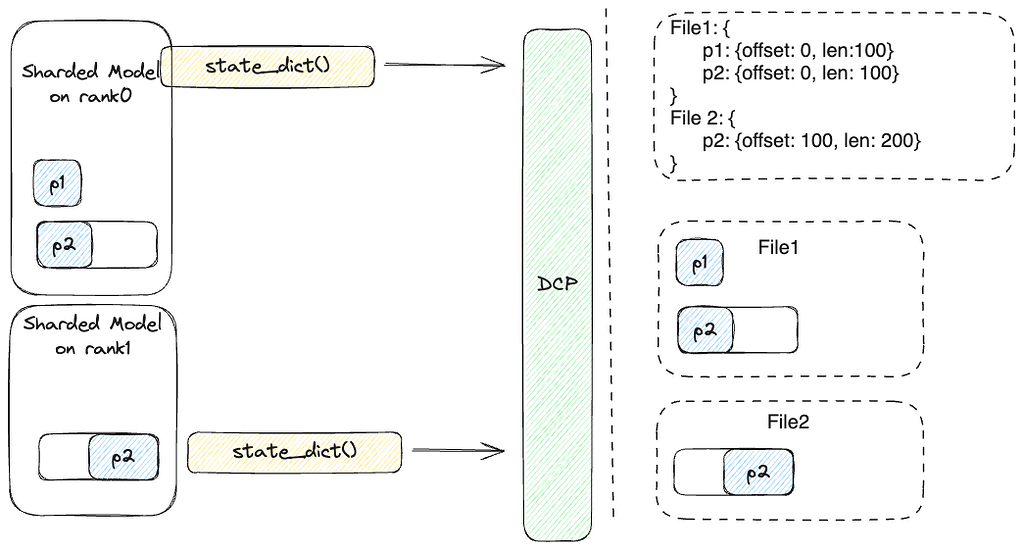
[Distributed w/ TorchTitan] Optimizing Checkpointing Efficiency with ...
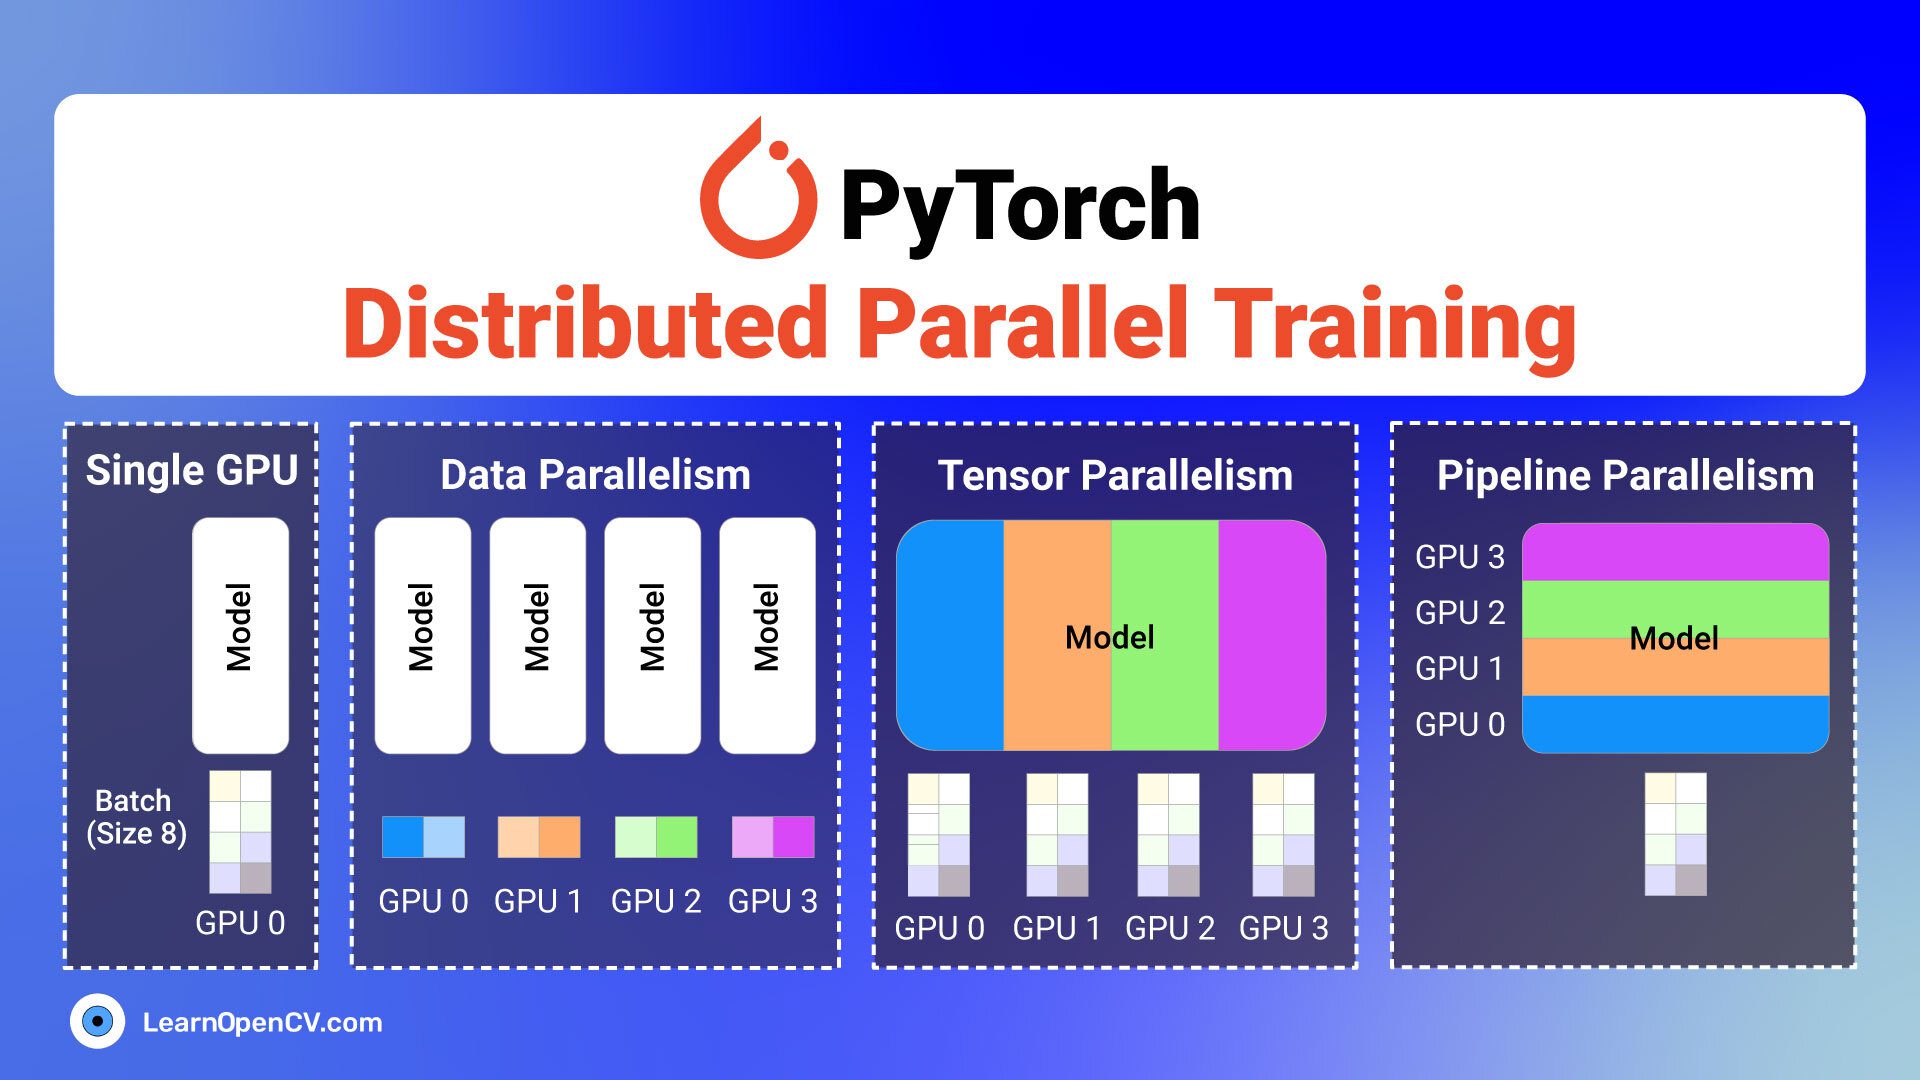
torch | LearnOpenCV

PyTorch Multinode - AMD Accelerator Cloud - Help