
Train And Run Dflash Speculative Decoding With Vllm
Train and run DFlash speculative decoding with vLLM
Train and run DFlash speculative decoding with vLLM
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
大模型推理加速——Fastest Speculative Decoding in vLLM with Arctic Inference and ...
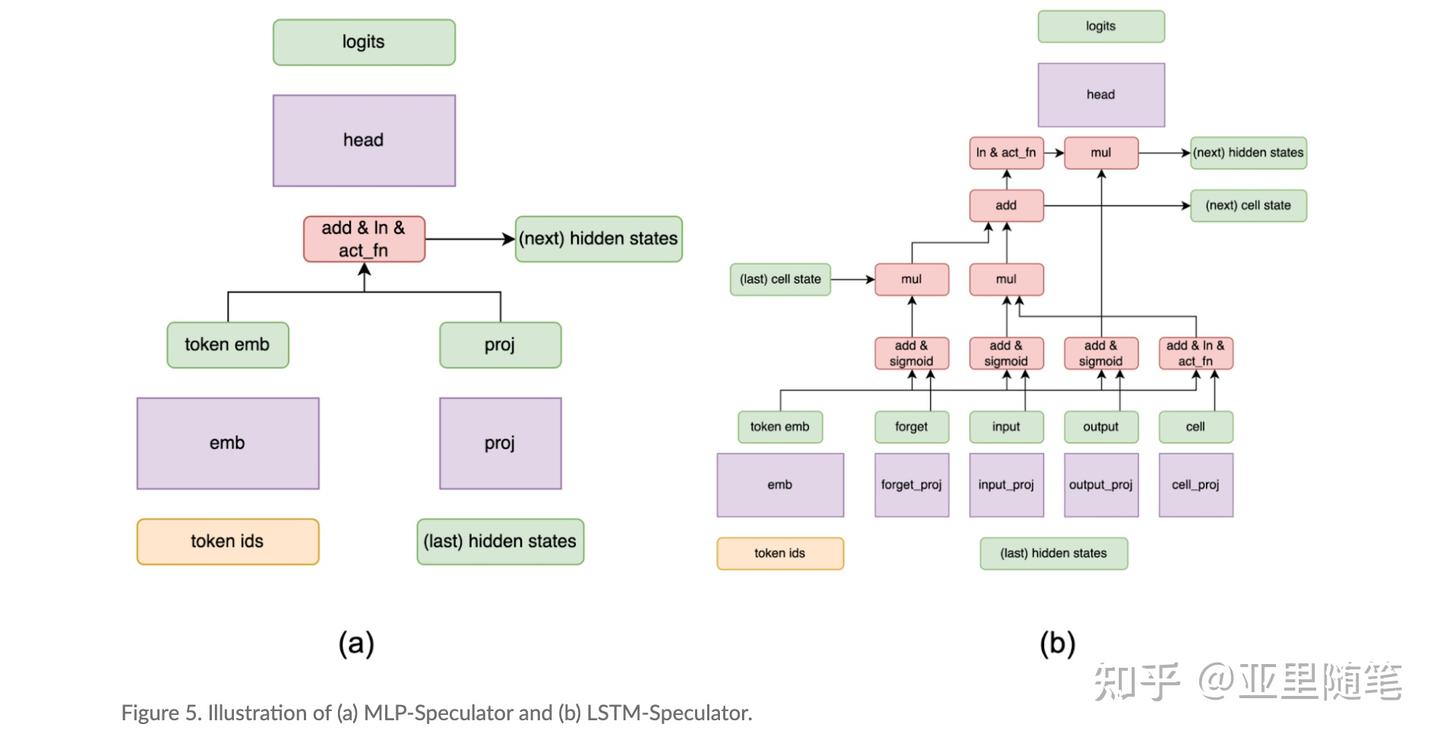
大模型推理加速——Fastest Speculative Decoding in vLLM with Arctic Inference and ...
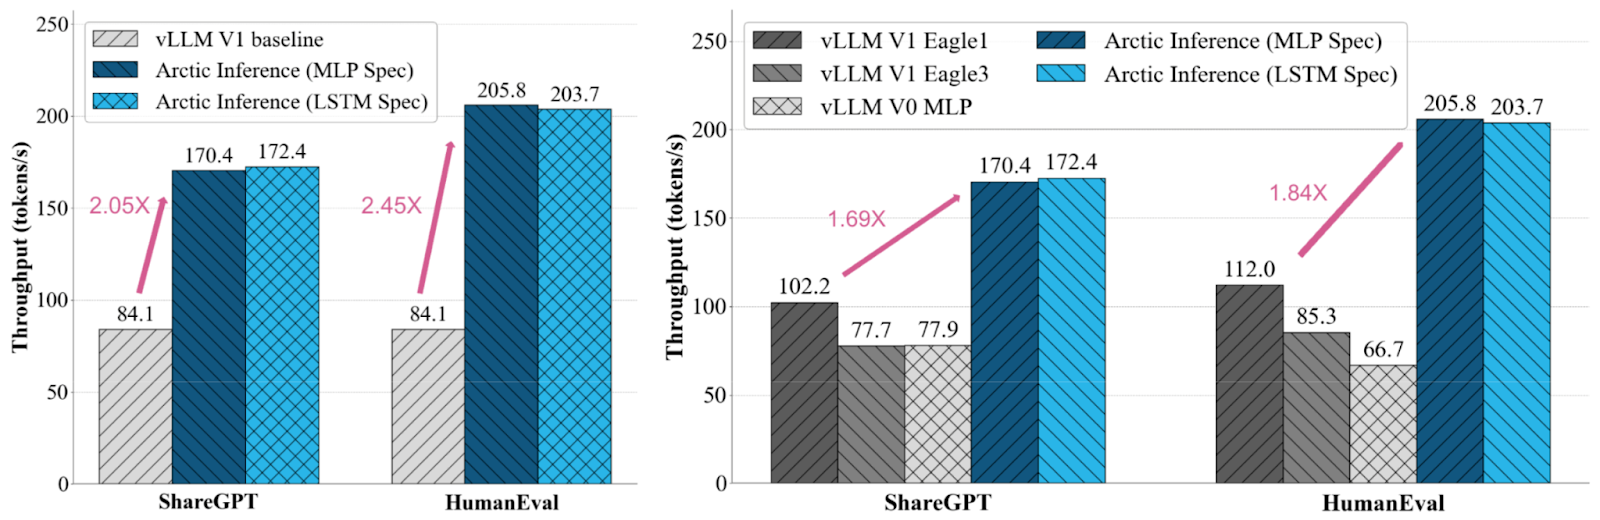
Fastest Speculative Decoding in vLLM with Arctic Inference and Arctic ...
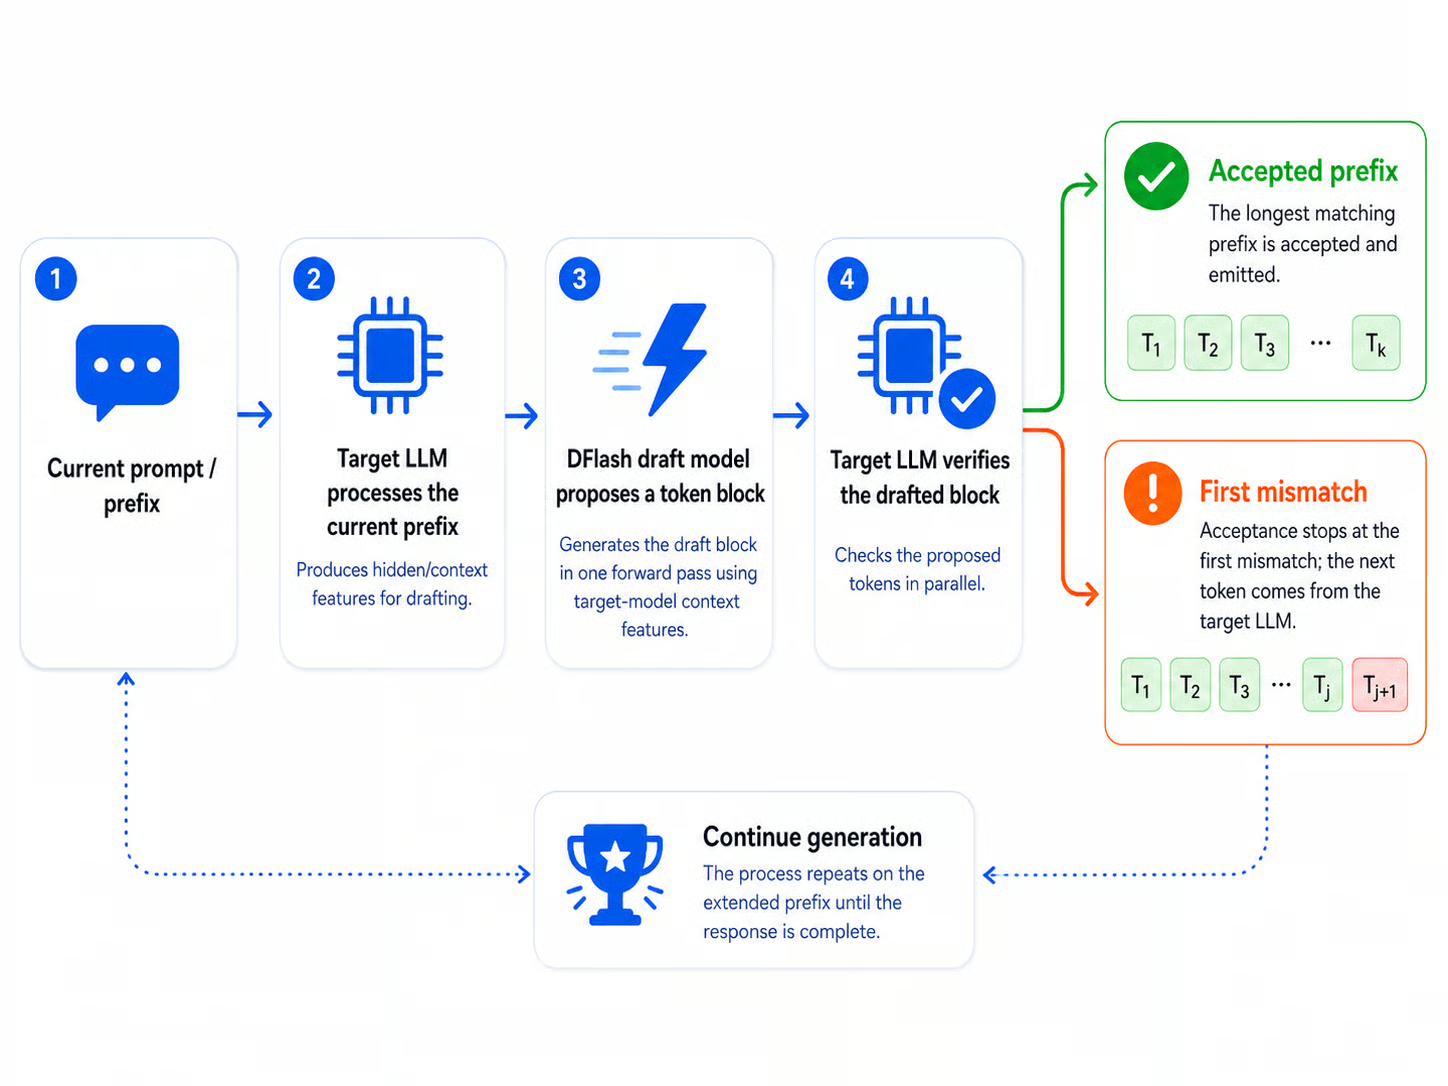
How to Speed Up Local LLMs with DFlash Speculative Decoding | DataCamp
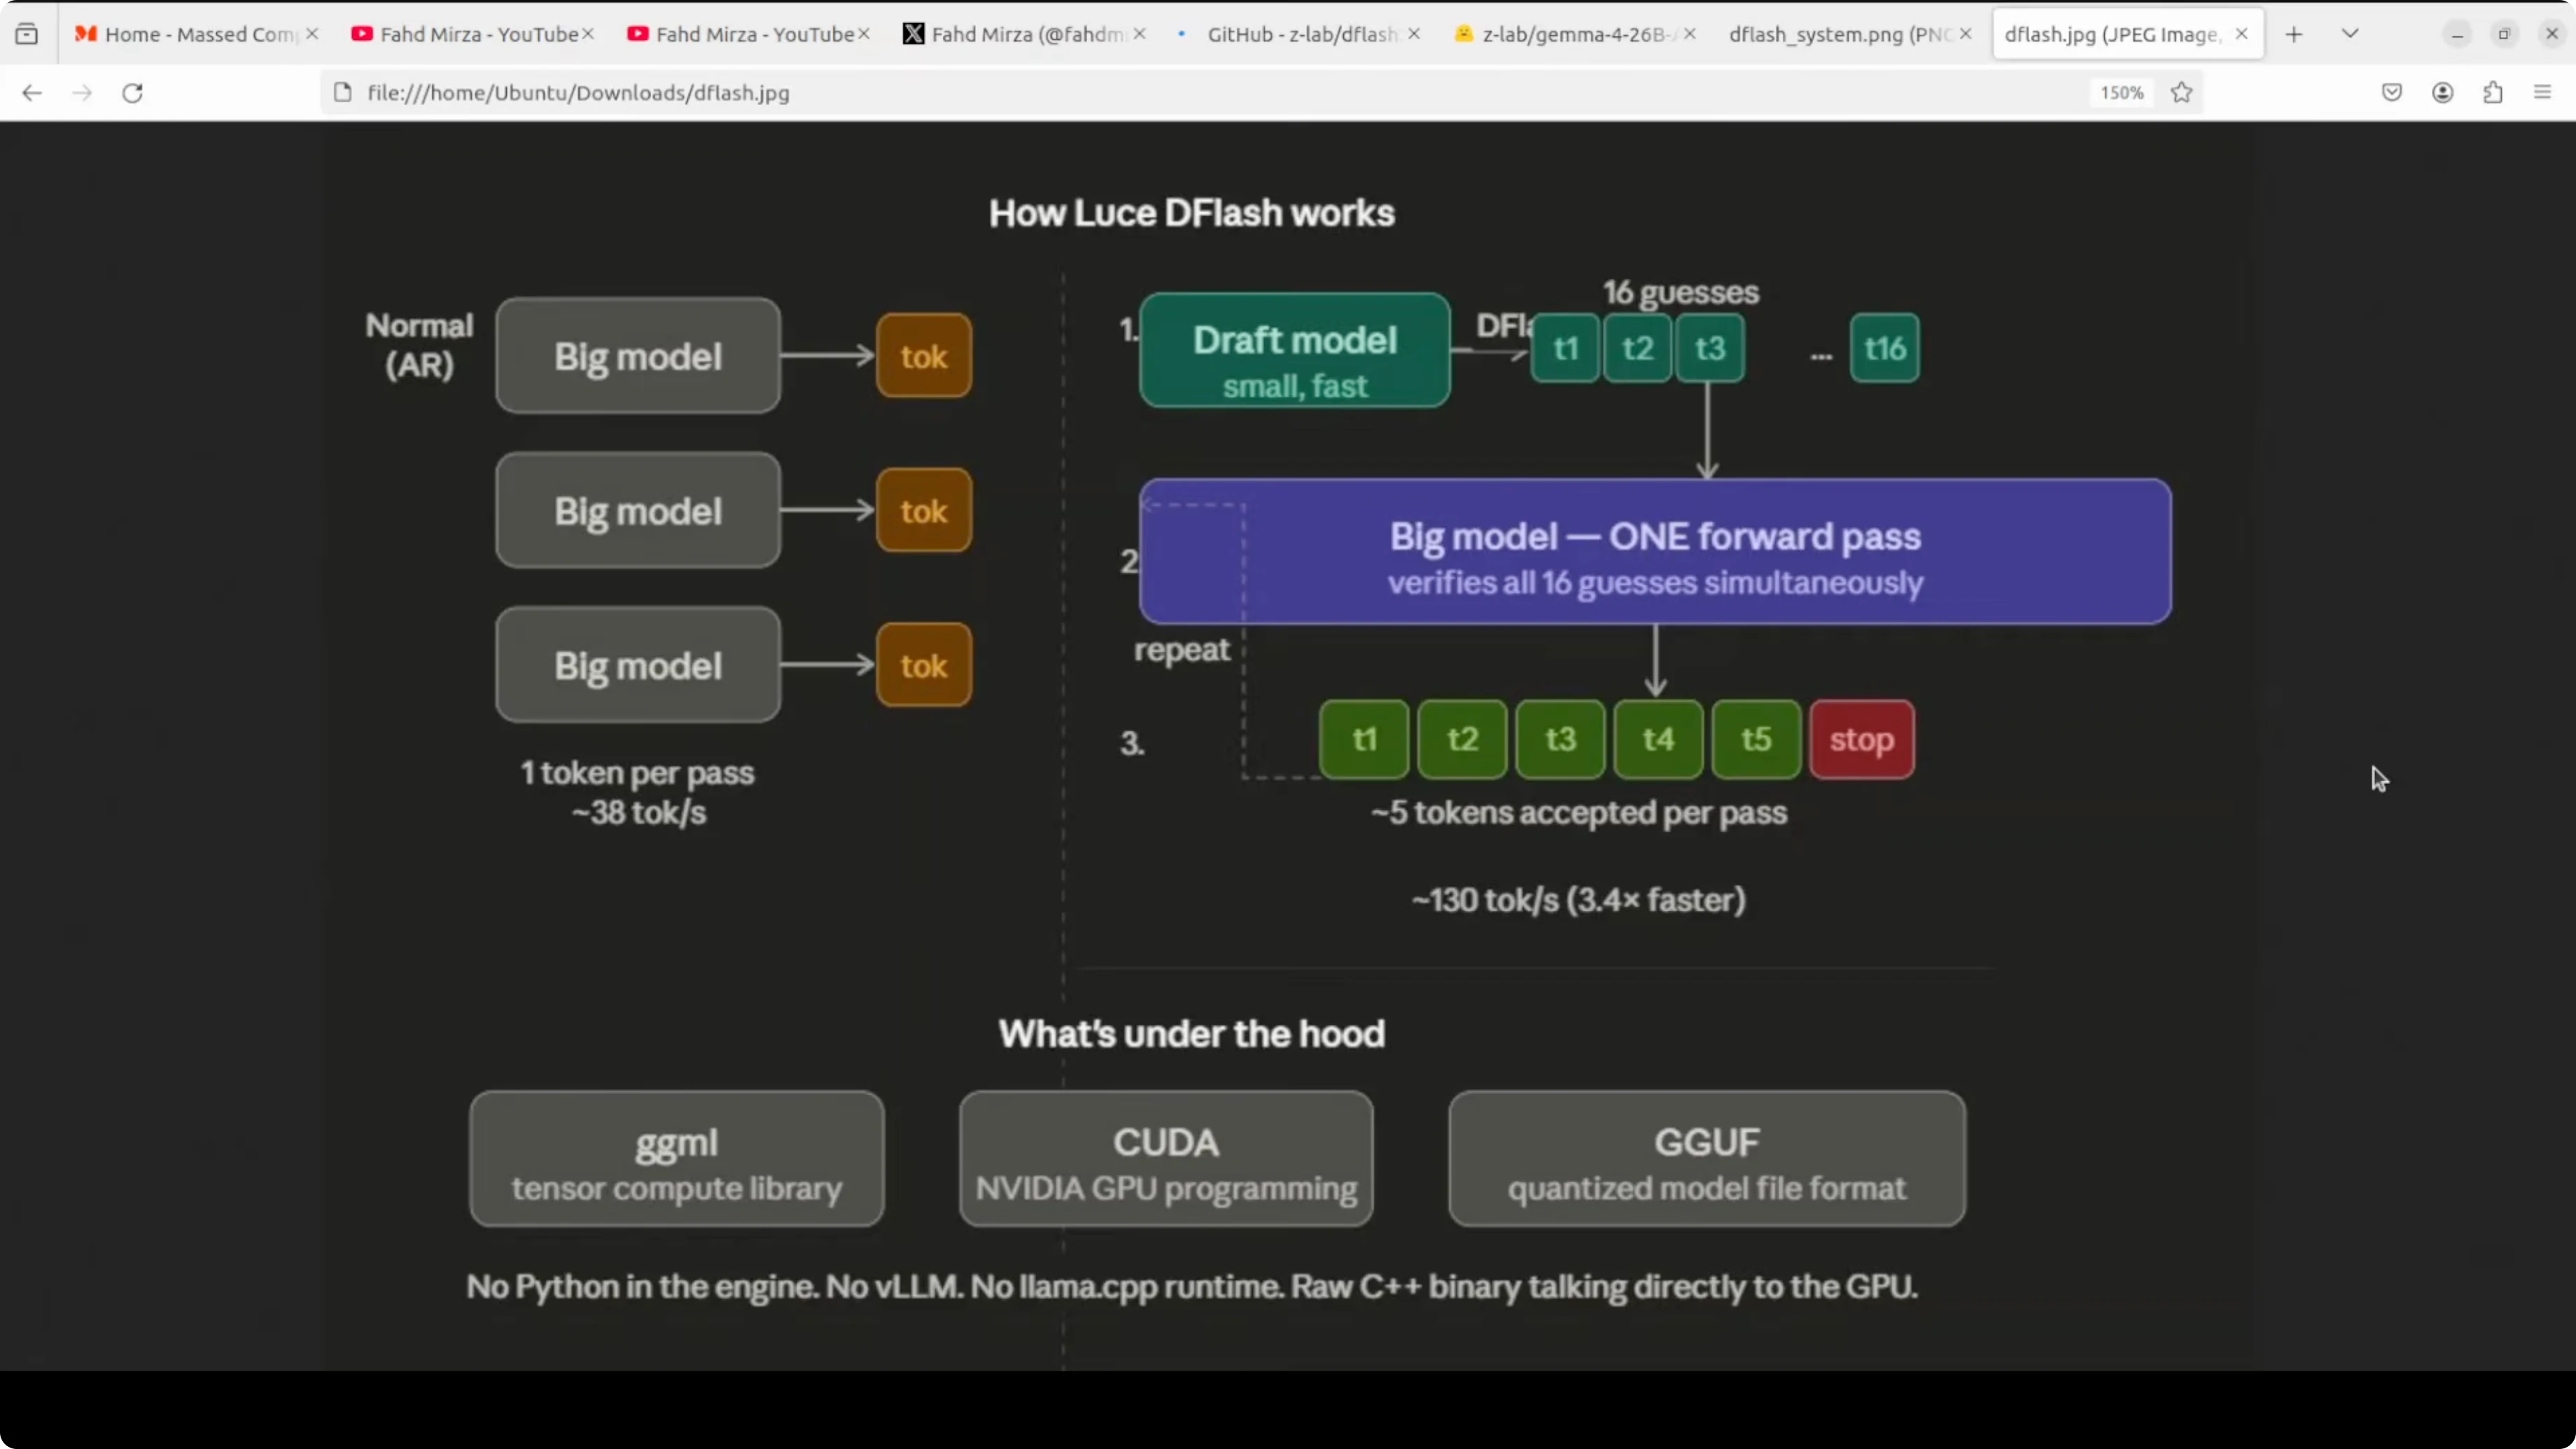
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
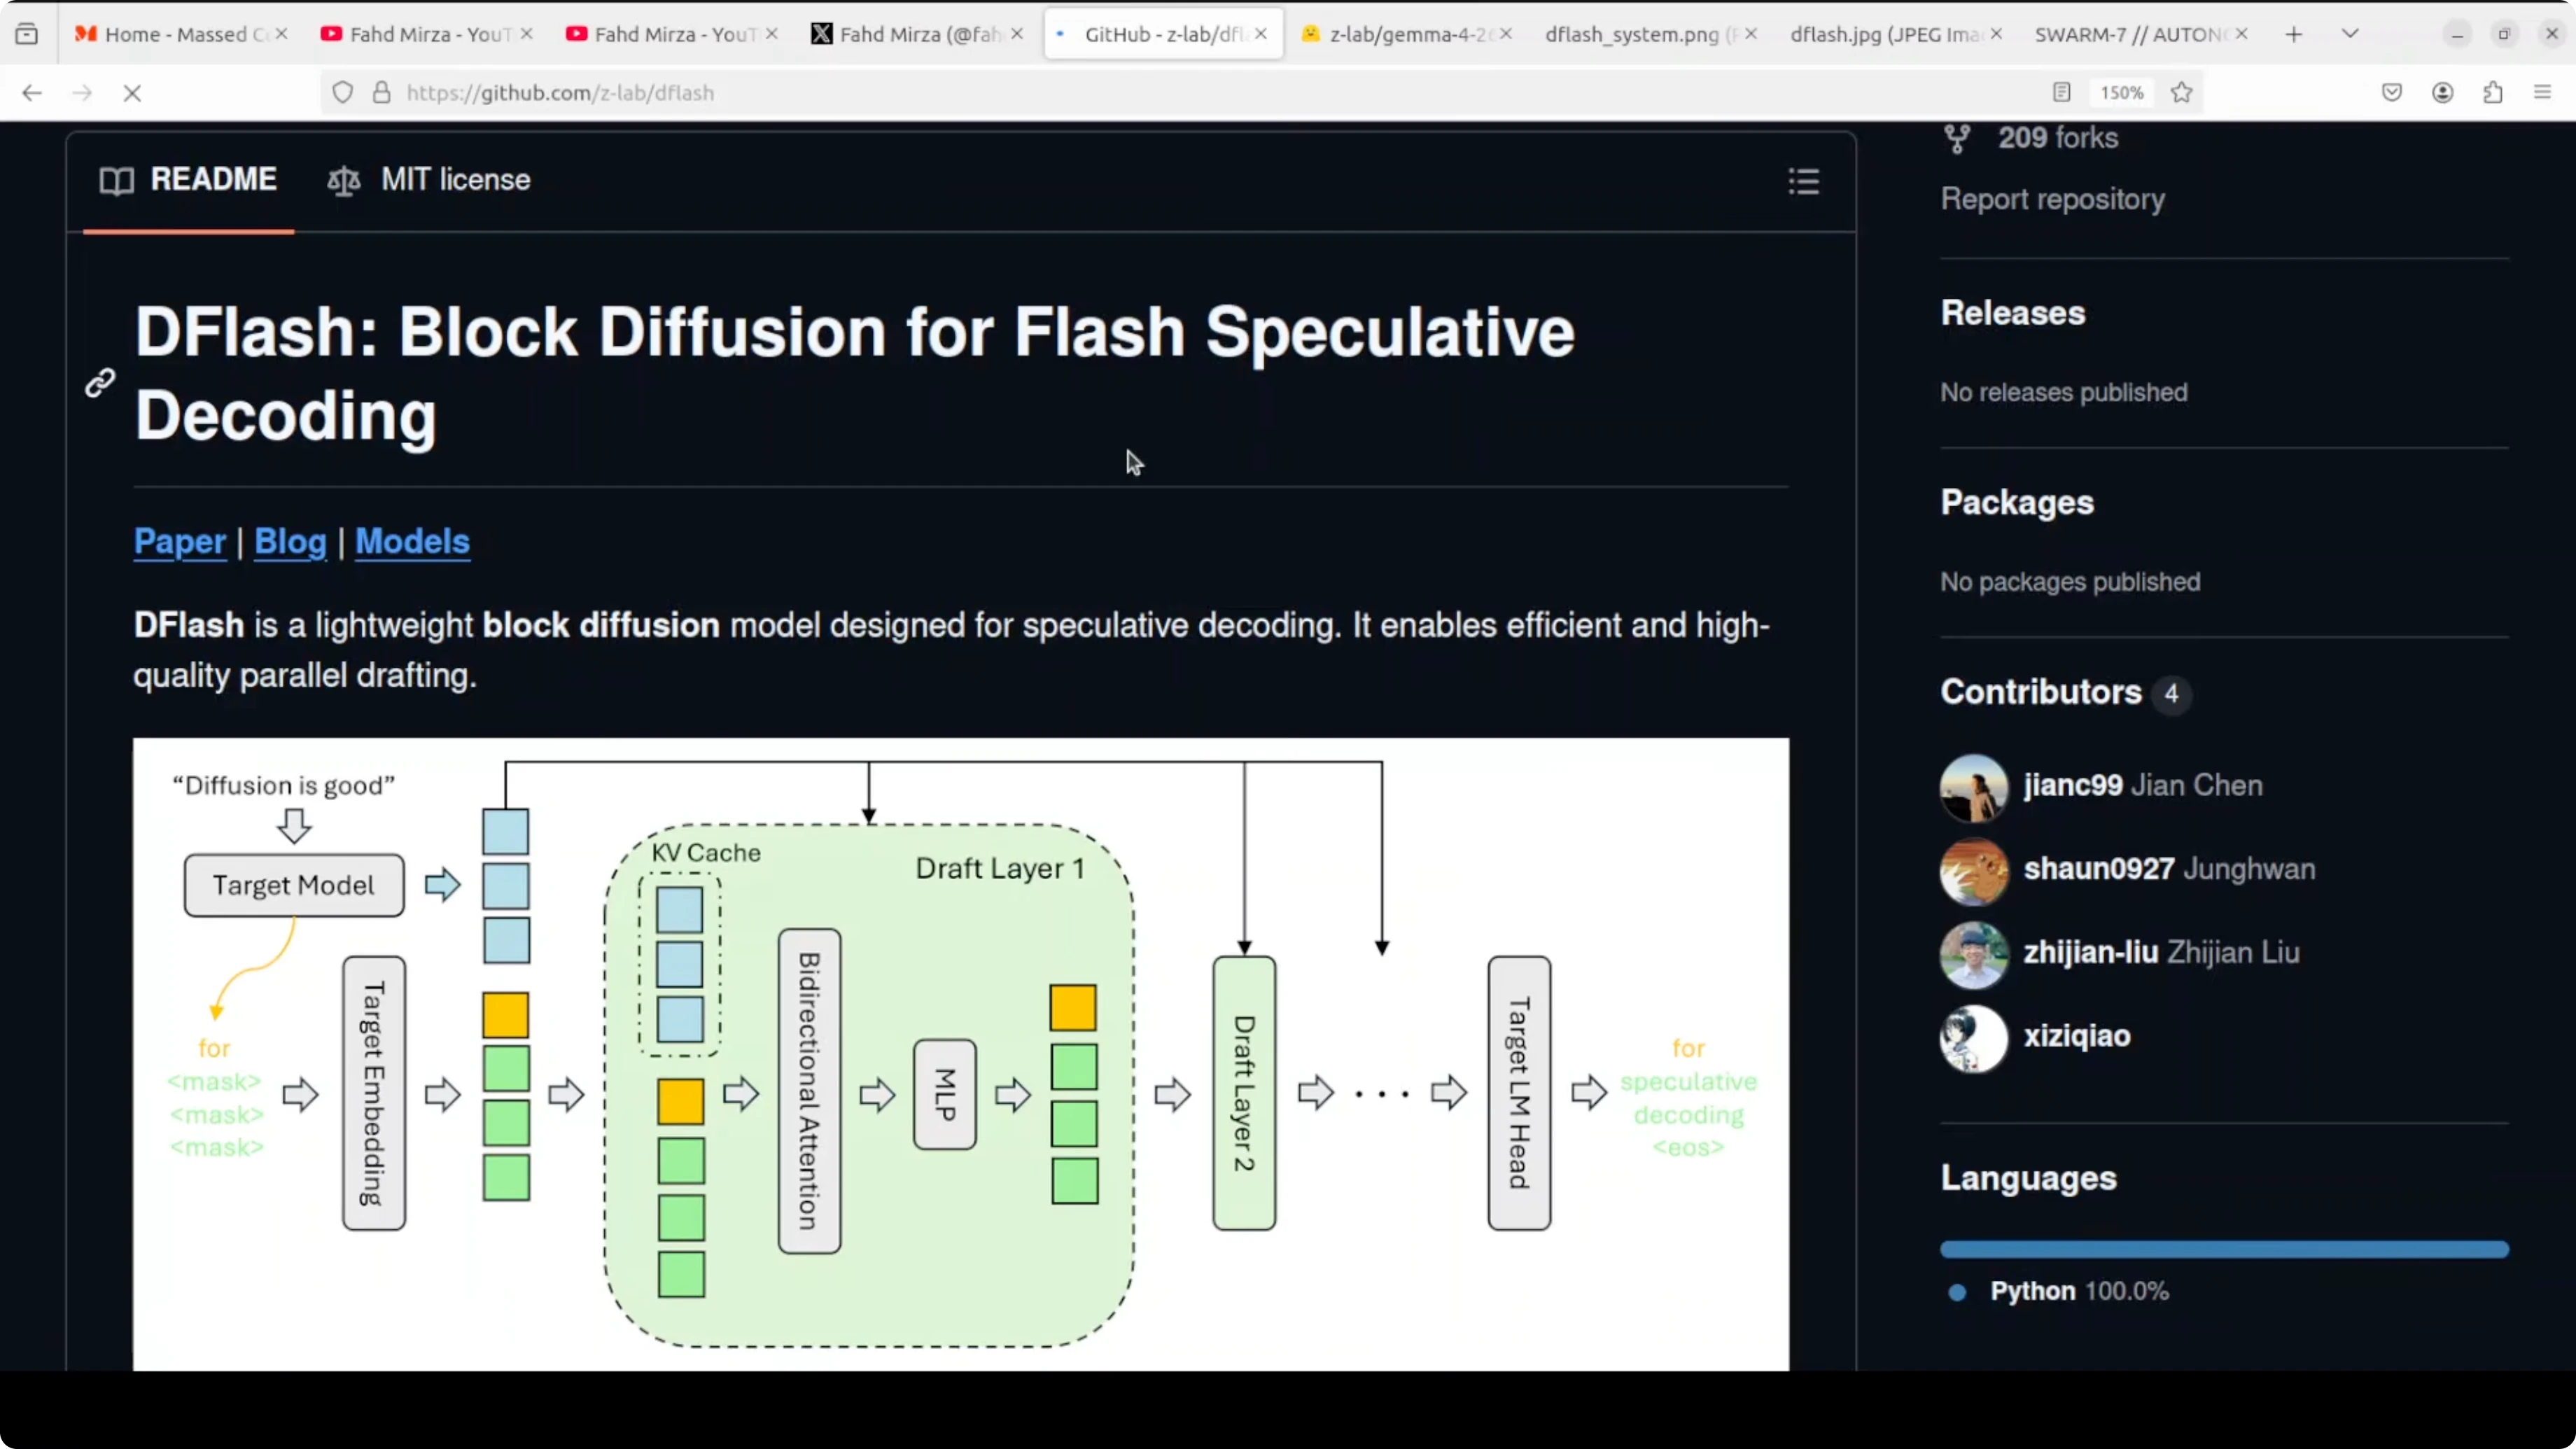
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
Diving into speculative decoding training support for vLLM with ...
Advertisement Space (300x250)
Deploy DFlash Speculative Decoding on vLLM (Gemma 4) | RavChat
Diving into speculative decoding training support for vLLM with ...
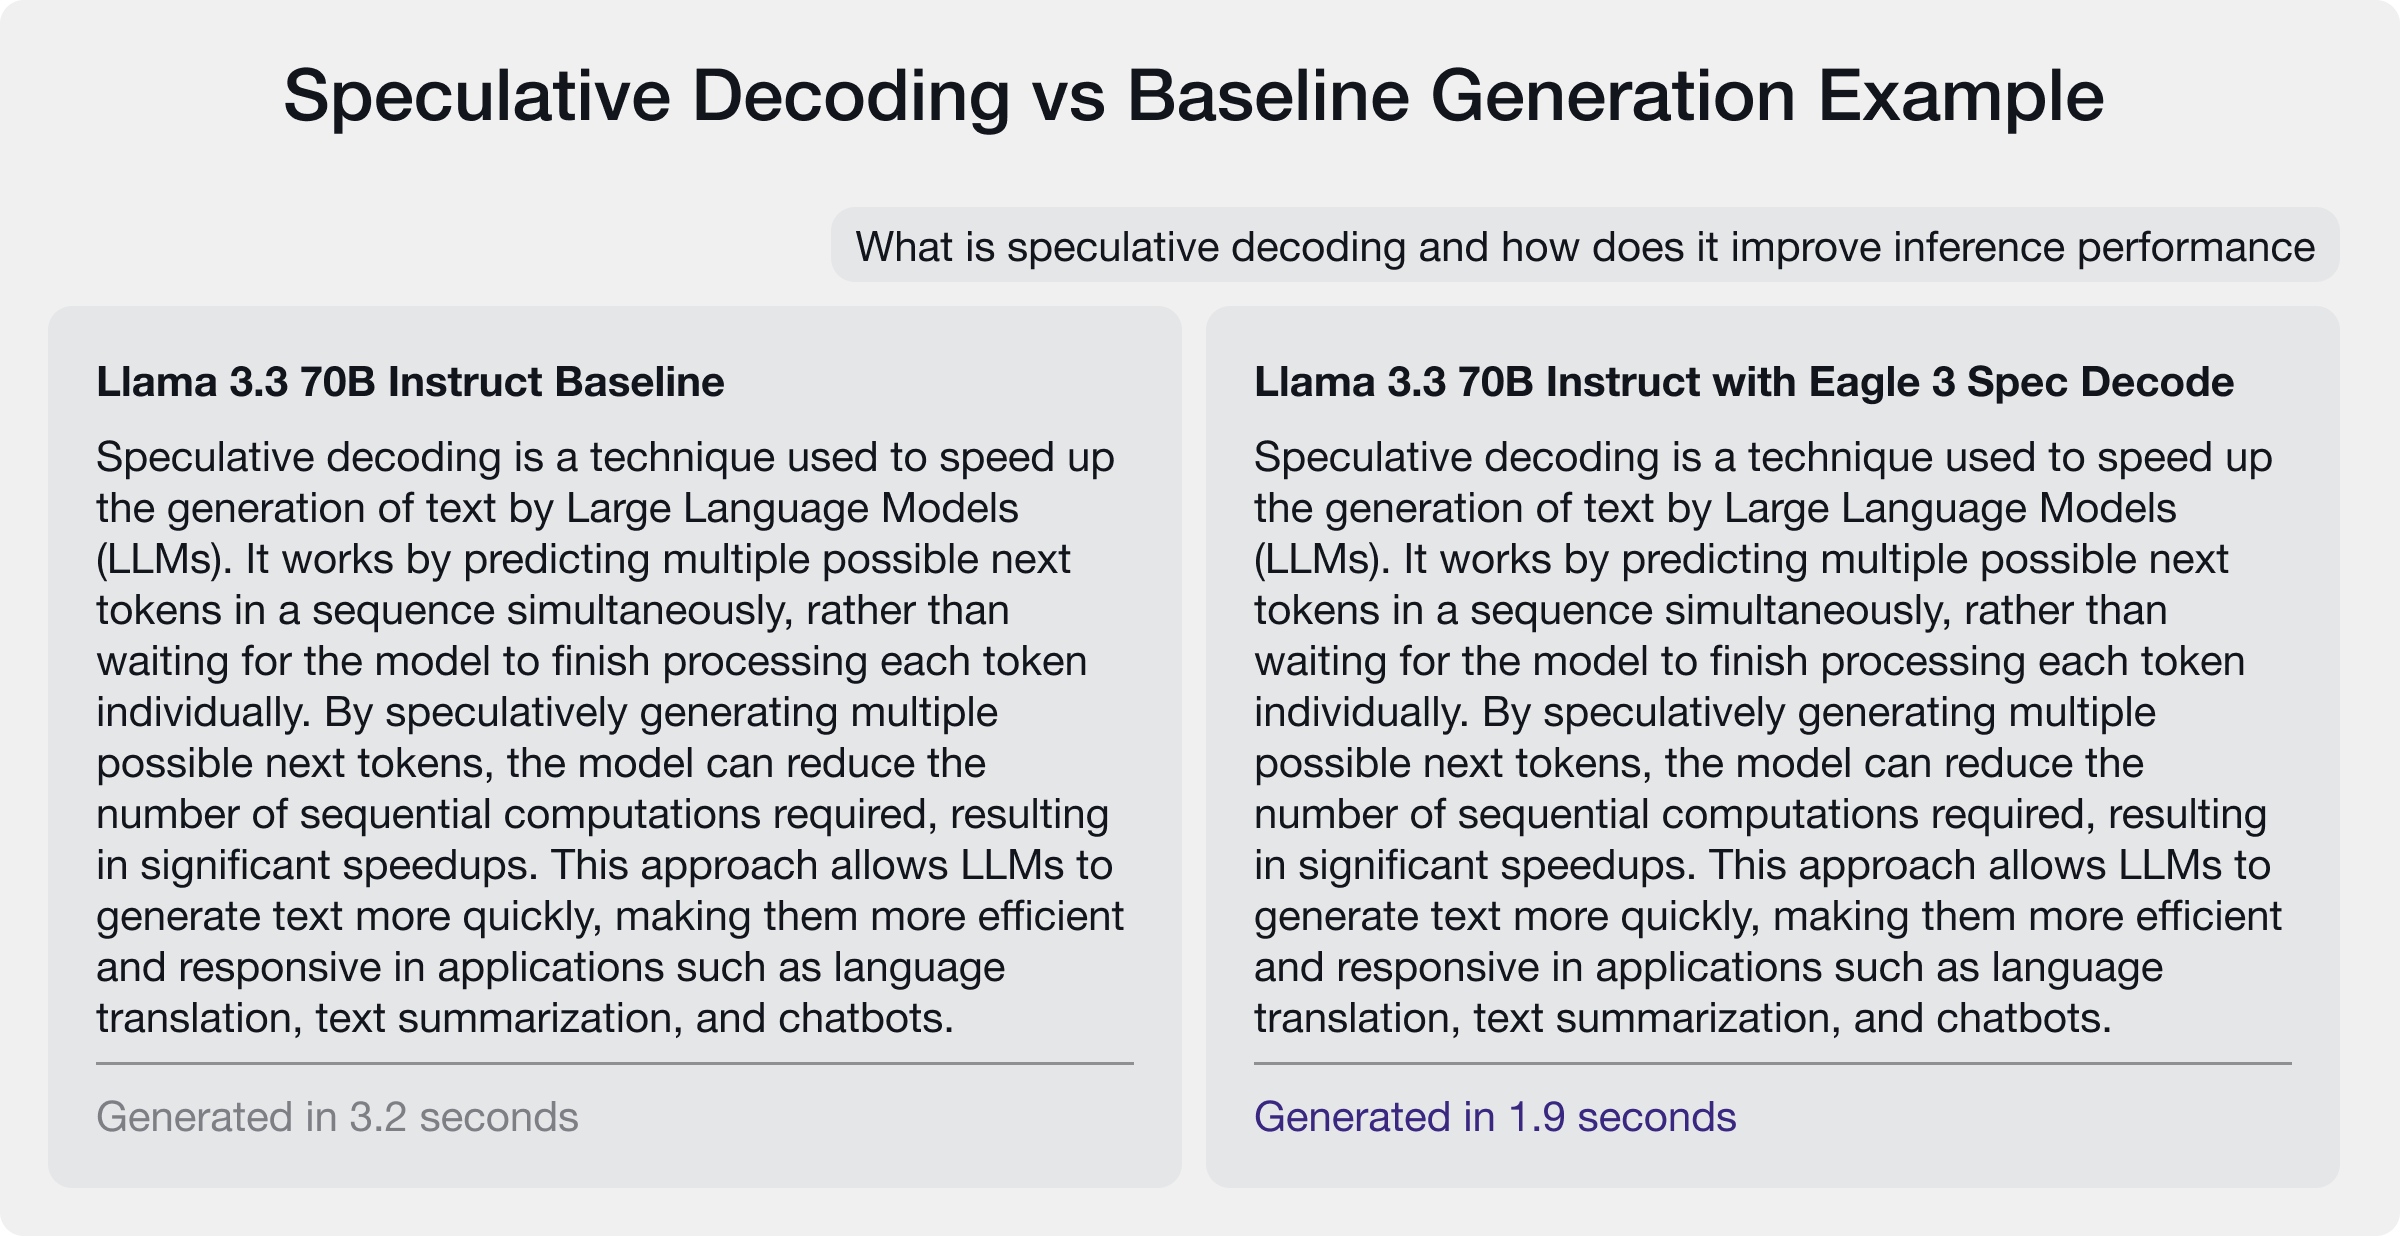
Faster inference with vLLM & speculative decoding | Red Hat Developer

Great systematic study on speculative decoding in vLLM 🔬 Thorough and ...
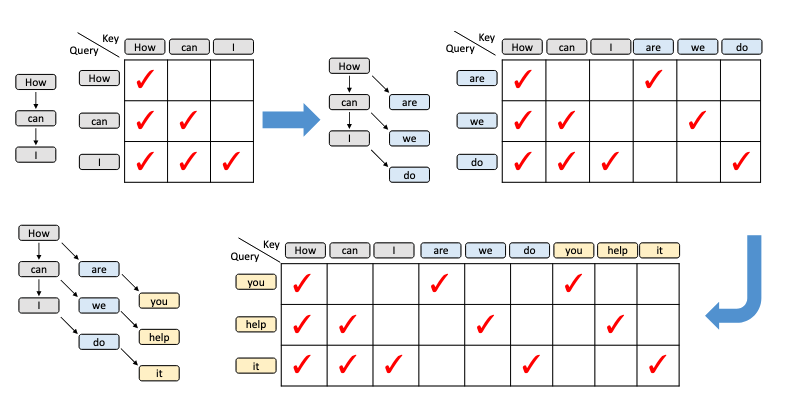
Diving into speculative decoding training support for vLLM with ...
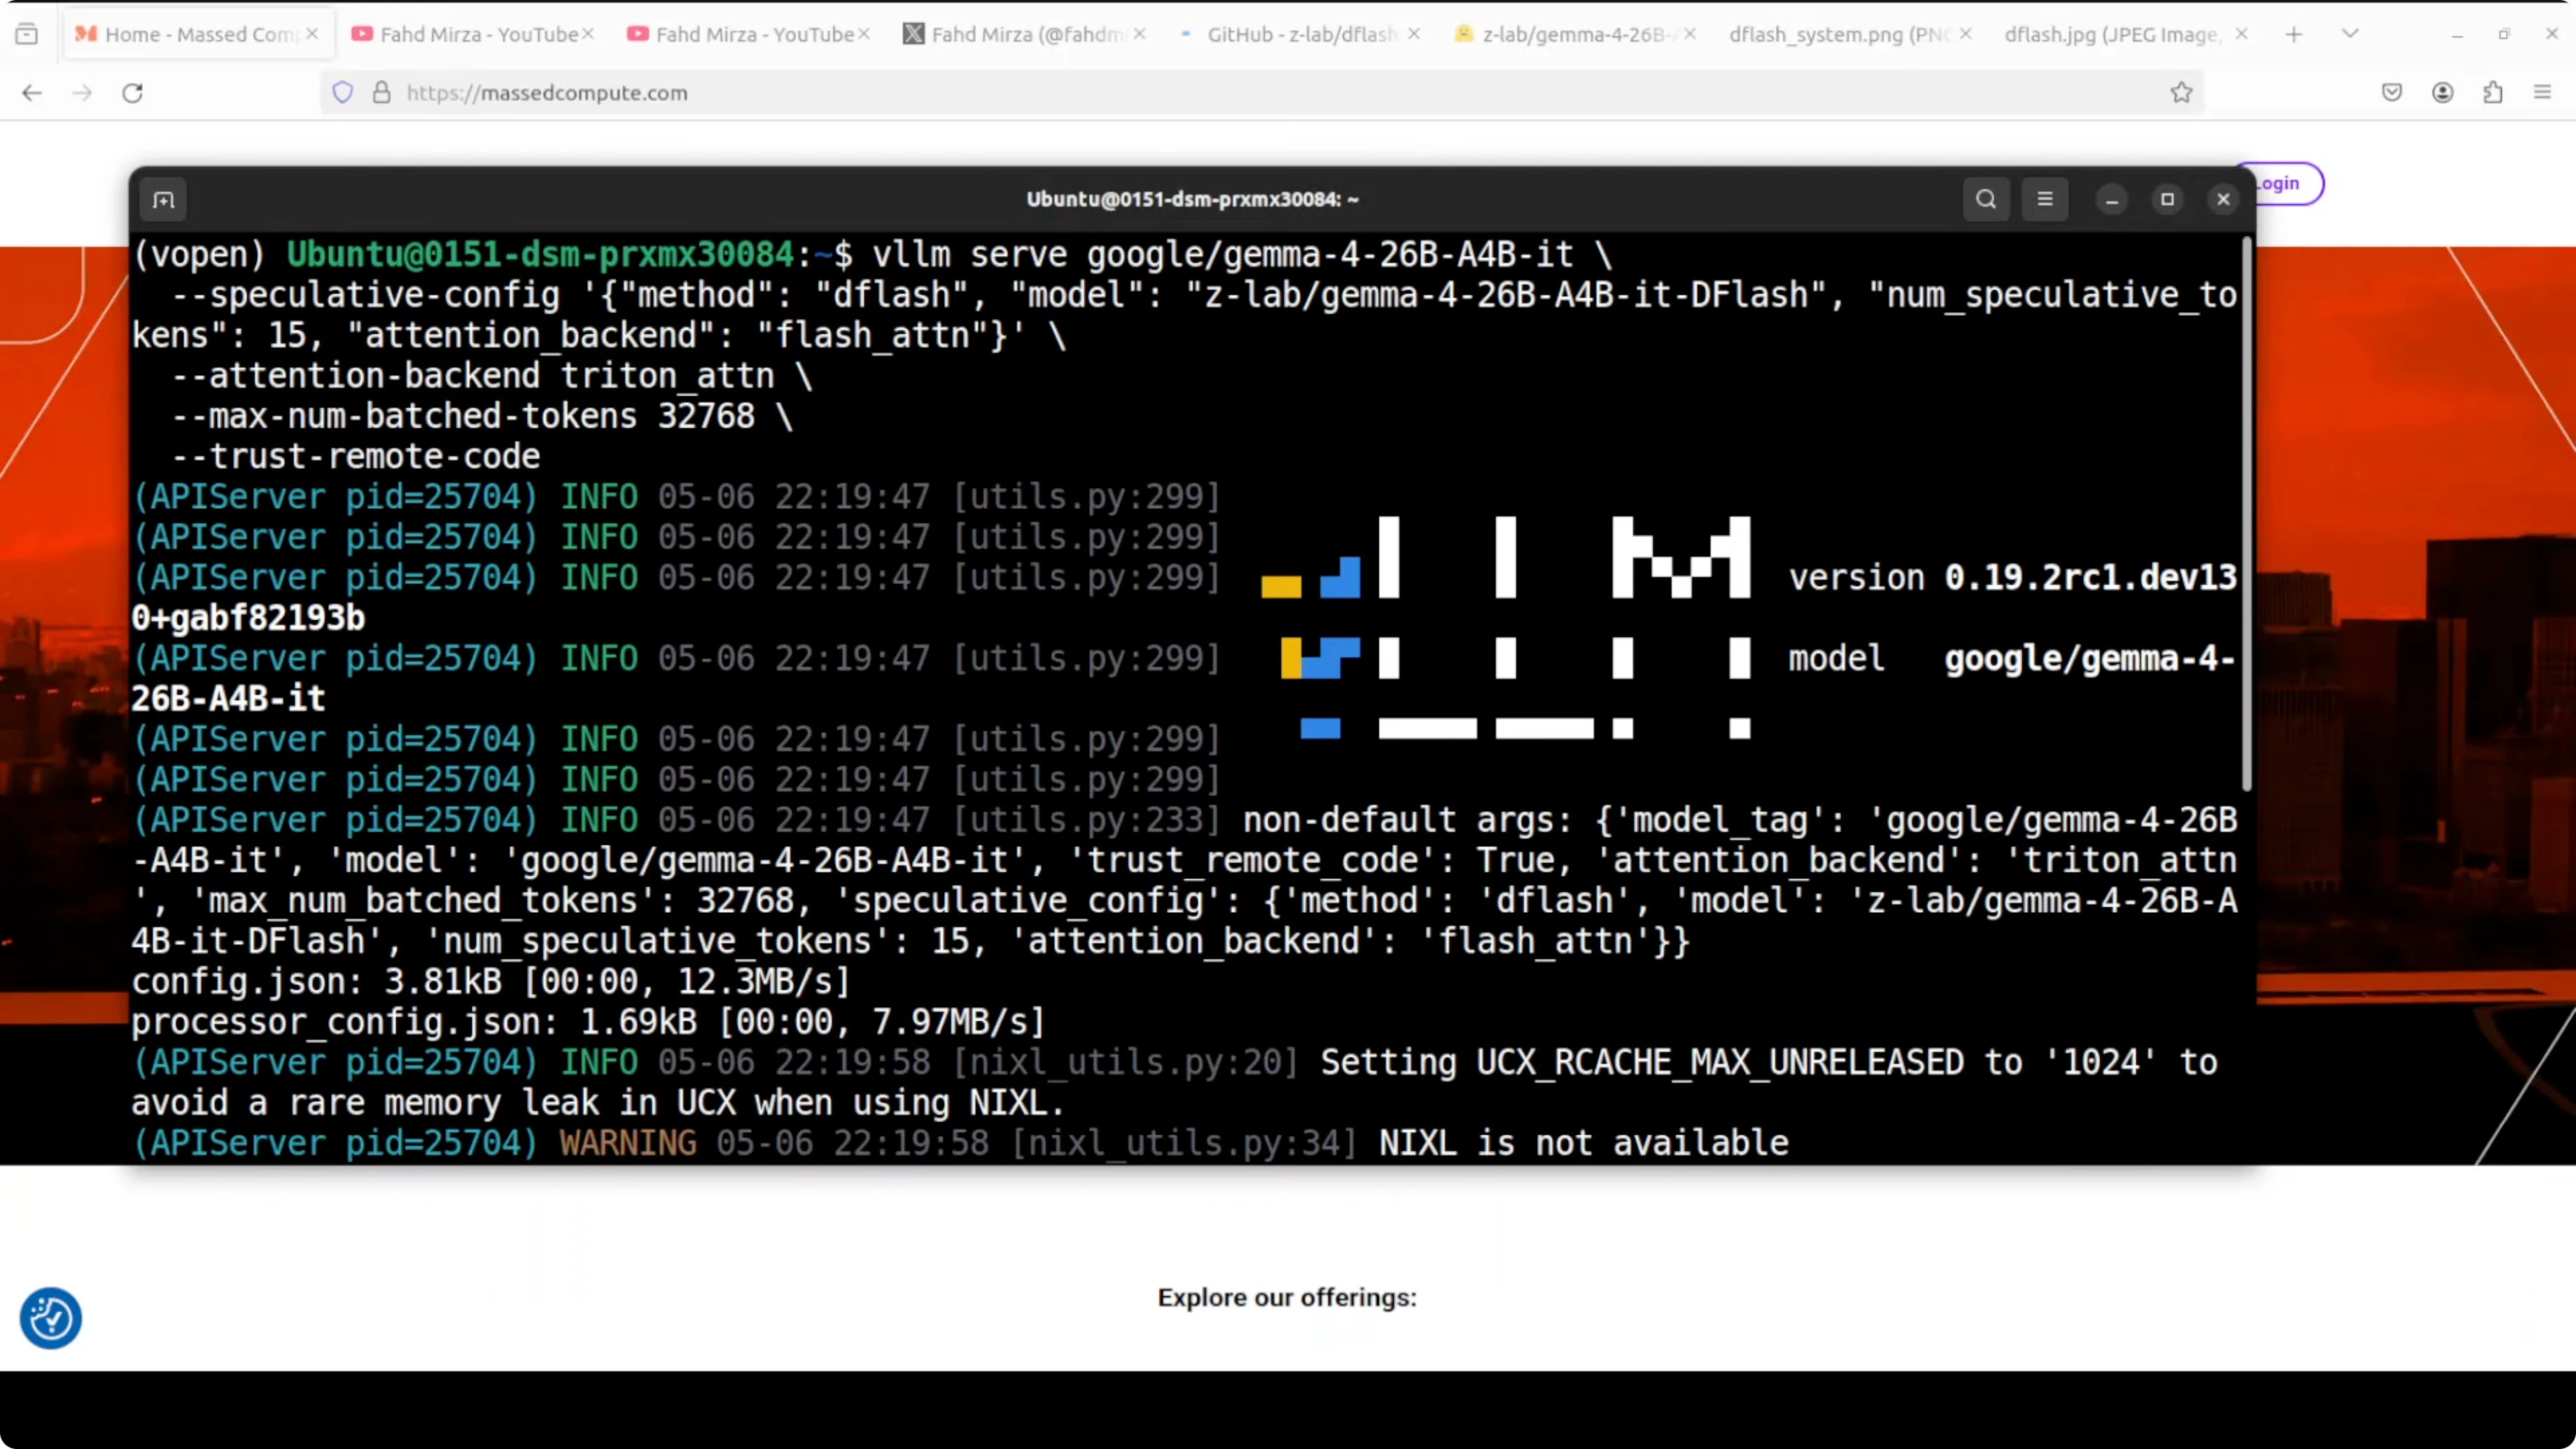
DFlash Drafter for Gemma 4 26B: Run Speculative Decoding Locally
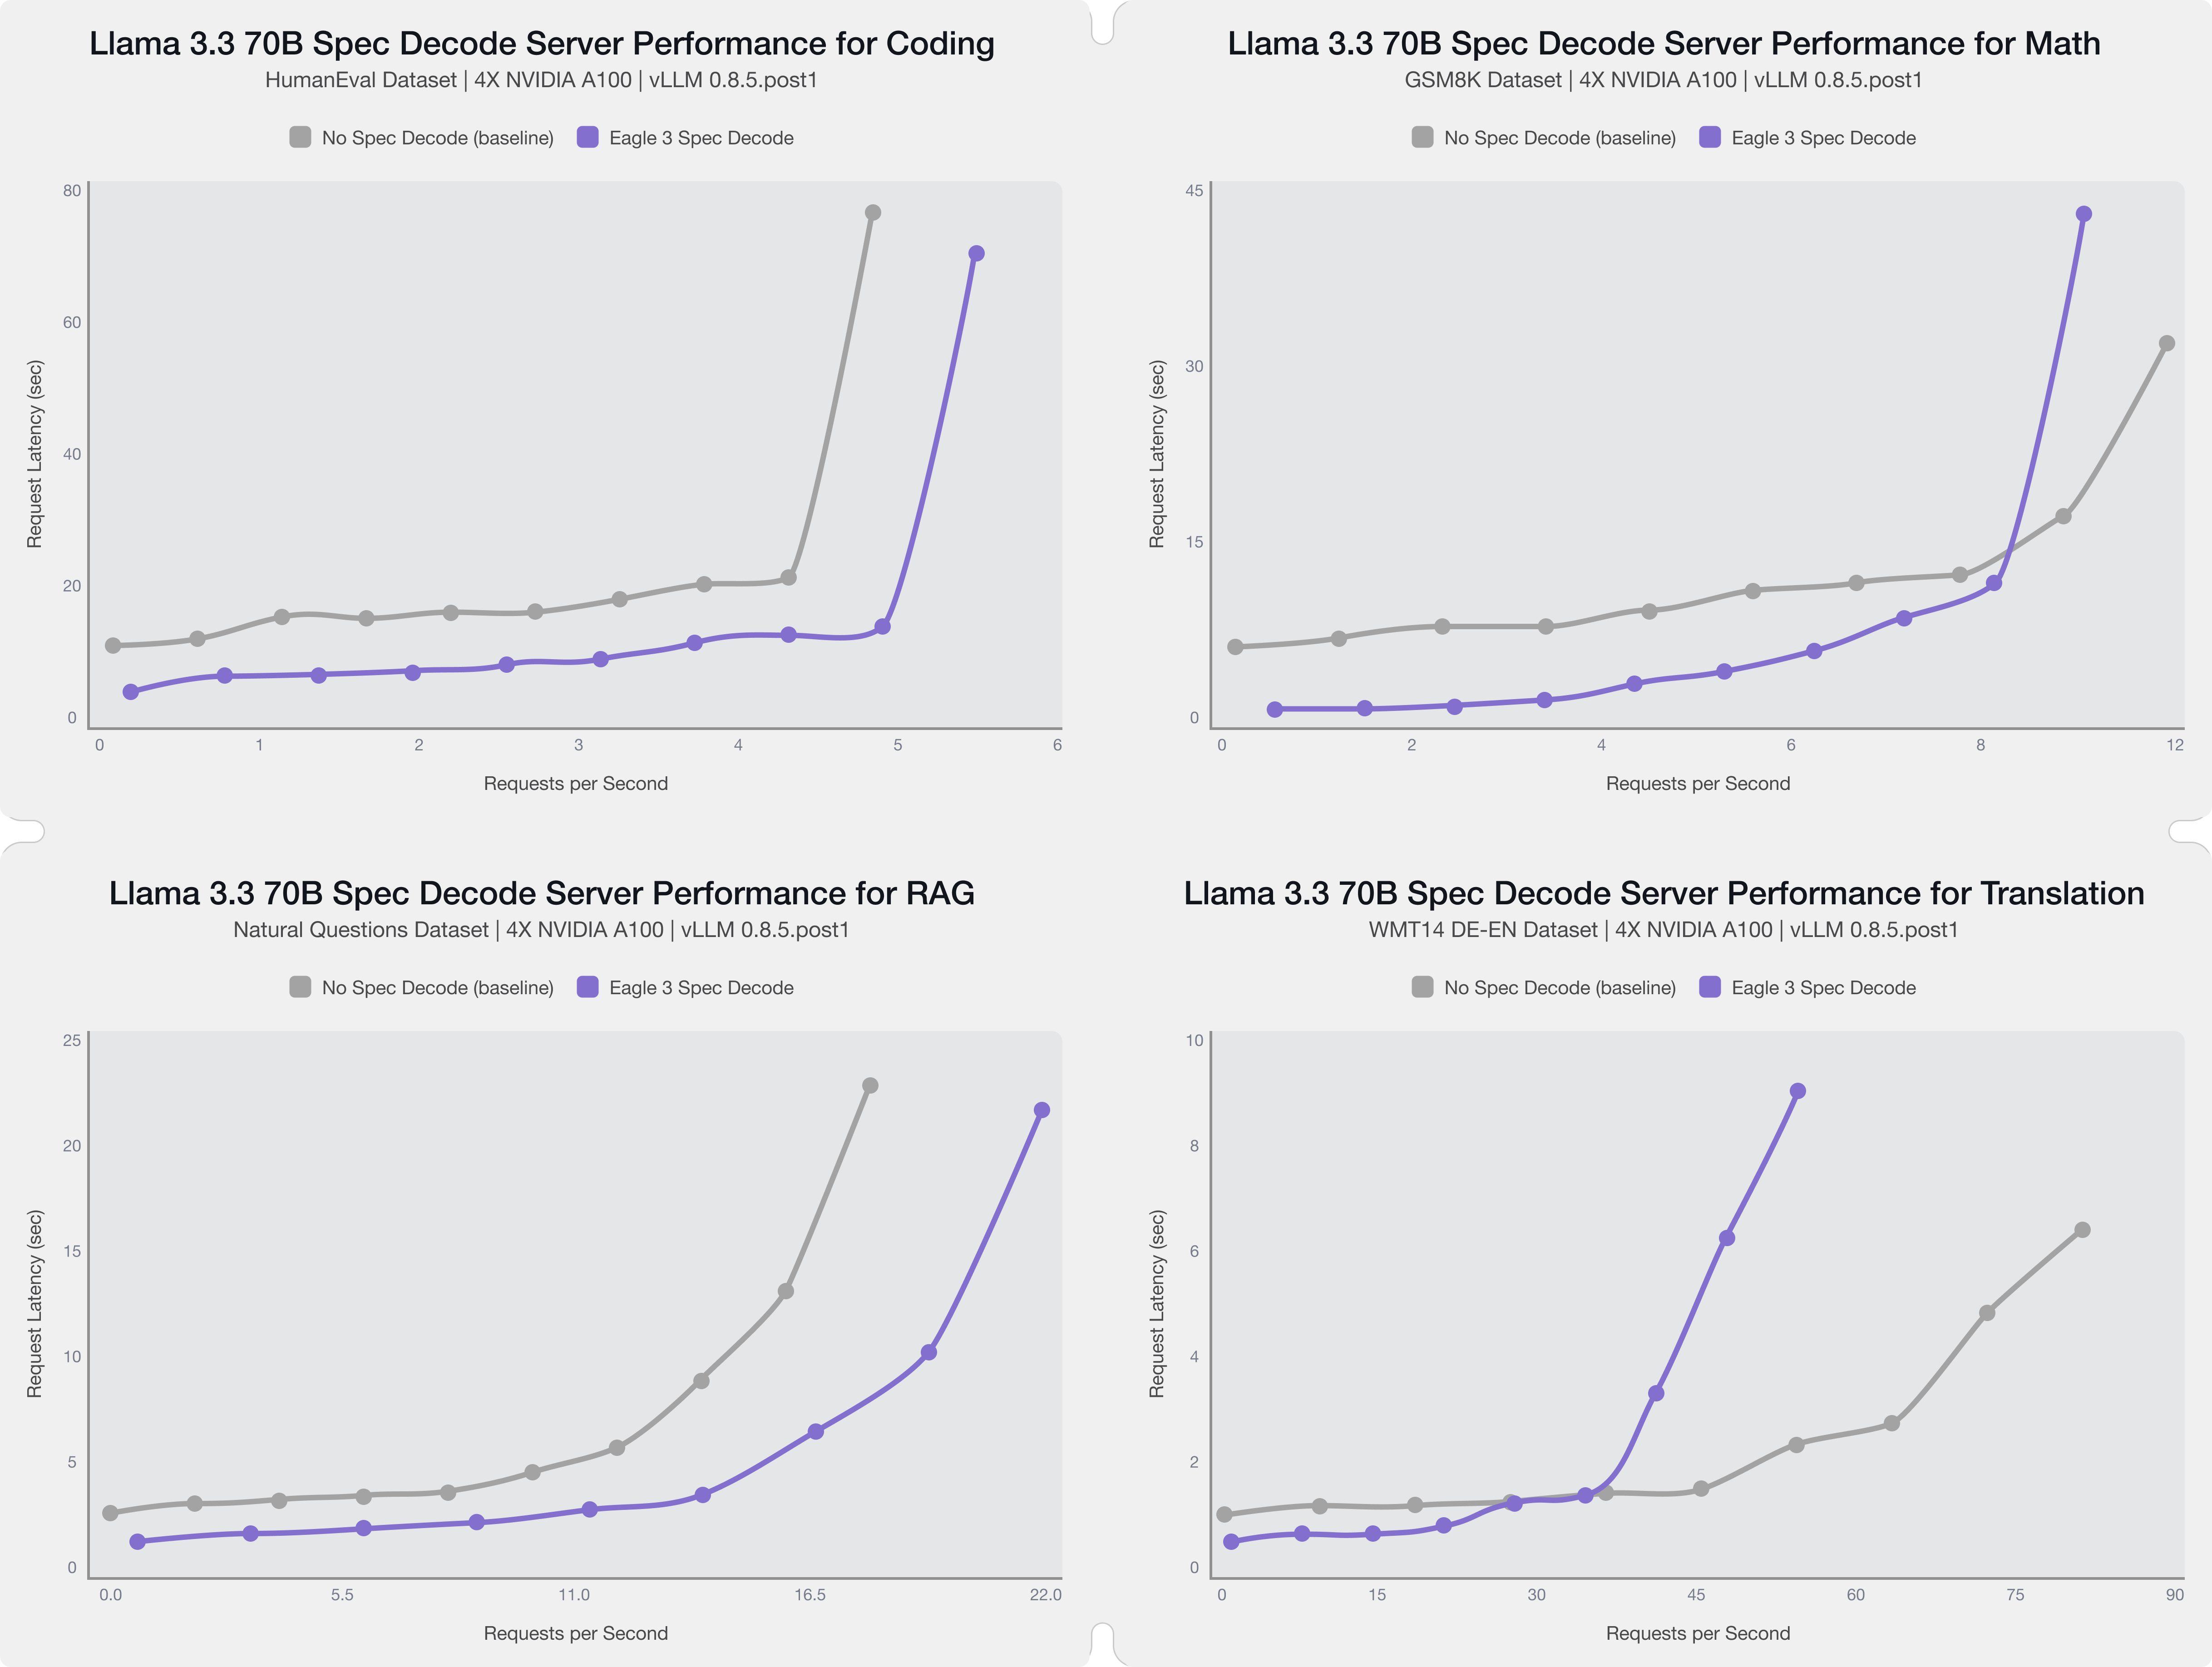
Faster inference with vLLM & speculative decoding | Red Hat Developer
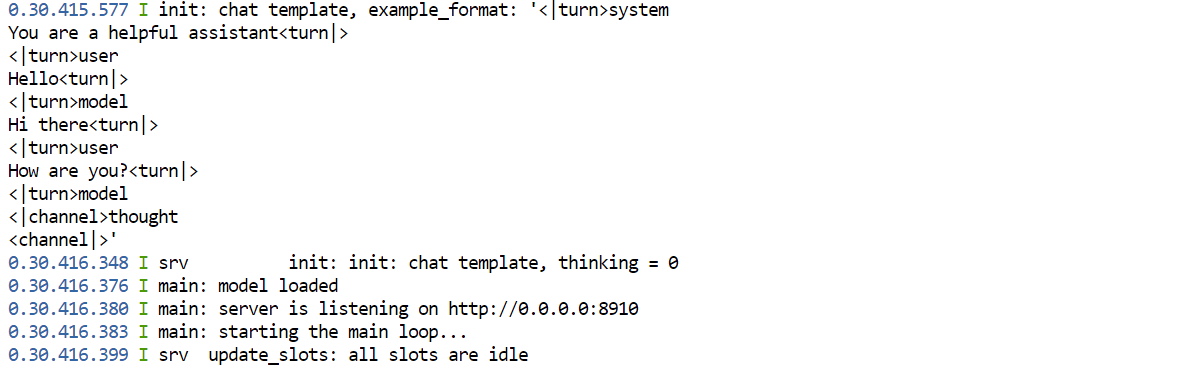
How to Speed Up Local LLMs with DFlash Speculative Decoding | DataCamp
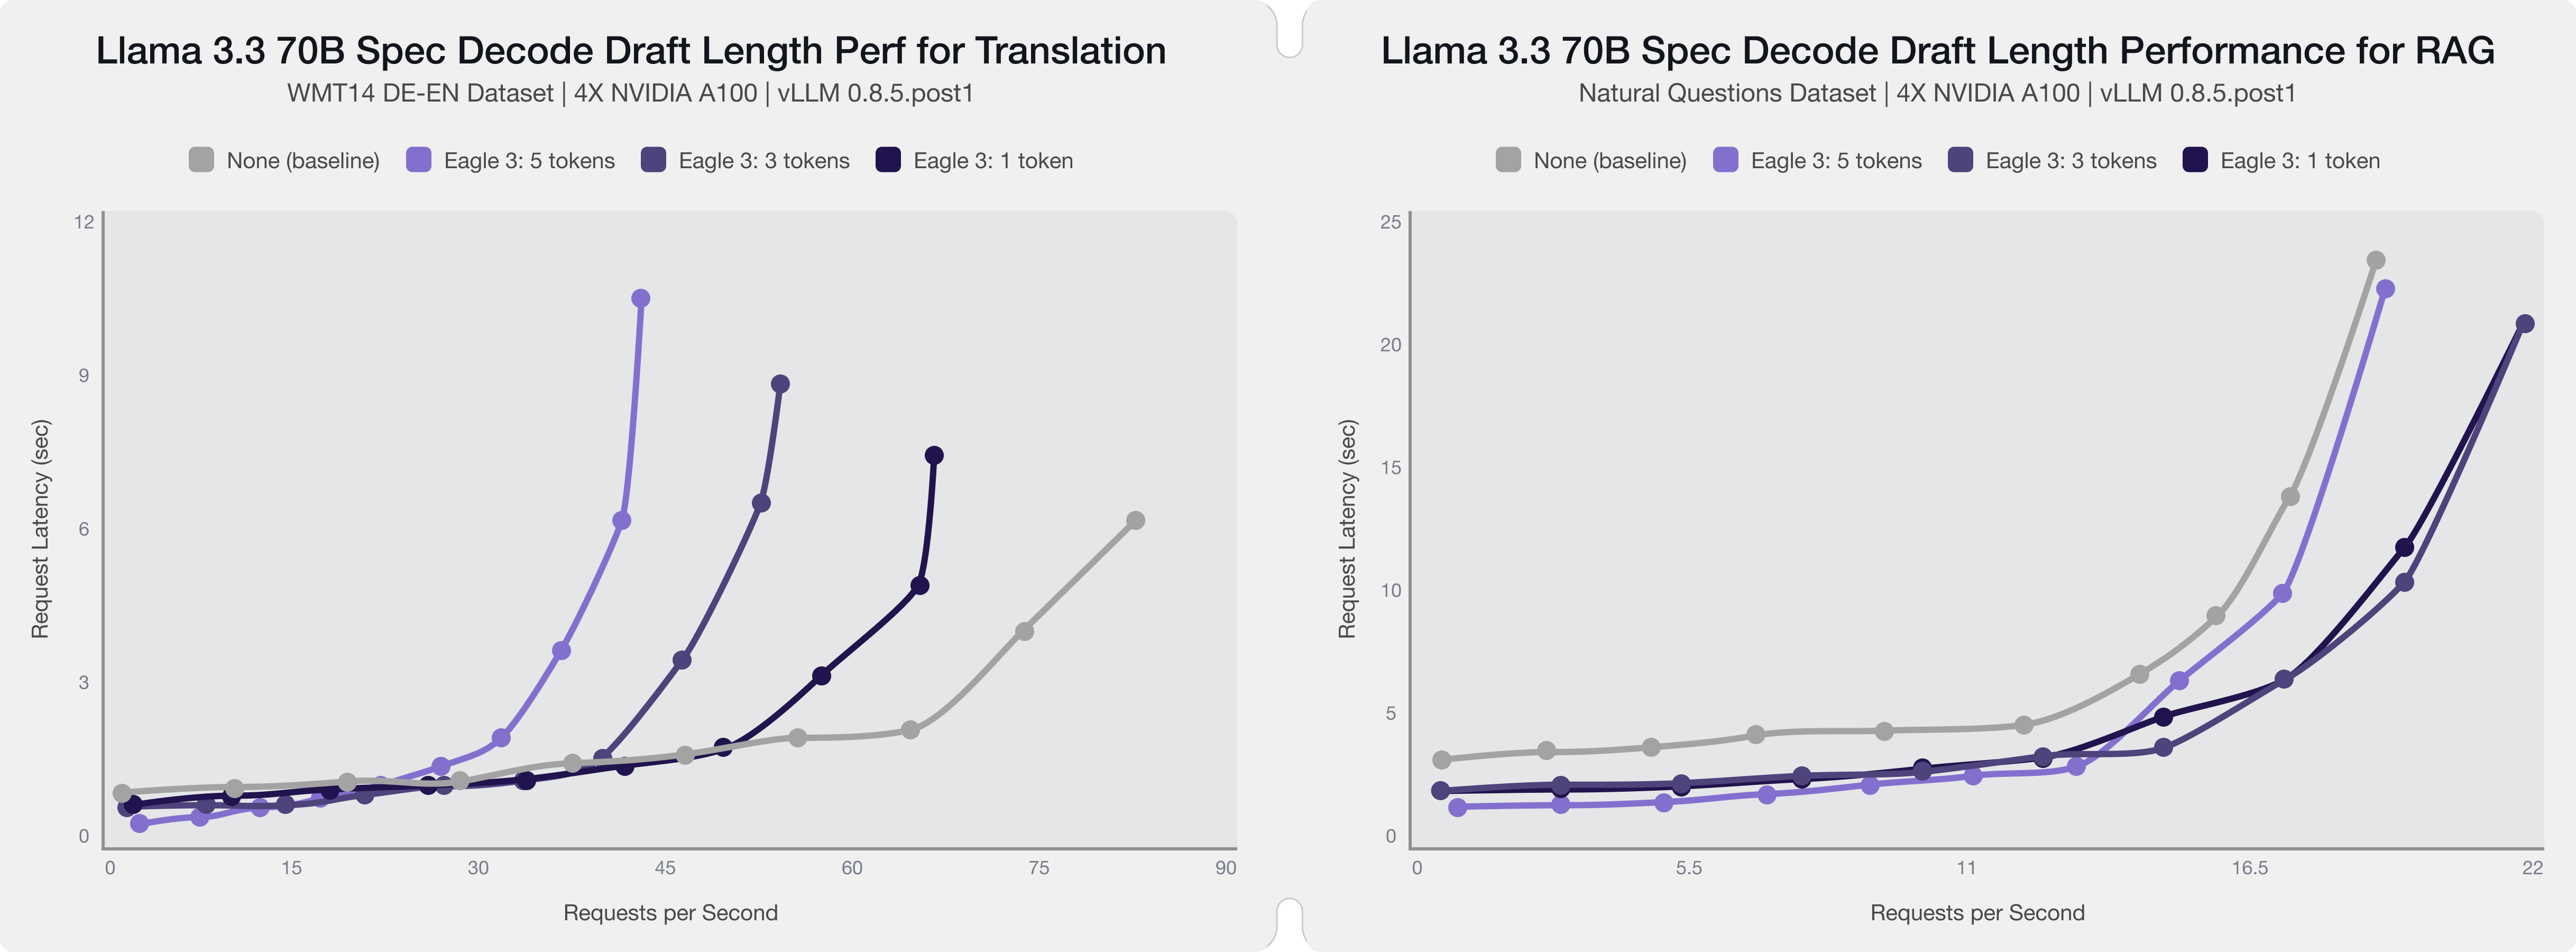
Faster inference with vLLM & speculative decoding | Red Hat Developer

Speculative Decoding for Free: Pairing DFlash with our DFO-Tuned Gemma ...
Advertisement Space (336x280)
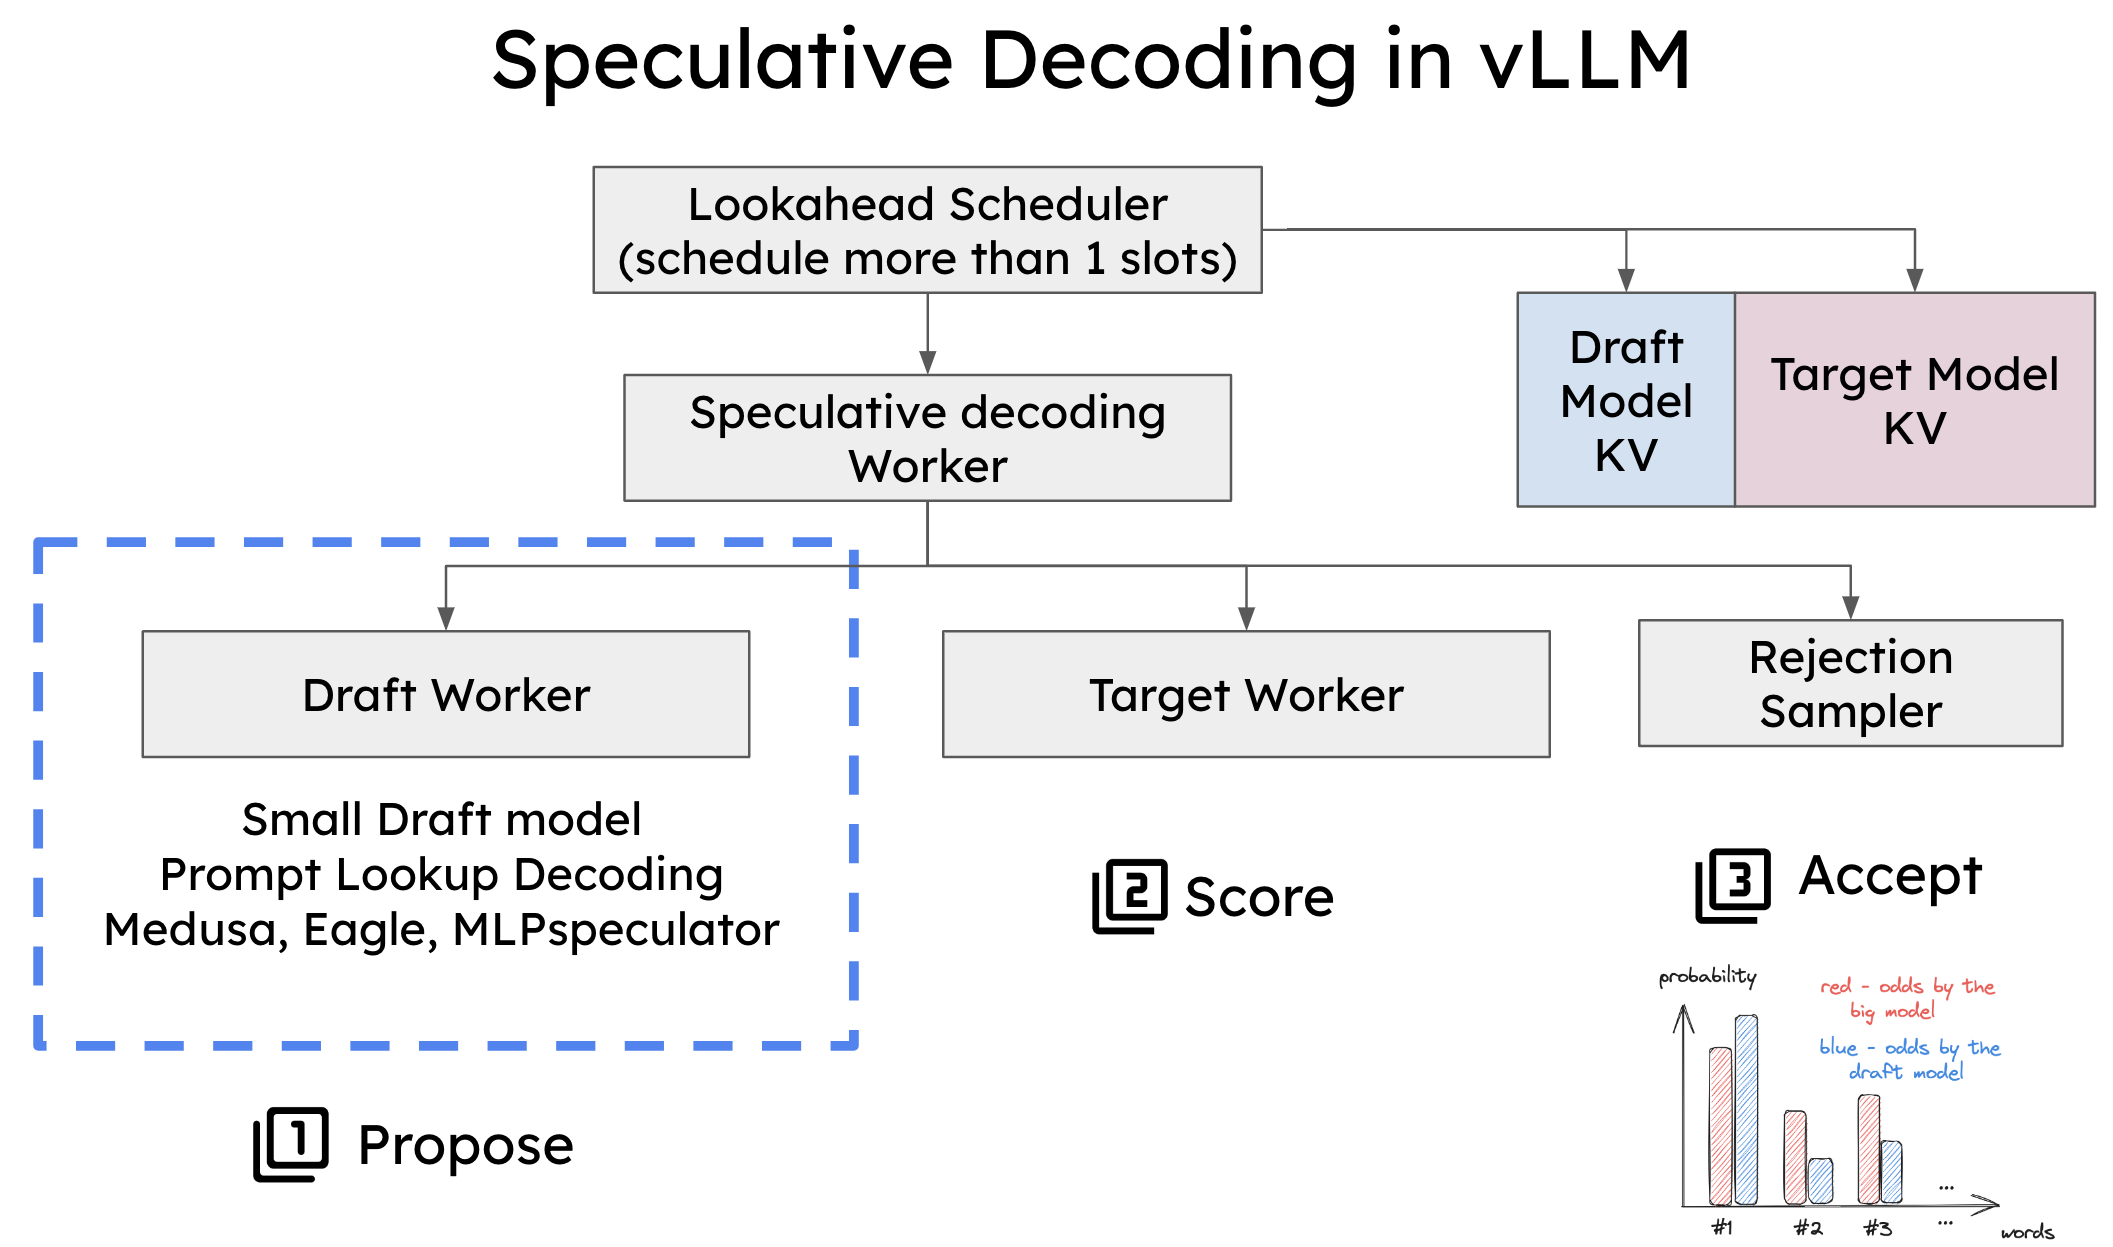
Speculative Decoding in vLLM | OpenLM.ai
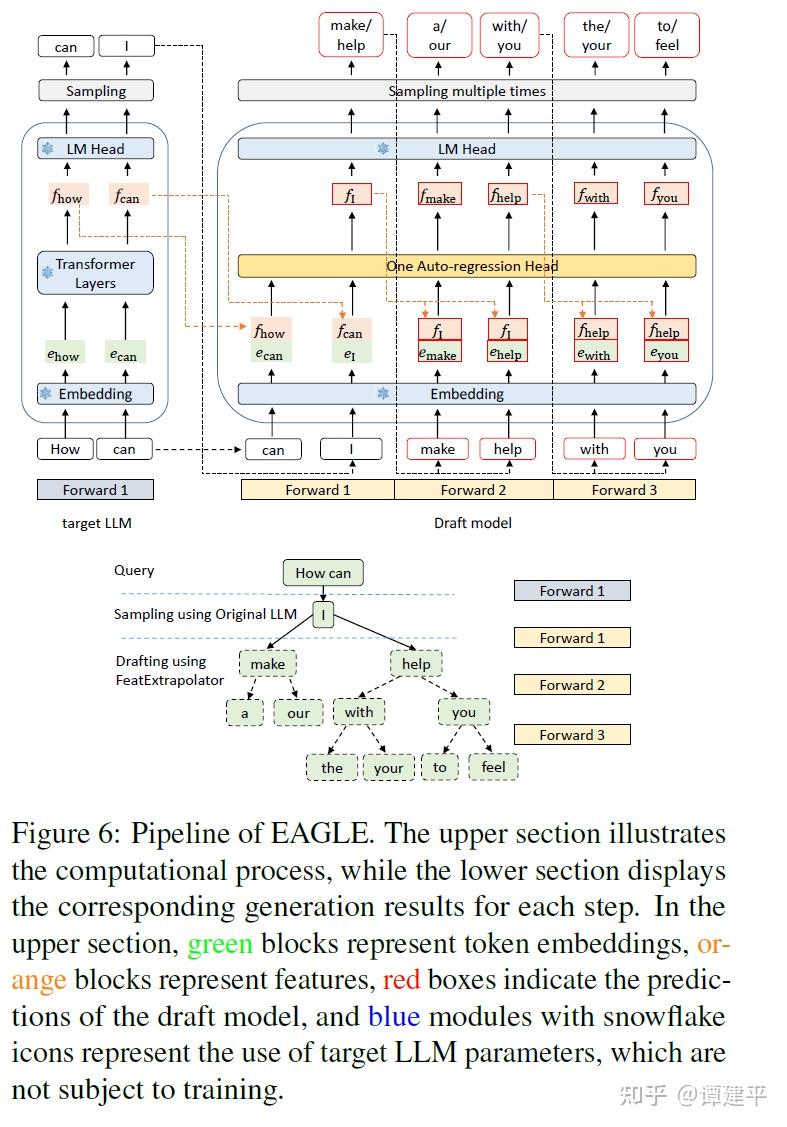
vllm Speculative decoding 论文整理总结 - 知乎
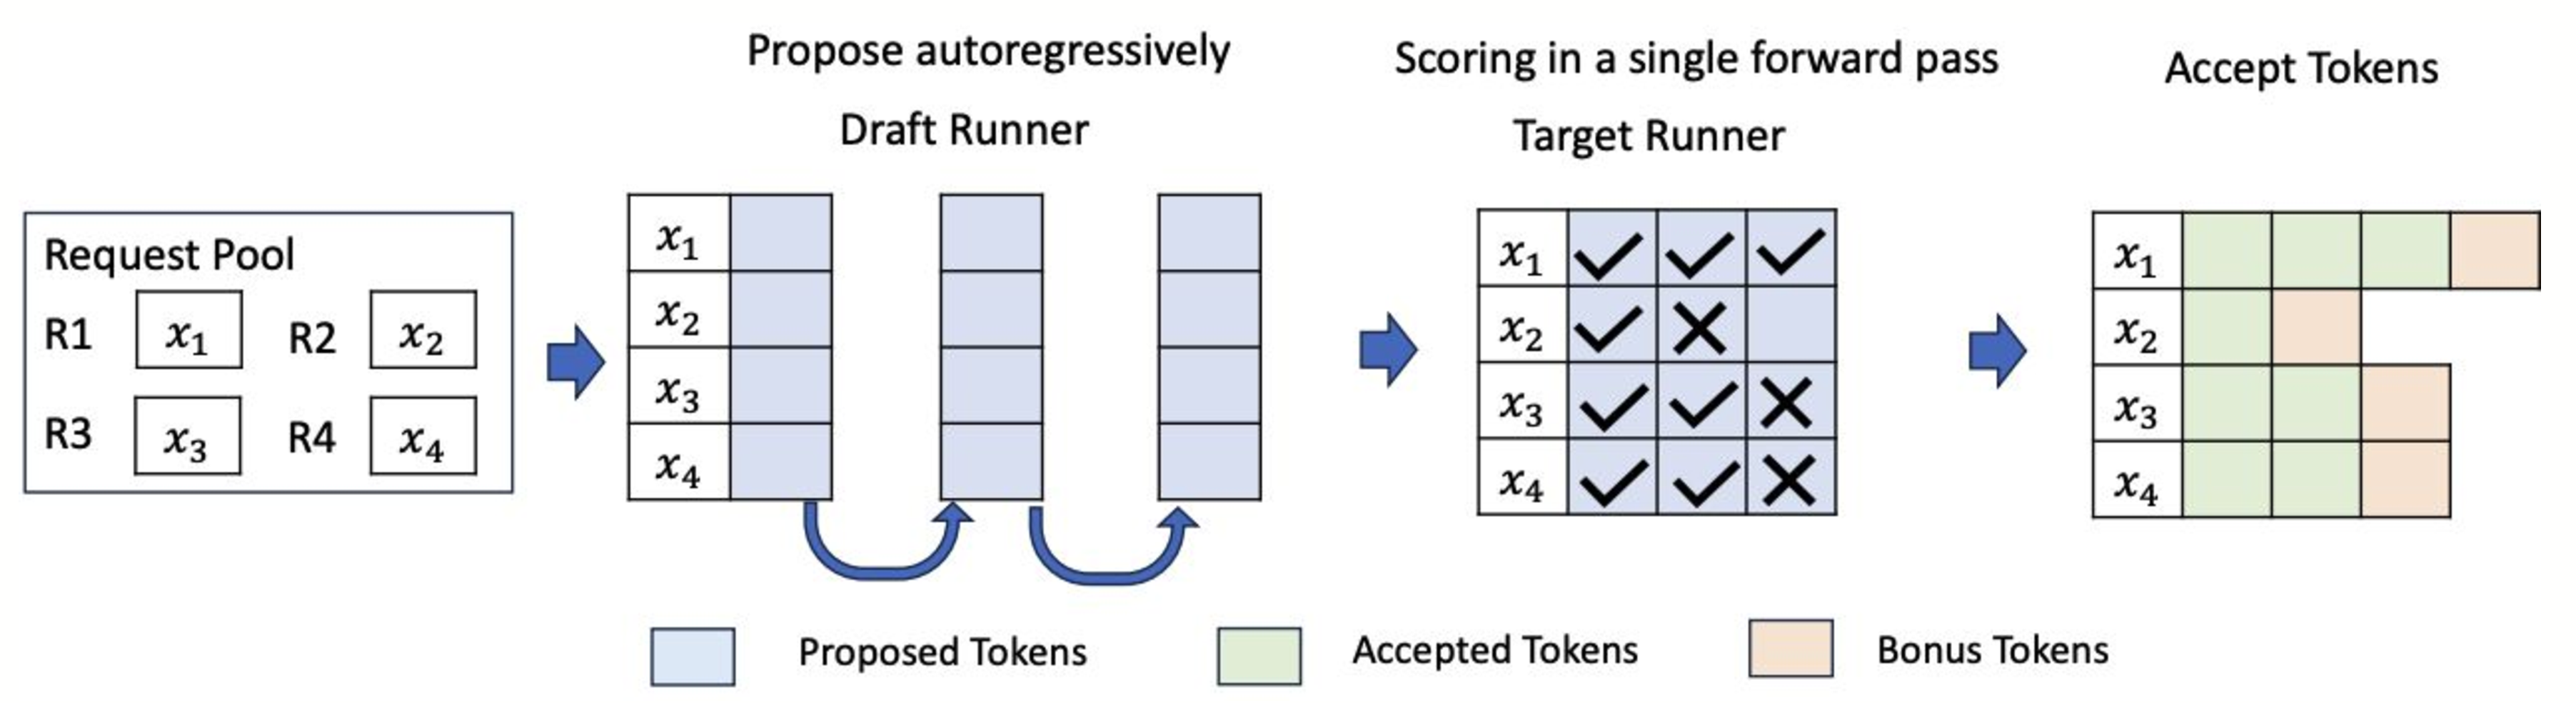
Speculative Decoding in vLLM | OpenLM.ai
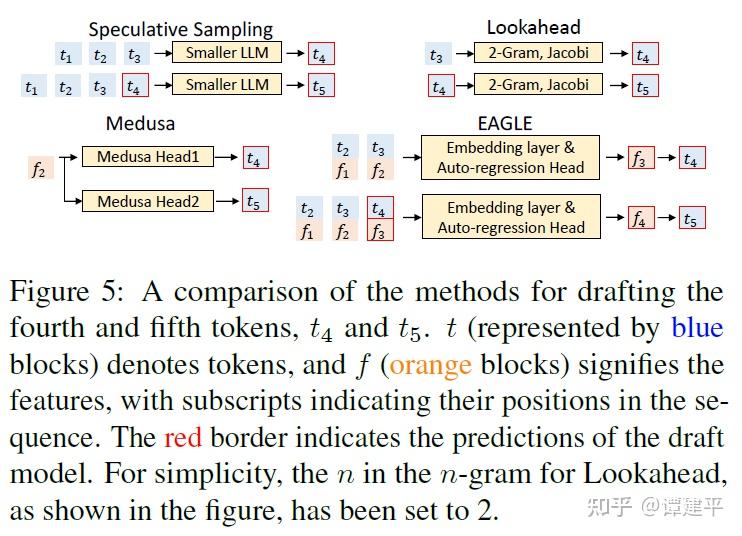
vllm Speculative decoding 论文整理总结 - 知乎
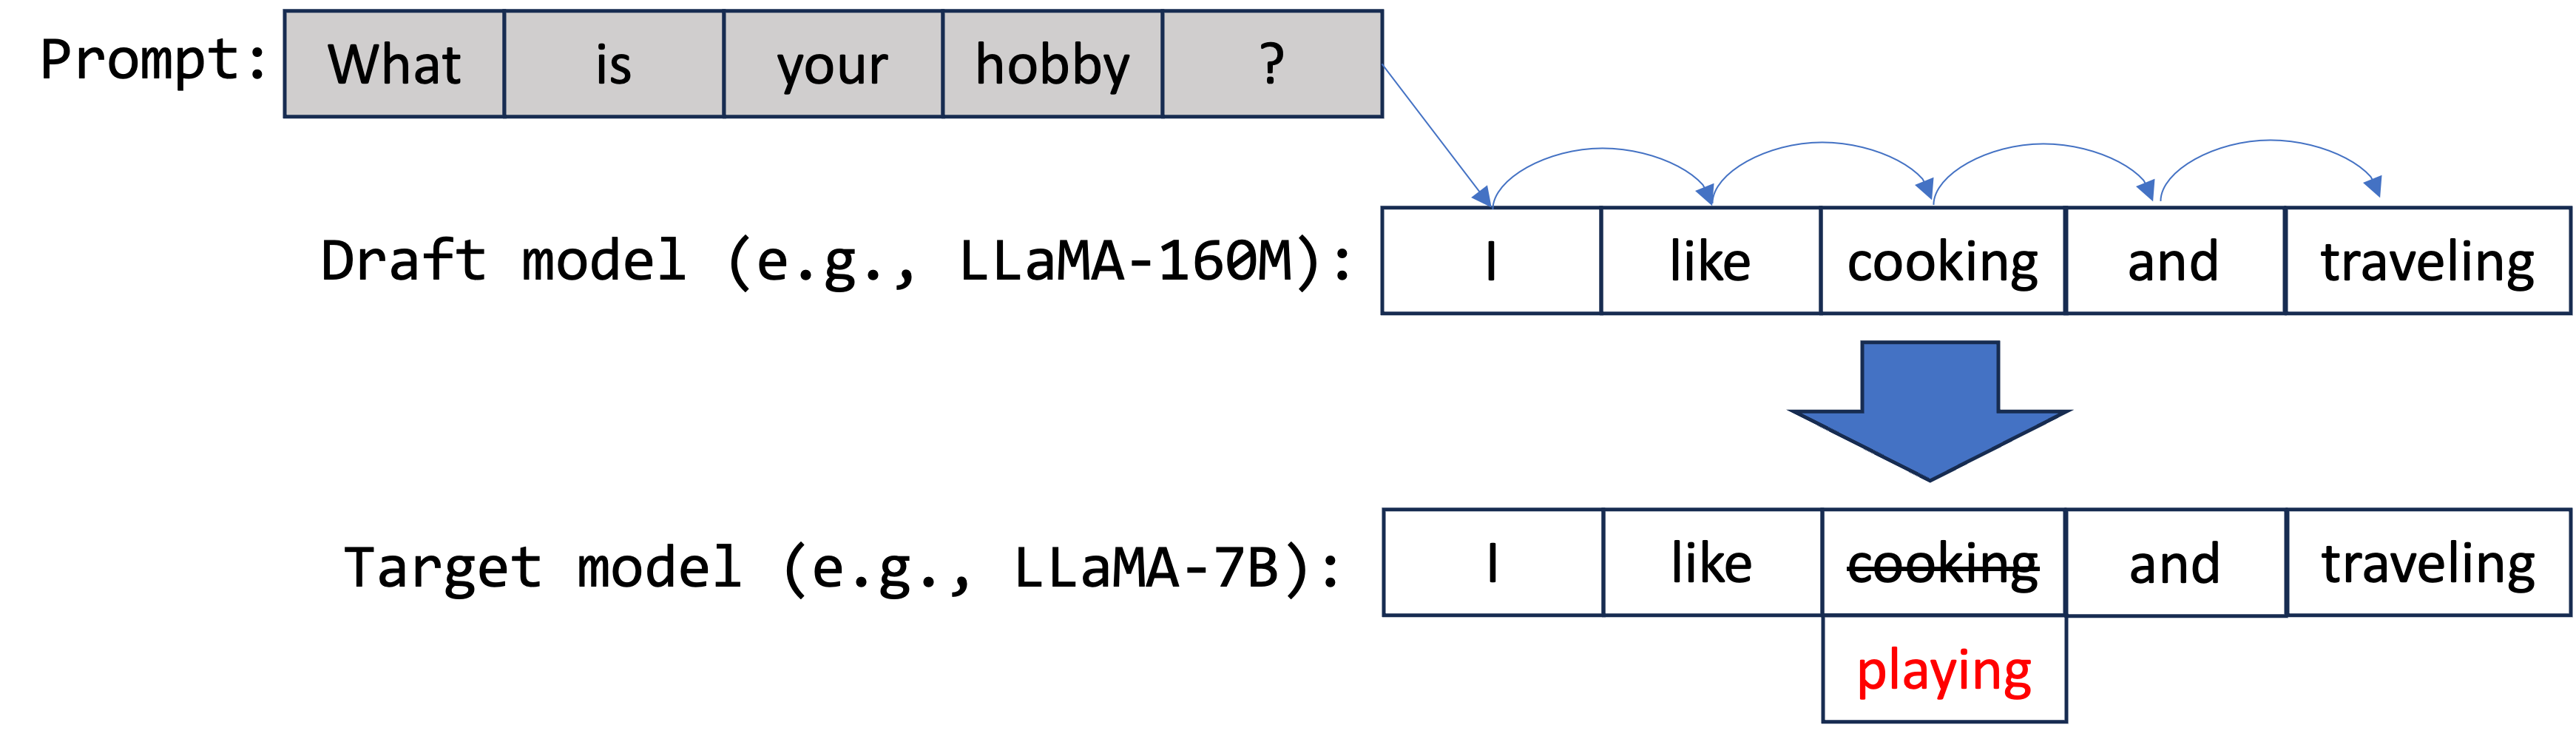
Speculative Decoding in vLLM | OpenLM.ai
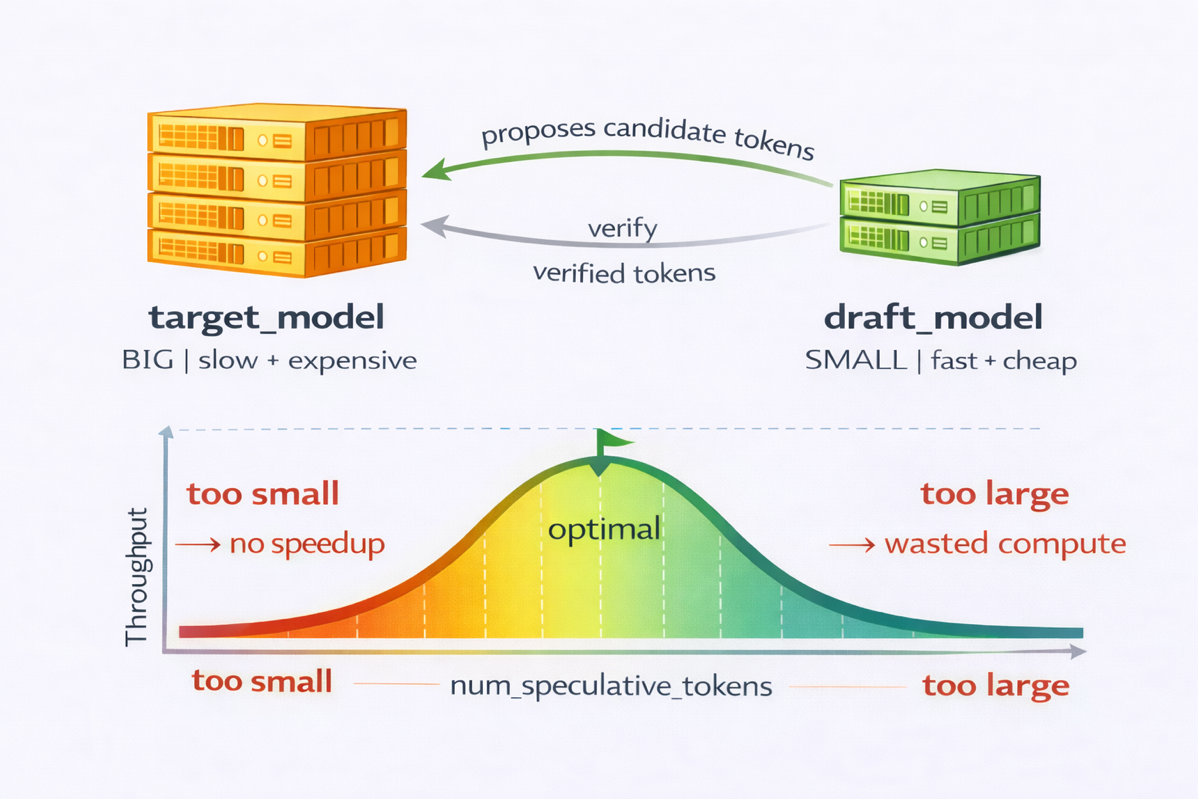
Accelerating decode-heavy LLM inference with speculative decoding on ...

P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...
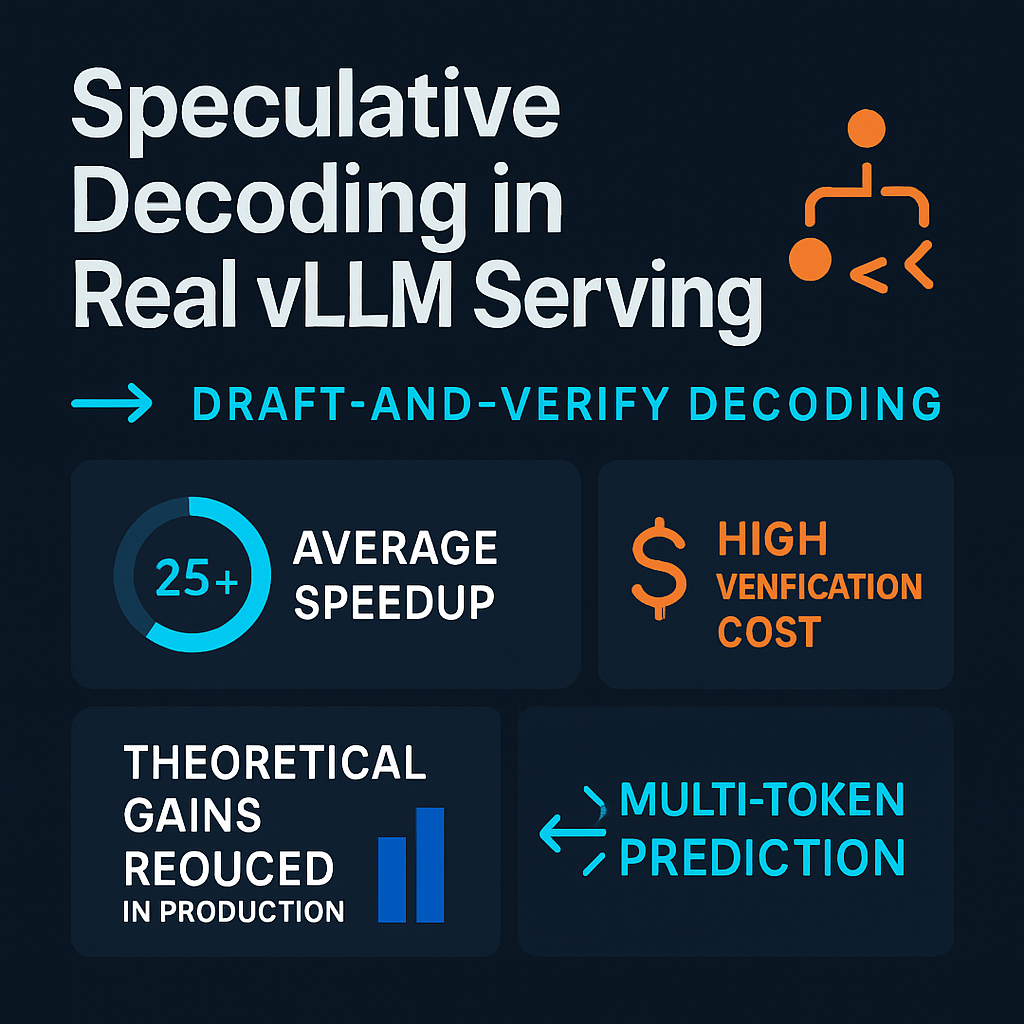
Speculative Decoding in Real vLLM Serving — AI Post Transformers
How Speculative Decoding Boosts vLLM Performance by up to 2.8x | vLLM Blog
Accelerating decode-heavy LLM inference with speculative decoding on ...
Advertisement Space (336x280)
Accelerating decode-heavy LLM inference with speculative decoding on ...
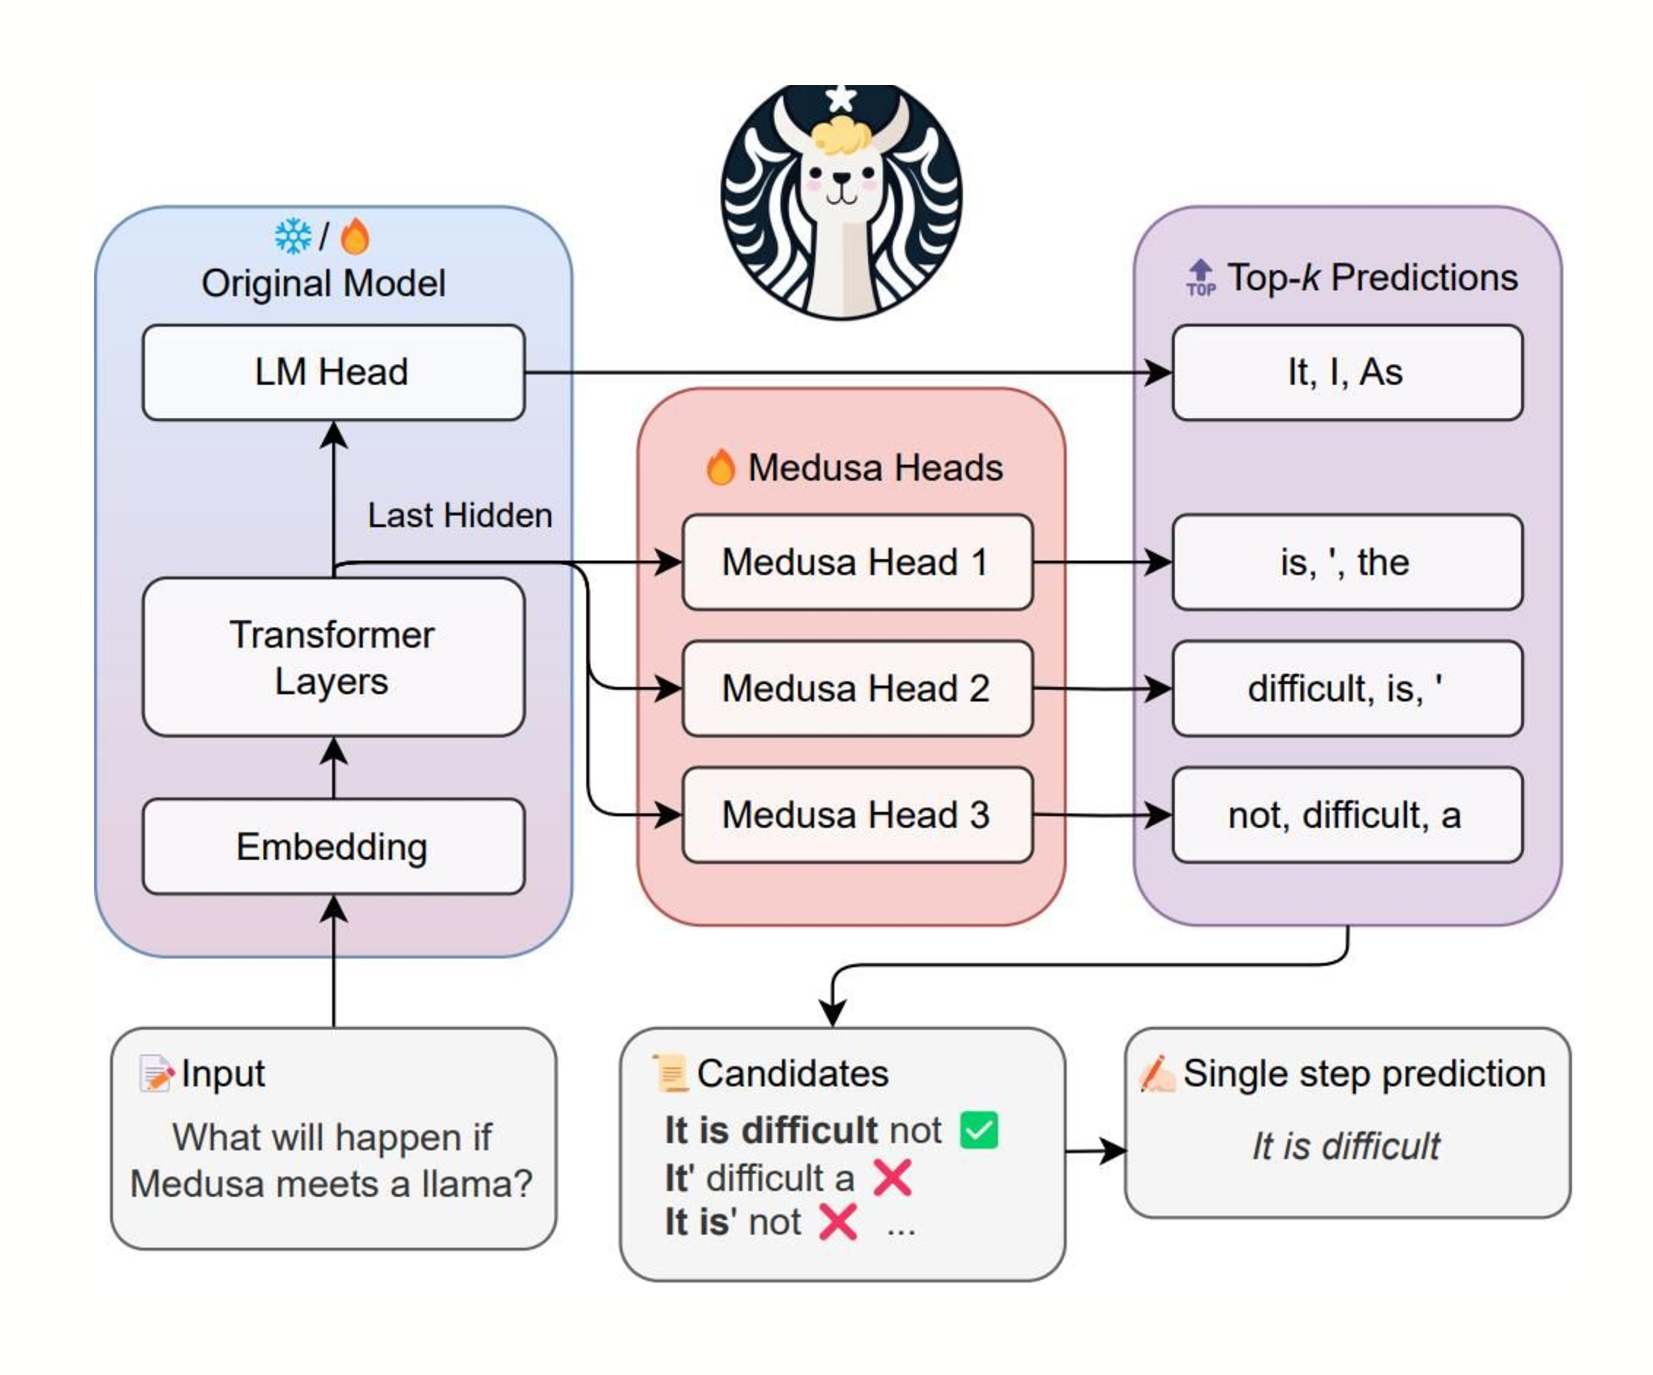
Speculative Decoding in vLLM | OpenLM.ai

With Speculators, you can train your own DFlash speculator for Gemma 4 ...
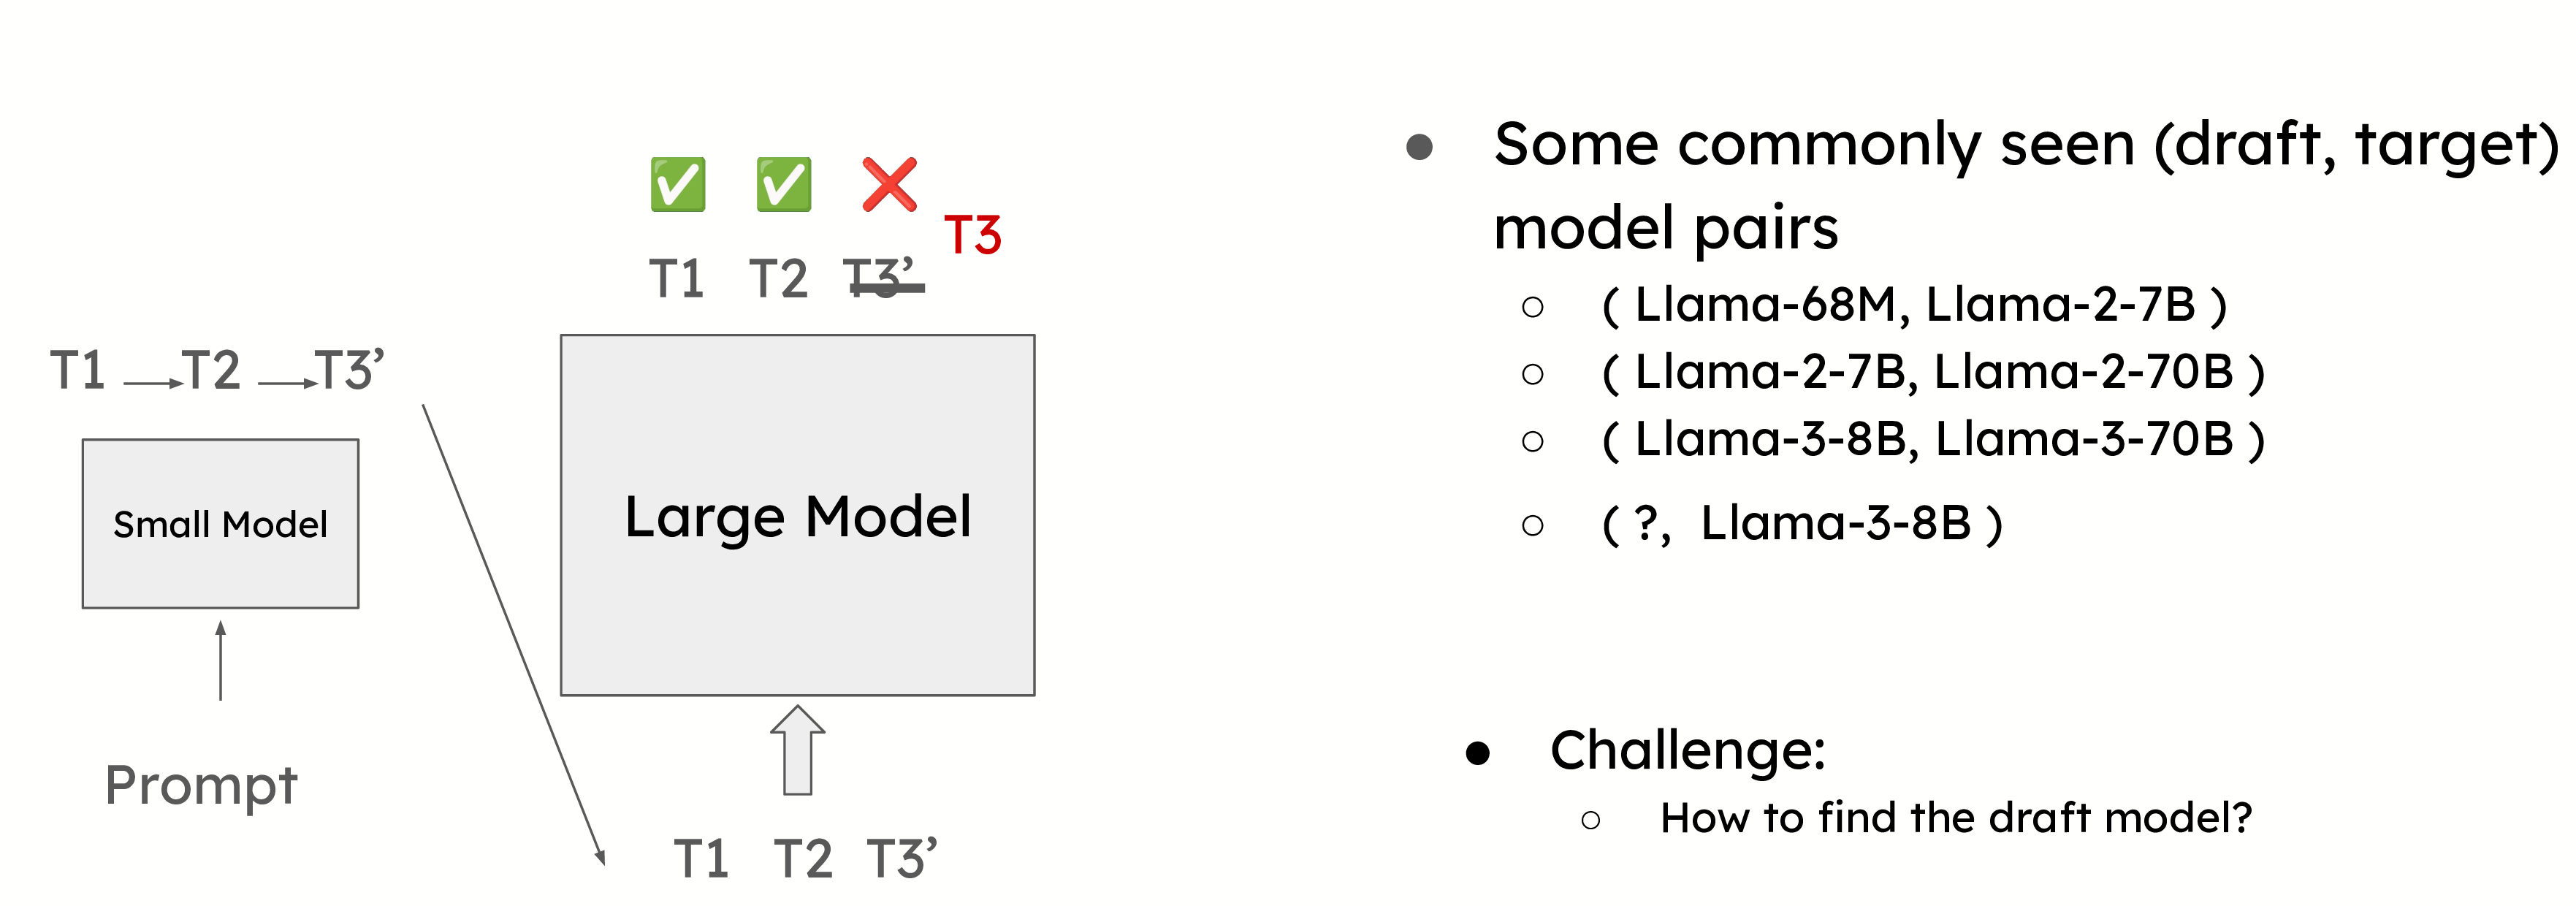
Speculative Decoding in vLLM | OpenLM.ai

Lecture 22: Hacker's Guide to Speculative Decoding in VLLM - YouTube
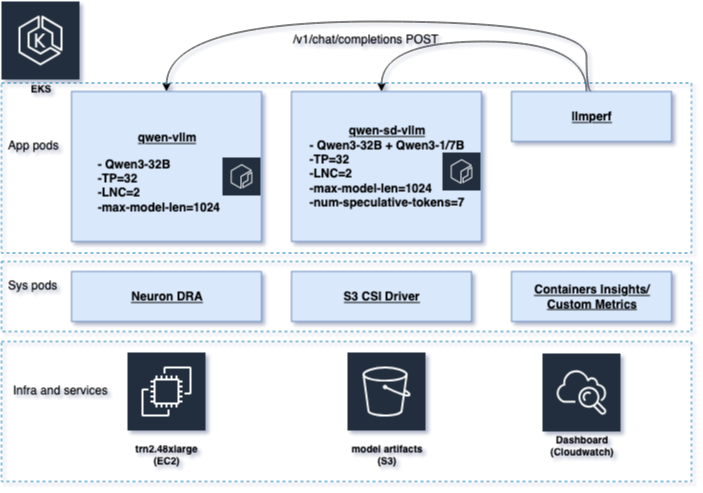
Accelerating decode-heavy LLM inference with speculative decoding on ...