
Training A Small Model To Write Better Ocaml With Rlvr And Grpo

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...

Training a small model to write better OCaml with RLVR and GRPO ...
Free Video: Training Small Language Models to Reason with Reinforcement ...
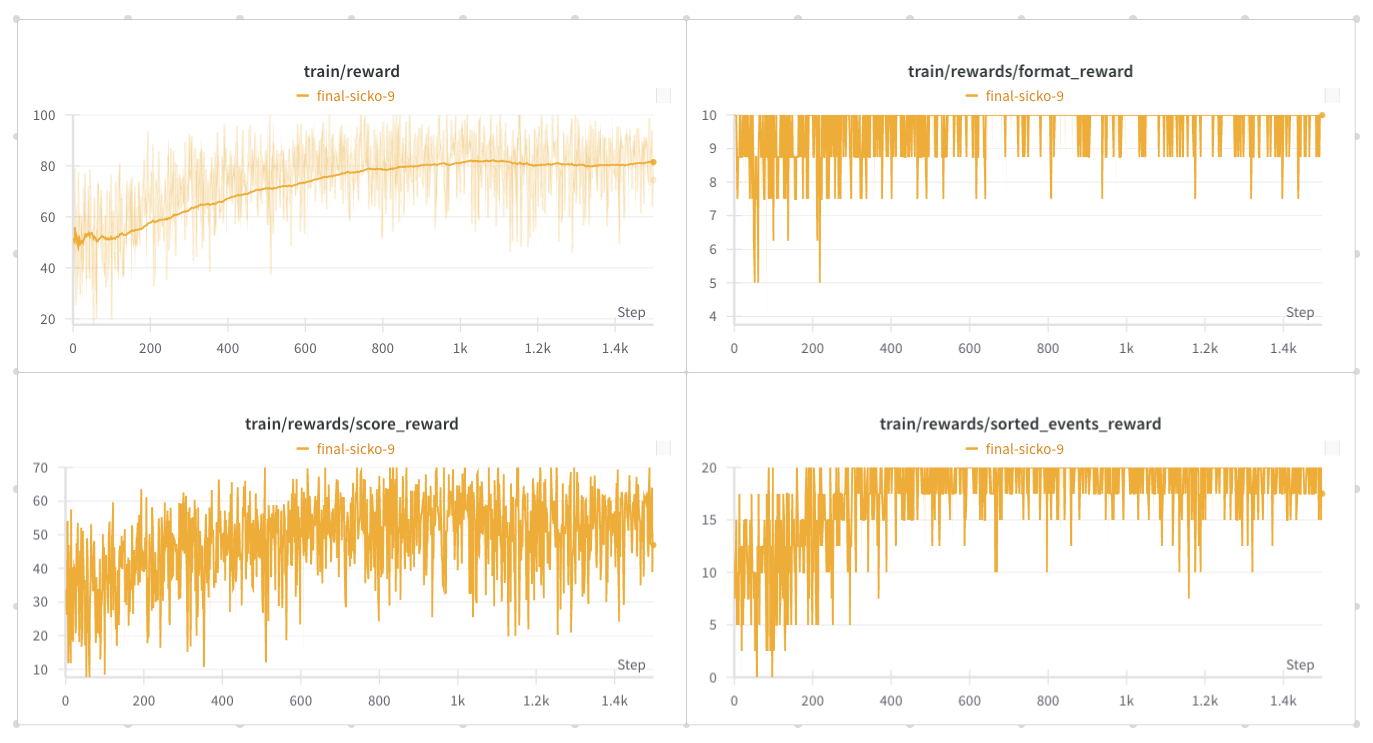
I trained a Language Model to schedule events with GRPO!

When training a language model with reinforcement learning, you ...
Advertisement Space (300x250)

Deep Dive into GRPO & RLVR: How to Train a Coding Agent

Recent reasoning research: GRPO tweaks, base model RL, and data curation

Post training an LLM for reasoning with GRPO in TRL - Hugging Face Open ...

Training Large Language Models: From TRPO to GRPO | Towards Data Science

Training Large Language Models: From TRPO to GRPO | Towards Data Science
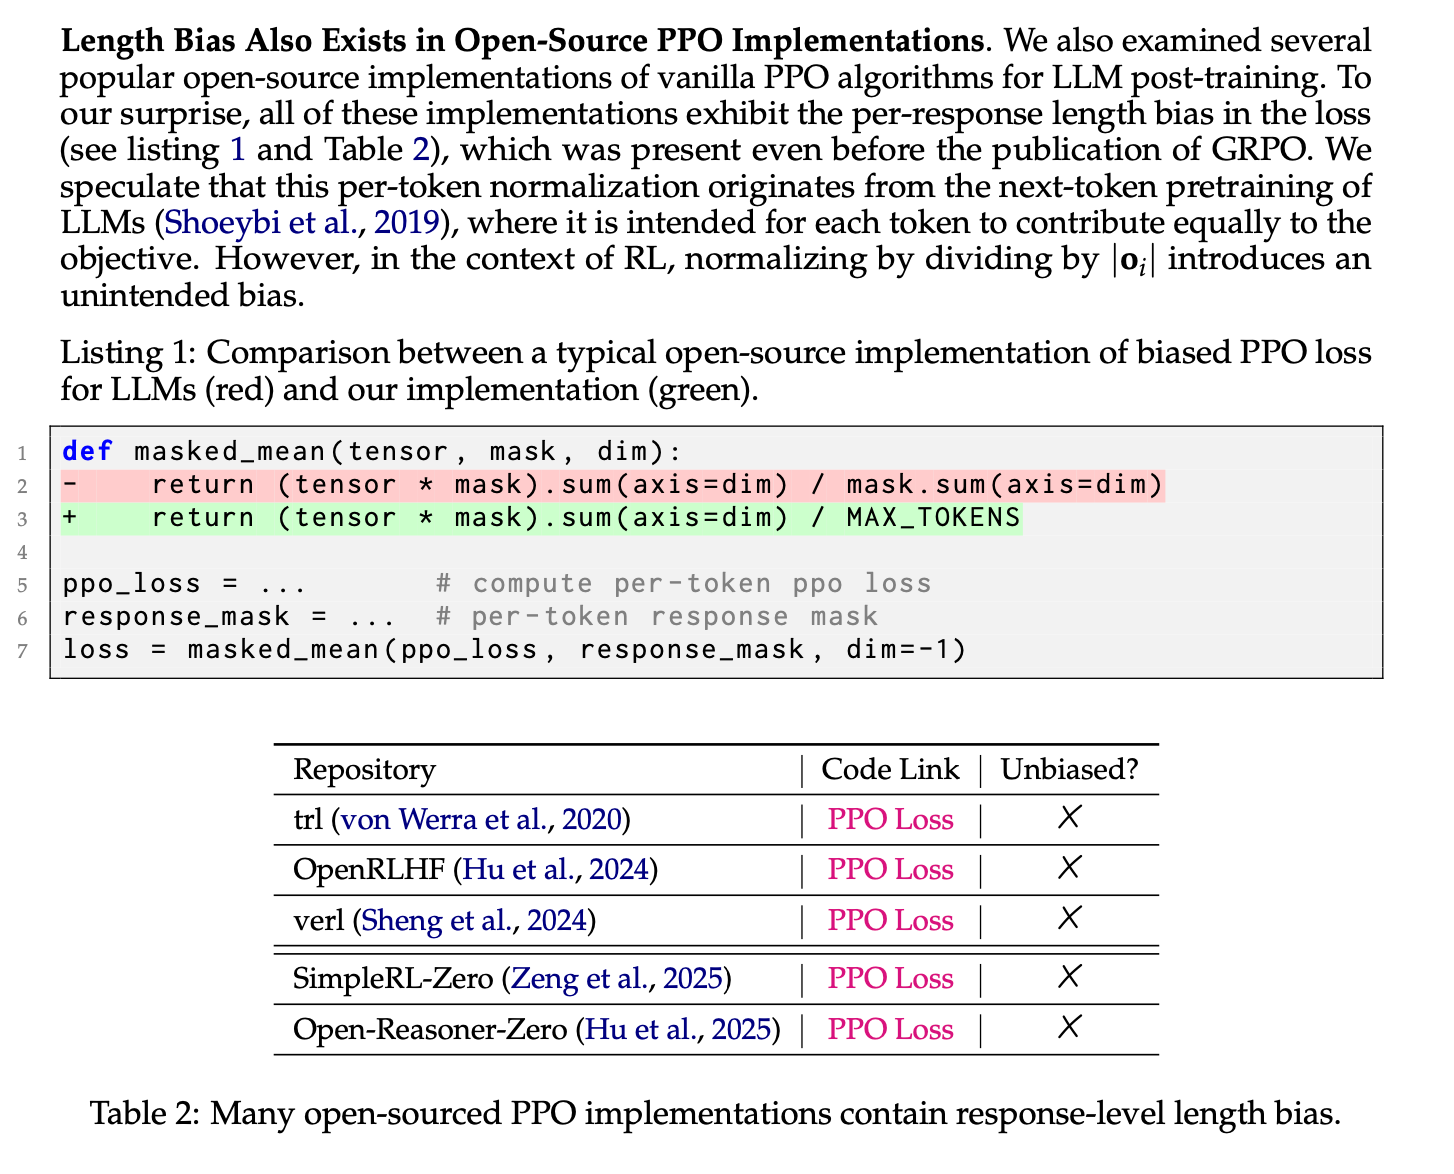
Recent reasoning research: GRPO tweaks, base model RL, and data curation
Welcome to a World of OCaml
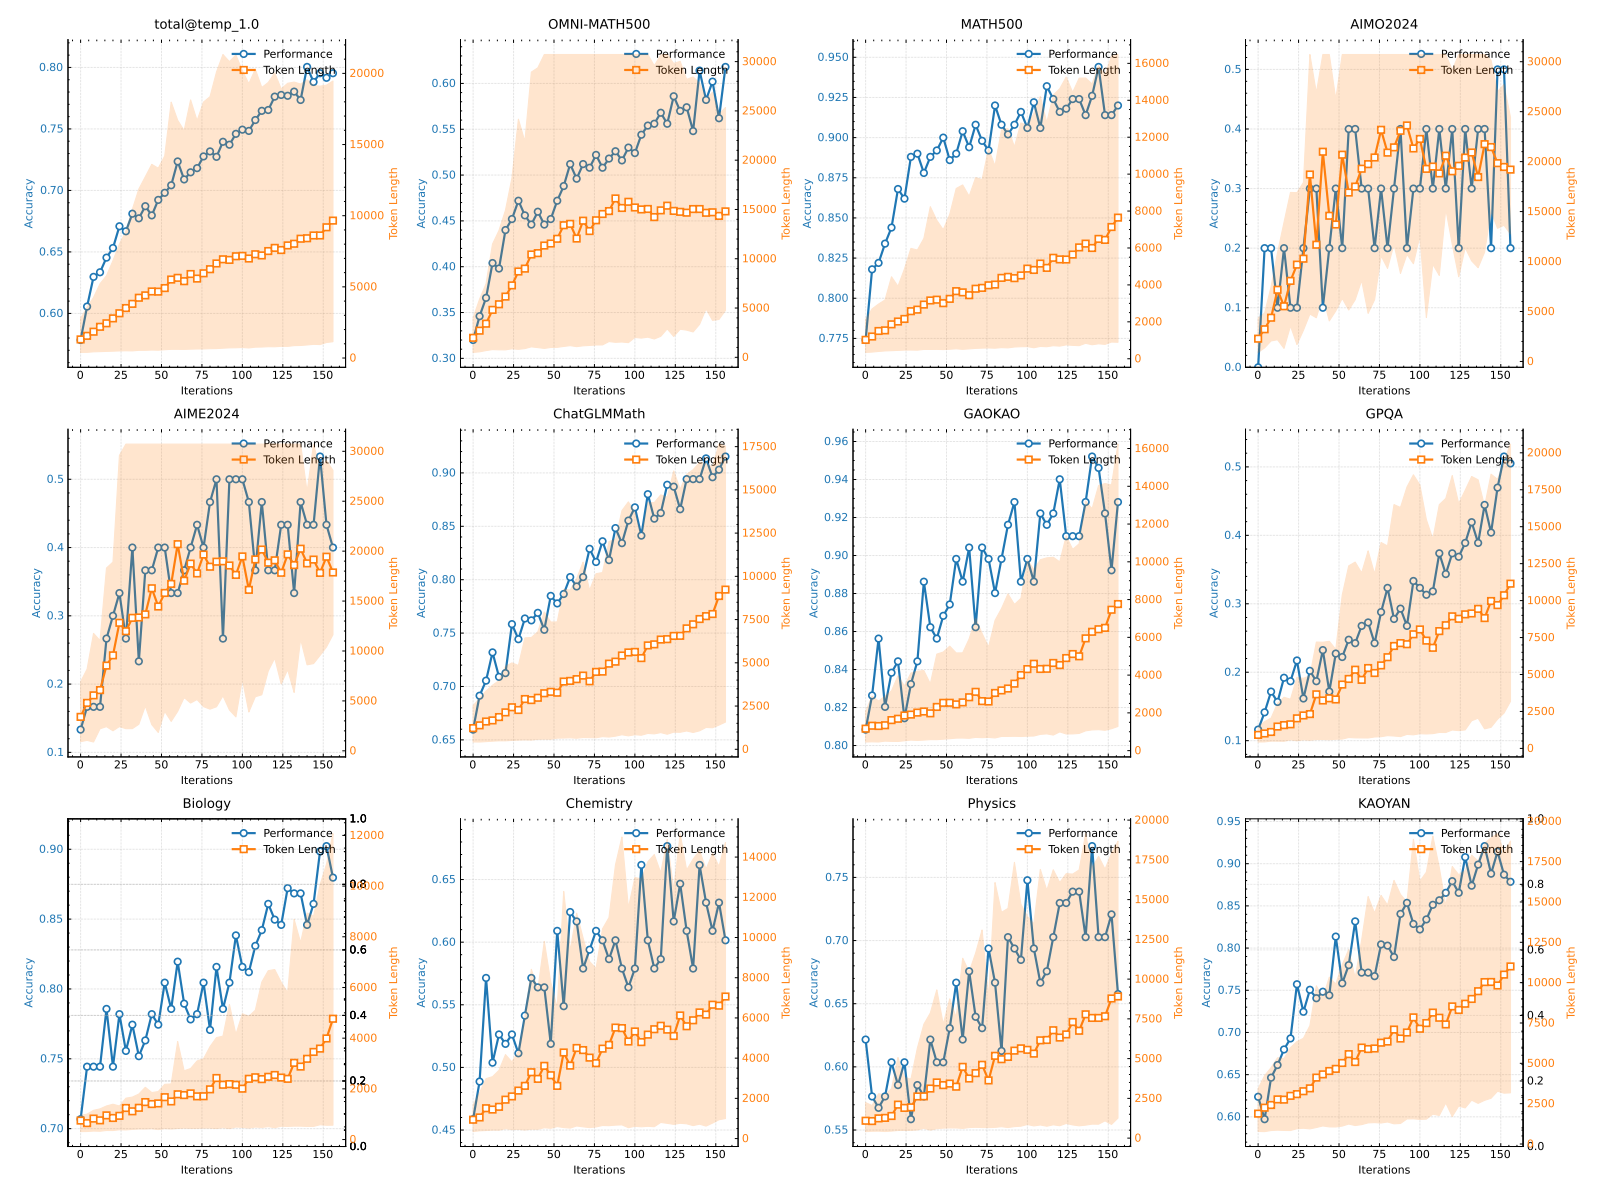
Recent reasoning research: GRPO tweaks, base model RL, and data curation
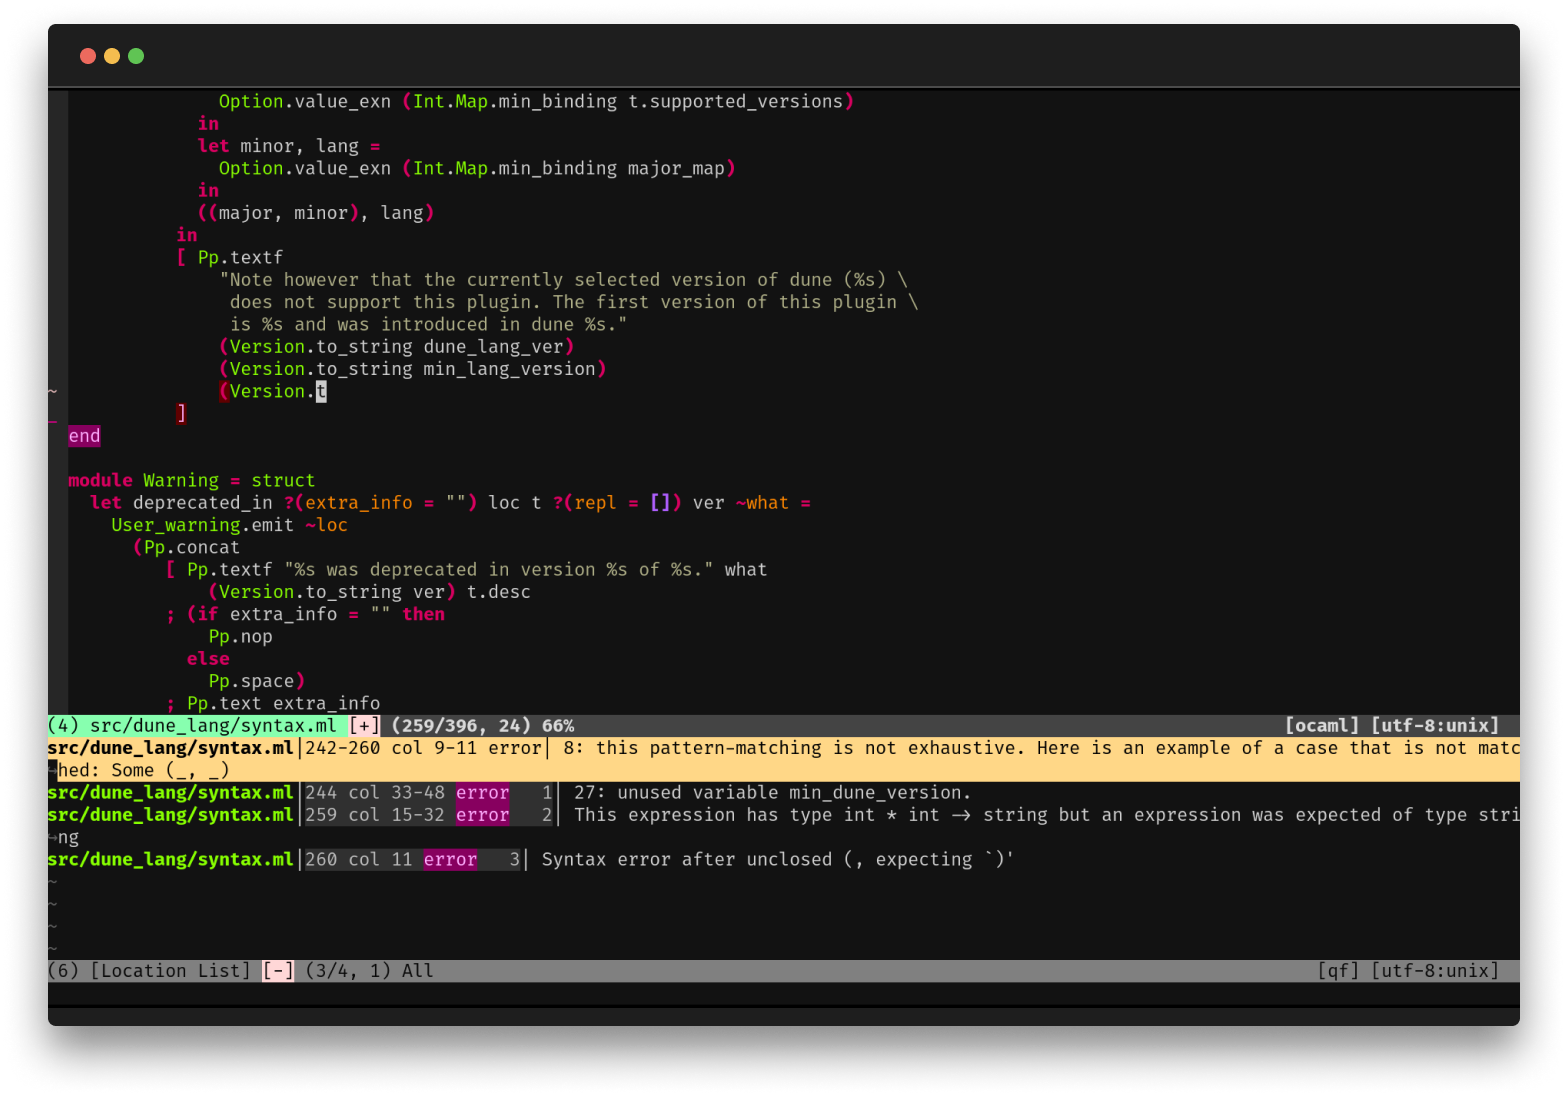
Welcome to a World of OCaml

RLVR-World: Training World Models with Reinforcement Learning
Advertisement Space (336x280)

From Random Forests to RLVR: A Short History of ML/AI Hello Worlds ...
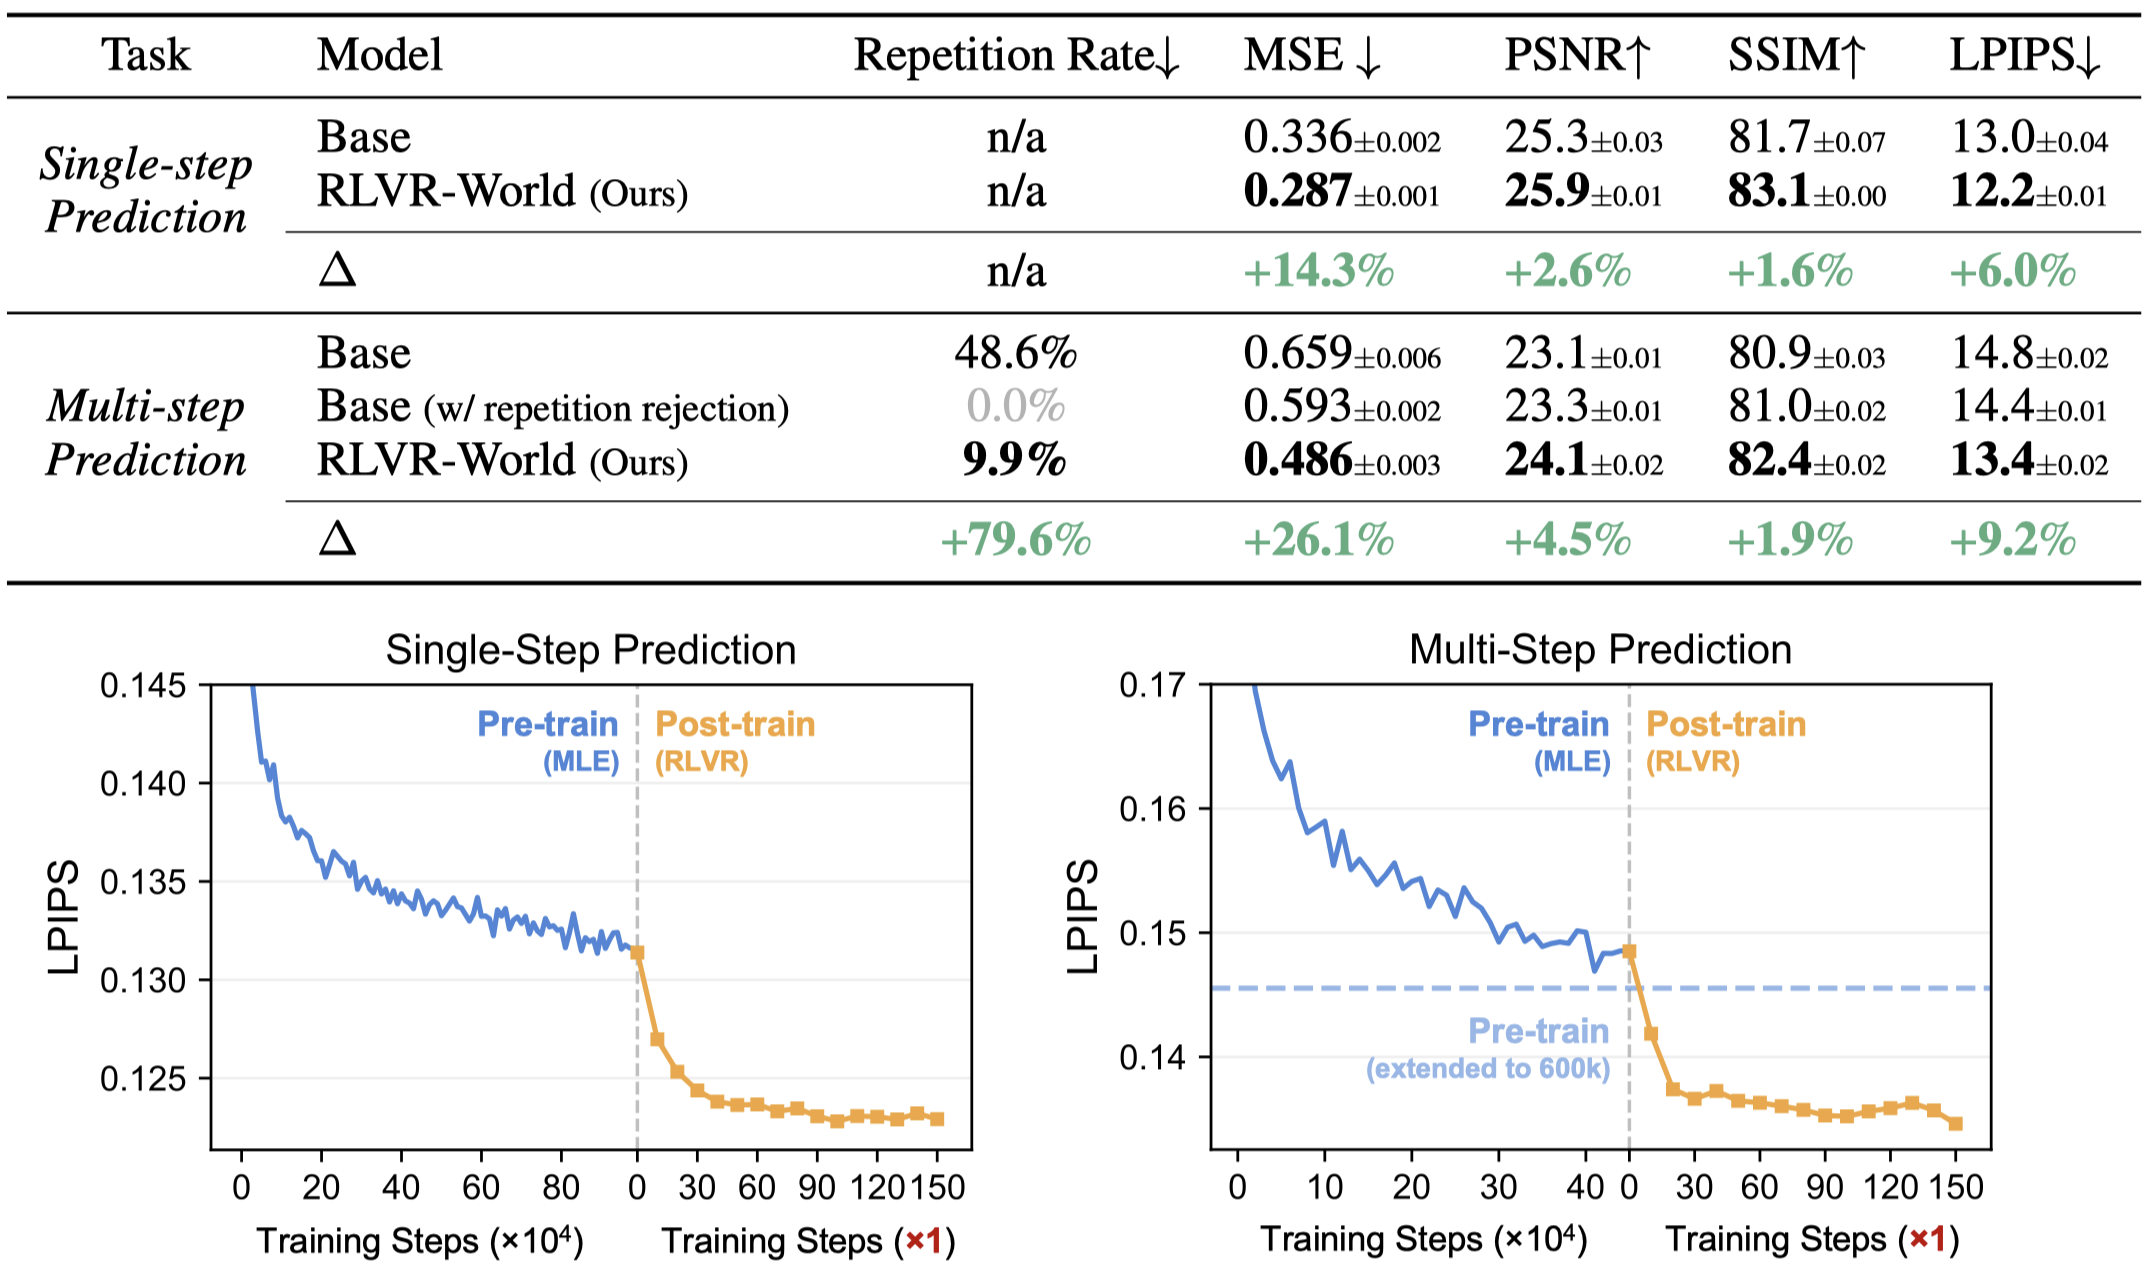
RLVR-World: Training World Models with Reinforcement Learning

RLVR-World: Training World Models with Reinforcement Learning

RLVR-World: Training World Models with Reinforcement Learning

[논문 리뷰] Med-RLVR: Emerging Medical Reasoning from a 3B base model via ...

RLVR-World: Training World Models with Reinforcement Learning | AI ...

Taming the Long-Tail: Efficient Reasoning RL Training with Adaptive Drafter

Rewards as Labels: Revisiting RLVR from a Classification Perspective
Three Steps for OCaml to Crest the AI Humps - Sadiq Jaffer

Vanilla GRPO has shortcomings that hinder RL training at scale. Here is ...
Advertisement Space (336x280)
Understanding Values and Functions in OCaml
RLVR-World: Training World Models with Reinforcement Learning - Paper ...

R1-VL: Learning to Reason with Multimodal Large Language Models via ...
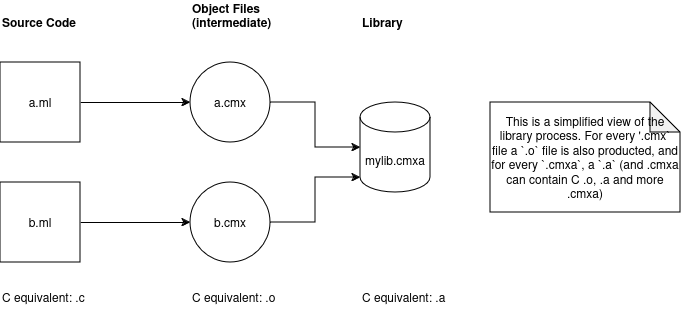
Keeping it small: helping the compiler to remove unused code in OCaml
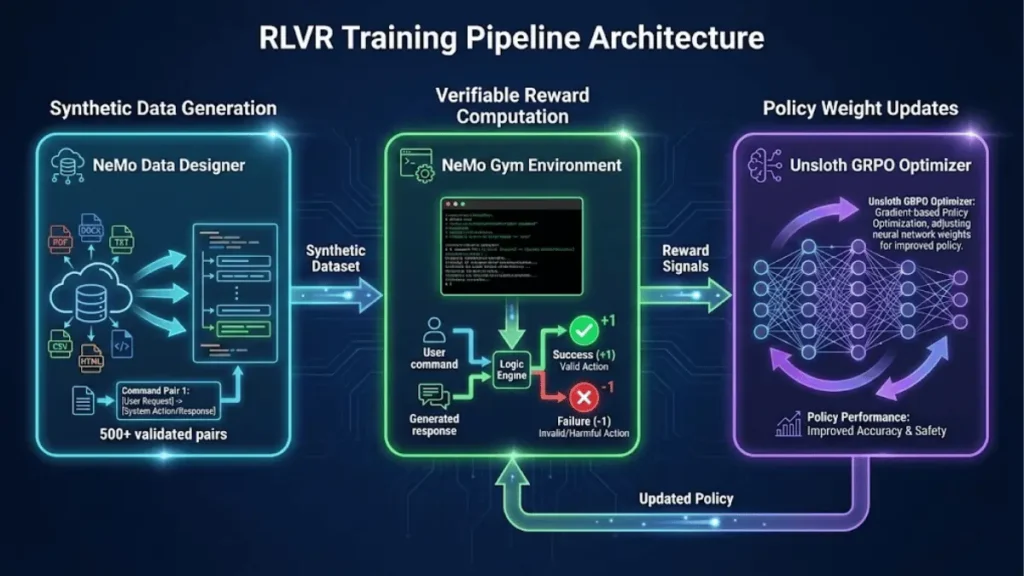
Train AI Agents with RLVR: NVIDIA's Synthetic Data Method
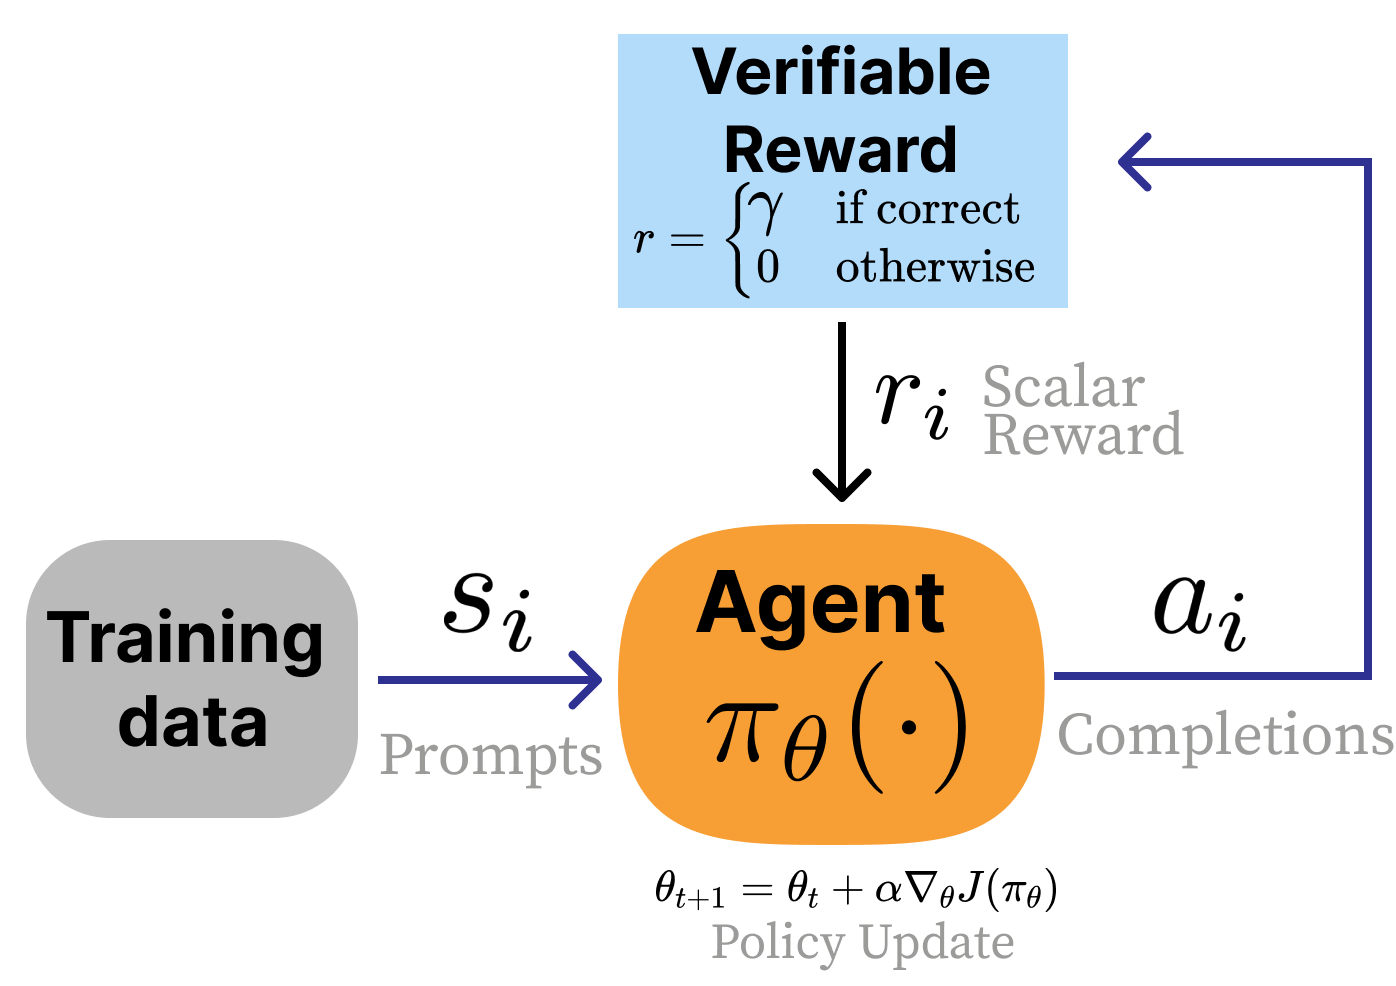
Reasoning and Inference-Time Scaling | RLHF and Post-Training Book by ...