
Transformer Encoder Block With Multi Head Attention And Scaled Dot

Transformer encoder block with multi-head attention and scaled dot ...

Transformer encoder block with multi-head attention and scaled dot ...

Multi head attention mechanism. In the encoder and decoder, multiple ...

| Transformers use scaled dot product attention (A) and multi-head ...

| Transformers use scaled dot product attention (A) and multi-head ...

Scaled dot-product attention and multi-head attention in Transformer ...

Transformer encoder network structure (left) and multi-head attention ...

Transformer encoder network structure (left) and multi-head attention ...

Graphical representations of scaled dot product attention (left) and ...

(i) Scaled dot product attention and (ii) Multi-head attention [25 ...
Advertisement Space (300x250)
2: Transformer's Scaled Dot-Product Attention and Multi-Head Attention ...

The encoder structure of the original Transformer and the process of ...

2: Transformer's Scaled Dot-Product Attention and Multi-Head Attention ...
5: Scaled Dot-Product Attention and Multi-Head Attention utilized in ...
Transformer architecture, multi-head attention layer architecture, and ...

Transformer architecture, multi-head attention layer architecture, and ...
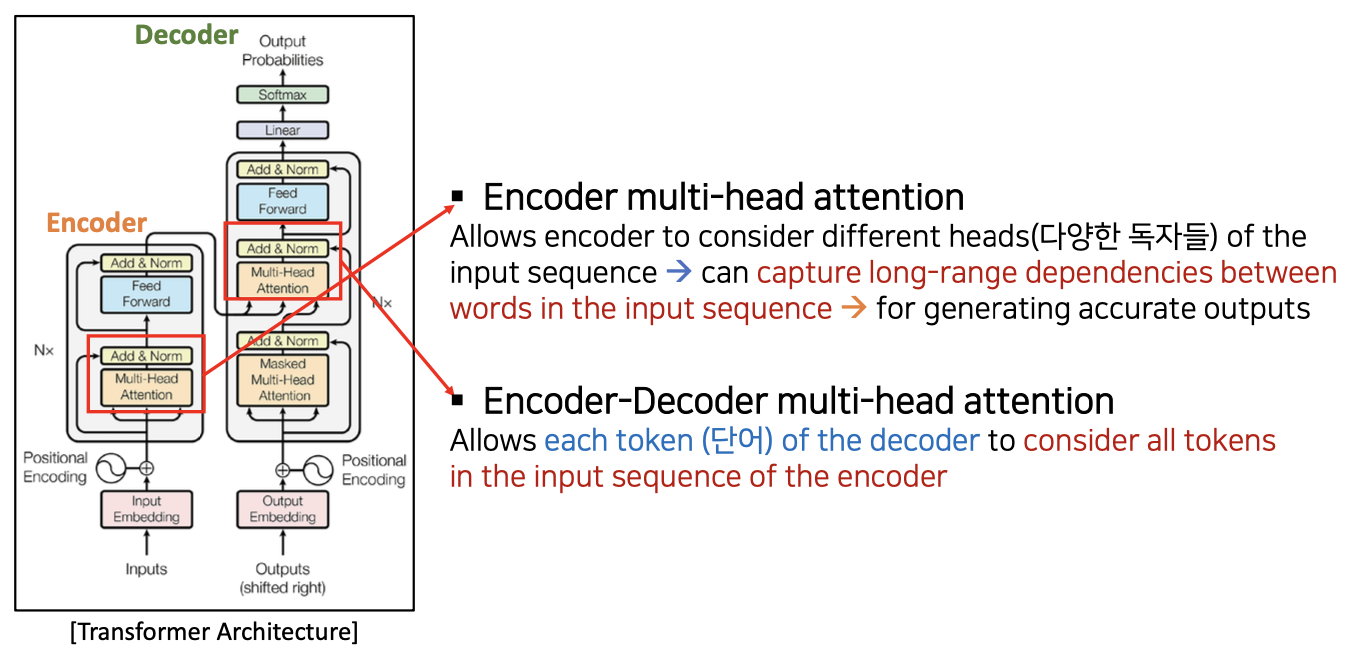
Chapter 3. Transformer and Attention

Transformer encoder block illustration. The block consists of a ...
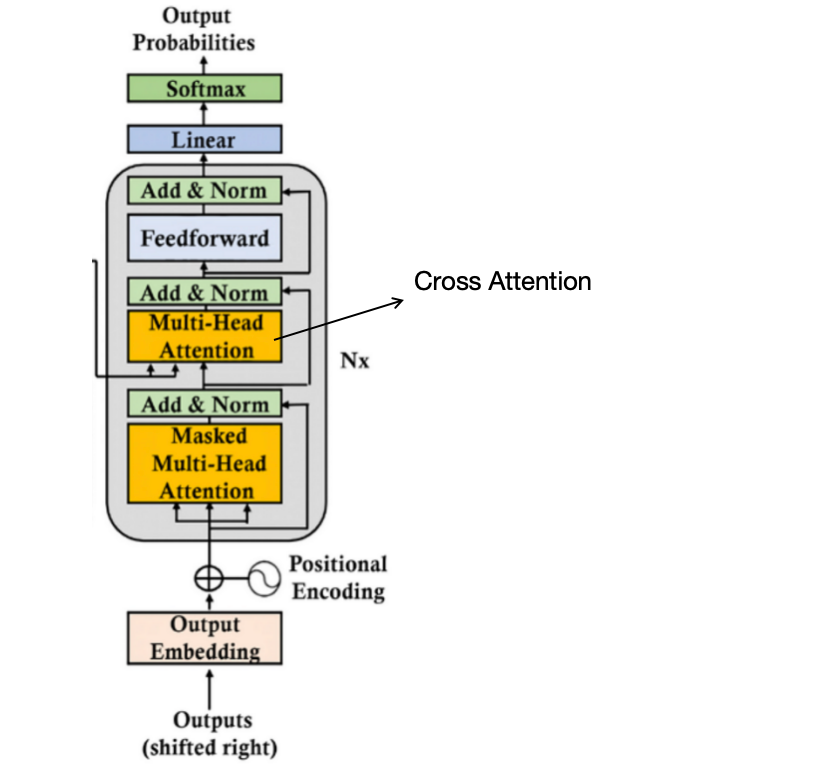
In Depth Understanding of Attention Mechanism (Part II) - Scaled Dot ...
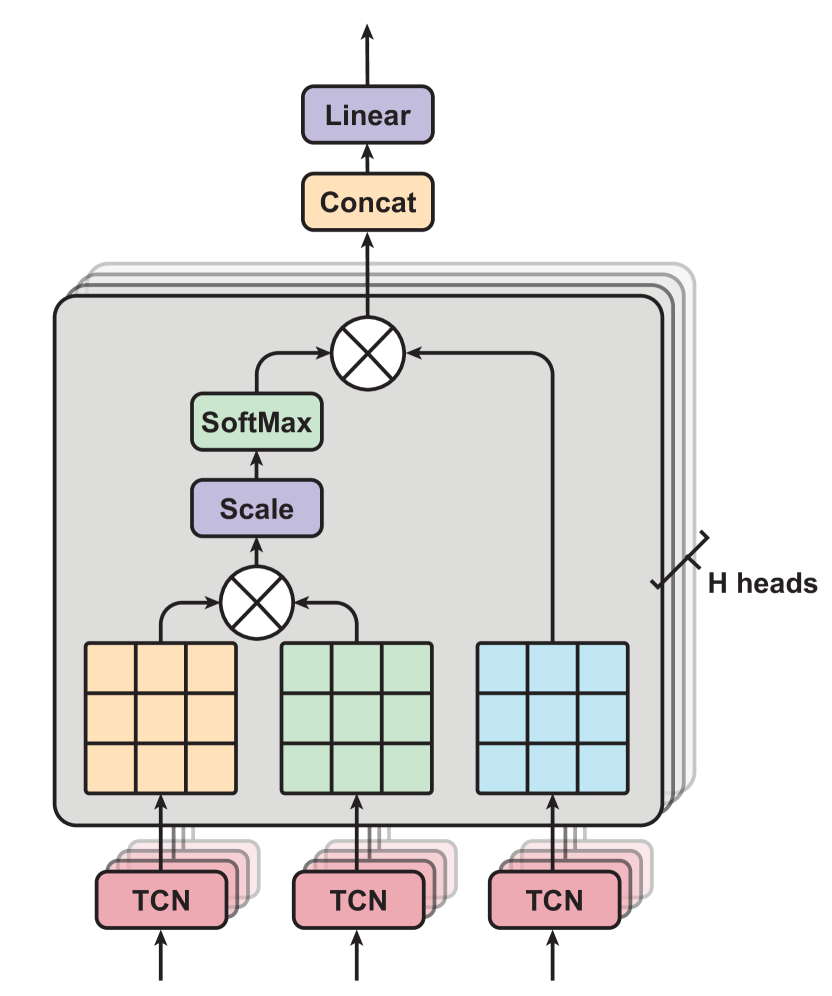
[2303.06845] Transformer Encoder with Multiscale Deep Learning for Pain ...
Advertisement Space (336x280)

Multi-head attention & scaled dot product attention (Vaswani et al ...
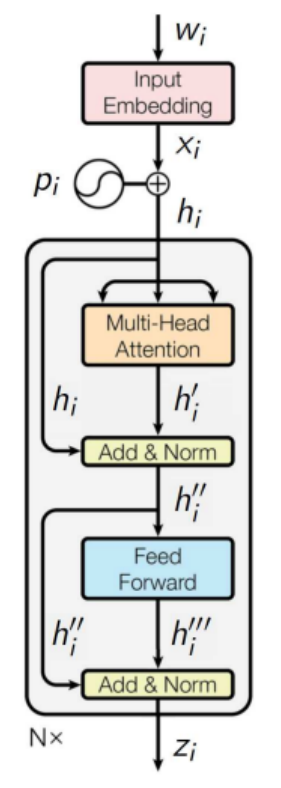
Attention mechanism and Transformer architecture

(Left) Scaled dot product attention; (right) multi-head attention [39 ...

Transformer Modules (Left to Right): Scaled dot-product attention ...
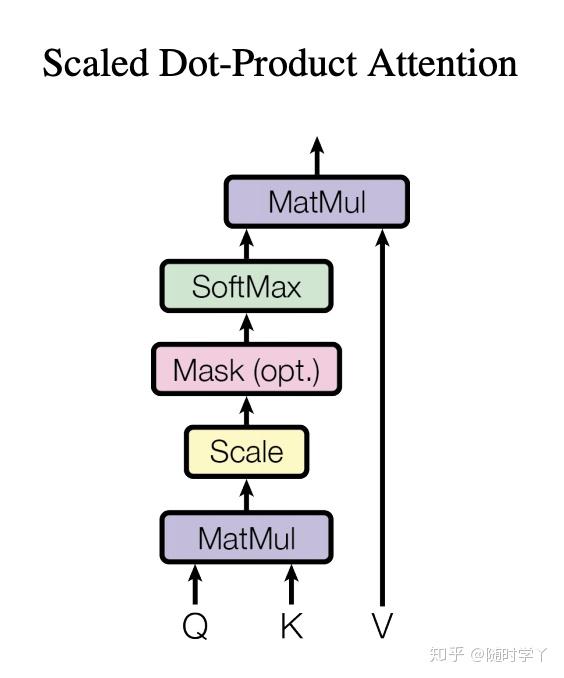
拆 Transformer 系列二:Multi- Head Attention 机制详解 - 知乎
Transformer encoder layer architecture (left) and schematic overview of ...
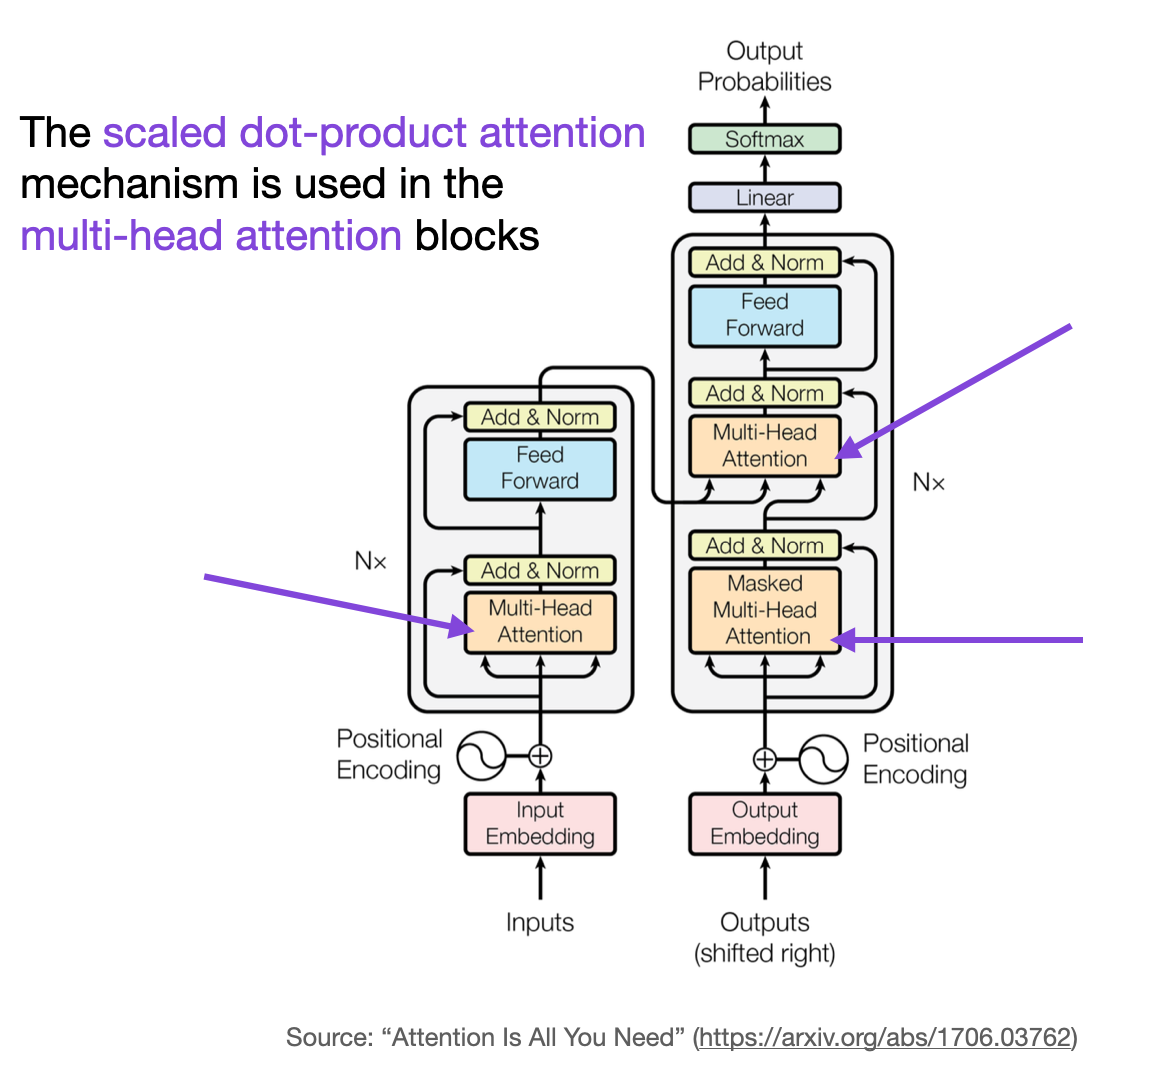
torch attention | torch nnn scaled dot – FYKH
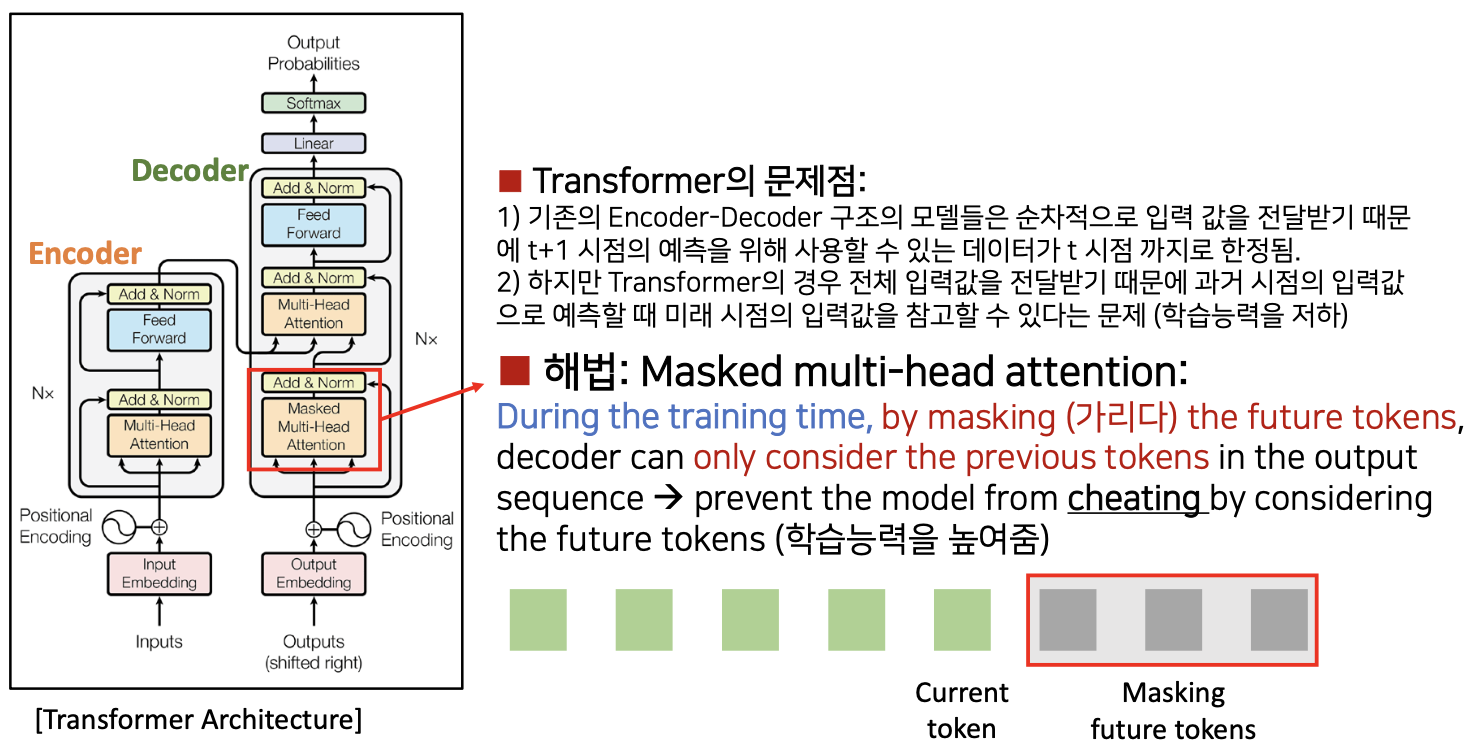
Chapter 3. Transformer and Attention

The structure of the multi-head attention and the structure of scaled ...
Illustration of the scaled dot-product attention (left) and multi-head ...
Advertisement Space (336x280)

2. Illustration of scaled dot-product Left attention and multi-head ...

Scaled Dot-Product Attention and Multi-Head Attention | Download ...

Attention model in Transformer. (a) Scaled dot-product attention model ...

Multiscale Convolution and Attention based Denoising Autoencoder for ...
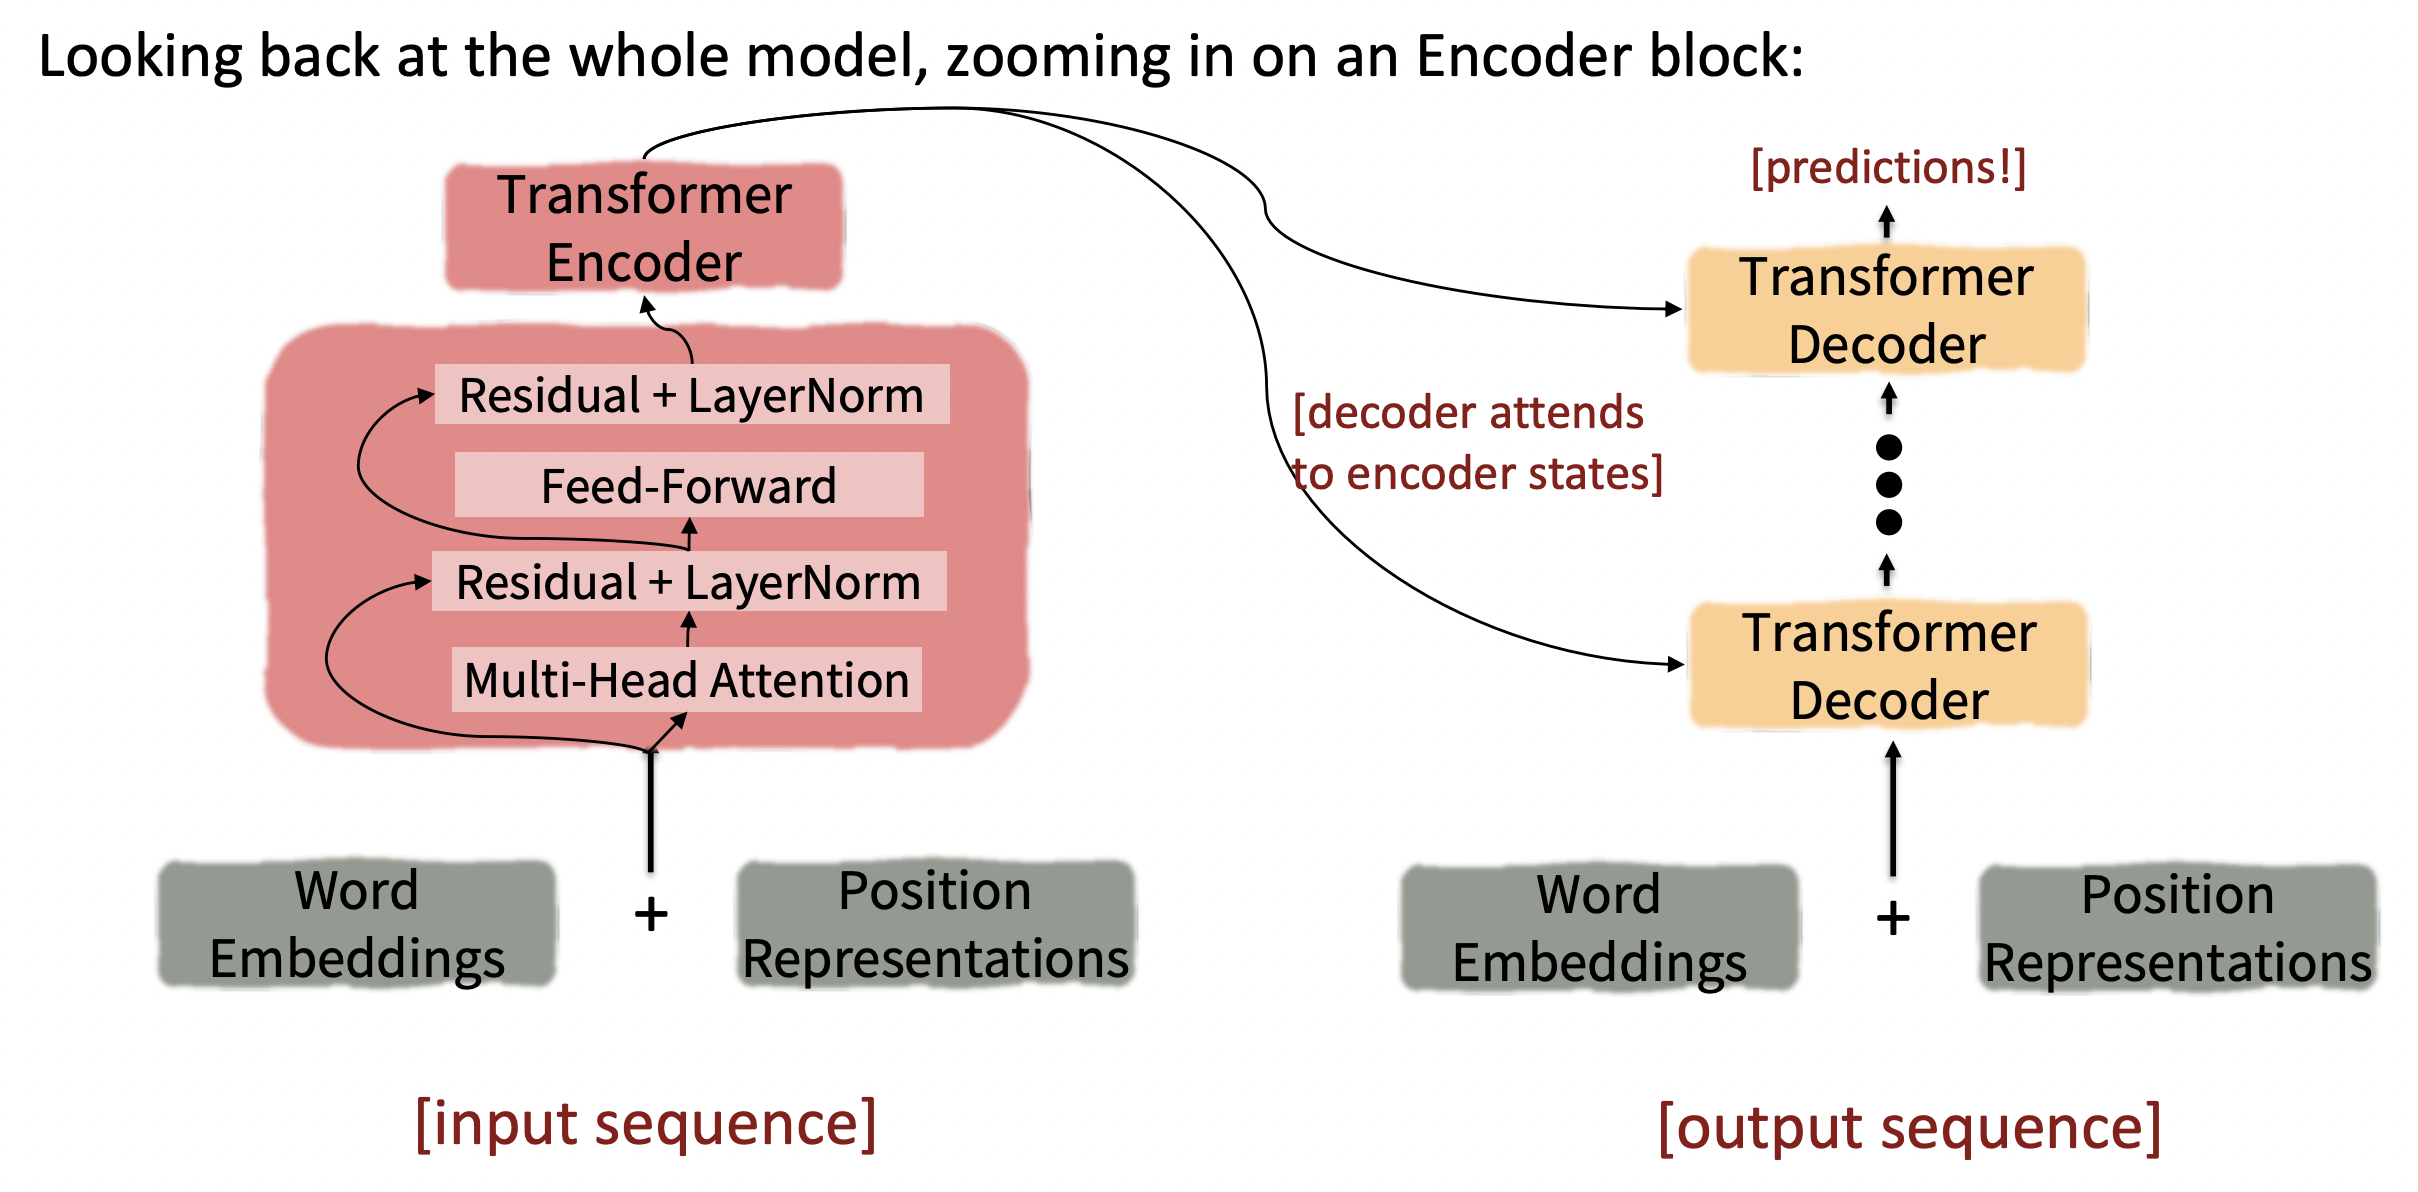
[CS224N] Lecture 9 - Self- Attention and Transformers

Emotion Classification Based on Transformer and CNN for EEG Spatial ...