
Transformer Encoder Layer H Represents The Multiple Heads Of Attention

Transformer encoder layer, h represents the multiple heads of attention ...

Transformer encoder layer, h represents the multiple heads of attention ...

Transformer encoder layer, h represents the multiple heads of attention ...

shows a flowchart of the encoder layer in the Transformer encoder. The ...
Transformer encoder layer architecture (left) and schematic overview of ...

9: The architecture of a transformer model. The encoder consists of í ...
(a) The architecture of an transformer encoder layer. (b) The ...

(a) The architecture of an transformer encoder layer. (b) The ...

(a) The architecture of an transformer encoder layer. (b) The ...

Transformer encoder block illustration. The block consists of a ...
Advertisement Space (300x250)

Multi head attention mechanism. In the encoder and decoder, multiple ...
Detailed structure of a Transformer Encoder layer. The output of frame ...

Architecture diagram of our multi‐head attention transformer based on ...

Attention Is All You Need: The Original Transformer Architecture
The structure of Hierarchical Multi-Head Attention encoder. | Download ...

(left) The architecture of a transformer encoder. (right) Multi-head ...

Transformer architecture, multi-head attention layer architecture, and ...

Architecture of the Transformer layer, which contain a multi-head ...

Transformer encoder network structure (left) and multi-head attention ...

Transformer encoder block with multi-head attention and scaled dot ...
Advertisement Space (336x280)
Illustration of parallel attention forcing, applied to a Transformer ...
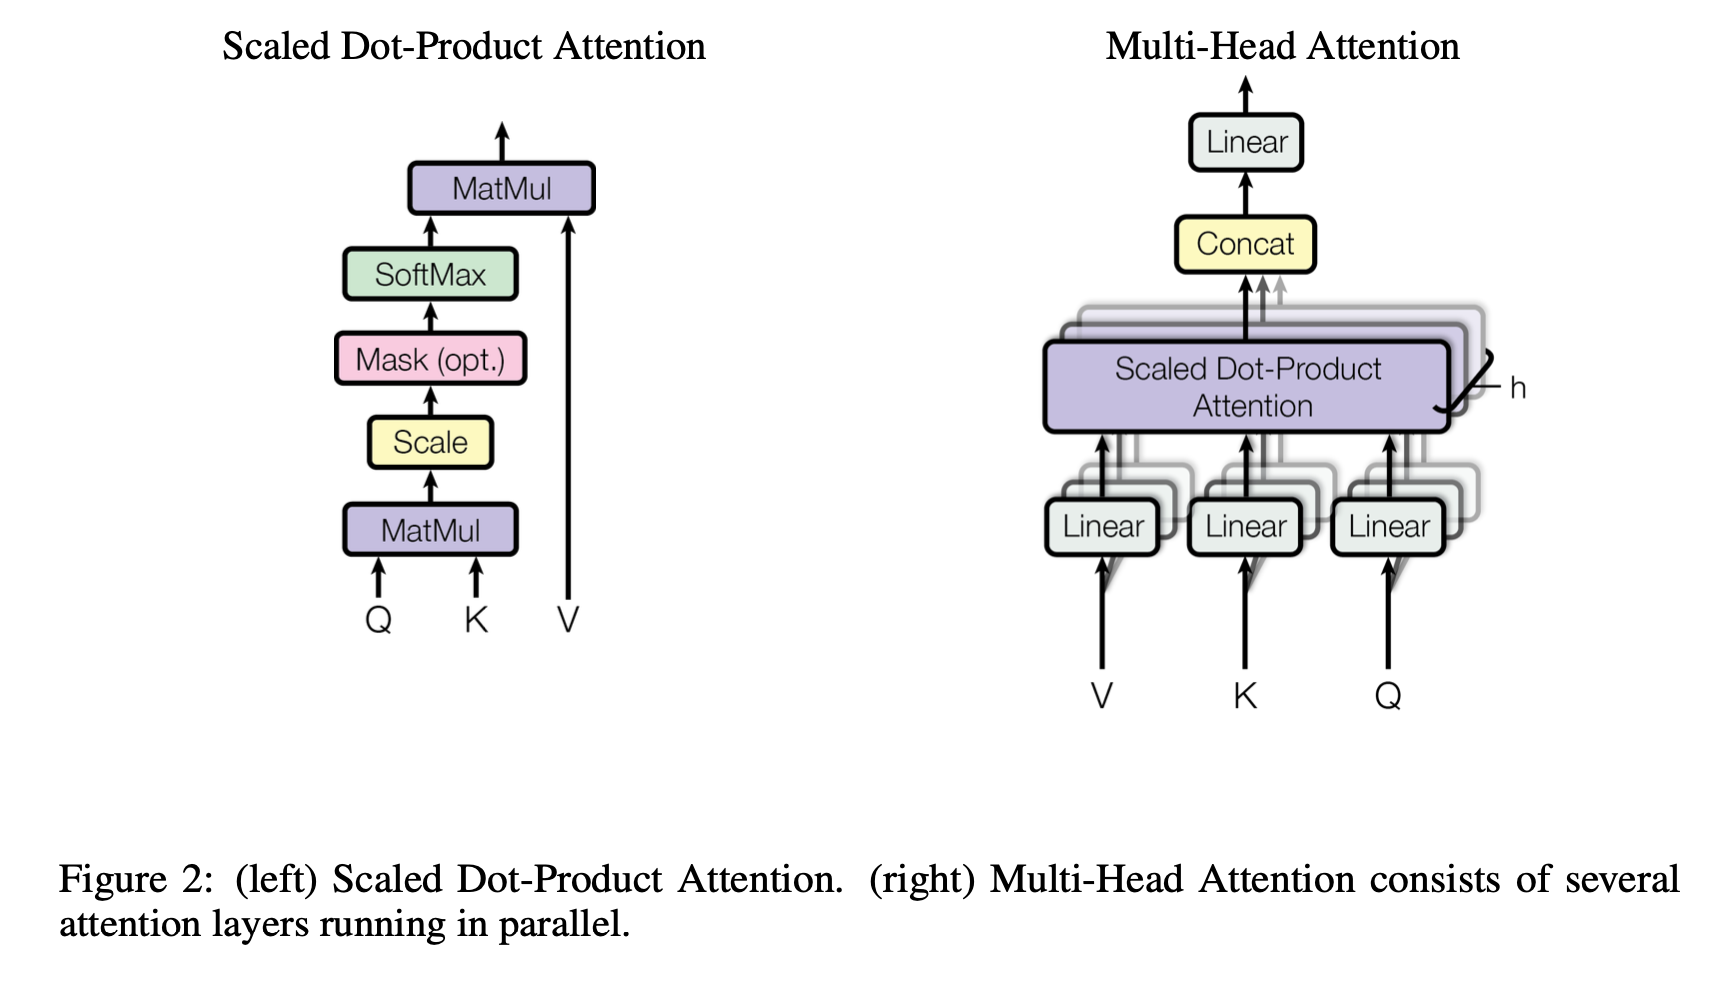
One of the key concepts introduced by Transformer model is multi-head ...

Transformer encoder network structure (left) and multi-head attention ...

Transformer encoder block with multi-head attention and scaled dot ...

Detailed Diagram of Transformer Neural Network Encoder with Self ...
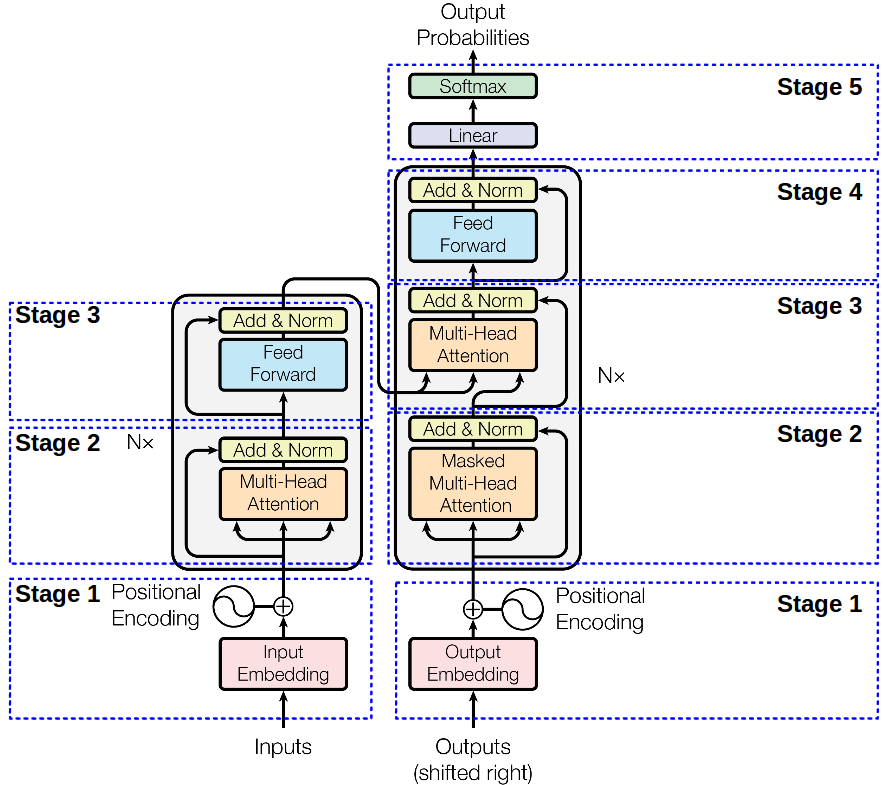
The Transformer – Attention is all you need. - Michał Chromiak's blog

Understanding The Transformer Architecture
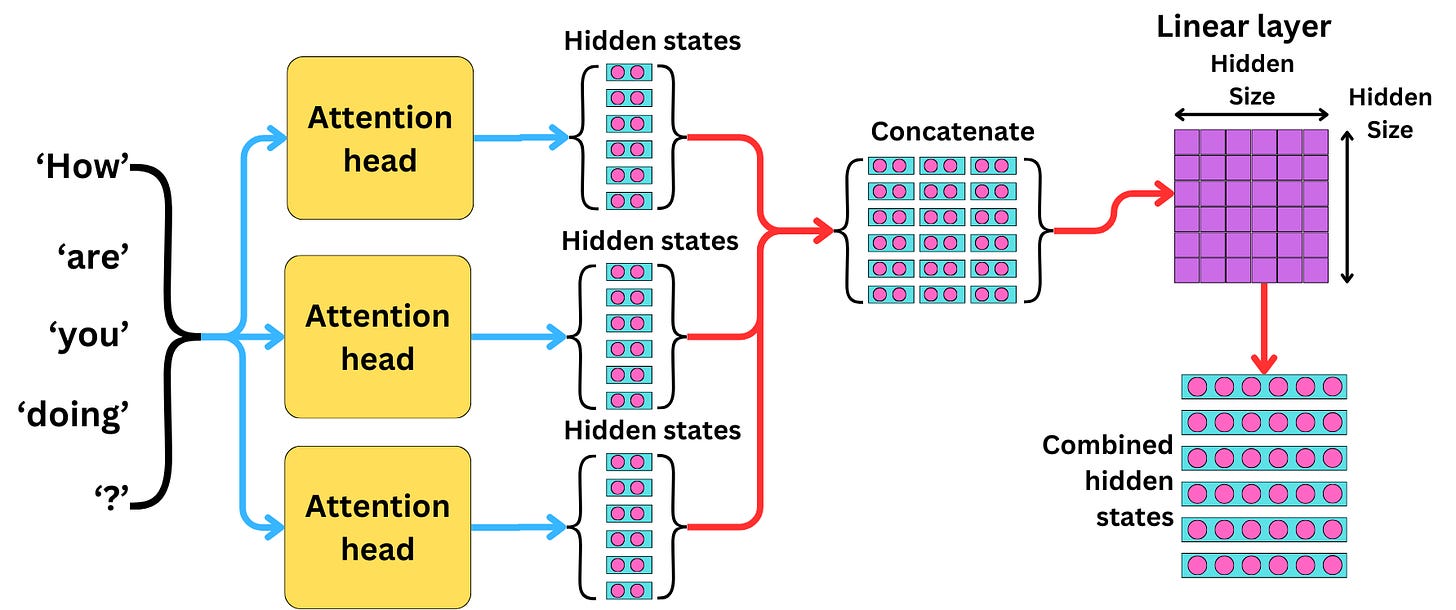
The Transformer Architecture (V2) - by Damien Benveniste
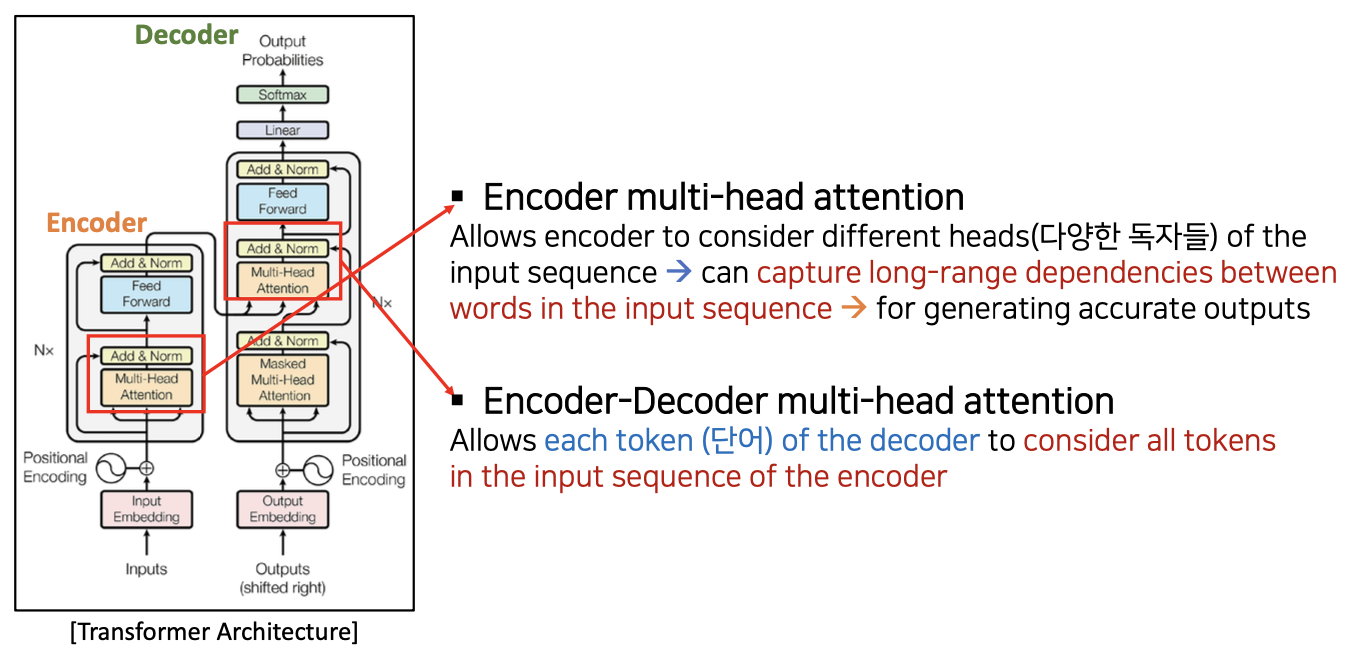
Chapter 3. Transformer and Attention
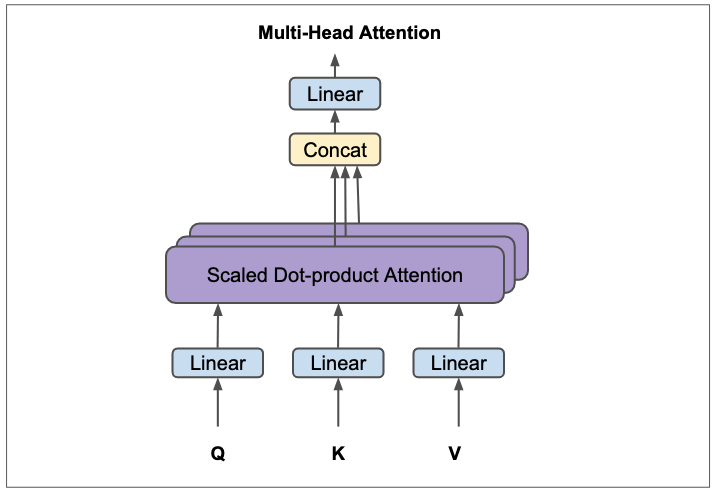
AI Research Blog - The Transformer Blueprint: A Holistic Guide to the ...
Advertisement Space (336x280)
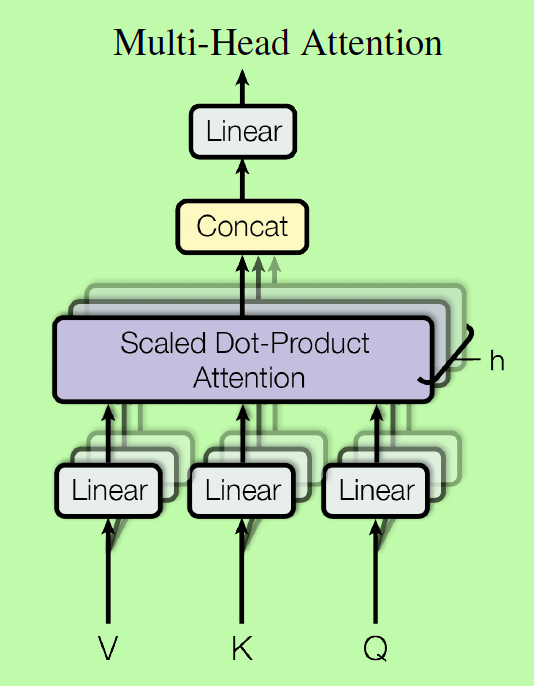
Unlocking the Transformer Model
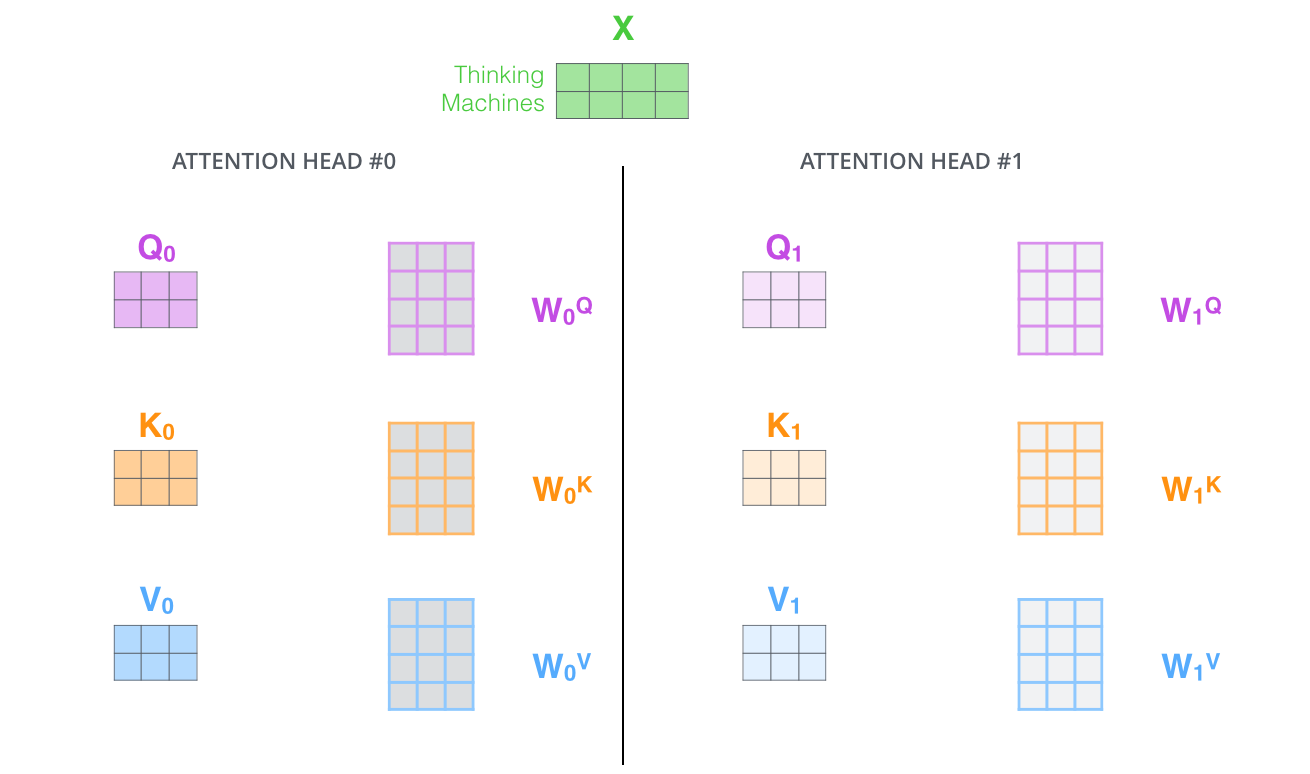
The Illustrated Transformer – Jay Alammar – Visualizing machine ...

The Transformer Architecture (V2) - by Damien Benveniste
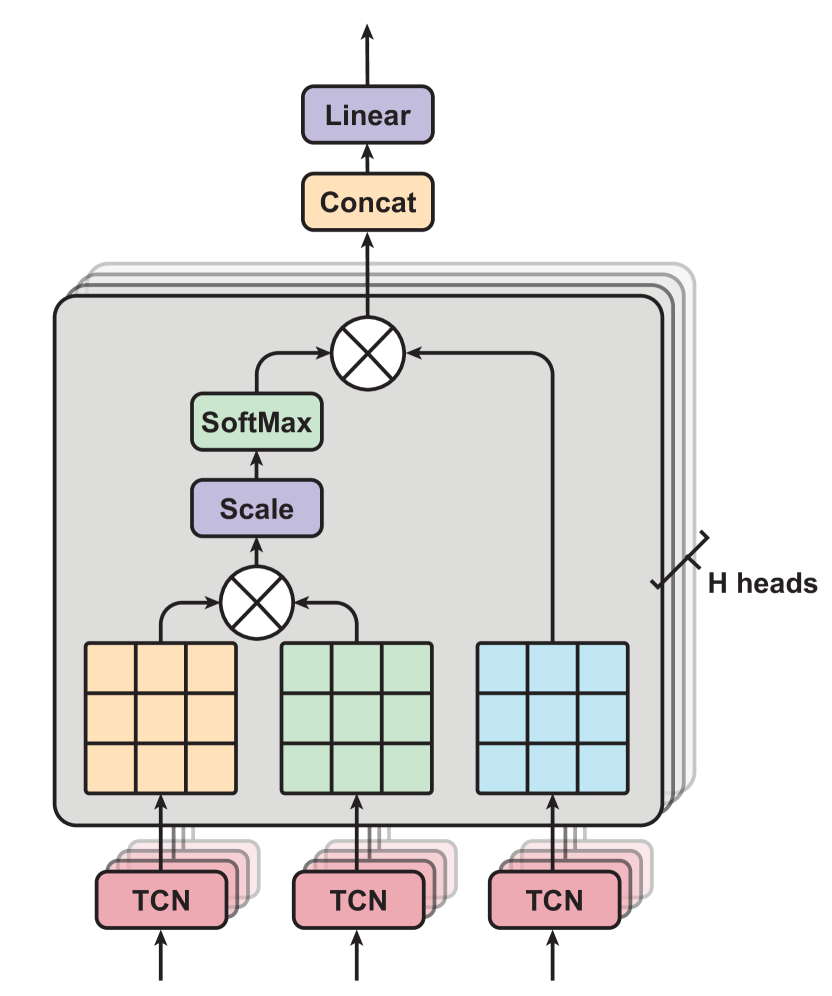
[2303.06845] Transformer Encoder with Multiscale Deep Learning for Pain ...

Decoder vs Encoder in Transformer Models | AI Tutorial | Next Electronics

The architecture of the multi-head self-attention layer. | Download ...