
Turbocharging Ai Inference With Kv Cache Offload

Turbocharging AI Inference with KV Cache Offload

KV Cache Offloading: Unlocking AI Inference Efficiency with NVMe SSDs ...
KV Cache Offload for AI Inference

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

Revolutionizing AI Inference With KV Cache Servers

KV Cache Offload Accelerates LLM Inference - NADDOD Blog

Inference-Time Hyper-Scaling with KV Cache Compression | AI Research ...
White Paper: KV Cache Offload to Improve AI Inferencing Cost and ...

KV Cache Offloading: The New Storage Workload for AI Inference

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...
Advertisement Space (300x250)

Enabling inference at massive scale with hybrid storage for KV cache ...

Enabling inference at massive scale with hybrid storage for KV cache ...
AI inference gains 10x boost from KV cache offloading - SiliconANGLE

LLM Inference: Accelerating Long Context Generation with KV Cache ...
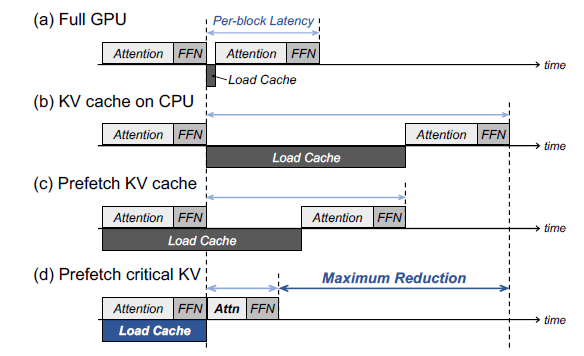
KV Cache compression with Inter-Layer Attention Similarity for ...

KV Cache Is Eating Your VRAM. Here’s How Google Fixed It With ...

From Bottleneck to Breakthrough: Scalable KV Cache Offloading with Dell ...
TurboQuant KV Cache Compression: What Changes for LLM Inference

Batch Processing & KV Cache: Supercharging On-Device AI Inference
Google's TurboQuant Achieves 6x KV Cache Compression for LLM Inference ...
Advertisement Space (336x280)

Dell PowerScale and ObjectScale with KV Cache Offloading | ITN

AI 推理 KV Cache 详解:Transformer 架构下的性能优化关键 - 开发技术 - 冷月清谈
Cache Eviction in AI: KV Cache Management Explained | Inference Systems
KV Caching Explained: Boost AI Inference Speed and Reduce Latency ...
KV Cache Offloading in K8s: The Stateless Truce — AI Infrastructure ...
What is KV Cache? A Beginner's Guide to Faster AI Inference

KV Cache Offloading in LLM Inference | PDF | Cache (Computing ...
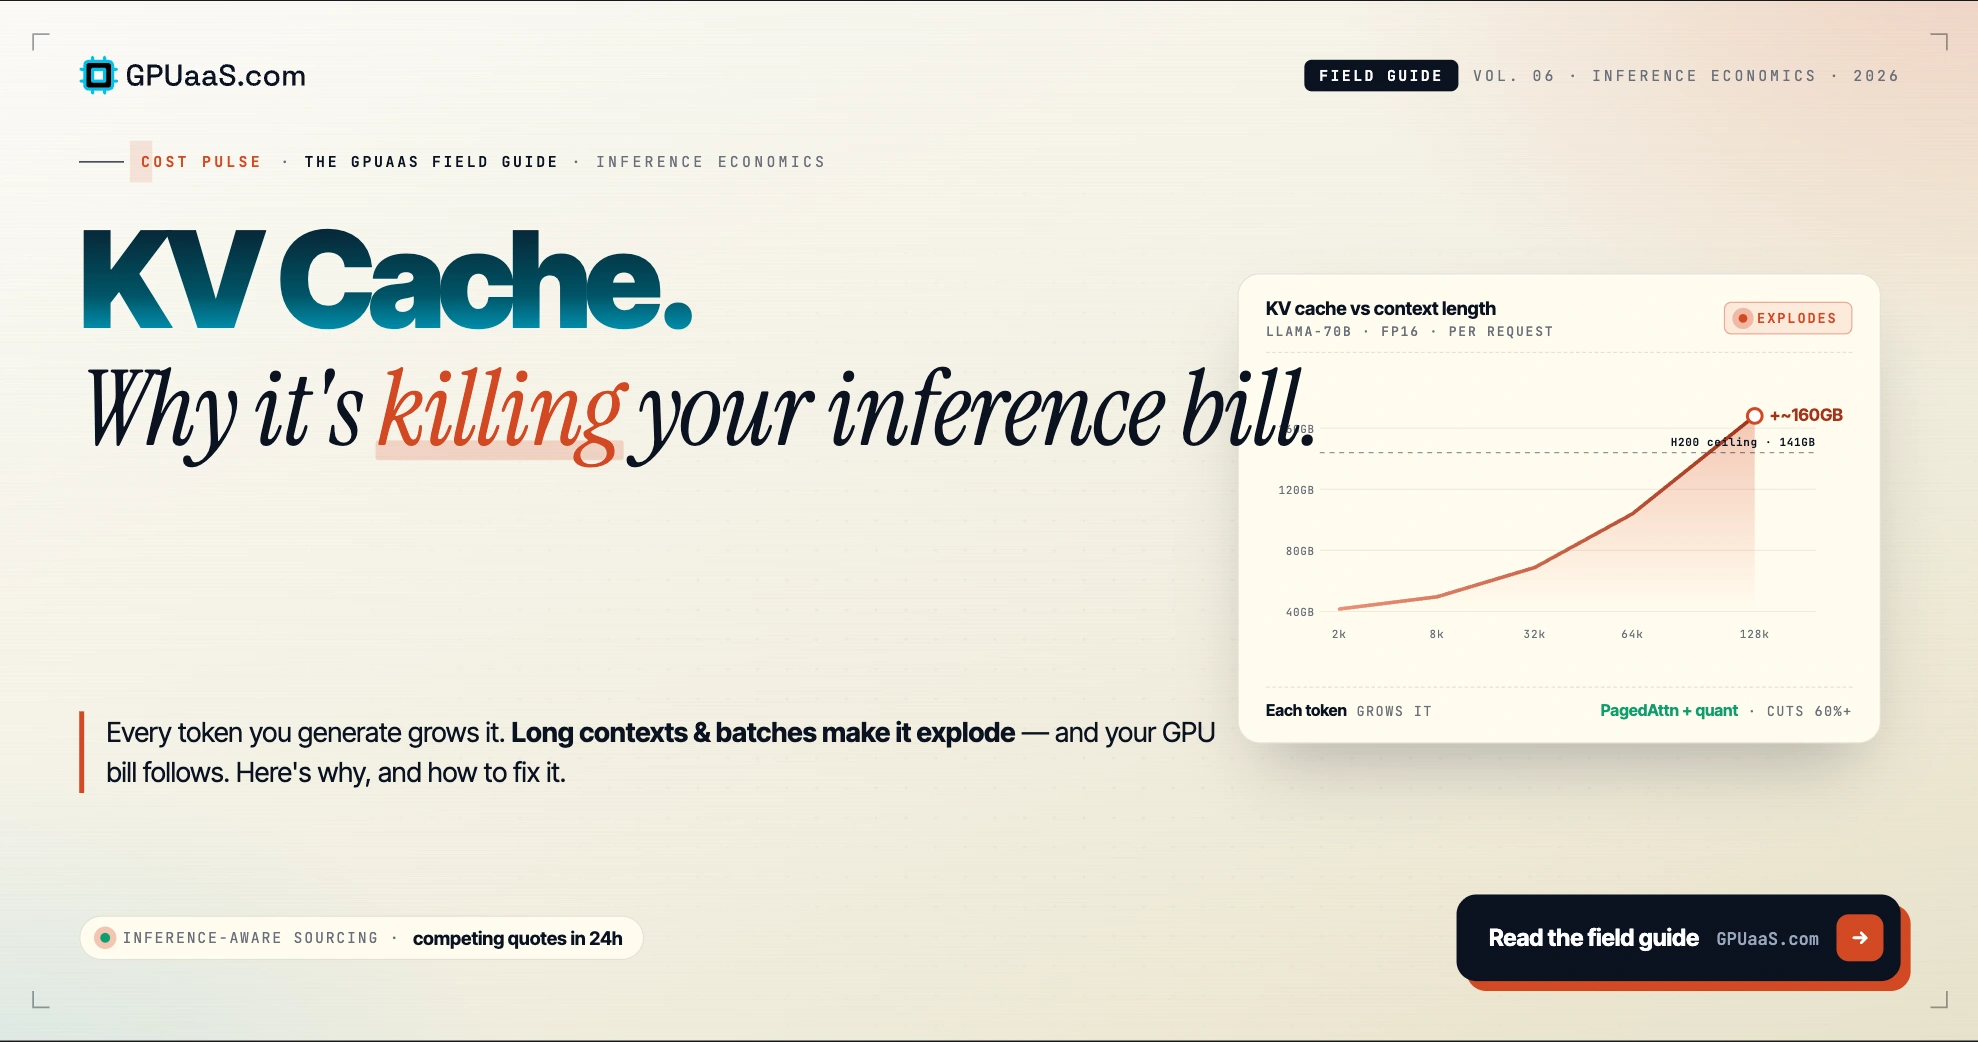
KV Cache Explained: Cut LLM Inference Costs 2026 | GPUaaS.com

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...
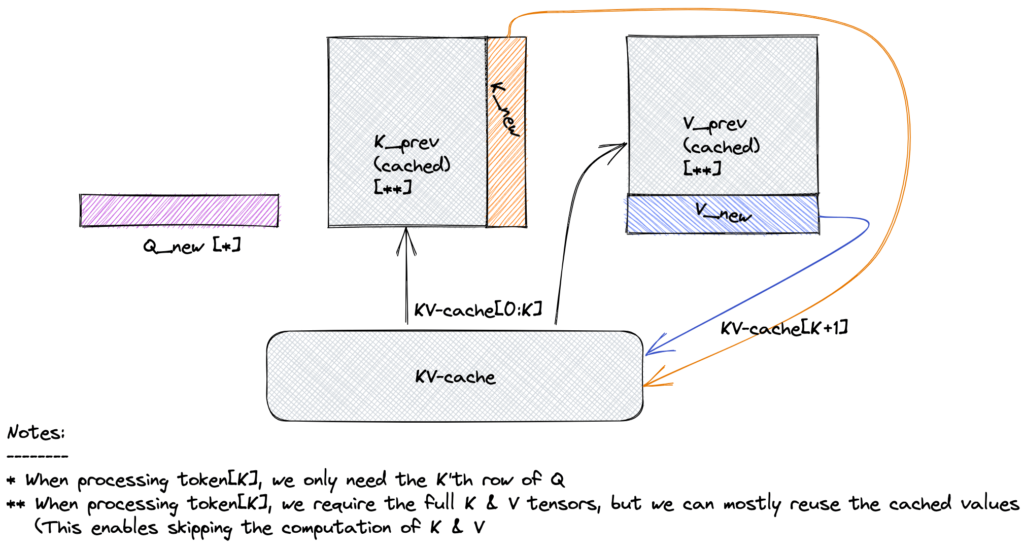
KV Cache in Transformer Models - Data Magic AI Blog
Advertisement Space (336x280)
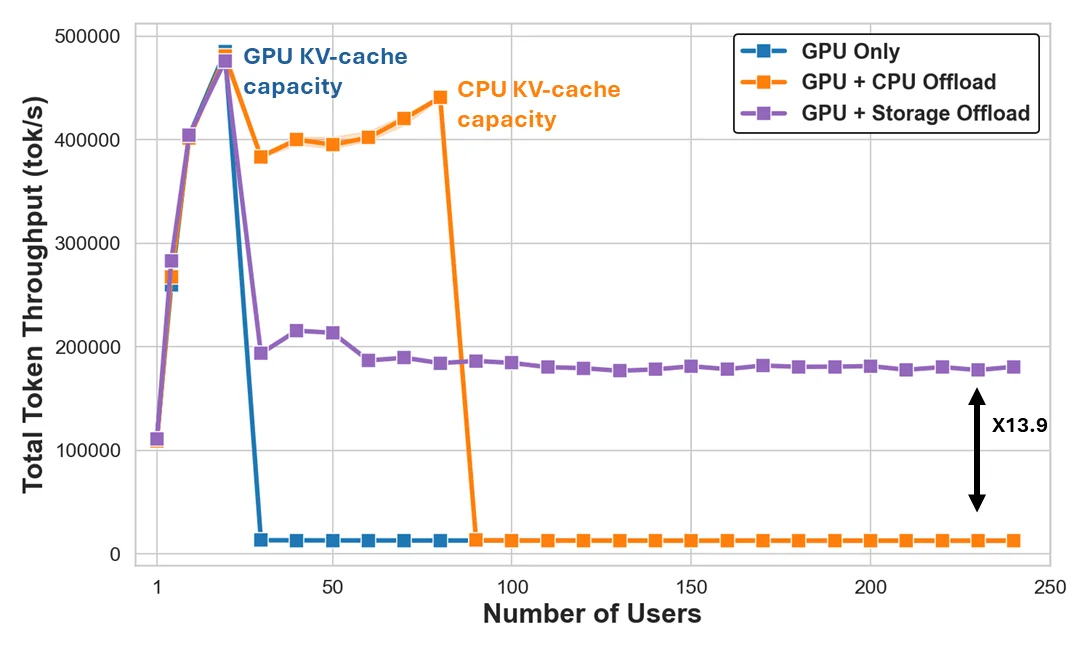
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d
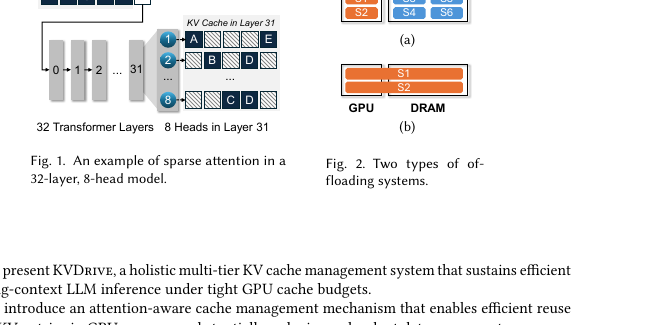
KVDrive:面向长上下文 LLM Inference 的多层 KV Cache 管理系统中文翻译稿
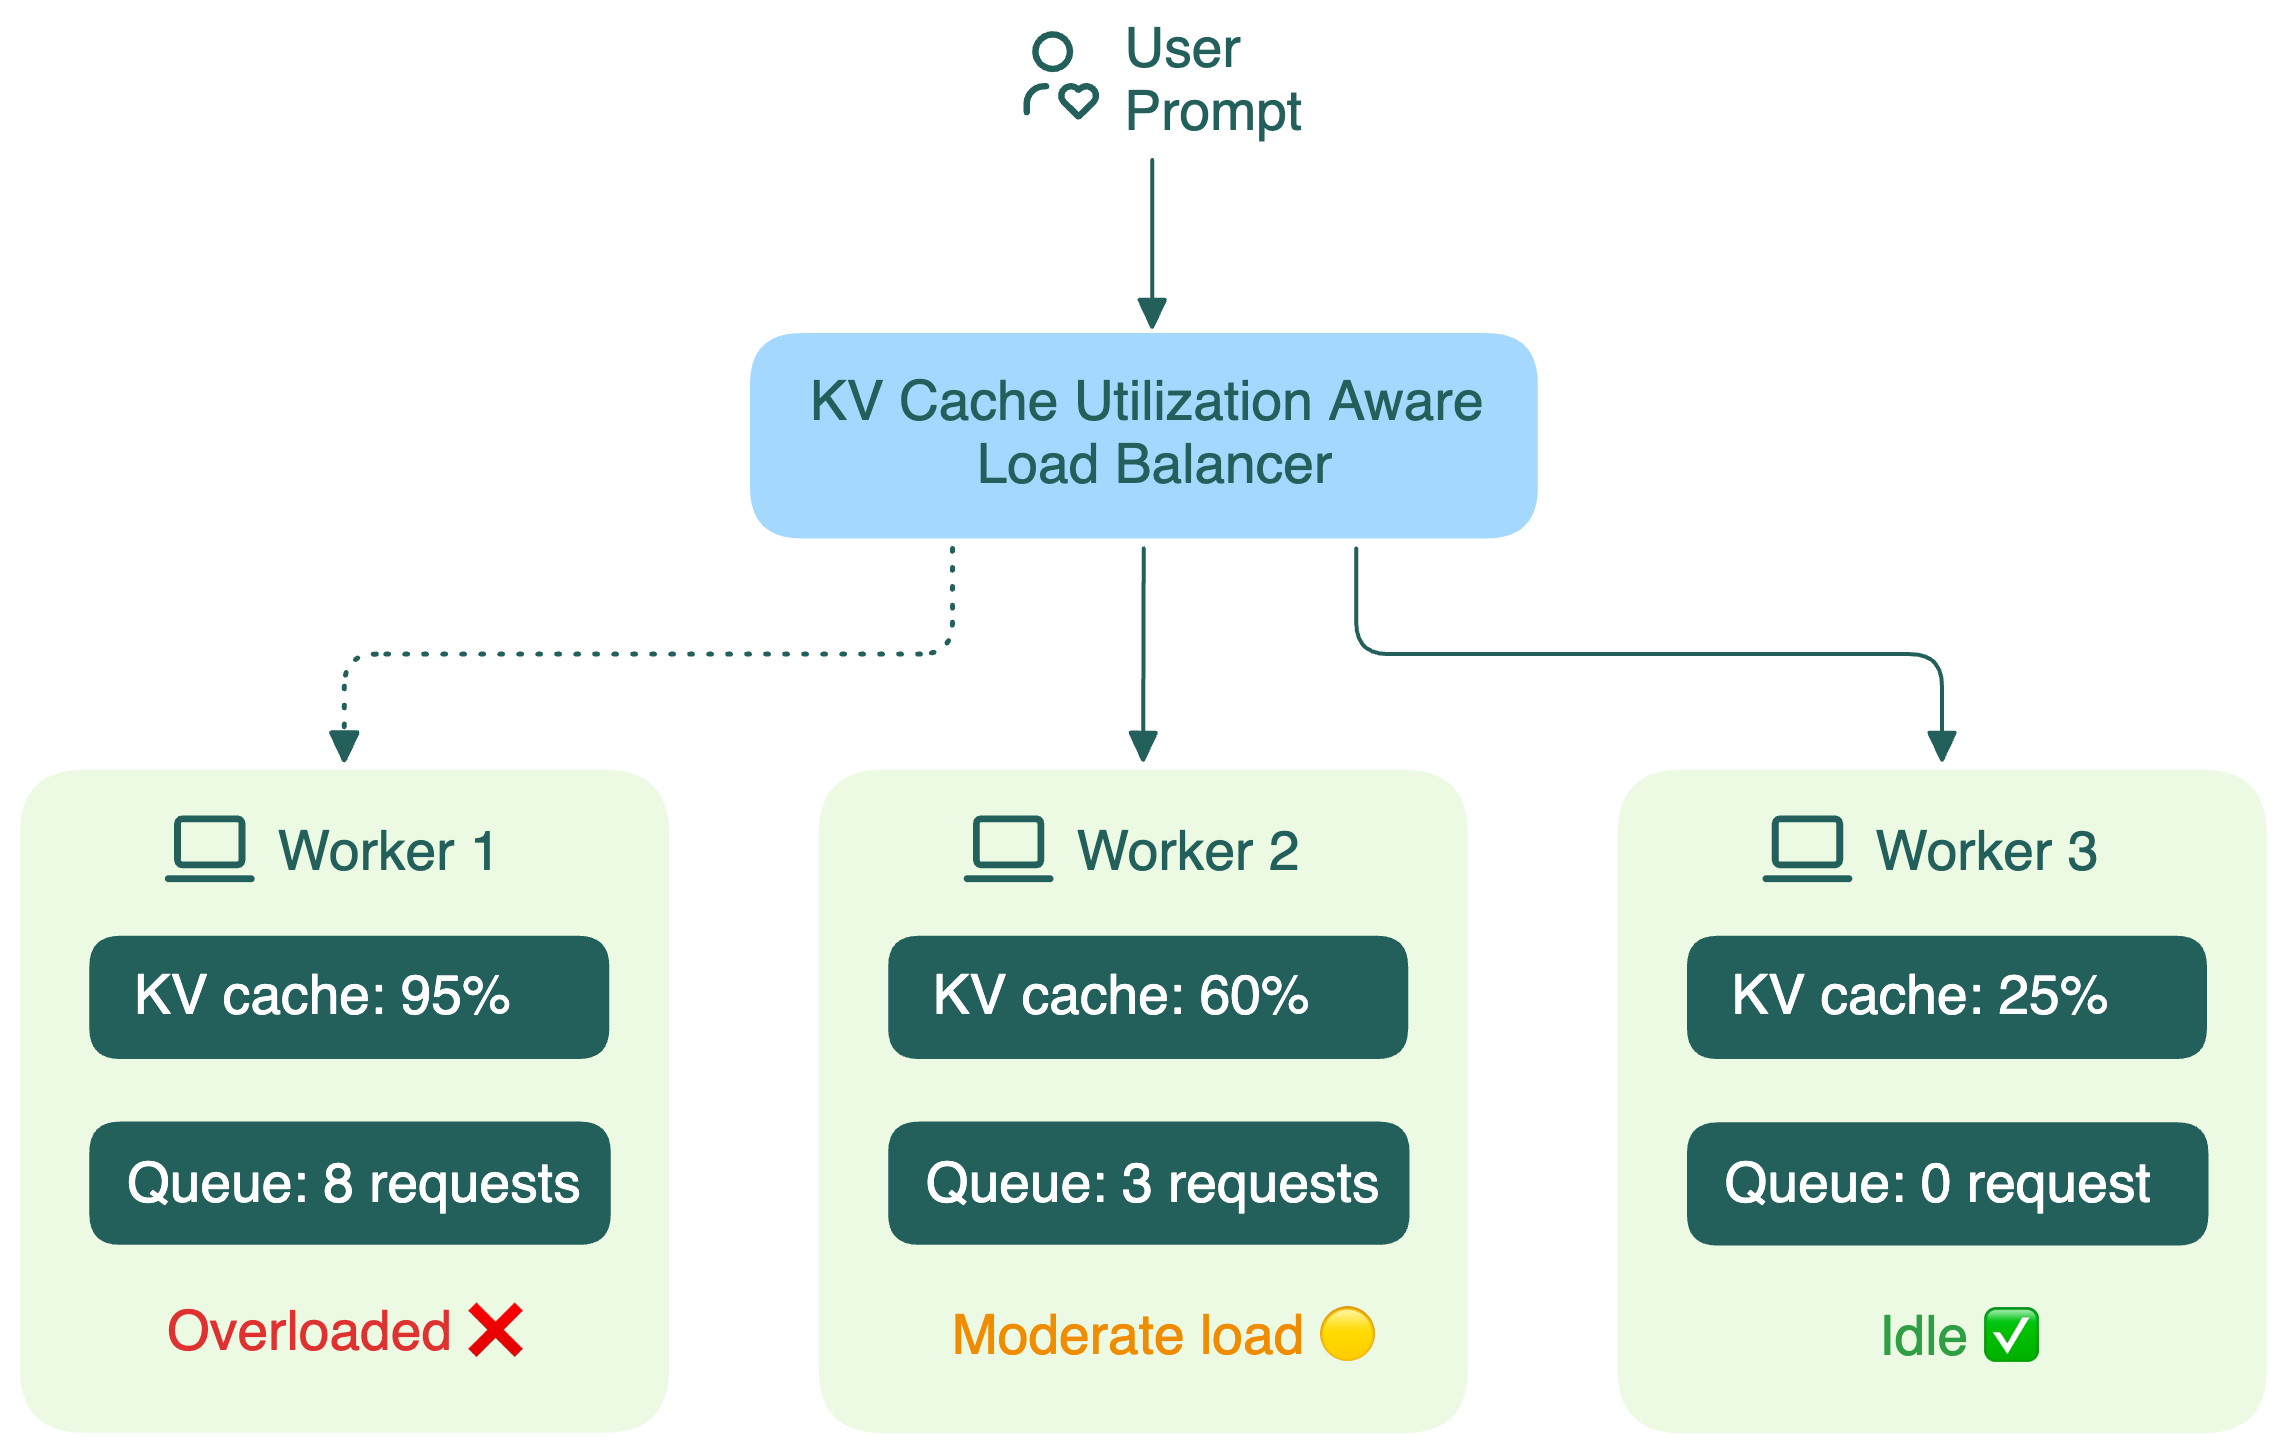
KV cache utilization-aware load balancing | LLM Inference Handbook

LLM Inference: Accelerating Long Context Generation with KV Cache ...

TurboQuant: Compressing KV Cache for Real-World Inference

Layer-Condensed KV Cache for Efficient Inference of Large Language ...