
Kv Cache Offloading Unlocking Ai Inference Efficiency With Nvme Ssds

KV Cache Offloading: Unlocking AI Inference Efficiency with NVMe SSDs ...

KV Cache Offloading: Unlocking AI Inference Efficiency with NVMe SSDs ...

KV Cache Offloading: Unlocking AI Inference Efficiency with NVMe SSDs ...

Offloading LLM Models and KV Caches to NVMe SSDs — AI Post Transformers

Turbocharging AI Inference with KV Cache Offload

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...

Revolutionizing AI Inference With KV Cache Servers

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

Enabling inference at massive scale with hybrid storage for KV cache ...

Nvidia pushes AI inference context out to NVMe SSDs
Advertisement Space (300x250)

Enabling inference at massive scale with hybrid storage for KV cache ...
NVMe KV Cache Offloading for LLM Inference: Serve 10x More Users on the ...

KV Cache Offloading: The New Storage Workload for AI Inference

Enabling inference at massive scale with hybrid storage for KV cache ...

Enabling inference at massive scale with hybrid storage for KV cache ...
NVIDIA ICMSP Explained: KV Cache NVMe Offload, 5x Inference Gains, and ...

Dell PowerScale and ObjectScale with KV Cache Offloading | ITN

From Bottleneck to Breakthrough: Scalable KV Cache Offloading with Dell ...

Nvidia pushes AI inference context out to NVMe SSDs
KV Cache Offloading in K8s: The Stateless Truce — AI Infrastructure ...
Advertisement Space (336x280)
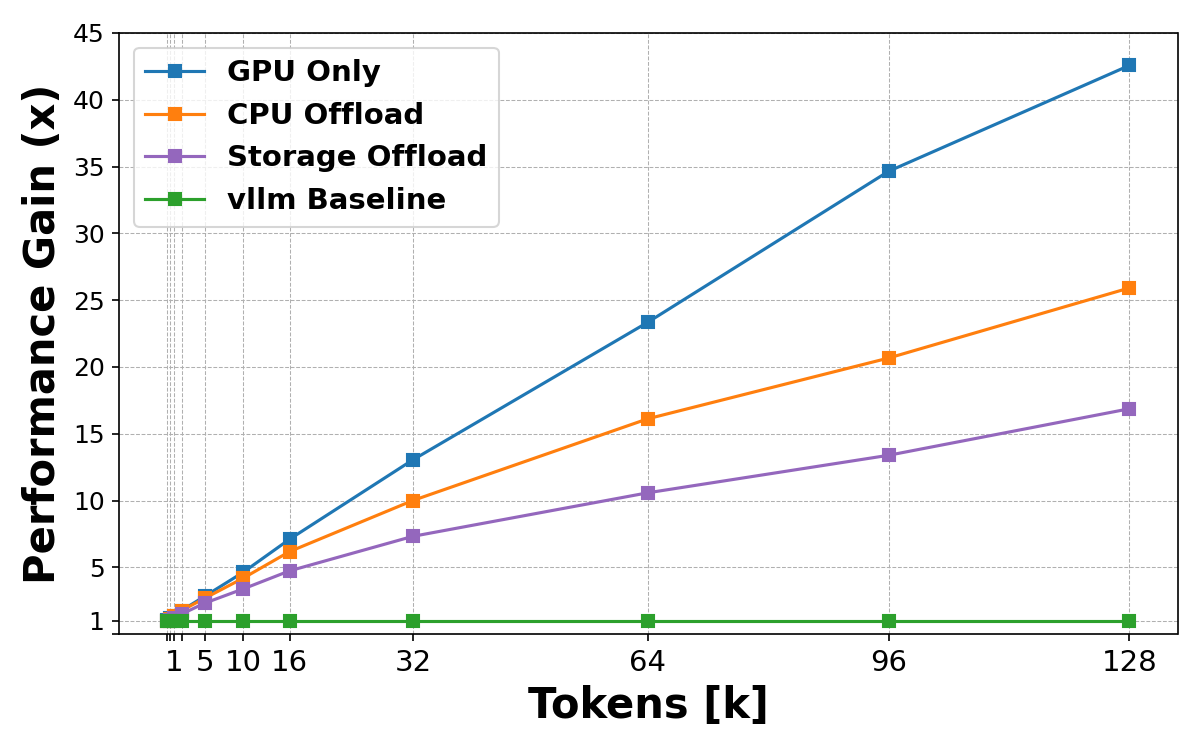
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d

AI KV Cache SSDs Signal a New Local Agent Infrastructure Layer — nexu

Inference-Time Hyper-Scaling with KV Cache Compression | AI Research ...

Enabling inference at massive scale with hybrid storage for KV cache ...
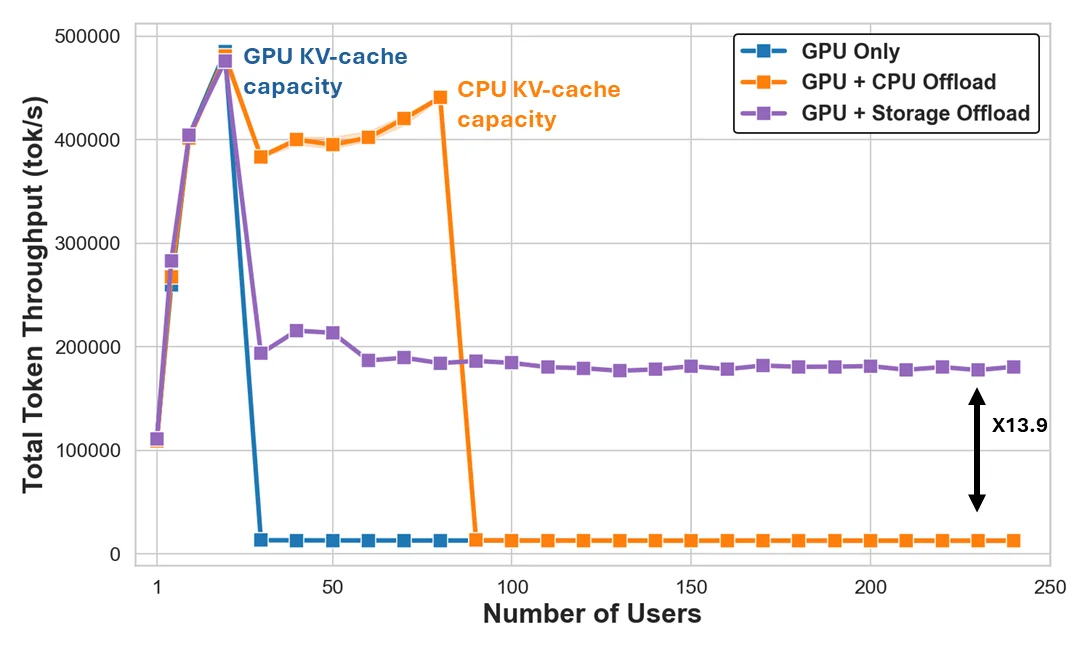
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d
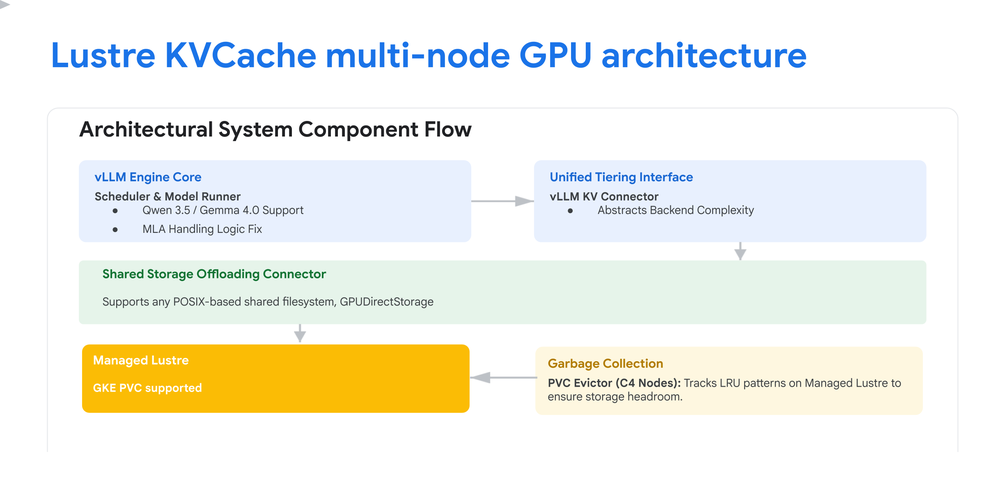
Scaling LLM Inference: Multi-Node KV Cache Offloading with GKE ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...

KV Cache Offloading to NVMe: Progress and Questions

[论文评述] KVSharer: Efficient Inference via Layer-Wise Dissimilar KV Cache ...
Advertisement Space (336x280)

KVSwap: Disk-aware KV Cache Offloading for Long-Context On-device ...
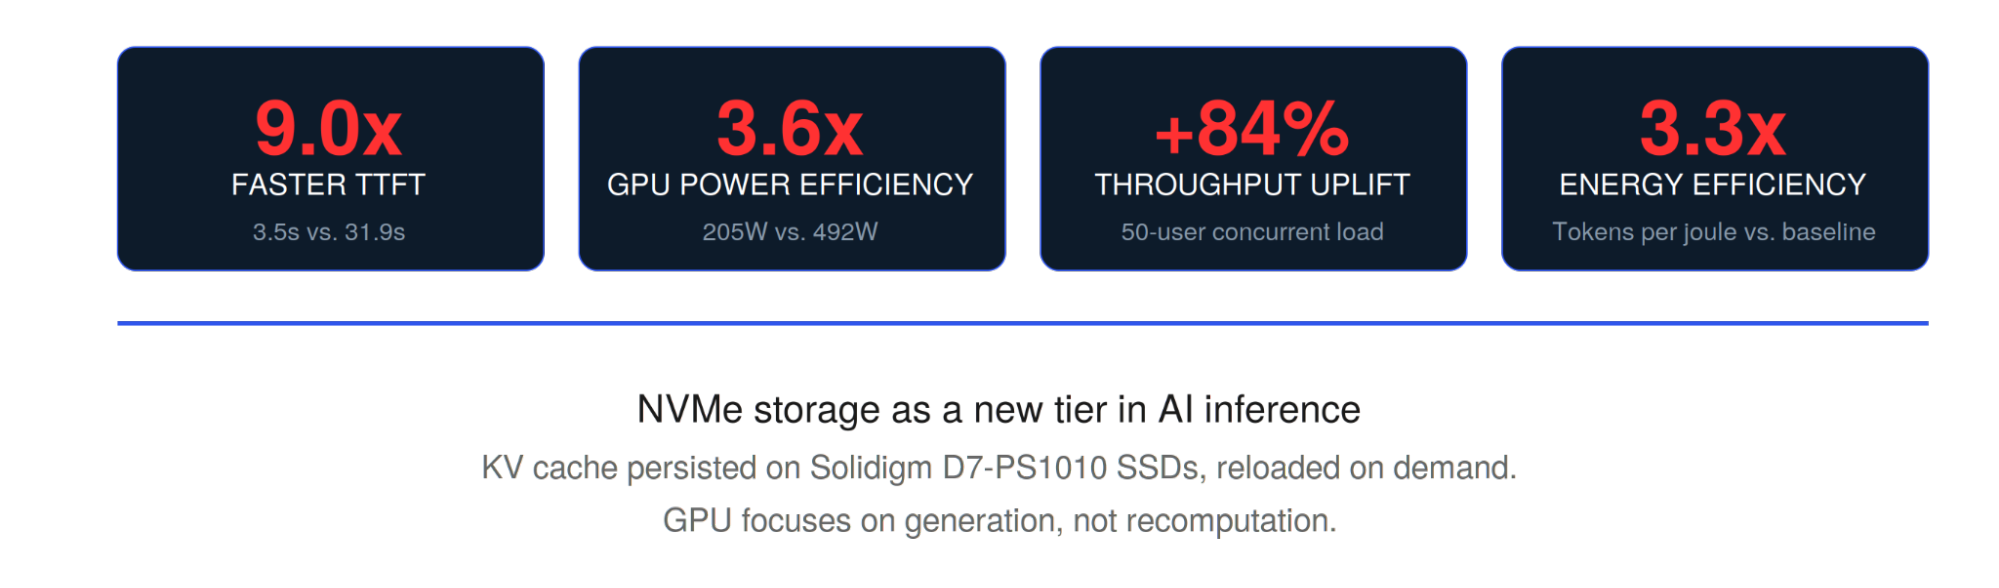
Eliminate Redundant GPU Compute: How Solidigm D7-PS1010 NVMe KV Cache ...
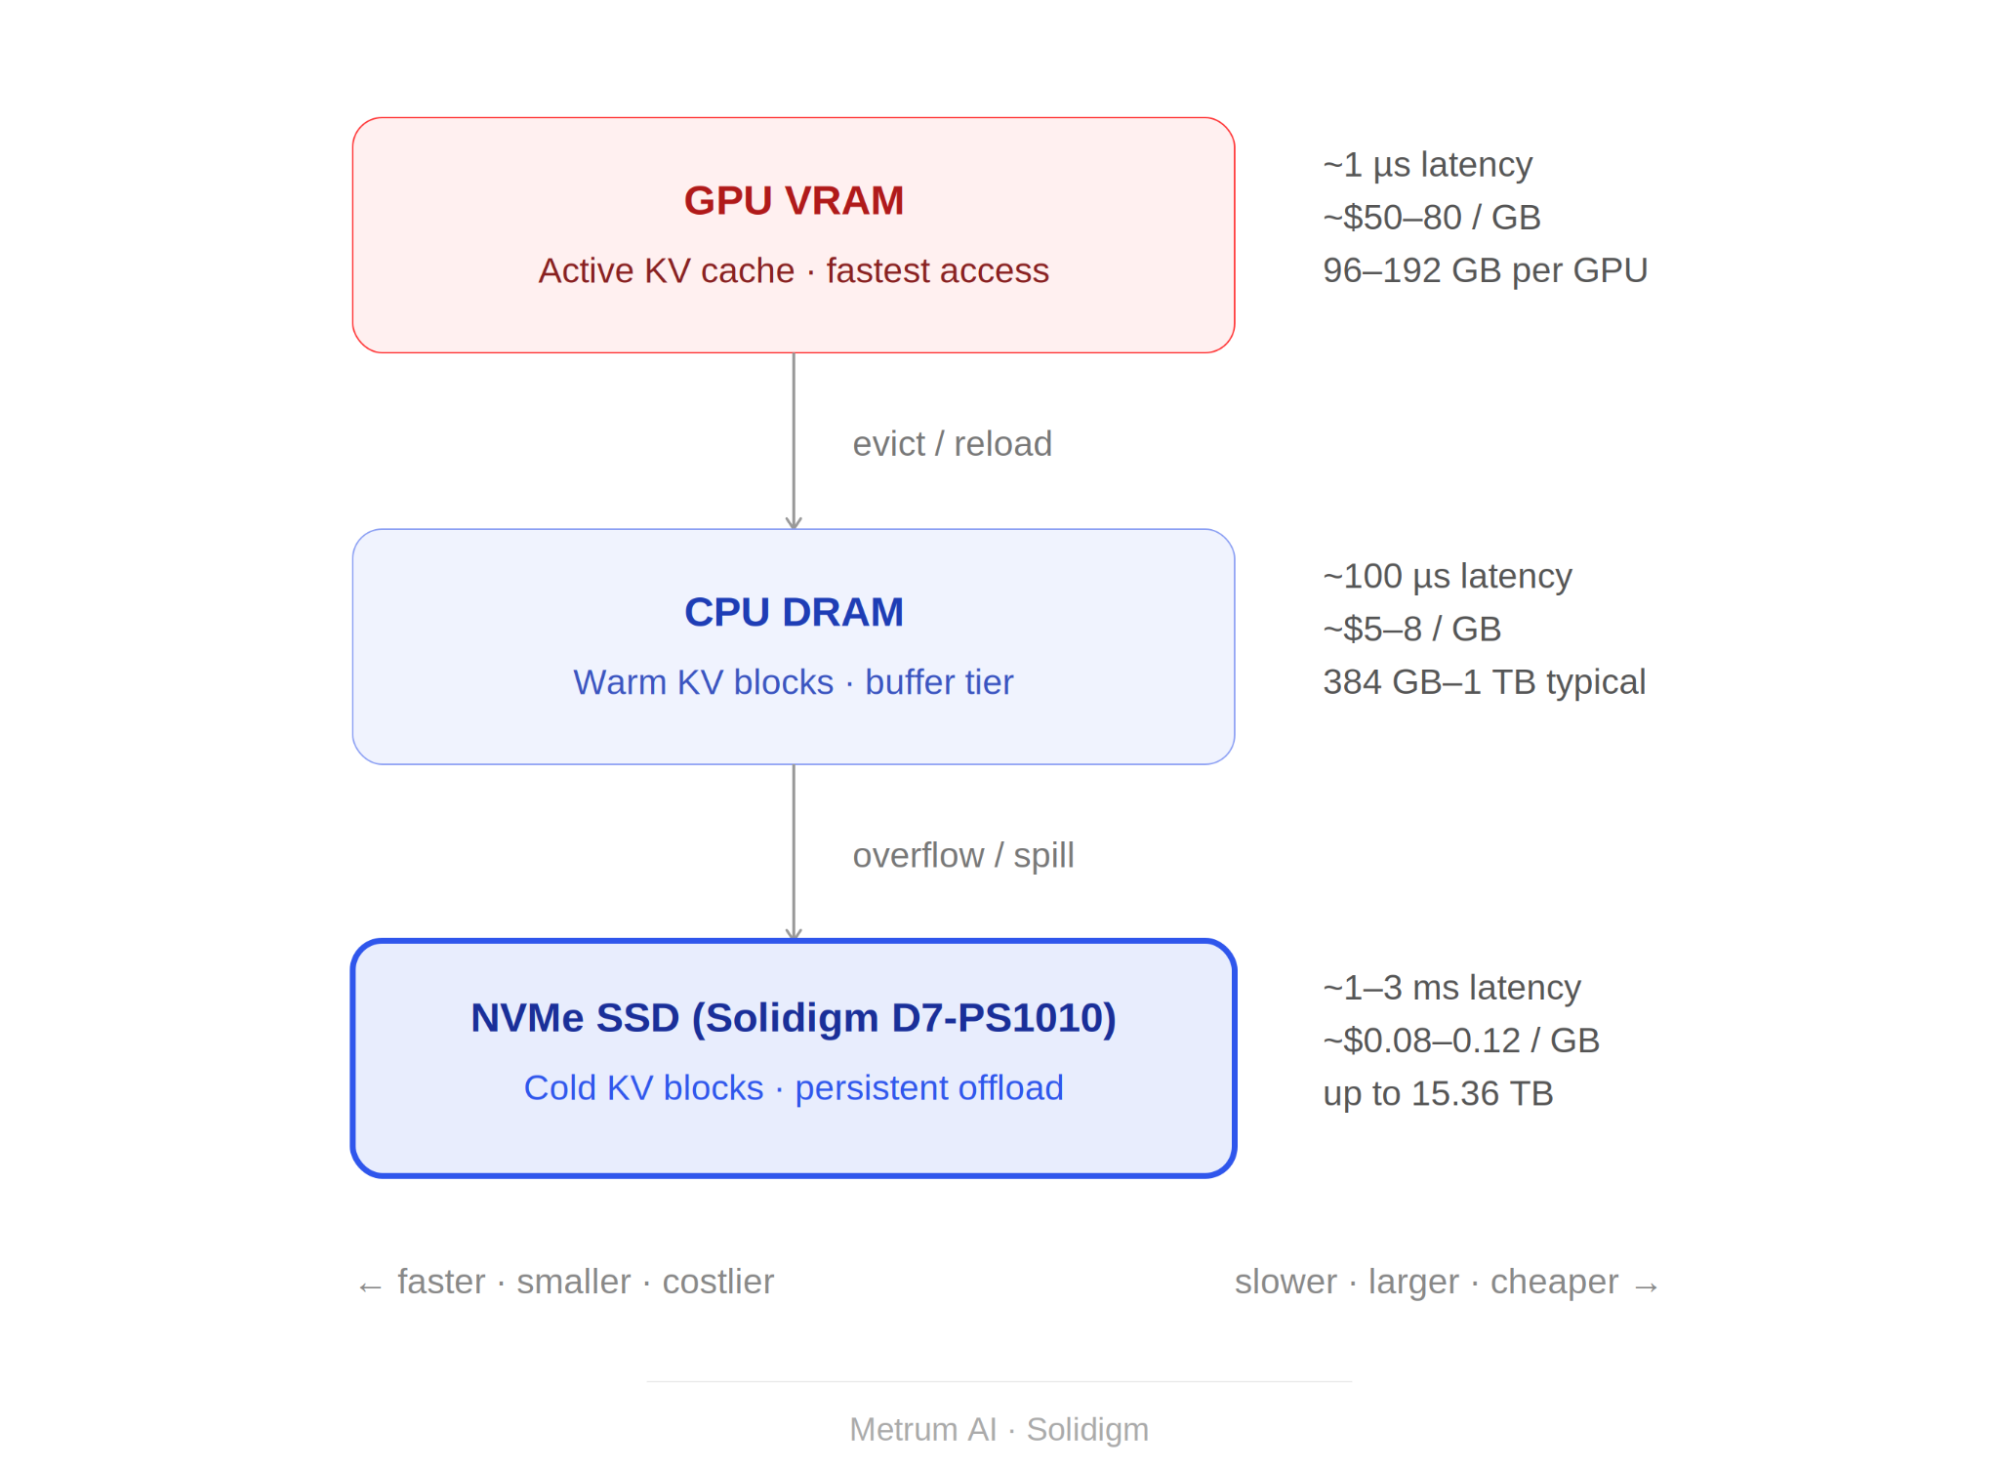
Eliminate Redundant GPU Compute: How Solidigm D7-PS1010 NVMe KV Cache ...

A Roadmap for KV Cache Offloading at Scale - Momento
White Paper: KV Cache Offload to Improve AI Inferencing Cost and ...

KV Cache Offload Accelerates LLM Inference - NADDOD Blog