
Tuto Startup Accelerating Decode Heavy Llm Inference With Speculative Dec
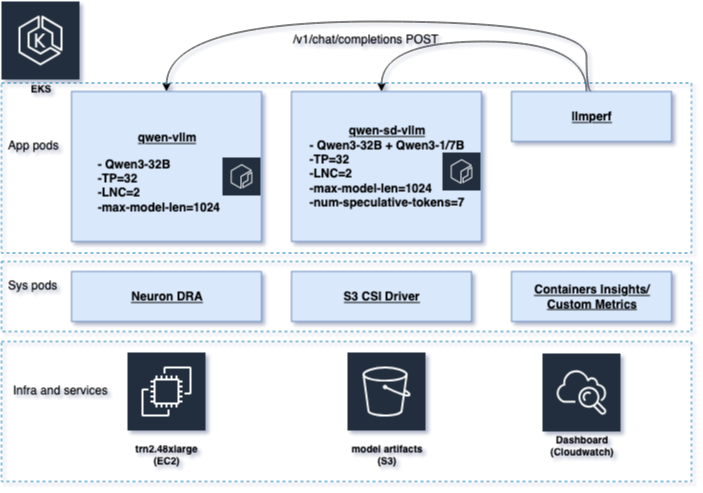
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
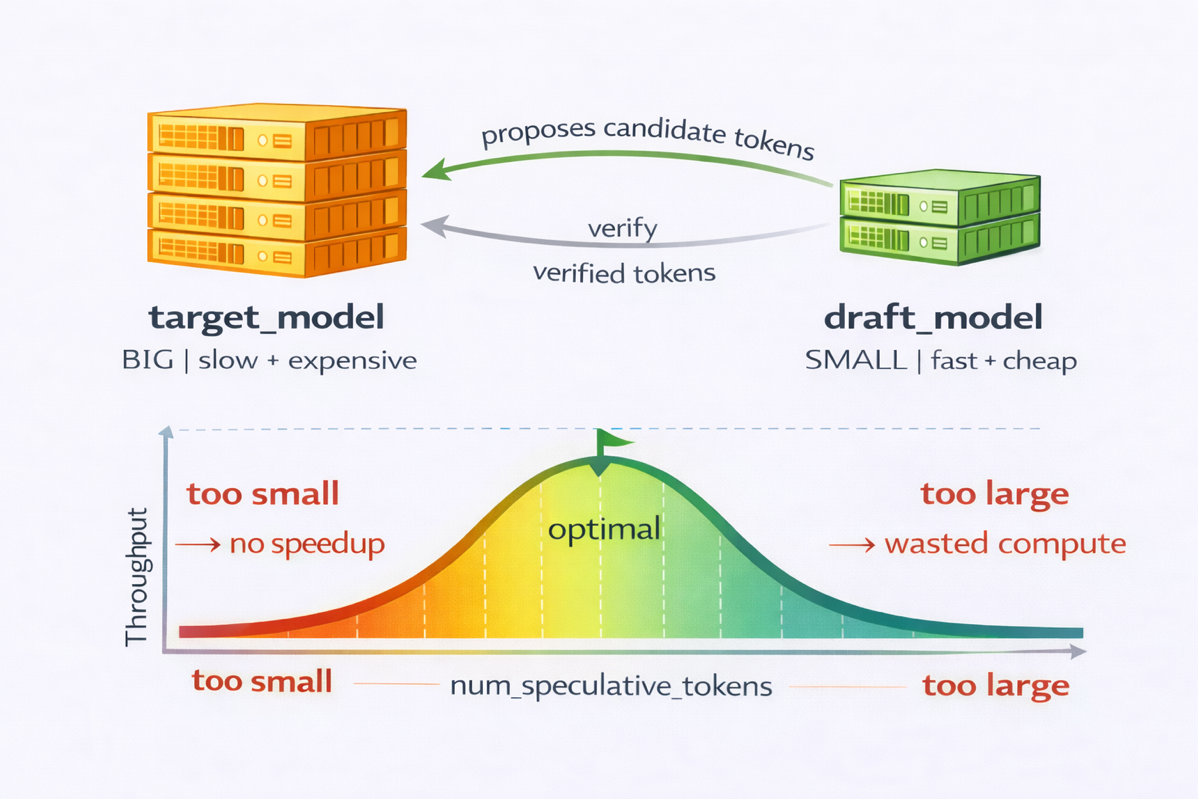
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
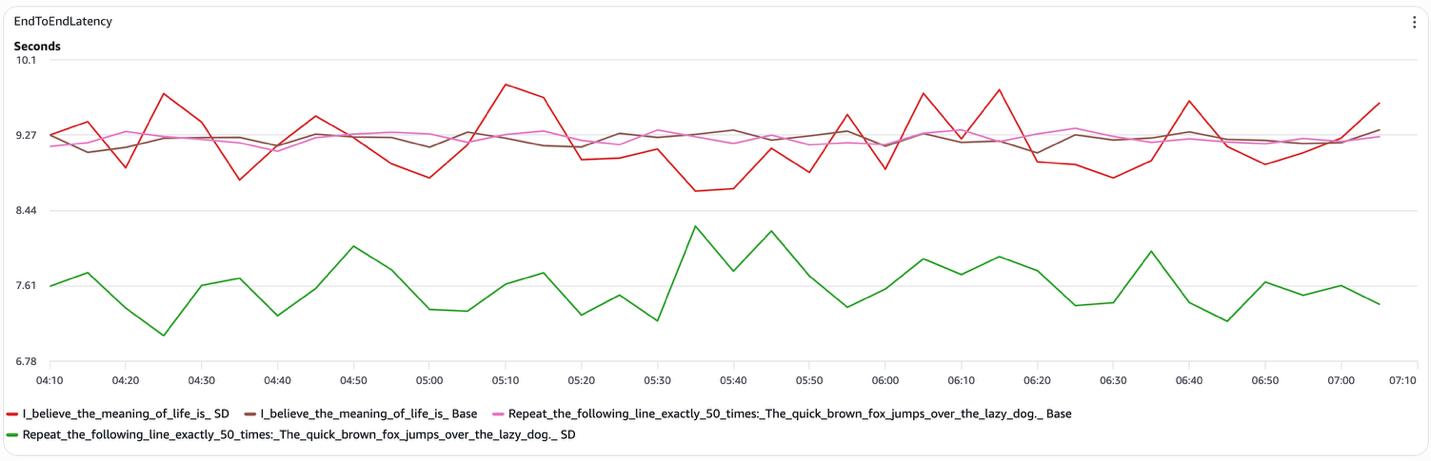
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
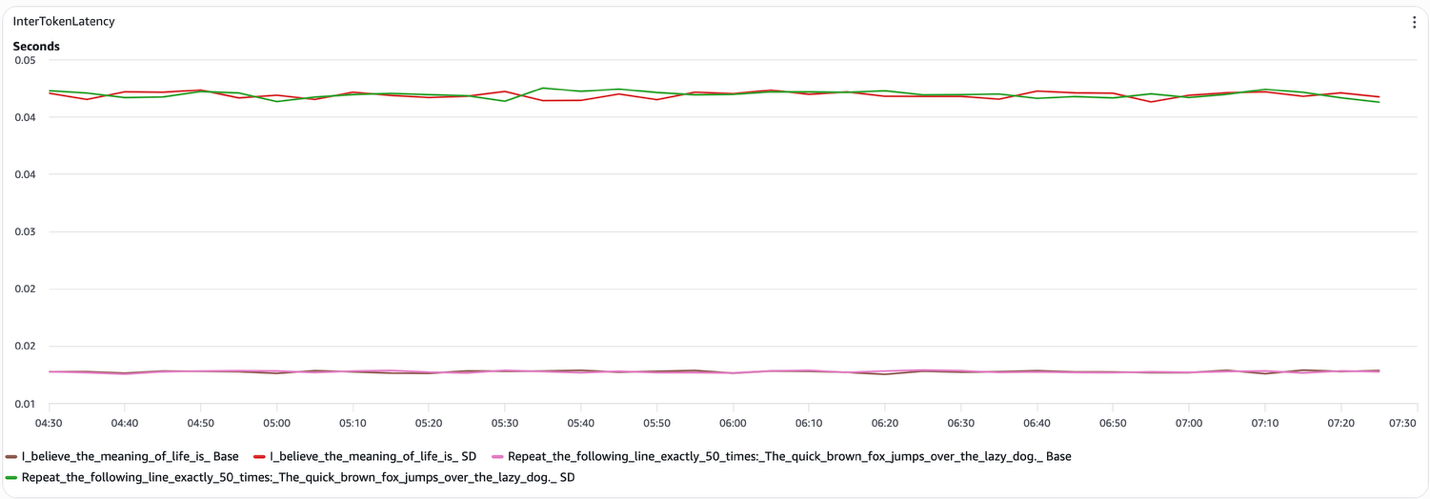
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
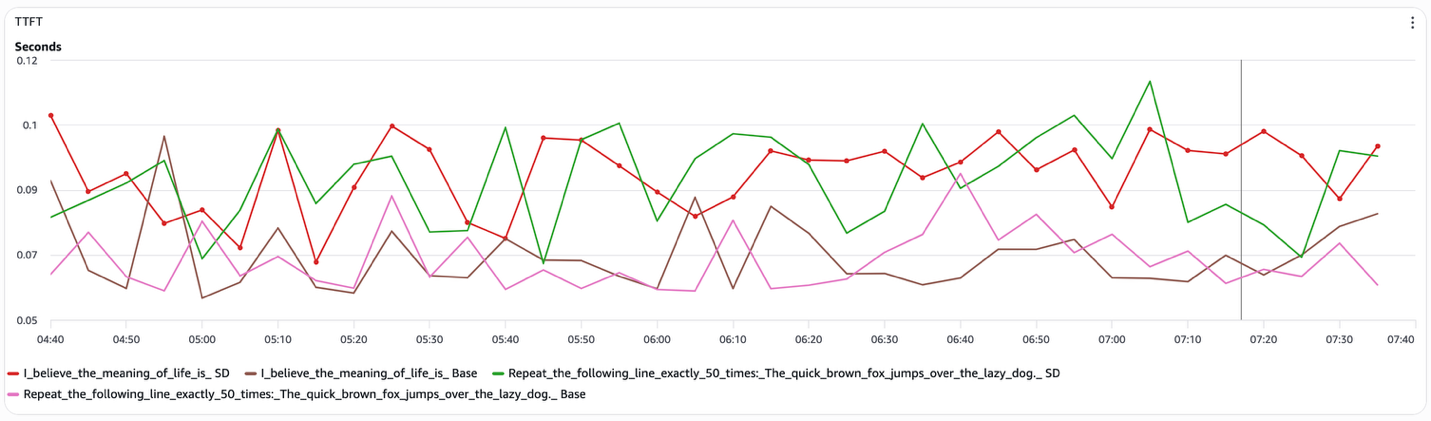
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
Accelerating decode-heavy LLM inference with speculative decoding on ...
Accelerating decode-heavy LLM inference with speculative decoding on ...

Paper page - Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Staged Speculative Decoding

Accelerating LLM Inference with Speculative Decoding - LinkedIn ...
Advertisement Space (300x250)

Accelerating LLM Inference with Staged Speculative Decoding: Paper and ...
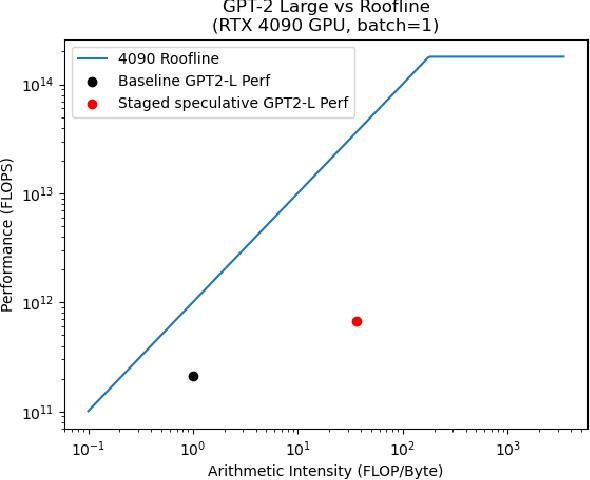
Figure 1 from Accelerating LLM Inference with Staged Speculative ...
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...
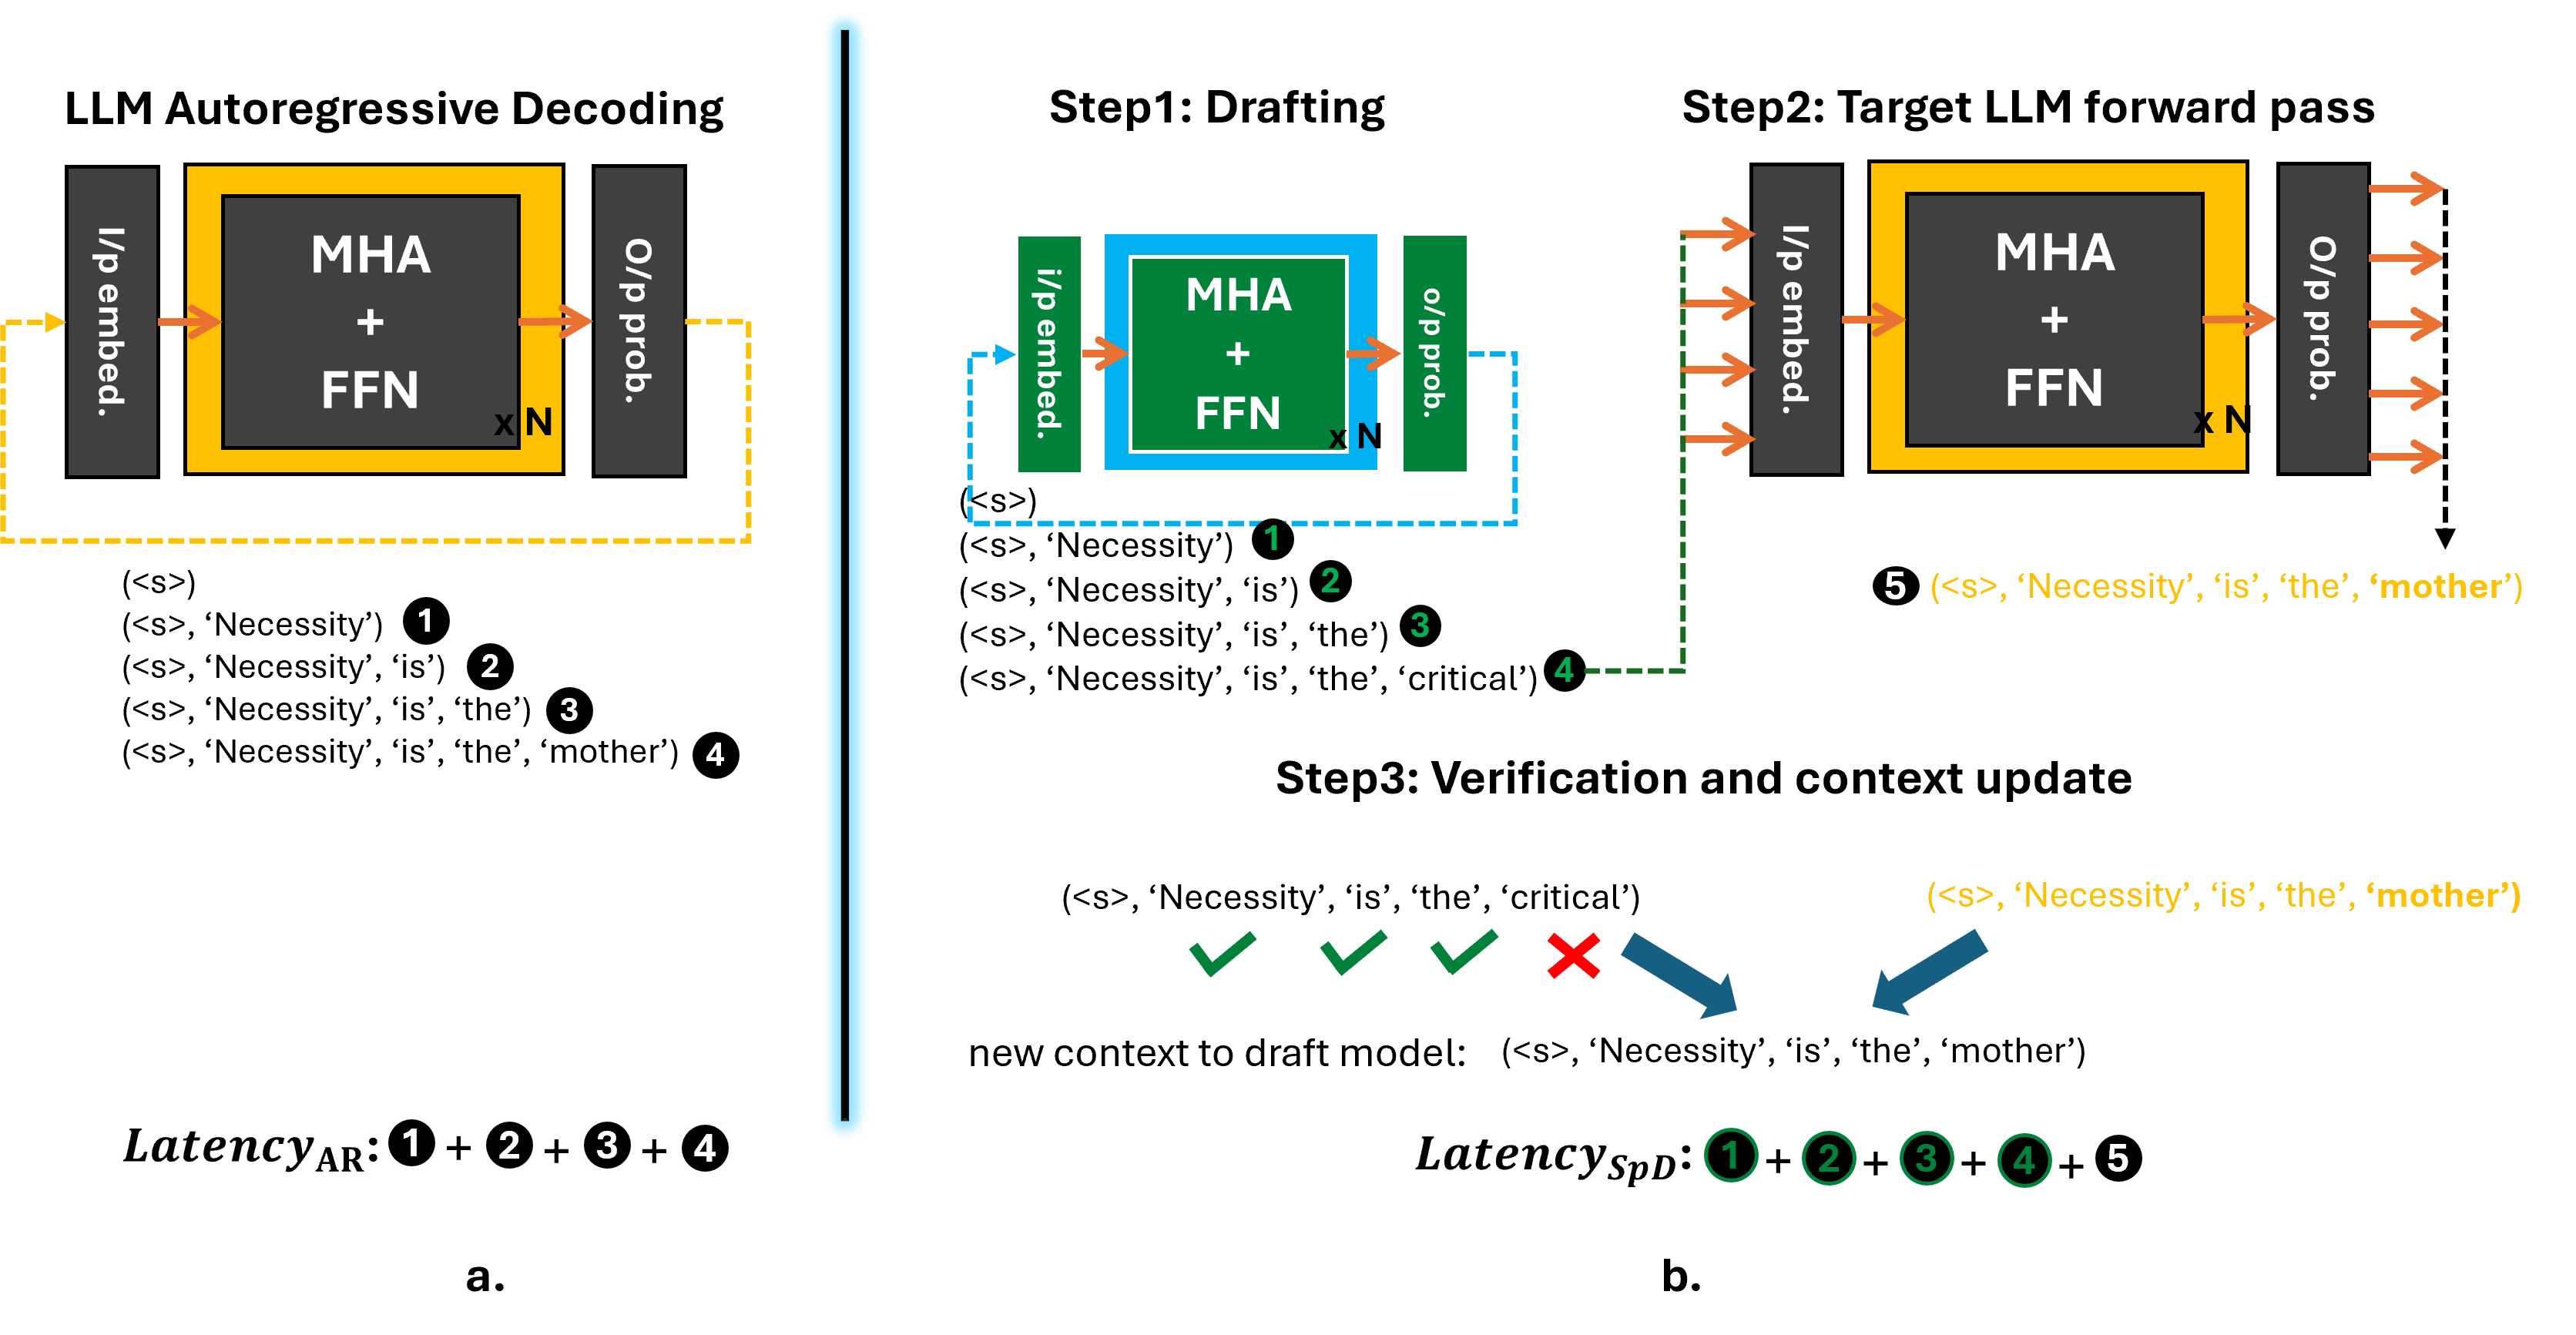
Accelerating LLM Inference: Up to 3x Speedup on MI300X with Speculative ...
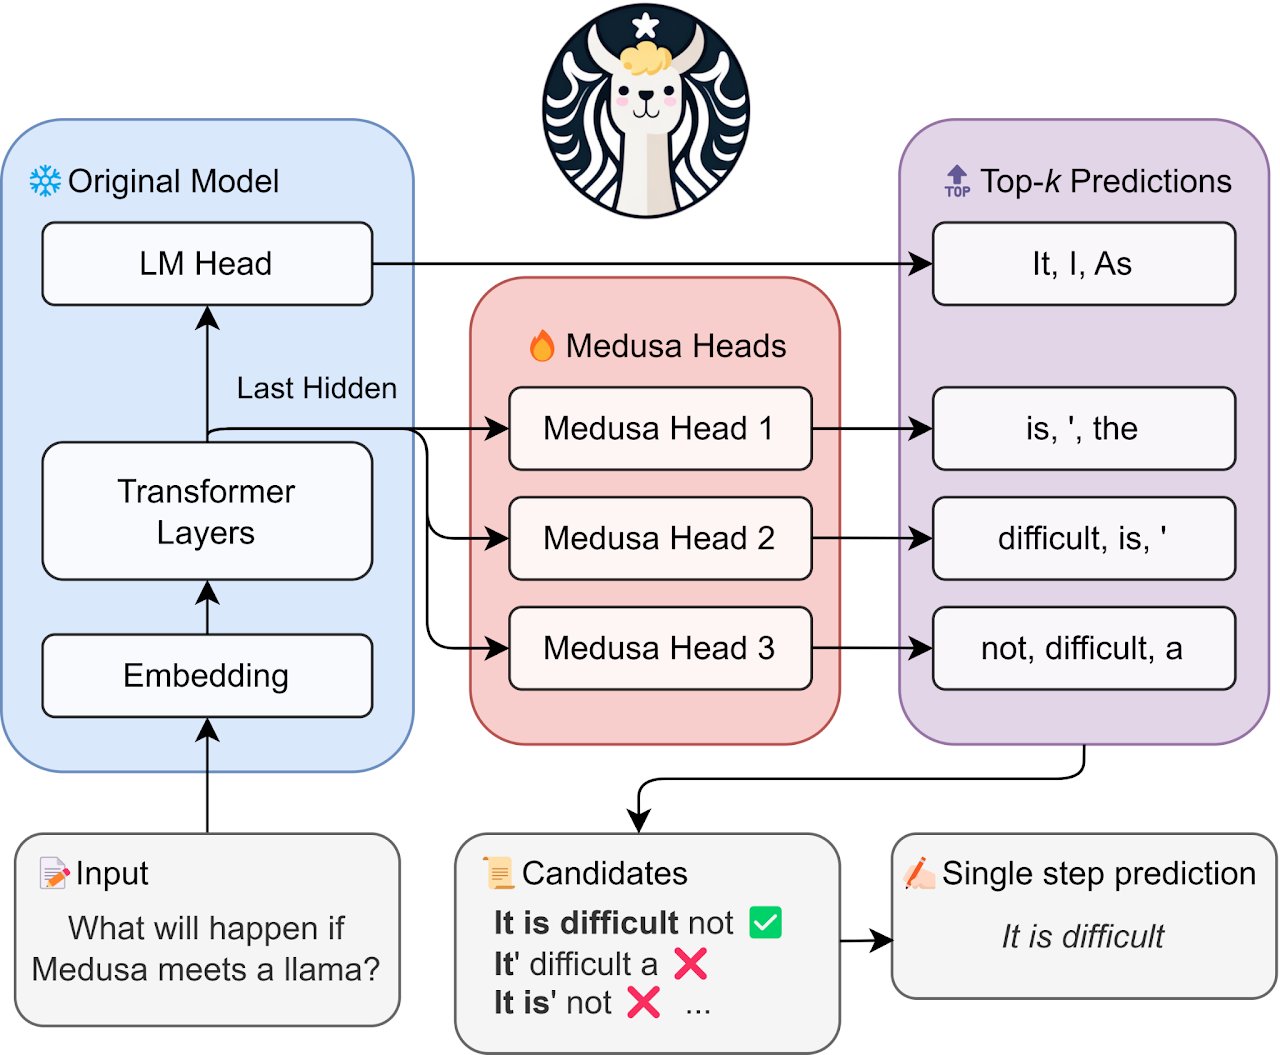
Accelerate LLM Inference with Speculative Decoding | Charles Xu

SpecInfer: Accelerating Generative LLM Serving with Speculative ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...
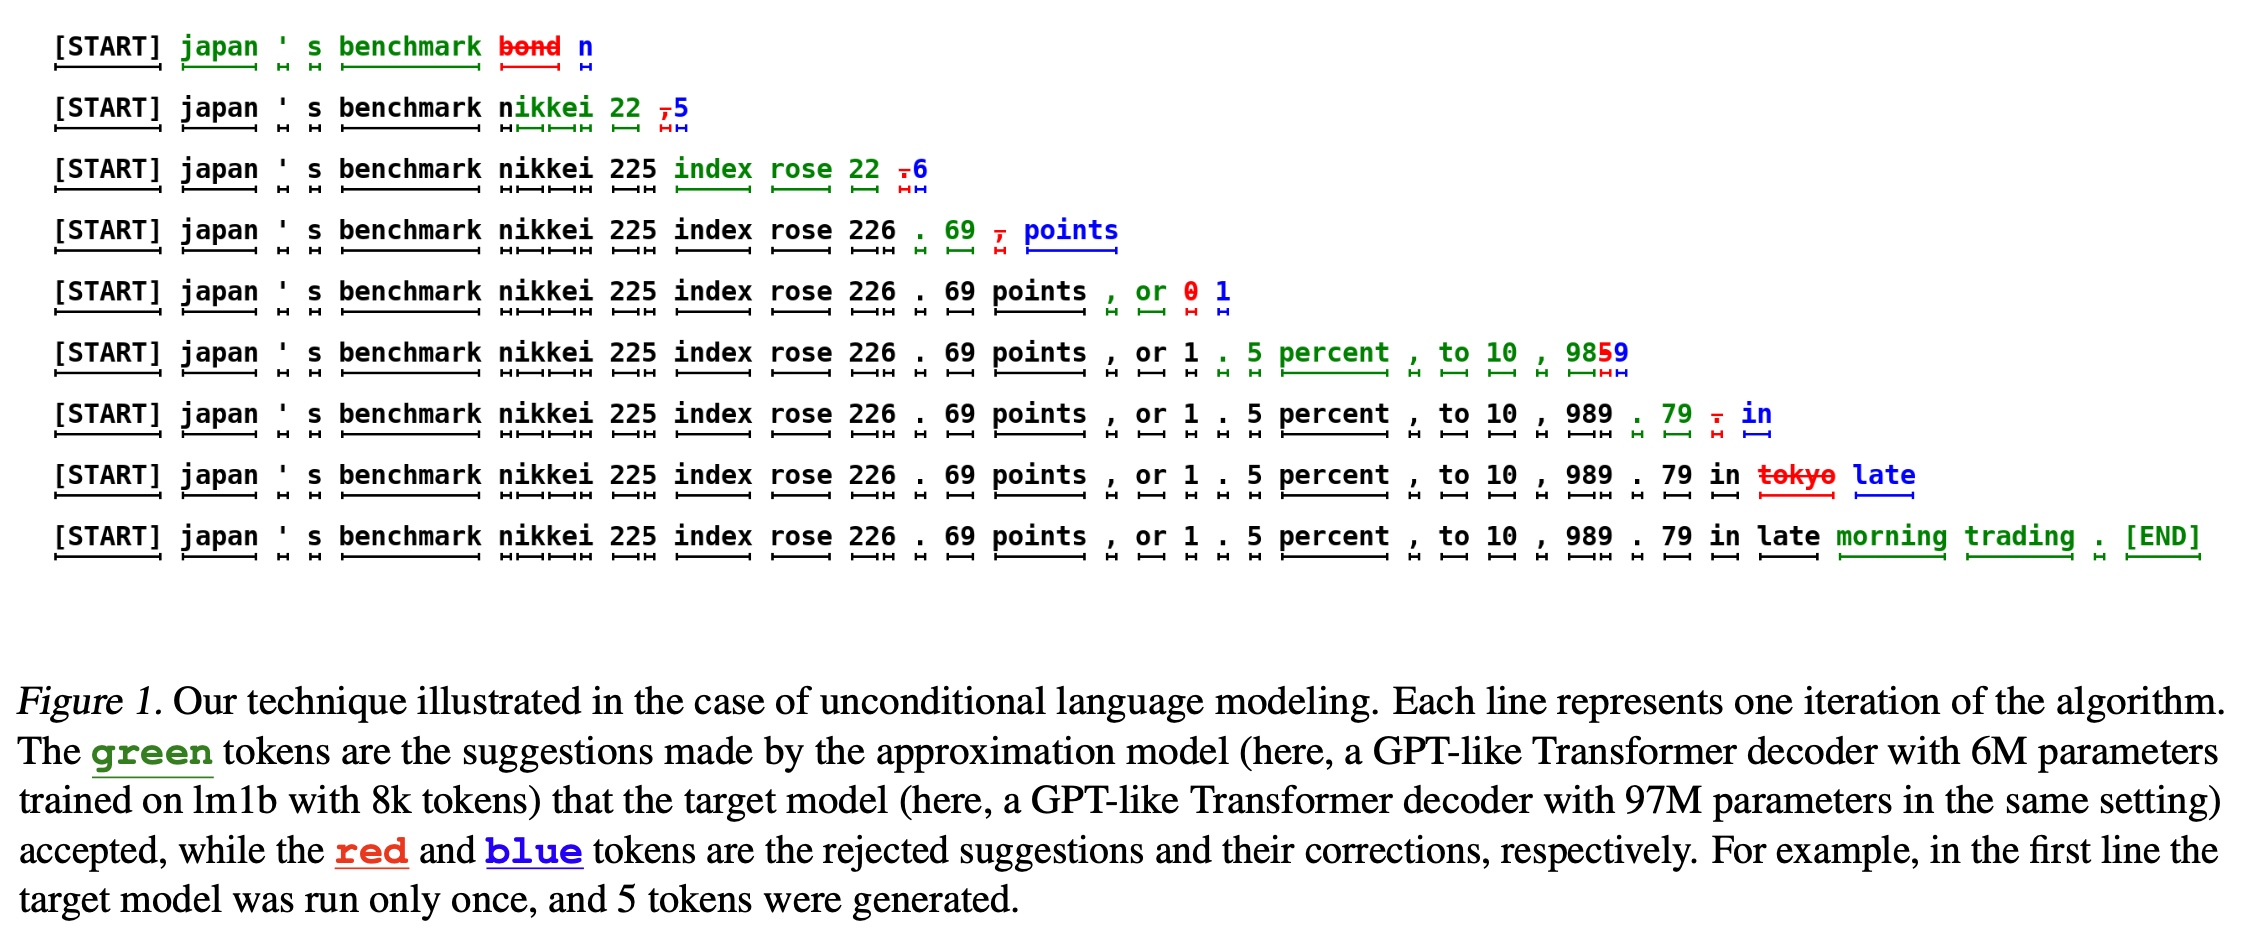
Accelerate LLM Inference with Speculative Decoding | Charles Xu

SpecInfer: Accelerating Generative LLM Serving with Speculative ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...
Advertisement Space (336x280)
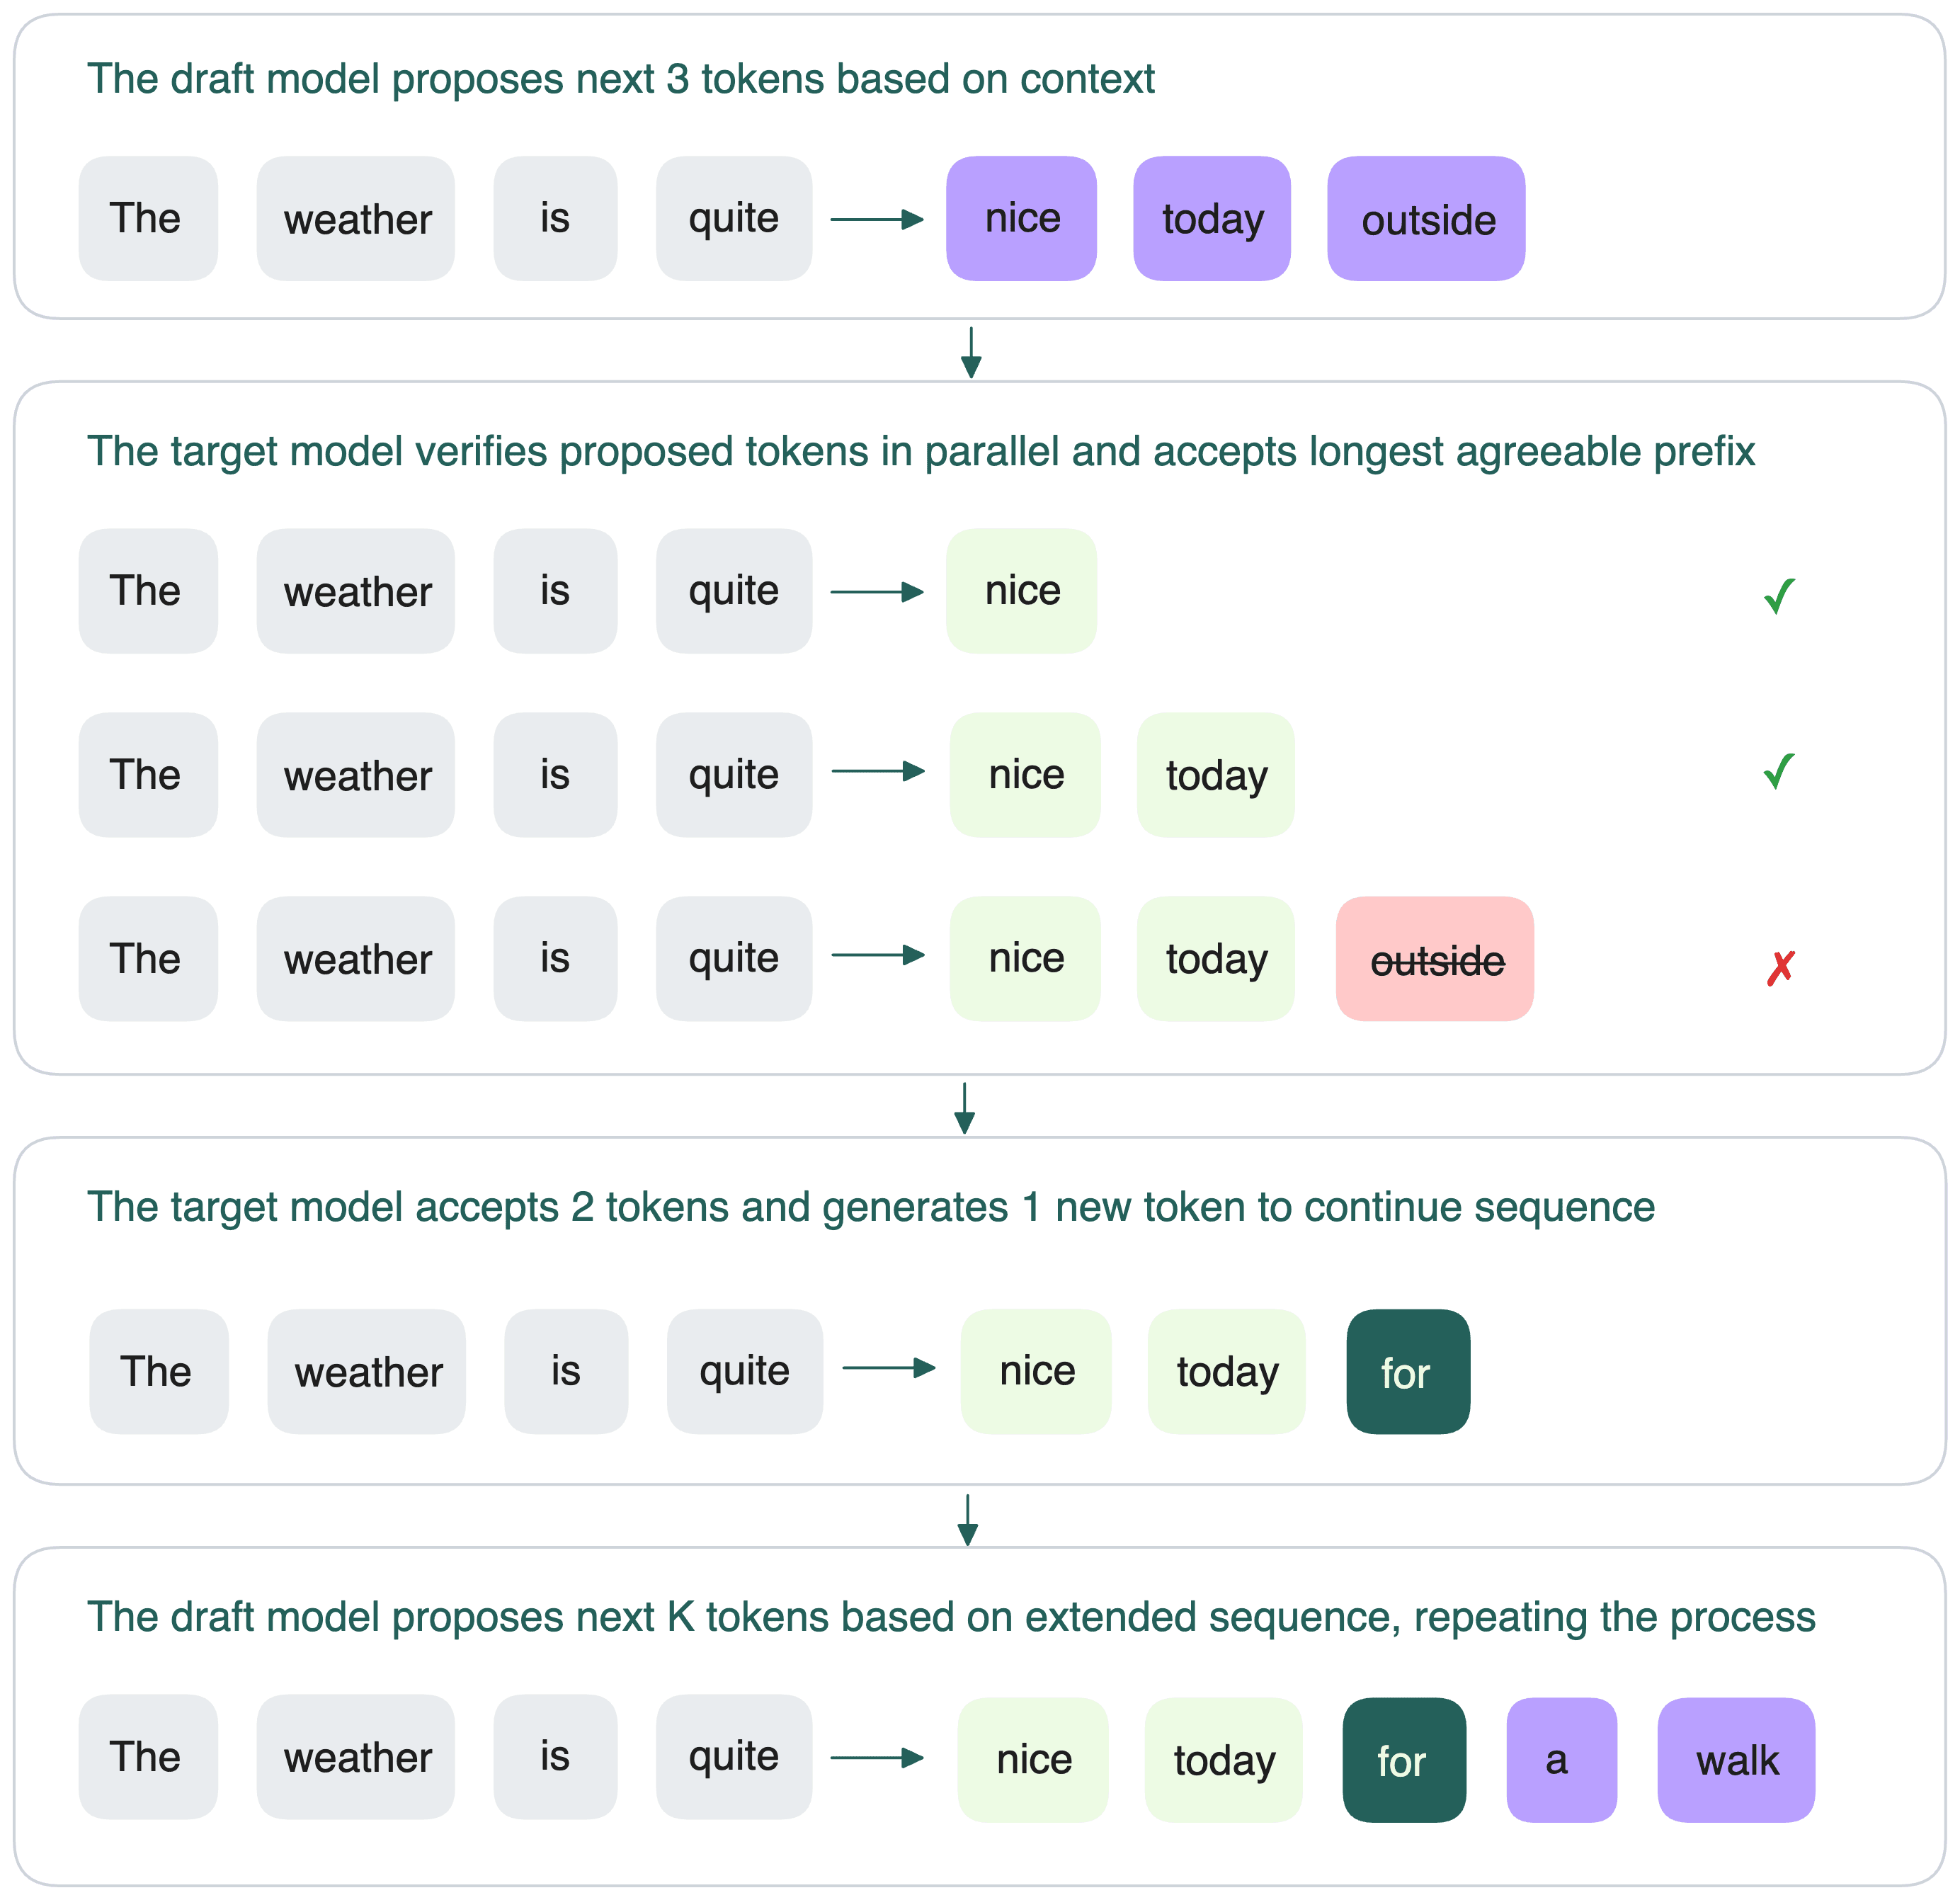
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Speculative Decoding: 3× Faster LLM Inference with Zero Quality Loss ...

Accelerating LLM Inference: Up to 3x Speedup on MI300X with Speculative ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...

(PDF) SpecInfer: Accelerating Generative LLM Serving with Speculative ...
GitHub - ccs96307/fast-llm-inference: Accelerating LLM inference with ...
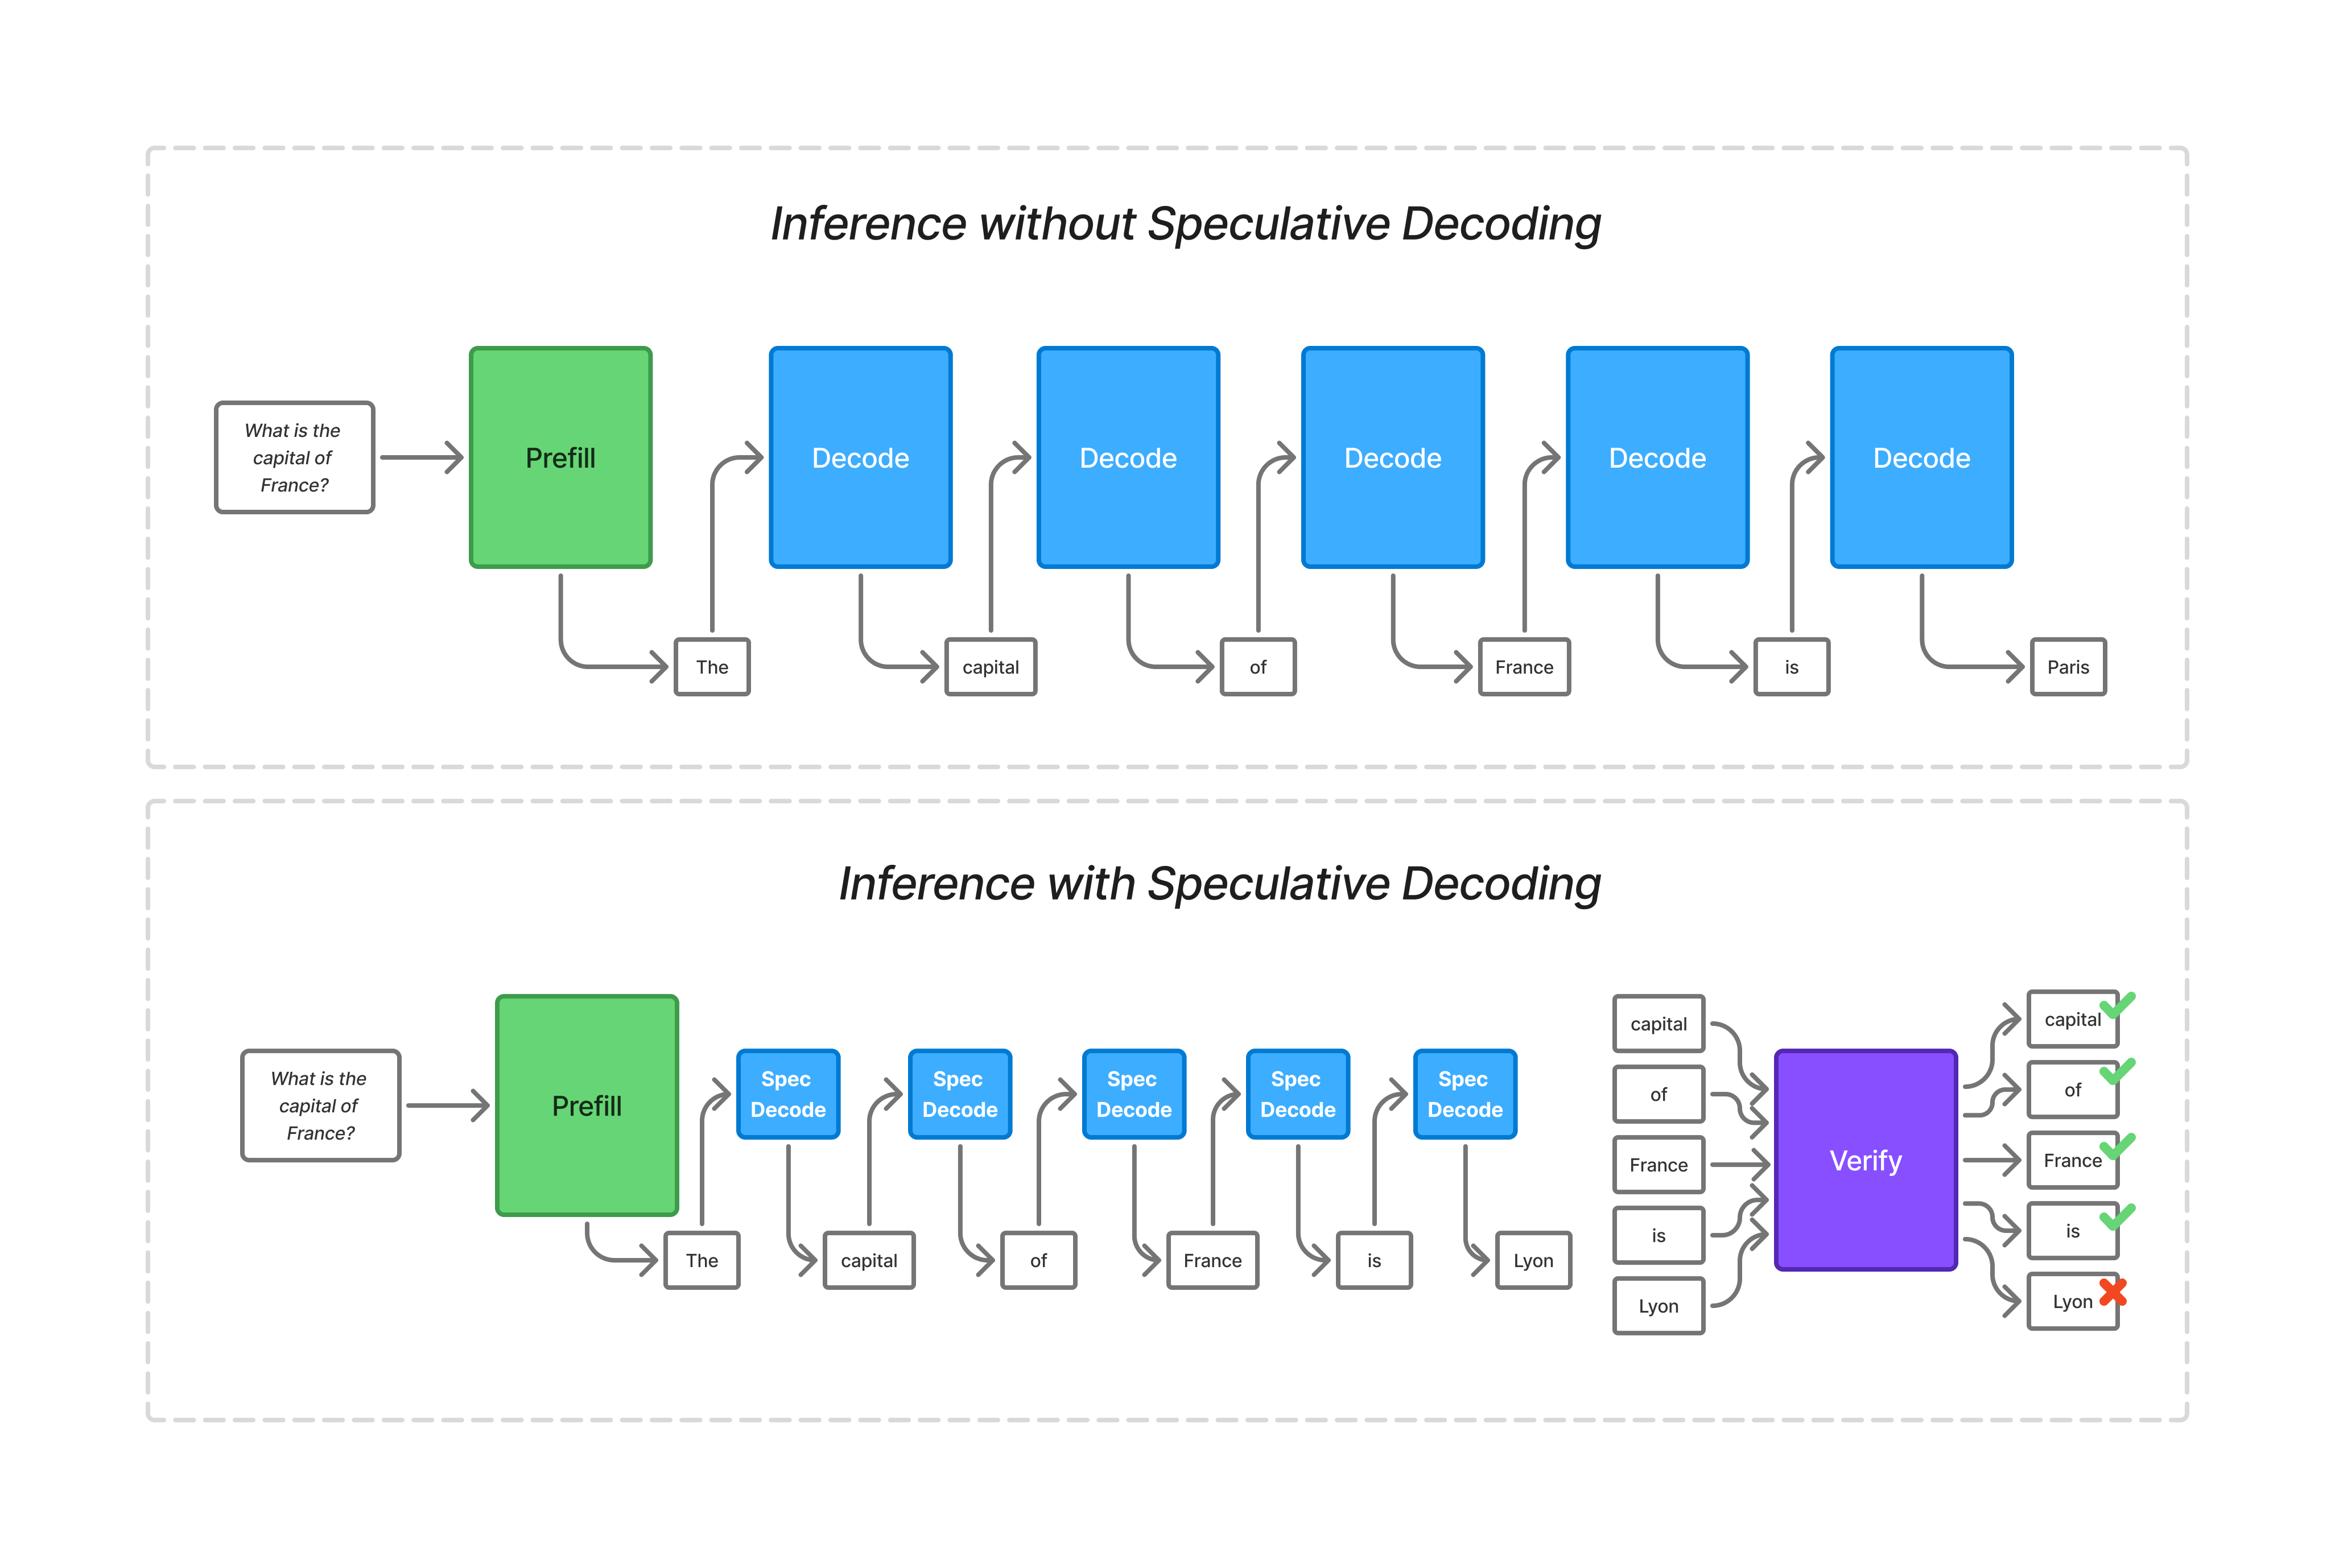
Low-Latency Inference with Speculative Decoding on d-Matrix Corsair and ...
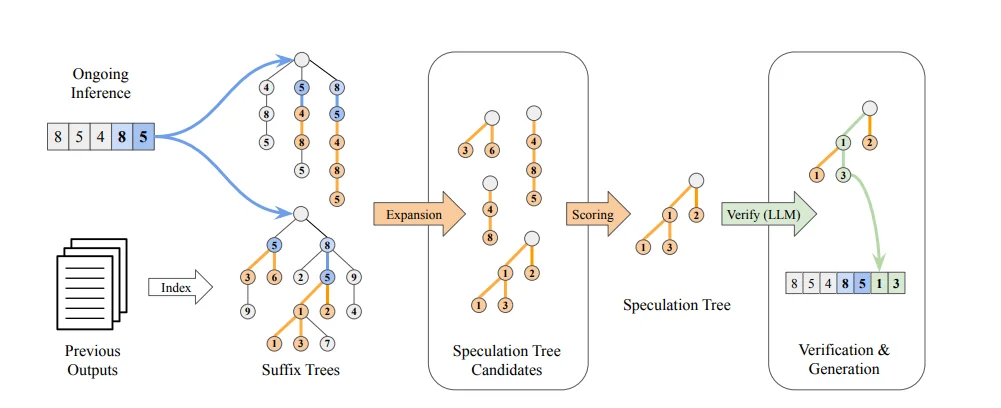
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
Advertisement Space (336x280)
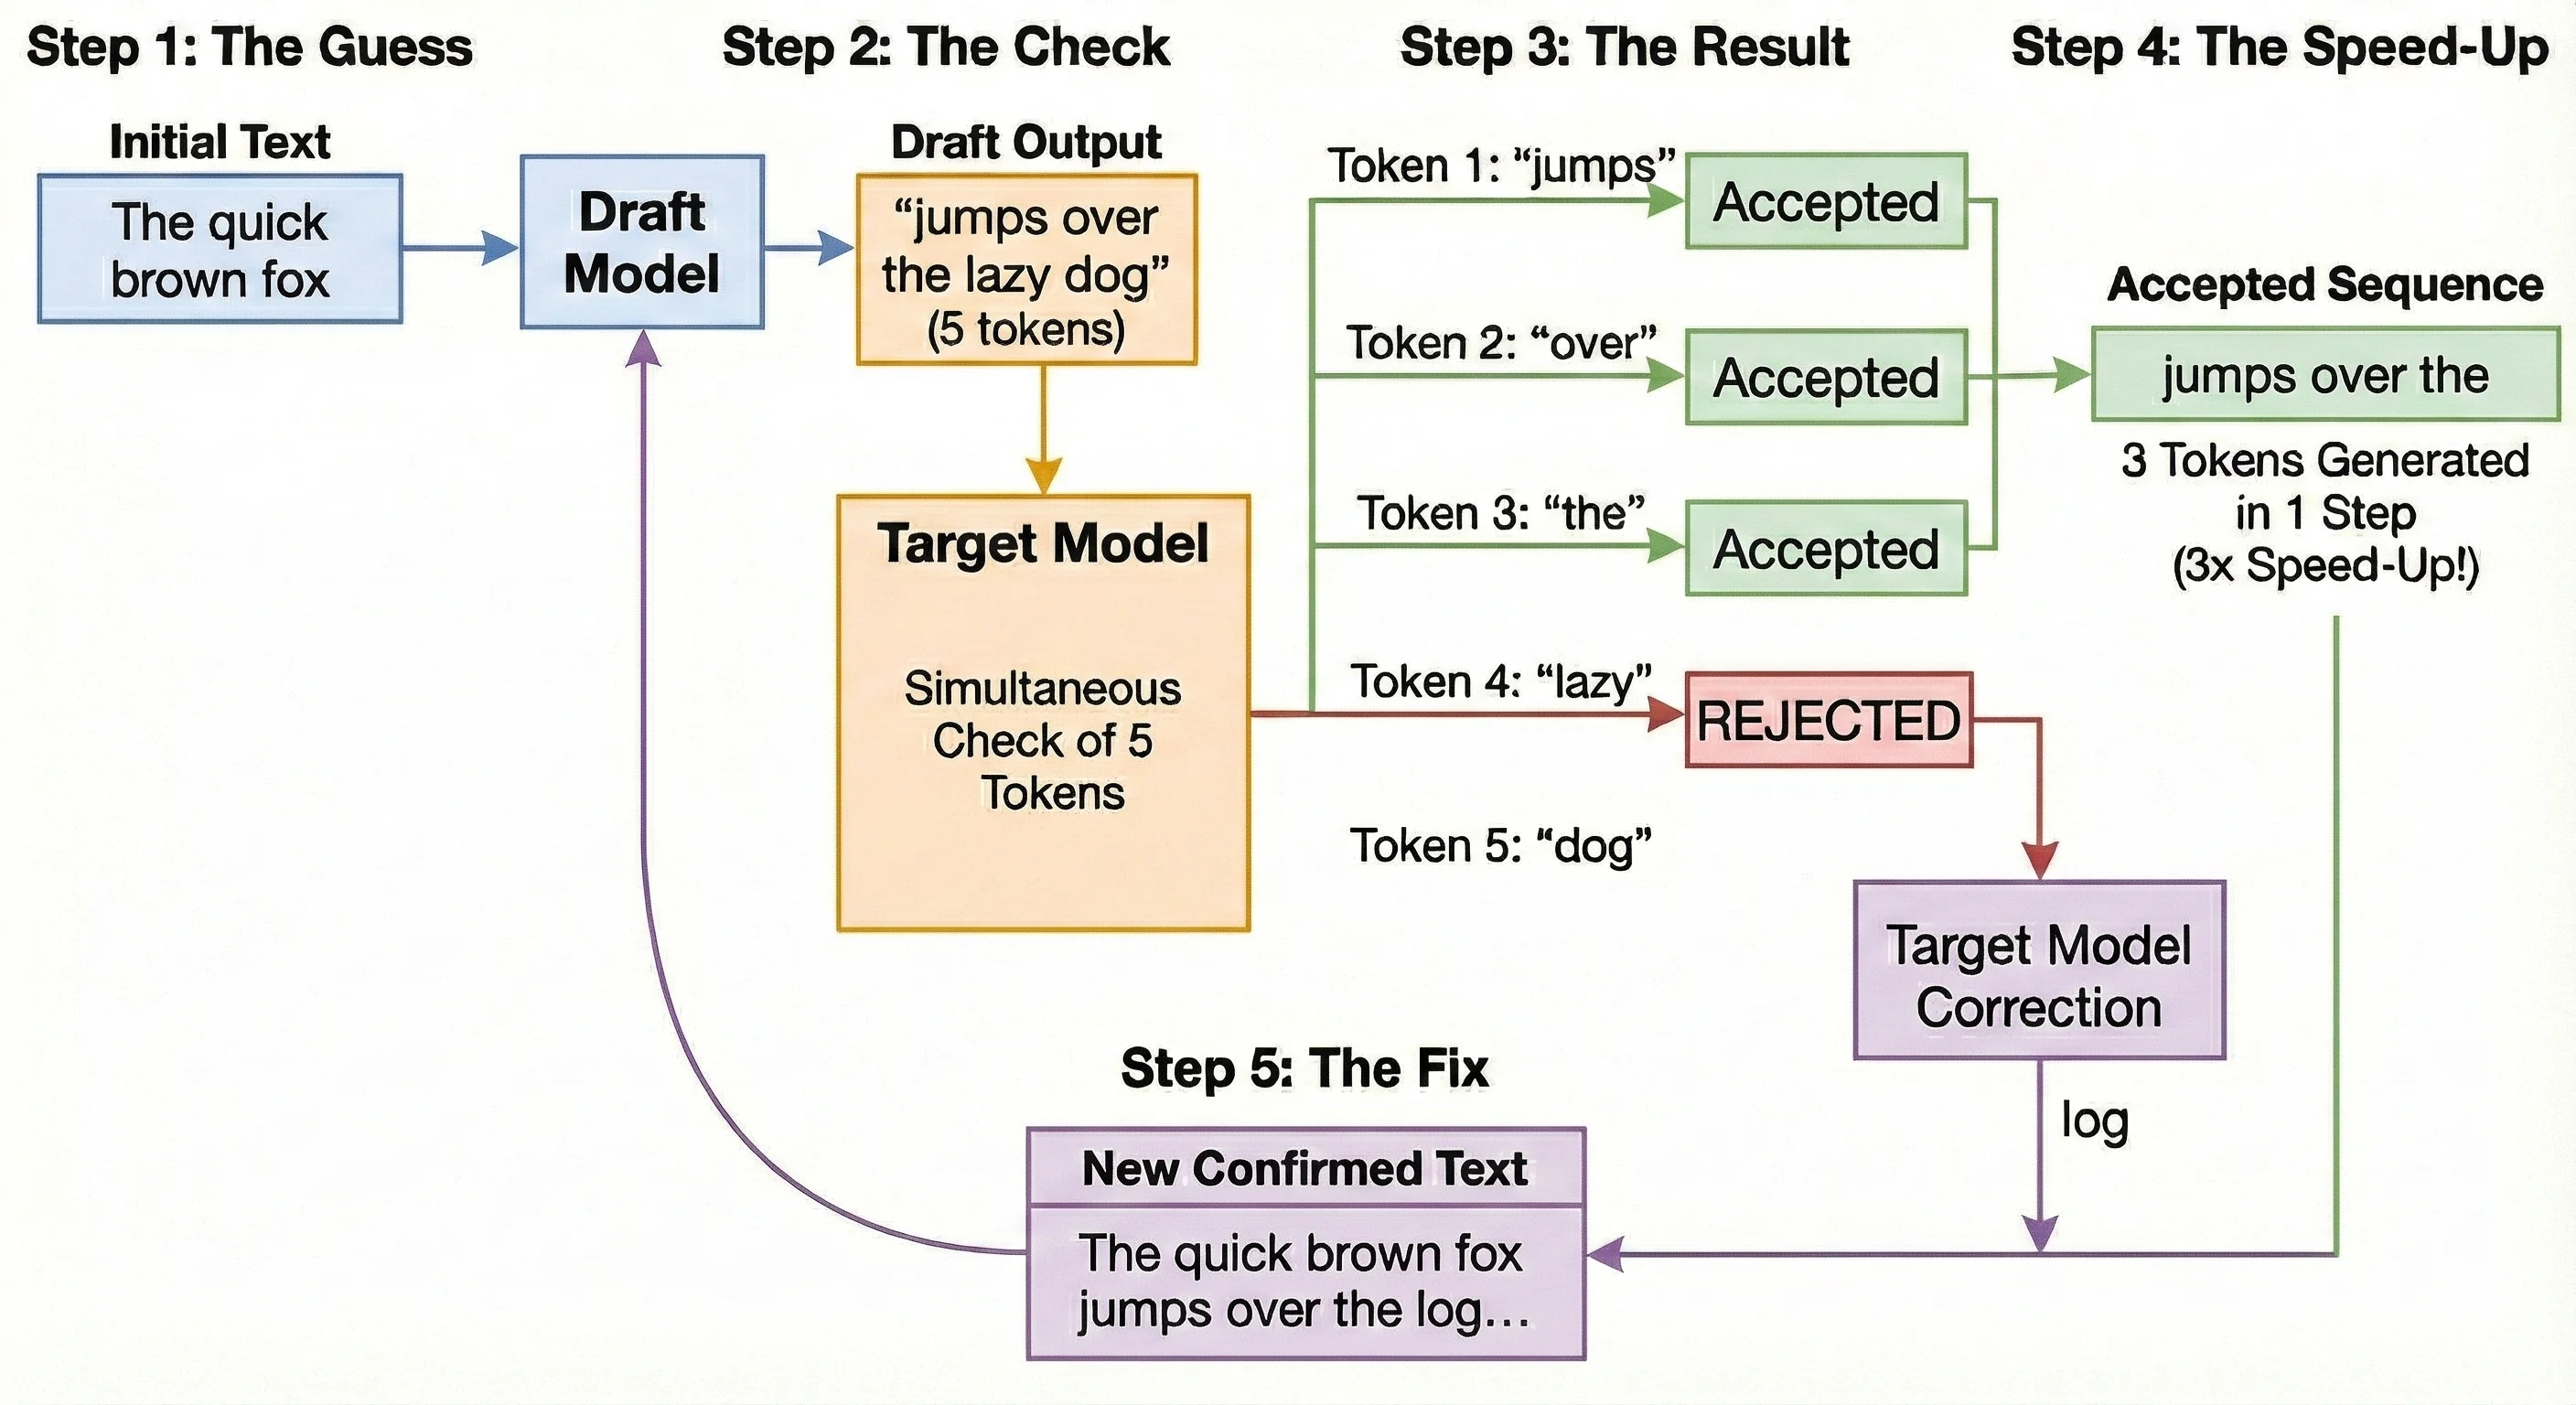
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Accelerating LLM Inference: Decoupling Prefill and Decode (PD ...

SpecInfer: Accelerating Generative LLM Serving with Tree-based ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube

LycheeDecode: Accelerating Long-Context LLM Inference via Hybrid-Head ...
LycheeDecode: Accelerating Long-Context LLM Inference via Hybrid-Head ...