
Unet Tts Improving Unseen Speaker And Style Transfer In One Shot Voice

Unet-TTS: Improving Unseen Speaker and Style Transfer in One-shot Voice ...
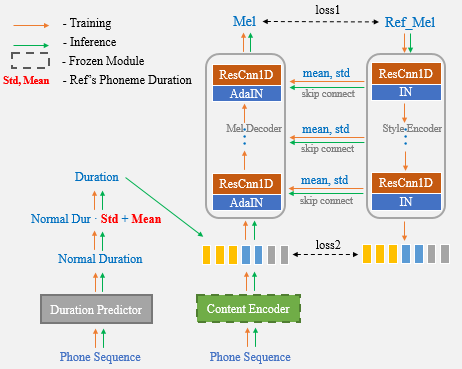
Unet-TTS: Improving Unseen Speaker and Style Transfer in One-shot Voice ...

(PDF) Improving Performance of Seen and Unseen Speech Style Transfer in ...

Improving Performance of Seen and Unseen Speech Style Transfer in End ...
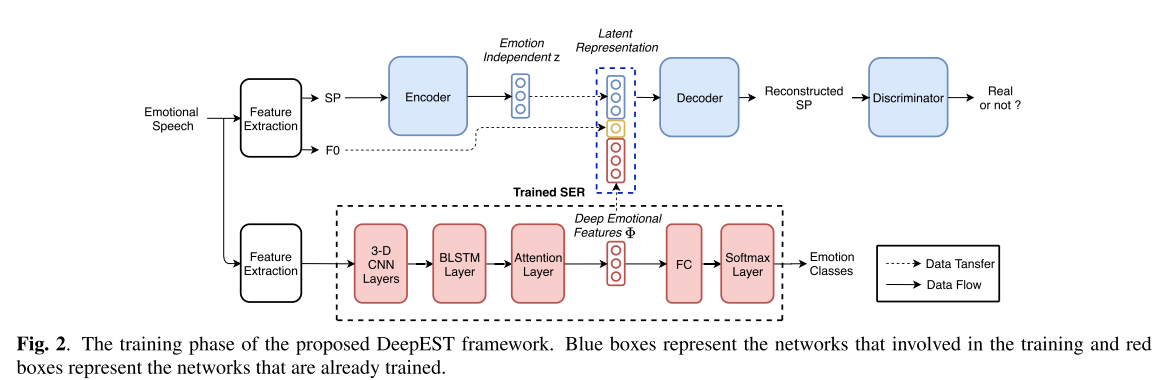
[文献阅读] Seen and Unseen emotional style transfer for voice conversion ...
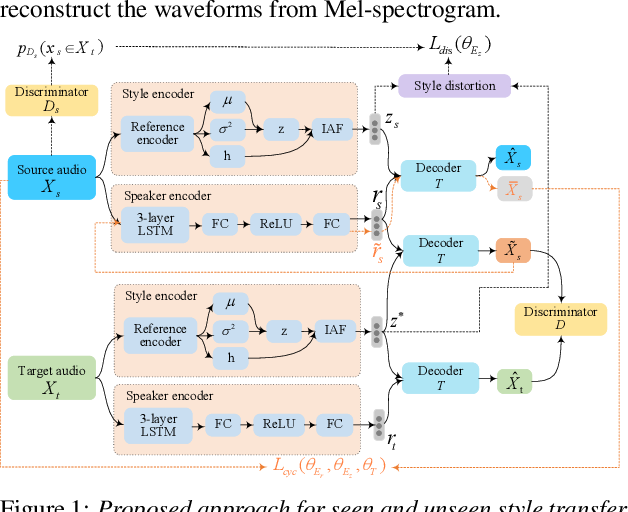
Figure 1 from Improving Performance of Seen and Unseen Speech Style ...

One-Shot Voice Conversion For Style Transfer Based On Speaker ...

(PDF) Transfer Learning, Style Control, and Speaker Reconstruction Loss ...

Transfer Learning Style Control and Speaker Reconstruction Loss For ...

Improving Data Augmentation-based Cross-Speaker Style Transfer for TTS ...
Advertisement Space (300x250)

[2103.09420] Improving Zero-Shot Voice Style Transfer via Disentangled ...

StyleTTS-VC: One-Shot Voice Conversion by Knowledge Transfer from Style ...
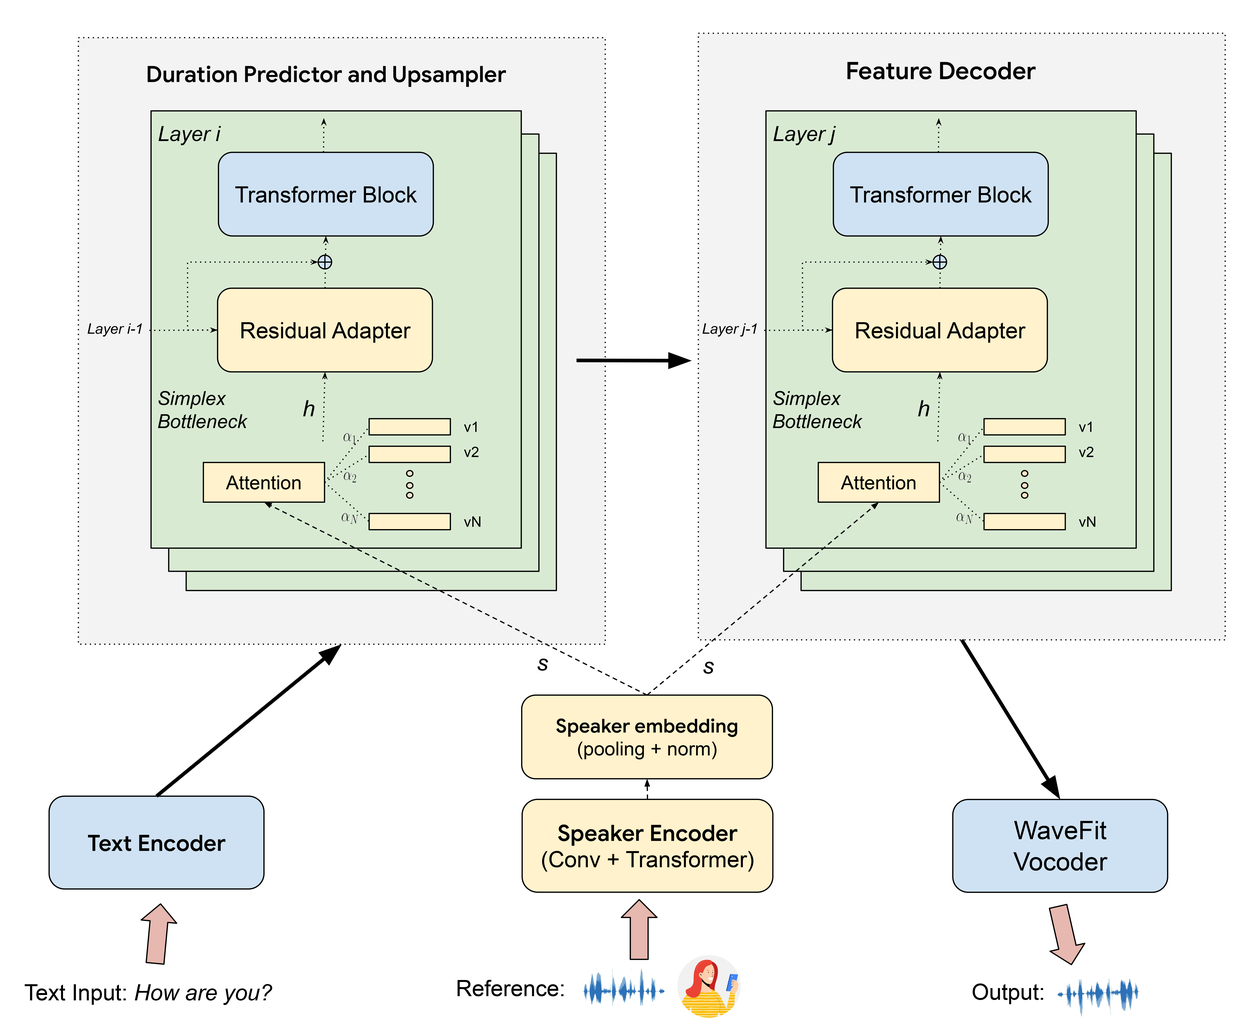
Restoring speaker voices with zero-shot cross-lingual voice transfer ...

Exploring synthetic data for cross-speaker style transfer in style ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
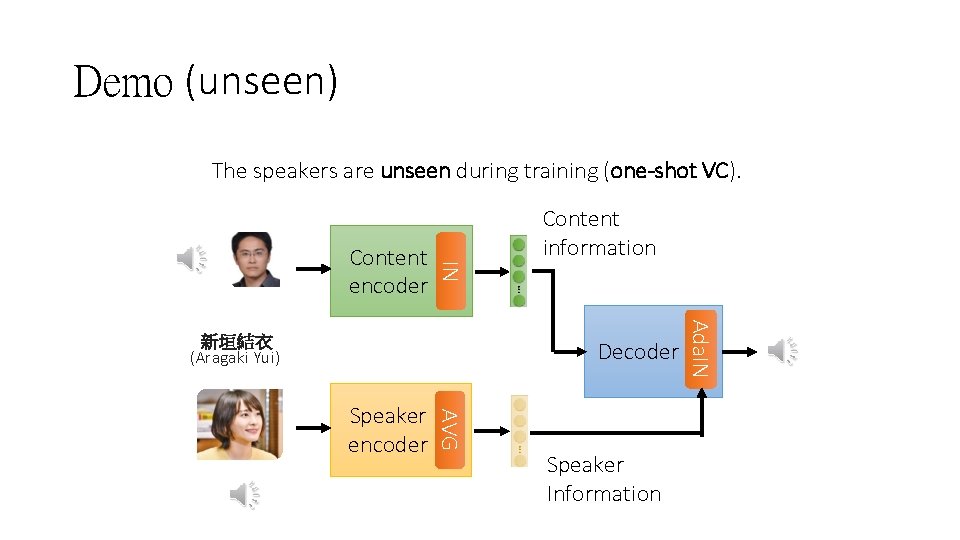
Oneshot Voice Conversion by Separating Speaker and Content

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
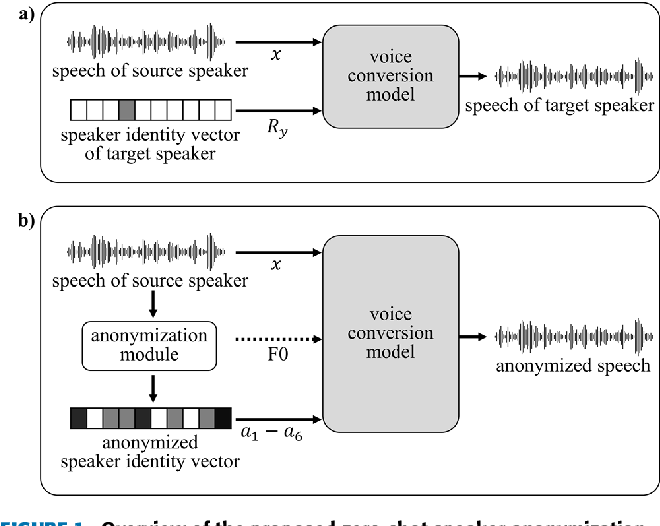
Figure 1 from Zero-Shot Unseen Speaker Anonymization via Voice ...

[2111.12277] One-shot voice conversion for style transfer based on ...

[논문 리뷰] Exploring synthetic data for cross-speaker style transfer in ...
Advertisement Space (336x280)

Exploring synthetic data for cross-speaker style transfer in style ...

StyleTTS-VC: One-Shot Voice Conversion by Knowledge Transfer from Style ...
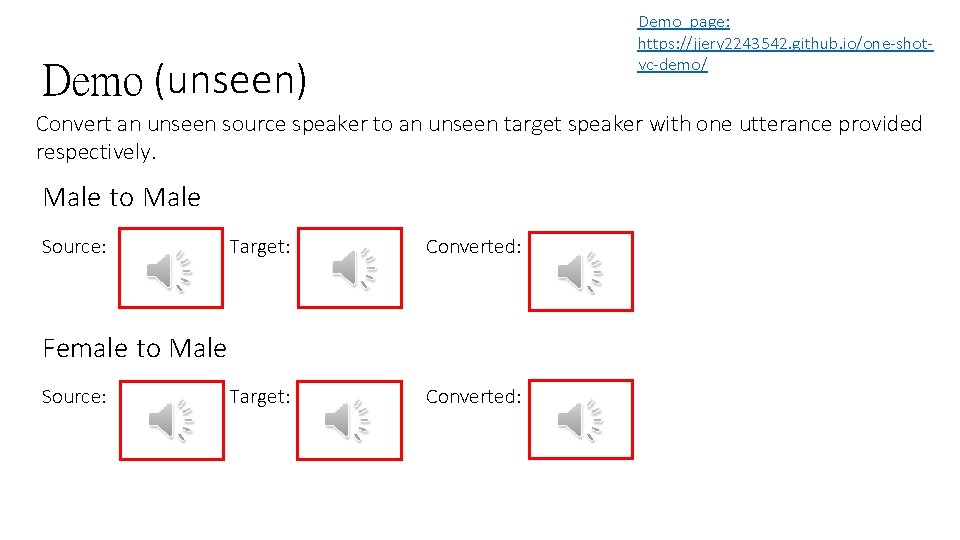
Oneshot Voice Conversion by Separating Speaker and Content

[2111.12277] One-shot voice conversion for style transfer based on ...
GitHub - CMsmartvoice/One-Shot-Voice-Cloning: :relaxed: One Shot Voice ...
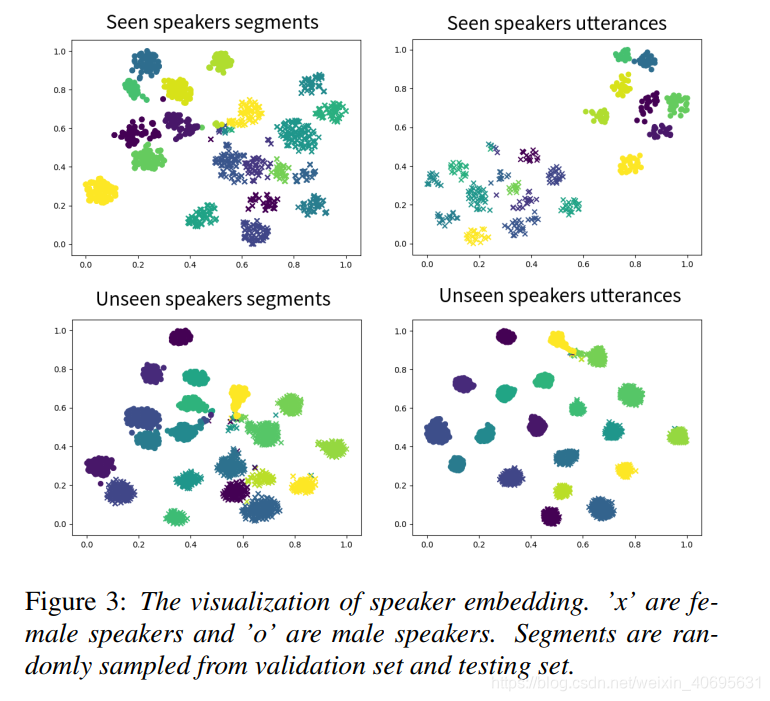
《One-shot Voice Conversion by Separating Speaker and Content ...
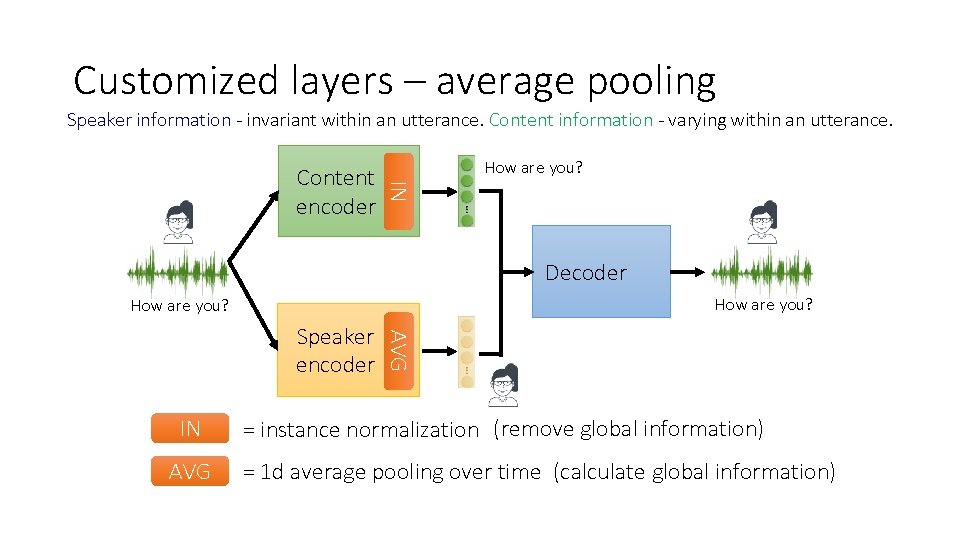
Oneshot Voice Conversion by Separating Speaker and Content

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

D-vector Visualisation for both Seen and Unseen Speakers in both Native ...
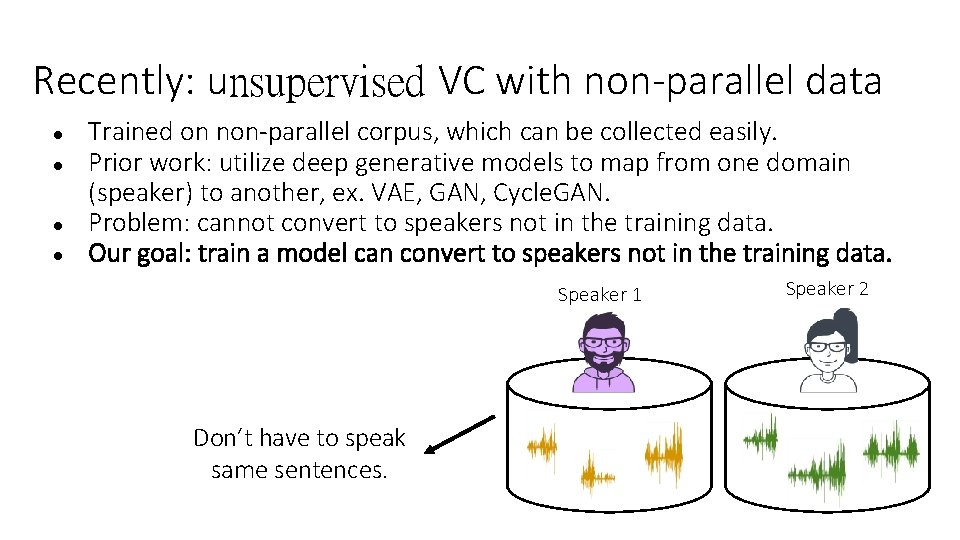
Oneshot Voice Conversion by Separating Speaker and Content
Advertisement Space (336x280)
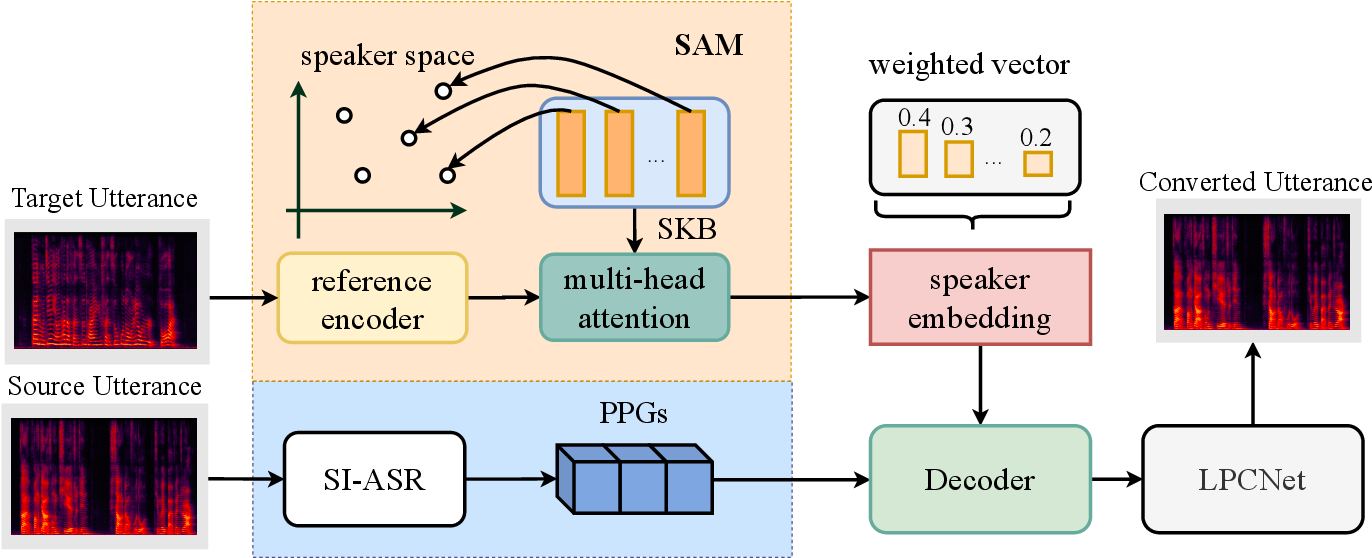
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

VQVC+: One-Shot Voice Conversion by Vector Quantization and U-Net ...

VQVC+: One-Shot Voice Conversion by Vector Quantization and U-Net ...
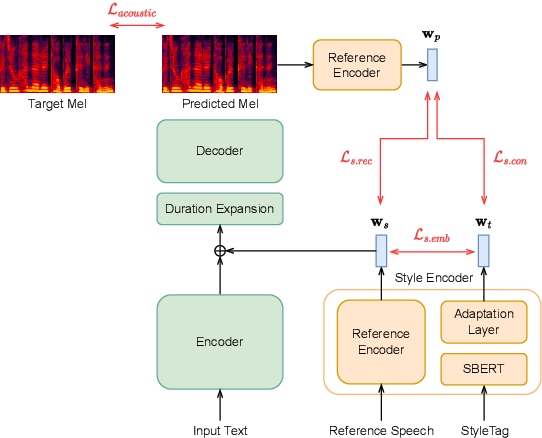
Figure 1 from Text-driven Emotional Style Control and Cross-speaker ...
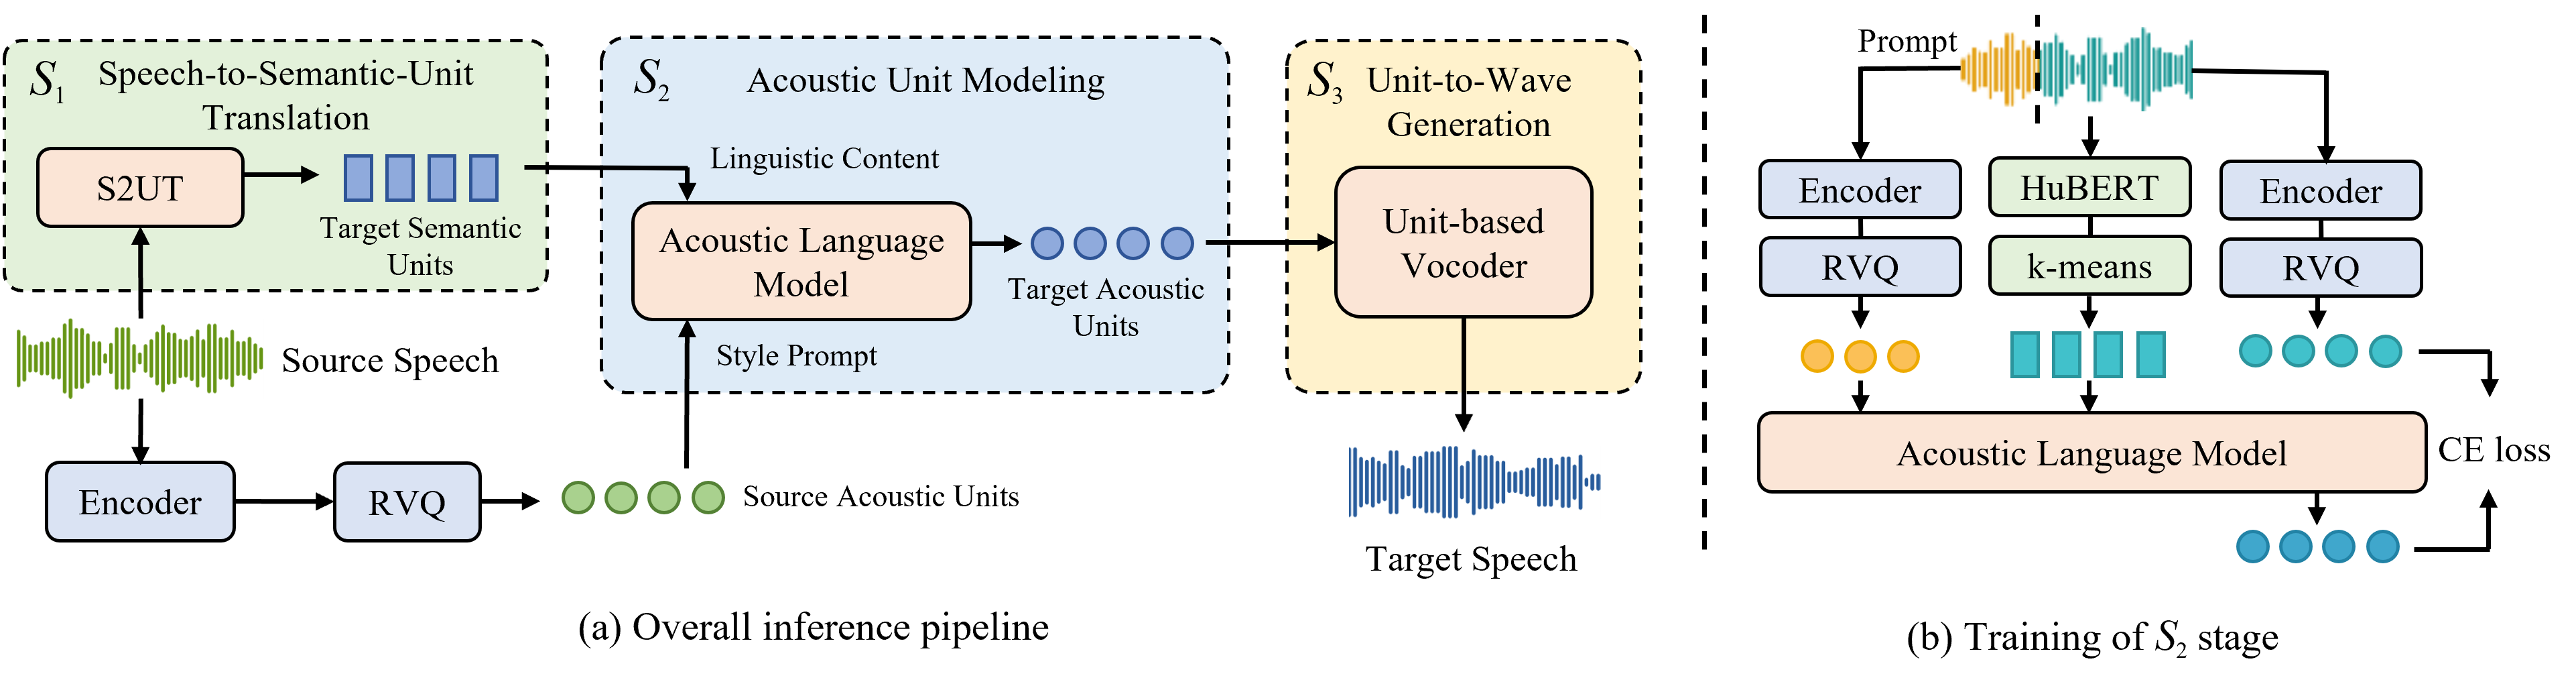
Speech-to-Speech Translation with Discrete-Unit-Based Style Transfer

VQVC+: One-Shot Voice Conversion by Vector Quantization and U-Net ...