
Usage Does Vllm Support Mix Deploy On Gpucpu Issue 13517 Vllm
[Usage]: Does vllm support mix deploy on GPU+CPU? · Issue #13517 · vllm ...
[Usage]: Does vLLM support multi-task · Issue #13390 · vllm-project ...
Does vllm support both CUDA 11.3 version and PyTorch 1.12? · Issue ...
[Usage]: How to start vLLM on a particular GPU? · Issue #4981 · vllm ...
[Feature]: Does vLLM plan to support host multiple llm base models ...
vLLM Recipes: Deploy Any Model on Any GPU | Luca Berton
Does vllm support CPU? · vllm-project vllm · Discussion #999 · GitHub
[Bug]: Multi-GPU Support for Quantized Models in vLLM · Issue #13297 ...
How to deploy vllm model across multiple nodes in kubernetes? · Issue ...

Deploy vLLM with Docker on Runpod: Container Config, Model Loading, and ...
Advertisement Space (300x250)
[Installation]: VLLM does not support TPU v5p-16 (Multi-Host) with Ray ...
Unable to specify GPU usage in VLLM code · Issue #3012 · vllm-project ...
[Bug]: vllm doesn't support multi-instance GPU · Issue #6551 · vllm ...

Deploy LLMs with vLLM on NVIDIA Jetson AGX Orin Dev Kit - Hackster.io
[Installation]: How to install vllm on an M40 GPU? · Issue #15751 ...
[Feature]: is vllm support sequence-parallel? · Issue #3940 · vllm ...
[Performance]: Vllm performance on L40s GPU · Issue #5007 · vllm ...
Example: Autoscaling vLLM with KEDA based on GPU KV Cache Usage ...

Deploy open LLMs with vLLM on Hugging Face Inference Endpoints
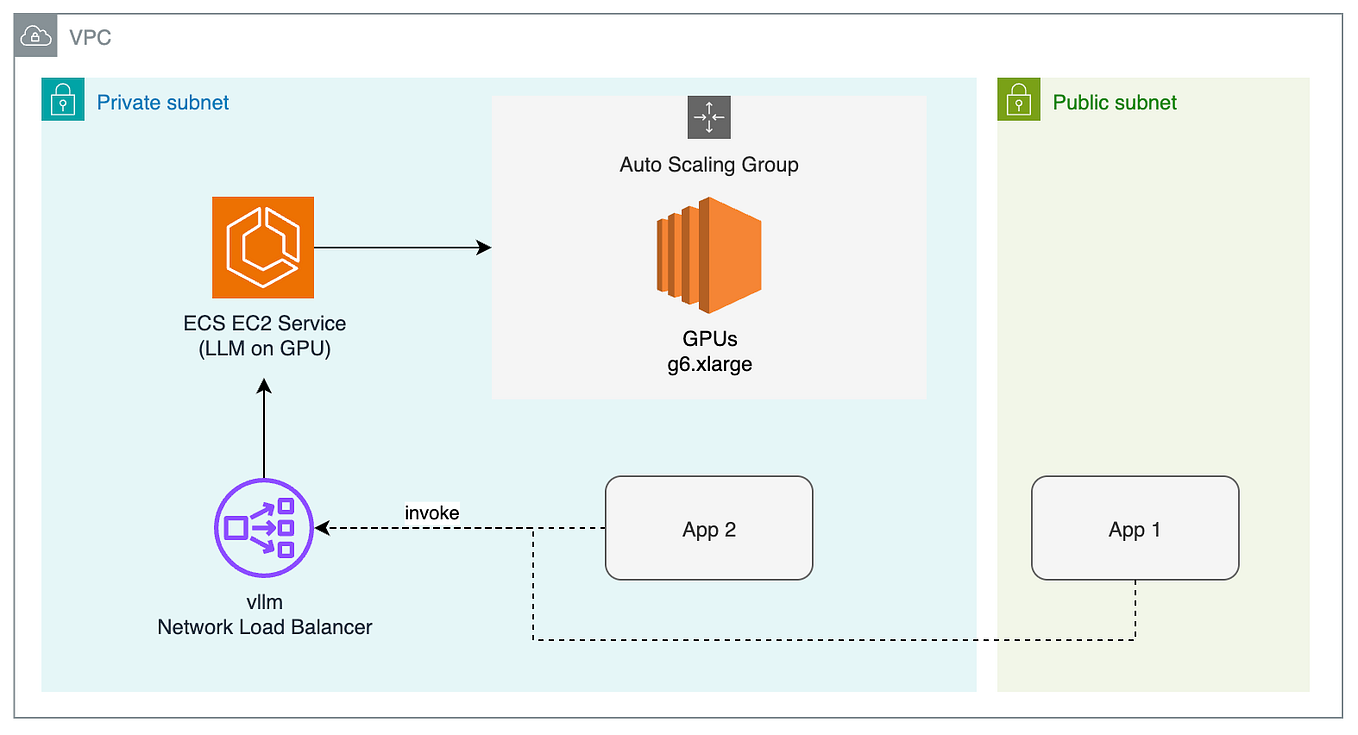
Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...
Advertisement Space (336x280)
vLLM Model Runner V2 on GPU Cloud: Deploy MRV2 for Faster LLM Inference ...
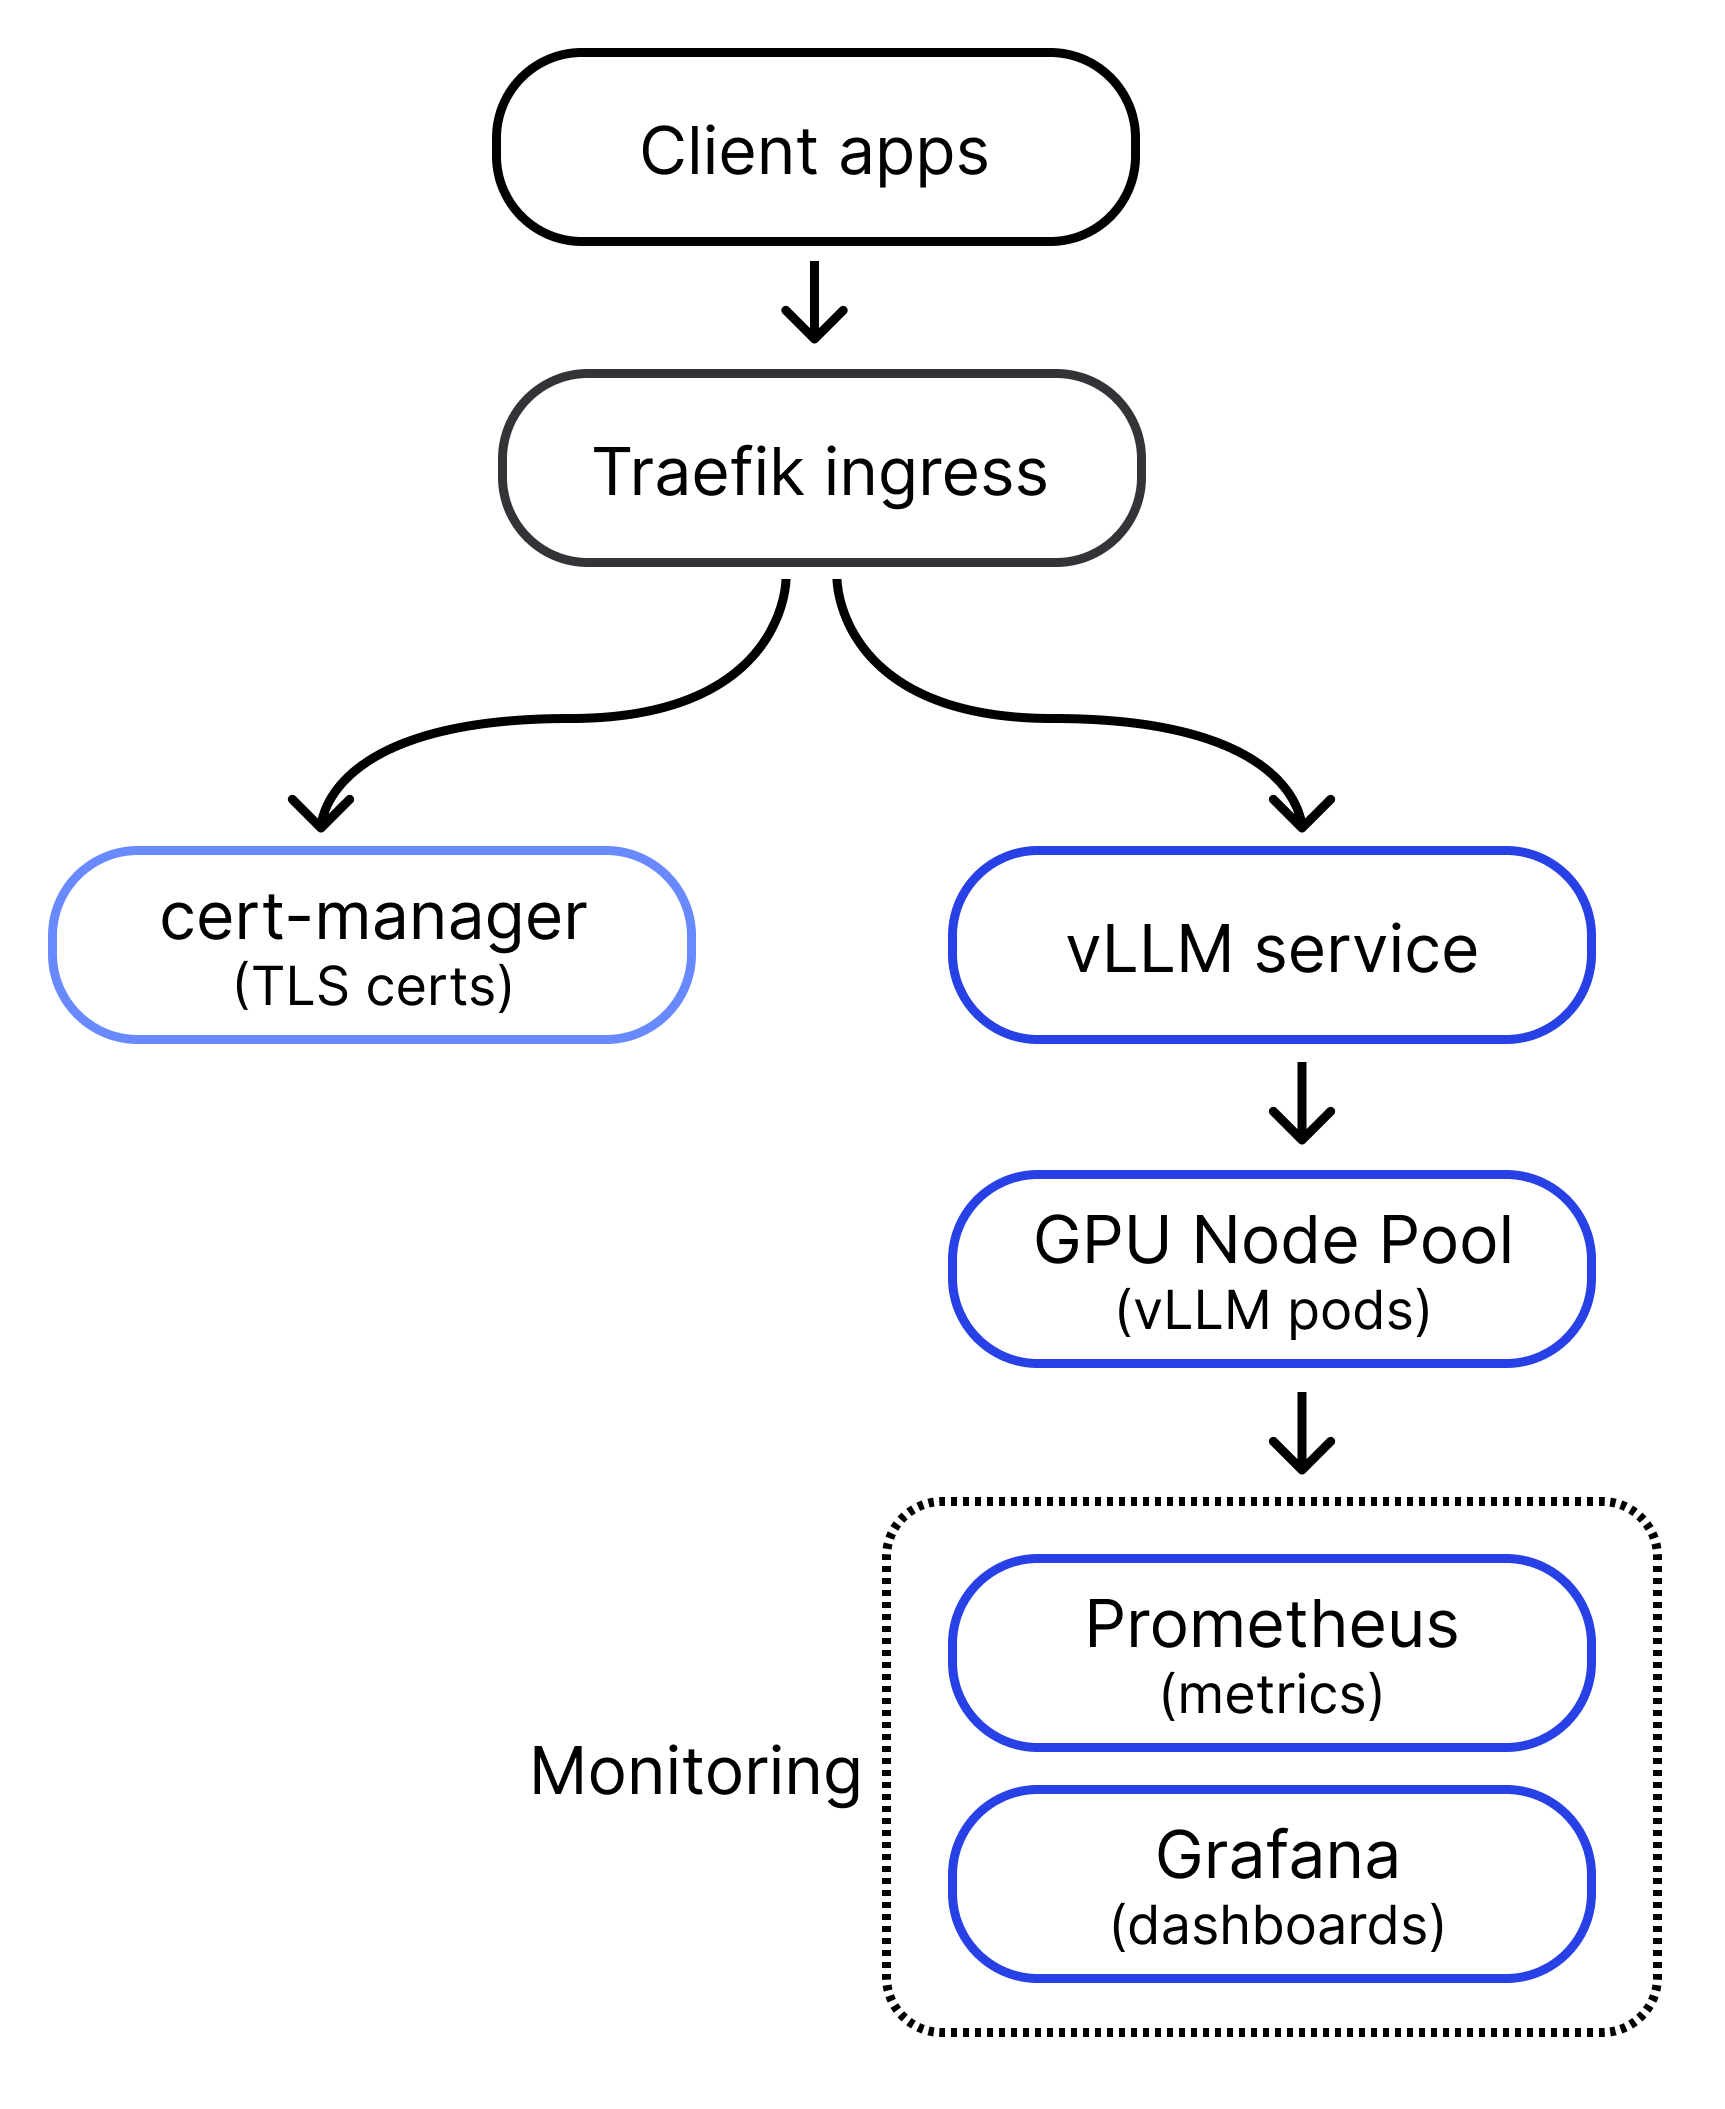
Deploy vLLM for inference - CoreWeave Docs
[Usage]: How to release GPU of vLLM model in python code · Issue #6544 ...
Request for GLM-5.1 + AMD MI300X vLLM deployment recipe · Issue #333 ...
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
vLLM model serving server hangs when GPU KV cache usage reaches 10% ...
[Usage]: vllm server mode, gpu util · Issue #6131 · vllm-project/vllm ...

How to deploy vLLM
How to Deploy vLLM with ArgoCD
Advertisement Space (336x280)

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
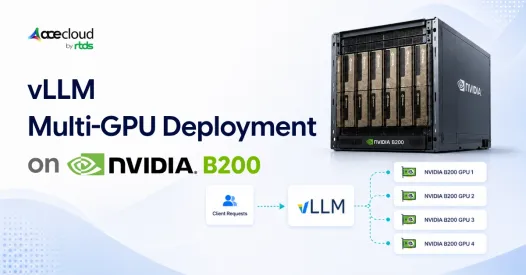
VLLM Multi-GPU Deployment On NVIDIA B200
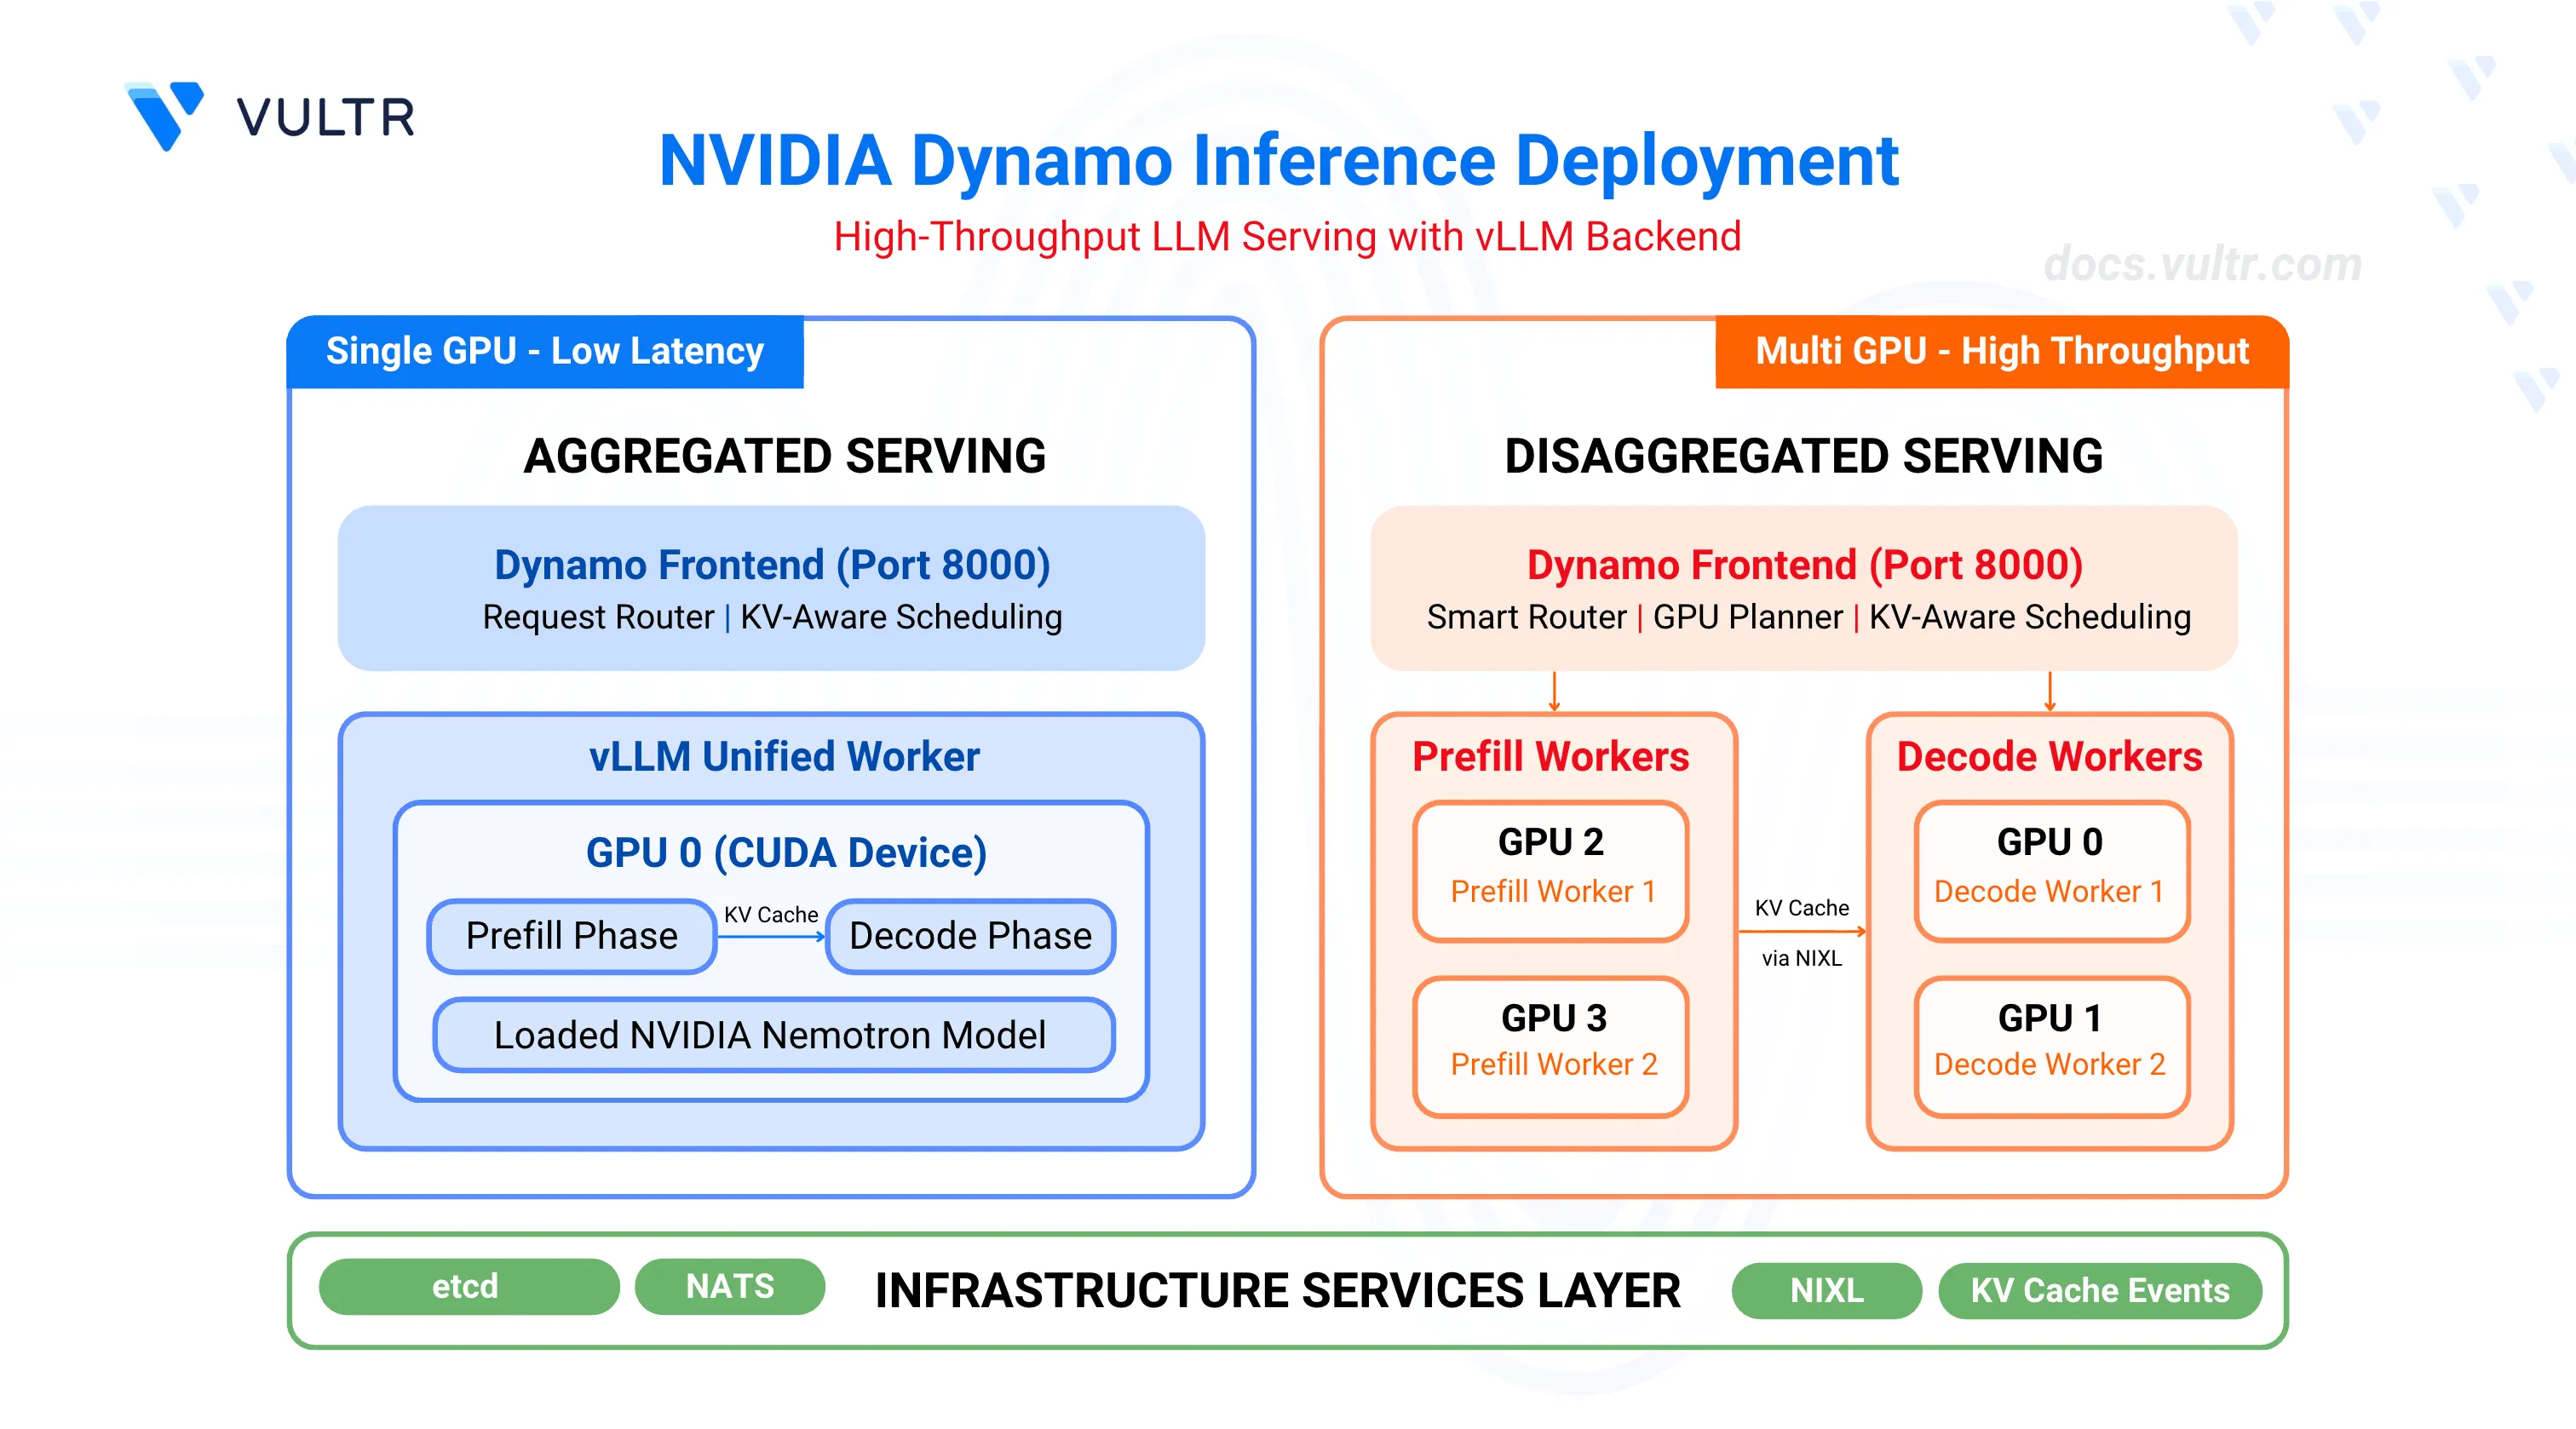
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs
[Bug]: Multi GPU setup for VLLM in Openshift still does not work ...
How to Deploy vLLM in Production with Docker (2026) | Yotta Labs
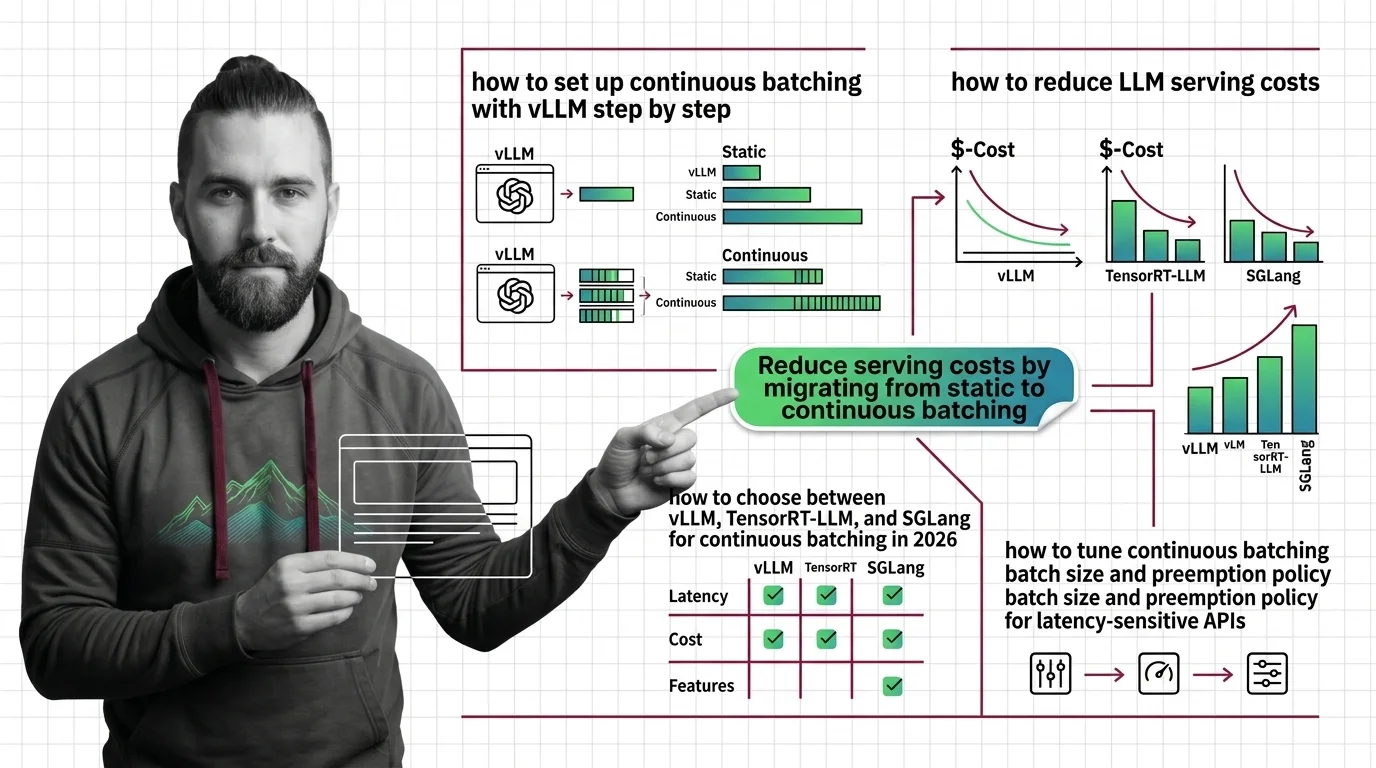
Deploy Continuous Batching: vLLM vs TensorRT-LLM vs SGLang