
Vigor Advancing Visual Grounding For Lvlms With Fine Grained Reward

ViGoR: Advancing Visual Grounding for LVLMs with Fine-Grained Reward ...
ViGoR: Enhancing Visual Grounding in LVLMs with Reward Modeling - Studocu

(PDF) Advancing Visual Grounding with Scene Knowledge: Benchmark and Method

Advancing Visual Grounding with Scene Knowledge: Benchmark and Method ...

ViGoR: Improving Visual Grounding of Large Vision Language Models with ...

ViGoR: Improving Visual Grounding of Large Vision Language Models with ...

Paper page - MoDA: Modulation Adapter for Fine-Grained Visual Grounding ...

[2411.03405] Fine-Grained Spatial and Verbal Losses for 3D Visual Grounding

VGS-Decoding: Visual Grounding Score Guided Decoding for Hallucination ...
Perceptio: Spatial Grounding for LVLMs | StartupHub.ai
Advertisement Space (300x250)

Figure 1 from Multi-Grained Alignment for Visual Grounding | Semantic ...

(PDF) VLM-Grounder: A VLM Agent for Zero-Shot 3D Visual Grounding

Fine-Grained Spatial and Verbal Losses for 3D Visual Grounding | AI ...

Figure 1 from Advancing Fine-Grained Visual Understanding with Multi ...

Advancing Fine-Grained Visual Understanding with Multi-Scale Alignment ...

Paper page - Advancing Fine-Grained Visual Understanding with Multi ...

[2411.03405] Fine-Grained Spatial and Verbal Losses for 3D Visual Grounding

VLM-Grounder: A VLM Agent for Zero-Shot 3D Visual Grounding

Figure 1 from AugRefer: Advancing 3D Visual Grounding via Cross-Modal ...

Multi-task Visual Grounding with Coarse-to-Fine Consistency Constraints ...
Advertisement Space (336x280)

[논문 리뷰] MoDA: Modulation Adapter for Fine-Grained Visual Grounding in ...

Example 1 of fine-grained visual understanding with grounding ...

Advancing Fine-Grained Visual Understanding with Multi-Scale Alignment ...

MoDA: Modulation Adapter for Fine-Grained Visual Grounding in ...

VLM-Grounder: A VLM Agent for Zero-Shot 3D Visual Grounding

SpotAgent: Grounding Visual Geo-localization in LVLMs through Agentic ...
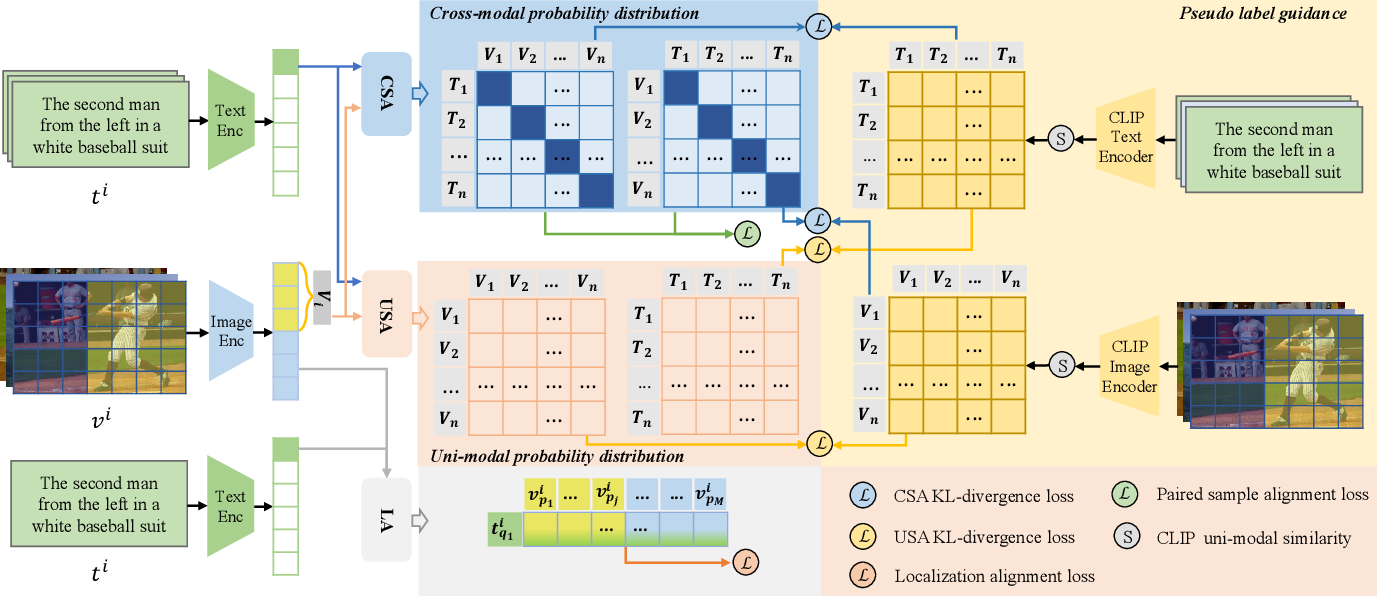
Figure 2 from Multi-Grained Alignment for Visual Grounding | Semantic ...
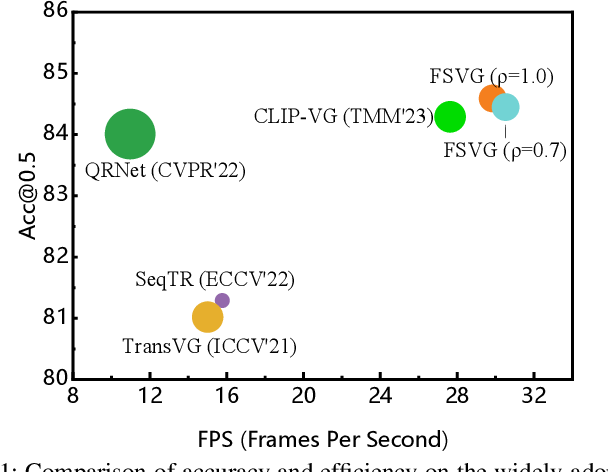
Figure 1 from A Simple and Better Baseline for Visual Grounding ...

[2506.01850] MoDA: Modulation Adapter for Fine-Grained Visual Grounding ...

LLM-Grounder: Open-Vocabulary 3D Visual Grounding with Large Language ...
Advertisement Space (336x280)

SpotAgent: Grounding Visual Geo-localization in LVLMs through Agentic ...

ECCV Poster ViGoR: Improving Visual Grounding of Large Vision Language ...

Paper page - ViGoR: Improving Visual Grounding of Large Vision Language ...

HiVG: Hierarchical Multimodal Fine-grained Modulation for Visual ...

Visual Description Grounding Reduces Hallucinations and Boosts ...
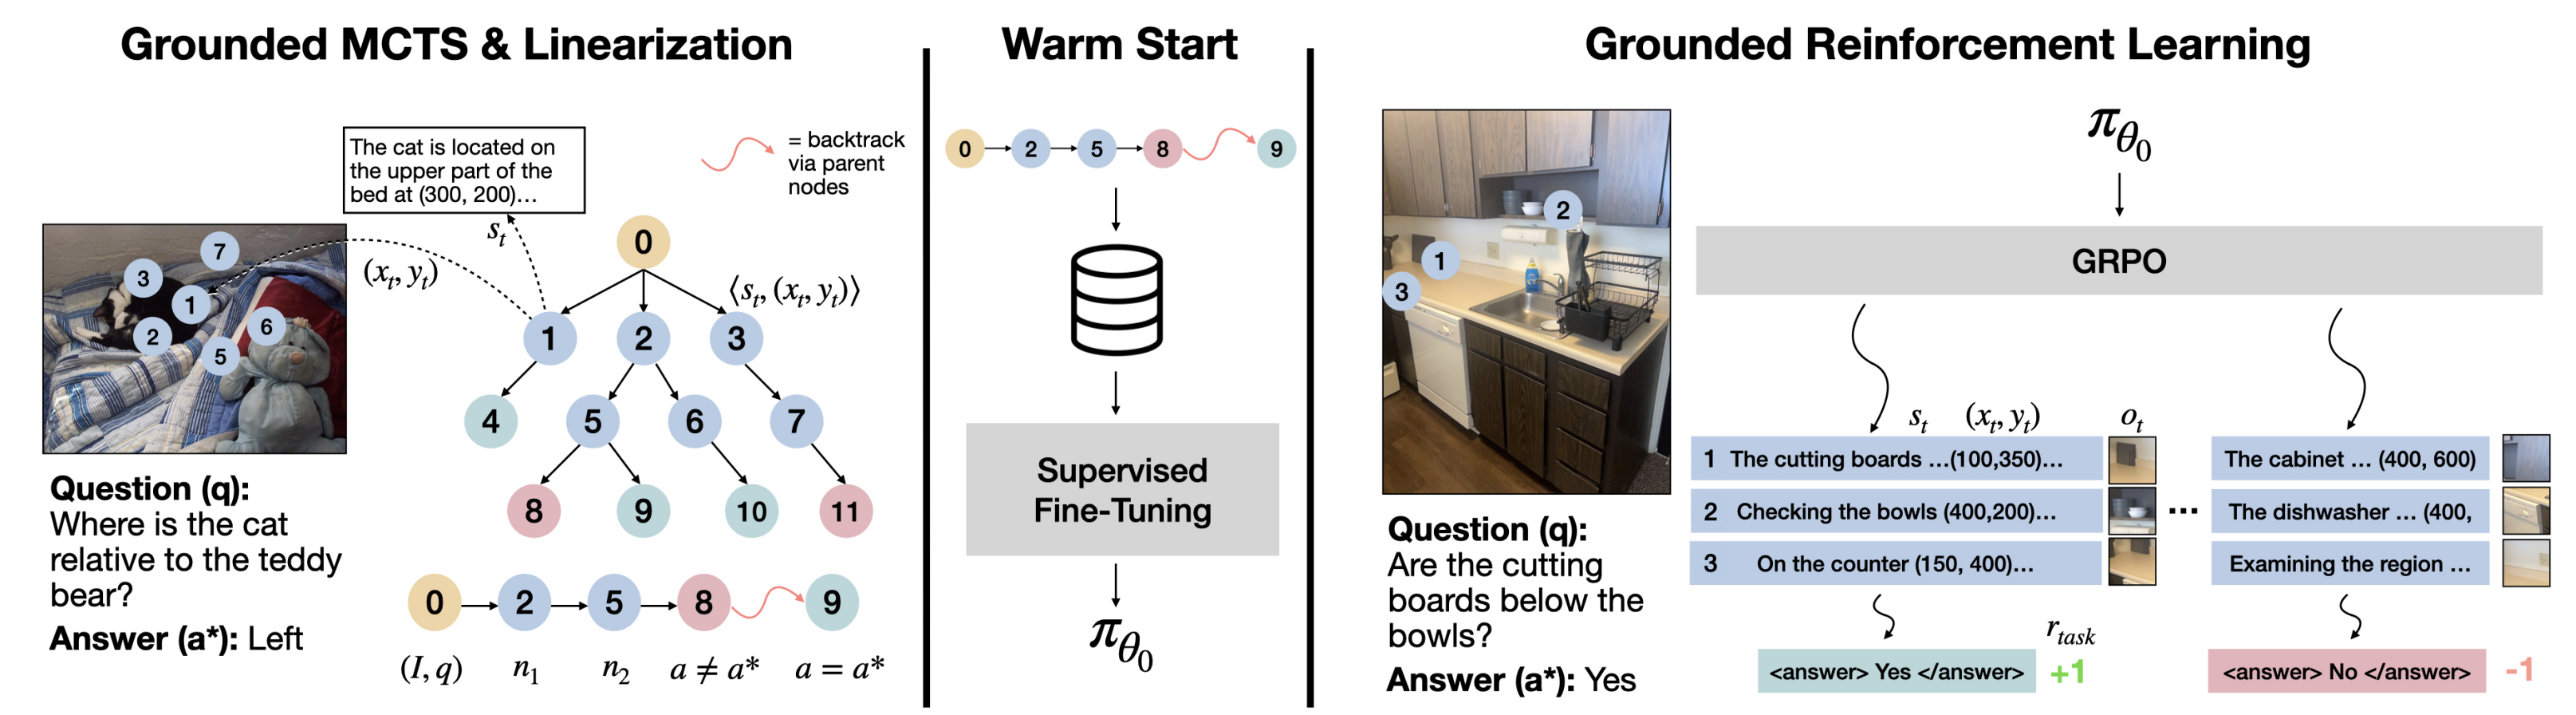
Grounded Reinforcement Learning for Visual Reasoning