
Vllm Production Deployment 2026 Multi Gpu Tensor Parallel Fp8 Docker
vLLM Production Deployment 2026: Multi-GPU Tensor Parallel + FP8 Docker ...
TensorRT-LLM Production Deployment on GPU Cloud: Engine Build, Multi ...
vLLM Production Deployment Guide 2026 | Lyceum | Lyceum Technology

LLM Semantic Router Production Implementation vLLM SR 2026 | Iterathon

vLLM Production Deployment: Complete 2026 Guide | SitePoint

We're Live: OCI Deployment Guide for vLLM Production Stack - General ...

How to Deploy vLLM in Production with Docker (2026) | Yotta Labs
vLLM Python 2026 : servir des LLMs en production — PagedAttention ...
How to Deploy vLLM in Production with Docker (2026) | Yotta Labs
tensor parallel question on multi-GPUs and API deployment issue · Issue ...
Advertisement Space (300x250)
vLLM en production : le guide du développeur 2026

Run Gemma 4 with vLLM — Production Deployment

vLLM Interview Questions: 2026 PagedAttention + Production Guide

Data Parallel Deployment - vLLM

Data Parallel Deployment - vLLM

tencent/Hunyuan-A13B-Instruct-FP8 · VLLM docker deployment
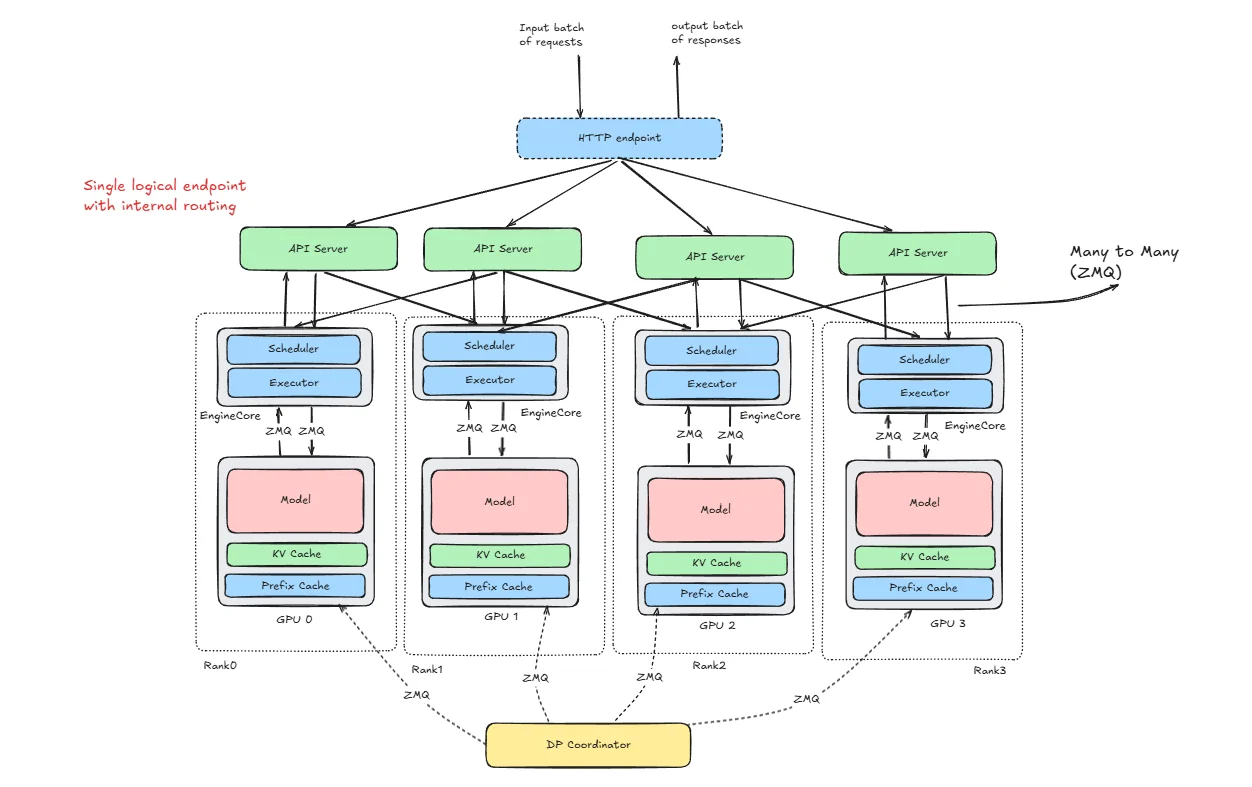
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
vLLM Docker Deployment: Production-Ready Setup Guide (2026) | Inference.net
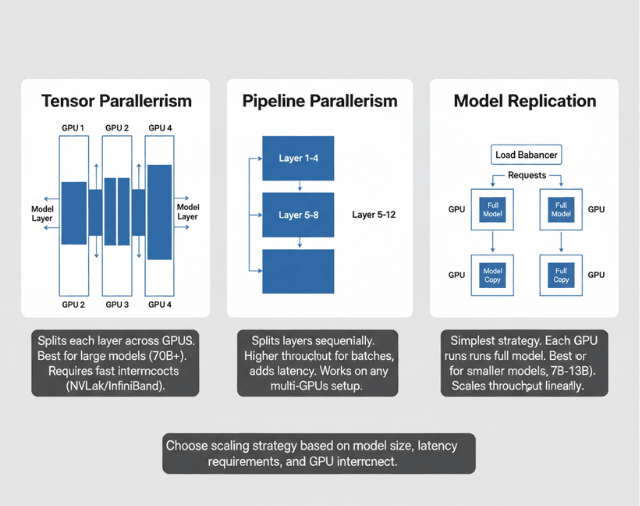
GPU Guide for LLM Deployment - RTX 4090 to A100 Benchmarks (2026)
vLLM Multi-GPU Documentation — Tensor Parallelism Setup & Configs (2026 ...
Advertisement Space (336x280)
vLLM Docker Deployment: Production-Ready Setup Guide (2026) | Inference.net
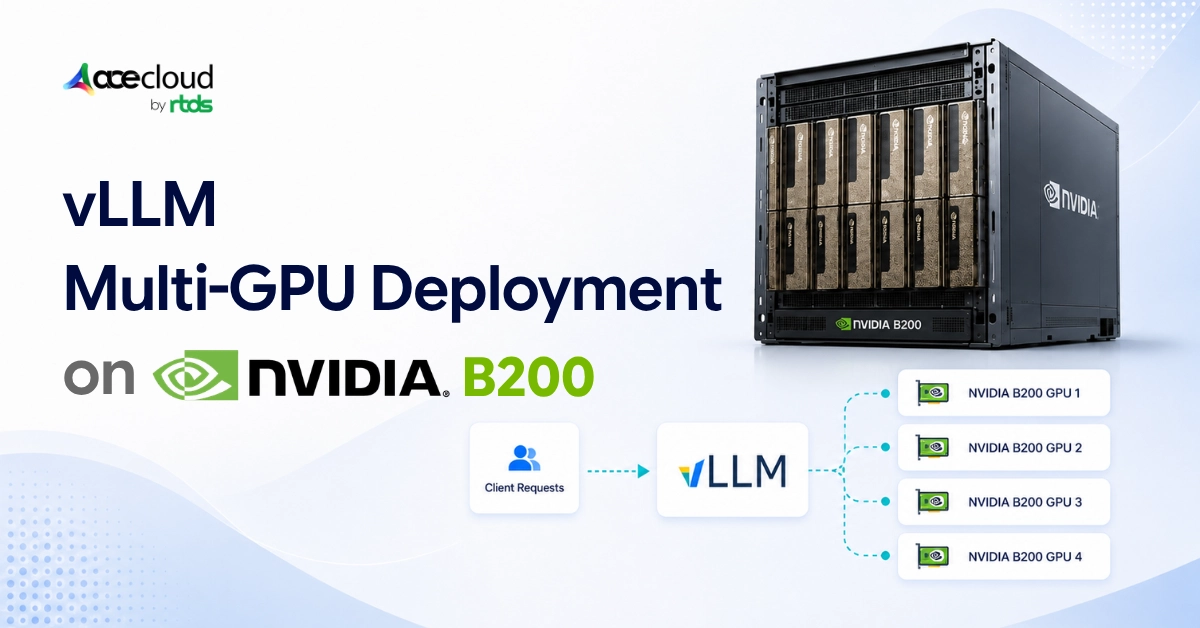
VLLM Multi-GPU Deployment On NVIDIA B200

How to Choose the Right GPU for vLLM Inference | DigitalOcean

vLLM 2026 完整指南:PagedAttention 高吞吐推理引擎 - AI 织梦博客

Install vLLM on Linux for Production LLM Serving (2026 Guide)
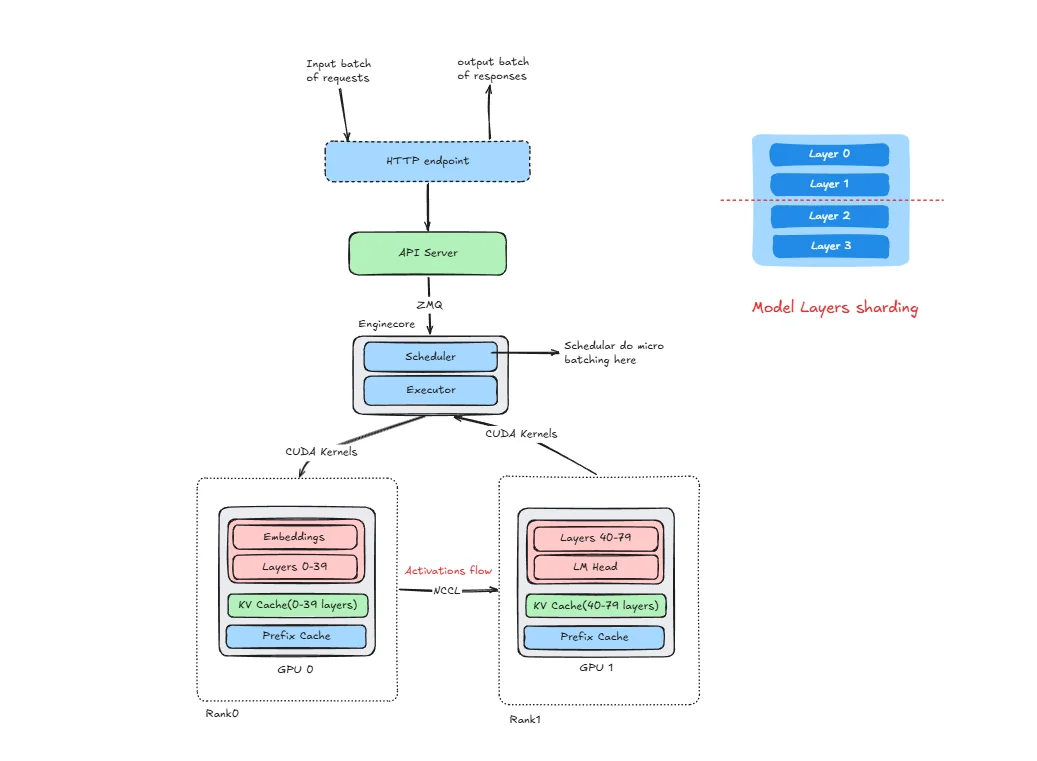
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...

Deploy vLLM with Docker on Runpod: Container Config, Model Loading, and ...
Open Source LLMs, from vLLM to Production (Instruct.KR Summer Meetup ...
vLLM Model Runner V2 on GPU Cloud: Deploy MRV2 for Faster LLM Inference ...
[Bug]: Qwen3.5-122B-A10B-FP8 multi GPU issue(tensor-parallel-size ...
Advertisement Space (336x280)
deploy vLLM with LoRA in production stack | by Kobe | Jun, 2025 | Medium

How to Build a vLLM Container Image for LLM Deployment | Vultr Docs

Enterprise-Ready LLM Inferencing with the vLLM Production Stack on Dell ...
Pliops Announces Collaboration with vLLM Production Stack to Enhance ...
A vLLM Docker Compose recipe for running Qwen 3.6 27B on dual RTX 3090s ...
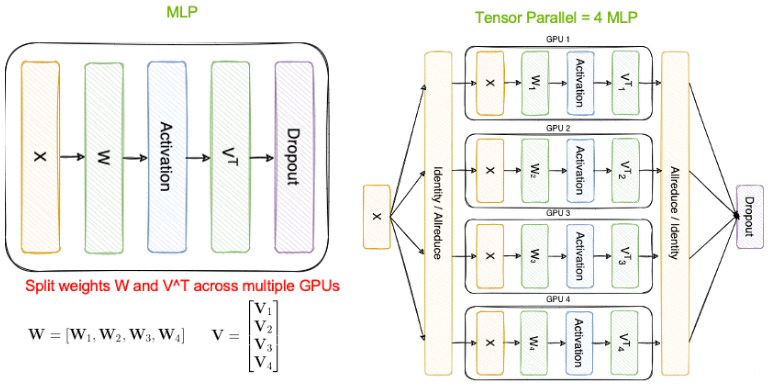
Amazon EC2 G5/G6 인스턴스에서 GPU Tensor Parallelism으로 비용 효과적으로 LLM 서빙하기 ...