
Vllm Quickstart Guide Of Hos High Performance Llm Inference For

VLLM Quickstart Guide of HOS: High-Performance LLM Inference for ...

VLLM Quickstart Guide of HOS: High-Performance LLM Inference for ...

LLM inference engines performance testing: SGLang VS. vLLM | by ...
vLLM Installation for High-Performance LLM Inference - CubePath Docs ...

vLLM High-Throughput LLM Inference Guide | PDF | Cache (Computing ...
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
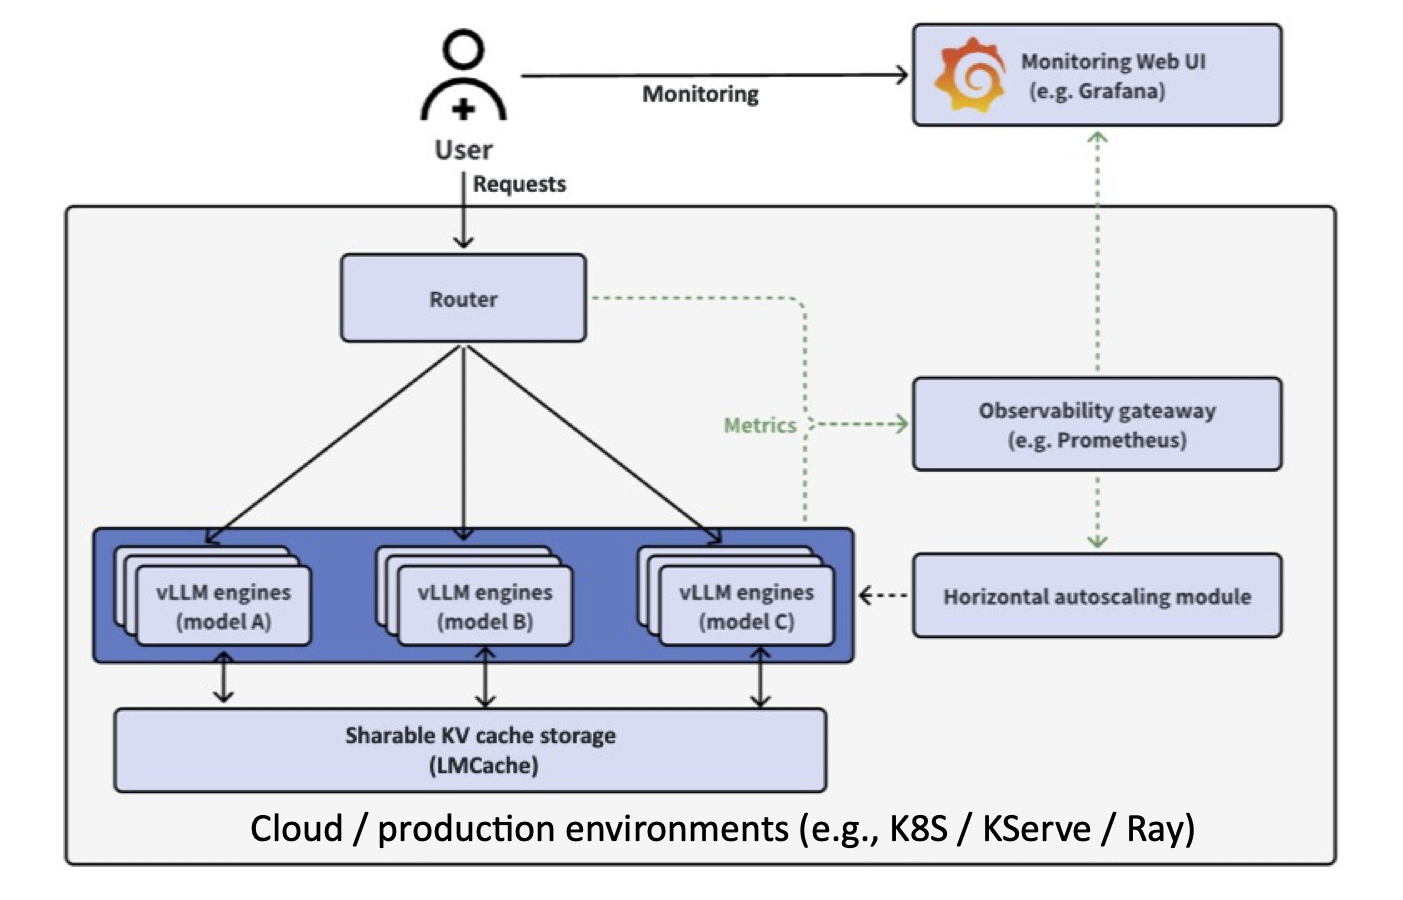
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...

vLLM Review: High-Performance LLM Inference Engine for GPU ...
A guide to LLM inference and performance

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...
Advertisement Space (300x250)

A Quick Guide to vLLM for Fast AI Inference
vLLM vs Hugging Face for High-Performance LLM Inference | by Ali ...
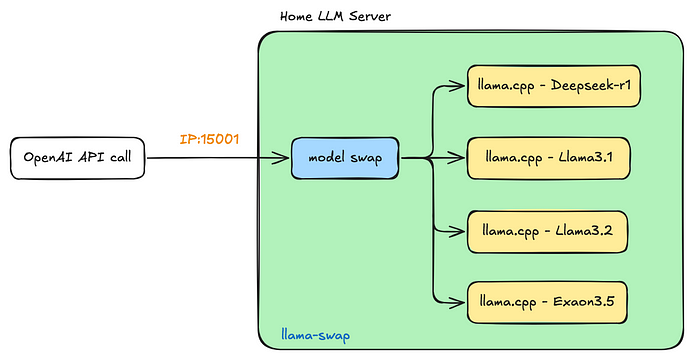
LLM inference engines performance testing: SGLang VS. vLLM | by ...
Local LLM Inference on Mac: vLLM Metal Quick Start Guide - Infinirc
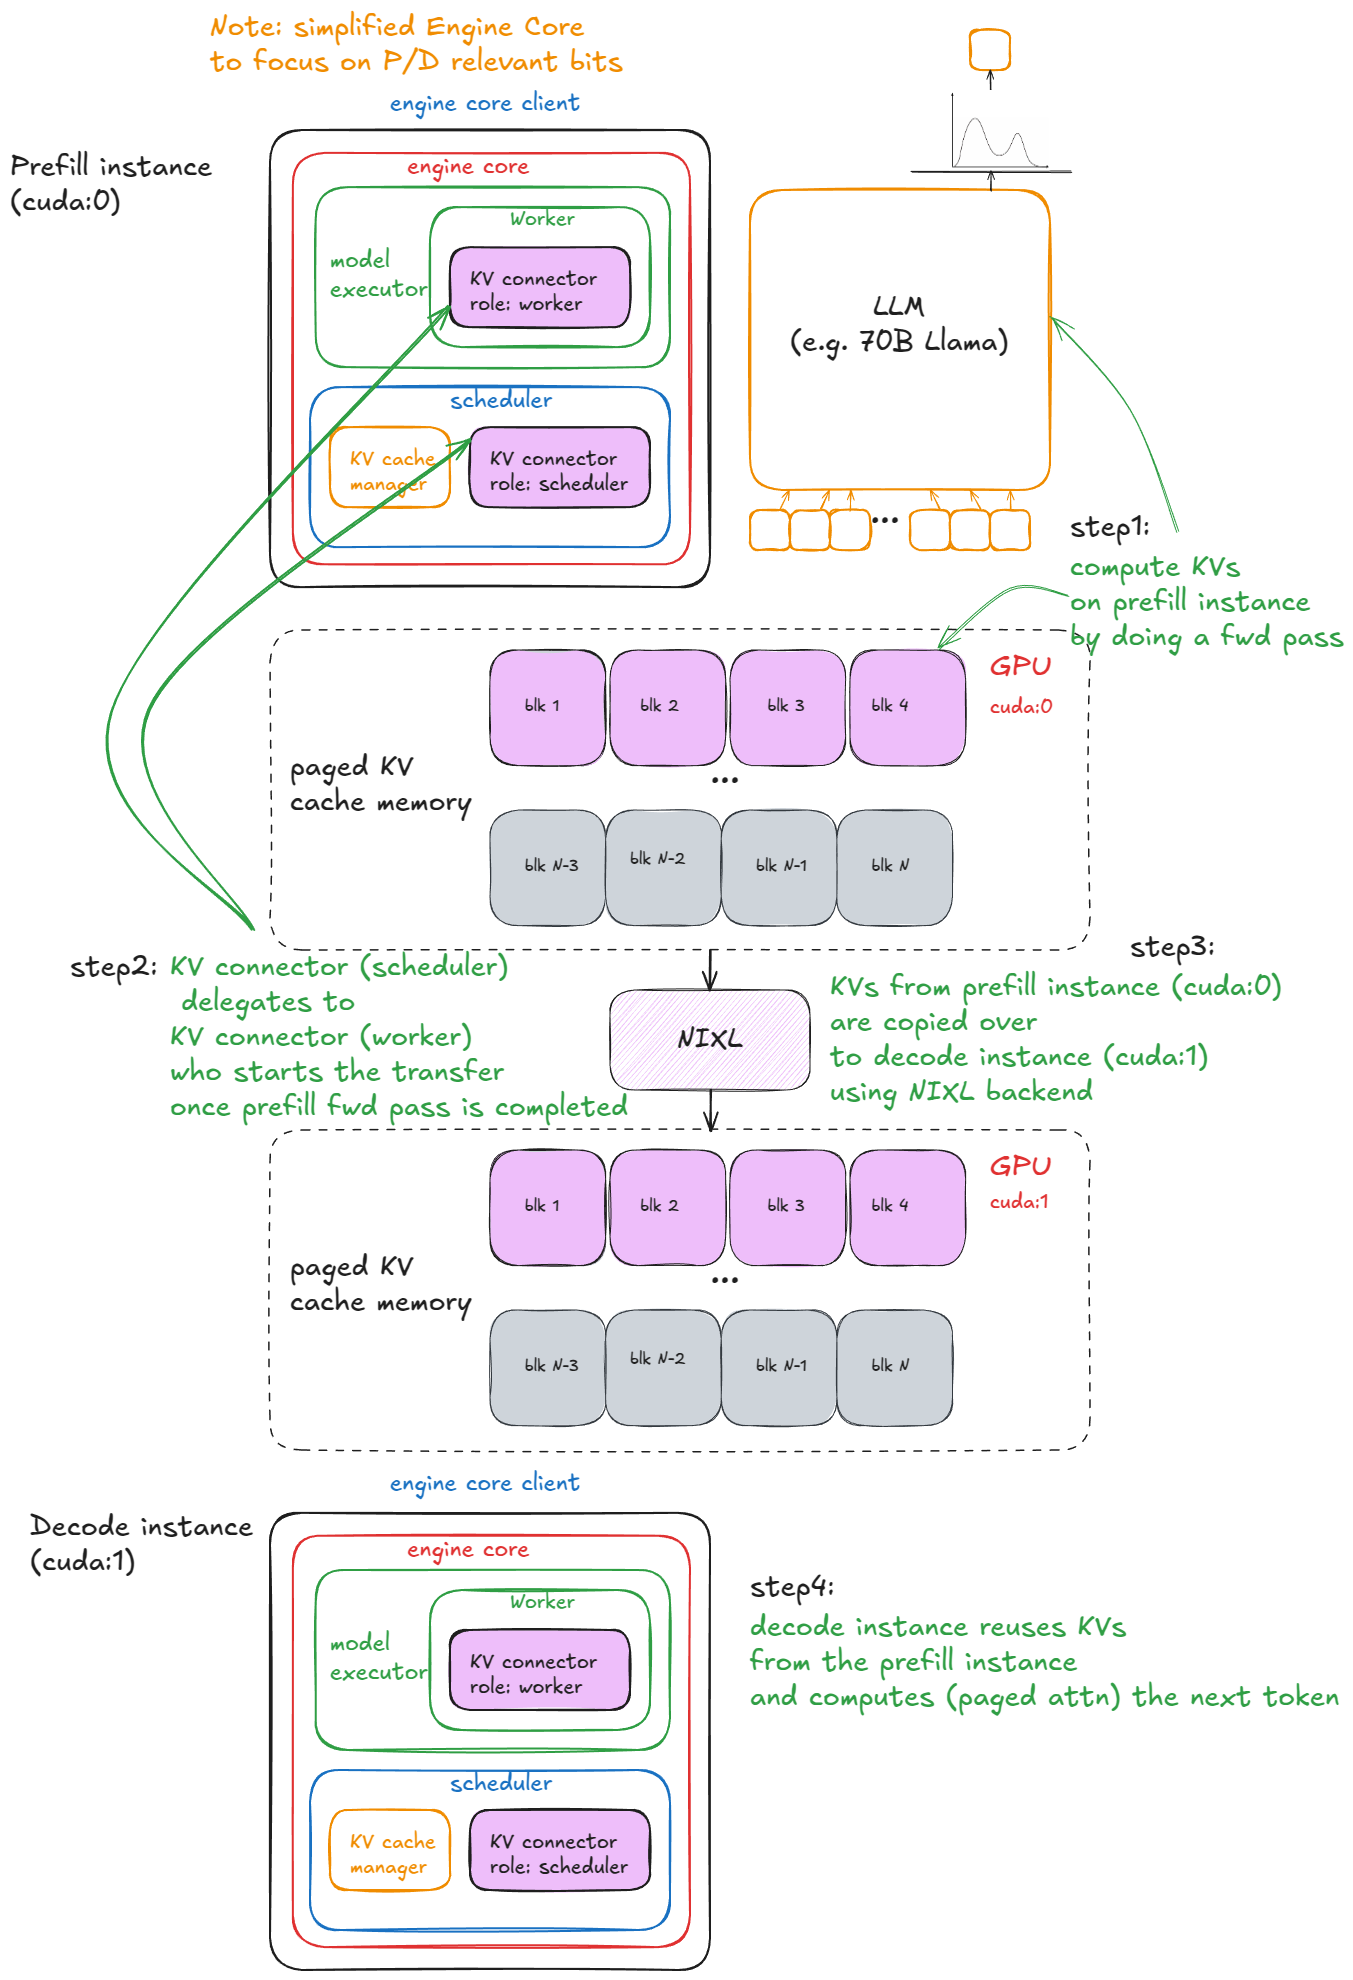
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
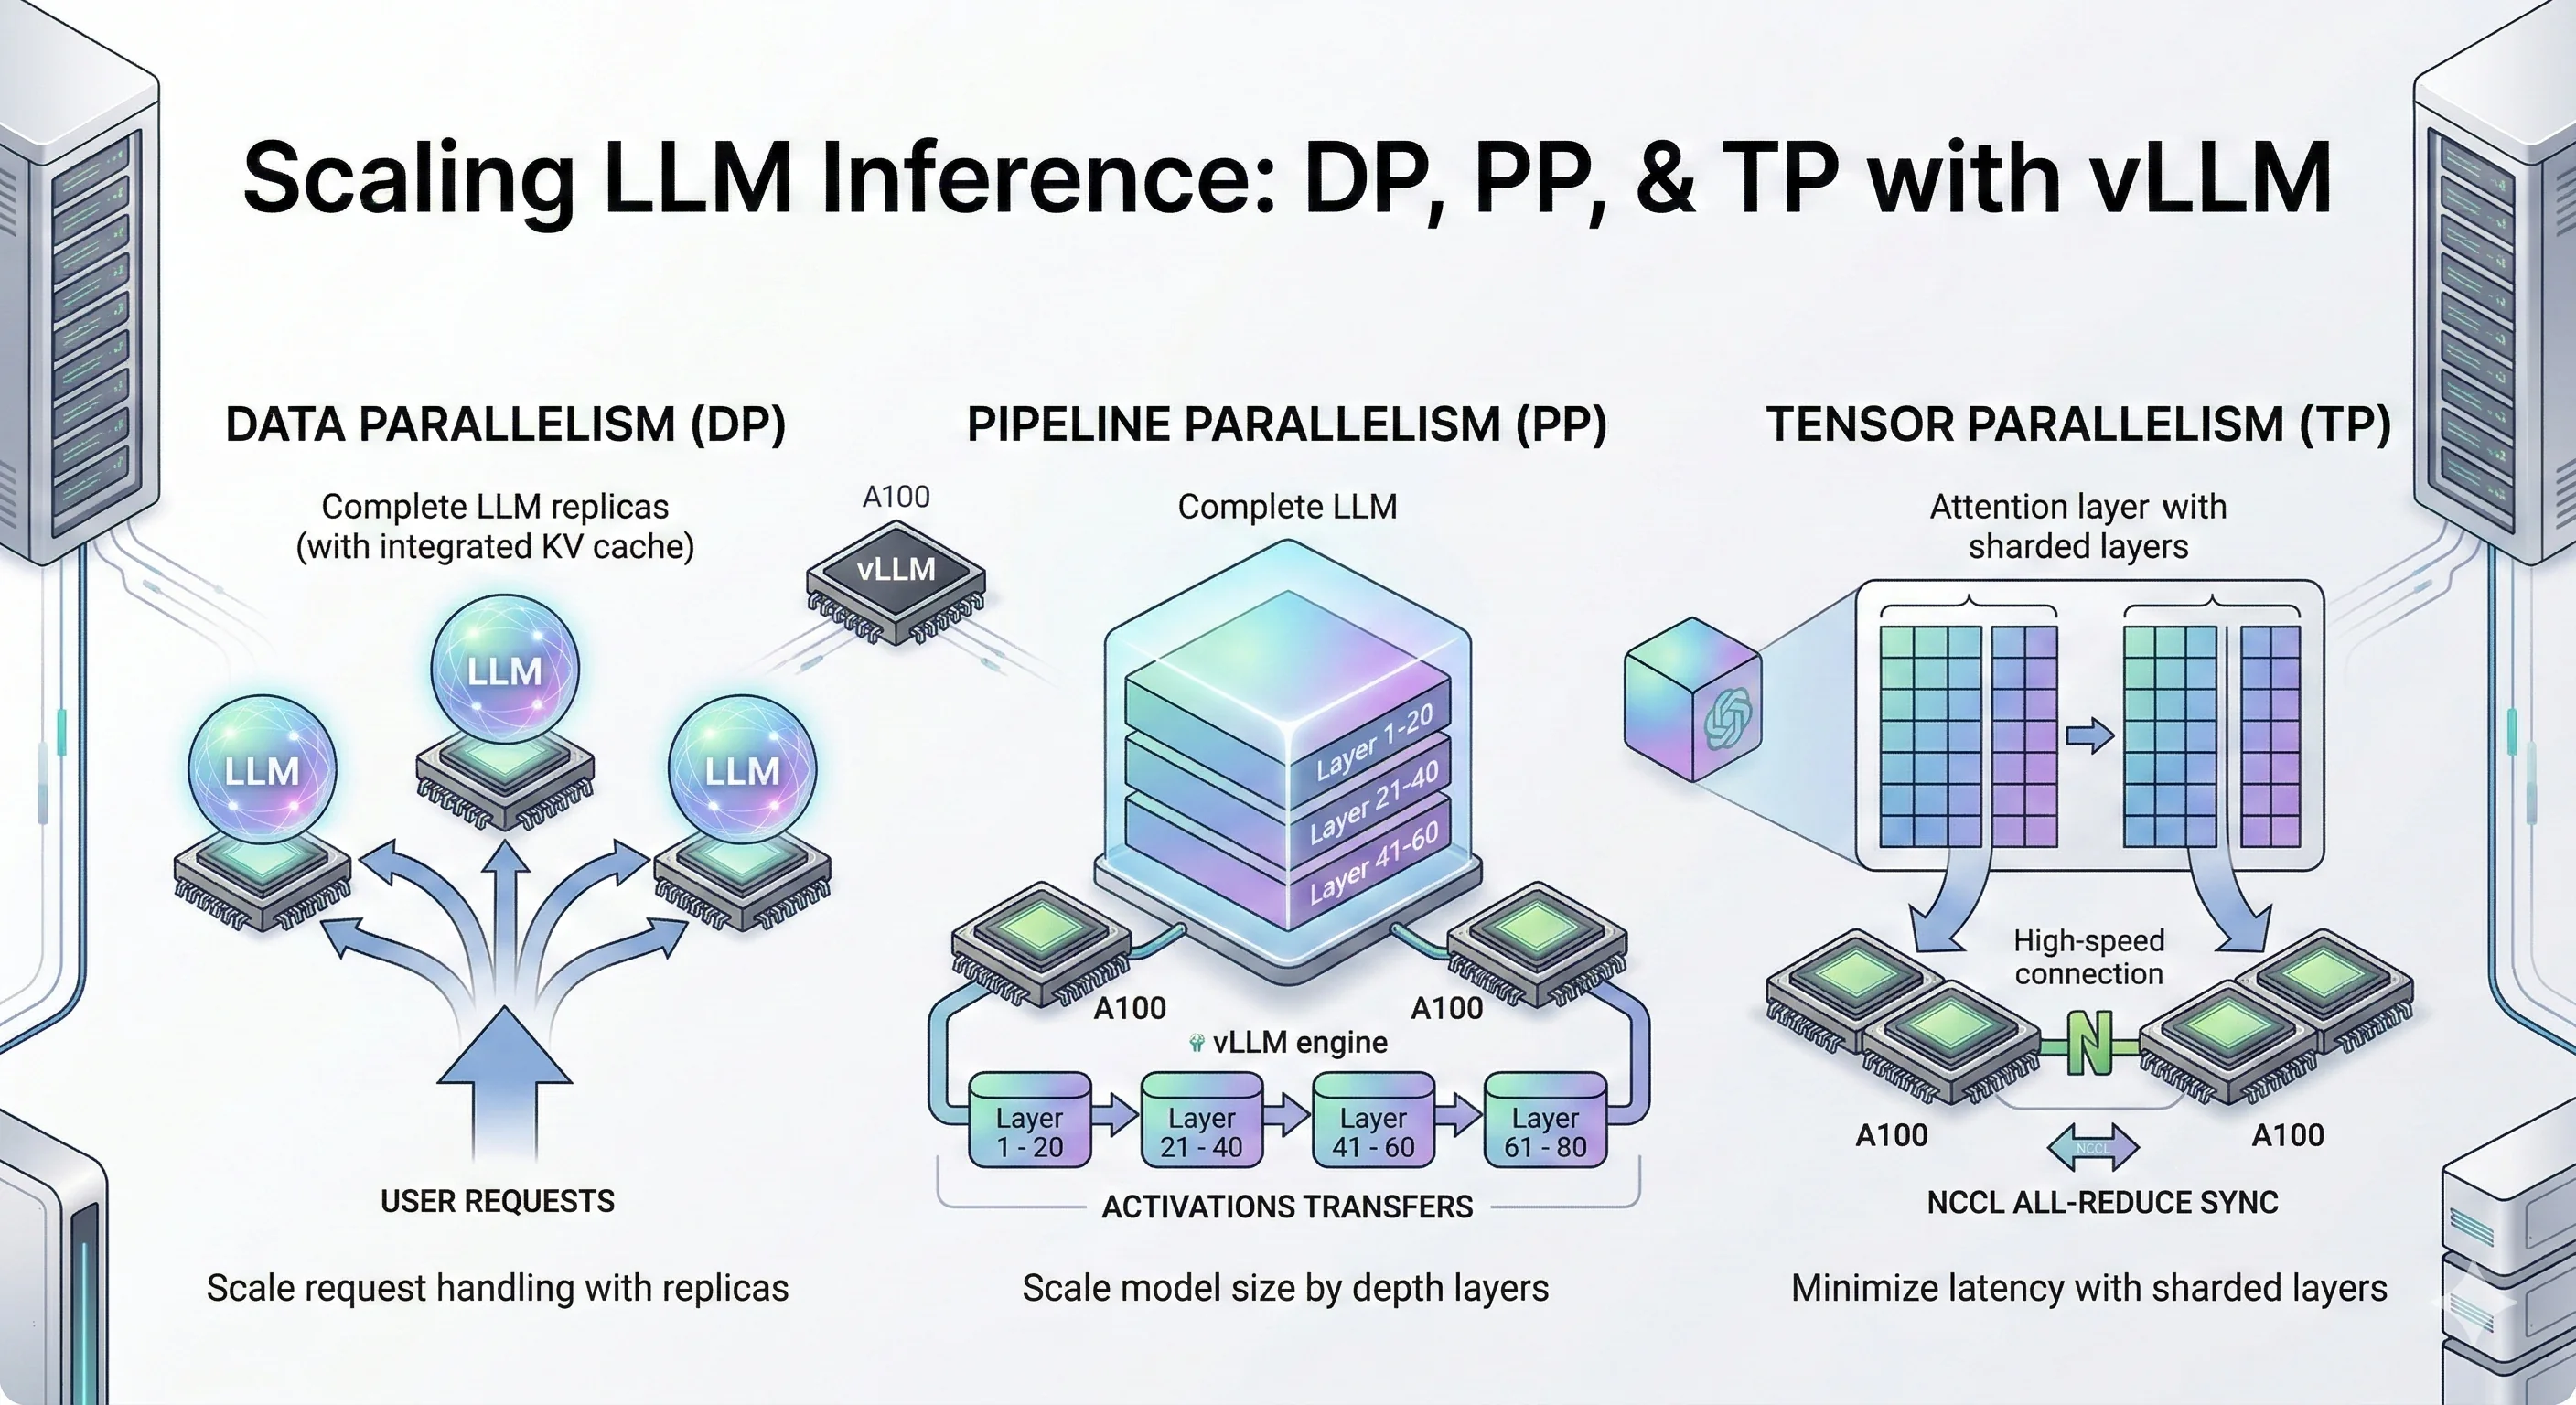
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
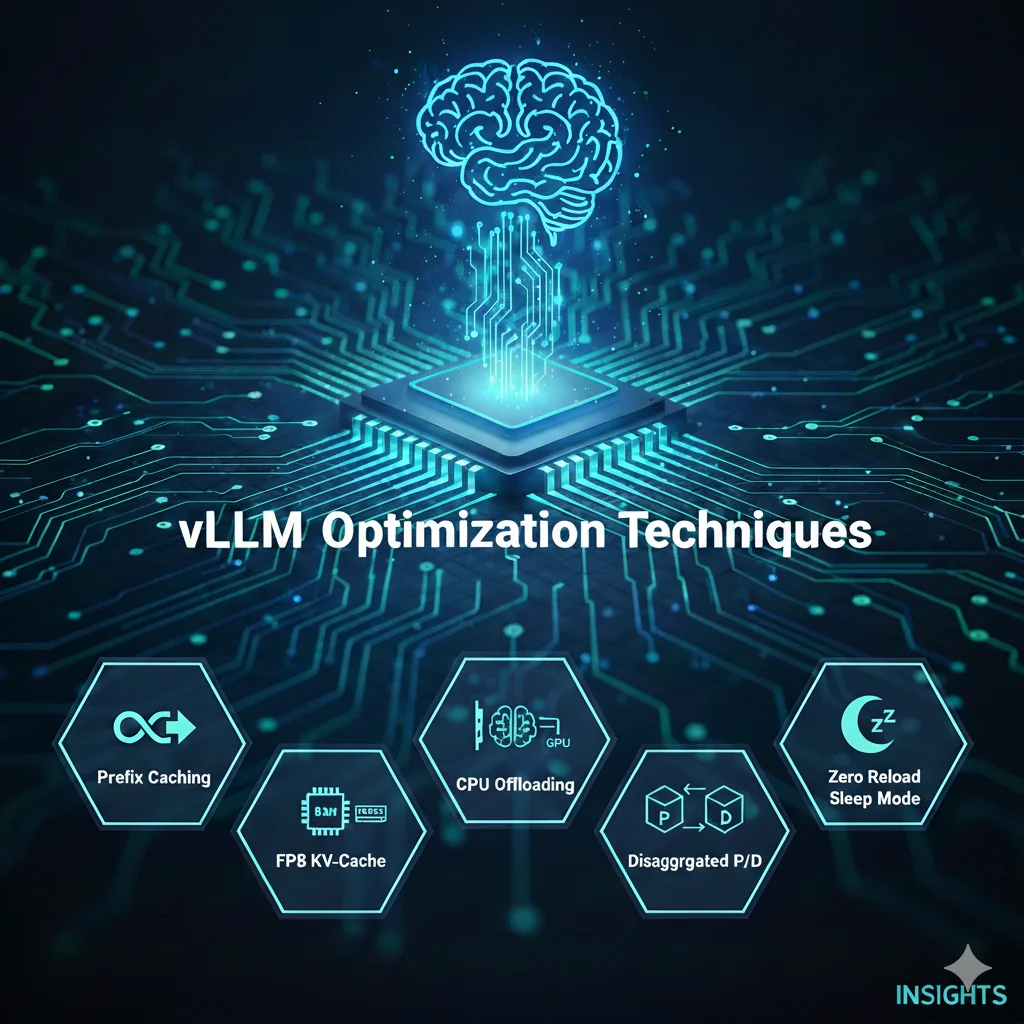
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

vLLM Advanced: Building Custom Inference Pipelines at Scale (2026 Guide ...
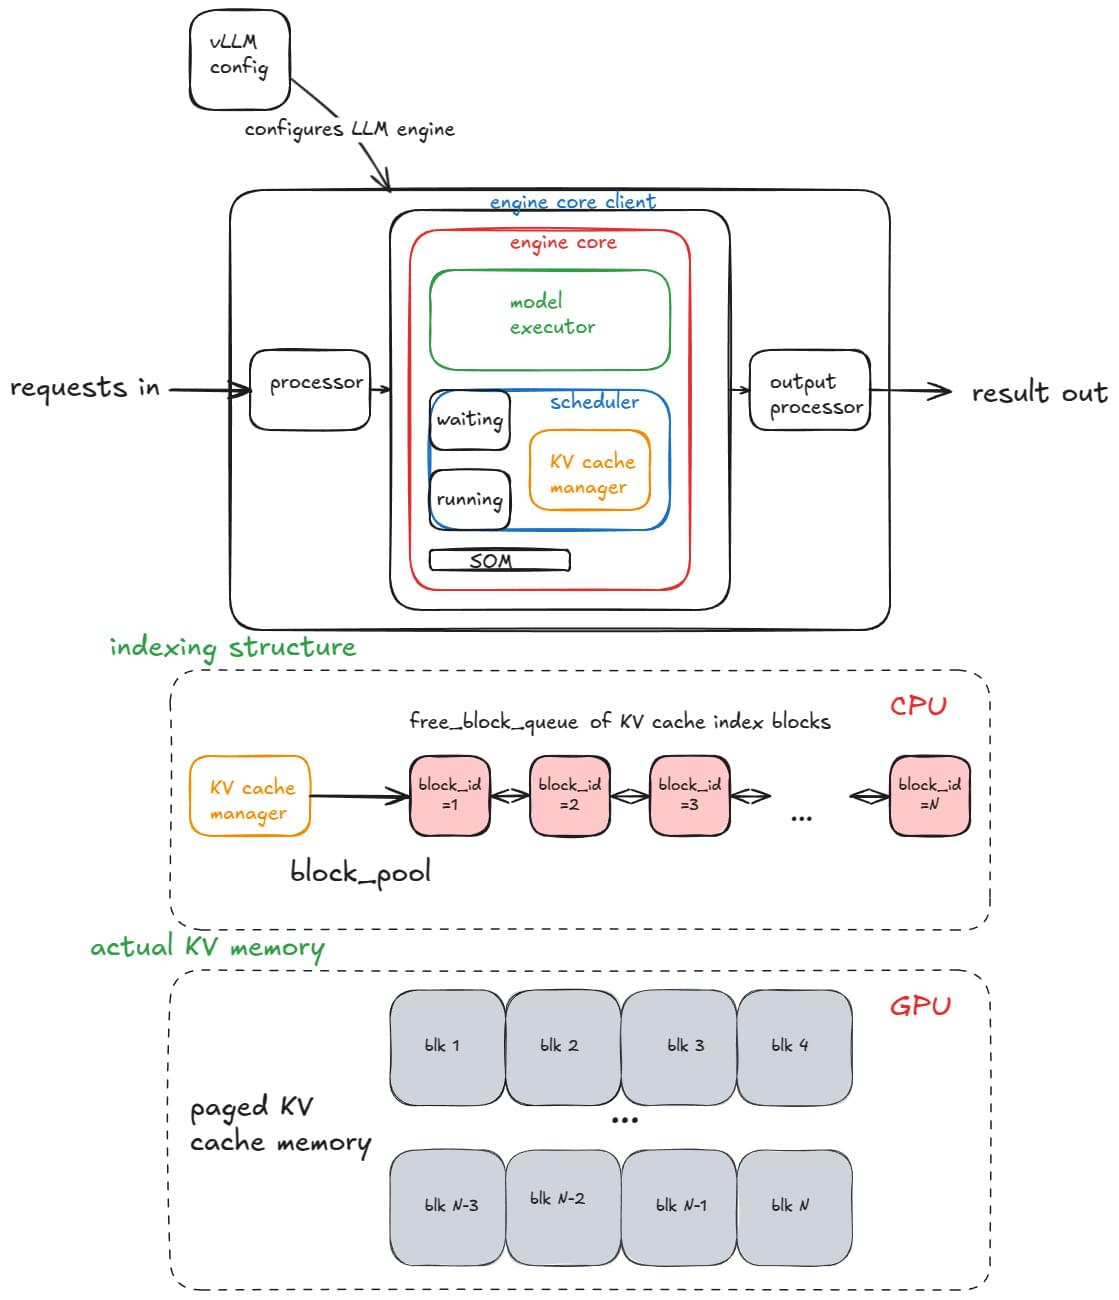
Inside vLLM: Anatomy of a High-Throughput LLM Inference System ...
Advertisement Space (336x280)
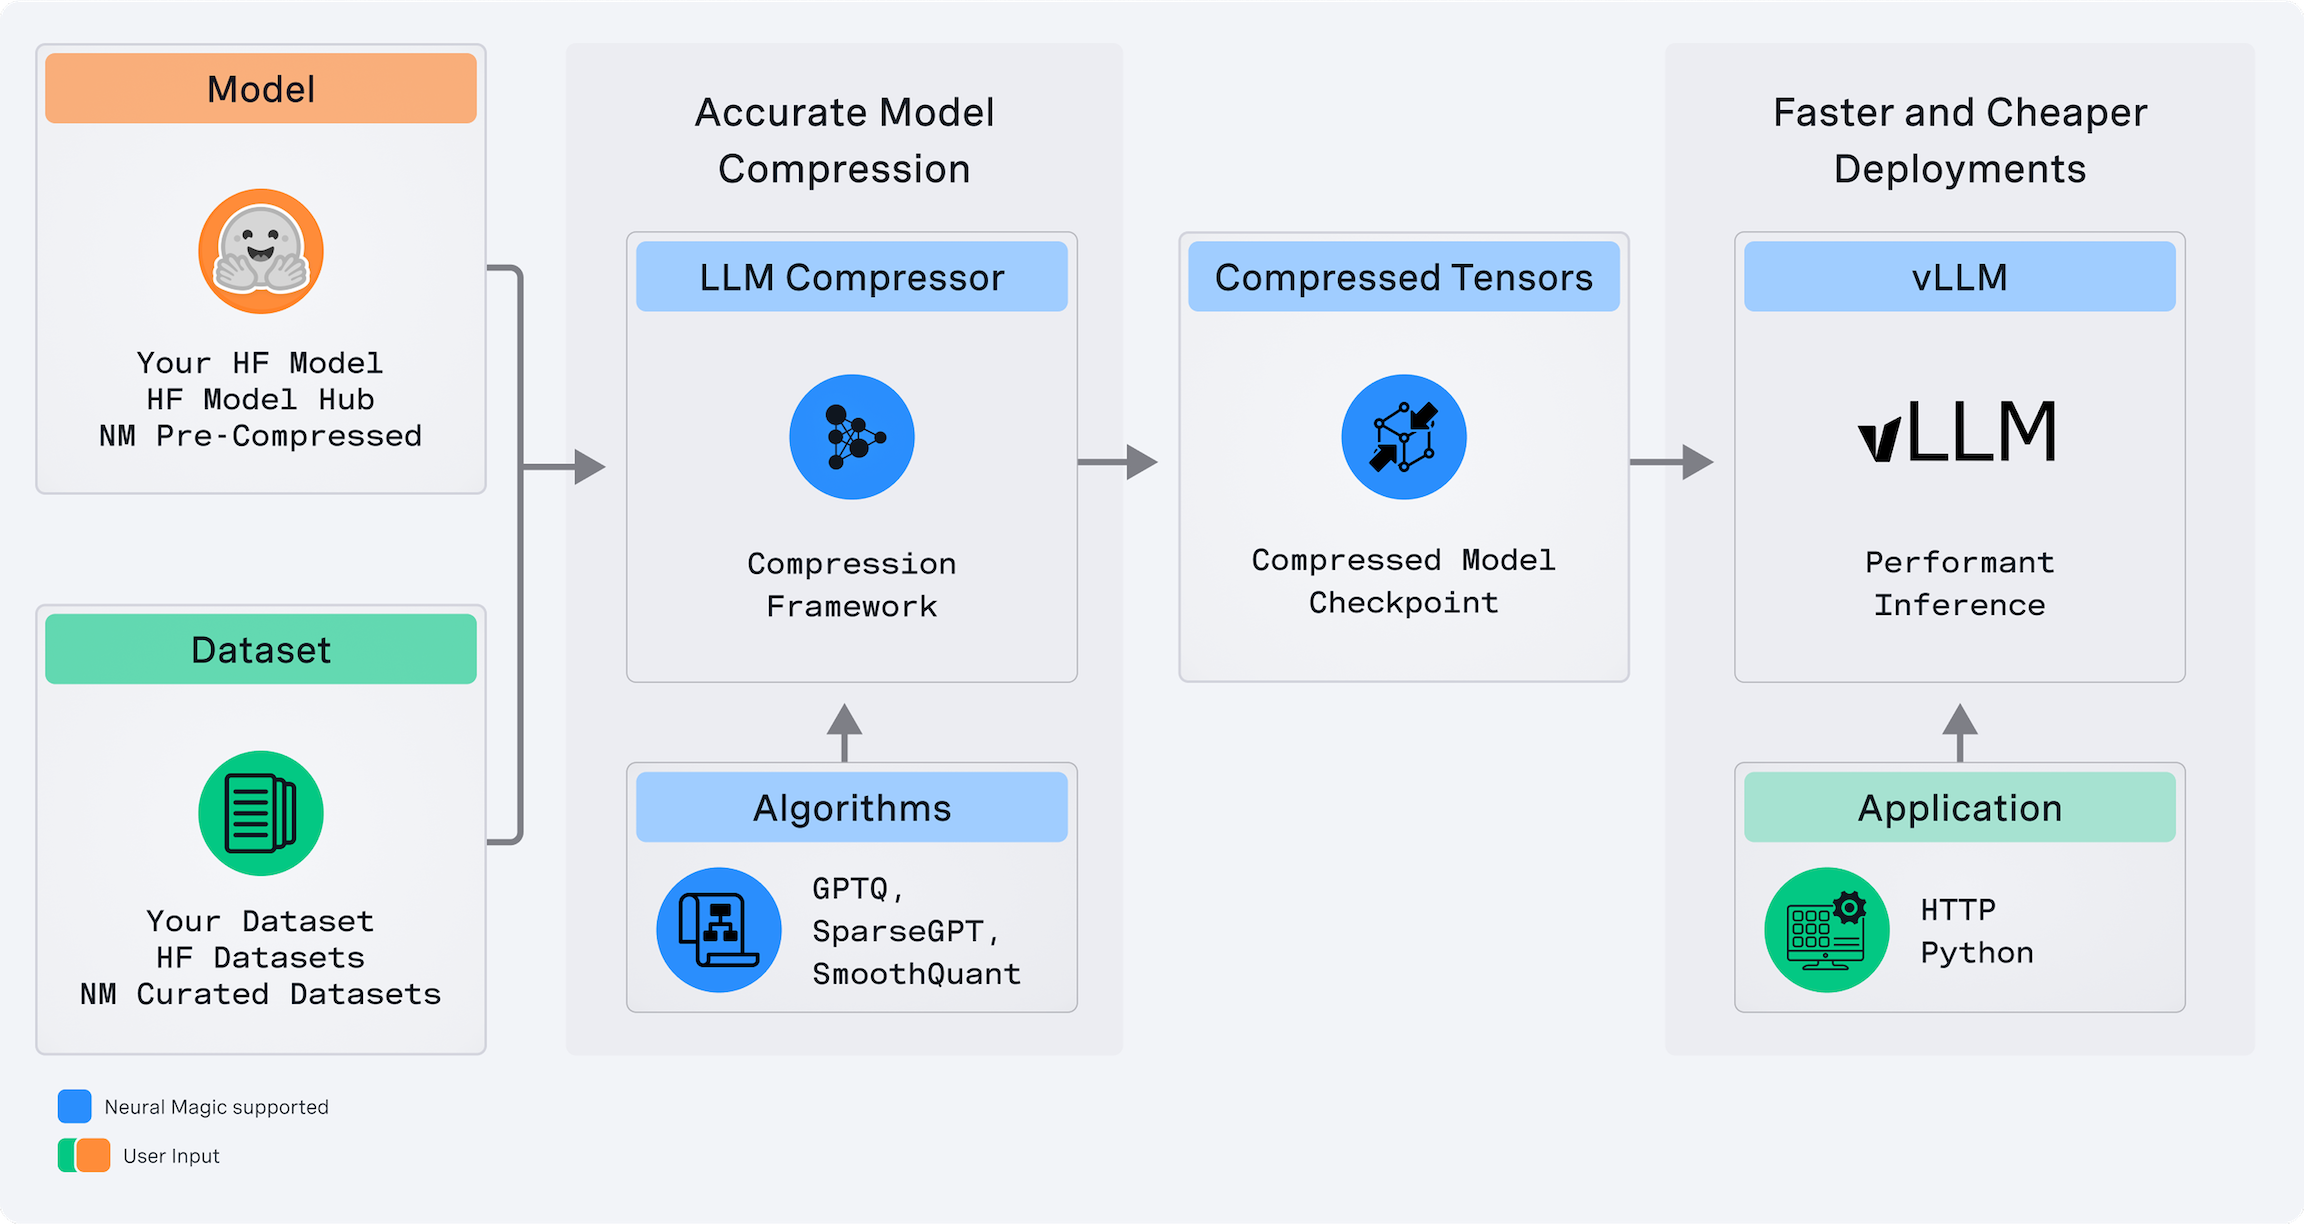
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

Accelerating LLM Inference with vLLM - APC 技術ブログ

LLM Inference Optimization Production Guide 2026 | Iterathon

vLLM: Anatomy and Mechanisms of High-Throughput LLM Inference | by ...
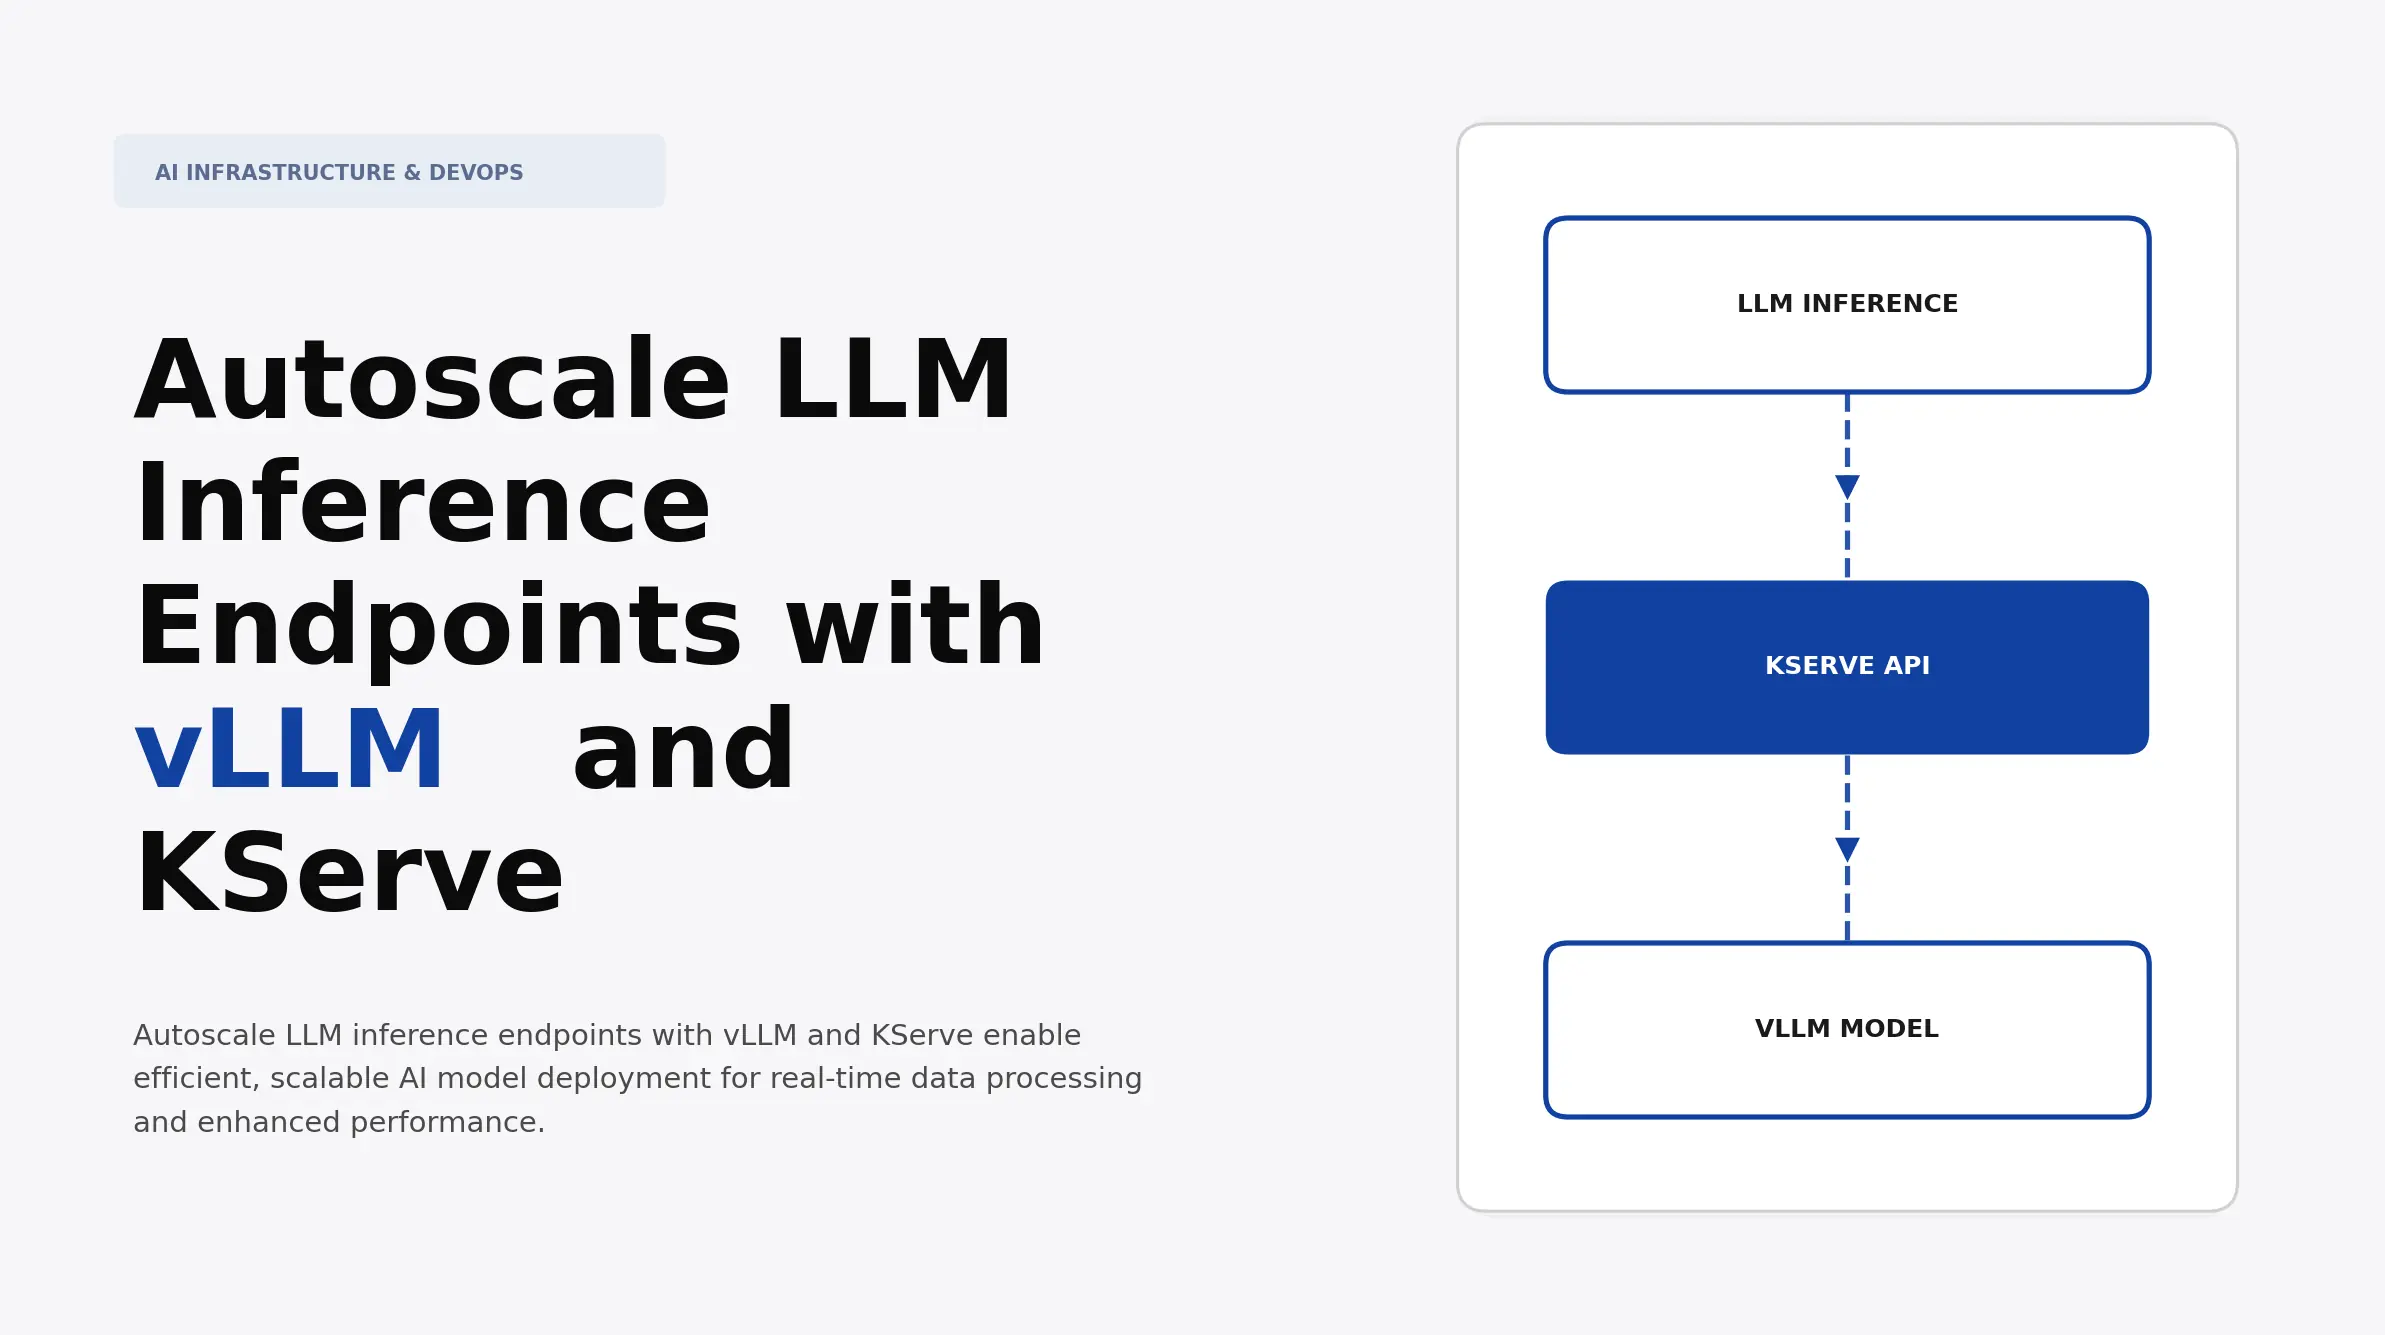
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
How to Deploy LLMs with vLLM for High-Performance Inference
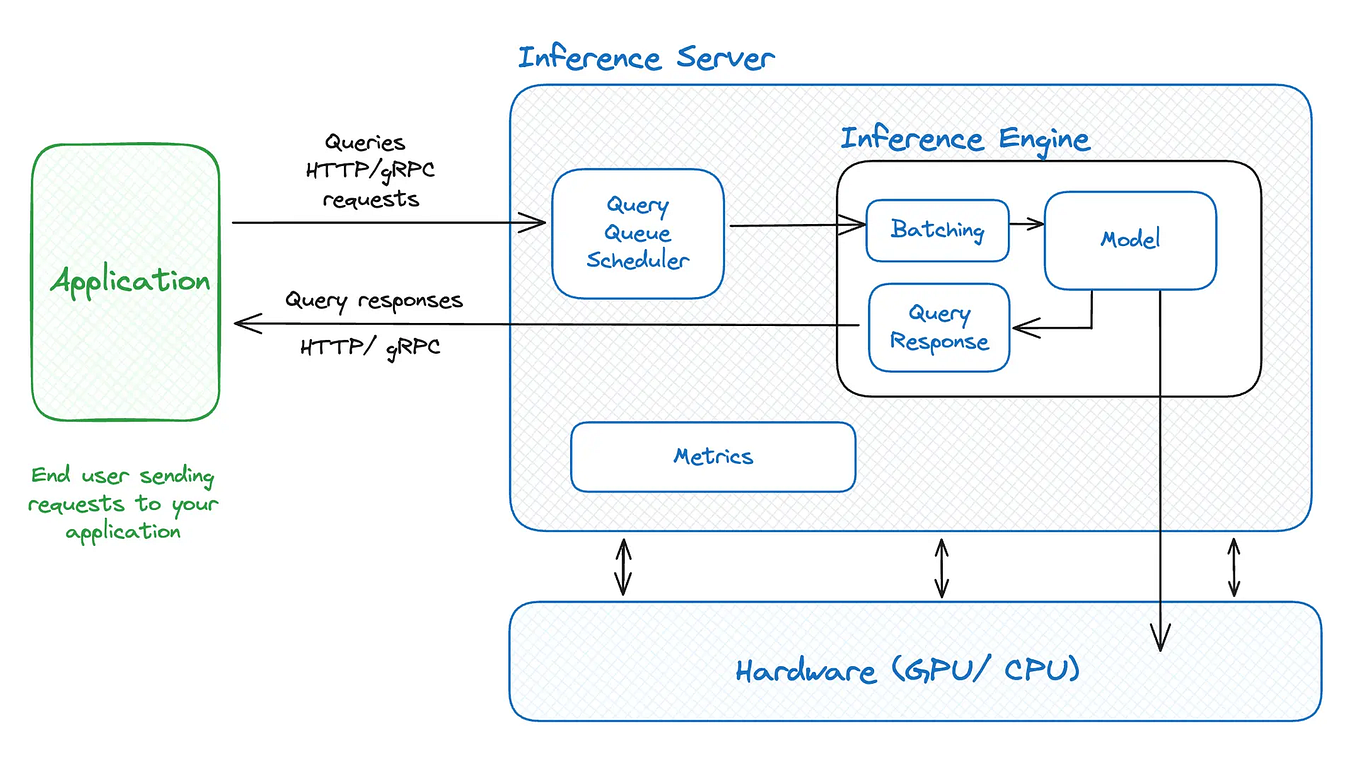
Boosting LLM Inference Speed: High Performance, Zero Compromise | by ...
vLLM Guide 2026 | High-Throughput LLM Serving
LLM Inference Battle: vLLM vs. TensorRT-LLM vs. Hugging Face TGI vs ...
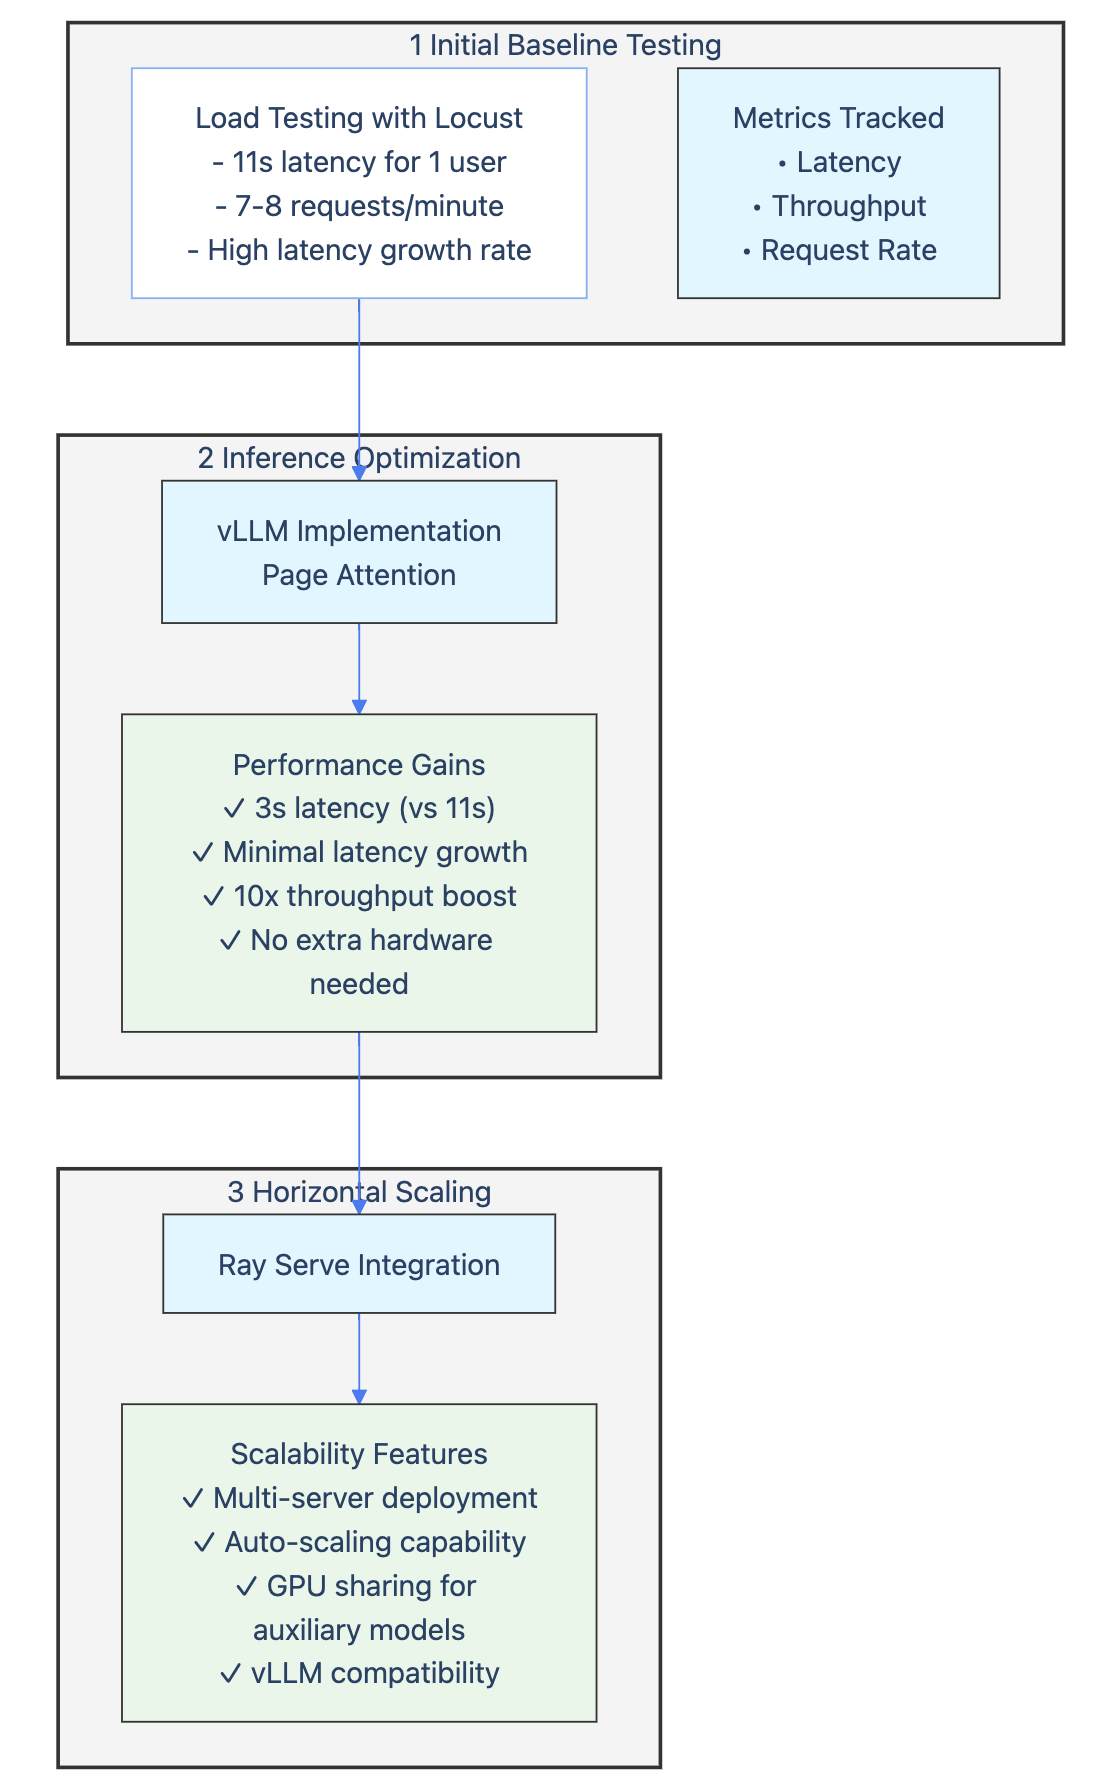
Optimizing LLM Performance and Cost: Squeezing Every Drop of Value ...
Advertisement Space (336x280)

Meet vLLM: For faster, more efficient LLM inference and serving
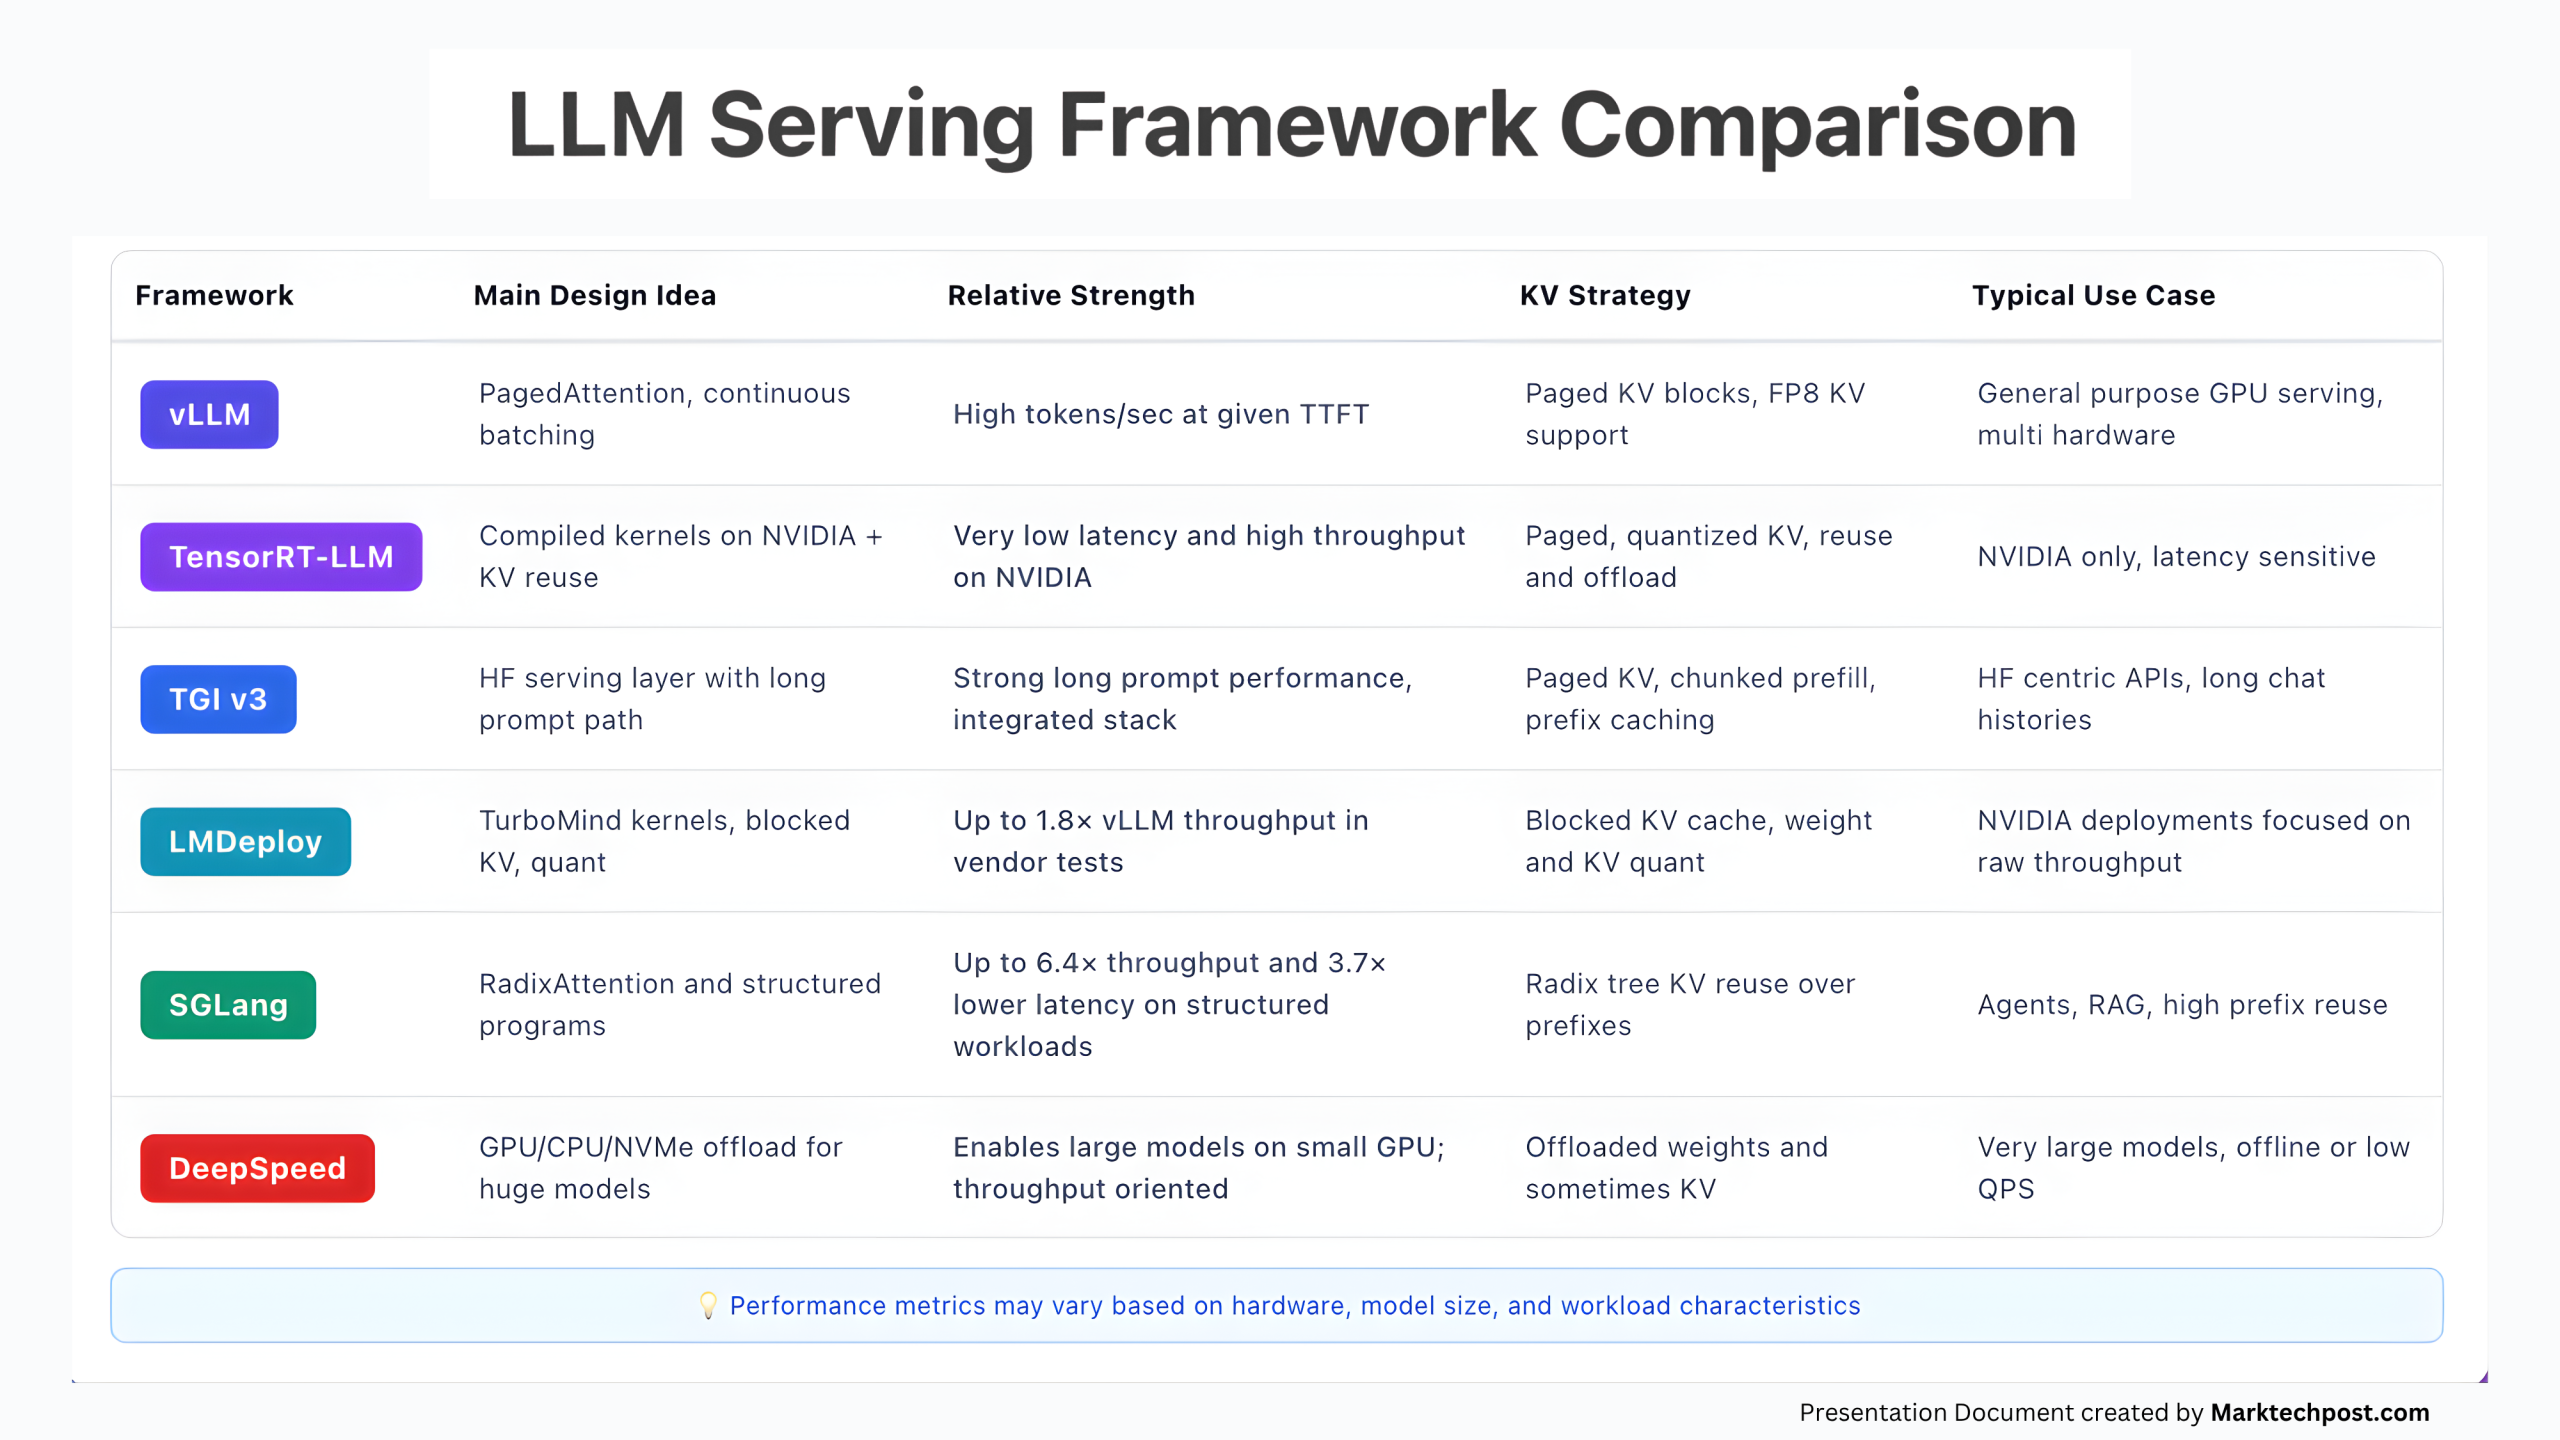
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...

Install vLLM on Gigabyte AI TOP ATOM: High-Performance LLM Inference ...
tiny-vllm: Educational Implementation of High-Performance LLM Inference ...

Efficient LLM Inference and Serving with vLLM
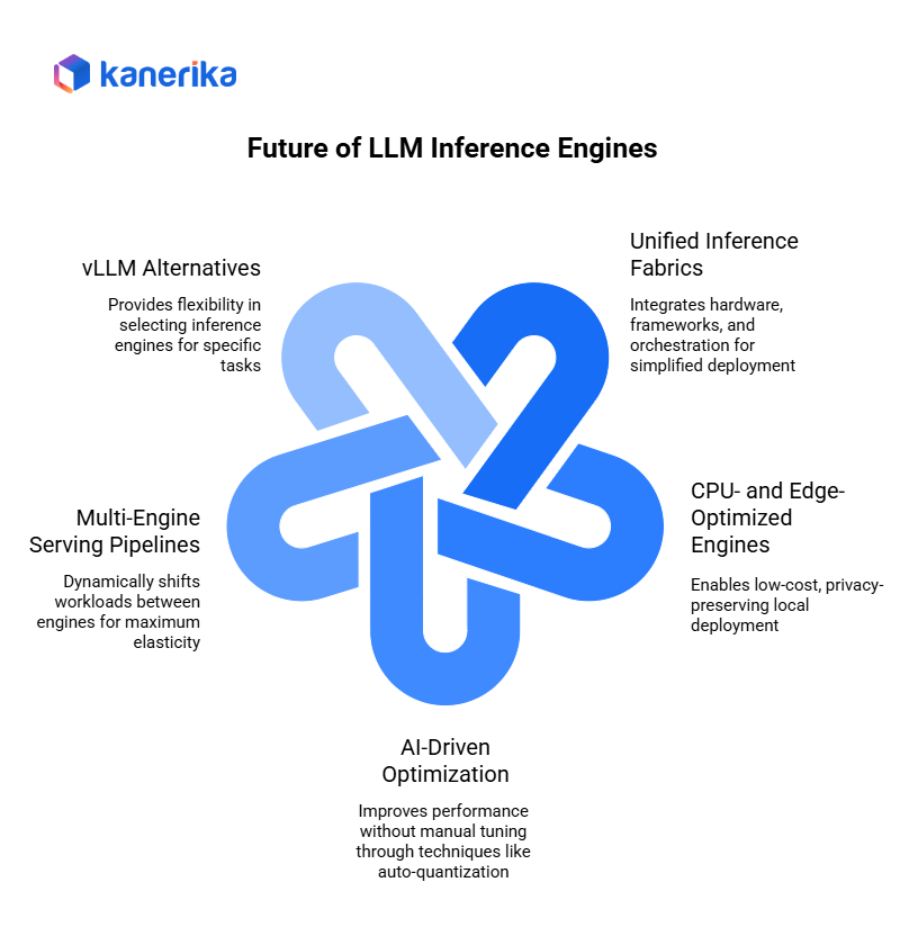
Top 10 vLLM Alternatives for Faster AI Inference in 2026