
Vllm Tutorial 2026 Pagedattention Llm Inference Guide Weavai Blog

vLLM Tutorial 2026: PagedAttention LLM Inference Guide - WeavAI Blog

vLLM Tutorial 2026: PagedAttention LLM Inference Guide - WeavAI Blog

SGLang 2026 Guide: Fast LLM Inference & Deployment - WeavAI Blog

LLM Inference Optimization Production Guide 2026 | Iterathon

Real-Time Streaming LLM Inference Guide 2026 | Iterathon

LLM Batch Inference Cut Costs 50% Production Guide 2026 | Iterathon
vLLM Production LLM Serving: Developer Guide 2026
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
vLLM คืออะไร? คู่มือ LLM Inference Server สำหรับ SME 2026 — ADS FIT
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
Advertisement Space (300x250)

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

vLLM Advanced: Building Custom Inference Pipelines at Scale (2026 Guide ...
vLLM Tutorial: Fast, OpenAI‑Compatible LLM Serving Guide
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

Introduction to vLLM and PagedAttention | Runpod Blog

Free Video: Fast LLM Serving with vLLM and PagedAttention from Anyscale ...
vLLM Python 2026 : servir des LLMs en production — PagedAttention ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...
vLLM PagedAttention Production Serving Optimization and Inference ...

10 Best vLLM Alternatives for LLM Inference in Production (2026) - DEV ...
Advertisement Space (336x280)
A guide to LLM inference and performance
LLM Inference 2026: Speed, Cost, Optimization Guide
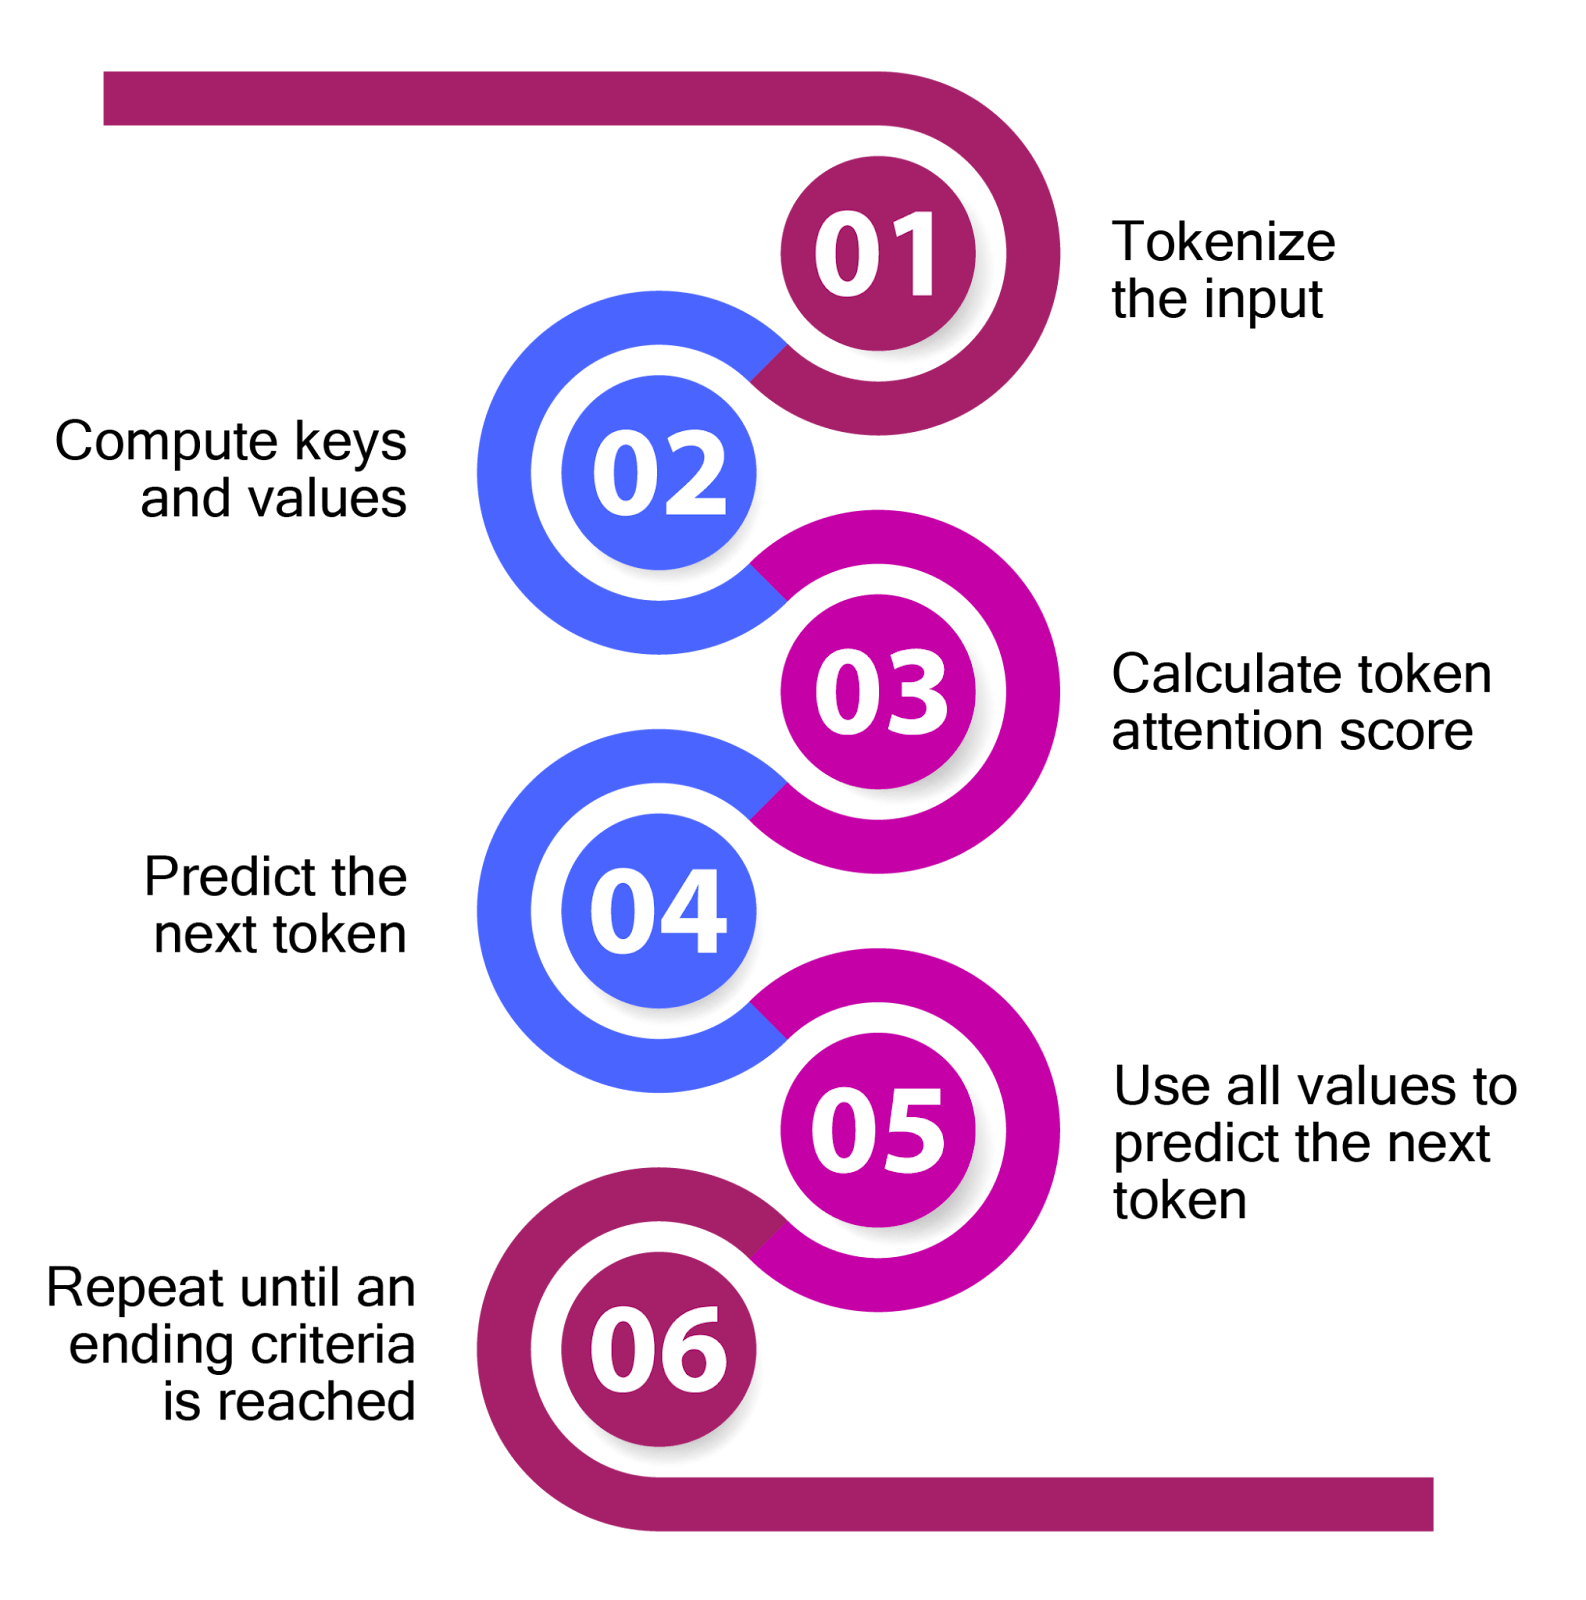
LLM inference optimization: Tutorial & Best Practices | LaunchDarkly
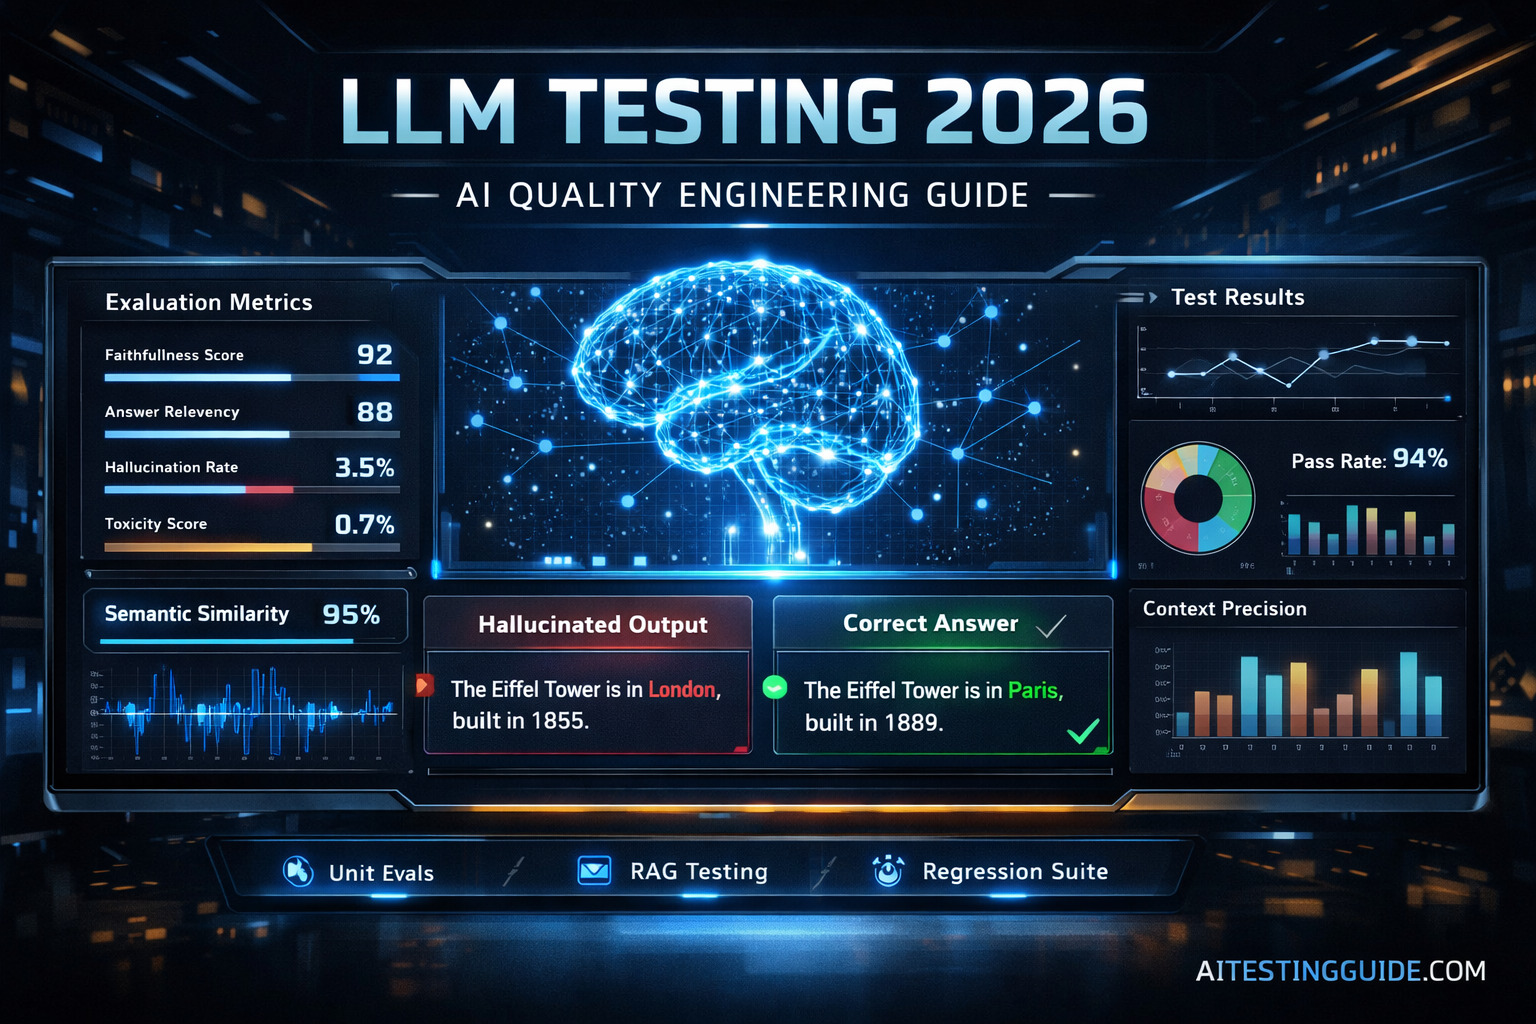
Test LLM Applications 2026 — Honest Guide for QA Engineers
How to Run LLM Inference with vLLM in Docker

Open WebUI 2026: Free Local AI Interface Setup Guide - WeavAI Blog
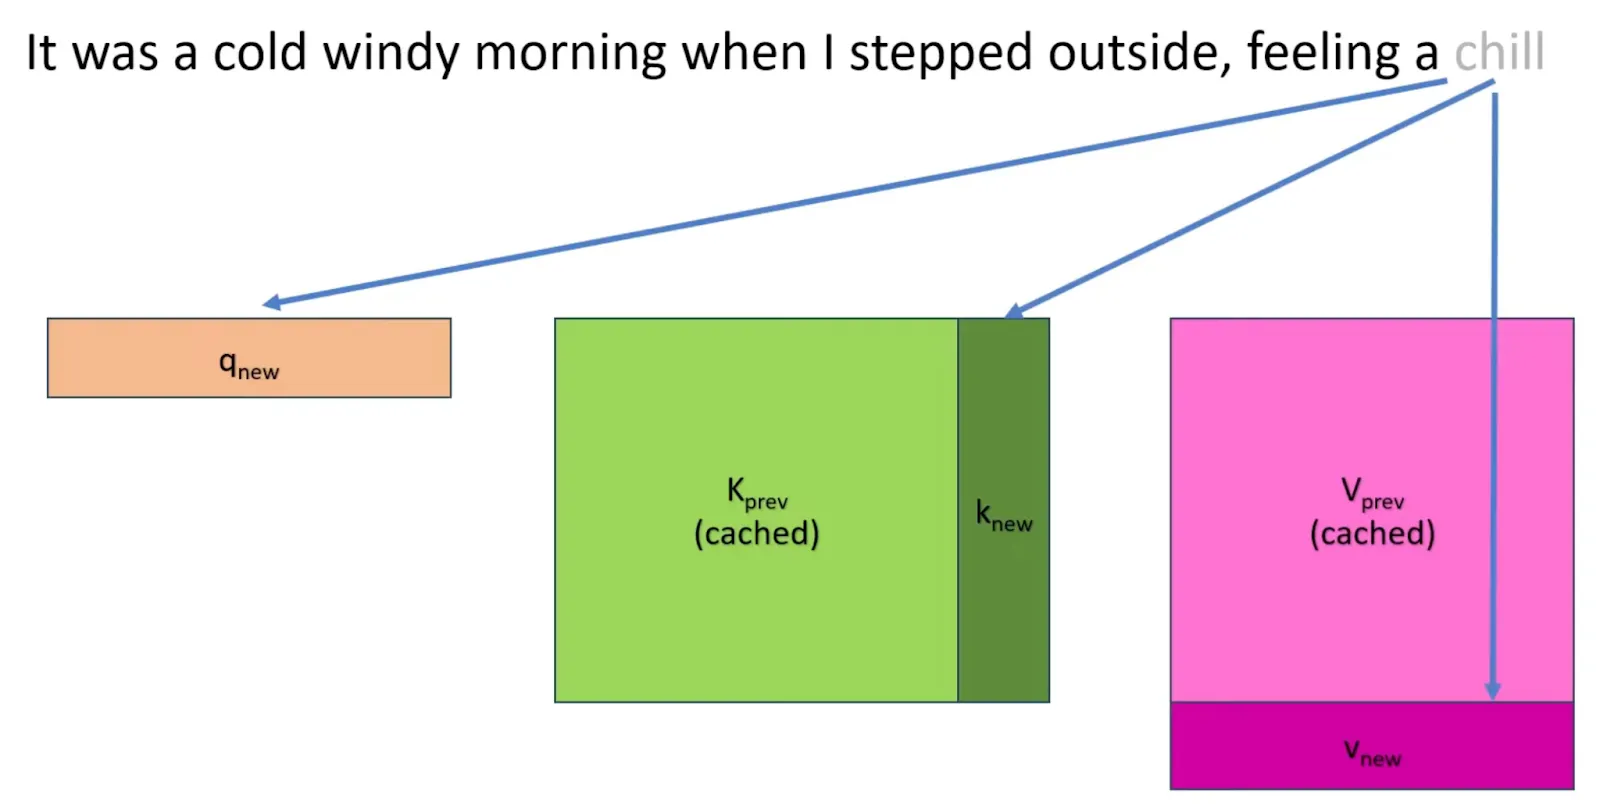
Introduction to vLLM and PagedAttention | Runpod Blog
Efficient LLM Inference and Serving with vLLM
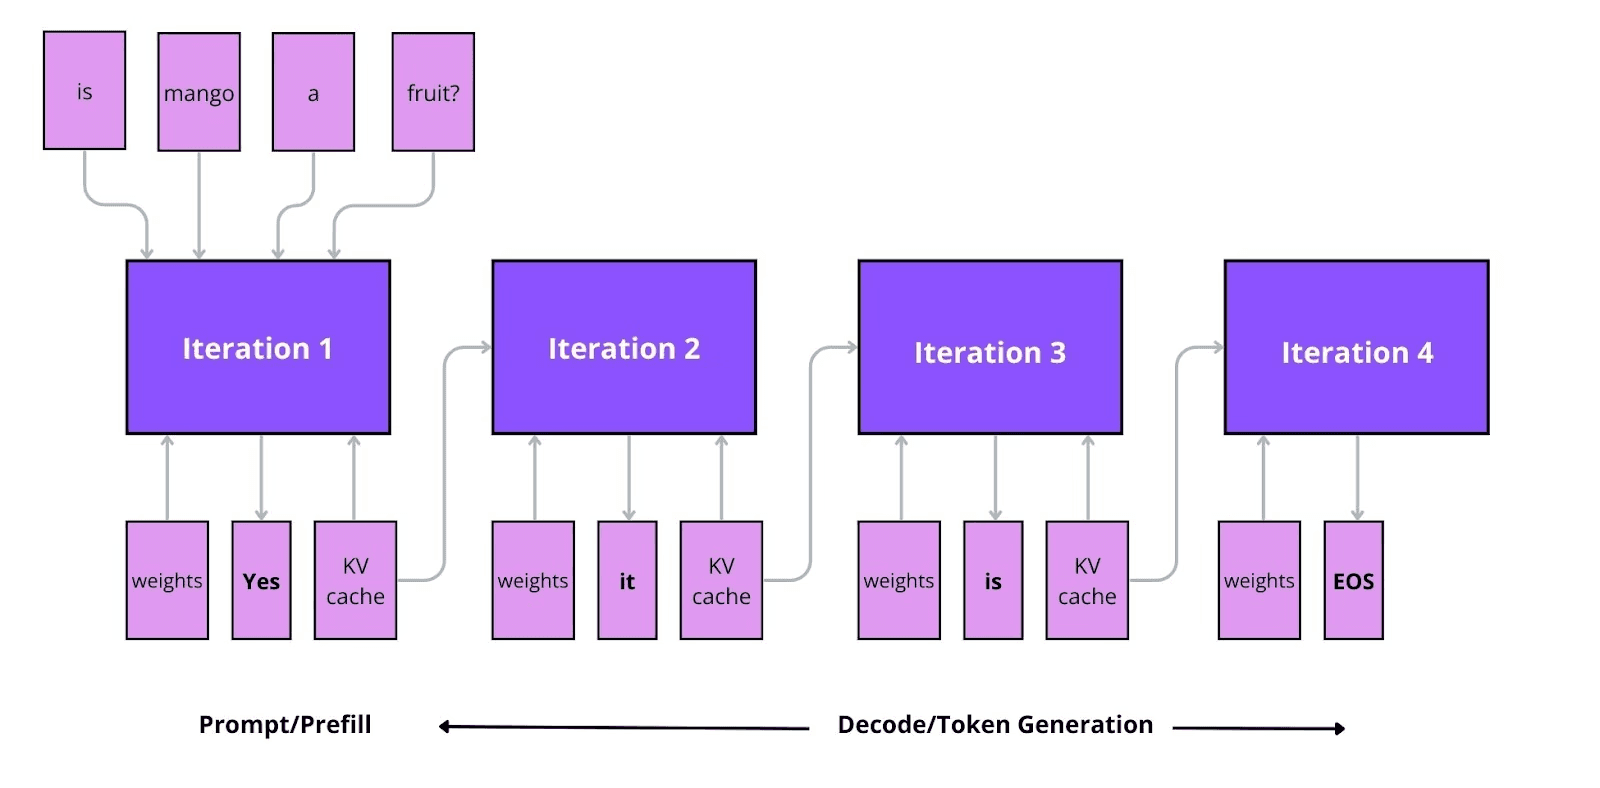
LLM Inference 2026: Speed, Cost, Optimization Guide
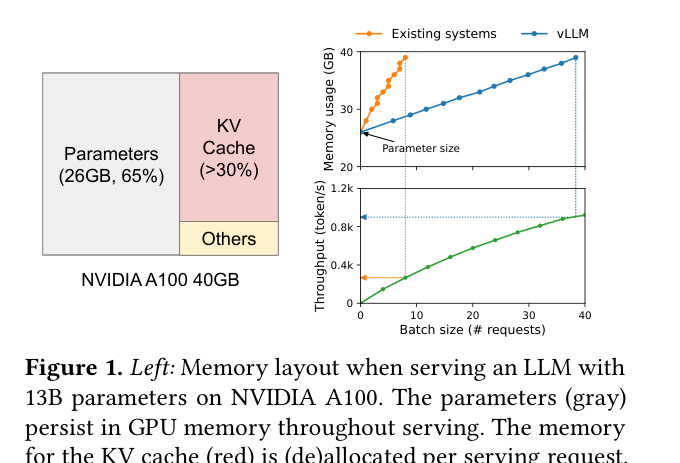
vLLM & PagedAttention: Memory Revolution in LLM Inference | AI Learning ...
Advertisement Space (336x280)
vLLM Installation for High-Performance LLM Inference - CubePath Docs ...
vLLM OpenTelemetry: Monitor LLM Inference Metrics with Parseable
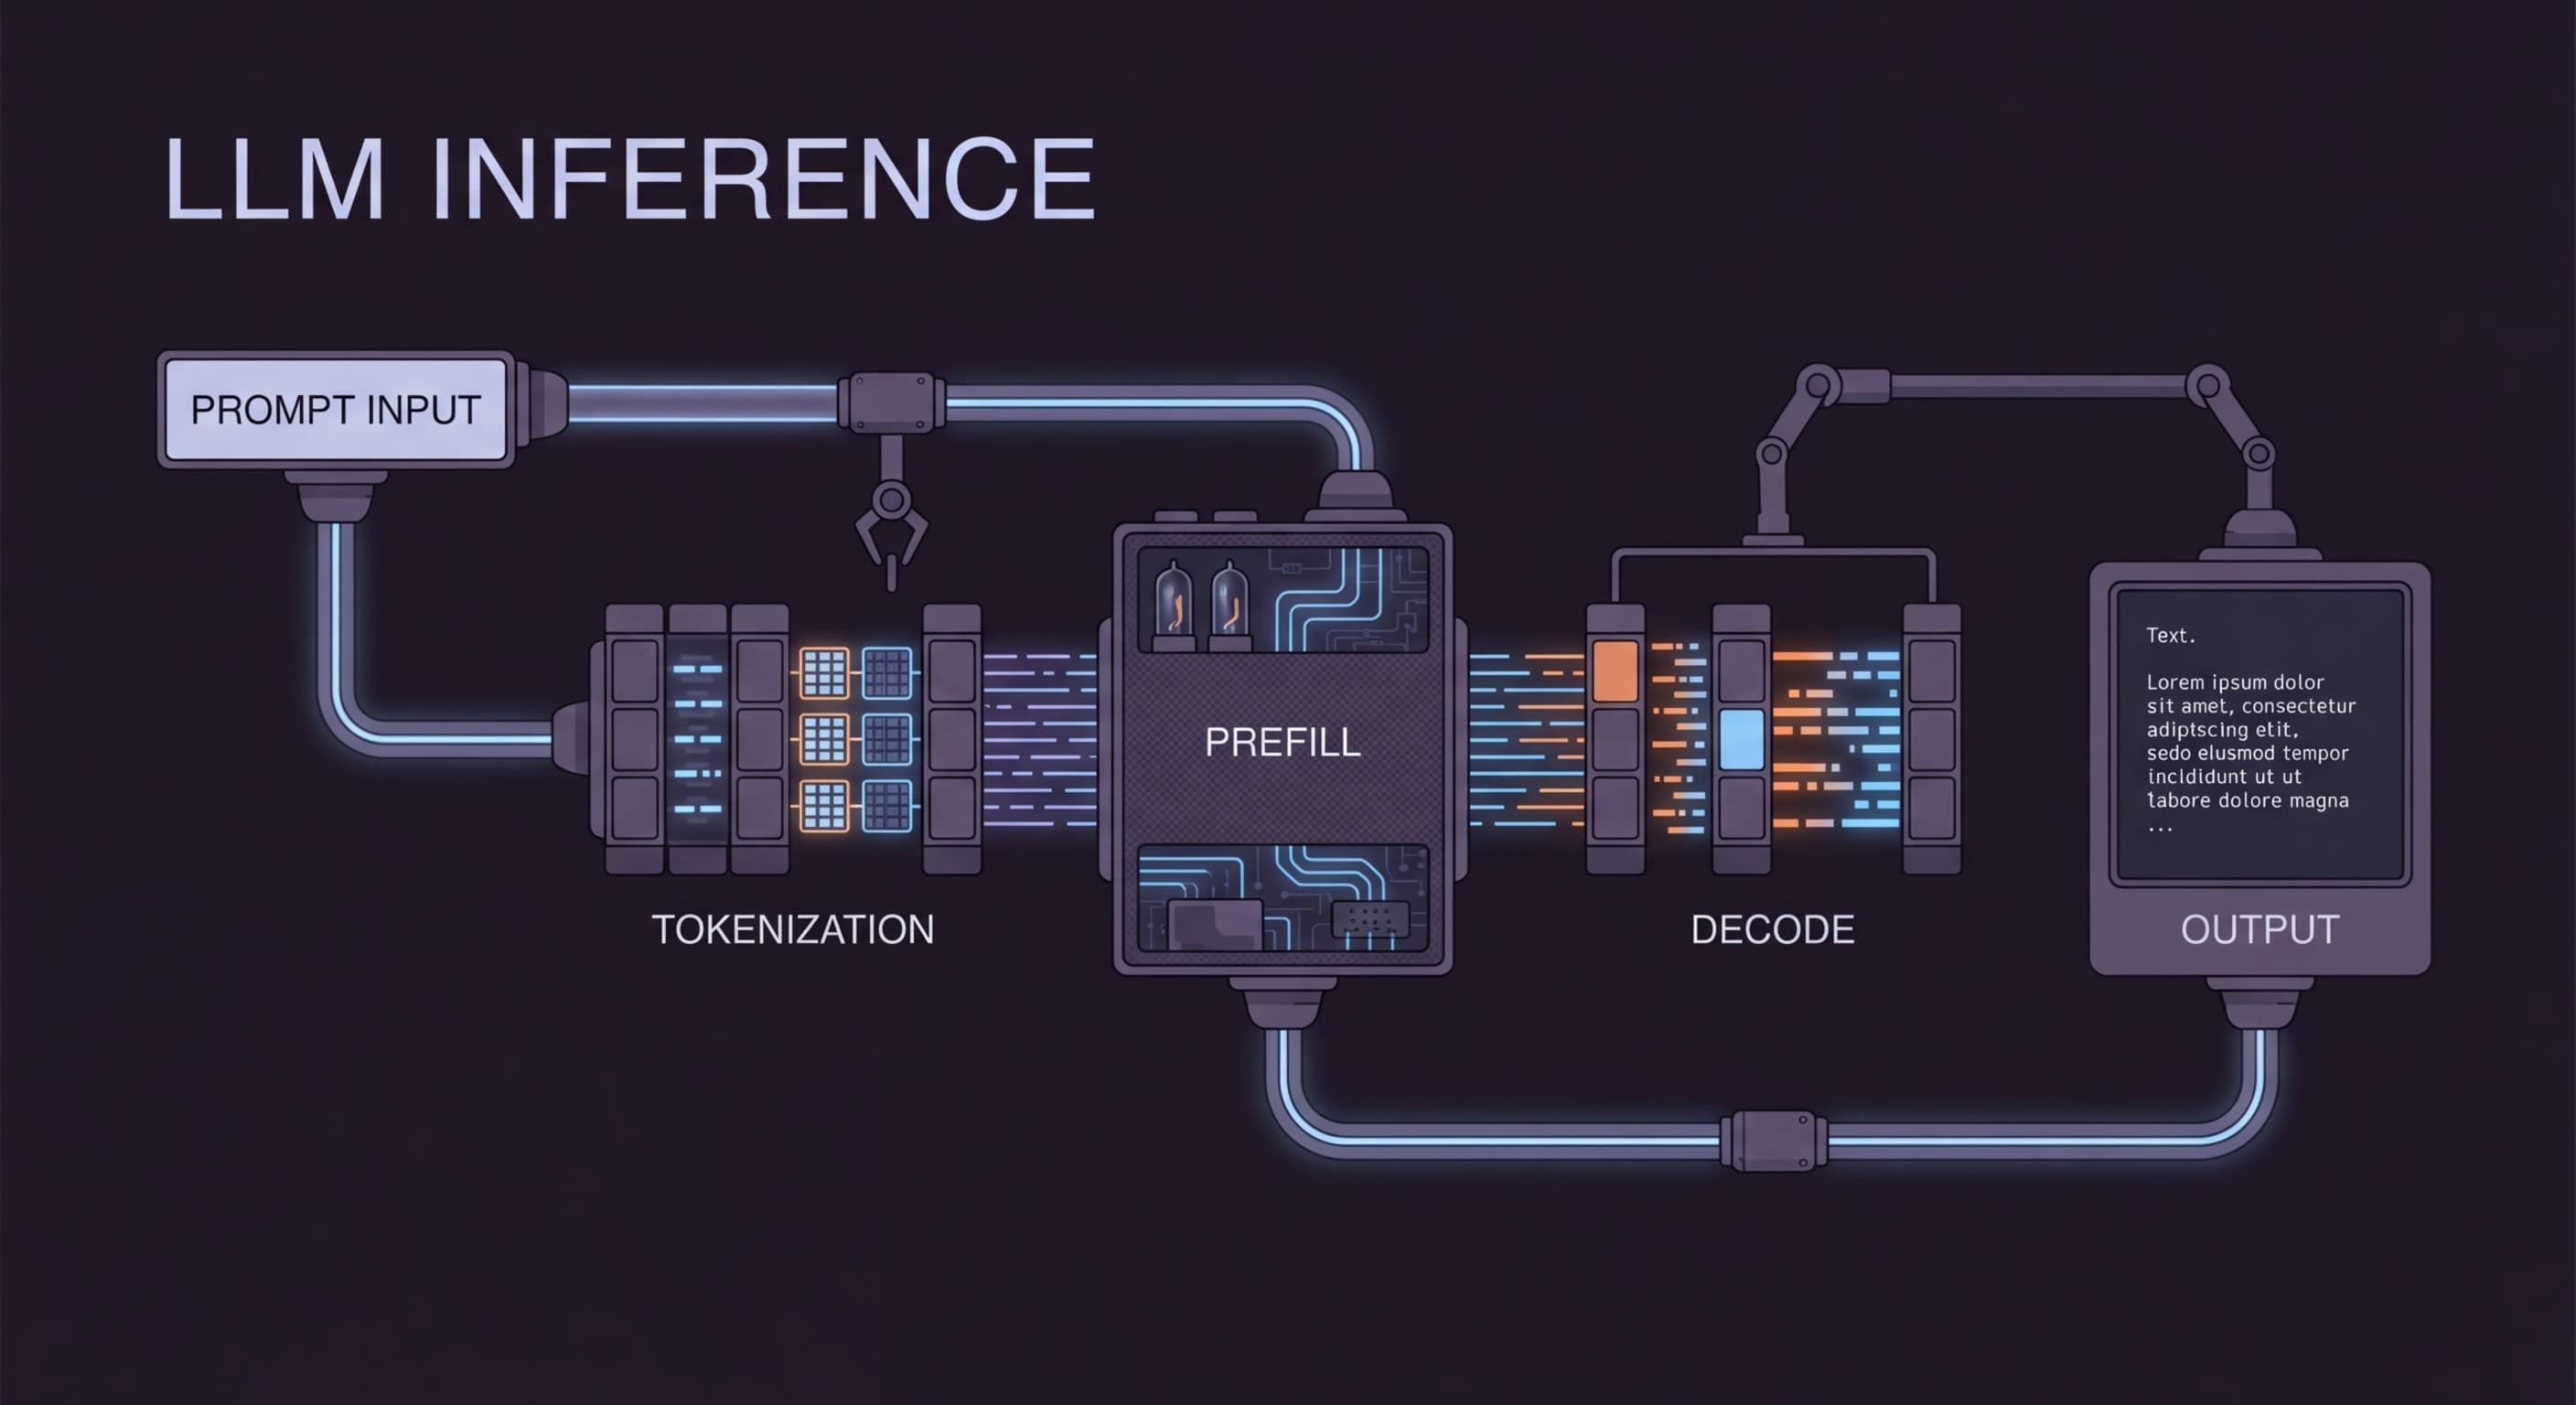
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph

vLLM 完整使用教學 2026:PagedAttention 高吞吐量 LLM 推論引擎完整指南

vLLM 完整使用教學 2026:PagedAttention 高吞吐量 LLM 推論引擎完整指南
vLLM 완벽 가이드 — PagedAttention으로 LLM 추론 처리량 24배, GPU 비용 절감